) and case studies are a good fit.
Personalization is the key concept here. A target account should be nurtured through continuous delivery of bespoke content that leads him/her down the sales pipeline.
### **4 - Measuring the ABM success**
Companies use ABM to raise awareness, increase engagement, and generate more lifetime value from targeted accounts. The number of visits to a blog page, downloads of an e-book, or demo and free trials signed up for can all tell an ABM team about the level of interest they managed to engender in their target accounts. However, the more meaningful indicators are the reduction in the sales cycle and the growth in the average annual contract value ABM was able to create.
## **ABM vs. Traditional marketing: Key differences**
Traditional marketing comes up short for a company offering a wide range of products and services to a similarly wide range of customer profiles. A blanket marketing campaign without the necessary nuances naturally dumbs down the messaging and dilutes the value proposition for different ICPs. Suppose your company manufactures sports bikes, bicycles, and electric bikes all at the same time. In that case, you will have trouble attracting any customers interested in one of those categories without specifically targeting them.
Two major points of differentiation between traditional marketing and ABM are the funnel and the way marketing and sales cooperate.
### **The funnel**
Traditional marketing aims to [build a brand](https://www.ismartcom.com/blog/account-based-marketing-vs-traditional-marketing-whats-the-difference-anyway) first, which is expected to drive inbound leads. In order to build the brand, traditional marketers use mass media, trade shows, or mass emails, doing everything at scale.
The marketing funnel in traditional marketing is wide at the top and keeps getting narrower at every stage until sales manage to close a few deals. Traditional marketers believe that there is strength in numbers, so they cast a wide net with the hope that it will land them many leads, which they will later qualify and hand off to the sales.
The ABM approach turns the marketing funnel on its head and works with an inverted funnel. It is a targeted approach that prioritizes [quality over quantity.](https://www.ibeamconsulting.com/blog/abm-vs-traditional-marketing-b2b/#ib-toc-anchor-8) ABMers focus on a small group of accounts that are potentially best-fit customers for the product. These accounts tend to be more receptive to the messaging, which reflects their needs and pain points. Once the demand from these high-value customers is satisfied, ABMers move on to the next best group, a Tier 2 if you will, and expand into different segments or verticals like that.
### **Marketing-sales cooperation**
Traditional marketing aims to generate as many leads as possible and send them down the funnel to sales. The responsibility of the marketing function is limited to providing the sales function with opportunities they can close.
The ABM, on the other hand, involves a different approach. ABM guru Hillary Carpio states that field marketers, ABMers, and sales development teams need to work hand-in-hand, describing them as a “[one-team pipeline machine.](https://steno.ai/exit-five-b2b-marketing-podcast/61-abm-with-hillary-carpio-head-of-abm-at-snowflake#00:39:22)” Together, they work to identify the accounts that will be targeted to put the sales team in the best position to close deals. ABMers help field marketers understand what people in a particular region are interested in and which ones among them seem more engaged.
The sales function owns the list of accounts to be targeted in an ABM framework. But every account on that list must be studied by marketing and sales. These two functions first focus on how a prospective customer has come into contact with the product and what kind of engagement (a visit to the website, reading a few blog posts, a demo etc.) he has had with it. The next step is to identify the touch points from that engagement and build a targeted marketing campaign around them. Marketing and sales do not work sequentially but side-by-side in the ABM, from the identification of the target account to the closing of deals.
## **Mistakes to avoid in ABM**
### **Not conducting enough research**
The ABM strategy is based on ICPs, and its success is predicated on how well these ICPs represent reality. General assumptions about the industry won’t help. Practitioners of ABM need to have a profound understanding of the traits of the ICP. This involves calculating the total addressable market, identifying key stakeholders, studying the tech stack used, and understanding the jobs people are trying to get done and their pain points.
ABM requires zeroing in on a shortlist of accounts. To make sure that these are the best-fit customers, ABMers should gather as many data points as possible to enrich the customer profiles. The more information you have on the industry, company size, revenue, key decision-makers, current product range, and future investment or product launch plans, the more precise your ABM strategy will be.
### **Failing to recognize where in the customer journey the targeted account is**
Some ABMers tend to get a bit formulaic with regard to how they implement the ABM strategy. They pick tactics from the ABM playbook in sequential order without putting much thought in it, starting with paid ads first, then sending emails, inviting the prospect to a demo, or sending him a gift.
However, prospects will not respond positively to marketing content that is not in line with their intent and engagement level. A [demo invitation](https://www.poweredbysearch.com/blog/account-based-marketing-strategy/#h.1ei9ijp62t9) won’t work with customers who are not yet aware of their problem. Similarly, a prospect who visits your website and consumes your technical documentation is probably too far along the curve to be sent a generic email or a blog post. Exposing these two groups to the same ads would be a waste of money spent on paid ads.
### **Not employing enough personalization**
The differentiating aspect of ABM is the personalized playbook it envisions for each targeted account. Offering each and every account bespoke content is easier said than done. It is the main reason ABM is such a resource-intensive strategy.
The success of your ABM strategy is directly related to how well you customize your messaging to the needs of your targeted accounts. However, applying the same level of personalization to every targeted account is neither possible nor desirable. Your limited resources and creative energy should be focused on your [most valuable accounts.](https://growdigitally.com.au/top-6-account-based-marketing-mistakes-to-avoid-for-your-abm-program/) This includes writing blog posts, creating ad copies, designing landing pages, developing onboarding processes and selecting personalized gifts tailored to different accounts, and being present in channels they prefer.
Serving your Tier 2 and Tier 3 accounts with hyper-customized content is not feasible. The content these accounts will consume will be less differentiated but still relevant to their needs.
### **Failing to meet the customers where they are**
ABM is predicated on the belief that there is no one-size-fits-all solution in marketing. Blanket assumptions lead you to nowhere because each account is different and, thus, requires tailored messaging. The beautiful thing about getting to know who your target accounts are is you don’t have to rely on emails or social media posts to start a conversation with them.
LinkedIn direct messages, paid ads, social media posts, email, and direct mail are indispensable to ABM practitioners. However, once you enrich your data set with data from your CRM or a third-party data-gathering tool, you should step out of the digital world and meet your target accounts in trade shows, conferences, or product launch events. ABM makes this possible by teaching you where your target accounts are, what they are interested in, and what they plan to do in the near future. Capitalizing on the human touch is what makes ABM so effective.
## **Benefits of pursuing an ABM strategy**
### **Sales and marketing alignment**
ABM is “_a concerted effort to deliver the right message to the right person at the right time to increase the go-to-market effectiveness_” and forms a “[three-legged stool](https://steno.ai/exit-five-b2b-marketing-podcast/61-abm-with-hillary-carpio-head-of-abm-at-snowflake#00:06:43)” with field marketing and sales development.
In a traditional marketing framework, marketing and sales are evaluated on the basis of their own distinct goals. Marketing is charged with generating as many qualified leads as possible for sales. The measure of success for sales is the deals closed.
In an ABM framework, however, leads are not handed off from marketing to sales. These two functions work together to design the whole pipeline, from identifying the high-value accounts to determining the critical contacts within each account to course-correcting based on the feedback from the field. Instead of evaluating sales and marketing on their own, the whole ABM pipeline is graded on [the percentage of accounts engaged](https://steno.ai/exit-five-b2b-marketing-podcast/61-abm-with-hillary-carpio-head-of-abm-at-snowflake#00:39:22) and revenue generated.
> “_You can't do a direct, ‘this asset led to this lead that led to this meeting that led to this opportunity;’ there is no direct ROI in that sense. So we're looking at the overall targeting of the account and surrounding of the account and how the impact compares to other accounts with a similar profile that did not get that same treatment. So I'm looking at the lift of ABM targeted versus ABM engaged._”
Make sure to check out this video by Hillary Carpio for a deep dive into how ABM can help align marketing and sales.
{{ youtube(id="vu8nBROMEtA") }}
### **More efficient customer acquisition**
ABM, when implemented right, is capable of creating a [customer acquisition engine.](https://accelerateagency.ai/saas-account-based-marketing-strategy#the-benefits-of-ABM-compared-to-traditional-marketing) Instead of throwing it against the wall and seeing what sticks as is usually done in digital marketing, ABM suggests a more methodical approach, working its way from the ground up.
The research conducted on the accounts to be targeted, zoning in on an ever smaller segment of the market that matches the ICP, engaging the target accounts through personalized content, and then expanding to other stakeholders within the same account are steps that cumulatively increase your chance of closing a deal. With ABM, you have a list of high-value accounts that fit your ICP and content customized to their needs, which means that you are never lost as to how to approach potential customers.
### **Shorter sales cycles**
ABM leads to shorter sales cycles simply because the sales teams do not have to waste time vetting the leads or starting from scratch to get potential customers interested in the product. The names on the target account list are closest to how the marketing and sales teams would describe the best-fit customers of a company. These accounts show differing levels of intent and engagement, which the sales team can capitalize on. Your best-fit customers tend to be the most receptive people to your messaging, so targeting these people significantly shortens the sales cycle.
### **Higher customer lifetime value**
ABMers work with high-value accounts that are a better fit for the product or service being offered. For ABM to make sense for a company, tier 1 accounts must have an ACV of at least $15,000. These people tend to be power users who make products they like a bigger part of their lives. They respond better to customer loyalty programs. They are more likely to agree to upselling and cross-selling offers. As a result, they generate more revenue for a company over the course of the business relationship.
### **Higher ROI**
The meticulous customization of messaging and marketing content in ABM involves more upfront costs, but this focused approach helps land significantly bigger contracts, more than making up for the costs incurred. A well-implemented ABM plan takes into account the customer-journey fit and adjusts content accordingly. Doing this minimizes the risk of delivering emails, paid ads, or demo invitations to people who would not be interested and ensures more efficient use of company resources.
## **Tips for ABM success in B2B SaaS**
ABM fits like a glove to the marketing needs of B2B SaaS companies catering to the enterprise and mid-market. However, to make the most of ABM, you company should meet certain requirements:
### **A minimum deal size of $15,000**
ABM is an expensive strategy to pursue. Like in the manufacturing sector, the more you rely on customization, the higher your costs are. To justify the investment in ABM and the staff that will drive it, experts like [Brandon Redlinger](https://www.exitfive.com/podcast/abm-overview) believe that the annual contract value should be more than $50,000 at the minimum. Yet, there are other practitioners who argue that technology has brought that threshold down. It is difficult to put an exact number on it, but it is safe to assume that contracts smaller than five figures won’t be enough to cover the costs you incurred. B2C offerings with short sales cycles, smaller average contract value, and high velocity are not suitable for an ABM strategy.
### **Established sales, marketing, and design teams**
Creating personalized content for targeted accounts and different stakeholders under each account on a regular basis is quite a challenge. Most of the time, the resources of a startup won’t allow it to pursue an ABM strategy at scale. Usually, an ABM team involves [five main roles:](https://fullfunnel.io/abm-strategy/)
**ABM manager:** This “integrated marketing manager” aligns everyone else around a program, manages the budget, determines the KPIs to track, and plans the whole campaign.
**Researcher:** This professional brings together the data that will be used to form ICPs and enriches that data with CRM data for further customer segmentation.
**Content marketer:** The content marketer will be responsible for creating personalized content in different formats that will be used in emails, ads, or landing pages.
**Designer:** The high rate of content creation necessary for ABM makes it difficult to outsource this function. A designer will bring a coherent design language to the content created for different accounts.
**Sales development representative (SDR):** SDR is the field component of the team that drives the engagement with target accounts, making offers, and providing the ABM team with feedback from the field.
### **A multi-pronged approach targeting different stakeholders**
ABMers have to deal with a group of stakeholders, often referred to as a buying committee, rather than a single decision-maker, as in B2B marketing. Each target account involves [three main roles](https://accelerateagency.ai/saas-account-based-marketing-strategy#how-to-execute-an-effective-ABM-marketing-campaign-for-SaaS) ABMers should engage:
- **Everyday users** are the people who personally use a product to get a job done. Being in a position to benefit the most from the product, they are likely to become the champions of the purchase decision in their organizations.
- **The manager** oversees the way the product is used, evaluates the benefits, and gives feedback to the executive who is going to make the financial decision on the product. They are potential influencers with clout to impact the final purchase or renewal decision on the contract.
- **The decision-maker** signs the check and makes the final financial decision to purchase the product or not. Input from influencers can have a significant impact on this final decision. Similarly, blockers who oppose the purchase because they don't believe in the benefits or favor some other solution can sway the decision.
Daily users are more receptive to digital marketing campaigns, and it's possible to engage them by giving them exceptional customer support and ensuring their success.
A personal touch from the ABM team would be better for the people in the manager role. Educating them about the product's benefits and converting them into champions can pay off in the long run.
A return to traditional marketing tactics is justified to win over the decision-makers in executive roles. It might sound awkward for a SaAS company to consider, but the good ol' wine & dine tactic is still the go-to move to build relationships with executives and land big enterprise contracts.
## **Successful ABM implementations with high ROI**
ABM is getting increasingly popular among companies unsatisfied with the results of conventional marketing practices. Here are three examples where companies leveraged ABM to zero in on a specific problem and achieved impressive outcomes:
### **Caroo**
#### **Problem**
When the pandemic disrupted life in the office and made remote work a necessity, in-office snack platform [Caroo](https://cxl.com/blog/account-based-marketing-examples/#h-6-how-caroo-reached-85-of-target-accounts-after-a-rebrand) was caught off-guard. With its revenue plunging, the company reimagined itself as a corporate gifting platform for remote teams.
#### **Solution**
Caroo employed a well-planned ABM approach leveraging highly personalized content for different use cases and verticals to increase traction.
#### **Tactic used**
The team at Caroo was able to pique the interest of distinct customer segments by launching microsites tailored to specific customer personas.
#### **Result**
The Caroo team was able to engage 85 percent of the accounts on its list. This impressive rate was a testament to the effectiveness of Caroo's approach and how well its microsites resonated with the customers it targeted.
### **TigerConnect**
#### **Problem**
TigerConnect, a software company with a product facilitating clinical communication, [had trouble driving enough traffic to its website](https://directiveconsulting.com/case-studies/healthcare-communication-linkedin-advertising/) with its advertising strategy based on low-volume, high-intent keywords.
#### **Solution**
TigerConnect brought in Directive Consulting to devise a new marketing plan. Directive suggested a targeted approach focusing on more narrowly-defined customer profiles that could be a good fit for the product.
#### **Tactic used**
Directive started by creating educational material focusing on the lack of communication in clinics to support the ad campaign. It then introduced an ABM strategy going after people with specific job titles and skill sets on LinkedIn, who looked most likely to respond positively.
#### **Result**
Directive's LinkedIn move increased paid lads by 31 percent and decreased cost per action by 71 percent quarter-over-quarter. At the price of a 15 percent increase in LinkedIn ad spending, TigerConnect enjoyed a 111 percent increase in visitors from this platform.
### **Branch**
#### **Problem**
The mobile attribution platform Branch was having trouble increasing its [conversion rate.](https://www.navattic.com/blog/b2b-saas-abm-examples) The sales and marketing functions were not aligned properly, undermining the company's gifting strategy by extending to two months the time it took to pick out and send gifts.
#### **Solution**
Branch doubled down on its ABM campaign by introducing the gifting platform Alyce and decided to take its ABM game up by a notch by following a multi-channel marketing strategy.
The marketing team at Branch also started leveraging emails, social media, and phone calls to multiply the points of contact with the targeted accounts.
#### **Tactics used**
Branch achieved better personalization in gifting through the use of Alyce, a corporate gifting platform. By adopting a multi-channel strategy, the marketing team used emails, social media, and phone calls to multiply the points of contact with the targeted accounts.
#### **Result**
Streamlining the gift selection process reduced the time it took to tailor gifts to minutes. Branch was able to land two six-figure contracts thanks to its dedicated use of the ABM strategy.
## **How can ABM teams utilize Peaka for account-based marketing?**
Pulling in data from different tools and building a single view of truth is Peaka’s forte. Its connectors streamline data integration for startups and SMBs, connecting the most popular SaaS tools.
[Peaka’s HubSpot-Stripe integration](/blog/integrations-hubspot-stripe/) has a major role to play for ABM teams. This dedicated connector helps users merge their revenue and CRM data, making it possible to filter companies with specific levels of revenue according to the company size, industry, and country.
Armed with Peaka’s data integration capability, ABM teams can
- Zero in on accounts that provide the closest fit with the ICP they identified before,
- Enrich the revenue data with customer attributes,
- Form the three-tiered customer segmentation that is so central to the ABM strategy,
- Create better and more engaging content, increasing the likelihood of conversion.
## **SaaS ABM strategy content to consume**
- Video – [Goods to Selling High: How to Make ABM Actually Work with Snowflake's Head of ABM, Hilary Carpio](https://www.youtube.com/watch?v=vu8nBROMEtA)
- Podcast — [ABM (Account-Based Marketing) Overview](https://www.exitfive.com/podcast/abm-overview)
- Podcast — [ABM with Hillary Carpio (Head of ABM at Snowflake)](https://steno.ai/exit-five-b2b-marketing-podcast/61-abm-with-hillary-carpio-head-of-abm-at-snowflake)
- Podcast — [How to Define, Measure and Hire for ABM with Hillary Carpio](https://podcasts.apple.com/us/podcast/how-to-define-measure-and-hire-for-abm-with-hillary-carpio/id1657886939?i=1000602440203)
- Article — [ABM strategy: The Step-by-step Guide for B2B Companies (2023)](https://fullfunnel.io/abm-strategy/)
- Article — [Why SaaS Embrace an Account-based Marketing Strategy](https://insights.strategicabm.com/saas-account-based-marketing)
- Article — [ABM for SaaS: The Definitive Framework](https://directiveconsulting.com/resources/abm-for-saas-definitive-framework/)
## **Conclusion**
ABM is the right kind of marketing for any company with the average contract value to justify its costs. Its step-by-step approach to marketing aligns different functions around a single purpose, helps build long-term relationships with customers, and increases the lifetime value of contracts.
Successful implementation of ABM requires thorough research into customer attributes, high levels of personalization, a multi-channel presence, and a multi-pronged approach to win the hearts of different stakeholders in an account. Nobody can claim that ABM is easy to execute, but the rewards are so enticing that it's all worth a try for anyone that can afford it.
--- START: blog/after-deluge-post-pandemic-business-world/after-deluge-post-pandemic-business-world.md ---
# **After the Deluge: Business World in the Post-pandemic Era**
The pandemic, having swept across the world like a tsunami, seems to be under control finally. Finally, there is some glimmer of hope that things can settle on a new normal, if not go back to *the* normal. Floodwaters are subsiding, laying bare before our eyes a landscape, parts of which are recognizable and some, totally alien. What does this new normal spell for the business world? Here is a list of 3 big transformations taking place in the business world nowadays:
## **1 - Hybrid work becoming the norm**
Once the lockdowns set in, remote work turned from a previously peculiar practice to the norm in a few weeks. The employees seem to have liked remote work, so much so that 61 percent of office workers [responding to a survey](https://envoy.com/wp-content/uploads/2021/03/BreakoutAsset-ReturnToWorkplace-032521-1.pdf) said that they would look for a new job if they were not offered flexible work in the future. The disappearance of daily commute to work and the associated time and money savings, the chance to spend more time with family and reduced exposure to Covid-19 got employees hooked.
However, an all-remote workplace does not seem realistic yet. Sharing an office with colleagues make it easier for employees to engage in networking and make their voices heard by the management. Employers, too, have their own reasons for willing to go back to the old way of doing work. Business leaders such as the chief executive officers of Goldman Sachs and Barclays [support](https://www.bbc.com/news/business-56759151) going back to the office—they notice that some aspects of the work life like the shared culture and resulting synergy cannot be replicated online.
## **2 - A new labor market for the tech business**
Although more traditional segments of economy might have a hard time coming to terms with the new hybrid or remote work arrangements, the tech business seems to be pushing for the change. [Slack and Stripe](https://www.bloomberg.com/news/articles/2020-09-15/stripe-employees-who-relocate-to-get-20-000-bonus-and-a-pay-cut) are actively encouraging this by offering their employees one-time bonuses in exchange for accepting a salary cut for remote work. Google is endorsing a [hybrid work plan](https://www.forbes.com/sites/jackkelly/2021/05/06/google-announces-a-hybrid----return-to-work-plan-including-both-remote-and-in-office-options/) where employees will spend approximately three days working at the office and those opting for full-time remote work will be asked to agree to salary cuts. With 2 out of 5 employees [willing to take a pay cut](https://envoy.com/wp-content/uploads/2021/03/BreakoutAsset-ReturnToWorkplace-032521-1.pdf) for flexible work, it doesn’t sound too far-fetched that the two parties will soon meet each other in the middle. Actually, signs from the field point to the fact that there already is a new *modus vivendi* in place, as indicated by the exodus of tech workers from places like the Bay Area in the U.S.
The Bay Area has been home to some of the biggest tech companies in the world and attracted top talent from all over the world for decades. But things seem to be changing nowadays. Having experienced productivity in a remote work arrangement, tech workers in the Silicon Valley have decided that they could do without the daily commute to work, and some even moved to other states where housing is much more affordable compared to the Bay Area. Texas and Florida seem to be the [top destinations](https://techmonitor.ai/leadership/workforce/people-jobs-fleeing-bay-area-is-this-end-of-silicon-valley) benefiting from this exodus. In the new normal in the tech labor market, firms will keep leveraging the skills of their employees and reduce their payrolls while the employees will enjoy higher net earnings thanks to savings on commute and housing. Sounds like a win-win situation, doesn’t it?
## **3 - Looking for an agile way of driving growth**
The pandemic hit every segment of the economy but with varying degrees of damage incurred. Travel and hospitality sectors were particularly hard-hit, spending months out of operation. The pandemic stopped many projects in their tracks: In the U.S. construction business, almost [$10 billion worth of infrastructure projects](https://www.constructiondive.com/news/96b-worth-of-infrastructure-projects-delayed-or-canceled-during-covid-19/582713/) were either delayed or cancelled in the first six months of the pandemic. While the IT sector proved more resilient thanks to leveraging technology and finding ways to keep things running, it still faced [wide-scale project delays and cancellations](https://www.ciodive.com/news/coronavirus-impact-IT-companies-software-comptia/578299/).
The calamity had caught everyone off-guard this time, unlike the recessions in the past where hundreds of articles and even books warning about the upcoming crises had already been written before the first impact. Pandemic reminded everyone of a kind of unpredictability for which no organization but governments only could hope to take measures.
This unpredictability will have lasting effects on the business world. Business leaders, from startups to corporate giants, will be reluctant to commit as much time and money to projects as they did in the past. They will want to see proofs of concepts, realistic simulations and reports before pulling the trigger on new projects. The waterfall project management process, which demands big sums and long months before bearing any fruit, will fall out of favor with decision makers who learnt their lessons from the pandemic. Agility and having the option to pivot when necessary will be the order of the day.
## **4 - No-code to the rescue**
These changes combine to bring no-code platforms to the fore, which are capable of creating proofs of concepts and MVPs much more quickly and at a much lower cost than conventional software development. Consider for a moment a firm which is newly branching out into a new segment of the market and building a sales team as part of this plan. For a firm like this, investing in a top CRM tool and training the employees would involve a lot of risks with the possibility of another peak in the pandemic and ensuing lockdowns looming in the background. Using no-code platforms like Peaka to prototype, test and launch a CRM tool, however, will take a considerably smaller investment and be more likely to fit the specific needs of the firm.
The post-pandemic IT world will be defined by fluidity: People switching careers or relocating for work, and businesses making an effort to be agile in management and project development. Agility and adaptability will keep you in the game while those putting all their eggs in one basket will fall by the wayside sooner or later. We believe that [Peaka](/) stands out among competitors by giving you a platform that keeps with the times: Flexible, resourceful and capable of growing with your business.
--- START: blog/ai-data-governance-framework/ai-data-governance-framework.md ---
# **AI Data Governance: A Framework for Enterprise Teams**
One of the biggest problems facing enterprises today is governing the data that AI systems can access.
Imagine the following scenario: A copilot answers a sales rep's question with another team's pipeline data. An agent updates a record it shouldn't have read in the first place. Compliance asks who approved that, and nobody can say.
These problems didn’t happen before GPTs and Claudes took over the world. Traditional data governance was built for humans clicking through dashboards on a known cadence. But AI consumers don't behave like that.
AI data governance is the set of policies, controls, and audit mechanisms that determine which data AI systems (LLMs, retrieval pipelines, and autonomous agents) can access, how they can use it, and how every interaction is recorded.
Today, I’m going to cover what makes governance for AI different, the control surface, the failure modes, and a practical path to putting controls in place without choking the AI program.
## **Why traditional data governance falls short for AI**
Traditional governance assumes a human in the loop, that is, an individual who logs in, runs a query, reads the result, and applies judgment. Most existing controls (role-based access, dashboard-level permissions, quarterly access reviews) were designed for that consumer.
AI agents don’t submit to the same assumptions:
+ **Speed and volume:** An agent can issue thousands of queries per minute. Quarterly access reviews are meaningless.
+ **Aggregation:** An LLM that stitches data across systems can produce outputs more sensitive than any single source, creating a re-identification problem that traditional governance doesn't address.
+ **Indirection:** The user prompts in English; the agent decides what to query. Permissions need to follow the user, not the agent's service account.
+ **Writes, not just reads:** Agents change state, so governance has to cover state changes alongside data exposure.
{{ resize_image(path="../static/assets/images/blog-images/mathew/ai-governance-matrix.png", width=759, height=400, op='fit_width', alt="a table depicting AI governance challenges and fixes") }}
AI consumes data differently, and the control surface has to match.
## **The control surface of AI data governance**
A workable program needs to address all of the following:
### **Access control at query time**
Permissions are evaluated at read time and scoped to the end user the AI is acting on behalf of, not to the service account running the agent.
### **Data classification**
Every dataset is tagged for sensitivity (PII, PHI, financial, internal-only) so policies can apply automatically rather than being hand-wired per integration.
### **Purpose limitation**
The same data may be allowed for one use case (a support copilot) and disallowed for another (a marketing model). Governance enforces the difference.
### **Output controls**
Redaction, masking, and DLP apply to what the AI returns, not just what it queries. An LLM can re-derive PII from non-PII columns.
### **Auditability**
Every AI-driven read and write should be logged with the user, prompt, resolved query, accessed data, and response. The full interaction should be reconstructable after the fact.
### **Lineage for AI outputs**
You need to know which sources contributed to a given AI answer or action, so a wrong output can be traced back to a wrong input.
### **Action governance**
Agents that write, transact, or trigger workflows require stricter, separate controls than agents that only read. The two are different risk classes and should be governed accordingly.
### **Model and prompt governance**
Prompts, system instructions, and model configurations that shape AI behavior should be versioned so that behavior changes are attributable.
## **Stretching the wrong controls**
RBAC has been the default for a long time. It was designed for predictable, human-shaped access. Agents act on behalf of many users under a single identity by default, which breaks the model. The solution is identity propagation. The agent queries as the end user, with their permissions, not its own. Agent identities also need to be subject to stricter oversight than human users.
Also, prompt-level guardrails ("don't return SSNs") are necessary but unreliable. Models can be jailbroken, confused, or simply wrong. The more reliable approach is defense-in-depth. Enforce at the data layer first (the AI never sees what it shouldn't), then at the model layer, then at the output layer. Each is a backstop for the others. The instinct to layer these controls is often resisted because teams believe that governance slows AI programs down. The opposite is true in practice.
Teams without governance ship one demo, hit a security review, and stall for six months. Governance designed in from the start lets the AI program scale to more use cases, more data sources, and more sensitive workflows. Ungoverned AI plateaus at low-stakes use cases.
{{ resize_image(path="../static/assets/images/blog-images/mathew/ai-governance-misconceptions.png", width=759, height=400, op='fit_width', alt="a table depicting AI governance myths") }}
## **A checklist: Is your AI data governance in place?**
One of the most helpful approaches to data governance, in our experience, is to look at it through the lens of a rubric. Use the controls above as a starting point. If you can answer most of the following questions positively (and efficiently), you're likely in a good place:
+ Can you tell, for any AI response, which data sources contributed to it?
+ Are AI queries executed under the end user's permissions, or the agent's service account?
+ Is every AI-driven read and write logged in a way you could hand to an auditor?
+ Are sensitive fields classified consistently across sources or per integration?
+ Are there separate, stricter controls for agents that take actions vs. agents that only read?
+ If a model is swapped or a prompt is changed, is that change versioned and attributable?
+ Can you revoke an AI system's access to a specific dataset in minutes, not weeks?
+ Are output-layer controls (redaction, DLP) in place, or is the model the only line of defense?
A "no" on any of these means you're not yet at gold-standard governance.
## **Why data virtualization is a solution**
You might be wondering why Peaka is writing about this topic. After all, we're a data virtualization product, not a security vendor.
That's exactly the point. Data virtualization (or data federation, as some say) is a natural place to enforce several governance controls at once.
### **Single query interface**
Data virtualization provides one place to enforce access policies across sources. Because everything connects to the virtualization and all queries pass through it, there's no risk of accessing stale data that's been further locked down between sync and query time. Column- and row-level policies apply consistently across heterogeneous systems via federation.
### **Centralized audit log**
Every AI-driven query is captured in one stream. Federation forces everything to be cataloged the same way, making it easy to filter and locate data. Classification metadata is also attached to the layer that the AI actually queries.
That said, virtualization alone doesn't cover output redaction, prompt-layer guardrails, or model versioning. It does make it easy to add those layers by simplifying the data access problem, and it pairs cleanly with an AI security solution.
## **What is Peaka?**
Peaka is a dynamic layer that sits on top of your existing data infrastructure, such as data warehouses, databases, SaaS tools, and operational systems, exposing a single SQL interface with built-in permissions, classification, and audit.
Peaka enforces governance and access at the seam where AI queries meet your data, so agents integrate cleanly without bypassing the systems you already run.
If you’re looking to make your data AI-ready with built-in data governance, [book a demo](https://calendly.com/peaka/demo) with Peaka.
--- START: blog/ai-data-governance-metadata/ai-data-governance-metadata.md ---
# How Metadata Enables AI Data Governance at Scale
Prior to general AI adoption and agents being deployed en masse across enterprises, humans were the primary end user for data sources. We manually wrote all queries, scanned tables to perform joins, and knew what a specific column meant in the context of the whole schema. If a financial analyst was referencing a transaction fee column in a financial table, they would likely know whether it referred to a foreign transfer fee, a payment processing fee, or something else entirely. Now that we are hooking up our chatbots and agents to internal databases and asking them to perform analysis or execute a series of actions, we also need to make sure those databases can provide the right context and structure to securely and accurately support agentic use cases.
## How agent and human data access differ
There are a few key differences between agent and human behavior when interacting with data systems, and they shape how we should set up our data to be AI-ready:
- **Volume:** Agents run queries at multiple times the volume a human would. For any given task, they query to explore the database, understand joins and columns, and execute an action. For any security review that involves a data access report, that report loses much of its value when there are agents performing queries every few milliseconds. The review gets even murkier when those agents aren’t tied to a specific identity. Data sources need a new way to audit who accessed what and when.
- **Statelessness:** Agents don’t remember the contextual or business knowledge around a piece of data. Sure they can see the GMV column in a table, but they don’t remember that it doesn’t include shipping fees like a data analyst would.
- **Attribution:** If an employee is asking a chatbot to perform an analysis instead of querying it themselves, they won’t know which sources the data is being pulled from. Knowing the inputs for any answer or analysis ensures it is grounded in accurate and relevant data sources. And on the flip side, preventing a wrong answer from being generated again means knowing what the wrong inputs were.
- **Sensitivity:** An employee at a healthcare startup may encounter patient intake data and know it’s PHI. Agents cannot automatically perform that discernment. Even with guidelines and guardrails, something could slip through the cracks. And when it comes to sensitive data, even the smallest slip-up could cost an organization compliance certification or enterprise deal.
So how can we make sure the AI we deploy across our organizations is equipped with the contextual knowledge needed to query data accurately, securely, and accountably? The answer is a single centralized data control plane with a robust metadata layer. I’m going to walk through what this metadata layer should look like and how a data virtualization platform like Peaka can make that layer a reality for your organization.
{{ resize_image(path="../static/assets/images/blog-images/mathew/agent-vs-human-data-interaction.png", width=759, height=400, op='fit_width', alt="a table comparing ai agents to human interaction") }}
## Types of metadata and how they support governance controls
### Technical metadata
Technical metadata is the set of information that describes the structure of the data source. It includes schema, column, and table names, relations, data types, indices, constraints, and other descriptive context. Anything you need to understand how the database is organized and functions falls into this category, and it is the baseline layer of metadata that every other type depends on.
### Business metadata
Business metadata tells you how to make sense of or apply a piece of data in the real world. It’s a complement to technical metadata because, while technical metadata tells you how a piece of data exists, business metadata tells you what it actually means. For example, technical tells you that a specific column is titled `q3_cust_rev`, is a decimal, and exists in the finance schema. Business tells you it's "Q3 customer revenue, net of refunds, owned by the finance division." Your organization's policies live at this layer, because a rule is far more foolproof when it says "revenue figures are restricted" than when it points at `q3_cust_rev` by name and breaks the moment a schema changes. Business metadata also gives agents the relevant context that a human analyst would otherwise carry in their head, such as whether a revenue number is net of refunds or whether GMV includes shipping.
### Lineage metadata
Lineage metadata provides the track record for any piece of data being queried. It traces the path from the original source through any joins, transformations, or aggregations that were performed, logging everything that happened to generate the final value(s) a query returns. With regards to AI governance, lineage metadata enables attribution. If a human is asking a chatbot to generate a list of products by units sold, lineage metadata tells the human exactly which tables the LLM referenced and how the sales metric was calculated from those tables. Because AI isn't deterministic and won’t necessarily take the same path twice, lineage is especially crucial for reproducing an analysis or identifying where something went wrong when an incorrect answer is generated.
### Operational metadata
Operational metadata captures the access and use history around the data source. It includes when a data source was last refreshed, who accessed it and when, what queries were performed, and what larger process they were part of (if any). When paired with a strong AI-native IAM strategy (where agent identity is either independently defined or tied to a specific user), operational metadata is what makes auditing possible. A comprehensive operational record is what resolves the volume problem from earlier. A data access report without identity tagging makes it impossible to tell thousands of queries apart, but an operational record with robust access information lets security reviewers actually reconstruct the what, when, and who.
### Policy metadata
Policy metadata is the classification and rules layer, the sensitivity labels (PII, PHI, confidential), access tiers, retention requirements, and ownership assignments that dictate how a given piece of data can be used. A data analyst looking at patient intake data immediately knows it’s PHI, but an agent doesn’t have any way of knowing that without policy metadata. And while LLM guardrails are a necessary safeguard against sensitive data exposure, they aren't airtight and can be bypassed by a sophisticated prompt injection attack. Sensitivity labels live at the data source itself, so the controls acting on them apply no matter which entity is requesting access. In addition to sensitivity classification, policy metadata also includes the access tiers for each label that determine who can access it, the retention rules that state how long data can be stored, and the accountable party assigned to each label.
## How Peaka enables data governance through data virtualization
The metadata layer described above is what makes AI data governance even possible, but enforcing it manually is burdensome and error-prone. Organizations would need to set up each data source independently, continuously check that all metadata stays consistent across the sources, and update multiple locations when a schema changes or a new role is provisioned. A data virtualization layer like Peaka's is what makes metadata management seamless and reliable at scale.
### Centralizing technical and business metadata
Peaka allows organizations to connect all of their data sources to one centralized plane and then generates technical metadata on top of it to create a single, unified SQL interface. On top of that interface is the semantic layer that holds all business metadata for the organization. Once a metric or business term is defined, it can be attached to columns anywhere across the unified interface and any policy relating to that term is applied automatically. Teams across the company can then maintain and reference those shared definitions whenever needed, rather than guessing the meaning of a column or needing to ask around for more context.
### Enforcing policy metadata and audit logging
Classification metadata is also applied at the data level, where fields can be labeled as PHI, sensitive financial data, etc. Organizations are able to define what labels are useful for policy implementation and access control within the Peaka virtualization interface and easily attach those labels to columns. Then, permissions get evaluated at query time and attributed to the end user that the AI is querying on behalf of. Because everything flows through one layer, all queries, their results, identity information and other relevant metadata are recorded by Peaka in a central audit log and can be used to reconstruct any agent interactions. That audit log doubles as the operational record needed to make sense of query volume at agent scale.
### What Peaka doesn't cover
It’s worth clarifying that Peaka is a data virtualization platform that manages all the above, but does not cover output sanitization, LLM guardrails, or model versioning. It’s meant to work in conjunction with a robust AI security layer. What it does is enforce AI data governance at the data source itself, acting as the control point in front of your entire data infrastructure. When the right set of metadata is recorded and every query flows through a single governed layer, it transforms your data sources from human-friendly and merely AI-compatible to fully AI-native and secure.
If you're ready to give your data sources the technical, business, lineage, operational, and policy metadata your AI agents need, [book a demo](https://calendly.com/peaka/demo) with Peaka.
--- START: blog/ai-pair-programmers-future-copilots-nocode/ai-pair-programmers-future-copilots-nocode.md ---
# **AI Pair Programmers: The Future Copilots for No-code?**
The increasing demand for software is at the heart of significant changes taking place in the software industry. The annual increase in the number of developers joining the workforce cannot keep up with the sharp rise in demand for developer talent. This creates a shortage of developers for which many people are trying to find a solution.
Our no-code platform, [Peaka](/), itself is a product of an initiative to solve this developer shortage, along with some other platforms.
> *"Helping coders with the boring, tedious parts of their work so that they can focus on things where their creativity will be better employed…"*
This has been a common theme running through the mission statements of many no-code platforms. It looks like no-code tools are not alone in this, as illustrated by Greg Brockman, CTO of OpenAI lab, who hopes that his firm's latest product will "[help solve programmer shortage in the U.S.](https://www.theverge.com/2021/8/10/22618128/openai-codex-natural-language-into-code-api-beta-access)"
In this blog post, we will take a look at two prominent AI pair programming tools with a lot of hype around them. Do OpenAI Codex and Github Copilot represent a breakthrough in software engineering? Or are they tools that overpromise and underdeliver like many others?
## **OpenAI Codex**
Headquartered in San Francisco, OpenAI has just launched OpenAI Codex, its AI-based programming assistant, and has been making the headlines recently. Codex is a machine learning model that can work with programming and natural languages. It is based on OpenAI's former sensation, GPT-3, which is trained on the open-source data available on the internet and contains [175 billion parameters](https://www.theverge.com/21346343/gpt-3-explainer-openai-examples-errors-agi-potential).
Having swallowed whole the open-source data, machine-learning models like Codex calculate what the next word should be in any given sentence. It is strictly an exercise in statistical [pattern matching](https://www.wired.com/story/github-commercial-ai-tool-built-open-source-code/) with an AI system analyzing the existing code to come up with the most suitable code patterns.
However, Codex differs from its predecessor with its bigger memory, which helps it handle tasks that GPT-3 could not. Codex can work on a dozen programming languages and even understand commands given in daily spoken English. The platform understands [metaphors or nuanced expressions](https://towardsdatascience.com/heres-how-openai-codex-will-revolutionize-programming-and-the-world-e8432aafc5f7) and can still carry out the tasks despite the ambiguity involved in the commands. Putting aside what this all means for the future of software engineering, it undoubtedly makes for impressive demos. Check [this](https://www.youtube.com/watch?v=-Dpl2awseZU) out.
## **GitHub Copilot**
GitHub Copilot is another AI-based programming assistant trained in open-source code. It is fluent in programming languages such as [Python, JavaScript, TypeScript, and Ruby.](https://www.sitepoint.com/github-copilot-ai-pair-programming/)
Copilot is powered by OpenAI's Codex machine learning model. For now, Copilot is limited to being a coding assistant that autocompletes lines of code on Visual Studio Code. However, it [won't be of much help on a new platform](https://copilot.github.com/) where it cannot learn from past patterns of code.
[A study conducted at New York University](https://analyticsindiamag.com/bugs-software-no-code-ai-platfrom-copilot/) illustrated this path-dependency problem of AI-assisted code generation. In the study, when GitHub Copilot was given an intentionally compromised code as an initial scenario to work with, it generated code containing some form of weakness or vulnerability almost half the time. Therefore, Copilot's success depends on two factors:
+ The previously written code in the project it will work on,
+ The code quality of the open-source repository it will use as training data.
Copilot set out to reduce manual work for professional coders and lower the entry barriers for people from non-technical backgrounds Nevertheless, question marks about its true value as an AI-based assistant still remain. It may at times provide broken code or code that is hard to understand. Moreover, the code suggested by Copilot may actually slow down coders as they have to weigh different suggestions while they write code. These two problems dent Copilot's reputation as the next big technological breakthrough.
## **Ethical concerns**
Apart from initial shortcomings, which may be fixed really soon, the real hurdle in front of these AI pair programming tools will likely be ethical rather than technical.
These machine learning models train on open-source code scraped from well-known code repositories for the profit of corporate organizations. This fact is bound to rub some members of the coding community the wrong way. Although GitHub describes its use of publicly available code as "fair use," [not many people agree.](https://www.wired.com/story/github-commercial-ai-tool-built-open-source-code/) Combined with the verbatim copying of pieces of code in some instances, this practice fuels the debate over code ownership: Who owns the code? The person who first wrote it and put it out there for public use? The AI coding assistant that changed it and suggested it to a customer? Or the customer who paid for the services of platforms like Codex or Copilot?
Another problem with AI pair programming tools involves the unfiltered nature of the outputs that can be considered [biased, discriminatory, and offensive](https://onezero.medium.com/for-some-reason-im-covered-in-blood-gpt-3-contains-disturbing-bias-against-muslims-693d275552bf) against some cultures, communities, or religions. This problem stems from the way these platforms learn from what is available on the internet. Machine learning models owe their [scalability](https://www.theverge.com/21346343/gpt-3-explainer-openai-examples-errors-agi-potential) to the lack of human intervention. Without any human intervention, it is only natural that they will spit out stuff closely resembling what is out there on the internet. "*Garbage in, garbage out,*" as they say. Wary of getting drawn into a scandal, executives of both [GPT-3](https://github.com/openai/gpt-3/blob/master/model-card.md) and [Copilot](https://copilot.github.com/#faq-does-github-copilot-produce-offensive-outputs) have already vowed to take the necessary steps to eliminate this kind of output.
## **Glimpses of a future collaboration**
The rise of AI-based programming assistants corresponds to a particular point in the evolution of software. The outputs these tools produce as of now are still for coders only, who can use AI pair programming tools for fine-tuning the code they write. But, it is too risky to put to use AI-generated code without some sort of human review.
[Some experts](https://www.channelasia.tech/article/691087/how-low-code-platforms-enable-machine-learning/) have a different take on the issue, though. They regard no-code as the only solution capable of bridging the gap between the number of data scientists experienced in machine learning models and the growing demand for the services of these professionals. These people will leverage no-code technology to expand the reach of machine learning in the business environment, similar to how "[citizen developers](https://quandarycg.com/citizen-developer-pros-cons/)" use no-code tools to build internal tools.
The next real breakthrough in the evolution of software will take place when AI-based tools become ready to produce outputs in the form of blocks of code that can be dragged and dropped in a no-code framework, catering to the needs of people with no knowledge of coding. These AI pair programming assistants will then truly become force multipliers as they will be capable of producing code for a citizen developer, who would otherwise have to depend on a coder.
With the introduction of AI-assisted no-code platforms, it is not difficult to see developers assuming more responsibility as [designers](https://www.forbes.com/sites/nishatalagala/2021/08/21/will-ai-make-coding-obsolete/?sh=6fc60cf81049) or system architects. As they will have more time on their hands, developers will be able to tackle more strategic matters like system complexity, functionality, and ethical concerns that will definitely require more attention in the future.
--- START: blog/ai-power-of-data/ai-power-of-data.md ---
# **How AI Improves Data Quality**
ChatGPT's fast rise to popularity in December 2022 once again brought the potential of artificial intelligence (AI) under the spotlight. Using AI for a chatbot proved a lot of fun and also provided users with retweetable material for social media, but that couldn't be all there is to AI.
Among the use cases AI is fit for, the ones related to data management and analytics look the most mature, and they are where AI has been making a difference for quite some time. It's now time to ignore the usual infatuation with the shiny new toy and look at what AI can do for us on a consistent basis.
## **Improving data quality**
Data quality has become part of the corporate agenda in recent years as companies have come to appreciate the value of being data-driven. Data quality has [six dimensions](/blog/data-quality-dimensions/) (accuracy, completeness, consistency, validity, timeliness, and uniqueness), and ensuring that the data possesses all these six attributes takes a company-wide data governance policy.
Finding out whether data stored in different repositories are consistent with each other, presented in a valid format, or contain the required information can be a labor-intensive task. That's why you won't find many people volunteering for such jobs at your company. However, organizations cannot afford to ignore data quality problems just because they are difficult to tackle. Not doing anything about data quality problems [may cost 100X](https://www.makingstrategyhappen.com/the-cost-of-quality-the-1-10-100-rule/) as much as taking action to ensure data quality before problems arise. To make matters worse, this figure does not include the damage your reputation already suffers and the cost incurred from the wrong decisions made. Gartner claims that poor data quality costs an organization [$12.9 million on average](https://www.gartner.com/smarterwithgartner/how-to-improve-your-data-quality), which is no small sum.
Organizations conduct [data cleansing](https://www.techtarget.com/searchdatamanagement/definition/data-scrubbing) to fix errors, remove duplicates, and fill in the missing data points. Considering the amount of data organizations have to deal with today, it is a tall order to expect employees to manually take care of data cleansing. AI technology is tailor-made for this use case. Data creates patterns as it accumulates. Being notoriously good at pattern recognition, AI can be used to [identify anomalies](https://xperra.com/solutions/data-cleaning.html) and correct data points that do not fit with the rest of a data set. Using AI to take care of labor-intensive tasks optimizes resource allocation and frees up engineers and data scientists for work that is better suited to their areas of expertise.
## **Helping weave the data fabric**
Breaking down data silos and creating a unified, single view of data is something every enterprise aspires to do nowadays. One such concept developed to cater to the data integration needs of enterprises is data fabric. [According to Gartner](https://www.gartner.com/smarterwithgartner/data-fabric-architecture-is-key-to-modernizing-data-management-and-integration), data fabric is "*a design concept that serves as an integrated layer (fabric) of data and connecting processes.*" It refers to an end-to-end data management architecture used mostly for [business intelligence or IoT analytics](https://www.tibco.com/reference-center/what-is-data-fabric).
An organization's data is usually scattered over multiple cloud environments, on-premise storage units, IoT devices, and applications. Bringing together this data in a seamless way, forming a unified layer, and continuously updating that layer with new data as it is generated in disparate sources is a huge challenge. An organization has to mobilize all the human and machine capabilities in its toolbox to overcome this challenge.
With the explosive increase in the amount of data that organizations generate every day, handling metadata management has become a task beyond the capabilities of mortal human beings. [Discovering and curating data](https://www.dataversity.net/five-data-and-analytics-trends-what-lies-ahead-in-2023/) can be a tedious process, which AI and ML can help simplify at scale. AI and ML automate the data discovery process and create a kind of [intelligent enterprise data catalog](https://www.aidataanalytics.network/data-science-ai/articles/3-ways-ai-is-changing-data-management) to facilitate the formation of a data fabric. With these two technologies becoming integrated into data ingestion, data processing, and data governance, building a data fabric becomes easier, with less risk of human error in the process.
## **Enhancing predictive analytics**
[Predictive analytics](https://thunderbird.asu.edu/thought-leadership/insights/power-predictive-analytics) is a branch of advanced analytics that leverages data mining, statistical modeling, and machine learning to make predictions about future events. It is widely used by companies to plan ahead to mitigate risks and take advantage of opportunities. The uncertainty caused by the pandemic, supply chain disruptions, and rising energy prices have only served to emphasize the value proposition of this particular branch of analytics.
AI's pattern recognition capability makes it a perfect fit for predictive analytics in inferring the future behavior of people and things by looking at historical and current data. Companies can use predictive analytics to
+ schedule the [maintenance activities](https://www.techtarget.com/searchenterpriseai/feature/Machine-learning-and-predictive-analytics-work-better-together) for machinery;
+ detect [credit risk and fraud](https://www.investopedia.com/terms/p/predictive-analytics.asp#toc-uses-of-predictive-analytics) in banking;
+ [identify dissatisfied customers](https://www.ibm.com/topics/predictive-analytics) who are about to churn in marketing and sales;
+ [optimize inventory levels](https://www.sap.com/insights/what-is-predictive-analytics.html) and [secure on-time deliveries](https://www.forbes.com/sites/forbestechcouncil/2021/08/11/unlocking-the-power-of-predictive-analytics-with-ai) in supply chain management.
Managing uncertainty ranks high on the priority list of decision-makers. Bringing data together does not suffice for these people. They have to turn data into actionable insights and do this in an ever more chaotic world where butterfly effects are in full force. AI looks slated to become the most loyal assistant for decision-makers in the future.
## **Conclusion**
Technologies that do not fit a common, sensible use case are doomed to remain as fads and get phased out in time—just ask Segway. AI has passed that threshold as it already has found productive roles it can play in different industries. The future looks even brighter for AI. Software is taking over our lives, and the number of experts cannot keep up with the demand for engineering and data science talent. AI seems poised to assume a bigger role in these conditions, whether we like it or not.
--- START: blog/ai-ready-data-for-ai-agents/ai-ready-data-for-ai-agents.md ---
# **Clean Data vs. AI-Ready Data: What AI Agents Actually Need**
Before organizations invested seriously in data quality, decisions were being made on records that were duplicated, formatted inconsistently, missing critical values, or just plain wrong. That cleanup was a direct response to a very real problem.
But clean data made an assumption that's worth calling out. The consumer was a human. Human analysts are forgiving consumers. They have institutional memory. They know "revenue" in the finance model excludes refunds processed in the same billing period. And when a column name is ambiguous, they know to ask in the Slack channel before moving forward.
So clean data got optimized for correctness at rest. The "context", whether in the form of an implied business rule or a field name, lived in people's heads, in Confluence, or in Slack channels. This was an acceptable tradeoff, because humans could go find it.
This worked for a long time. Then, the consumer changed. Today, we'll be discussing the shift we've seen in the data world. We'll talk about how AI agents have brought to light a new type of data, AI-Ready Data, and how it is different from clean data. We'll also talk about how teams need to approach this whole new challenge.
## What type of data do AI agents need?
An AI agent is a different kind of consumer. It's stateless at the data layer. Each invocation starts from scratch with no memory of what came before. It generates its own queries from schema names, which means it's making semantic assumptions about what the schema itself provides. Put simply, an AI agent doesn't know what it doesn't know. The failures that follow aren't random. They are a direct result of the given context.
### Why won't clean data work for AI agents?
An agent reading a column named `column_A` won't ask what it means. If the schema has no description attached, the agent infers from context. The produced answer may be syntactically correct, but semantically wrong. From a technical standpoint, a clean value in an under-described column is still an input for an AI agent.
Or think of an agent with access to a data warehouse with the capabilities of answering cross-system questions. If the CRM data, payment data, and product usage data aren't synced in the same ETL (Extract, Transform, Load) window, the answer is partial. By default, we wouldn't know that. The agent doesn't error. It returns an answer. There's no signal that the output is based on an incomplete picture, which is exactly what makes these failures so hard to catch.
### How is AI-ready data different?
AI-ready data carries the context an AI agent needs to operate reliably without a human in the loop. It needs to be self-describing, reachable, fresh, and governed at the point of access.
Clean data solved the problem of wrong values. AI-ready data solves the additional problem of missing context. For AI agents, missing context fails just as badly as a wrong value. Often, it fails even more severely, as the output can be misleading.
## Where most teams get it wrong
When AI fails on data, the instinct is to reach for more infrastructure. Usually, teams try to compensate through one of two ways.
{{ resize_image(path="../static/assets/images/blog-images/mathew/workarounds-limitations.png", width=759, height=400, op='fit_width', alt="a table depicting AI governance challenges and fixes") }}
### Vector databases
[Vector databases](https://www.ibm.com/think/topics/vector-database) are the right tool for semantic retrieval problems. This works for a specific class of use cases, such as call transcripts or support tickets, where meaning is distributed across the text. However, structured questions like "What is the current account balance?" don't fit that model. Forcing it through a vector database gives you worse latency and more hallucinations than a direct structured query would.
### Data warehouses
The other common move is to sync more systems and run ETL pipelines more frequently. The problem here is that every system you copy into a [data warehouse](/blog/data-warehouse-limitations-ai/) becomes stale almost immediately. An agent asking about a customer subscription needs data fresh from the source system. A snapshot of it from 20 hours ago has no value. Going down the data warehouse route typically results in excessive engineering overhead without fixing the core issue. You end up with pipelines on top of pipelines and a data team that spends most of its time trying to keep the whole architecture in sync.
So how should teams actually make data AI-ready?
## What the data layer needs to do differently for AI agents
Data movement as a prerequisite for data access was a reasonable tradeoff when queries came from humans on a predictable schedule. It breaks when agents query live systems at runtime, against operational sources the warehouse has never seen.
The answer is a layer that federates data across sources, such as warehouses and third-party APIs, at query time. Data that needs to be fresh is delivered live, while data that can tolerate a short lag is intelligently cached.
Additionally, AI agents need data to describe themselves. The failure mode from earlier with the generic column name gets solved by attaching meaningful metadata at the query surface the agent queries through. Table descriptions, column definitions, metric logic, and entity relationships all need to live in the query interface.
Governance is another consideration. When an agent queries a warehouse through a service account with broad read permissions, the warehouse only sees the service account. There is no information about which user the agent is actually acting on behalf of. Therefore, the warehouse can't apply row-level constraints as requested by the user. That is why permissions, scoped to the actual user context, should also live in this data layer. Queries should be routed through each source's existing access control plane with the user's credentials.
Finally, the data layer has to absorb change without breaking. Sources and schemas change. AI agents add new tools. In the old model, every upstream change required a downstream pipeline fix before the warehouse was usable again. A query-time layer like the one we are describing is inherently less brittle because it doesn't require rebuilding a transformation pipeline every time a source evolves. Schema contracts and versioning can be enforced at the query surface, so that breaking changes (e.g., a renamed column) are caught before they reach the agent.
This is all one coherent design with a dynamic layer that sits on top of existing infrastructure, consolidating data and giving AI agents the right conditions to work. That's the architecture Peaka is built around.
## Final thoughts
The transition to AI-ready data is more than just adding warehouses or running the existing ETL pipelines faster. The challenge is an architectural one. The standard isn't just clean data anymore. Now, data must have the right context, freshness, governance, and stability present at the query surface.
Meeting that standard is harder. But the teams that do won't just have better AI; they'll have a data layer that keeps up with whatever comes next.
If you’re looking to make your data AI-ready with built-in data governance, [book a demo](https://calendly.com/peaka/demo) with Peaka.
--- START: blog/airbyte-embedded-vs-embedded-peaka/airbyte-embedded-vs-embedded-peaka.md ---
# **Airbyte vs. Peaka: Embedded Analytics Platforms Compared**
As the demand for in-product analytics rises, SaaS teams can no longer see customer-facing analytics as a “nice-to-have.” It has become a source of competitive edge thanks to the enhanced product stickiness and customer retention it can provide.
Two contenders that often come up in the conversation are Embedded Peaka and Airbyte Embedded. While both offer ways to connect to external data sources, the difference lies in how much of the integration stack they cover and how much burden they place on your engineering team.
Here is the breakdown:
## **1. Built for embedding, not just syncing**
Embedded Peaka is purpose-built for embedding governed, query-ready data directly into your SaaS product. Unlike Airbyte Embedded, which is an extension of a data sync tool, Peaka provides a full-stack solution: from connector infrastructure and SQL querying to UI components and multitenant governance.
| Feature | Embedded Peaka | Airbyte Embedded |
| :--------------------- | :------------------------------------- | :------------------------------------ |
| **Deployment Mode** | ✅ Purpose-built for embedding | 🟡 Limited support via Embedded Cloud |
| **UI Components** | ✅ Dialogs, query editor, autocomplete | 🟡 Basic iFrame UI |
| **Branding & Theming** | ✅ Full white-labeling | ❌ None |
### **What this means for you**
Embedded Peaka reduces your need for frontend, backend, and infra work, so you can deliver a branded, seamless data experience inside your app faster with fewer dependencies.
## **2. Query-ready and without replication headaches**
Airbyte Embedded requires you to replicate data to a destination like Snowflake or BigQuery before it can be queried. Adding a data warehouse to your stack introduces latency, cost, and governance headaches.
Embedded Peaka skips that step by offering **live federated queries** and **smart caching** out of the box, so you can access live customer data without heavy infrastructure.
| Feature | Embedded Peaka | Airbyte Embedded |
| :----------------------- | :--------------------------------------------------- | :--------------------------------- |
| **Data Access Model** | ✅ Live querying (no replication) | ❌ Requires replication |
| **Query Engine** | ✅ Built-in (Trino-based) | ❌ No query engine |
| **Caching & Rate Limit Handling** | ✅ Rate limit-aware caching built-in | 🟡 Basic retry logic |
### **What this means for you**
You eliminate data warehouse dependency and still deliver real-time insights that your customers love.
## **3. No dev bottlenecks: Embedded Peaka handles OAuth, multitenancy, and governance**
Airbyte may help you connect to external sources, but it stops there. Peaka goes beyond conventional data integration by handling
- OAuth workflows (hosted or BYO)
- Schema isolation across tenants
- Row-, column-, and role-based access control
- Fully managed connector lifecycle
| Feature | Embedded Peaka | Airbyte Embedded |
| :----------------------- | :--------------------------------------- | :--------------------------------------------- |
| **OAuth** | ✅ Built-in, multitenant aware | 🟡 Limited (BYO or via proxy) |
| **Multitenant Support** | ✅ Native support | 🟡 Basic configuration only |
| **Connector Maintenance** | ✅ Peaka-managed | ✅ Managed in Airbyte Cloud |
### **What this means for you**
Faster iteration and creating more value instead of trying to reinvent the wheel.
## **4. Built to maintain product velocity**
While Airbyte helps engineers sync data, Embedded Peaka helps product teams **ship usable features.** Whether you’re launching a self-service reporting module, adding AI-driven analytics, or integrating campaign dashboards, Peaka gives you:
- Connectors for 300+ tools (Stripe, HubSpot, Zendesk, etc.)
- UI + backend packaged in one deployable solution
- Modern SDKs (JS, Python, Java) and API access
### **What this means for you**
You get the flexibility of deploying Embedded Peaka as either a headless data backend or an end-to-end data management + UI solution.
## **Key takeaways**
+ **Airbyte Embedded handles data integration**, but lacks a query engine, UI components, or multitenant governance for in-product analytics.
+ **Embedded Peaka is a full embedded analytics platform**, offering connectors, federated SQL, smart caching, and customizable UI out of the box.
+ **Embedded Peaka supports live querying without replication**, while Airbyte requires syncing data to a warehouse before it’s usable.
+ **SaaS teams ship faster with Embedded Peaka**, eliminating the need to build OAuth flows, dashboards, or access control systems from scratch.
## **Conclusion: Embedded Peaka reduces complexity and lets you ship faster**
If your goal is to build a reliable, scalable, and branded customer analytics experience, Airbyte is just the beginning of the stack. Embedded Peaka, however, is _the_ stack.
Peaka isn’t just a connector platform; it’s your embedded data delivery engine, complete with live queries, UI components, OAuth, and tenant-level controls.
Try [Embedded Peaka](/embedded-peaka/) or [book a demo](https://calendly.com/peaka/demo) to talk to our team about your use case.
Evaluating embedded analytics platforms?
Make sure to read our blog posts discussing how Embedded Peaka stacks up against other popular platforms in the market:
+ [Embedded Peaka vs. Cdata](/blog/cdata-vs-embedded-peaka)
+ [Embedded Peaka vs. Merge.dev](/blog/merge-vs-embedded-peaka)
+ [Embedded Peaka vs. Hevo Data](/blog/hevo-vs-peaka-comparison/)
+ [Embedded Peaka vs. Polytomic](/blog/polytomic-vs-embedded-peaka)
--- START: blog/angel-investors-advice-founders/angel-investors-advice-founders.md ---
# **Sage Advice from Angel Investors to Founders**
Fundraising is one of the most challenging endeavors a founder can engage in. Meeting wealthy strangers and trying to impress them with a pitch deck so they will willingly part with hundreds of thousands or millions of dollars is a tall order. So many things can go wrong, and the chances are that the founder will leave a meeting empty-handed.
As a founder, it may be your first time talking to an angel investor, but that probably isn't the case for your incumbents. Talking to thousands of founders every year and trying to spot the best deals, angel investors have developed rules of thumb to screen projects. The product you are building, the kind of founder you are, and how you execute all tell investors something about you.
## **Product—Half-baked solutions for real problems**
For most angel investors, real problems take precedence over big ideas. If nothing else, products based on real problems are easier to pitch. Such products also tend to gain traction more quickly. You don't have to educate people about their benefits because the need is already there.
[Pejman Nozad](https://www.linkedin.com/in/pejman/), who was named one of the most successful angel investors by Forbes in 2012, likes to see [a personal history between a founder and the problem](https://www.youtube.com/watch?v=VThN7kpjRpM) she is trying to solve. Nozad argues that a genuine connection like that can produce a compelling product. His insight ties in well with comments from [Elad Gil](https://www.linkedin.com/in/eladgil/), who found success in investing in companies like Airbnb, Stripe, and Coinbase. For Gil, the fact that the founder is using her own product and that people are paying to use it are good indicators of future success.
[Kevin Hale](https://www.crunchbase.com/person/kevin-hale), previously of Wufoo fame, goes one step further and defines the [characteristics of the problem](https://www.youtube.com/watch?v=DOtCl5PU8F0) in detail. Your product has the potential to be great if it is based on a problem that is urgent and expensive to solve. If the problem is happening frequently, it gives you a better chance to convert. If the problem results from regulatory and legislative changes, all the better for a startup because that forces people to make mandatory adjustments. The demand will be less flexible in this case, improving the startup’s odds of success. These characteristics combine to create such a pressing need and make people so desperate that they can settle for what [Michael Seibel](https://www.linkedin.com/in/mwseibel/) calls "[half-baked ideas.](https://www.youtube.com/watch?v=ugmjf0fJY84)"
## **Founder–A drive to excel and expertise to match it**
Angel investing is, in a sense, a challenge to find the right people to invest in. A great founder is someone who can build the right kind of team to build the right products for the right market segment. Great angel investors recognize that investing in good founders is more important than investing in bright ideas.
The startup literature puts so much emphasis on the product-market fit that founders have become obsessed with the term. But a similar concept, founder-market fit, has lacked the same level of attention. Angel investors find it important that a founder has prior experience in an industry related to the one he plans to disrupt. If that's not the case, he should at least demonstrate a satisfactory level of subject-matter expertise on the problem he is trying to solve.
Most founders lack the financial data to convince investors to back their projects. That's why investors like [Dalton Caldwell](https://www.linkedin.com/in/daltoncaldwell/) of Y Combinator look for [technical excellence](https://techcrunch.com/2022/04/27/how-to-get-into-y-combinator-dalton-caldwell/) in a new applicant. All of a sudden, the applicant's work experience and subject-matter expertise become the most significant indicators of the product's future success.
In addition to a resume rich with proofs of related work experience, there are other signs of a strong founder-market fit that angel investors would like to see in a founder. One is an obsession with the problem at hand and doing whatever it takes (hiring the best team, studying new approaches to the problem) to solve it. Another is the determination in the face of setbacks and inspiring the team to soldier on. Being a fast learner and a good salesman capable of telling a good story about the mission are other qualities that raise a founder's profile in the eyes of an investor.
## **Execution—"You cannot build a big company by procrastinating"**
Startups are built to grow fast. "If they are not growing fast, they are just small businesses," says Kevin Hale. Angel investors appreciate startups that act fast and with urgency. Complacency after a raised round or failure to take action to course-correct when things are not going well does not help instill confidence in them. The investment guru Ron Conway thinks it is [better to take action](https://www.youtube.com/watch?v=bgwqM6J3WeM) and make mistakes than sit on your hands doing nothing:
> "*You cannot build a big company by procrastinating. You gotta make decisions–even if that means making a mistake–and move the ship forward.*"
What can you do as a founder to earn angel investors' trust? Prove that your team learns fast, engage in serious research whenever you determine some knowledge deficit, and keep testing hypotheses and building. Be restless. Leave no stones unturned until you achieve perfection.
## **Final thoughts**
Fundraising will always remain more of an art than a science. It is a process whereby everything about a founder, his background, idea, and team should come together to dazzle the people ready to write a hefty cheque. The advice angel investors give founders is as close to a blueprint for success as it gets. Founders would be well-advised to heed it.
--- START: blog/angel-investors-algorithm/angel-investors-algorithm.md ---
# **What is Algorithm-based Investing?**
It is no secret that elite angel investors chase statistical outliers. They are after those home runs that will become unicorns, generate an outsized return on investment, and make up for all the money lost on other startups in the portfolio that flamed out. No one, not even the angel investor himself, will remember the failed projects that never panned out, but everyone will be talking about the one or two startups that shot up through the roof in valuation.
Not many angel investors can find those home runs on a consistent basis, though. Those with a string of successful investments in their resumes describe their secret to success as a curious blend of gut feeling, lessons learned, and a healthy dose of risk tolerance. That's hardly a formula you can copy.
Like all of us, angel investors are limited by the amount of information they can digest and cognitive biases that can influence their decisions. But what if we outsourced investment decisions to artificial intelligence (AI)? Can technology offer help in devising a repeatable strategy to discover the best startups at an early stage? Should we do away with the old way of investment and turn to artificial intelligence and machine learning (ML) instead?
## **Cognitive biases: Enemies of rational thinking**
The proponents of algorithm-based investing emphasize how this method can help eliminate cognitive biases in order to justify its use. Angel investors, especially the inexperienced ones, are particularly prone to [three common biases:](https://journals.sagepub.com/doi/full/10.1177/1042258720945206)
+ **Local bias:** Investors tend to mistrust and stay away from opportunities distant from their own environment due to the lack of information.
+ **Overconfidence:** Inexperienced angel investors tend to overestimate their knowledge and investment skills, trusting in their foresight in the face of a major decision. This assumption makes them ignore some of the available information, which undermines the quality of their decisions.
+ **Loss aversion:** While experienced angel investors see losing money as part of the game and chase home runs, inexperienced ones are more sensitive to potential losses. Worried that they have limited funds, these people tend to shun counterintuitive ideas. As a result, they miss out on some truly transformative ideas, which usually look counterintuitive at first.
## **ML to the rescue**
An ML algorithm is immune to cognitive biases and can make objective decisions while evaluating investment opportunities. This bias-free approach easily outperforms inexperienced angel investors hampered by cognitive biases.
> *[According to a study](https://hbr.org/2020/11/do-algorithms-make-better-and-fairer-investments-than-angel-investors) researchers at the University of St. Gallen (Switzerland) conducted among 255 angel investors, the ML algorithm generated an internal rate of return (IRR) of 7.26 percent, while angel investors with higher levels of bias lost money at an IRR of -20.52 percent.*
> *On the other hand, experienced angel investors, with an average IRR of 22.75 percent, proved more successful than the algorithm by a wide margin.*
The key to leveraging ML for high-return investments is to find metrics that best predict startup success. AngelList has been one of the pioneers in this area, putting theory into practice and focusing on job applications a company receives in a quarter as their magic metric to track. The platform's job market arm, AngelList Talent, is used by around 2 million users every month. The AngelList team [vets 35,000 companies](https://techcrunch.com/2021/12/22/angellist-just-closed-a-25m-fund-to-back-startups-based-on-hiring-velocity/) seeking talent every quarter and narrows them down to half that number. Then, they reach out to 20 companies that are most popular with job seekers.
Abraham Othman, head of the investment committee and data science at AngelList Venture, believes that there is a correlation between hiring interest and company valuation and sounds confident in his company's investment model. Othman is particularly impressed by how the algorithm can cut through the noise like pitch deck clichés and investor bias and give the less-represented social groups a better chance to raise money.
However, in this specific case, the method's validity seems debatable at best. A company is rarely in complete control of the hiring demand it is receiving. Pay your employees more, and you will see more people willing to work for you, regardless of the potential of your product or idea. Or, if the rents are out of control in a particular location, companies located in places with similar living standards but lower rents will see a hike in demand, which has nothing to do with a startup's future potential. Scenarios like these cast some doubt on the method's viability, especially for angel investors chasing the next big idea.
## **The downsides of using ML in investment**
The limitations of algorithm-based investing are not metric-specific but rather structural. What comes out of AI is dependent on what you feed in. AI is good at pattern recognition, and it will get better at a task as it gets to train on bigger data sets. However, no matter how much data you feed into a computer, it will never be able to spot something like ingenuity or determination. Thus, there is no way for the computer to factor into equation parameters like the founders, their experience and determination, the team composition, etc.
The founder is the single most crucial factor for an angel investor to consider during an investment decision. The pitched idea may not look realistic at all, or the market may be nonexistent. But a founder who sounds like he has a plan and demonstrates the will to overcome everything to realize his dreams can tip the scales in his favor. Elite angel investors would not want to give up a chance to connect with such special people for the safe bets an ML algorithm would offer them.
## **Final thoughts**
So, where does that leave us? The Harvard Business Review study above argues that there is room for algorithm-based investment. The algorithm beats novice investors handily, but it is no match for elite angel investors. Therefore, training the ML on data based on investment decisions made by elite angel investors will make it sharper. This more advanced AI can, in turn, be deployed to help novice angel investors and shield them from cognitive biases that affect the inexperienced the most.
However, the weight of intangibles in successful entrepreneurship ensures that ML can only play a complementary role in investing. The ability to compose rules from patches of data is what sets elite angel investors apart from the rest. ML may guarantee mediocre results, but would Ron Conways and Sam Altmans of the world be content with mediocrity? Not likely.
--- START: blog/angel-investors-challenges/angel-investors-challenges.md ---
# **Angel Investing: The Challenges Ahead**
We live in "[interesting times](https://en.wikipedia.org/wiki/May_you_live_in_interesting_times)" for sure, like in the alleged curse attributed to the Chinese. Nobody knows which gods we managed to piss off, but fresh out of a once-in-a-century pandemic, we stumbled into a European war. Supply chains look all messed up and energy prices keep rising, which create enormous problems and uncertainty for every economic actor.
The global inflation and the Federal Reserve rate hikes implemented to deal with it impact everybody, even the florist in the corner on your street. Amidst all this, angel investing is facing a unique set of challenges. How angel investors tackle these problems will not only define angel investing for years to come but have a bearing on the startup ecosystem, too.
## **Changing demographics**
A new breed of angel investors is filling up the ranks nowadays. These newcomers are entrepreneurs who previously led startups to successful exits and decided to try a new role in the ecosystem. These tech entrepreneurs are aged [40 to 45](https://www.youtube.com/watch?v=OkOqTkNKT8k)—twenty years younger than the dominant group of investors up to this point. They are more technically aware, which is a blessing for the startups they will invest in and the founders they will mentor.
However, they are also used to a more hands-on approach, having taken their startups from zero to one with a small team and hard work. The transition from a successful career as a founder to an angel investor role takes a mental shift. It is like a world rally champion retiring from the sport and then trying his luck as a co-driver to an up-and-coming driver. The fact that you are no longer running the show but providing help might be challenging to accept for some. Luckily, as Y Combinator partners illustrate, founder-turned-angel investors are smart enough to recognize what their new roles demand and adapt accordingly.
## **How to combine technology with intuition**
In their book, [*Play Bigger*](https://www.amazon.com/Play-Bigger-Dreamers-Innovators-Dominate/dp/0062407619), Christopher Lochhead and his friends estimate that the cost of developing and launching a software product fell by 100 percent or more between 1990 and 2015. The emergence of cloud computing played a big part in this reduction. This new technology leveled the playing field for every company, enabling startups to enjoy similar cost structures to enterprises without the scale. Andrew Jassy led AWS's pioneering efforts in taking this particular technology to the masses. He has been quoted many times summarizing his [vision](https://www.wsj.com/articles/who-is-andy-jassy-jeff-bezos-acolyte-moves-from-cloud-to-amazon-ceo-11612309443) when he started AWS:
> "*Any individual in his or her own garage or dorm room could have access to the same cost structure and scalability and infrastructure as the largest companies in the world.*"
Cloud computing achieved this vision, allowing people to develop software products from scratch and be competitive right out of the gate. The result was a never-seen-before proliferation of startups, making sourcing and screening investment opportunities much more difficult for anybody willing to invest.
Harnessing the power of artificial intelligence (AI) and machine learning (ML) can solve the problem of vetting all these investment opportunities. ML-based algorithms may have failed to attract much attention from elite angel investors due to their inability to help with evaluating the intangibles of a founder and his team. But the enhanced computing power they bring to the table can take care of much of the heavy lifting in gauging the potential of startups.
Sam Altman [believes](https://www.youtube.com/watch?v=s-4QqHHE16s) the days of investor leverage against founders are over. It's a founders' world now, and angel investors need all the help they can get to identify successful startups as soon as these companies start their journey. In the future, success in angel investing will be defined by execution speed. Taking too long to pull the trigger on a deal pushes founders away and damages an investor's reputation, translating into less business in the future. Only investors quickly spotting and getting in contact with founders and closing deals without wasting time will get the first dibs on the best startups.
There is a place for ML in this race against time. ML can be trained to [crawl the web pages and social media accounts](https://medium.com/birds-view/the-future-of-vc-augmenting-humans-with-ai-30f1d79a09c3) of startups, tracking metrics like team size or social media activity. Once ML filters the list of startups and narrows it down to a handful of companies with meaningful improvement in the selected metrics, it's time for angel investors to shine. With the tedious part of the job out of the way, they can now apply judgment and gut feeling to pick the best ones.
It works just as well with recruitment, too. [Beril](https://www.linkedin.com/in/berilkarabulut/), our talented and super-entrepreneurial Senior Product Designer, knows a thing or two about this, as she previously co-founded a platform bringing together angel investors and startups. Beril likens ML's potential role in angel investing to an "HR module for angel investors." For example, do you need a CTO who led a biotech startup in the past before he ran out of money? ML has you covered. Define the parameters, and ML will prepare a shortlist of suitable candidates that fit the bill for you.
## **The need to look for new horizons**
As the investment scene in the U.S. and Europe matures, the competition among angel investors to spot promising startups intensifies. All that screening and due diligence go to waste when an angel investor fails to close a deal in the face of competition from other angel investors. We previously [touched upon](/blog/angel-investors-algorithm/) how local bias influences angel investors intimidated by the lack of information regarding startups in distant locations and cause them to invest in local startups. However, the tight investment market and the ever-rising startup valuations make it necessary for angel investors to strongly consider other markets with hidden gems.
### **India**
India currently ranks third among the largest startup ecosystems, right behind the U.S. and China, and enjoys a predicted year-on-year growth rate of [12-15 percent](https://economictimes.indiatimes.com/small-biz/sme-sector/how-tech-startups-are-boosting-the-growth-of-small-e-commerce-businesses-in-india/articleshow/91703404.cms). The total number of registered startups in the country stands at [61,400](https://www.salesforce.com/in/blog/2022/09/indian-startup-ecosystem-growth-mindset-salesforce-startup-program.html). As of September 2022, the country is home to [107 unicorns](https://www.livemint.com/opinion/online-views/indias-startup-ecosystem-should-adapt-to-tight-money-conditions-11663520006918.html) with a total valuation of $340.79 billion, 44 of them joining the list in 2021.
The Indian startup ecosystem looks enticing, with immense potential for growth, particularly in the e-commerce, fintech, and SaaS segments. The increasing penetration of internet technologies helps unlock this potential. Indian startups achieved a compound annual growth rate of [49 percent](https://inc42.com/reports/the-state-of-indian-startup-ecosystem-report-2022) from 2014 to 2021, more than four times what Chinese startups managed. These figures remind angel investors that getting priced out of the U.S. market for early-stage startups can be a blessing in disguise if they have prospects lined up in India.
### **Africa**
The African startup market accounts for only 0.2 percent of the $3.8-trillion global startup market. African startups raised just [$1.1 billion](https://startupgenome.com/reports/gser2021) in 2020. Numbers look modest, to say the least. However, it is the growth trajectory that is intriguing: The amount of funding raised in Africa in 2020 was more than twice the number in 2019, and it more than quadrupled in a year, reaching [$4.9 billion](https://institute.global/policy/supercharging-africas-startups-continents-path-tech-excellence) in 2021. The continent is experiencing a boom in population, and mobile phone and internet penetration are on the rise. The stage is set for exciting developments in the startup market.
The most successful African startups are in the fintech segment, taking financial services to the unbanked masses. As of 2021, there were [four African unicorns](https://www.statista.com/statistics/1250055/african-unicorn-startups-by-country/), three of which were fintech companies. The average startup size still remains small, though. While the median seed round is worth [$2,882,000 in the U.S.](https://founderfridays.substack.com/p/funding-fridays-no-17), it is worth around [$140,000 in Cape Town](https://startupgenome.com/reports/gser2021), South Africa, arguably the most startup-friendly city on the continent. Angel investors finding it hard to compete in the U.S. would face better odds in Cape Town, Lagos, or Johannesburg. However, there is still much to be done on the bureaucratic side of things. African governments should improve the existing legislation and introduce regulatory frameworks to create an environment favorable to startup growth and build trust with investors.
Venturing into a different continent is a daring act for anyone, local bias or not. To mitigate the risks, angel investors willing to explore new markets would be well-advised to get in touch with local [business angel networks](https://blog.dealum.com/angel-investing-future/). Networks provide foreign angel investors with local partners who know the lay of the land. They help foreign investors overcome the information asymmetry, source good startups worthy of investment, and vet them, increasing their odds of success. Angel investors need reliable and fast procedures to do business in uncharted territory, and these networks, with their accumulated know-how, can fill the need.
## **Conclusion**
The challenges awaiting angel investing are no joke. But they also present opportunities for people who can conquer them.
A new generation of angel investors will inject new blood into the system and bring fresh insights with them. Harnessing AI and ML will help angel investors cast a wider net and make better investment decisions. The investment scene in the U.S. is more competitive than ever, but the developing startup ecosystems in India and Africa offer angel investors opportunities at more affordable valuations than Silicon Valley. Once overcome, these three challenges can catapult angel investing to another level.
--- START: blog/angel-investors-philanthropy/angel-investors-philanthropy.md ---
# **Angel Investors: Philanthropy à la Silicon Valley**
Institutional investors like venture capital (VC) firms have been the dominant players on the investment scene for years. While VC firms usually invest in post-revenue startups, angel investors have carved out a niche for themselves by focusing on early-stage startups. Who are these people? What motivates them to put money into risky projects?
[Angel investors](https://www.investopedia.com/terms/a/angelinvestor.asp) are people with a high net worth who look to invest in startups and early-stage companies. These people seek deals to secure them a stake in startups that can pan out in the future and generate a payoff much higher than what other investment opportunities can provide. The angel investor-founder relationship is a symbiotic one. While the former looks to make outsized gains on a relatively small investment, the latter gains access to funds that would otherwise not be available to a startup, as banks are unwilling to lend to companies without assets or inventory.
Here are three reasons why angel investors do what they do:
## **The promise of high ROI**
Entrepreneurship is risky business. IT startups face an even higher risk, as documented by [Failory](https://www.failory.com/blog/startup-failure-rate): 63 percent of IT startups fail. Therefore, an angel investor putting money into a startup is undertaking quite a risk of losing all that money. That’s why founders willing to attract investors are willing to part with around 20 percent of their equity because that’s what it takes to convince an angel investor to put money into a high-risk business.
Despite this massive risk of failure, angel investors are still lining up to invest in startups at an even higher rate than before. Why? Because of the Power Law. Investors believe that a handful of investments will generate the most returns and more than make up for loss-generating others. These people are looking to score a home run: One investment that will turn into a billion-dollar company and save the whole portfolio. A startup making an exit can create a 10X or 50X return for an investor, which is far more than can be expected from other investment opportunities.
Airbnb, for example, raised a seed round in 2009 at a [$2.4 million](https://en.wikipedia.org/wiki/Timeline_of_Airbnb) valuation. At the time of its IPO in 2020, the company was valued at $47 billion, translating into a 20,000X return on investment (ROI). Peter Thiel invested half a million dollars in Facebook and made around $1.1 billion from this investment at a [2,220X return.](https://www.angellist.com/blog/what-angellist-data-says-about-power-law-returns-in-venture-capital) Such success stories have become part of the Silicon Valley culture, and Power Law has become ingrained in the thought process of tech investors.
## **A chance to remain engaged**
Most angel investors are former founders themselves. Having achieved success and earned considerable sums, they see angel investing as a way to remain a part of the startup ecosystem. Some are addicted to the thrill of building a product from scratch and turning it into a competitive product. Becoming an angel investor gives these people a taste of that competitive environment once again, this time without the immense pressure of being a founder.
Talking to founders, learning about bright ideas and the challenges they face, mentoring them, and seeing them succeed can be a source of satisfaction for even millionaires. That’s part of why tech leaders like Sam Altman, Peter Thiel, and Michael Seibel participate in accelerators and angel investment funds.
In addition to the capital they invest, angel investors can make an impact on the prospects of startups through two qualities they bring to the table:
### **Experience**
An angel investor with experience in a related industry can be a true asset to a startup. Capital, although crucial for a startup, can be raised from family and friends. Later on, when financials appear, banks can be enlisted for loans. But a mentor who can extend a helping hand during the growing pains of a startup is not easy to find. Someone who has done it before, made mistakes, and learned from them can provide the founders with much-needed guidance.
Founders have so many responsibilities in product development, evangelizing, customer support, hiring, and so forth that they may have trouble putting it all together. Angel investors can help founders with strategic problems like the market analysis. They can also offer guidance in tactical matters regarding execution, helping steer the startup in the right direction at critical times.
### **Connections**
Startups rely on their local means and resources in a fight against global competition. What can elevate them and let them tap into resources that otherwise wouldn’t be available to them is a group of well-connected investors. These connections are sure to broaden the horizons of founders and benefit them in multiple ways:
+ Founders may leverage the angel investor’s phonebook to talk to top people to sort out technical hurdles.
+ Angel investors can boost recruitment efforts, helping founders reach out to talent and pick the best among them.
+ Angel investors can lay the foundations for future fundraising efforts. Developing relations with prospective investors and nurturing those relations pay off when the time comes to raise money another time.
## **Giving back to the community**
Why do people want to write cheques for companies with a small chance of panning out? Michael Seibel thinks of it as a form of “[charity.](https://www.youtube.com/watch?v=ugmjf0fJY84)” *Charity à la Silicon Valley*.
When people finally make it and turn their dreams into hefty deposits in their bank accounts, they want to do good. Some give back to the community they hailed from; others donate to NGOs pursuing certain causes, and some set up funds to ensure that their good deeds will last. These actions are good for your conscience, help your brand, and make sense for your future.
Silicon Valley culture glorifies investing in the startups of nobodies with dreams. Instead of helping people, the tech community prioritizes helping people help themselves. Making a few million dollars in the process doesn’t hurt, either. Giving back to the community and nurturing a new generation of tech celebrities can elevate an angel investor to the level of a thought leader people turn to. This philanthropic act involves regularly investing small sums in a large number of startups and also fits in with the principle of diversifying the portfolio to find a home run.
## **Final thoughts**
Angel investors are to the startup ecosystem what bees are to the flora: They promote cross-pollination. By injecting capital where needed and providing wisdom where very little is found, they set startups for success and contribute to upward mobility. What they want to see in founders is another story and deserves a lengthy discussion in another post.
--- START: blog/angel-investors-secret-sauce/angel-investors-secret-sauce.md ---
# **Top Angel Investors Reveal Their Secret Sauce**
Angel investing is a field rife with uncertainty. Writing cheques to literal nobodies with the hope that their startups will flourish someday is risky business. However, some investors seem to get it right, doing significantly better than their peers. What's their secret? Have these people discovered a winning formula that helps them spot the most promising startups?
It turns out that successful angel investors have developed straightforward rules of thumb to inform their decision-making and stuck to them no matter what. Luckily for us, these people are not reluctant to talk about their thought processes, giving us a glimpse into the reasons for their continued success. Here is a look at the three most important parameters high-performing angel investors put a special emphasis on:
## **Market—Look out for a tide that will take you far**
There are several parameters angel investors take into consideration while deciding whether to put money into a project. The founder, his team, and the idea undoubtedly play significant roles in this decision. However, what angel investors care about the most is the market. [Andy Rachleff](https://www.linkedin.com/in/rachleff/), formerly of Benchmark Capital and now the executive chairman of Wealthfront Inc., [sums it up](https://web.stanford.edu/class/ee204/ProductMarketFit.html) the best:
+ When a great team meets a lousy market, the market wins.
+ When a lousy team meets a great market, the market wins.
+ When a great team meets a great market, something special happens.
One of the first questions angel investors ask a founder tends to be the size of the "total addressable market." Founders can earn brownie points if they can provide figures proving that there is a sizable, underserved market when they are asked this question. A startup entering an uncontested market space ("[blue ocean](https://twitter.com/mikebeckhamsm/status/1559010621806485504)") and leveraging a current trend to gain an exceptional boost, just like a surfer catching a wave, is sure to intrigue angel investors.
The reason why angel investors put so much value on the market has to do with Power Law. They are looking for the next iPhone or Zoom, something that will revolutionize an industry, become an integral part of people's lives, and earn its investors an enormous return on investment while most of their portfolio generates losses. Ron Conway predicts the failure rate of angel investors at [40 to 60 percent.](https://www.youtube.com/watch?v=bgwqM6J3WeM) To compensate for that high risk, he chose to invest in internet technology in the early 90s, hoping for growth at thousands of percent a year. Conway always goes for the big hit because once you score it, "*you start playing with house money.*"
This is typical angel investor behavior: Spreading the wealth over a wide range of investments and shooting for a few big hits that can cover the losses in the majority of investments and result in a sizable profit. With the internet and software becoming almost traditional sectors no longer offering the returns they did in the past, angel investors are looking for the next big market. That's why investors like Peter Thiel follow the same pattern, investing in utopian projects in budding sectors like biotech, nanotechnology, space exploration, and robotics.
## **Speed—Be ready to act**
Angel investing is a race against time. An angel investor spends her days meeting founders, listening to pitches, making decisions as to whether to write a cheque, and then moving on to the next project. Repeatable success in this kind of endeavor takes a methodical approach and a lot of preparation to speed up things.
Michael Seibel advises fellow investors to [study prospects beforehand](https://www.youtube.com/watch?v=ugmjf0fJY84) so that they can always be ready and make decisions quicker. As the investments you made a couple of years ago mature and either fail or succeed, you must move forward with new investments that will hopefully pan out in a few years. Therefore, there needs to be a deal flow and a steady supply of projects coming your way so that you won't spend your time looking for new projects. Seibel writes his friends a cheque to create that flow and avoid FOMO (fear of missing out) at the same time. And he is all the more wealthy for it.
FOMO features heavily in Pejman Nozad's thought process, too. That's no surprise considering that the Iranian-born investor missed out on [a chance to invest $50,000](https://www.youtube.com/watch?v=VThN7kpjRpM) in Facebook at around $80 million valuation in July 2005. Nozad passed on the deal because the two sides couldn't agree on the terms of a 5-year lease agreement involving an office Facebook would rent from Nozad's company. Nozad must have had many sleepless nights talking to himself about "*shoulda, woulda, coulda.*" He now believes that an angel investor should go ahead and invest in a deal when he feels it is the right thing to do:
> *"If you met an exceptional outlier, those outliers who are actually from Mars, do not overanalyze the situation. Just get on the rocket ship and go."*
Ali Partovi, who had an enviable track record of investments in Facebook, Dropbox, Airbnb, and Uber, agrees with Nozad's point and [expresses his conviction](https://www.youtube.com/watch?v=-NwcwC3l3uk) in even more serious terms:
> *"When you have a strong intuitive feeling, you should go with it. This industry is not very sympathetic to people who hum and haw and take a long time to make decisions."*
Taking weeks to make decisions hurts your reputation as an investor. It reduces your chance of getting good deals because founders take note when they are taken for a ride.
## **Reputation—Play the long game**
One of the most reliable ways to secure a deal flow, as Michael Seibel suggests, is to ensure that your reputation is untainted. Smart angel investors who realize that they are in this for the long-run act accordingly.
Aaron Harris, an entrepreneur and investor who was a Y Combinator partner for more than seven years, argues that an impeccable reputation is a must for a chance to invest in the hottest startups. Harris draws attention to a virtuous cycle of reputation: A good reputation helps you create a good deal flow, giving you a better chance to invest in better startups, which brings about more success and breeds a better reputation.
Reputation is an investor's scorecard, the end result of all his deeds, good or bad. Building a good reputation requires doing the right thing for a long time, even if that might hurt one's short-term interests. It entails small things like being on time when you meet a founder, or when you reject an entrepreneur, doing it with quality and telling them why, as [Ben Horowitz suggests.](https://www.youtube.com/watch?v=sU7l6se-z1A)
Aaron Harris warns against petty maneuvering in the last phase before a deal. Sometimes angel investors may make outrageous last-minute demands after an agreement is reached. This puts the founders in a dilemma between giving up something they shouldn't be giving up for the sake of getting the deal done or not raising money at all. However, Harris believes the hit an angel investor's reputation suffers from such a move is not worth the tiny gains achieved. Geoff Ralston puts it even more succinctly:
> *"Don't be pennywise and pound foolish."*
Do not take advantage of entrepreneurs. Do the sensible thing and think of your investment as a long-term partnership. Nurture that relationship. Look for ways to contribute by helping the founders hire people to plug in the existing skills gaps, mentoring them in the day-to-day running of operations, and introducing them to other investors.
## **Final thoughts**
The angel investor role is a synthesis of a visionary; a shrewd, hard-working business person; an understanding friend; and a candid mentor. You know the happy-go-lucky angel investor archetype, right? The one that virtually stumbles into good deals and tells funny stories about them later. It could not be further from the truth. Luck may play a role, but it's not any bigger than what Louis Pasteur assigned to it when he said, "*Fortune favors the prepared mind.*" The best angel investors find a way to be prepared at all times.
--- START: blog/angel-investors-startup-success/angel-investors-startup-success.md ---
# **The Angel’s Touch: How Angel Investors Help Startups**
Just as angel investors try to pick the best startups to put their money into, founders should do due diligence to choose the right angel investors for their companies. Because there is more to the founder-angel investor relationship than just wiring money in return for some equity in the company. A good chemistry between those two can improve the prospects of the startup.
Here is a closer look at what angel investors bring to the table:
## **Daily operations**
Running the day-to-day operations of a startup is different from having an idea and building an MVP. The daily tasks related to business, engineering, human resources, accounting, and networking aspects of a startup can be overwhelming for founders. As a founder, you have to make numerous decisions at a frenetic pace and, most of the time, on your own. Some of the decisions may involve major trade-offs; others might be about whether to stay the course or pivot. Sometimes you feel like you are at a fork in the road multiple times a day. That's when having someone you can bounce ideas off comes in handy. An angel investor is the ideal person for that. Just by making himself available for a chat or replying to founder emails without delay, an angel investor might make the decision-making process easier for a founder.
Having a stake in the company and caring about the long-term prospects of their investments, angel investors like to see solid foundations laid down at a startup. Doing this requires getting priorities straight. Prioritization is the name of the game early on in a startup's life. It not only defines how you will allocate your scarce resources but also has a significant impact on the company culture. Actually, culture is, in a sense, what you prioritize at your organization. By coaching founders about which metrics to prioritize and where to channel the limited resources at hand, an angel investor can ensure that the right values will be in place.
## **Leveraging the network**
An angel investor’s phonebook is a bigger asset to a startup than his checkbook can ever be. Money can be raised from friends and family, but you need the right connections to hire the right people, receive good press or talk to the big shots of the industry.
Hiring is one of the trickiest tasks you will have to deal with as a founder: When you will hire or fire people can define the trajectory of your startup. Hire too many people too soon, and the cash burn and HR problems will start threatening your viability. Delay the necessary hiring or firing decisions for too long, and you will find yourself in trouble. Angel investors can help founders with such critical decisions.
Recruitment is a fairly straightforward process in the early stages of a startup. Friends from previous jobs or their friends are natural candidates for job openings at the beginning. But finding the right person to lead a 50-strong engineering team will not be that easy. Very few entrepreneurs have a phonebook containing suitable names to oversee the operations of a company with a multi-million dollar ARR. A well-connected angel investor can make a difference here by tapping into his network to suggest names and even planning a rigorous screening process to pick the best candidates. Startup founders cannot afford to pass on contributions like that.
Another problematic area for founders is distribution. Generating interest in the product, getting good press, connecting with podcast hosts, or even something as simple as distributing an opinion piece on the founder's vision for the industry and the company can be formidable challenges at the outset. Leaning on contacts, an angel investor can grease the wheels and help with product and idea distribution.
Bringing together founders with other entrepreneurs, professionals, and investors is when angel investors truly shine. For example, Ron Conway takes pride in [introducing founders to his contacts](https://www.youtube.com/watch?v=bgwqM6J3WeM) at Apple, Facebook, Twitter, and Google. Having helped these tech giants recruit and take off in their early years, Conway can leverage his relationships with people he placed in those and ask for a favor or two.
## **Delivering the occasional reality check**
What founders lack at an early-stage startup is not somebody they can fool around with and spend some of the money they raised. They don't need more friends as they probably have enough of them. What they truly need is someone—preferably with knowledge about the technical or business side of things—capable of giving them a reality check at times.
It is easy to be complacent as a startup founder. The occasional spike in traction seen from time to time, praise received during a demo, or simply [having raised money](https://www.ycombinator.com/blog/fundraising-rounds-are-not-milestones) can count as success for some founders. The team might be celebrating [nailing the product-market fit when they didn't](https://www.ycombinator.com/blog/the-real-product-market-fit), and somebody has to tell them that it's a false alarm. They could be banking on protection from a moat when there is none. Even worse, problems between the co-founders might be getting out of hand.
When complacency and procrastination set in and problems are left to fester, someone with a stake in the startup has to step in and steer the ship in the right direction. An angel investor can bring up the hard truths the product team tries to avoid. Having been through similar stuff before as an investor and probably a founder, an angel investor can help keep the focus on the big prize. He can drill into a founder that, in order to raise a Series A, a feel-good story or a fancy plan won't be enough to raise a Series A, and tangible results will be needed.
Another common case during a startup's early stages is the panic that begins when the initial plan proves ineffective. A founder's typical reaction in such a situation is to either increase marketing spending or ship new features to make the product more attractive to people. Both these steps are bound to fail: The former will only increase cash burn as the newcomers, too, will churn since marketing doesn't solve what fundamentally is wrong with the product. The latter action will also turn out to be futile because, at that point, you probably don't know who you are building those features for. Developing features for an ambiguous customer persona is a waste of resources.
At moments like these, somebody has to be the voice of reason or the adult in the room, advise against doing the sexy thing, and instead, insist on getting the fundamentals right first. An experienced angel investor knows that the right thing to do when the initial plan fails is to start testing hypotheses until you find the product-market fit.
## **Final thoughts**
Although the amount invested by an investor and the valuation naturally dominate the discussions around founders and angel investors, figures do not tell everything. Founders would be well-advised to consider factors other than valuation when evaluating angel investors. In the right situation, an experienced, well-connected angel investor can be an immense asset to a startup, helping fill skills gaps, driving press exposure, or bringing in new investors. Making the right decision on an angel investor can save a founder from having to make many tough decisions down the road.
--- START: blog/announcement-soc-2-type-2/announcement-soc-2-type-2.md ---
# **Peaka Achieves SOC 2 Type 2 Compliance**
We are proud to announce that Peaka has achieved SOC 2 Type 2 compliance. This significant milestone is the result of a one-year audit conducted by an independent auditor. It affirms that Peaka complies with the necessary security processes, procedures, and controls to ensure the security and privacy of user data.
Our SOC 2 Type 2 attestation comes five months after we received our SOC 2 Type 1 report and underlines our ongoing efforts to uphold the best practices in information security.
Here is what our founder & CEO [Mustafa Sakalsız](https://www.linkedin.com/in/sakalsiz/) had to say about this significant development:
> *Peaka has reached another milestone by successfully completing its SOC 2 Type 2 audit. Unlike the SOC 2 Type 1 report, which took a snapshot of Peaka’s security posture at a single point in time, the SOC 2 Type 2 attestation verifies that our internal controls and processes performed as expected over a sustained period. We will continue to invest in our security practices, refine them, and document their effectiveness with annual audits so our customers can rest assured that their data is safe with Peaka.*
Now, let’s take a closer look at this process and what it means for Peaka and our users.
## **What is SOC 2?**
SOC 2, which stands for Systems and Organization Controls 2, is a compliance framework developed by the American Institute of Certified Public Accountants (AICPA). It serves as a standard for auditors to evaluate the effectiveness of an organization’s security procedures against data breaches and unauthorized access.
## **What is a SOC 2 audit?**
A SOC 2 audit is an investigation carried out by an independent auditor to assess an organization's security processes and protocols. The audit uses five criteria, called trust service principles, to assess how effectively an organization protects its data: Security, availability, processing integrity, confidentiality, and privacy.
Upon reviewing the organization's security policies and practices, the independent auditor writes a report summarizing how well it satisfies the five trust service principles.
## **Types of SOC 2 reports**
There are two types of SOC 2 reports, and they differ in the timeframe they use to evaluate an organization’s controls.
**SOC 2 Type 1** provides an assessment of the security processes at a specific point in time, offering a snapshot of whether the necessary controls are in place. Peaka received its [SOC 2 Type 1 report](https://www.linkedin.com/feed/update/urn:li:activity:7255609095288713216) back in October 2024.
**SOC 2 Type 2** monitors the security processes for a longer period of time (usually 6-12 months), giving stakeholders visibility into the long-term effectiveness of the internal controls designed.
## **What does this mean for Peaka and our users?**
Peaka’s SOC 2 Type attestation creates significant value for our company and users:
### **For Peaka**
#### **Regulatory compliance in certain industries**
Highly regulated industries like finance, healthcare, and telecommunications have stringent requirements for data access, security, and privacy. A SOC 2 Type 2 attestation is a significant step for Peaka toward satisfying those requirements and assuring customers from those industries that their expectations will be met.
#### **More efficient internal processes**
A SOC 2 Type 2 audit documents and enforces operational best practices in an industry. This will make our internal processes more efficient and ensure that we have better incident response and risk management practices in place.
### **For our users**
#### **Deeper trust and increased transparency**
A SOC 2 Type 2 audit is conducted by an independent third party in accordance with industry-standard practices. This helps reassure our users that Peaka has established reliable security procedures and internal controls to protect user data and that they have remained consistent over time.
#### **Simplification of future audits**
Peaka’s SOC 2 Type 2 attestation ensures the security, privacy, and confidentiality of the user data. This independent verification of the security processes at Peaka simplifies the future audit processes for our users when they need proof of compliance with regulations and industry standards.
Throughout the process, Drata supported us for compliance monitoring, and AssuranceLab led the process as an auditor. We thank both companies for their guidance and collaboration.
--- START: blog/api-open-banking-defi/api-open-banking-defi.md ---
# **How to Use APIs for Open Banking & DeFi**
We have [stressed](/blog/customize-complement-extend-software/) [time and again](/blog/no-code-api-deployment/) that APIs have the power to transform a business. It is just that some industries lend themselves more to API-induced extendability compared to others. Finance is one such industry, and has benefited immensely from API-powered transformation lately.
Certain financial practices such as lending money or financing a purchase have been around for thousands of years since the days of overland trade networks under Assyrian and Babylonian monarchies. The bank as an institution as we know it, however, came into being in [Renaissance Italy](https://en.wikipedia.org/wiki/Bank) in the fourteenth century, where city-states of Venice, Genoa, Florence, and Pisa were running their overseas trade empires, and their merchants needed instruments to facilitate trade. The banking infrastructure expanded considerably over the centuries, but the services and products offered by banks have remained fundamentally the same. Two new concepts, open banking and decentralized finance, are slated to change that, apparently.
Open banking [refers to](https://ideasoft.io/blog/banking-technology-trends-to-watch-in-2022/) a system where “banks open up their APIs to third-party service providers to access clients' financial data and conduct financial transactions on the clients' behalf." This concept represents a departure from the centuries-old practices of the finance industry where a few institutions monopolize financial data toward a more [open model](https://www.bankinghub.eu/innovation-digital/open-banking-stays) where new stakeholders like fintech companies will get access to the same data.
Open banking as a concept resulted from an effort in the UK to regulate the retail banking sector, which was dominated by a few big banks. In 2016, UK Competition and Markets Authority [stipulated](https://www.openbanking.org.uk/regulatory/) that the nine largest banks would open APIs for securely sharing customer financial data with third parties. EU took a similar step by enacting the [PSD2](https://www.bankinghub.eu/themen/open-banking-far-more-than-psd2) regulation, forcing banks to open dedicated APIs to let customers securely share their financial data with third parties. These two regulations had similar goals:
+ Increasing the competition in the finance industry so that customers could get access to a broader range of offerings that better fit their needs at a lower cost
+ Ensuring seamless transmission of financial data
+ Giving customers a single contact point for managing all of their financial products and services.
Open banking offers significant benefits to all parties involved in it. Legacy banks get to monetize their existing infrastructure by opening it to third-party users, and they end up creating a new stream of revenue. Fintech companies find a chance to build a business on top of the infrastructure of legacy banks and offer competitively-priced, innovative banking services to a customer base previously neglected by established banks. Clients, too, stand to [benefit a lot](https://ideasoft.io/blog/open-banking-explained/) from open banking practices. They can pick and choose from among a broader range of options tailored to their needs, get to enjoy lower service costs, and gain more visibility into their own financial data.
APIs prove particularly effective in facilitating certain types of transactions. They can automate the transmission of financial data and reduce the time and bureaucratic effort involved in arranging loans or financing. Additionally, APIs can expedite the reconciliation process among multiple bank accounts by allowing your accountant to access whatever data he needs without the need to request bank statements from each bank.
Stripe, the widely-popular payment processing platform, offers two services, Stripe Treasury and Stripe Capital, which help illustrate how open banking works in different cases. Stripe Treasury is a banking-as-a-service (BaaS) platform where Stripe gets access to the infrastructure of a legacy bank such as Goldman Sachs or Citibank, and opens that infrastructure to its own clientele. This arrangement has let banks achieve [two goals](https://efipm.medium.com/banking-as-a-service-without-being-a-bank-stripe-s-treasury-60212b427efa): Lower customer acquisition costs and tap into an underserved customer segment. Customers benefited, too, by getting access to the regulated system of an established bank.
On the other hand, Stripe Capital is a lending program in which Stripe leverages APIs to lend money to merchants conducting trade on the Shopify platform. Stripe Capital [introduces](https://stratechery.com/2020/stripe-platform-of-platforms/) capital from legacy banks to small businesses in a much frictionless way, creating added value for everyone involved.
Open banking represents a significant stage in the customization and decentralization of banking services, but it is far from the pinnacle. That pinnacle today happens to be decentralized finance (DeFi), which is an ecosystem of financial applications and projects [built on top of blockchain technology](https://www.cnbc.com/2021/09/17/how-decentralized-finance-works-and-why-its-taking-on-wall-street.html). Transactions in the DeFi ecosystem are not mediated by a bank, a broker, or a stock exchange but [smart contracts](https://ethereum.org/en/defi/#bitcoin), which are Ethereum accounts that can hold funds and send/refund them based on certain conditions.
DeFi threatens the whole financial system as we know it. It challenges the unquestioned authority governments and international institutions wield over the financial system. It reverses the data visibility game we have grown used to. What has always been visible to governments and opaque to individuals become entirely reversed now, with individuals gaining complete control over their financial data away from the prying eyes of governments. DeFi gives people excluded from the financial system a chance to get back in the game. This may prove especially vital for people like refugees who lack the necessary documentation to open a bank account and people who remain unemployed due to lack of access to a financial service.
Crypto exchanges facilitate DeFi transactions by opening APIs and letting users perform transactions via those APIs. This gives the end-users the chance to leverage the hardware of crypto exchanges without having to invest in such equipment. In that regard, DeFi practices are not that far off from open banking practices, where legacy banks open up their infrastructure to fintech companies through APIs.
It might be difficult for you to comprehend all the possible ramifications of opening up your platform to the outer world via APIs. The only factors limiting the possibilities are the imagination of your end-users and the power of your APIs. The lesson to be learned here is that APIs can help you keep your customers happy by enabling them to develop a solution for their problems and give you a resilient ecosystem built around your product.
--- START: blog/automated-data-processing-to-scale/automated-data-processing-to-scale.md ---
# **How to Boost Scalability with Automated Data Processing**
Whether you are a startup or an established business, automated data processing (ADP) can help you gather and share data. To scale your business, focus on improving efficiency as the workload expands.
## **Automate your data, automate your business**
Recent research shows that most businesses spend 50 percent of their time on [mundane data quality tasks](https://www.montecarlodata.com/blog-data-quality-survey). No matter how detail-oriented your team is, mistakes are bound to happen. With Peaka’s expertise and automated data processing software, you can transform data into a more comprehensible format. The following sections examine the top benefits of automated data processing to boost scalability.
## **Top 10 Benefits of Automated Data Processing**
Use an [automated data processing tool to process continuously](/blog/data-integration-architecture/) while eliminating errors. These tools identify trends, patterns, and correlations of data. Here are the top 10 benefits of ADP.
### **1. Boosts Efficiency**
The propensity for human errors plagues manual data processing. For example, assigning your staff to clean data and validate orders is a tedious task that causes mistakes. If there are delays, you risk losing your customers. With automated data processing, you don't have to spend time managing high-volume data.
ADP does all the heavy lifting to reduce the costs associated with errors, so you can focus on critical operations. If you're looking for a reliable platform to help build projects and bring your data together, [Peaka has all the necessary tools](/docs/).
### **2. Improves Data Security**
Data breaches can occur when you least expect them. The best way to keep your sensitive data safe is by using [automated data processing software](/blog/best-saas-analytics-tools/). To start with, data automation simplifies security processes like threat detection, data encryption, and access control. Beyond that, it ensures secure data validation and timely recovery.
### **3. Avoid Creating Data Silos**
[Data automation](/blog/benefits-of-data-integration/) eliminates the barriers that hurt productivity and promotes data accessibility. Typically, data silos are separate from the rest of the business and are under the control of one business unit, such as a department. With an automation strategy in place, you can unlock the silos to bring data from disparate sources.
Since automation gives users greater autonomy, they can make data-driven decisions. Regarding automation, Peaka can connect you to almost anything, including GraphQL API and REST. These tools process data from different sources to suit various tasks. The other benefits of eliminating data silos include:
+ Centralized data storage
+ Enhanced collaboration
+ Improved data accessibility
+ Efficient reporting
### **4. Guarantees Legal Data Compliance**
Non-compliance with data privacy and safety can attract [hefty penalties](https://education.securiti.ai/certifications/privacyops/privacy/data-protection-consequences/). The best strategy to navigate complex data privacy regulations is to use automation tools to assist with privacy laws that protect sensitive information. When you meet the legal requirements to manage data subject requests, you can create inventories that maintain the trust of the shareholders.
### **5. Enhances Productivity**
Another way to scale your business is by eliminating repetitive tasks, allowing your employees to focus on what matters most: Productivity. ADP saves time on tasks like data entry. Best of all, it frees your workers from mundane chores to focus on innovative activities. By eliminating the need for extra human resources, you boost production.
### **6. Cost and Time Savings**
Automation ensures your employees do more work within a specific timeframe. The money you've been using to pay your employees can now be channeled away from data processing tasks. Even better, you eliminate the bottlenecks and correct them. Aside from saving on hiring more employees, you abolish repetitive processes. As a result, ADP reduces the expenses associated with errors.
If you employ a data analyst, they may be wasting time and resources by retrieving data from a sheet instead of focusing on tasks like statistical analytics. However, with data processing software, the analyst can concentrate on operations that enhance business growth. Of course, you can eliminate the headache of hiring a large team altogether.
### **7. Standardized Data**
A key aspect of data automation is tracking and measuring [key performance indicators](/blog/b2b-saas-analytics-tools/) (KPIs). When information is entirely handled by humans, it's likely to contain errors. Measure the effectiveness of your strategy; with a reliable ADP tool, you'll get standardized data to diagnose the pain points and make informed decisions.
### **8. Improves Data Accuracy**
Inaccurate data can lead to compliance violations, financial losses, and damage to reputation. ADP improves data accuracy and eliminates the costs associated with such errors. By relying on software, you increase the accuracy of data analysis.
When data is organized, you can handle large datasets accurately. Since every step in automation is recorded digitally, you get auditable records and end up paperless.
### **9. Real-time Data Analysis**
Imagine the frustration that comes with manually sifting through large volumes of data. Sectors like e-commerce, logistics, and customer service need real-time data for accurate decision-making. If you rely on manual data, you won't get accurate results.
Adopt ADP software to streamline your operations. Your clients will enjoy your services if you collect and analyze data within minutes.
### **10. Improves Customer Experience**
If you can handle data without error, customers will have a better user experience. Skip the tedious manual processes and prioritize your clients’ needs.
## **The Bottom Line**
Automated data processing can scale up your business through increased productivity and doing more within a specific timeframe. It relieves you from manual tasks like data collection, cleaning, analysis, and reporting. When done correctly, you can analyze large amounts of data with few resources.
With Peaka, you can integrate all your data sources—relational and NoSQL databases, SaaS tools, and APIs. Query them as a single data source immediately.
See Peaka’s [growing library of custom integrations](/integrations/).
--- START: blog/b2b-inbound-marketing-strategy/b2b-inbound-marketing-strategy.md ---
# **How to Create an Inbound Marketing Strategy that Converts**
## **Introduction**
The current era of marketing is digital, hence the evolving consumers’ behaviors and business dynamics require companies to understand how to practice effective B2B inbound marketing strategies.
Nowadays, marketers do not succeed anymore by forcing their brands on customers but rather by pulling them in through useful, appealing content.
In this article, we are going to reveal the secrets of an effective **B2B inbound marketing strategy** that really delivers.
Therefore, let's get into inbound marketing and see how you can attract your customers, involve them, and convert them.
But before we start, we should first answer the question: What is an Inbound Marketing Strategy?
## **What is an inbound marketing strategy?**
An **inbound marketing strategy** is a comprehensive plan that revolves around creating and sharing valuable content to pull potential customers toward your business or brand rather than pushing your message onto them.
This strategy is customer-centric and aims to build long-term relationships with your target audience by addressing their needs and interests.
## **The best strategies for B2B inbound marketing**
Now that we've got a grasp of what inbound marketing is, let's explore the best strategies for implementing a successful B2B inbound marketing strategy.
### **1. Content marketing**
One of the foundational pillars of B2B inbound marketing is content marketing. This strategy involves creating and distributing high-quality, relevant content to attract, engage, and delight your target audience.
***It's about providing value and knowledge to your prospects, whether in the form of blog posts, videos, whitepapers, infographics, or any other content format.***
### **2. Social media marketing**
Social media platforms are powerful tools for reaching and engaging with your target audience. Platforms like LinkedIn, Twitter, and Instagram can be invaluable for B2B inbound marketing.
***Sharing your content, interacting with your audience, and showcasing your company's personality can all contribute to a compelling inbound strategy.***
### **3. Email marketing**
While email marketing is often considered more traditional, it remains a key component of successful B2B inbound marketing strategies.
***Email allows you to nurture leads, provide tailored content, and guide prospects through the buyer's journey.***
### **4. Search Engine Optimization (SEO)**
An often underestimated but crucial aspect of inbound marketing is search engine optimization.
SEO helps your content get discovered by potential customers when they search for relevant topics on search engines like Google.
***SEO involves optimizing your website and content to rank higher in search results.***
### **5. Paid advertising**
In addition to organic strategies, consider incorporating paid advertising into your B2B inbound marketing strategy.
***Platforms like Google Ads and social media advertising can help you reach your target audience quickly and efficiently.***
### **6. Data integration**
This method allows you to seamlessly merge and utilize data from various sources to provide a more personalized and effective marketing experience.
With this knowledge at hand, we can now investigate some examples of a successful inbound B2B marketing approach.
***#Pro Tip: Before going into the best examples, let’s remind you that you can easily create [no-code data integrations with Peaka](/)!***
## **3 best examples of inbound marketing strategy that works well**
{{ resize_image(path="../static/assets/images/blog-images/flatart/inbound-marketing.png", width=759, height=400, op='fit_width', alt='inbound marketing written folders') }}
### **1. HubSpot—The inbound marketing pioneers**
{{ resize_image(path="../static/assets/images/blog-images/flatart/hubspot.png", width=759, height=400, op='fit_width', alt='hubspot homepage') }}
Discussion of B2B inbound marketing strategy can never be complete without mentioning HubSpot.
[HubSpot](https://www.hubspot.com/) is involved in inbound marketing and sales and has been growing its user base thanks to a sound strategy.
It is also important to note that HubSpot offers free tools such as ebooks, webinars, and templates for email marketing among others, which all help with customer acquisition.
Additionally, the company is running an informative blog and posting about different issues that are important to most startups and SMBs. With this method, they are able to capture and nurture leads efficiently.
***#Pro Tip: Peaka’s [HubSpot-Stripe Integration](/blog/integrations-hubspot-stripe/) simplifies customer segmentation for you!***
### **2. Salesforce—Providing invaluable insights**
{{ resize_image(path="../static/assets/images/blog-images/flatart/salesforce.png", width=759, height=400, op='fit_width', alt='salesforce homepage') }}
Over recent years, [Salesforce](https://www.salesforce.com/) has become popular by reminding various enterprises that the shift from manual processes to CRM is inevitable.
They conduct webinar series, write highly comprehensive blogs, and develop several white papers on different aspects of CRM and its advantages.
Their content goes beyond demonstrating expertise and actually informs enterprises about their product’s worth.
***With a B2B inbound marketing strategy, Salesforce shines by emphasizing education and value.***
### **3. Adobe—Showcasing expertise**
{{ resize_image(path="../static/assets/images/blog-images/flatart/adobe.png", width=759, height=400, op='fit_width', alt='adobe homepage') }}
[Adobe](https://www.adobe.com/), a multinational software company known for its multimedia and creativity products, serves as a source of useful techniques that lead to improved digital marketing.
***Through providing useful tips and directions, Adobe connects with the readers and appears as a pioneer in the field.***
## **Final thoughts**
In order to establish an effective B2B inbound marketing strategy, you should concentrate on developing useful content, optimizing it, and using different platforms to reach and attract your target market.
The above instances point out the strength of inbound marketing and consequently, the ability to foster growth in your line of business.
Offer useful content to your visitors with a primary emphasis on educating and involving the audience.
As a result, you build trust in people, attract leads, and convert those leads into loyal customers
So, embrace what these excellent brands are doing, and you will be on your way to develop an effective B2B Inbound marketing strategy.
--- START: blog/b2x-marketing-strategy/b2x-marketing-strategy.md ---
# **How to Create a B2X Marketing Strategy**
Building a B2C (Business-to-Consumer) marketing strategy for a startup is no easy task. At that point, you are at the very beginning of your journey with an unproven product that you hope will fill a need for a certain customer segment in the market. Within that segment, there are customer personas who will hopefully adopt your product. Identifying those personas is more of an art than science, though. You start with gender and age and then take into account other information like the level of education, job, and marital status. The more detailed and precise your descriptions are, the more successful your marketing offensive will be. Or so they say.
## **Chasing "phantom targets"**
By focusing on the customer personas, a startup aims not only to understand the needs and motives of its customers but also to get to know them well enough to establish an [emotional bond](https://www.digitalauthority.me/resources/business-to-consumer-b2c-marketing-ultimate-guide/) with them. However, this is easier said than done. Most of the time, the startup founders have to rely on their gut feelings about who their customers are, and make decisions based on assumptions that are as yet not verified, adjusting as they go. As indicated by the traction problems most tech startups run into, this tactic does not bring guaranteed success.
Without any understanding of the market or quantitative data showing how demand for your product varies across different customer segments, picking a particular segment as yours is akin to putting your proverbial eggs in a make-believe basket. In his book [*Jobs to Be Done*](/blog/book-review-jobs-to-be-done-ulwick/), Anthony Ulwick defines those customer personas built around psychographic and demographic data as "phantom targets" (*Jobs to Be Done*, p.52). According to Ulwick,
> *"[a] 28-year-old man from Montana with a college degree can have the same unmet needs as a 55-year-old woman from Florida who dropped out of high school. Both, for example, may be unhappy with their internet service."*
Instead of pretending that we can determine what a customer wants by looking at demographic and psychographic data, business strategists like Ulwick and Clayton Christensen suggest we focus on jobs, that is, tasks people are trying to get done. Hence the expression, *jobs-to-be-done*. Ulwick goes one step further than Christensen in his book and dissects those customer jobs into their components, bringing a more quantitative approach to marketing strategy.
## **B2B: Impractical for startups?**
B2B (Business-to-Business) marketing is ruled out for most startups because there is a widespread belief that it is resource-intensive. Its successful implementation requires [money, sales staff, connections, and brand recognition](https://medium.com/@pophamjohn97/b2b-b2c-b2g-the-newest-thing-is-b2x-and-its-a-terrible-idea-a44d019ea251) that most tech startups lack. B2B involves a top-down approach where a decision-maker [at the management level and in control of a budget](https://www.pjmconsult.com/index.php/2021/04/enterprise-tech-sales-top-down-selling-vs-bottom-up-marketing.html) makes the purchase. Startups are usually discouraged from pitching their products to enterprises unless they have a product that fits an enterprise's well-defined needs like a glove.
However, this does not mean that tech startups can never tap into the corporate market. Although enterprises have their own cultures, established decision-making mechanisms, and rules independent of any particular individual, employees' habits still get to shape the way these organizations function. Employees will bring their favorite tools and platforms to the office and act as brand ambassadors for the products they like. Their recommendations to co-workers help trigger a bottom-up adoption process. Once the product proves its mettle in a project or within a team, an enterprise-level purchase becomes easier. This strategy of driving bottom-up adoption in enterprises is called **B2X** ('X' standing for 'everything' in this case). It is some kind of a crossover resulting from a synthesis of B2C and B2B strategies. It requires startups to connect with their most passionate customers and build communities around these people. While nurturing these communities, startups should ensure that they can deploy solutions capable of addressing enterprise-level problems when their number is called.
## **When in SaaS-land, do as the unicorns do**
Notion is a SaaS company that provides a case in point for the power of B2X. The company successfully hybridized B2B with B2C to build its growth engine. It leveraged an [organic community](https://www.youtube.com/watch?v=m2ZWJn-tPCQ) of corporate Notion users as a bridgehead to drive its enterprise sales. The key to Notion's success was the flexibility of its product—it could be adapted to different use cases—and its ability to offer quick solutions to the problems of enterprises, as these organizations have to act quickly.
Notion's success is undoubtedly impressive; however, the company that wrote the book on bottom-up marketing is definitely Atlassian. For years, Atlassian prided itself on not employing a sales team. Instead, the company leveraged product-led growth before product-led growth became the marketing cult that it is today.
Atlassian's marketing effort was built on a freemium model that eliminated any risk for potential users, letting them see how the company's products would fit into their lives before paying any money. Founded in 2002 and unable to afford a sales team at the beginning, the company had achieved [$50 million](https://nira.com/atlassian-history/) in ARR by 2010. Atlassian owed this growth to the popularity its products enjoyed among corporate employees.
Atlassian's project tracking software Jira, for example, became popular among developers and project teams thanks to its capabilities in tracking bugs, managing a product roadmap, and version control. Once Jira cornered the developer market, it single-handedly turned Atlassian into a household brand for enterprises, acting as a catalyst for enterprise sales.
Similarly, Atlassian's cloud-based collaboration platform Confluence made things easier for HR teams, marketing professionals, and content creators. Winning the hearts of individual employees turned Atlassian into the powerhouse software company we know today—enjoying [$3 million](https://www.saastr.com/5-interesting-learnings-from-atlassian-at-almost-3-billion-in-arr/) in ARR and still growing its revenue at an astonishing 37 percent year-over-year rate.
The freemium model became the backbone of the B2X marketing strategy for tech startups. Slack took advantage of this strategy to get users hooked first and achieved a [free-to-paid conversion ratio of 30 percent.](https://www.nirandfar.com/habit-forming/) Zoom employed a freemium model, which did not ask for any credit card information for the free-of-charge 40-minute phone calls it offered to users. When it reached $330 million in revenue in the fiscal year of 2019, [55 percent](https://www.techtarget.com/searchunifiedcommunications/news/252461958/Zoom-IPO-demonstrates-power-of-freemium-pricing) of the 344 customers paying Zoom more than $100,000 a year were former freemium users.
## **Conclusion**
B2X strategy has so far proved that it can help tech startups not only gain traction but also become unicorns in a short time. The catch here is to have a product that appeals to different use cases, has a short time-to-value so that the user can appreciate the value without hassle, and adapts to customers' needs in different environments.
The 1990s were characterized by Coca-Cola's "think global, act local" mantra: Companies needed to satisfy local needs and adapt to local conditions in order to achieve global success. Today, success in the enterprise segment for tech companies requires a similar approach: Conquer the hearts of the employees first, and you will conquer the minds of the managers. B2X is the strategy that makes this possible.
--- START: blog/benefits-of-data-integration/benefits-of-data-integration.md ---
# **Top 9 Benefits of Using a Data Integration Platform**
## **Introduction**
Businesses are continuously looking for methods to make the most of the enormous volumes of information at their disposal in today's data-driven environment.
The secret to realizing data's full potential is to integrate it seamlessly across different platforms and systems.
***This procedure, called data integration, is essential for making better decisions, increasing productivity, and eventually achieving success.***
You can also check out our article titled [How to Create an Inbound Marketing Strategy that Works Well](/blog/b2b-inbound-marketing-strategy/) to learn about creating an inbound marketing strategy.
Today, we will dive into the **benefits of data integration** in this post, by first explaining what it is, and why it is important.
Before we plunge into the benefits, let's first clarify what data integration is.
## **What is data integration?**
At its core, **data integration** is the process of combining data from different sources to provide a unified view. This could involve data in various formats such as tabular data, visuals, audio files, videos, and more.
The aim is to create a cohesive and comprehensive data set that can be analyzed to extract meaningful insights.
***In simpler terms, data integration is about connecting the dots in your data landscape.***
Data integration involves various techniques, including ETL (Extract, Transform, Load) processes, data virtualization, and API-based integrations.
It is not just about aggregating data but also transforming it into a consistent format that facilitates meaningful analysis.
## **Key takeaways**
- With the explosive growth in the amount of data that organizations have to handle, data integration is no longer a *nice-to-have,* but it has become a *must-have* for organizations striving to stay ahead of the competition.
- Data integration enables organizations to harmonize the data being kept in diverse formats, break down data silos, and ensure data quality.
- Data integration helps form a single view of truth and facilitates data-driven decision-making. It eliminates manual processes, minimizing the risk of human error and increasing productivity.
- Peaka sets itself apart from other data integration platforms with its zero-ETL approach that removes the need to build and maintain ETL pipelines. Its ready-made connectors and AI-to-SQL capability lower the technical barriers for non-technical users who want to bring together and query their data.
## **Data in numbers**
- The [global data integration market size](https://www.precedenceresearch.com/data-integration-market) was estimated to be $12.14 billion in 2022, and it is projected to reach $39.25 billion by 2032, growing at a compound annual growth rate (CAGR) of 12.5 percent, according to a report by Precedence Research.
- The [global data storage market](https://www.snsinsider.com/reports/data-storage-market-2768), worth $212.01 billion in 2922, is projected to reach $791.52 billion by 2030, growing at a CAGR of 17.9 percent, according to a report by SNS Insider.
- Over 80 percent of [IT decision-makers](https://www.g2.com/articles/big-data-statistics#bigdatachallenge) think that analytics projects in their organizations keep getting delayed because data is not available in the required format.
- While the [number of data scientists in the U.S.](https://www.bls.gov/ooh/math/data-scientists.htm) is expected to grow 35 percent from 2022 to 2023, there will be 17,700 job openings every year throughout the decade. This figure is a sign that innovative approaches like zero-ETL and AI will play a bigger role in picking up the slack and making data available to data consumers.
## **Why is data integration important?**
{{ resize_image(path="../static/assets/images/blog-images/flatart/data-integration-graphic.png", width=759, height=400, op='fit_width', alt='data integration graphic with icons') }}
There are many reasons why data integration is important. Here are just a few:
### **1. To harmonize data in diverse formats**
Data comes in a myriad of formats, from structured tabular data to unstructured data stored in audio and video files.
Without a seamless integration process, these diverse data formats remain disparate and fail to provide a holistic understanding of the business landscape.
A [data integration tool](/) can harmonize this data, converting it into a unified format that is easily digestible by analytical tools.
This simplifies the analysis process and, at the same time, ensures that you don't lose any valuable insight due to incompatible data formats.
### **2. To break down data silos**
One of the primary pitfalls of not implementing data integration is the creation of data silos. These isolated pockets of information hinder collaboration and synergy across departments.
For example, marketing teams may have valuable customer insights that could significantly benefit product development, but without integration, these insights remain trapped in a silo.
By breaking down these data silos, organizations can foster a culture of collaboration, where insights from various departments contribute to a more comprehensive understanding of the business ecosystem.
### **3. To ensure data quality**
Data integration is not merely about bringing data together; it's about ensuring that the data is accurate, complete, consistent, valid, and timely.
In the absence of proper integration, organizations run the risk of relying on flawed or outdated information, leading to misguided decisions.
Data quality is crucial for businesses relying on analytics and reporting for strategic decision-making.
Data integration tools often include mechanisms to validate and cleanse data during the integration process, ensuring that the resulting data set is reliable and accurate.
## **What are the benefits of data integration?**
Data integration is a complex process that requires careful planning and execution. However, the benefits of data integration can be significant that they justify the extra effort. So, now let’s check the benefits of data integration!
### **1. Creating a single view of truth**
One of the key benefits of data integration is the creation of a single view of truth.
In a typical organization, data resides in various departments and systems. Finance may have financial data, marketing may have customer data, and operations may have production data. Without integration, these views of data remain isolated.
Data integration brings together these disparate views, creating a unified and comprehensive understanding of the organization's performance.
This single view of truth becomes the foundation for strategic decision-making, as all stakeholders can align themselves around a shared understanding of the business landscape.
### **2. Enabling data-driven decision-making**
In this data-driven era, making decisions based on accurate and comprehensive information is paramount.
Data integration empowers organizations to leverage insights from diverse sources, facilitating informed decision-making.
This, in turn, enhances strategic planning and contributes to the overall success of the business.
For example, a retail organization integrating data from sales, customer support, and inventory can make data-driven decisions about product offerings, pricing strategies, and inventory management.
This holistic approach ensures that decisions are based on a complete understanding of the market dynamics.
### **3. Eliminating manual processes**
Manual data handling is both a time-consuming and error-prone process.
Data integration automates the process of gathering data and synthesizing information, reducing the need for manual intervention.
This not only saves time and resources but also minimizes the likelihood of human errors that can have far-reaching consequences.
Consider a scenario where sales data from an e-commerce platform needs to be reconciled with inventory data from a warehouse management system.
Without data integration, this reconciliation process might involve manual data entry and validation, opening the door to errors.
Data integration tools streamline these processes, ensuring that data flows seamlessly between systems, reducing the risk of errors, and improving overall operational efficiency.
### **4. Boosting efficiency**
Efficiency is the lifeblood of any successful organization. Data integration streamlines processes, allowing organizations to achieve more with less.
Automating repetitive tasks and providing a consolidated view of data promotes efficiency gains across various functions, from marketing to finance.
For instance, consider a healthcare organization integrating patient data from electronic health records, billing systems, and appointment scheduling platforms.
This integration provides a comprehensive view of patient information and streamlines administrative processes, reducing the time and effort required for tasks such as billing and appointment scheduling.
### **5. Improving customer service**
In an era where personalized experiences reign supreme, customer service is a critical differentiator.
Data integration provides a 360-degree view of customer interactions by consolidating data from various touchpoints.
Such comprehensive understanding enables businesses to tailor their services to individual customer needs, fostering satisfaction and loyalty.
### **6. Enhancing business intelligence**
Business intelligence is the sum of activities for collecting and analyzing data to provide executives, managers, and workers with actionable information. It makes data-driven decision-making possible, serving as the cornerstone of strategic planning.
Data integration empowers organizations to create comprehensive reports and dashboards, offering a holistic view of performance.
This data-driven insight facilitates forecasting, trend analysis, and strategic planning, ensuring that businesses stay ahead in a fiercely competitive landscape.
### **7. Streamlining compliance and risk management**
For industries governed by stringent regulatory frameworks, compliance is non-negotiable.
Data integration ensures consistent and accurate reporting, mitigating the risk of compliance breaches.
Moreover, centralizing risk-related data enables organizations to proactively identify and address potential risks, safeguarding both reputation and financial stability.
### **8. Facilitating innovation**
Innovation thrives on the ability to connect ideas and information.
Data integration breaks down information silos, fostering collaboration among cross-functional teams.
The resulting collaboration, fueled by seamless data access, accelerates the development of new products or services, propelling the organization into the vanguard of innovation.
### **9. Scalability and future-proofing**
As businesses grow, so does the complexity and volume of data.
Data integration solutions are designed to be scalable, ensuring that organizations can expand their operations without compromising data efficiency.
This scalability future-proofs data integration investments and allows businesses to adapt to evolving needs seamlessly.
## **Who can benefit from data integration?**
{{ resize_image(path="../static/assets/images/blog-images/flatart/integration-concept.png", width=759, height=400, op='fit_width', alt='integration concept shown with icons') }}
The benefits of data integration are not confined to a specific industry or business size. Organizations across sectors, whether large enterprises or small startups, can harness the power of data integration to drive success.
Let's explore how different sectors can leverage the advantages of data integration.
### **1. Healthcare**
In the healthcare sector, patient data is dispersed across different systems, from electronic health records (EHRs) to billing and insurance platforms.
Data integration plays a crucial role in creating a unified patient profile, enabling healthcare professionals to access comprehensive information seamlessly.
This helps improve patient care and enhances administrative efficiency by automating processes such as billing and claims management.
### **2. Finance and banking**
Financial institutions deal with vast amounts of data, including customer transactions, account information, and market data.
Data integration in the finance sector streamlines these complex data flows, providing a consolidated view for risk management, compliance, and customer relationship management.
### **3. Retail and e-commerce**
In the retail and e-commerce sector, data integration is instrumental in optimizing the customer experience.
By integrating data from online and offline channels, organizations can create a unified customer profile, enabling personalized marketing strategies and improving inventory management.
### **4. Education**
In the education sector, data integration supports the management of student information, academic records, and institutional operations.
Integrating data from diverse sources such as learning management systems, student information systems, and assessment tools enhances administrative efficiency and provides educators with a comprehensive view of student performance.
### **5. Government and public services**
Government agencies and public services deal with diverse data sets, ranging from citizen records to infrastructure data.
Data integration enhances the efficiency of government operations by creating a unified view of information.
This supports initiatives such as data-driven policymaking, public safety, and resource allocation.
## **What are the top 4 data integration platforms?**
The market for data integration platforms is a crowded one with many offerings for customers with different needs. However, four tools stand out from the rest with their novel approach to data integration:
### **1. Peaka**
{{ resize_image(path="../static/assets/images/blog-images/flatart/peaka-homepage.png", width=759, height=400, op='fit_width', alt='peaka homepage') }}
Peaka is a zero-ETL data integration platform that brings your data together and lets you query it in its source without having to deal with physical ETL processes.
The platform offers a wide array of ready-made connectors that make it a breeze to pull in data from the most popular SaaS tools.
Its embedded ChatGPT allows even non-technical users to generate SQL queries using natural language.
Peaka users proficient in SQL can use it to query NoSQL databases. After querying and filtering their unified data, they can form new data sets and expose them with APIs to serve other applications and systems.
### **2. Denodo**
{{ resize_image(path="../static/assets/images/blog-images/flatart/denodo-homepage.png", width=759, height=400, op='fit_width', alt='denodo homepage') }}
Denodo is a data management platform built on the “logical data warehouse” concept. It makes use of the data virtualization technique to simplify data access for enterprise users.
Denodo creates a virtual layer of data by bringing together data from disparate sources and breaking down data silos. It organizes the data into a universal semantic model and offers it to data consumers in different departments, making it ready for analysis and BI operations.
### **3. Dremio**
{{ resize_image(path="../static/assets/images/blog-images/flatart/dremio-homepage.png", width=759, height=400, op='fit_width', alt='dremio homepage') }}
Dremio is a data lakehouse providing its users with self-service data analytics capability. It claims to combine the performance of a data warehouse with the scalability of a data lake.
Like Denodo, Dremio, too, serves the enterprise segment and is a better fit for technical users like data engineers and IT teams. However, it appeals to tech-savvy business users, as well, with its no-code user interface and BI connectors.
### **4. Mozart Data**
{{ resize_image(path="../static/assets/images/blog-images/flatart/mozartdata-homepage.png", width=759, height=400, op='fit_width', alt='mozart data homepage') }}
Mozart Data is a data platform that revamps conventional data integration methods with clever, modern touches. It utilizes data warehouses, ETLs, and no-code automation to centralize data and make it ready for analysis. In that sense, Mozart Data is a more traditional platform than the other three.
By automating ETL pipelines, Mozart Data allows users to focus on the analytics side of things rather than preparing and cleaning data and building and maintaining ETL pipelines.
## **What are the challenges of data integration?**
While the benefits of data integration are compelling, it's essential to acknowledge the challenges that organizations may encounter during implementation.
Issues such as data quality, compatibility, and integration complexities can pose hurdles.
However, with careful planning, robust technologies, and strategic partnerships, these challenges can be overcome, ensuring a smooth integration process.
## **Final thoughts**
The importance of data integration cannot be overstated.
It serves as the foundation for improved decision-making, increased efficiency, and reduced costs.
Businesses that embrace data integration gain a competitive edge, unlocking a myriad of benefits that extend across all facets of operations.
***As technology continues to advance, the role of data integration will only become more crucial.***
To fully harness the potential of data integration, organizations must invest in robust solutions, foster a data-centric culture, and stay abreast of emerging trends.
***Embrace the power of data integration and unlock the true value of your organization's most valuable asset.***
--- START: blog/best-airtable-alternatives-2021/best-airtable-alternatives-2021.md ---
# **The Best Airtable Alternatives of 2022**
In recent years, no-code platforms have become increasingly popular. They allow people with little to no tech background to create applications and products they previously would’ve needed a programmer to complete. No-code platforms use a visual design interface with drag and drop functions and pre-made widgets and apps to allow users to see their final product as it comes together. It’s never been easier to create the app you’ve always envisioned, whether you have programming knowledge or not.
One of the most popular no-code platforms is Airtable, which offers users the power of a database with the familiarity of a spreadsheet. Since launching in 2013, the intuitive platform, which is perfect for both beginners and advanced users, has grown significantly and is now worth an estimated [$2.6 billion](https://www.reuters.com/article/us-airtable-fundraising/airtable-eyes-5-billion-valuation-in-new-funding-round-sources-idUSKBN2B4214). Airtable offers users more than 50 pre-built apps that help users bring their data to life in minutes and build the tools their business needs. One of the other features that makes Airtable stand out is how easy it is to create multiple views, such as a calendar or Kanban view, of your data. Airtable also has an extensive library of tutorials available to help with the learning curve. The videos range from a short introduction to each one of its data views to hour-long in-depth explanations of how to use the entire platform for specific use cases, such as project management.
Even with everything that Airtable has to offer, there are numerous alternatives that offer additional features or are better designed for certain needs or use cases. With the increase in available no-code platforms, it can feel daunting to determine which one is best for your individual or business needs, but here are a few of the best Airtable alternatives.
## Bildr
[Bildr](https://www.bildr.com/) first began as an internal platform that the company’s visual designers used to create everything from websites to extensions and SaaS products for clients quicker and more effectively than their competitors. Their team has been using the platform for 15 years, but it wasn’t until 2019 that it was released as a standalone platform to the public. Since Bildr was designed by visual designers, they have the advantage of understanding how visual designers think and work. Another advantage of the platform is that the Bildr team has dealt with many client requests over the years and the available libraries, actions, and elements are extensive. The main downside to Bildr is that some feel that the platform assumes users to have a certain amount of visual design experience and knowledge, which can be overwhelming for beginners. In addition, as a newer platform, the available documentation and support doesn’t help new users fully understand what the powerful platform is truly capable of.
For pricing information, see [here](https://www.bildr.com/pricing).
## AppSheet
Similar to Airtable, [Appsheet](https://www.appsheet.com/) helps users make mobile and web apps using data in cloud-based databases and spreadsheets. Since launching in 2014, the platform has helped users make nearly four million apps with no-code required. AppSheet was acquired by Google in 2020 and is now part of the Google Cloud, and users can easily use data from Google Sheets in their apps. In addition to Google Sheets, users can also use Excel spreadsheets, Salesforce, and various SQL databases like SQL Server and MySQL, among other data sources. Appsheet offers users a number of appealing features like multi-platform support for iOS, Android, and web applications and the ability to capture images, scan barcodes, generate reports, send emails, log locations, and more. The Appsheet platform is available as an add-on to Google Workspace and starts at only $5 a month for individual accounts. Appsheet also has enterprise accounts for businesses available, and its platform has been used by major companies like GE and Clear Link.
For pricing information, see [here](https://solutions.appsheet.com/pricing).
## Peaka
One of the newer no-code platforms, [Peaka](/), allows users to easily create responsive web and SaaS applications. Compared to other platforms, Peaka offers users a lot of customization options when it comes to style and specific components, as well as a built-in database for data design and management. Another unique feature of Peaka is that its license model isn’t based on the number of users like many other platforms’ models are, making it more cost-effective for users. Given that it is a newer platform, some features like templates, documentation, and pre-built integrations are currently limited or unavailable, but the team behind Peaka is hard at work making these features, as well as countless others, a reality.
For pricing information, see [here](/pricing/).
Airtable was one of the early movers in the no-code realm and has achieved success, becoming one of the most capable no-code tools out there. However, platforms like Bildr, Appsheet and Peaka are catching up with Airtable, offering viable alternatives. While Appsheet’s starter package costs just $5 per user a month, Builder and Peaka offer freemium versions (just like Airtable does), making it a no-brainer to give them a try. If you are curious about no-code platforms, it would serve you well to spend an evening or two discovering these options and see which one piques your fancy.
--- START: blog/best-chartmogul-alternatives/best-chartmogul-alternatives.md ---
# **5 Best ChartMogul Alternatives in 2026**
## **Introduction**
Being data-driven has become one of the main themes of keynote speeches over the last decade. However, it is easier said than done. To make data-informed decisions, you need a reliable data infrastructure that can collect data, unify the data stored in different sources, and make sense of it. Without this infrastructure in place, you end up with a nonstop buildup of data in silos, which does not add value to your organization.
Harnessing the power of data can transform a business. [A 2013 study by McKinsey](https://www.mckinsey.com/capabilities/growth-marketing-and-sales/our-insights/five-facts-how-customer-analytics-boosts-corporate-performance) illustrates the point. This survey of 400 executives from global companies investigated the effect being data-driven had on organizational performance and revealed these remarkable findings:
>"*Intensive users of customer analytics are 23 times more likely to clearly outperform their competitors in terms of new customer acquisition than non-intensive users, and nine times more likely to surpass them in customer loyalty. Our survey results also show that the likelihood of achieving above-average profitability is almost 19 times higher for customer analytics champions as for laggards. Even more impressive is their likelihood of migrating an above-average share of customers to profitable segments, at 21 times that of non-intensive users of customer analytics…*"
If there is a single industry that can become data-driven, it must be the SaaS industry because this cloud-based business model accumulates data like no other industry can. SaaS companies rely on SaaS analytics to make sense of their data. Using a capable SaaS analytics platform, SaaS companies can pull in data from different sources, get reports on different [SaaS metrics and KPIs](/blog/top-saas-sales-kpis/) defined, evaluate employee performance, and plan for the future.
One of the more popular platforms in this space is ChartMogul. We will take a close look at ChartMogul in this piece and discuss some of the viable alternatives.
## **What is SaaS analytics?**
[SaaS analytics](https://www.toucantoco.com/en/blog/what-is-saas-analytics-and-why-you-need-it) is how SaaS companies monitor, bring together, and analyze their data to make better decisions. While traditional businesses depend on a relatively small number of one-off transactions that involve lump sum payments, SaaS businesses rely on recurring revenue from numerous customers on usually small contracts. With SaaS analytics, SaaS businesses can
+ Study the nature of each of these small deals,
+ Figure out the characteristics of loyal, high-value customers,
+ Adjust messaging and content in a way that will appeal to the more valuable customers,
+ Devise tactics to improve retention and limit churn so that the compounding effects kick in.
Serial entrepreneur, investor, and SaaS analytics expert David Skok summarizes the basic concepts of the SaaS business in this video:
{{ youtube(id="bCBccKfG9U0") }}
## **Key takeaways**
+ SaaS analytics allow SaaS businesses to optimize resource allocation, streamline messaging and content creation, and improve the overall profitability of the business.
+ ChartMogul is an exciting option in the market, with a slick dashboard and cohort analysis capability.
+ ChartMogul has launched a stand-alone CRM, which it is promoting heavily. People unwilling to migrate their data from HubSpot to the new ChartMogul CRM still need a dedicated HubSpot-Stripe connector.
+ Peaka stands out as a do-it-all option in the market, with advanced data integration capabilities, a smart dashboard, and ready-made connectors.
## **SaaS in numbers**
+ The [average number of apps](https://pages.bettercloud.com/rs/719-KZY-706/images/BetterCloud-State-of-SaaS-2025.pdf) used by an organization was down from 130 in 2022 to 112 in 2023 and 106 in 2024, signaling a consolidation in the tech stack, possibly due to the emergence of versatile generative AI tools.
+ In 2015, there were [1,875 SaaS tools](https://joinframe.medium.com/saas-overload-whats-the-true-cost-of-fragmentation-111a9ff46631) in the marketing field alone. This number increased to 8,000 in just five years.
+ A [report](https://www.cloudeagle.ai/resources/guides-and-reports/2024-saas-spend-trends-and-insights) published by CloudEagle has found that companies spend $1000-$3500 per employee annually on software tools.
## **Why use a SaaS analytics tool?**
Running a SaaS business without utilizing metrics is like flying a plane blindfolded, but without the assistance of autopilot. In an industry where sales cycles are relatively short, SaaS analytics gives you the figures and averages you can monitor to assess how well your business is performing. It makes it possible for decision-makers to identify trends that are almost impossible to discover in tabular form.
Here is a summary of the benefits of using a [SaaS analytics tool](/blog/why-use-saas-analytics-tools/):
### **Simplified access to metrics and KPIs**
Monitoring metrics like net revenue retention rate, customer lifetime value, and customer acquisition cost helps gauge the health of your business. These figures may be complicated to calculate manually. A SaaS analytics tool ensures that data users can track metrics and KPIs at any time they need to.
### **Improved forecasting and reporting**
A SaaS analytics tool provides users with insights into future revenue and cost trends, enabling them to better utilize their budget and adjust hiring decisions based on the forecasts. It also simplifies reporting for investors and stakeholders with [customizable dashboards](/blog/data-visualization-with-power-bi-integration/) and exportable reports.
### **Refined customer segmentation**
By combining SaaS analytics with a CRM, users can see how spending changes in relation to the customer’s demographic, technographic, and firmographic attributes and identify best-fit customers for their product. With better-defined customer segments, companies get to tailor messaging and content for a specific buyer persona and increase marketing ROI significantly.
### **Actionable insights for decision-makers**
A capable SaaS analytics gives decision-makers visibility into different aspects of daily operations. Precise customer segmentation, detailed cohort analyses, and forecasts about future trends lead to data-driven decisions and help optimize targeting and campaigns.
## **What is ChartMogul used for?**
ChartMogul is a subscription analytics platform that imports data from different payment platforms and turns that data into metrics. By calculating crucial figures like ARR, LTV, and retention- and churn-related metrics, ChartMogul presents the results in a visually-pleasing dashboard, making it easy to notice trends.
One of the strengths of ChartMogul is its cohort analysis capability. Thanks to this feature, ChartMogul users can see their customers organized as part of groups that signed up at a particular time. These cohorts can then be analyzed in relation to the location, pricing plan selected, and discounts given. Cohort analysis is a valuable tool that can unveil patterns and cyclicality hidden in the spending habits of customer groups.
ChartMogul integrates with payment platforms like Stripe, PayPal, Chargeable, and Braintree. These integrations enable ChartMogul to generate revenue-based reports, such as MRR-by-location or MRR-by-cohort.
On the CRM front, ChartMogul integrates with Pipedrive using Zapier. That it does not offer a native connector for a popular CRM like HubSpot is a significant downside, though. Instead of providing dedicated connectors to integrate with different CRMs, ChartMogul has launched its own CRM for SaaS businesses. Users keeping their customer data on ChartMogul CRM will be able to enrich their revenue data pulled in from Stripe or PayPal with the customer attributes stored in this CRM.
## **5 alternatives to ChartMogul**
### **Peaka**
Data integration is Peaka’s forte. We specifically built Peaka to break data silos by pulling in data from different sources and blending that data to generate business insights for users.
Peaka provides a convenient solution for HubSpot users who wish to merge customer data with Stripe data without having to switch to another CRM such as ChartMogul. Peaka’s dedicated HubSpot-Stripe connector allows startups and SMBs lacking technical expertise or resources to merge their revenue data with customer attributes.
Having consolidated revenue and customer data, Peaka users can generate reports that offer a higher granularity than the usual MRR, ARPU, or LTV reports generated by run-of-the-mill SaaS analytics tools. With Peaka, users can further break down their data by country, industry, and company size. As a result, Peaka users can easily filter the data and identify customers in a particular industry (tech companies) based in a specific country (like Brazil) that have held IPOs among their customers, for example.
Who would need this level of granularity in reports? Marketing and sales teams feast on this kind of information, using it to improve customer segmentation. They leverage it to spot high-value customers who are a good fit for the brand, offering high lifetime value. Zeroing in on these best-fit customers, marketing and sales professionals create messaging and content that appeal to these people, scaling what works and eliminating what doesn’t. This kind of personalized outreach improves the ROI of the marketing budget and optimizes resource allocation.
### **ProfitWell**
ProfitWell offers a comprehensive suite of reports that users can generate. These reports cover standard [SaaS growth metrics](/blog/saas-growth-metrics/) like MRR, churn rate, customer lifetime value, and ARPU, and users can apply filters such as industry, location, or pricing plan to create more detailed reports. Additionally, ProfitWell provides a smart dashboard that enables users to transform tabular data into visually appealing charts and graphics.
ProfitWell has an API users can utilize to bring customer, subscription, and transaction data into the platform. The platform seamlessly integrates with payment gateways like Stripe, Chargify, Paddle, and Braintree. Users can specify triggers depending on the actions customers take or thresholds in the pricing plan. These triggers can later initiate automated workflows, sending emails reminding people to use certain features or renew their subscriptions.
One area where ProfitWell has a clear edge over ChartMogul is customer segmentation capability. Unlike ChartMogul, ProfitWell provides users with a HubSpot-Stripe connector, letting them blend customer data from HubSpot with the payment data extracted from Stripe. Furthermore, while ChartMogul aims to convince its users to adopt ChartMogul CRM, ProfitWell collaborates with marketing intelligence providers Fullcontact and Clearbit, allowing users to enrich data with demographic and firmographic attributes.
### **Baremetrics**
Baremetrics is a versatile platform that manages subscriptions, provides SaaS analytics, and offers [data visualization capability](/blog/data-visualization-with-looker-studio-integration/). It has nice features for customizing email campaigns and reminders to minimize rejected credit card payments or creating forms to gather feedback on why they left, offering valuable insights. The platform presents all of this data in a cool dashboard, making it a valuable source of information.
Baremetrics boasts a powerful Forecast Module, which is one of its key strengths. This feature enables users to make MRR, cash flow, and growth projections by controlling parameters like churn and time period. It helps reduce uncertainty and makes it easier for decision-makers to plan for the future and address any potential issues.
Baremetrics integrates with a wide range of payment platforms, including Stripe, Braintree, Recurly, and Chargebee. On the CRM front, Baremetrics offers integration with Pipedrive. When configured properly, the platform pulls in customer data from Pipedrive and merges that with the revenue data extracted from one of the aforementioned platforms. Like ChartMogul, Baremetrics lacks a dedicated HubSpot-Stripe connector, which is not-so-good news for the users of these two popular platforms.
### **Subscript**
Specifically developed to track SaaS analytics, Subscript is a relative newcomer to the SaaS analytics stage, but it boasts an impressive suite of features potential users seek in a business intelligence solution.
Many SaaS analytics tools offer basic reports like MRR, ARR, or LTV. Yet these figures give little insight into the reasons behind the changes. For instance, a decrease in ARR does not tell you much unless you know whether that fall stems from customer churn or downgrades to a lower pricing plan. Fortunately, Subscript breaks down these metrics into their lower-level components. With Subscript, users can delve deeper into a metric like MRR and analyze how the expansion MRR, contraction MRR, or churned MRR contribute to the overall figure.
Another trick up Subscript’s sleeve is the cohort analysis capability, which reveals the NRR from groups of customers that signed up in different months. By merging this with attributes like company size, industry, and location, users can generate granular reports and take action accordingly.
Subscript isn’t without its flaws, however. It has limited integration options, being a new product. As of now, it integrates with Stripe, HubSpot CRM, QuickBooks, and Xero. Integrations with other payment platforms and CRMs through dedicated connectors will add to the versatility of Subscript, making it a strong competitor in the market.
### **HockeyStack**
If you've already brought your data together and want to optimize your marketing and sales funnels, HockeyStack can be an excellent choice for you. It boasts a no-code user interface, making it ideal for small teams who don't have access to large technical teams.
However, despite the ease of use, HockeyStack falls behind other players in the market in two important areas. Firstly, it comes with fewer integrations than its competitors. Although it can extract data from major CRM platforms, it does not support integrations with popular payment processing platforms. Secondly, its reports lack the level of detail Peaka and Subscript can provide. Currently, HockeyStack is more suited for marketing attribution rather than SaaS analytics. While it helps users analyze the customer journey, it requires another tool that can pull in data from payment platforms and various CRMs.
HockeyStack allows users to see which parts of the marketing and sales funnels are performing well and how much they contribute to the company’s bottom line. Armed with this kind of insight, users can double down on messaging, ads, campaigns, and content types that resonate with customers and phase out the ones that don’t create value.
## **SaaS analytics content to consume**
+ Video—[David Skok of Matrix Partners: Driving SaaS Success Using Key Metrics | SaaStr](https://www.youtube.com/watch?v=bCBccKfG9U0)
+ Article—[Subscription Analytics 101 | What is Subscription Analytics](https://sarasanalytics.com/blog/subscription-analytics/)
+ Report—[Five facts: How customer analytics boosts corporate performance](https://www.mckinsey.com/capabilities/growth-marketing-and-sales/our-insights/five-facts-how-customer-analytics-boosts-corporate-performance)
## **Conclusion**
SaaS is a different ball game. Unless your SaaS company lands multiple six- or seven-figure contracts every year, you rely on recurring revenue from many smaller deals. To take advantage of the compounding effect of the recurring revenue model, you have to keep the existing customers happy, ensure that they spend more on your product, acquire new customers, and limit churn.
This requires a profound understanding of the customers, their pain points, and how they interact with your product. SaaS analytics platforms give you that. They help consolidate your data and present it in a way that makes it easy for you to draw insights from.
ChartMogul has made a name for itself among the SaaS analytics platforms for its innovative dashboard, variety of reports, and cohort analysis capability. However, the limited number of integrations it supports leaves much to be desired.
This is where Peaka shines. Peaka allows users to run SQL queries in data scattered over different sources. It combines a great dashboard with granular reports and supports integrations with a variety of reports. Peaka’s dedicated HubSpot-Stripe connector is perfect for businesses looking to connect their CRM and payment processing platforms without hassle. It’s the kind of tool startups and SMBs dream of.
--- START: blog/best-enterprise-data-warehouse/best-enterprise-data-warehouse.md ---
# **How to Choose the Best Enterprise Data Warehouse**
The top SaaS companies use enterprise data warehouses (EDW), which are centralized data repositories that integrate data from multiple sources across an organization. EDWs empower businesses to analyze large volumes of data for strategic insights and decision-making.
We’ve compiled insights on the key considerations for finding the best strategy for your business.
## **What You Need to Know to Maximize Value**
Enterprise data warehouses are still the most popular data integration platforms for businesses despite the high lifecycle management costs and complexity, with 54 percent [utilizing EDWs](https://globalit.com.tr/en/data-warehousing-trends-and-statistics-you-need-to-know-in-2022-everything-you-need-to-know-about-the-data-warehouse/) in 2022.
[Choosing the right enterprise data warehouse platform is crucial](/integrations/) for maximum value. The wrong choice can saddle your business with spiraling costs, security risks, integration issues, and limited scalability.
## **How to Determine Your Data Requirements**
Before starting your search for an EDW, it's vital to understand your specific needs and requirements.
### **Data Volume and Variety**
+ What is the size of your dataset?
+ How fast is it growing?
+ What types of structured, semi-structured, and unstructured data do you store?
### **Data Velocity**
+ How frequently is new data generated?
+ What are your real-time vs. batch processing needs?
### **User Base and Query Types**
+ How many business users will access the system?
+ What types of queries, reports, and analytics will they run?
### **Security and Compliance Needs**
+ What regulations or data governance policies must the EDW comply with?
### **Integration with Existing Systems**
+ Which source systems and BI tools does the EDW integrate with?
### **Budget Constraints**
+ What is your allocated budget for hardware, software, services, and ongoing management?
Clearly defining these requirements will guide your EDW selection and reduce misalignments down the road.
## **Cloud vs. On-Premises Deployment: What’s the Difference?**
Choosing the right deployment model is critical when selecting an enterprise data warehouse. Both cloud and on-premise models have their advantages and disadvantages.
### **Cloud-Based Enterprise Data Warehouses**
In a cloud model, the EDW software, hardware resources, and data files are housed within the vendor's cloud infrastructure, allowing online, remote access. AWS Redshift, Snowflake, and Azure Synapse Analytics are all popular models.
#### **The top benefits of cloud-based enterprise data warehouses include:**
##### **Agility and Innovation**
Innovate faster with quicker access to bleeding-edge analytics capabilities since the cloud provider continuously enhances services.
##### **Limitless Scalability**
[Scale independently](https://www.domo.com/learn/article/the-advantages-of-using-a-cloud-data-warehouse-in-your-business) to support spikes in data volumes and user requests. This is useful in dynamic or seasonal use cases.
##### **Availability**
Cloud providers architect redundancy across multiple fault domains for resilience. Achieve over 99.95% uptime via auto-failover.
##### **Pay-Per-Use Pricing**
Only pay for the storage, IOPS, computing resources, and services leveraged to reduce wasted overprovisioning and overall TCO.
##### **Faster Time-to-Value**
It’s operational in days/weeks since it doesn’t require a lengthy hardware setup. Shift focus to deriving insights instead of infrastructure management.
#### **The disadvantages of cloud-based enterprise data warehouses:**
##### **Data Sovereignty**
Your data moves outside the organization to align with the provider's security posture as per regulations.
##### **Vendor Lock-In**
Although mechanisms exist to migrate data across cloud platforms, they still pose challenges, especially at scale.
##### **Network Dependencies**
Your connectivity with the cloud provider impacts data loading speeds and query performance.
##### **Cloud Computing Skills**
Retraining staff may be required to leverage cloud management tools, architectures, and services.
### **On-Premises Enterprise Data Warehouses**
In an on-premises model, the enterprise data warehouse runs on infrastructure located within your physical data centers.
#### **Top benefits of on-premises enterprise data warehouses:**
##### **Enhanced Security**
[Maintain full physical control over data](https://www.stitchdata.com/resources/compare-on-premises-and-cloud-data-warehouse/#:~:text=Benefits%20of%20on%2Dpremises%20data,security%2C%20governance%2C%20and%20availability.&text=An%20organization%20has%20complete%20control,with%20an%20on%2Dpremises%20deployment.) access and protection via private infrastructure.
##### **Customization**
Since you own the environment, you can tailor EDW deployments and settings as per your specific policies and tech stack standards.
##### **Constant Access**
Eliminate internet connectivity issues that disrupt cloud performance. LAN speeds enable faster query responses.
#### **The disadvantages of on-premises enterprise data warehouses:**
##### **Substantial Upfront Costs**
Large CAPEX outlays are required for data center build-outs, servers, and storage before deriving value.
##### **Administrative Overheads**
Your team handles provisioning, patching, monitoring, backups, and upgrades.
##### **Scalability Constraints**
Adding capacity requires extensive data migration planning and downtime. It’s hard to match cloud elasticity.
Consider the pros and cons of each model carefully based on business priorities, long-term trajectory, and willingness to digitally transform. [Hybrid enterprise data warehouse models](https://www.informationweek.com/data-management/hybrid-data-warehousing-best-practices-for-it-integration) blending both cloud and on-premise are also viable, as well as [logical data warehouses](/blog/logical-data-warehouse/).
## **Criteria for Evaluating the Best Enterprise Data Warehouses**
Once you have a clear understanding of your needs and deployment preferences, it's time to evaluate potential EDW solutions based on the criteria below.
### **Data Modeling and Schema Flexibility**
Assess how easily the EDW accommodates changes to your data model over time. Look for auto-optimization features and support for schema-on-read modeling alongside traditional schema-on-write. Evaluate the availability of data hierarchy, aggregation, and metadata management.
### **Scalability and Performance**
Evaluate whether the EDW can scale up and out seamlessly to match the explosive growth in your data volumes and user base. Review query response times under load and examine throughput benchmarks for concurrent user queries. Check for in-memory caching, workload management, query optimization, and other advanced performance tuning features.
### **Security and Compliance**
Check the availability of granular role-based access controls, dynamic data masking, and row-level security policies to protect sensitive data. Review built-in auditing, activity logging, and anomaly detection mechanisms. Aim for regulatory compliance certifications such as HIPAA, GDPR, or SOC-2.
### **Data Integration and Pipelines**
Choose a platform with robust [data integration architecture](/blog/data-integration-architecture/), workflows, and pre-built connectors to simplify loading batch or streaming data from disparate sources. Review offerings for data quality, preparation, governance, and lifecycle management.
### **Analytics and Visualization**
[Leading EDW platforms](https://www.g2.com/categories/data-warehouse) integrate advanced analytics capabilities such as machine learning, predictive modeling, and text and image analysis to supplement SQL querying. Some also provide intuitive, [no-code](/blog/low-code-vs-no-code/) drag-and-drop visualization for on-the-fly dashboard creation.
### **Cloud Architecture and Services**
For cloud-based deployment, scrutinize the underlying infrastructure architecture, service level agreements, failover mechanisms, elasticity, and security controls.
### **License Cost Structure**
Calculate the total cost of ownership over three to five years, factoring in license fees, data egress charges, professional services, and hardware refresh needs.
Beyond technical capabilities, the vendor's vision, stability, partnership approach, and market footprint matter, too. Develop a scorecard to rate solutions based on your "must-haves" and ideal wishes.
## **The Bottom Line**
The truth is data enterprise warehouses are from a bygone era and are best suited only for enterprise-level companies. For startups and SMBs, there are much better options, such as data virtualization, logical data warehouse, and [zero-ETL](/blog/what-is-zero-etl/).
Partner with Peaka to meet your data integration needs with its state-of-the-art [zero-ETL approach](/blog/zero-etl-vs-modern-data-stack/), offering hassle-free data integration without having to copy or move your data.
See Peaka’s [growing library of custom integrations](/integrations/).
--- START: blog/best-figma-alternatives/best-figma-alternatives.md ---
# **The Best Figma Alternatives (For Designers and Freelancers)**
Did you know that 77 percent of [small businesses already have websites](https://smallbiztrends.com/2021/08/small-business-no-website.html) set up to boost their business credibility, improve brand awareness, and maximize growth opportunities? However, 1 in 4 small businesses has yet to establish a site, which could help them compete in a crowded market. A good website lets businesses establish their legitimacy and better deliver their message. Of course, this is where web designers and freelancers come in.
The rising demand for talent who can deliver the best results design- and interface-wise has led to a vast market for efficient design and collaboration tools and platforms. Today, there are many apps, software, and sites where designers and freelancers alike can collaborate on projects and get seamless feedback from clients. One prominent example is Figma.
## **What is Figma?**
Figma is a collaborative design interface tool focusing on real-time collaboration between its users. The beauty of Figma is that it allows users to work together on a browser-based, cloud-based design tool—including the software development team—so everyone can keep track of design changes. Software developers often need a diverse set of strong interdisciplinary skills to create a functional software product, especially as their competitive job market is expected to grow [24 percent by 2026](https://www.bls.gov/ooh/computer-and-information-technology/software-developers.htm). Skills including creativity, relationship management, and programming are all important for a good [software developer](https://online.maryville.edu/online-bachelors-degrees/management-information-systems/careers). Figma enables these developers to collaborate live with designers, ensuring projects flow smoothly from the planning and design stages to prototypes and execution. Moreover, working with a hands-on design approach through Figma lets developers improve their own skills in creating software.
However, recent developments for Figma may push some of its four million users towards making a switch to other platforms. The $20 billion [purchase of the platform](https://techcrunch.com/2022/09/15/adobe-is-buying-figma-for-20b-taking-out-one-of-its-biggest-rivals-in-digital-design/) by design giant Adobe, for instance, has got designers and freelancers worried that the incoming Adobe integrations might complicate simple, easy-to-use Figma. Below, we'll cover some excellent Figma alternatives for those looking for new digital collaborative workspaces:
## **Canva**
While mainly geared towards graphic design and presentations, [Canva](https://www.canva.com/) is a popular platform for creating many brand assets for small businesses or individual branding purposes. The platform's collaboration feature, called Canva for Teams, lets users and teams of all sizes work on designs together seamlessly in real time. Canva's web-based nature also makes it an unrestrictive, cross-platform workspace that ensures everyone on a team can log in and start contributing to a project.
For $12.99 a month, users can upgrade to Canva Pro for premium features, including access to premium images and media assets. Recently, Canva announced [its own productivity suite](https://fortune.com/2022/09/14/canva-design-melanie-perkins-workplace-tools-suite-google-docs-microsoft-office-adobe/) to rival that of Google Workspace, Microsoft Office, and Adobe's Creative Cloud, bringing forth collaboration opportunities that extend beyond design.
## **Penpot**
Penpot is an online design workspace and the first of its kind to boast an [open-source build](https://opensource.com/article/21/12/open-source-design-penpot). Created for specialized design and prototyping, Penpot provides real-time collaboration across teams to seamlessly create designs and prototypes for further insights into user interaction. Similarly web-based as Figma, Penpot won't restrict its users to installations and specific operating software, providing multi-platform and tech-friendly collaboration.
Due to its open-source nature, Penpot works with SVG (open web standards) formats, offering contributors various choices of tools to use to contribute assets to a project, all for free. We've previously written about [tech giants and open-source tools](/blog/open-source-and-tech-giants/), and how open-source tools form a loyal and dedicated community. Because of this, Penpot stands tall among its bigger and more popular contemporaries.
## **Adobe XD**
Coming from one of the biggest design software companies, [Adobe XD](https://www.adobe.com/products/xd/pricing/free-trial.html) is a design and prototyping software. Unlike Figma and the other alternatives listed so far, Adobe XD isn't a web-based tool, even though it's available on both MacOS and Windows. Similar to most other Adobe products, XD comes in a 7-day free trial, and then $9.99 a month.
Like other Adobe software, Adobe XD uses the same Creative Cloud system, facilitating real-time collaboration between designers. Additionally, the system also lets design teams execute prototypes and user interfaces that deliver high-quality results. This feature gives users access to Adobe's Creative Cloud Libraries for quality assets. While there aren't any official updates on web-based development yet, with Adobe's recent purchase of Figma, users are currently speculating on what Adobe XD will look like in the near future.
## **Sketch**
[Sketch](https://www.sketch.com/) is another design collaboration tool great for high-quality prototyping while serving as a live workspace for teams to work in. It offers both a web-based version and a software format for MacOS. Sketch also has an iOS app where users can view documents, test software prototypes directly on an iPhone, and even mirror designs simultaneously with edits on Apple products.
While often dubbed "just a Mac app," Sketch's features extend beyond Mac nativity. Sketch gives users a full offline workflow along with the use of an open file format for easy collaboration and asset contribution across other design tools and platforms. After a 30-day free trial for both individuals and teams, Sketch costs $9 a month or $99 yearly.
## **Conclusion**
Ultimately, the best Figma alternative depends on your use case as a designer or freelancer. For example, designers who are accustomed to Adobe programs and their interface will benefit from not having to re-learn features and navigation in Adobe XD, especially if there will be significant updates post-Figma acquisition. If your setup functions within a Mac ecosystem, on the other hand, perhaps the Mac-exclusive Sketch can be a better fit for a more seamless workflow and exchange of assets. For designers and small businesses just starting out, alternatives such as Penpot and Canva that come at no cost will be better. Either way, the design tool is only a part of the bigger web design process. The ideal alternative will be one that best supports your productive, creative workflow.
--- START: blog/best-hr-software-for-startups/best-hr-software-for-startups.md ---
# **The Best HR Software for Startups**
People are the most precious assets of any organization. This is all the more so for startups, which usually have little more than bright ideas and a few even brighter people willing to turn those ideas into reality. A large, established enterprise can afford to make a few wrong choices in hiring people every now and then since it has the resources to make up for such a mistake. Startups, though, can ill-afford to do that, and have to hit the jackpot every time they hire someone until the business takes off.
The pressure for startups doesn’t end with hiring, either. The need to manage the workforce, instill a certain culture into them and sort out problems before they spiral out of control combine to make Human Resource Management one of the most critical areas for a startup. A well-designed HR strategy for a startup should ensure picking the right teammates, seamlessly integrating them to the existing structure and making sure that they are happy together.
Bootstrapped startups would be wise to leverage cloud-based SaaS for tasks like web site design, payment management, email marketing and time management on the cheap. Cloud-based HR software can provide a startup with similar added value. Although there are [different versions of HR software](/blog/choosing-hr-software-startup/) such as Human Resource Information Software (HRIS), Human Resource Capital Software (HRCS) or Human Resource Management System (HRMS), here we will focus on the latter since it is the HRMS that offers the end-to-end capabilities from applicant tracking to employee onboarding to performance management to benefits and compensation management. We will start off with an account of the capabilities a good HR software equips startups with.
## **5 reasons why startups should invest in HR software**
Implementing a Human Resource Management System (HRMS) in early-stage startups provides an affordable solution to managing HR tasks without the need for a full-fledged HR department, allowing founders to concentrate on business growth while cutting costs and paperwork. Additionally, HRMS enables data-informed decision-making by digitizing HR processes and generating key performance indicators from HR data, laying the groundwork for a data-driven company culture. Furthermore, HRMS enhances employee engagement by offering a transparent platform for self-service in HR processes, transforms performance reviews into a continuous, comprehensive evaluation process, and ensures the security of sensitive personal and business data, safeguarding against data breaches and legal complications.
### **Dedicated HR management at an affordable price**
The small size of the team in an early stage startup usually does not justify a full-fledged HR department, and thus founders end up attending to HR-related tasks. HRMS can help with most of those tasks, from applicant tracking to scheduling interviews to payroll management, all of which would otherwise have to be done by a founder, and allows founders to focus on growing their business. In the meantime, it cuts the paperwork, reduces the time needed to create documents, lowers the HR headcount and saves the startup much-needed funds.
### **Data-informed decision-making made possible**
Facing many daily challenges and being sometimes overwhelmed by the sheer number of tasks at hand, startups can hardly afford detailed [record-keeping](https://solutiondots.com/blog/importance-of-hr-system-for-startups/). HRMS solves this problem by digitizing the whole HR process and collecting, organizing and managing HR data in an efficient way. Stats like employee retention rates, absenteeism and leave requests collected on the system can be converted into [meaningful KPIs](https://rubygarage.org/blog/hrms-benefits-for-business), which can then be used to gauge how well the business is performing. These stats lay the foundation of a data-driven company where data will be informing the decision-making process.
### **Employee empowerment through increased visibility**
HRMS offers a transparent platform where HR data can be viewed and modified by employees. HRMS gives employees increased visibility into the HR info, enabling them to self-serve. They can manage their leave requests, customize their training plans and update personal information on the platform. This not only introduces a more inclusive culture, but also helps reduce errors in data collection as the employees themselves would be providing and reviewing inputs.
### **Performance reviews transformed**
The dreaded and usually unproductive annual performance reviews are turned into [continuous performance management](https://www.startupguys.net/startups-invest-in-hr-software/) by HRMS. This new concept is built upon two ideas: Year round assessment of performance and 360-degree performance evaluation, which involves feedback from various stakeholders such as colleagues, clients and supervisors. This allows employees to make incremental changes to their performance without the need to wait for the annual performance review and learn from their mistakes before it is too late.
### **Data security taken care of**
Whether it is paper-based or on cloud, an HR system hosts a plethora of highly sensitive data: Personal information on employees, their social security data, payment details etc. Data security and privacy built into HMRS ensures safety of sensitive business and personal data. This prevents [data leaks](https://rubygarage.org/blog/hrms-benefits-for-business), which could trigger lengthy legal processes in addition to the damage to the reputation of the company.
## **Top 6 HRMS for startups**
### **Gusto**
[Gusto](https://gusto.com/) brings its magic into your HR effort right from the start at the hiring stage. It creates offer letters and facilitates onboarding by creating with one-click accounts for the new team member. Payroll management can be a real hassle for startups. Luckily, Gusto offers a comprehensive solution package that automatically calculates, files and pays payroll tax and by doing so, ensures full legal compliance. When it comes to benefits management, Gusto really shines by offering fully-customizable benefit packages that will perfectly fit your company and the expectations of your employees. It also allows you to tailor your paid time-off policies according to the needs of your business and manage the leave requests made by your employees. The fact that time tracking is integrated with the payroll management saves the startup a lot of time and effort to bring those two in sync.
The downside of Gusto is that its most basic plan does not include popular capabilities such as time tracking and onboarding.
The basic plan with payroll and benefit management features costs $49 per month with an additional $6 per month for each person.
In order to have the time tracking and onboarding tools, you should opt for the middle plan which comes with the same base price of $80 per month but with an added $12 per month for every person.
Gusto's Premium plan costs $180 per month with an additional $22 per seat.
### **BambooHR**
[BambooHR](https://www.bamboohr.com/)’s applicant tracking feature aims to smoothen the ride for both the company willing to hire and the applicant. The process starts with the one-click job posting on most popular job boards and social media sites. The applicant is kept up-to-date with continuous communication throughout the process. The system can draw up offer letters and allows the company to choose from among a group of templates to tailor the best onboarding experience possible. By making e-signatures an essential part of its system, BambooHR ensures a swift, stress-free onboarding process that does not waste paper.
Once in, all the information regarding an employee is gathered on a single database, which minimizes the risk of error, facilitates integrations with other applications and gives the employees visibility into their data. BambooHR prides itself on its reporting and data analytics capabilities, which are increasingly important in today’s data-informed management style. Its reports even have customized viewing option, keeping sensitive information out of the reach of people who should not see it.
BambooHR is offered in two plans: Essential and Advantage. The prices for these plans are not publicly available and potential customers are invited to ask for a quote. Some of the features like applicant tracking, onboarding and electronic signature are solely available with the Advantage plan and still others are offered as add-ons, which together make up the few cons of the system.
### **Trinet Zenefits**
[Trinet Zenefits](https://www.zenefits.com/) offers an integrated HR platform that can handle every task related to an employee from the first day it joins the company to the day the two part ways. Zenefits capitalizes on its partnership with Checkr to provide background checks on applicants. It makes a seamless onboarding process possible, with the employee data syncing with the payroll automatically. Promotions, certain decisions regarding leave management and terminations can be arranged by way of automated workflows, freeing up a lot of time for a startup.
Zenefits particularly excels in two areas thanks to two features that differentiates it from rivals: The first one, compensation management, provides benchmark figures for employee salaries. It uses its database of salaries collected from more than 100,000 employees across more than a hundred industries and provides its customers with information on what similar companies pay for an employee of comparable skill and experience level in a particular location or industry. This arms the Zenefits customers with the necessary information to make the best offers to the best candidates. The second difference maker in Zenefits toolkit is employee performance management. This suite allows the company to offer customized goal management and 360-degree feedback for each employee.
Zenefits comes with three pricing plans: Essentials for $8 per month per employee, Growth for $16 per month per employee and Zen for $27 per month per employee. The most affordable plan comes with popular features such as automated onboarding and time-off tracking, unlike Gusto and BambooHR, which do not offer those in their base plans. For its highly competitive compensation management and employee performance management features, customers should at least opt for the Growth plan, though.
### **Cezanne HR**
[Cezanne HR](https://cezannehr.com/) offers a modular platform that lets customers pick and choose the features they need the most and change the configuration of the platform as they go. In addition to traditional HR functions such as onboarding, time tracking or performance management, Cezanne HR offers specialized modules like the Career & Succession Planning Software. This particular module helps a company develop its talent pool to match company goals and groom certain people for certain roles. The unexpected resignation of a key employee can really test the resilience of a company. However, building a talent pipeline around Cezanne HR’s Career & Succession Planning module makes it possible for a company to quickly promote a qualified successor and weather the storm. Understanding the skill set of your employees and nurturing them in a pipeline framework render your company resilient when a key employee quits unexpectedly.
Cezanne HR can be considered as the embodiment of the maxim “think global, act local” as it not only offers free-of-charge translations in 10 different languages, but also provides multi-currency record-keeping and processes that can be configured according to local needs. Its multi-language services and compliance with local laws and regulations in different countries make it the HR software of choice in the age of remote work and a global workforce. Bringing your foreign employees and freelancers into the fold is much easier with an HR platform tailored to their needs.
Cezanne HR’s pricing is contingent on the modules picked and the active headcount of the customer. Prices start around £200, which might be a bit steep for a startup. However, the modular approach might fit the growth curve of a bootstrapped startup since founders could add different features as needs arise, and its multi-language interface could be the right call for startup leveraging talent from different parts of the world.
### **Freshteam**
If you are determined to perfect your recruiting game, [Freshteam HRMS](https://www.freshworks.com/hrms/) can be the tool you are looking for. Its Applicant Tracking feature offers more than a hundred job description templates and is built to leverage job boards, social media and email automation to bring in the best talent out there. It builds a funnel from the candidate sourcing stage to applicant engagement to offer letters, and in that sense, Freshteam HRMS is a recruitment tool first and foremost.
In addition to recruiting, Freshteam allows you to monitor and manage time-offs. It even lets you set up automated workflows for time-offs by defining the rules for them and identifying the necessary documents to be uploaded. However, the one area Freshteam truly excels in is reporting. The platform offers 7 curated reports on topics such as interviews, job postings and offers and hires, all of which can serve as metrics to evaluate your recruitment performance with.
In terms of pricing plans, Freshteam looks more startup-friendly than most of its competitors as it offers a free plan for up to 50 employees and 3 published job postings.
Its second plan, the Growth, charges a monthly platform fee of $71 and $1.20 per employee per month. This plan comes with recruitment automations and HR reports and analytics.
The Pro plan charges a monthly platform fee of $119 and $2.40 per employee per month. On top of the Growth plan, Pro plan offers advanced features like Talent Pool Management, multiple language support and offer management.
The Enterprise plan charges a monthly platform fee of $203 and $4.80 per employee per month and comes with a dedicated account manger, one click data export and advanced leave exports, in addition to the features offered in the lesser plans.
### **factoHR**
[factoHR](https://factohr.com/) is a mobile-first HR and payroll software that simplifies hiring and payroll processes for fast-growing startups. The platform provides onboarding tools that generate custom offer letters and joining kits, while self-onboarding features allow new hires to input their details directly. This approach reduces manual work and minimizes data entry errors.
The payroll system uses a wizard-like process that manages complex salary structures and statutory compliance requirements, ensuring employees receive accurate payments on time. Attendance and leave management integrate seamlessly, offering hybrid and remote teams biometric scanning, GPS tracking, and mobile punch-in options.
The modular dashboard delivers real-time insights into attendance patterns, performance metrics, and payroll data for HR teams and company founders. Automated workflows handle approval processes and document management tasks efficiently. The platform also includes asset tracking capabilities, internal ticketing systems, and peer-to-peer recognition features that help create a transparent and efficient work environment.
factoHR provides multilingual payslips, multi-currency support, and compliance with local employment regulations for startups expanding across multiple regions. This makes the platform suitable for global teams operating in different countries.
Pricing starts at $60/month for up to 50 employees, with an additional $0.83 per month for each extra employee beyond that limit. Billing occurs quarterly. Users frequently praise the platform for its user-friendly interface and automation features. However, some users report experiencing a learning curve during initial setup and occasional server performance issues.
## **How does Peaka help you enrich your HR data?**
[Peaka](/) simplifies data integration for startups and small to medium-sized businesses (SMBs), which typically cannot afford to employ large data teams. It uses APIs and ready-made connectors to pull in data from CRM relational databases, cloud platforms, and SaaS apps.
+ Traditional data integration relies on data replication to move data into a data warehouse to unify data from different sources. This process involves ETL pipelines and data modeling, which translates into significant maintenance hassle and related costs. Peaka offers startups and small to medium-sized businesses (SMBs) an affordable alternative, as it eliminates the need for data warehouses. By leveraging data virtualization, Peaka allows companies to unify their data with a much smaller team.
+ Companies can use Peaka to retrieve data from their HR systems and join it with data from any database or SaaS tool. This enables users to form a single view of truth and improve decision-making during performance evaluation and hiring.
+ Peaka’s dedicated connectors for BI platforms like [Looker Studio,](/blog/data-visualization-with-looker-studio-integration/) [Power BI,](/blog/data-visualization-with-power-bi-integration/) [Tableau,](/blog/data-visualization-with-tableau-integration/) [Metabase,](/blog/data-visualization-with-metabase-integration/) and [Apache Superset™](/blog/data-visualization-with-superset-integration/) streamline data visualization for even non-technical employees. Users can push their consolidated data to their BI tool of choice and turn it into dashboards that reveal trends and patterns hidden in tabular data.
Check out Peaka’s growing [library of custom connectors](/integrations/) and [book a free demo](https://calendly.com/peaka/demo) to see Peaka in action!
--- START: blog/best-nft-marketplaces/best-nft-marketplaces.md ---
# **Top 7 NFT Marketplaces of 2024**
In the digital space discussion these past few years, nothing is as polarizing a topic as NFTs. People either adore them and all the possibilities they bring or hate them with a burning passion. One thing’s for sure, though, more and more aspiring investors, businesses, and budding crypto enthusiasts are seeing the [value of NFTs](https://www.exodus.com/news/what-makes-an-nft-valuable/) and are hoping to join the game sooner rather than later.
And, really, who wouldn't be interested? [Just last year](https://www.ft.com/content/e95f5ac2-0476-41f4-abd4-8a99faa7737d), NFTs reached a market capitalization of $41 billion and a more than $30 million daily trading volume. Because of this exponential growth, all eyes are on the industry and its increasing number of marketplaces.
We've listed below the seven best marketplaces available today if you're curious about where you should buy or sell NFTs.
## **OpenSea**
[OpenSea](https://opensea.io) has been in the game since 2017, making it one of the most long-standing players in the NFT market. Because of its experience, it is now one of the world's leading NFT marketplaces. Since its launch, it's also the platform that brought NFT trading to the mainstream audience. To add to its stellar record, OpenSea has the largest trading volume globally.
OpenSea allows users to create, buy, and sell various NFTs. These include digital collectibles, music, art, trading cards, virtual worlds, and other digital tokens.
OpenSea's platform is based on the Ethereum blockchain, and it has partnered with the Polygon network to reduce gas costs. In addition, users may access more than 700 NFT projects through the platform, with an incredible 80 million NFTs available to trade.
Furthermore, one of OpenSea's most significant advantages is that it supports over 150 different cryptocurrencies as payment. This allows investors to buy and sell NFTs with their crypto balance in a simple manner. OpenSea charges sellers a 2.5 percent transaction fee when their item sells, but the buyer pays nothing (other than standard network fees).
## **Crypto.com**
Alongside OpenSea is [Crypto.com](https://crypto.com/nft), one of the world's fastest-growing NFT platforms. The marketplace began solely with NFTs on the Crypto.com blockchain, but it has now been expanded to include the Ethereum blockchain. As a result, the number of NFTs available to buy and sell on this platform has considerably increased.
What sets Crypto.com apart from its competitors is that it offers some of the lowest feeds for buying and selling NFTs. In addition, when you purchase an NFT on Crypto.com, you won't have to pay any transaction fees. They only charge sellers and creators a fee of 1.99 percent, which is relatively low.
Another great feature of Crypto.com is the way it curates its collections into recommended galleries. This makes it easy to identify the most anticipated releases and digital art that will most likely appeal to you.
The platform also allows sellers to run auctions and offer a buy-now price. So, if you see an NFT you want, you can buy it right away rather than risk losing out to another bidder.
## **NFT Launchpad**
Compared to the first few platforms we mentioned, [NFT LaunchPad](https://nftlaunchpad.com) is a relatively new NFT marketplace created by and for creators. It only launched in February 2022. However, because the platform has made it easy to create your own NFTs using formats like MP4, it has already attracted a number of designers and talents who are just getting started with their NFT journey. So if you’re looking for something new, NFT Launchpad is the best place to be!
The platform has an extensive collection of NFTs to choose from, and the great thing about NFT Launchpad is that it's easy to navigate through everything. Art, gaming, music, sports, collectibles, and more genres are available on this marketplace.
Creators can also mint numerous NFTs simultaneously, set their royalty structure, and sell at a fixed price or at an auction. Currently, the platform is compatible with MetaMask wallets, and support for Trust Wallet is well on the way.
## **Binance**
If you're looking for a highly-recommended platform that offers low fees, look no further than [Binance.](https://www.binance.com/en/nft/home) As one of the most notable cryptocurrency exchanges in the industry, Binance has a leg up in buying and selling NFTs. The marketplace is also one of the largest NFT marketplaces, with a collection size of over 2.5 million.
Binance organizes its NFTs into trendy collections, making it easier to identify art you're likely to be interested in. Another exciting feature is its "Mystery Boxes." You don't even have to pick which NFTs you want to buy! These mystery boxes include a small number of NFTs from a single collection for a low, fixed price. So you might get a bunch of pretty standard NFTs, or you could get a few rare objects worth much more than you paid.
## **SuperRare**
[SuperRare](https://superrare.com) is an Ethereum-based NFT platform that’s primarily a marketplace for consumers to purchase and sell one-of-a-kind, limited-edition digital artworks. Each piece of art is created by an artist and tokenized as a crypto-collectible digital commodity that you can own and trade. The platform provides a new way to engage with art, culture, and collecting on the internet.
Before anyone can place any digital artwork for sale on the platform, it must undergo a rigorous verification and approval procedure. SuperRare aims to foster creativity among the few established creators on its marketplace to guarantee that digital art collectors get the most out of their collections.
While SuperRare is not as eventful as all the other platforms listed above, it does have some pretty unique digital art pieces. However, one con of the platform is that it charges artists a steep 15 percent fee on direct sales.
## **Nifty Gateway**
[Nifty Gateway](https://niftygateway.com) has NFTs, which they call Nifties, built on Ethereum. The platform specializes in premium NFT drops or NFT releases with a limited number of assets. The site has featured a wide range of well-known musicians and creatives in the past, including Beeple, Steve Aoki, and Grimes. Nifty Gateway's selection is geared primarily towards high-end investors due to the strong demand for these NFTs.
Nifty Gateway isn't just an excellent platform for creators. It allows newcomers to the NFT market to purchase NFTs using a credit card, making it incredibly user-friendly. It also has open editions, which are NFTs that you may mint for a limited time for the base price. These limited editions are an excellent opportunity to acquire beautiful art without breaking your budget.
One thing to know about the platform is that it’s founded on a solid policy foundation that prioritizes innovation and authenticity. As a result, it is well-known for having one of the world's best verification process systems.
## **Rarible**
[Rarible](https://rarible.com) is a community-based NFT marketplace that allows users to purchase and sell various NFTs. In addition, the platform includes a user-friendly interface that will enable users to mint and trade NFTs easily.
The platform is a one-of-a-kind cryptocurrency exchange that supports three different blockchain networks: Ethereum, Flow, and Tezos. This multi-chain capability allows users to mint, buy, and trade NFTs from these viable blockchain platforms in the Rarible NFT marketplace.
If you're looking to discover new and unique NFTs, Rarible is the marketplace for that, as you can browse through trending collections, top sellers, and ongoing live auctions.
Rarible's prices are denominated in Ethereum, but users may also use the platform's Rarible token to make purchases. Both buyers and sellers pay a 2.5 percent transaction fee on the marketplace.
## **Final Thoughts**
Saying NFT marketplaces are taking the world by storm is probably an understatement. With more and more platforms popping up every day, the industry will become even more competitive. So if you haven't joined the game yet, there's no better time to do so than now.
If you’re still at the very start of your NFT journey, don’t forget to [learn everything you can about it.](/blog/best-nft-marketplaces/) So gather your artworks and collectibles, and crack on displaying your works with [Peaka's NiftyExpo!](/templates/)
--- START: blog/best-no-code-app-builders/best-no-code-app-builders.md ---
# **The Best No-Code App Builders In 2026**
Have you made up your mind to launch a brilliant mobile app but are not aware of the coding process? If so, no-code app builders could be the answer to your prayers.
No code app builders enable you to design or create IOS apps, Android apps, and Web apps with little to no technical ability. That’s one way to reduce resources and costs in finding and hiring a well-experienced, trustworthy, or recognized coding team.
According to a Gartner report, by 2024, the development of no-code apps will be answerable for over [65 percent](https://www.zdnet.com/article/top-8-trends-shaping-digital-transformation-in-2021/) of app development activity. It is predicted that the no-code development platforms will generate an income of [187 billion dollars by 2030](https://www.globenewswire.com/news-release/2020/11/10/2123468/0/en/Global-187-Billion-Low-Code-Development-Platform-Market-to-2030.html) worldwide. [Around 75 percent](https://quandarycg.com/low-code-statistics/) of the largest enterprises will utilize no-code development tools by 2024, not only for developing IT apps but also for developing initiatives for the citizens.
Keep reading for a comprehensive overview of top-notch no-code app builders on the market in 2022 for your particular needs.
## **1. Appypie–One of the best no-code app builders for mobile**
Appypie accelerates the creation of mobile apps by ten times! The best feature of this app creator is that no coding skills are necessary to begin using it. Without any prior technical experience in mobile app development or design, you can try it for free and build some unique apps.
You can easily drag and drop innovative functionality for your application using the editor in Appypie. The tool's workflow optimization does not require much work from you. You can successfully handle dull activities with the use of triggers and actions. This no-code app creator offers classes on developing the software for individuals from beginners to experts at all skill levels, whether you're constructing a dating app or a delivery app.
## **2. Clickup–A powerful all-in-one no-code solution for all businesses**
You can manage projects, papers, deadlines, and remote teams with the help of ClickUp's no-code solutions. Numerous companies now use ClickUp. It is a flexible no-code tool that enables you to make user-friendly dashboards. With its adaptability, ClickUp provides several interfaces with various well-known programs and platforms.
It is a full-featured app with the aspirational tagline "one app to substitute them all." Virtually, ClickUp is a capable platform that provides a fantastic no-code tool to link with various information sources or to build pathways and procedures for utmost efficiency.
## **3. Retool–Arguably the go-to software for building internal tools for businesses**
Retool stands out because it provides a variety of adaptable building components, including tables, charts, forms, and maps. It enables connections to external information sources but prevents the creation of sophisticated tools. This tool can be used as a no-code tool, but still, it functions as a low-code solution. That’s because the developers have to write API queries manually. Although it is easy to accomplish, it requires some practice.
Are you an architect? Or do you require a low-code answer? Retool is an excellent option for you. It allows you to create unique JavaScript code for virtually any component. Retool has gained recognition as a customizable extendable as a result. This software developer is passionate about security. Retool also offers friendly, responsive customer service and lets you utilize its corporate package to secure various apps against unauthorized users.
## **4. Bubble–A zero-code tool for web apps**
Bubble enables you to construct various apps without typing a solitary line of code. You may build a prototype to test your ideas before converting them into actual products. Additionally, you may discuss your suggestions with your clients. Furthermore, since Bubble serves the app, you don't require a web server.
As Bubble offers a fun trial that lets you design your homepage, you may try it out for free. Additionally, it has raised millions of dollars to make app development simpler for everyone. With Bubble, you may test your concept with a prototype before sharing it with platforms that interact with customers without having to deal with Javascript, HTML, or sizable databases. In addition, several venture-backed businesses already employ Bubble to drive their offerings.
## **5. Airtable–No-code data management app builder for the operations team**
Airtable lets you make user-friendly spreadsheets and databases. Checkboxes, hyperlinks, scanners, and downloads may be added to data management spreadsheets to make them more active. It allows smaller teams and individual users to expedite project workflow. In addition, you can create some very compelling visualizations to streamline facts and tasks further.
You may easily skip laborious and boring activities using Airtable. Airtable's ability to automate some operations and customize team-specific notifications is the cherry on top. This aids in focusing you or your organization on the most crucial matters!
Airtable is a very potent app builder that resembles a project management methodology used by big organizations and corporations to handle their data and spreadsheets and produce solutions in line with the teams' requirements. Additionally, you may benefit from its periodic frameworks and user-friendly design in the advertising, manufacturing, operational processes, HR, sales, and finance departments to achieve new levels of efficiency and organization.
## **6. Adalo–An intuitive & easy-to-use no-code app maker**
Adalo is a platform designed for front-end development, making creating online and mobile applications simple. You may quickly add features and UI Modules to your apps and carry out backend activities with its drag-and-drop functionality. Using the Actions feature, you may describe the on-page mechanism that starts the backend events.
The operating system of your application, Adalo, consists of a built-in google doc database that you can use to input and recover information, such as the items in an online store. The Adalo backend does not support the conventional backend logic. However, it incorporates other programs that provide genuine backend functionality.
Does it strike you as a little technical? You don't need to learn any programming or app design, so don't worry.
## **7. QuickBase–A flexible tool enhancing collaboration between the business and IT teams**
Even those with less technical aptitude may create web applications at scale using QuickBase. It links information, people, and ideas.QuickBase is recommended for users willing to develop complicated systems at scale. The platform allows you to utilize and include several applications in your project and easily translate concepts into practical applications.
Quickbase comprises a platform of programs that enable users with no technical expertise to scale and manage across many platforms. Additionally, it makes it quite simple for companies to effectively translate business ideas into applications.
## **8. Kintone–A powerful suite of countless tracking tools to enforce teamwork**
Teams can effectively work together to create apps with Kintone. This software assists organizations and groups in creating robust tools and analytics to improve workflows. You may create internal apps using Kintone to encourage cooperation and teamwork.
You may use Kintone to create a unified dashboard that is perfect for all of your reports, KPIs, and apps rather than keeping them all separate. With Kintone's no-code app builder, you have the flexibility of Excel plus a robust database to centralize your spreadsheets so you can complete the above activities without technical knowledge.
## **9. DraftBit–An online editor to access web browsers**
You don't need coding experience or technical abilities to create apps using DraftBit. Instead, DraftBit's pre-built components may be used to develop the software. Bits and Blocks are its two constituent parts. The first component type enables more accurate app creation, while the second promotes higher-level and quicker app development.
DraftBit also lets you preview new applications on your mobile device. So, it is more than just a tool for creating apps; it also allows you to test them on actual hardware.
## **10. AppSheet–An exceptional & less technically-oriented app creator**
You can build a whole application using AppSheet without writing a piece of programming. With AppSheet, you can easily add pre-built functions to your app, including capabilities like location capture, barcode scanning, email sending, picture capture, location logging, scanning for barcodes, report generation, logic application, and much more.
## **11. Peaka: No-code app development meets easy data integration**
[Peaka](/) is a no-code platform for building responsive, customer-facing web apps. The platform features a drag-and-drop interface that allows even people coming from non-technical backgrounds to develop apps and has served thousands of users since its inception.
The latest iteration of Peaka boasts an advanced data integration capability addressing the data integration needs of startups and SMBs. These companies typically lack the financial means to build data warehouses or employ data teams to maintain such infrastructure. With the new Peaka, they can now bring together their data wherever it resides without having to copy or move it. Once the data is united, users can leverage it to automate tasks, build workflows, or power internal tools and web apps.
"Data is the new oil," as they say. Peaka is democratizing access to data and empowering startups and SMBs to make the most of this powerful resource.
**To bring things to a close,**
Do you find coding difficult and cumbersome? No-code app developers execute the job of app designers for you; you'll undoubtedly start to enjoy apps. They give you a non-technical and simpler interface to build an app per your customers' needs. This way, you need not sit in front of your PC and suffer from mental stress to develop any app by coding manually.
App development is difficult since it calls for ingenuity and unrelenting effort. No-code apps are amazing tools that level the playing field non-technical people and enable software development, process improvement, making the creation of new apps easier.
## **Author Bio**
*Mike is a tech blogger and an avid reader. He has written various blogs and articles about the latest developments in blockchain technology, [Web3 development](https://bestweb3development.com/), Metaverse, and AI. When he is not researching or writing, he is probably playing Call of Duty, he is an avid gamer too!*
--- START: blog/best-no-code-communities/best-no-code-communities.md ---
# **Best No-Code Communities, Curated Lists & Resources in 2026**
Over the past few years, there has been an explosion of no-code app development and technical problems. By 2030, the global low-code development platform market is expected to produce [$187 billion in revenue](https://userguiding.com/blog/no-code-low-code-statistics/) and account for more than 65% of app development by 2024.
It’s simple, really. The more people with access to no-code tools that don’t require years of development education or skills, the faster new products will enter the marketplace. The world is full of creative people eager to find new ways of introducing their latest time-saving app or entertaining video game.
That is why we wanted to highlight some of the no-code, low-code community resources that have been mentioned frequently by our customers and guests. Many of these sites and tutorials are perfect for the beginner looking to get started with no-code platforms for their next MVP project. Here is our list of the best no-code communities and resources in 2022.
## 1 - Popupsmart 694 No-Code Tools
Popupsmart put together an amazingly [comprehensive list](https://popupsmart.com/no-code-tools/) of the latest and greatest no-code apps available online right now. They based their list on the low-code tools that are most frequently upvoted by users on Producthunt. Producthunt is an American website dedicated to sharing new products and discoveries based on user submissions. Popupsmart has an excellent array of mobile apps, no-code websites, and tech products sure to enhance your next project.
## 2 - Nocodelist.co
The aptly named [Nocodelist](https://nocodelist.co/) has over 300 no-code tools and products broken down by different categories. You can find excellent no-code apps for solving everything from working in the Blockchain to designing your own communities section of your website. The goal of the project is to identify those perfect no-code software solutions using user-driven upvotes and endorsements. This is a great place for beginners to get their feet wet before taking a deep dive into their specific niche.
## 3 - NoCodeDevs
[NoCodeDevs](https://www.nocodedevs.com/) was developed by famed no-code enthusiast Art West as a community that supports different creatives who want to connect and share stories about no-code/low-code solutions to their everyday problems. Users post everything from quizzes to webinars about their digital transformation into the no-code world and using automation for their projects. You’ll find a lot of high-powered tech insiders using this platform to swap ideas.
## 4 - 100 Days of No-Code
[100 Days of No-Code](https://www.100daysofnocode.com/) is a relatively newer community operating on a unique premise. Their underlying structure is that you should be able to complete any no-code project using available online resources by finishing 1% of the intended roadmap each day. By the end, you’ll have 100% completion in 100 days. They enforce this idea by using a public accountability system that is quite enlightening to follow. It gives you insight into how other groups and projects navigate the no-code platforms online.
## 5 - No-Code HQ
If you’re looking for more of the simple old-school sharing of project ideas, head over to [No-Code HQ.](https://community.nocodehq.com/) This is a community of like-minded individuals showcasing their latest successes and challenges involved in their project development. There are excellent tutorials to learn no-code app development with templates and tools that anyone from the beginner to the expert can take advantage of using.
## 6 - Nucode
The unique thing about [Nucode](https://www.nucode.co/) is the detailed sharing of projects being completed with no-code tools. They have a rich community of more than 2,800 members dedicated to getting into the nitty-gritty of how to overcome roadblocks. This is another no-code platform with decent tutorials and learning resources that can help out people who are a little lost in this industry niche.
## 7 - NoCode.Tech
We had to include a Slack community in our list because of the ease of using that platform for sharing information. [NoCode.Tech](https://www.nocode.tech/) is a little under 1,000 strong in its membership of incredible developers, designers, and innovators dedicated to showcasing their latest creations. On top of that, you get access to more than 200 tools and a “fortnightly” newsletter full of insightful industry news and relevant tech anyone in the no-code world would want to check out.
## 8 - NoCoders Academy
It would not be much of a list without some form of an academy. Just like the early days of learning DOS or Javascript, there is now an online no-code community with the goal of offering courses and tutorials for teaching everyone how to use low-code solutions for their next app or software solution. While we are getting a little overdosed on online courses, [NoCoders Academy](https://www.nocoders.academy/) does a great job of separating out the resources so you can pick and choose without having to follow a considerable outline or curriculum.
## 9 - Codeless.how
This is another company that really nailed their name. [Codeless.how](https://codeless.how/) is more on the crazy side of no-code app development that does not prescribe to any rule book. Their out-of-the-box solutions mix and match no-code tools from all kinds of sources for a truly unique outcome that will make you feel more MacGyver than Zuckerberg. We love the tools, topics, and showcases featured on this platform.
## 10 - NoCodeClub
Go and check out this website the first chance you get. They feature some of the coolest retro gaming visuals that you know means they have decent developers lurking in the background ready to answer your complicated no-code questions. [NoCodeClub](https://nocodeclub.co/) is a community of makers who use a gamified leaderboard as an interactive way to award members that collaborate and motivate newer members. It is a very cohesive community where everyone is willing to pitch in on solving a project challenge.
## 11 - No Code Founders
First things first, do not get intimidated by this community. The [No-Code Founders](https://nocodefounders.com/) community features, you guessed it, founders of no-code projects and solutions that have finished and are available on the market. They openly share the no-code tech stacks used and offer real-world advice for overcoming some of the more common challenges and roadblocks to getting a new idea to MVP.
## 12 - No Code MVP
Speaking of MVPs, how about a no-code platform dedicated to getting your new product as quickly as possible? With [No Code MVP](https://nocodemvp.com/) you’re treated to intense tutorials that will accelerate your roadmaps with a more agile response to fixes, repairs, and solutions. Admittedly, this is a messy “get the project out” kind of style, but it does the job well and teaches you a ton about the business of no-code app development.
## 13 - Webflow University
This is another of our “academy” resources that we thought we should feature. While it doesn’t have the scrappy style or rushed sense of producing a product as other no-code platforms, it does offer a ton of valuable insights and lessons taught by industry professionals. We suggest [Webflow University](https://university.webflow.com/) for those readers who prefer a bit more structure to their online learning.
## 14 - Nocodify
We thought it would serve our readers well if we included a secondary no-code source of information from another well-structured company. [Nocodify](https://nocodify.com/) focuses on the individual step-by-step guidance of building a new app using no-code visual development. This is an excellent tool for those that want a more drag-and-drop experience in their online education.
## 15 - Hello Guru
[Hello Guru](https://hub.helloguru.io) is a great place to start for those with absolutely no background in tech whatsoever. First off, we love the name. Secondly, this is a highly visual learning system that breaks down the individual tech and features being used in the no-code community. This means you have a lot more simplified instruction and tutorials available than the high-level information from entrepreneurs and developers who have already completed projects.
## Wrapping it Up
No matter where you stand in the no-code world, plenty of no-code/low-code tools, platforms, apps, and tutorials are readily available online. Many communities have grown up around the complicated world of app development and are more than ready to make the change over to a no-code solution.
When you join these communities, you’re bound to find an enthusiastic group of developers and designers eager to share their ideas, questions, projects, and provide you with pathways to new resources as they are announced. Whatever your style of learning, there is a no-code solution for you.
If you’re ready to jump feet first into the low-code, no-code world, why not start with our professional experts at Peaka? We offer an easy-to-understand way of building web apps and frictionless projects using visual editors that anyone can pick up. This is an excellent resource from our developers, who understand the demand beginners and seasoned creatives have for customizable tools.
You can schedule a demo with us at [Peaka](/) by visiting our site and checking out the many solutions available for your next project.
--- START: blog/best-note-taking-software/best-note-taking-software.md ---
# **The Best Note-Taking Apps of 2022**
In the past, if you were struck with inspiration while doing your weekly shopping, you'd have to scribble your idea down on a scrap piece of paper or maybe even your arm. Today, we have access to powerful note-taking apps that allow you to capture and organize any idea on any device. But with so many options, how do you decide on the best note-taking app for you? Fear not — we've compiled a list of the best note-taking apps available right now.
## Evernote (iOS, Android, macOS, Windows, Web)
You knew it was coming! Founded in 2007, Evernote is one of the most popular note-taking apps out there, with over [225 million users](https://expandedramblings.com/index.php/evernote-statistics/) as of 2019. Looking at Evernote's comprehensive list of features, it's no wonder that it's so widely used. For example, you can add notes in a variety of formats, including text, images, PDF documents, scanned handwritten notes (provided that you have legible handwriting) and even audio clips.
Evernote's versatility makes it an excellent note-taking app for people who like to capture notes on a napkin when they're on the go, as well as people who prefer a more organized approach. You can organize your notes into notebooks, add tags, create notes from calendar events, and even automate your note-taking.
There are [four price plans](https://evernote.com/compare-plans) for Evernote: Free, Personal, Professional, and Evernote Teams. Ignoring Evernote Teams, for now, the main difference between the plans is device syncing, storage and access to AI-based features. For example, you're limited to syncing with up to 2 devices with the free plan, but the Personal plan offers unlimited syncing. In terms of AI features, Evernote can make personalized content recommendations, such as links to web articles, based on what you type, among other features like geolocation searching.
In 2020 Evernote released a thoroughly [updated version](https://evernote.com/blog/new-evernote-android/) of the app for iPad and Android tablets, ironing out some of the previous bugs and making it easier for users to transition between note-taking on the tablet vs. computer.
Overall, Evernote is a robust and powerful note-taking app, but its premium versions are slightly expensive for the average user. As a result, most people will need a good reason to justify going beyond the free version.
## Microsoft OneNote (iOS, Android, macOS, Windows, Web)
[OneNote](https://www.microsoft.com/en-us/microsoft-365/onenote/digital-note-taking-app) is the only note-taking app that can match the mastery of Evernote, and it's totally free. Both apps are similar in terms of functionality - you can draw, record audio, scan images, embed spreadsheets, and organize notes with ease on either of them. However, there are some distinct differences. OneNote is the better option if you want the most features without opening your wallet. Still, Evernote has the edge when it comes to content clipping, organization, and UI.
It's also important to note that while the OneNote app is free, you are limited to [5GB of cloud storage](https://www.pcmag.com/reviews/microsoft-onenote). However, you can buy more storage if you need it, and Office 365 users get much more storage (1TB-6TB).
## Notion (iOS, Android, Windows, Web)
[Notion](https://www.notion.so/) is a relatively new note-taking app with a specific focus on collaboration. In fact, it's more than a note-taking app; it's also a project manager and a reference wiki. So it can be your all-in-one workspace solution if you want it to be.
You can create new notes, called pages, and then populate them with "blocks". Blocks are essentially responsive elements like images, audio, video, text, checklists, code snippets, files, and web bookmarks. You can also embed your current work tools to create a hub for everything you and your team are currently working on. The tables in Notion also function more like databases than tables — every row in the table is its own note that you can update freely.
Notion offers [four pricing plans](https://www.notion.so/pricing): Free, Personal Pro, Team, and Enterprise. With the free plan, you get access to unlimited pages and blocks, can sync across all devices, and share with up to 5 guests. However, if you want to experience some of the more powerful collaboration features, you'll want the Team version.
## Roam Research (macOS, Windows, Linux, Web)
The first three note-taking apps on our list utilize a similar approach to note organization — tags, folders, collapsible note hierarchies. However, [Roam Research](https://roamresearch.com/) does things differently. Described as a "note-taking tool for networked thought," Roam Research links notes together in a web structure (or graph database), making it easy to visualize the relationship between notes.
If you've struggled to find a note-taking app that sticks, it could be down to the hierarchical nature of traditional note-taking apps. They are top-down, with each note having a dedicated place in the hierarchy. This makes them great for project-based work, but not so much for those sparks of inspiration you have. Roam Research's network-based approach allows each note to function autonomously, connecting to other notes when it fits organically.
The downside to Roam Research is the price — the Pro version is $15 a month or $165 a year, and there's no freemium version, only a free trial.
Not happy with your note-taking habits? Looking for a more organized way of note-taking that will replace your old notebook? These four tools will transform the way you organize your notes and will boost your productivity. Give them a try and see which one suits your style the best.
--- START: blog/best-project-management-apps-2021/best-project-management-apps-2021.md ---
# **The Best Project Management Apps in 2026**
As the year slowly comes to an end, we took a moment to consider some of the best project management apps on the market. We handpicked those platforms that provided a wide range of tools for improving productivity and features that ensured clean communication.
This was a bit of a challenge as remote, and hybrid work models heavily influenced our picks. We needed those applications that could accommodate a team working from anywhere who checked in with leadership on their own schedule. With so many demands on reporting, around [4 out of 5](https://www.axelos.com/getmedia/9bd107ec-ab67-40d2-b632-f962881cc137/AXELOS-PPM-Benchmarking-Report-2019.aspx) project managers report they cannot go without some form of project management solution.
Not only were these low-code solutions excellent across multiple industries, but they are also the ones most likely to continue offering superior features and services well into 2022. Read on to see our list of the best project management apps.
## How Project Management Applications Help
The whole point of a low-code or no-code solution to managing your team and internal processes is to streamline tasks for more efficient project closings. Each of these apps provides pathways that improve your project planning, tracking, measuring, and reporting.
The main goal you should be fulfilling is collaboration. The pandemic has shifted the way we work, and having a suite of customized tools that encourage smoother communication is a must in today's market.
Each of these app solutions on our list has at least two tiers of a free option or premium account. Most of them have more than just the two that can fit teams of any size. We've done our best to outline the subtle differences and hope this list improves your team's capabilities.
### 1 - nTask
Most startups and small to medium-sized business owners find the real challenge when selecting project management software is the overabundance of choice. There always seems to be a particular app for specific niches.
This is where [nTask](https://www.ntaskmanager.com/) shines. It is a high-quality no-code application that provides a versatile list of project and task management tools, including kanban boards, Gantt charts, time-tracking, meeting management, and more, all at a low operating cost.
You can try nTask with their free plan that allows up to five team members and simple operations. When you upgrade to a paid plan, you'll find some of the most affordable options compared to other competitors.
This is the perfect project management app for those starting out their journey with plenty of options and integrations with other task management tools like Google Calendar and Slack for easy communication. If you are looking for a quick alternative that meets most of your needs, nTask is it.
### 2 - Asana
When you have a larger team spread out in different locations and time zones, [Asana](https://asana.com/) will probably be a great fit. We love to list a company like Asana because it is often left off of other lists due to its relatively low profile, but that doesn't make it any less effective.
We really like Asana allows you to create to-do lists, reminders, due dates, instructions, and comments on items, all while integrating smoothly with cloud services like Google Drive. This way, you can easily track everything all your team members are working on without having to utilize a ton of complex third-party solutions.
Asana uses a smooth interface that gets the job done well. This is a solid second place option designed for bigger teams with a modest price tag. There is a free option available, but it doesn't have as many features as the premium options, so you'll have to upgrade to get the full benefit.
We also love the workflow automation Asana offers, with custom triggers available from multiple project views, so the entire team stays on task.
### 3 - Trello
The nice thing about working with a low-code project management solution like [Trello](https://trello.com/) is its ability to communicate across almost all devices and platforms. It has an intuitive user interface that allows you to easily organize, coordinate, and track work.
This isn't a great app for traditional management as it doesn't have tools for rebalancing resources. You won't find swimlanes or work-in-progress limits. You will find an excellent communication tool with an easy-to-use free plan, though, and pre-built templates that work great for first-timers in the project management arena.
Trello is a kanban board app with a timeline view similar to a Gantt chart but more on the communication side than record keeping. With major companies like Google and Fender utilizing Trello, you can find decent benefits. If you're looking for a communication-driven project management solution, Trello is your best bet.
### 4 - Zoho Projects
[Zoho Projects](https://www.zoho.com/projects/) is a well-balanced no-code project management option for smaller teams. You get a range of integrations and a suite of features at an excellent value point with robust time-tracking tools to ensure all of your team is on task.
The downside is there are not any premade templates, and the resource management view can be a little overwhelming for larger teams. Nevertheless, this is a frequent choice for cash-strapped teams or developers looking for a quick turnaround on a project.
We really like the webhooks and workflow rules that create actions to trigger events inside native features of Zoho Projects as well as externally with other integrations including cloud-based services. You can set flexible hours by the task instead of by the time of day, which offers a bit more versatility with hybrid working teams.
Overall this is a decent choice for smaller groups that need a cheap option and the application of trigger events.
### 5 - Jira
We weren't sure whether we should include this powerhouse on our list because, while the capability of the project management app is pretty impressive, you do need a lot of technical expertise to fully utilize the features.
[Jira](https://www.atlassian.com/software/jira) is a highly agile project management app trusted by more than 65,000 organizations worldwide, including eBay and Airbnb. It offers a lot of features as well as active bug tracking that solve problems before they arise with the software. If you are an agile-based team, you'll probably want to check out Jira.
You should keep in mind that this is a low-code solution. That means you will need some technical knowledge to set everything up. Anyone outside of developers or software engineers may want to steer clear of Jira. There aren't any timeline views, and the collaboration tools are a little limited, especially for remote-focused workers.
### 6 - Clickup
[Clickup](https://clickup.com/) is an excellent all-in-one solution for a low-code project management app. While this can be a bit overcomplicated for some entry-level users, it does offer a ton of collaboration through multiple integrations like Google Sheets and real-time syncing with services from Apple, Google, and Outlook.
It is at the bottom of our list only because almost all the features require customization to get the full benefit. The alternatives we've already listed are a lot more turnkey and help those startups crafting a new MVP to market or small businesses just getting into project management.
After your team has outgrown other options, you may want to give Clickup a try as it offers some of the most robust options around. Just be sure to hire a digital Sherpa to get you through some of the more in-depth technical aspects. Once you get a solid understanding of the technical background, you may also want to consider graduating to Jira.
### 7 - Monday
[Monday](https://monday.com/) is probably the only other top pick we would suggest newbies try out. While we like others a bit more for startups and SMB organizations, Monday is close behind because of its flexibility to work with anyone from an individual freelancer to entire enterprise-sized teams.
The time-tracking and robust integrations are what set Monday apart from the rest. You can easily communicate with pretty much any other service and app you would need to grow your business, including Slack, Dropbox, Zoom, Google, Todoist, and more.
The downside is you have to pay to play. If you want access to everything Monday has to offer, you'll need to pay for the premium options. You cannot utilize the Gantt charts and timeline views with an entry-level plan.
## Customizing Your Solution
One other option that may work best for your team is to create a customized web app that fits your team's specific needs. We suggest trying out the free options of a few of these excellent project management apps and then coming over to Peaka to create a bespoke solution for yourself.
Peaka offers a frictionless visual editor to create no-code web apps that solve your company's unique challenges. You get the ability to customize all the aspects of your project management app that meets the concerns and suggestions of your team and managers.
Peaka goes beyond project management tasks. We offer a fully functional platform for designing incredible solutions through the power of simple components and database models that provide a wealth of options for practically any business.
Take a look at our current temolates on [our website](/templates/) or reach out to our support staff with any questions you may have. Using our drag-and-drop editor to build your project management app will be a great way to usher in the new year.
--- START: blog/best-saas-analytics-tools/best-saas-analytics-tools.md ---
# **Top SaaS Analytics Platforms: What to Use and Why It Matters**
If you want to improve your platform's user experience, then it’s time to explore the top SaaS analytics tools. These tools help leverage the right data to make informed decisions, optimize user experiences, and drive business success. The following sections take a closer look at the top 25+ SaaS Analytics tools.
## **Why Are SaaS Analytics Tools Important?**
SaaS analytics tools empower organizations to make decisions based on concrete data rather than intuition or guesswork. Businesses can analyze trends, track [key performance indicators](https://www.clearpointstrategy.com/blog/18-key-performance-indicators) (KPIs), and identify areas for improvement, leading to more informed and strategic choices.
SaaS analytics tools also have robust reporting features that enable organizations to create detailed and customizable reports. These reports can be tailored to specific business objectives, making it easier for stakeholders to understand complex data and trends. More and more businesses are using analytic tools to excel, and the SaaS market is likely to [exceed $800 billion by 2030](https://www.venasolutions.com/blog/saas-statistics).
## **What Are the 25+ Leading SaaS Analytics Tools?**
Here's a list of the 25+ best SaaS analytics tools to try in 2024.
### **1. [Mixpanel](https://mixpanel.com/)**
Mixpanel is a powerful SaaS analytics tool focused on user-centric insights for web and mobile applications. With advanced event tracking, user behavior analytics, and retention analysis, Mixpanel empowers businesses to make data-driven decisions, optimize user experiences, and drive growth through a deep understanding of user interactions.
### **2. [Plerdy](https://www.plerdy.com/)**
Plerdy is a comprehensive SaaS analytics tool specializing in conversion rate optimization (CRO). Offering real-time heatmaps, SEO checking, session replay, and event tracking with Google Analytics integration, the tool helps businesses gain valuable insights into user behavior and efficient feedback collection. Other takeaways include customizable pop-up forms and detailed purchase information that enables you to make the right enterprise decisions.
### **3. [Twilio Segment](https://segment.com/)**
Segment is a powerful customer data platform that simplifies data management for businesses. Efficiently collecting, cleaning, and [controlling customer data](/docs/), it serves as a centralized hub, enabling seamless integration and collaboration across applications and empowering businesses to make informed decisions based on accurate and organized data.
### **4. [Kissmetrics](https://www.kissmetrics.io/)**
Kissmetrics prioritizes customer engagement, offering strategic insights to [optimize marketing efforts](https://improvado.io/blog/marketing-optimization-guide) and improve user experiences. The platform excels in cohort analysis, funnel tracking, and customer segmentation, enabling businesses to understand, measure, and improve the entire customer journey for enhanced conversions and loyalty.
### **5. [Matomo](https://matomo.org/)**
Matomo delivers comprehensive user behavior analysis through heatmaps, scrollmaps, referral maps, and recordings. While using the platform, you can save unlimited data across websites, individual segments, and everything in between. The biggest takeaway? Matomo is an Open Source platform, and the data here is completely secure.
### **6. [Looker](https://cloud.google.com/looker)**
Looker is a versatile business intelligence platform that facilitates data exploration and discovery for informed decision-making and comes with many nifty features. Its intuitive and user-friendly interface allows users to create and share interactive dashboards, fostering collaboration. LookML, Looker's modeling language, enables easy customization and definition of data relationships, ensuring data consistency across the organization. Looker's robust data modeling capabilities facilitate the transformation of raw data into meaningful insights, and its real-time analytics provide up-to-date information.
### **7. [Omniconvert](https://www.omniconvert.com/)**
Omniconvert is a SaaS analytics and optimization platform designed to help e-commerce businesses increase customer lifetime value. It combines A/B testing, personalization, advanced segmentation, and survey tools to optimize user experiences and drive data-informed decisions. With powerful analytics and seamless integrations, Omniconvert enables teams to understand customer behavior, improve retention, and align marketing and UX strategies for measurable business growth.
### **8. [Tableau](https://www.tableau.com/)**
Tableau is a powerful data visualization and business intelligence tool that transforms complex data into actionable insights. With diverse data source connectivity, Tableau allows seamless integration for powerful visualizations, aiding users in making data-driven decisions with clarity and precision.
### **9. [Hotjar](https://www.hotjar.com/)**
Hotjar merges analytics and feedback tools to gain a deep understanding of user behavior on websites. Hotjar's insights help optimize website usability and conversion rates. Its user-friendly interface and comprehensive analytics make it a valuable tool for enhancing the online user experience.
### **10. [Optimizely](https://www.optimizely.com/)**
Optimizely is an experimentation platform that empowers businesses to test and optimize digital experiences, enhancing user engagement and conversion rates. This tool specializes in [A/B testing](https://www.optimizely.com/optimization-glossary/ab-testing/) and experimentation, optimizing user experiences for enhanced website performance.
### **11. [Adobe Analytics](https://business.adobe.com/products/analytics/adobe-analytics.html)**
Adobe Analytics offers robust features for web analytics, allowing businesses to track user behavior, measure campaign success, and gain actionable insights. An integral part of Adobe Marketing Cloud, this tool offers deep insights into customer behavior for strategic marketing decisions.
### **12. [Woopra](https://www.woopra.com/)**
Woopra offers real-time customer analytics and insights to enhance understanding of user micro journeys, making way for improved end-user experiences.
### **13. [Pendo](https://www.pendo.io/)**
This tool guides product teams in understanding user behavior and aiding users in creating superior product experiences.
### **14. [FullStory](https://www.fullstory.com/)**
Fullstory provides session replay, heatmaps, and analytics, offering a holistic view of user interactions for website optimization.
### **15. [Statcounter](https://statcounter.com/)**
This real-time web analytics tool provides valuable insights into website traffic and user engagement.
### **16. [Smartlook](https://www.smartlook.com/)**
Smartlook captures user behavior on websites and mobile apps, offering the right insights for optimized user experiences.
### **17. [IBM Cognos Analytics](https://www.ibm.com/products/cognos-analytics)**
This comprehensive business intelligence and analytics platform by IBM is ideal for informed decision-making. With self-service capabilities, IBM Cognos Analytics empowers users to explore data, create interactive dashboards, and share insights, fostering collaborative decision-making across teams.
### **18. [QlikView](https://www.qlik.com/us/products/qlikview)**
This tool delivers business intelligence and data visualization solutions, transforming complex data into actionable insights.
### **19. [Domo](https://www.domo.com/)**
Domo is a cloud-based business intelligence platform that facilitates data visualization and analysis for data-driven decision-making.
### **20. [Sisense](https://www.sisense.com/homepage/)**
Sisense business intelligence and analytics solutions are specially designed for handling complex data sets.
### **21. Mode Analytics**
This is a collaborative analytics platform that combines SQL, Python, and R for efficient data analysis and exploration.
### **22. Power BI**
Power BI is Microsoft's business analytics tool for visualizing and sharing actionable insights. The tool seamlessly integrates with various data sources, supports AI-driven insights, and allows sharing and collaboration.
### **23. Keen IO**
Keen IO is a customizable analytics platform that offers real-time event data processing. Its features include data visualization, dashboards, and API analytics for comprehensive insights. The customizable analytics backend helps build tailored analytics features directly into your platform.
### **24. Periscope Data**
This data analysis tool directly connects to databases, providing quick insights for data-driven decision-making.
### **25. Google Analytics**
Regarding [SaaS analytics tools](/blog/b2b-saas-analytics-tools/), Google Analytics excels in user engagement analysis, providing metrics on bounce rates, session duration, and pages per session. The platform's conversion tracking features enable the measurement of key actions, such as form submissions or product purchases, facilitating the assessment of marketing campaign effectiveness.
### **26. Heap Analytics**
This tool offers event tracking, analytics, and insights without the need for code.
### **27. Amplitude**
Amplitude empowers companies with insightful product analytics, enhancing understanding of user behavior for informed decision-making.
### **28. Zonka Feedback**
[Zonka Feedback](https://www.zonkafeedback.com/) combines customer feedback and survey tools to help businesses gather real-time insights on customer experiences across multiple touchpoints. Zonka Feedback’s data-driven insights empower companies to improve customer satisfaction and streamline their feedback processes. With its intuitive interface and detailed analytics, it is an essential tool for businesses looking to enhance customer experiences and drive loyalty.
## **The Bottom Line**
SaaS analytics tools exemplify innovation, providing businesses with versatile solutions to transform data into actionable insights. Whether it's the comprehensive analytics of Google Analytics or the real-time event processing of Heap Analytics, these tools are pivotal for organizations seeking to navigate the complexities of the data-driven era.
Peaka’s data integration platform can connect to any API. See our [growing library of custom integrations](/integrations/).
--- START: blog/best-slack-alternatives-2021/best-slack-alternatives-2021.md ---
# **The Best Slack Alternatives in 2026**
For many people, the transition to remote working during the pandemic was fraught with frustration. Businesses that relied on slow, clunky, and siloed communication apps felt the effects of poor communication. For example, did you know that miscommunication costs companies with over 100 employees an average of $420,000 per year? If that wasn't enough, a whopping 28% of employees cite poor communication as the primary reason for not delivering work on time.
These statistics paint a critical story - communication tools are the lifeblood of successful businesses in 2021. But which communication app should you choose? Many companies default to using the mighty Slack - a popular app loved by many. However, there are plenty of excellent Slack alternatives out there, complete with unique features that might be a better fit for your company.
## Discord (Windows, macOS, Android, Linux, Web app)
[Discord](https://discord.com/) has been dubbed "Slack for gamers," but the truth is, you don't need to be an energy-drink-guzzling video game enthusiast to benefit from Discord. Discord allows one-on-one messaging as well as group communication, and where it really shines is with its low-latency voice chats. In other words, if you're looking for a reliable platform with crystal clear audio, Discord is an excellent choice.
Perhaps the best thing about Discord is that you can use its vast array of features for free. The paid version (Discord Nitro) essentially just adds a few vanity features you can take or leave.
## Zulip (Windows, macOS, Linux, iOS, Android, Windows Phone)
[Zulip](https://zulip.com/) is an open-source team chat that packs a punch. But how does it differ from the rest? Comparing itself to Slack, Zulip argues its app is better for busy managers who are too tied-up to participate in team chats and are often overwhelmed by a flood of messages. The app takes inspiration from email, using a unique threading feature where every chat has a topic (much like a subject line).
The free version is available to all organizations and allows 10,000 messages of search history, 5 GB file storage, hundreds of integrations, and more. The Standard version is priced at $6.67 a month per user and funds the open-source project, as well as offering additional features like unlimited search history and 10 Gb of storage per user.
## Chanty (Windows, macOS, Android, iPhone, and iPad)
[Chanty](https://www.chanty.com/) is a simple, no-frills team communication app that just works. However, despite its reputation for being simple and easy to use for the less tech-savvy among us, plenty of powerful things are going on beneath the hood. The app uses AI to improve communication and collaboration and has a deliberate focus on tasks over chat. For example, the Tasks button is displayed prominently above any conversations.
Chanty has a "forever" free app for individual users or a business version, priced at $3 per user per month. The business version comes with a bunch of extra features, including unlimited integrations through Zapier, unlimited group audio calls, screen sharing, a dedicated support line, and more.
The [website](https://www.chanty.com/pricing.html) also has a helpful tool where you can compare the cost of the communication tool you currently use against Chanty to see just how much you can save!
## Element (Web, Android, iOS, macOS, Windows, and Linux)
[Element](https://element.io/) is an end-to-end encrypted decentralized messaging app available on a computer or as a mobile app. It has all the hallmarks of a great messaging app, including public and private rooms, audio and video calling, file sharing, and more. However, where Element really shines is in its approach to privacy and security. The decentralized nature of the app means that none of your data is held in one place by the company. In other words, you control your data and can even create your own server if you're particularly security conscious. You can also integrate Element with other chat platforms like SMS, Telegram, Facebook Messenger, and Slack. Pricing starts at $2 per active user on the cheapest business plan.
## Mattermost (Android, iOS, macOS, Windows, and Linux)
[Mattermost](https://mattermost.com/) has been dubbed a blend of Slack and Microsoft Teams, and if you give it a spin, you'll see why: It looks and acts just like Slack but has the robust Enterprise features of Teams. Much like Element, Mattermost is dedicated to solid security, allowing you to create a server for on-premise or cloud access. Mattermost offers two plans for its cloud-hosted and on-premise packages. It charges $10 a month for its cloud-hosted regular package while its Enterprise package is subject to custom pricing. The only [free plan](https://mattermost.com/pricing-self-managed/) comes with the on-premise version and limited functionality.
## Rocket.Chat (iOS, Android, Windows, macOS, Linux, and Web)
[Rocket.Chat](https://rocket.chat/) is a free, open-source communication tool that is fully customizable. So, what makes Rocket.Chat unique? Put simply, it's the total flexibility to adapt the platform into anything you need it to be. You have access to the code to customize, integrate, and extend the app's capabilities according to your businesses' wants and needs. There's a Free, Pro ($3 per user per month), and an Enterprise version of the software.
## What's the Verdict?
While Slack might be the most well-known communication tool out there, it's not perfect. It is known to use a lot of RAM, deplete your battery quite fast while offering limited archiving capability and deleting your old messages after some time in the free version. Picking the right app for your business shouldn't come down to a popularity contest but rather the features that will help you and your employees thrive. For example, if tasks are as (or more) important to you as just chat, then Chanty could be a good option for you. On the other hand, if you want reliable audio and an excellent hub for project work, Discord will serve you well. It's time to take control of your team communication and pick the app that will drive results!
--- START: blog/best-social-media-management-2021/best-social-media-management-2021.md ---
# **The Best Social Media Management Apps in 2026**
Social media is an essential part of running any business in 2021. It makes sharing products, reaching new customers and connecting with existing customers quicker and easier than ever before. But managing multiple social media profiles across numerous social networks, trying to keep up with messages, comments, and other interactions, and staying up to date on the latest trends can be an incredibly time-consuming part of any social media managers’ day. This is where social media management apps come in handy. These apps allow users to schedule, post and monitor their content as well as interact with followers and see insights into how their content is performing. But with so many apps to choose from, how do you know which one is right for you? To make it a little easier, we’ve put together a list of some of the best social media management apps in 2021.
## Hootsuite
[Hootsuite](https://www.hootsuite.com/) is an all-in-one platform that allows users to manage multiple accounts across multiple social networks through one app. It’s been around since 2008 and is definitely a favourite among many, with more than 16 million users in 175 countries. Hootsuite is one of the most extensive social media management apps and allows users to connect to Instagram, Facebook, YouTube, Twitter, LinkedIn, and Pinterest. With Hootsuite, users can create and schedule posts, monitor content and see how its performing, schedule content, collaborate with team members to plan upcoming campaigns and reply to messages from a single streamlined inbox. Hootsuite also provides users with a number of valuable insights and the ability to create custom reports based on the metrics that are most important to their business.
## Zoho Social
[Zoho Social](https://www.zoho.com/social/) is another fantastic all-in-one social media management app known for its simple yet elegant interface and ease of use. The app works with Facebook, Instagram, Twitter, and LinkedIn and has a version specifically designed for marketing agencies, which enables additional features such as white labelling and client lists. With Zoho Social, users can schedule posts using the publishing calendar and content queue, curate their content within the app, monitor engagement and reply to Twitter and Facebook direct messages, and create custom and scheduled reports on performance and engagement. Zoho Social also integrates with the other Zoho apps, including Zoho Workspace, Zoho Campaigns, and Zoho CRM, making collaboration more manageable than ever before.
## Sprout Social
[Sprout Social](https://sproutsocial.com/) stands apart from other social media management apps because it is one of the few platforms that include CRM features with the app. This feature allows users to plan, create, manage and post content for Twitter, Facebook, Instagram, LinkedIn, YouTube, and Pinterest within the application. They can also access messages from all their accounts in a unified social inbox, making responding to messages quick and simple. One of the features that Sprout Social is best known for is its in-depth analytics that lets users to monitor keywords across all accounts and create easy-to-read reports. Sprout Social also helps users to improve their social media strategy by using insights and trends to take their content to the next level.
## Loomly
[Loomly](https://www.loomly.com/) is a social media management app designed to be used by teams with collaboration in mind. With Loomly, users can get notified when someone on their team comments on or updates content through Slack, Microsoft Teams, email, or push notification. Users also can store their photos, videos, and templates in Loomly’s library and access Loomly Studio, the Hashtag Manager, and the UTM parameters generator. Like other social media management apps, Loomly allows users to schedule their content, preview their content before actually posting, respond to comments and messages from Facebook, Twitter, Instagram, and LinkedIn, and view analytics for their posts. Loomly’s analytics are available in real-time, and the app also provides analytics for posts not posted using the app.
## Buffer
[Buffer](https://buffer.com/) is best known for its post tracking tools and in-depth real-time analytics. The app is run by a smaller team, with 85 members across 15 countries, who work hard to regularly release new features and analytics to help businesses increase performance and engagement across multiple social networks. Users can plan and publish content for Instagram, Facebook, Twitter, Pinterest, and LinkedIn right from Buffer’s comprehensive and straightforward dashboard. Buffer also offers additional features for Instagram that help users build their brand using Instagram marketing, planning and preparing stories as well as reminders when it’s time to post scheduled content. Users can also engage with commenters and collaborate with teammates. Buffer’s analytics not only allows users to analyze their content’s performance in real-time but also integrate with Google analytics and generate custom reports of those analytics.
## Crowdfire
[Crowdfire](https://www.crowdfireapp.com/) is a fantastic social media management app for businesses or individuals looking for an all-in-one app that works with a large number of platforms. Currently, Crowdfire supports Facebook, Instagram, YouTube, Twitter, LinkedIn, WordPress, Etsy, Shopify, Pinterest, Medium, Vimeo and more. One of its most popular features allows users to create social media posts for every update they have on one of the connected sites. Additionally, users can discover content based on keywords and interests, pre-schedule and publish content, and customize content based on which platform it is going to be posted on. Crowdfire regularly adds new features to the app and also offers specific capabilities for certain platforms. For example, users can follow and unfollow on Twitter and have content suggested for sharing, such as articles.
## Social Pilot
[Social Pilot](https://www.socialpilot.co/) is one of the most affordable social media management apps and offers users a simple yet powerful dashboard packed with features. The app is compatible with Facebook, Twitter, Instagram, Google My Business, LinkedIn, Pinterest, and TikTok. It allows users to publish content using a social media calendar, upload up to 500 posts at a time and collaborate with team members. Social Pilot also has client management tools making it a great option for agencies who manage multiple clients. It also helps users to curate and create content by finding and suggesting relevant content. Users can search as many keywords as they’d like to see recent posts relating to that keyword to find inspiration and stay up to date.
## Agorapulse
[Agorapulse](https://www.agorapulse.com/) is an all-in-one social media platform with scheduling, responding, and reporting features. Users can use a unified social inbox to respond to messages, comments and reviews from Facebook, Instagram, LinkedIn, Twitter and YouTube. The app also allows users to plan and schedule content through an easy-to-use and visually appealing content calendar and collaborate with other team members. Agorapulse is also a popular choice among many social media managers and agencies for its monitoring and reporting. Users can see trends and insights about their brand along with competitor analyses. Agorapulse’s analytics are updated in real-time, and users can easily create custom reports and have them sent directly to their email.
## Sendible
[Sendible](https://www.sendible.com/) is often considered the best social media management app for agencies and was specifically designed to be used in that setting. It features a custom dashboard which can be helpful when attracting new clients and can be used with Facebook, Twitter, Instagram, Pinterest, LinkedIn and Google My Business. Sendible also offers a number of unique integrations such as YouTube, Canva graphic editors and a royalty-free image search making it incredibly easy to create content all in one place. Apart from the dashboard, users can plan and publish content, collaborate with team members, and approve new posts. Sendible also provides users with valuable insights into how their content is performing and allows them to monitor mentions to increase engagement.
## Sprinklr
[Sprinklr](https://www.sprinklr.com/) is a social media management app designed for enterprises and large agencies that deal with high profile clients. Sprinklr users can connect to more than 30 platforms, including Facebook, Twitter, and Instagram. Within the app, they can plan content, create campaigns, respond to reviews and comments and collaborate with team members. Sprinklr also provides users with valuable insights into everything from customer location to how they feel about products. In addition to the more traditional social media management application features, Sprinklr allows users to connect with customers via live chat, messaging, email, SMS and more. Users can also use chatbots to have more efficient conversations with customers using applications like Facebook messenger and WhatsApp, and have an automated workflow for how contact requests are handled to solve customer issues faster.
Whether you’re a small business owner looking to increase traffic to your site or a social media manager for a major corporation, social media management apps are some of the most powerful tools you can have in your toolkit. With so many different apps available, there is sure to be one that fits every company’s needs and budget.
--- START: blog/best-video-editing-software/best-video-editing-software.md ---
# **Best Video Editing Software in 2024**
Do you remember Windows Video Maker, that easy-to-use tool with bare-bones functionality we all used to edit videos in the early noughties to not-very-good results? I remember spending hours trying to edit family videos, adding effects that consistently fell short of creating the wow effect I hoped for but it was par for the course, I guess. Those videos were made to be memories, relics of better times and not intended for mass consumption. Windows Video Maker was a different tool for a different time when there was significantly less emphasis on visuals compared to today.
The advent of the social media age changed all that — now videos were being made for a much a larger audience whose expectations considerably differed from the expectations of your family. Platforms such as Youtube, Instagram, Twitter and TikTok created a new breed of celebrities who made a living off their video-making skills. Video creation has been responsible for billions of dollars worth of sales and become an essential part of any marketing strategy. According to [Influencer Marketing Hub](https://influencermarketinghub.com/tiktok-stats/), TikTok reached one million views per day in its first year alone. Now, a video-sharing app is the most downloaded app on the Google Play Store!
But how can you produce videos that will be up to the standards of our visually-driven society? Thankfully, hard times times create powerful tools (I know, [G. Michael Hopf](https://www.goodreads.com/quotes/8751435-hard-times-create-strong-men-strong-men-create-good-times) did not exactly say it like that) and today we have access to powerful video editing tools that can help us deliver top-quality video content. To save you time, we’ve put together a list of the best video editing software. Read all about our top video editing software recommendations, so you can start creating your own binge-worthy video content as soon as possible!
## Premiere Pro
[Adobe's Premiere Pro](https://www.adobe.com/products/premiere.html) is an extremely popular video editing software. This industry-standard tool is suitable for both Mac and Windows and is used by some of the most successful video creators.
Although Premiere Pro is an advanced piece of software, even a video editing novice can learn on the job and get to grips with Pro’s easy to use interface. Video creating professionals in business, marketing, music video production, documentary making and feature film creation all use Premiere Pro. I personally began using Premiere Pro due to a friend's recommendation. Despite having minimal video editing experience, a few hours playing around and a couple of Google searches helped me learn the ropes with the platform. Those looking to get the most out of Premiere Pro’s advanced features might benefit from taking a course on the platform.
Adobe charges for Premiere Pro through a monthly subscription or yearly fee. The annual fee is $239.88, and the monthly fees range from $20.99 (annual, monthly plan) to $31.49 (per month plan). Although there is no free version of Premiere Pro, the price point for a non-linear video editor with the advanced feautures and creative freedom of Pro is very good value for money!
## Wondershare Filmora Video Editor
[Wondershare Filmora](https://filmora.wondershare.com/video-editor/) users are mostly online content creators who use video to tell stories. If you're not familiar with video editing, Wondershare Filmora is an easy and accessible software for learning the basics of video editing.
Although aimed at those with less experience, and predominantly for the online world, this platform has useful tools for perfecting your video and audio. Automatic audio sync, noise reduction, audio compression and transitions are all available on the platform. Alongside these technical tools, the platform focuses on branding and eye-catching editing. Animations, effects, texts and masks help make your videos recognizable and unique to your brand.
Getting started on Filmora will cost you $7.99 per month, $39.99 per year, or a one-off lifetime payment of $69.99. The Filmora Wondershare software is suitable for both Mac and Windows.
## Final Cut Pro
[Final Cut Pro](https://www.apple.com/final-cut-pro/) is Apple’s non-linear video editing software. Despite being one of the most popular video editors, it is only compatible with Mac, which means Windows users might want to try Adobe's Premiere Pro.
Premiere Pro and Final Cut Pro have similar interfaces, clientele and tools. Both are designed for users who are well-versed in video editing or willing to invest the time and money required to learn. Video editing professionals tend to use Final Cut Pro to edit and fine-tune video using a fast and advanced video editor.
Those who require fewer features and less advanced technology can still use Final Cut Pro for their basic needs. However, I’d recommend looking at cheaper software, such as Wondershare. After all, what’s the point of paying for features you don’t need?
You can purchase Final Cut Pro for $299. This payment is for the latest version of the software and lasts for six years. Paying this upfront cost works out at $4.15 per month. Although this might seem like a large sum of money to pay upfront, you don't have to worry about updating or renewing your subscription for video editing software during these six years.
## Blender
For those just getting started in video editing, this free video editor a great place to begin. [Blender](https://www.blender.org/) isn’t just a video editor; it’s a creative community. The Blender community is full of artists and creatives who cherish the Blender software and create wonderful content with it.
Unlike the other video editors in this list, Blender is an independent public benefit organization. It pledges to remain a free, open-source software owned by its contributors.
The Blender creation suite also offers rendering, modelling, animation, simulation and more alongside its video editing software. If you're searching for a free platform with unparalleled passion and dedication to create, Blender is the software for you.
These four tools appeal to different users with different levels of video editing skills and budgets. Make up your mind on what your needs are and which one would be a better fit for your skills, budget and time, and then get down to creating content! Who knows, maybe you could be the next great YouTube phenomenon!
--- START: blog/best-zapier-alternatives-2021/best-zapier-alternatives-2021.md ---
# **The Best Zapier Alternatives of 2026**
Did you know that more than [67 percent of global workers](https://www.businesswire.com/news/home/20210520005067/en/New-Study-Finds-Majority-of-Global-Office-Workers-Crushed-by-Repetitive-Tasks-Stifled-From-Pursuing-More-Fulfilling-Work) feel they are doing the same monotonous tasks over and over during their day? More than two-thirds of the workforce think they are wasting time answering the same emails or completing tasks that should otherwise be automated.
Think about all that lost resource allocation. If those same workers could free up time to focus more on customer needs and less on back-office tasks, they could explode the revenue potential for their company. These workers could benefit from automation software like [Zapier](https://zapier.com/).
## What is Zapier?
Zapier is an online platform that connects your apps with the services you use the most. It automates routine tasks without needing customized integration. For example, imagine you’re a real estate agent trying to build leads and develop a strong network of buyers and sellers. With Zapier, you could use a Google lead sheet where prospective clients enter their contact information on your website. Then, every time a new customer is signed up to receive more information, Zapier automatically sends them a personalized letter. This cuts down on your time fostering that lead.
Basically, Zapier lets you control “If/Then” statements throughout your digital ecosystem. It allows you to create trigger events where “if” one thing happens, “then” another thing is the result. If you send a Tweet, then it is resent to your Facebook feed. If a customer leaves a review on your site, then you receive an email notifying your team to review the contents.
Zapier is a valuable tool to automate your business and help reallocate your precious resources. But, like everything else, it never hurts seeing what else is available on the market that could fit your company better or come in at a more attractive price point. So here are some excellent alternatives to Zapier in 2026.
## 1 - Integromat
[Integromat](https://www.integromat.com/en) is a no-code alternative to Zapier that simplifies, optimizes, and integrates business processes into apps and software suites. This alternative is best for users who enjoy more customized control over their automation and understand complex multi-step integrations. It is the opposite of Zapier in that it is more powerful but also more complicated to set up. As a result, you can get more bang for your buck, but only if you won’t be overwhelmed by a heavy user dashboard and possible combinations.
Integromat offers a free pricing level for 1,000 operations and 100 MB of data transfer. You can also sign up for their paid Basic, Standard, Business, Platinum, and Custom plans to accommodate anywhere from 10,000 operations to more than 800,000 operations. That allows companies of all sizes to find a price point that will work with their automation needs.
[Learn more about Integromat](https://www.integromat.com/en)
## 2 - Automate.io
This platform is a significant competitor to Zapier because of the number of actions users can process. Where Zapier offers only 2,000 tasks, [Automate.io](http://automate.io/) would allow 10,000 at the same price point. It also serves a wide array of organizations worldwide across the majority of cloud-based services. All of that integration is a serious benefit.
This is the kind of Zapier alternative best designed for people with large newsletters or complex marketing campaigns that need CRM integration. They do offer a free plan for 300 actions and 5 bots. The paid plans are a bit more expensive than the average, but the value is definitely present.
[Learn more about Automate.io](http://automate.io/)
## 3 - Outfunnel
[Outfunnel](https://outfunnel.com/) is a cleaner marketing automation tool compared to Zapier. Once you set up a single automated campaign with your CRM, it will automate in the background based on data changes. Every customer touchpoint with your campaign (clicks, reads, etc.) gets recorded and put into context so you can adapt your campaign and retarget where needed.
This platform is more manageable than Zapier to set up but does not offer as many app connections. Before you sign up, you should review their info to ensure your company apps and services integrate adequately into the platform. Unfortunately, they do not have a free plan but do offer a free trial.
[Learn more about Outfunnel](https://outfunnel.com/)
#4 - IFTTT
We wanted to mention this alternative specifically because it is so user-friendly for individuals and mobile devices. They offer a variety of plans that start at the free level for 3 “applets.” These applets allow you to create cross-platform If/Then workflows like we mentioned at the start of the article.
This is really useful for social media users who want to automatically post specific photos across different platforms or respond to certain comments with previously created text. IFTTT works great with mobile devices that have digital voice assistants. You can say something like, “Hey Siri, post that last photo,” and the most recent photo you took gets automatically sent to Instagram through the applet you created.
[Learn more about IFTTT](https://ifttt.com/)
## Conclusion
Zapier is a great way to automate your routine and repetitive tasks so you can focus on your customers. There are excellent alternatives to Zapier available across the digital landscape that offer lower rates, more tasks, and customized options. Whatever your current needs may be, there is most likely a task automation platform available. We think these 4 alternatives offer a wide array of services for most clients.
If you would like to learn more about all of the no-code digital solutions available, check out our blog. Even better, learn how to create your own completely customized digital apps without needing any programming by viewing our demos at [Peaka](/). We look forward to hearing from you!
--- START: blog/book-review-automatic-customer/book-review-automatic-customer.md ---
# **Book Review: The Automatic Customer by John Warrillow**
Lately, the Peaka content writing staff obsessed over the subscription model, bringing you blog posts analyzing this particular model throughout April. I thought I would join the party by reviewing a book on that particular model for the Peaka's *Book of the Month.*
John Warrillow discusses ways of creating recurring revenue in any line of business in his book [*The Automatic Customer: Creating a Subscription Business in Any Industry*.](https://www.amazon.com/Automatic-Customer-Creating-Subscription-Business/dp/0241247004) The author urges everyone to look at their businesses from a broader perspective and seek ways to disrupt the market. He suggests his readers keep an open mind about the model and encourages them to think, “*How could this model apply to my industry?*” and “*What part of this model could I borrow for my company?*”
## A very personal thing
*The Automatic Customer* is a comprehensive survey of the existing subscription models, the thinking behind them, and how they are implemented. The author had previously run a traditional consulting business wherein he chased customers for a month to achieve his financial goals, only to start over at the beginning of the next month. Exhausted by this never-ending cycle, he started to look for another model that would make his customers automatic and save him the monthly hassle.
Warrillow cites eight reasons for entrepreneurs to consider the subscription model: The potential increase in the valuation of the company; the boost in the customer lifetime value; the fact that subscribers buy more from the brand they subscribe to; the increased efficiency and lowered cost resulting from the improved predictability in revenue streams… All convincing and sensible reasons to give the subscription model a chance.
## Templates to implement
The author then moves on to discuss the most common business models based on subscriptions. By no means an exhaustive account, Warrillow’s list gives the readers an idea about how versatile the recurring revenue model can be if you have a little bit of creativity. It also provides us with a glimpse into some of the motives that get people to sign up for products and services: To gain exclusivity; to have peace of mind with regard to tasks of utmost importance; to receive front-of-the-line service; to have the luxury of not having to deal with routine, monotonous tasks…
This section is uplifting for any entrepreneur as it shows the scope of opportunity the recurring revenue model offers. Dollar Shave Club example is a well-studied one and one that we wrote about on this blog. Warrillow demonstrates that there are people out there willing to sign up to receive fresh-cut flowers every week or month or have their light bulbs at home checked and changed regularly.
Warrillow brings to the readers’ attention that any business can be reconfigured as a subscription business. If there is seasonality or uneven demand in your line of work or your sales cycle starts all over again every month, you can, and probably must, give the subscription model a chance.
## Tackling the churn menace
There are several passing mentions of churn and how to contain it throughout the book. Churn is critical for the future success of a business. The recurring revenue model promises an ever-growing, long-lasting revenue stream but with a caveat: You have to minimize churn.
However, the way churn is dealt with in *The Automatic Customer* is quite descriptive and leaves much to be desired. The most striking aspect of churn, the compounding effect it creates on monthly recurring revenue (MRR) over the long run, is missing from the account. For a more detailed analysis of the churn issue, one would do well to refer to a product-led growth guru like David Skok, whom Warrillow cites more than a few times in his book.
*The Automatic Customer* offers a good read with many interesting examples from the author’s personal career and other successful businesses that took advantage of the subscription model. However, it isn’t the kind of user manual some readers might hope it would be.
Although it demonstrates the extent of what is possible with the subscription model, *The Automatic Customer* falls short of providing a detailed roadmap that businesses can rely on. Entrepreneurs should turn to the qualitative analyses offered by people like Wes Bush and David Skok for that.
--- START: blog/book-review-cold-start-problem/book-review-cold-start-problem.md ---
# **Book Review: The Cold Start Problem by Andrew Chen**
Along with the mythical "product-market fit," "network effects" must be the most commonly-used phrase in the pitch decks of SaaS startups. These two concepts help bridge the gap between the unremarkable today, with little to show for in terms of financials, and a glorious future, where the product in question will undoubtedly take off. Theoretically, every SaaS product is just a product-market fit and network effects away from becoming a unicorn.
Nir Eyal's [*Hooked*](/blog/book-review-hooked/) was the first book we reviewed that laid out what network effects can achieve for products. Eyal's book proposed a model to understand the habit-forming dynamics that got users hooked on certain products. The hooks he talked about, such as "like," "share," and "retweet," made people come back to the product and kept the network effects humming.
But *Hooked* was different from *The Cold Start Problem:* The former studied network effects at the product level, explaining how they took over once the users developed an itch to use the product.
On the other hand, *The Cold Start Problem* looks at how the network effects come to be and elevate not only individual products but whole industries. In addition to its macro-level focus, the book also takes a scholarly approach and breaks network effects down into acquisition, engagement, and economic effects.
## **As insider as it gets**
The author Andrew Chen is an entrepreneur and investor who helped popularize terms such as "viral loop," "growth hacking," and "network effects," and thus, played no small part in shaping the Silicon Valley culture as we know it today. Currently a general partner at Andreessen Horowitz, Chen led Uber's Rider Growth product teams from 2015 to 2018, during a period when the company was rewriting the book on growth before its IPO. Chen's experience at Uber provides the basis for his discussion of network effects in the book. However, he goes beyond that and conducts a series of interviews with decision-makers from other tech giants. Airbnb, Uber, Twitch, PayPal, LinkedIn, Clubhouse, and the like all have their dedicated chapters in the book, which Chen uses to dwell upon a particular aspect of network effects.
A network effect refers to a phenomenon whereby some products become more valuable as more people use them. The usual example is the telephone, which would be useless if you were the only one in the world using it. A second telephone owner that you know about would at least make your device usable. However, for this invention to realize its full potential, a large group of phone owners, out of whom you would have a few that you would like to talk to every day, would be necessary.
Without securing a certain number of users, networked products like marketplaces, ride-sharing apps, or social media platforms will find it difficult to convey their value proposition to existing users. Your Facebook feed would be pretty dull if you had only one contact. Would Twitter be the same menacing and addictive platform that it is now if there were only a handful of people on it?
## **I'll see your Metcalfe and raise you… a meerkat!**
The book's title is a clear allusion to the trouble of getting your car started on a cold winter morning. It cleverly captures the challenge of getting your user base to a size where it can support itself before your existing users get fed up with the lack of interaction and disperse. This challenge of getting your network over the hump is the problem that Chen tries to solve in his book.
In the startup world, you are advised not to question how a startup got its first hundred or thousand customers because you wouldn't want to know as anything goes in that process. Chen's book is about developing a framework that startups can employ to build that initial network that can sustain itself without collapsing. His source of inspiration, however, is quite uncommon.
Usually, any discussion of network effects centers around a discussion of [Metcalfe's Law.](https://en.wikipedia.org/wiki/Metcalfe's_law) Chen does away with convention, arguing that Metcalfe's law doesn't say anything about the quality of the engagement and that more nodes are not necessarily better. Instead, he turns to Warder Clyde Allee, a professor of ecology, and the study of population dynamics for inspiration. What Chen formulates as Meerkat's Law tells us that there is a tipping point—called an Allee threshold—in animal populations beyond which a group becomes more defensible against predators, until the population hits the carrying capacity of the ecosystem in question.
This analogy helps readers understand that a critical mass is needed to make a network self-sustaining. Before that tipping point, there is not enough interaction, and hence value, to justify staying in the network for people. Once that tipping point is reached, everything starts to click, and the organic interaction within the network creates enough value to keep people engaged and make them stick around. *The Cold Start Problem*, in a sense, deals with the problem of "crossing the chasm," "overcoming the trough of sorrow," or "going from zero to one," in startup talk.
## **Key concepts from the book**
Andrew Chen makes use of some key concepts to get his point across throughout the book. Here are three of them:
**Atomic network:** "The smallest possible network that is stable and can grow on its own." For example, for Slack, this was a team of three. Members of an atomic network get to enjoy the product's value proposition, so they will stick around. Their engagement rate will increase, which, in turn, will start driving the network effects.
Once a healthy atomic network is built, the next thing is to copy and paste the formula until the tipping point, where the network begins to thrive. This is where "growth hacks" like viral videos or referral programs involving sign-up bonuses work wonders. What happens when you don't have atomic networks? Your product fizzles out as Google+ did, despite all the initial fanfare, the media blitz, and the 90 million users announced at the beginning.
**The hard side of the network:** "The small percentage of people that typically end up doing most of the work within the community." These are the busiest drivers in the case of Uber, people who pull in millions of views with every video they post on Youtube, or power gamers watched by millions of other gamers on Twitch.
People making up the hard side of a network do tasks that require more work in their respective networked products. Therefore, satisfying their needs and improving their user experience is critical for the network effects to kick in. When these stars are unhappy and leave the network, they can take a big chunk of the user base with them, which can set off "anti-network effects" and trigger the unraveling of the whole network at some point.
**Moat:** This term refers to the levers a network can use to defend itself. However, contrary to popular belief, Chen makes an important point that networks do not have an inherent defense capability resulting from merely being a network. In the market, the network that more effectively puts into action acquisition, engagement, and economic effects tends to win. While the smaller network wants to capitalize on niche segments, the larger network takes advantage of higher monetization to fend off newcomers.
Features cannot serve as moats as they are easy to copy. It's nearly impossible to copy a network with its intrinsic value and engagement. That is your moat.
## **Final thoughts**
*The Cold Start Problem* has all the characteristics of a great book: A cleverly chosen title, a clear theoretical framework, and real-life examples to illustrate how that theory is to be implemented. Andrew Chen takes the time to explain how businesses succeed when correct levers are pulled and drives his point home by discussing the instances where even the giants falter when they don't pull the right lever.
Coming from a Silicon Valley veteran, *The Cold Start Problem* is a breath of fresh air, offering explanations instead of slogans as we are used to seeing from other Silicon Valley greats (\*cough\**Peter*\*cough\**Thiel*). It is a must-read for anyone planning to build or market a networked product.
--- START: blog/book-review-crossing-the-chasm/book-review-crossing-the-chasm.md ---
# **Book Review: Crossing the Chasm by Geoffrey A. Moore**
How can a startup with its unproven product gain traction, pull itself out of obscurity, and become a thing? This happens to be the billion-dollar question on the minds of management professors, investors, and founders. With little traffic generating almost no meaningful metric to analyze, no historical pattern to take as a yardstick, and no customer base to receive feedback from, it is no wonder that founders begin to feel lost shortly after a product launch. The feeling is akin to waking up in a boat in the middle of the ocean, not knowing in which direction to row. You can row in any direction, but for what reason? What if you are actually getting further away from the nearest shore while you think you are rowing in the right direction?
## **A new solution to an old problem**
Paul Graham called this state of being lost "[the Trough of Sorrow.](https://twitter.com/paulg/status/1316661104911806465)" Ben Horowitz dubs it "[the Struggle.](https://fs.blog/ben-horowitz-the-struggle/)" For Bruce Cleveland, it is "[the Traction Gap.](https://www.amazon.com/Traversing-Traction-Gap-Bruce-Cleveland/dp/1635765730)" Geoffrey A. Moore, in his book [*Crossing the Chasm*](https://www.amazon.com/Crossing-Chasm-3rd-Disruptive-Mainstream/dp/0062292986), which we review this month, describes it as "the chasm." A reference book that inspired other authors and has been cited thousands of times for almost three decades, *Crossing the Chasm* is about market development, focusing on how companies can grow their early market success into mainstream market dominance. Between the early and mainstream markets stands the chasm, which swallows many startups that initially showed promise. Moore analyzes why high-tech marketing produces inconsistent results, with some startups hitting the jackpot and others going under.
Moore sets off reviewing the two previously dominant frameworks in the field: High-Tech Marketing Model and the Technology Adoption Life Cycle that it is based on. The latter groups customers into five: Innovators, early adopters, early majority, late majority, and laggards. The High-Tech Marketing Model assumes that successful products capture the first group, the innovators, and smoothly move from left to right, with each segment becoming a point of reference for the segment to its right. In his book, Moore debunks these two frameworks and asserts that there are cracks between each adjacent segment, posing obstacles to smooth market development.
## **Meet the personas**
Moore introduces his own insights into the Technology Adoption Life Cycle and revises it. He gives us a psychographic analysis of each segment. He characterizes the innovators as "the technology enthusiasts," the early adopters as "the visionaries," the early majority as "the pragmatists," the late majority as "the conservatives," and the laggards as "the skeptics." These personas represent customer archetypes with distinctive features described by the author in laser-sharp detail as if he is looking at a photograph and telling us what he sees in it.
Moore argues that the chasm happens to be between the visionaries and the pragmatists. Whereas the visionaries are risk-takers chasing breakthroughs and seeking "order-of-magnitude" returns on their investment, pragmatists are level-headed business leaders who want to play it safe, invest in proven products, and only buy from the market leaders. Because these two have almost diametrically opposed characters, Moore states that visionaries can not serve as a reference base for the pragmatists. Pragmatists want to see competition before deciding to use a product. So, a product should either beat its competitors, if there are any, or build a market first and wait for the competition to show up before being taken seriously by pragmatists. It is an idea also echoed in [*Traversing the Traction Gap*](/blog/book-review-traversing-the-traction-gap/), which we reviewed last month, as the authors of the book emphasized the importance of "category creation."
*Crossing the Chasm* lays out what B2B companies can do to engender adoption for a product among the pragmatists. The author uses a D-Day analogy to drive his point home. Just as the Allies landed on a few beaches in Normandy in June 1944, secured beachheads, and went on to drive the entrenched Axis troops out of their positions, Moore suggests companies do the same with their new products.
> *"Cross the chasm by targeting a very specific niche market where you can dominate from the outset, drive your competitors out of that market niche, and then use it as a base for broader operations."*
## **A few points to keep in mind**
The fact that the book still has relevance after nearly three decades speaks to its success. Today, you can hardly read a book on management or listen to a podcast about marketing without reading or hearing it get cited. However, *Crossing the Chasm* is not without its problems.
First, it was written in the golden age of B2B marketing. Therefore, its inferences do not automatically translate into today's more dynamic startup world. Two short appendices added to the main text seem to have done little to bridge that gap.
Secondly, the author's style can sometimes render the text a difficult read. The book is full of analogies and metaphors: *Knocking over the headpin, assembling an invasion force, taking the beachhead, crossing the chasm, visionaries, pragmatists, pioneers, settlers…* Trying to figure out what all these metaphors map to in the mind of the author can be quite the challenge and adds to the cognitive load of the reader trying to chart a route out of the chasm.
Lastly, when dealing with the market segmentation problem, Moore brings very little to the table other than advising his readers to rely on "informed intuition." His suggested methodology basically involves the marketing team coming together for a brainstorming session, laying out possible use cases and people who would be interested in them, and generating scenarios around these personas. He tacitly concedes that this methodology is not scientific at all, and thus not repeatable. This point considerably undermines his framework as he introduces no quantifiable, measurable and repeatable process for his readers to implement. "Gut feeling" doesn't make a good suggestion for founders with little to no experience.
Still, *Crossing the Chasm* remains a must-read, if not for anything else, to understand and appreciate the impact it has had on a whole range of books on high-tech marketing. Supplement it with Anthony Ulwick's *Jobs to Be Done* and Bruce Cleveland's *Traversing the Traction Gap*, and you may consider yourself well-armed for your next battle on your way to building the next unicorn.
--- START: blog/book-review-founders-faq/book-review-founders-faq.md ---
# **Book Review: Founder’s FAQ by İlker Köksal**
Entrepreneurs are a source of inspiration to most of us. They don't have to be an Elon Musk or Mark Zuckerberg to deserve our admiration—they don't even have to be successful, if you ask me. Something about people with the guts to chart their own way and working to bring their ideas to life has always fascinated me. This is why I have been drawn to reading books written on or by entrepreneurs as of late.
The book we featured last month, [*Delivering Happiness*](/blog/book-review-delivering-happiness/) by the late entrepreneur Tony Hsieh, was one such look into how entrepreneurs deal with the immense challenges they take on, some of which they themselves seek. The book we feature today, [*Founder's FAQ: The Predictable Journey of the Ups and Downs of a Startup*](https://www.amazon.com/Founders-FAQ-Predictable-Journey-Startup-ebook/dp/B08XSBWL43) by İlker Köksal, is a similar attempt at shedding light on what it takes to succeed as a founder in today's startup environment.
The book starts with Köksal nudging his readers into engaging in some kind of soul-searching before founding a business. Throughout that particular section, you feel as if Köksal is right in front of you, staring you right in the eye and questioning whether you have what it takes to succeed as a founder. He reminds you that you won't be going too far without first being honest with yourself about the core assets you bring to the table as a founder. Do not solely rely on your subjective evaluation of yourself but double-check by asking your colleagues to grade your skills and see if both evaluations are consistent, he says. It certainly is a good piece of advice; founding a business on wrong assumptions seems like a surefire way of dooming yourself to failure.
## **Find your own "why"**
It is not without reason that Köksal is such a passionate champion of soul-searching before rolling up the sleeves for a startup. A startup founder will no doubt run into some setbacks during his journey. Money alone cannot motivate a person to overcome all those setbacks—there has to be a bigger idea he must be chasing. A founder should have convincing answers to questions about why he is building a startup or developing that particular product. Because, when times get tough and money is not there, he will need something to hold on to. The two critical questions are:
+ "Is there a market for your product?", and
+ "Are you the right person to build it?"
Ambiguous answers short of a resounding "yes" to these two questions should be considered red flags. Once you are sure that you are the right person for the job, determining the total market size, developing a sound business model, and following up with a long-term business plan are the next steps.
Being a computer engineer and a serial entrepreneur, Köksal boasts a proven track record with two startups he founded—one of them bootstrapped and the other one VC-backed. Therefore, his words carry a lot of weight. Not only that, but he also brings in the wisdom of CEOs, entrepreneurs, and institutional investors after the discussion of each topic throughout the book. This gives the readers a chance to see how business leaders think.
## **The journey to raise venture capital**
The book is full of deep insights and words of wisdom distilled from the experience Köksal and the professionals he interviewed share with us. But the chapter on the fundraising process stands out the most among all the rest. It sheds light on how that magic moment that grabs the headlines when a startup receives a seven- or eight-figure investment comes about.
Köksal offers us a glimpse into what goes on behind the scenes for a startup during its efforts to raise venture capital and covers a wide range of topics related to raising funding. He helps founders form a sound strategy, starting with how to determine the right time to start seeking funding and then moving on to other topics such as how much funding they should seek or what angel investors or venture capital firms look for at the funding stage, etc. Köksal's emphasis on the implications of the equity dilution and the need to keep an eye on how the cap table shapes up is very instructive for inexperienced founders.
I think this is the section where Köksal's interviews with industry professionals really pay off. Institutional investors and venture capital firms have a different mindset than friends and family, who usually support you with pre-seed funding. Therefore, raising venture capital is an entirely different beast. Picking investors' brains on different aspects of a subject as complex as raising money puts things in perspective for the readers. Really neat stuff.
## ***Trade-offs, trade-offs, more trade-offs...***
[*Founder's FAQ*](https://foundersfaq.com/) is a much-needed reality check for prospective founders. This is a very clear account of the challenges awaiting them during their startup journey. Actually, it is a breath of fresh air among cliché-laden Ted Talks or Medium posts that don't tell the audience much more than "*You can do this, just believe in yourself!*"
*Founder's FAQ* brilliantly lays out the conflicting goals a founder will be pursuing: The need to establish a certain culture, on the one hand, but keep things fluid and nimble at the same time, on the other; having to set a vision for the employees to follow, on the one hand, but avoid micromanagement, on the other, or the need to seek funding, while trying to avoid risking excess dilution of founder shares. It serves as a forewarning to the founders, teaching them about the tough decisions they will have to make at every stage and showing them that this will be no walk-in-the-park.
No two startup journeys are the same—your own journey as a founder will come with its unique challenges. Having read *Founder's FAQ*, though, you will stand a much better chance to overcome them.
--- START: blog/book-review-hooked/book-review-hooked.md ---
# **‘Hooked’ by Nir Eyal and Ryan Hoover**
Added someone as a friend. Liked a photo. Commented on another one. Retweeted a video. Exchanged emojis with. Swiped left.
These are some of the actions millions of people carry out a total of billions of times on their mobile phones. They are also the basis on which some of the biggest brands in the world thrive. Facebook, Instagram, Twitter, Snapchat, Tinder, Linkedin and the like all became what they are thanks to techniques employed that make users come back to their products multiple times a day. These platforms get their users ‘hooked’ and by doing so, increase the lifetime customer value, achieve higher growth rates, make it more difficult for their customers to shift to other brands and erect an entry barrier for the new players in the market.
## **The Hooked Model in practice**
In order to shed light on how some products manage to gain a cult-like following while some don’t, Nir Eyal and Ryan Hoover dive deep into the mechanics of habit formation in their book [*Hooked*](https://www.amazon.com/Hooked-How-Build-Habit-Forming-Products/dp/0241184835). The authors introduce the Hook Model, which consists of four steps: Trigger, action, variable reward and investment.
+ **Triggers** are both internal and external and they refer to the things that cause the itch pushing us to use a product over and over.
+ **Action** is the actual behavior itself, which is done in anticipation of a reward. The easier and more fun the action, the higher the likelihood that the user will want to repeat it.
+ **Variable reward** is the unpredictability associated with the usage action and this turns every interaction with the product into a new adventure.
+ **Investment** involves the user giving the product a bigger place in her life. By bringing in more people, sharing more data with the platform or spending more money to upgrade to a more premium service, she makes it more likely that she will come back and go through the four steps of the Hook Model another time. The fact that we value more the products in which we invested significant time and effort is just one of the tricks our brain plays on us.
## **The creepy background to the model and ethical concerns**
However, those tricks seem to be an integral part of marketing, customer acquisition and retention efforts these days. As Eyal and Hoover take us through the stages of the Hook Model and explain the reasoning behind each step, a chilling feeling sets in. Getting people addicted to something always involves taking advantage of particular weaknesses or cognitive biases we as human beings are particularly vulnerable to. Your favorite coffeehouse, for example, is taking advantage of one such bias (called “The Endowed Progress Effect”) when they gift you a punch card with two holes already punched, with the promise of a free cup of coffee when you get to ten punched holes. They could just as well give you a card with eight unpunched slots but the tactic with two pre-punched holes achieved a completion rate 82 percent higher than the other, as Eyal and Hoover quote from an [experiment](https://papers.ssrn.com/sol3/papers.cfm?abstract_id=991962).
The possibility that corporate giants might have figured out all our cognitive biases and have us all wrapped around their fingers is a disturbing one. Ethical conduct on the part of companies is what can shield customers from the harm they are not even aware of. *Hooked* dedicates considerable space to a precautionary discussion of the role ethics should play in habit formation. Where does marketing end and manipulation start? Does the goal of creating an addictive product justify anything and everything?
Eyal and Hoover bring to the fore two questions for product designers to use as a yardstick in deciding whether they crossed the red line in habit formation: “Would I use this product myself?” and “Does this product improve the user’s life?” Products for which both answers are “yes” are the ones you can get behind. On the other hand, pushing a product that wouldn’t improve the user’s life and you wouldn’t use yourself could simply be deemed exploitation. As legislation catches up with times, one can expect that this sort of exploitation of people’s cognitive weaknesses for material gain will have legal implications, too.
## **Final thoughts**
*Hooked* reveals the magic touch that turns brands into integral parts of our daily lives. It is also a guide for product designers and growth marketers, full of hints on little adjustments you can implement in your funnel and make a big impact on customer usage rates. The questions under the ‘Do This Now’ section at the end of each chapter provide a good way of self-reflection and honest assessment of your product. If you think your product is underachieving, *Hooked* might be a good starting point to chart a new route.
--- START: blog/book-review-how-open-source-ate-software/book-review-how-open-source-ate-software.md ---
# **Book Review: How Open Source Ate Software by Gordon Haff**
There was a time when open-source software was known by just a small group of coders. It has moved on from days when it was the free software advocated by a few tech geeks to an era where it now undergirds mission-critical public and private platforms. This month's book, [*How Open Source Ate Software: Understand The Open Source Movement and So Much More*](https://www.amazon.com/How-Open-Source-Ate-Software-dp-1484267990/dp/1484267990), by Gordon Haff, sheds light on how this transformation took place and what kind of ramifications it had on the software industry at large.
## **Been there, done that**
The author of the book, Gordon Haff, is a tech guru and Red Hat evangelist with decades of experience in product development. Open source has been at the center of his professional life as he worked, wrote, and talked on this topic for years. *How Open Source Ate Software*, a definite reference to [Marc Andreessen's oft-cited words](https://www.wsj.com/articles/SB10001424053111903480904576512250915629460), is a book on open-source software and the new software industry. As he talks about open source, Haff is actually analyzing the transformation the software industry underwent from software as an add-on used to sell more hardware to closed-source, proprietary software to software as a commodity.
## **A new way of developing software**
In his book, Haff regards open source as "a broader movement for organization, collaboration, innovation, and development," as opposed to the narrower sense associated with people's right to access free software. Open source turned out to be a disruptor that changed the way software was developed. From Haff's account, one gets the impression that the emergence of open source, and Linux in particular, was an inevitable outcome. The rise of the Internet had changed everything and Microsoft, the king of the software market at the time, was slow to react to this change. If it weren't for Linus Torvalds, some other coder would take advantage of this window of opportunity. This position is supported by a quote from Bryan Cantrill, an engineer and co-founder of Oxide Computer, who says:
>*"I think if it's not Linux, it would have been one of the BSD variants that would have been the de facto Unix on x86. It is the rise of the Internet, and it is the rise of SMP [symmetrical multiprocessing] to a lesser degree, and then the rise of commodity microprocessors as the highest performing microprocessors to which Linux grabbed a ride, drafted on those economic mega-trends, but did not really contribute to them."*
Open source can be a confusing concept for regular folks to understand. First, just because some software is open-source doesn't mean it is free of charge. Red Hat, the company Haff has worked for since 2010, illustrates this point. Secondly, "open" does not mean "vulnerable." On the contrary, contributions from elite developers all over the world make a project more resilient. Thirdly, there is the issue of open-source licenses. Why would you need to use something that is seemingly open and free? Haff does a good job of touching upon topics like these and explaining them to the uninitiated.
## **Only selectively open**
Haff also draws attention to a problem that might have far more serious ramifications for our society today than whether some piece of code is open or proprietary. He highlights that companies like Google and Facebook are rather enthusiastic about open-sourcing their code, but they are much more reluctant when it comes to sharing their data. The two tech giants, often criticized for the morally questionable methods they employ to gather data, are effectively using their [open-source contributions](https://www.statista.com/chart/25795/active-github-contributors-by-employer/) for a charm offensive to present a better image. They have achieved this without compromising the opaqueness of how they gather and handle data, which happens to be our data.
However, the book isn't without its flaws. Its layout is a little confusing, as it usually happens when you try to blend a chronological narrative with a subject-based approach. The author spends page after page giving his readers tips on how to name a product in another section. He delves into topics such as the history of software, open data, open education, open hardware, and open culture, which are only tangentially related to open source while wrapping up the book. In that sense, the book sometimes feels like a collage of excerpts brought together from different texts or speeches and lacks coherence.
## **Final thoughts**
Still, *How Open Source Ate Software* is worth a read to understand and appreciate how open source has evolved, changing our lives in the meantime. After all, it is one of the most unlikely stories in the tech world: A modern version of the well-known biblical story of David and Goliath, but with a different ending. This time, the flimsy David doesn't go so far as to destroy the giant but befriends him after teaching him a lesson. By first proving its mettle and then winning over the hearts and minds of everyone, including software companies whose livelihood depended on proprietary software, what open-source software has achieved so far is no less impressive than what David did.
--- START: blog/book-review-innovators-dna/book-review-innovators-dna.md ---
# **Book Review: The Innovator's DNA by Clayton M. Christensen**
Saving innovation from the grasp of chance and divine intervention, and turning it into something predictable, repeatable have been the passion of many a scientist, industrialist, business executive, and scholar since the First Industrial Revolution. The late Harvard professor Clayton M. Christensen has been one of the more prolific scholars in researching innovation. His *jobs-to-be-done* concept focusing on understanding customer needs and having that understanding guide innovation have been significant contributions to the field, inspiring other works as well.
[*The Innovator's DNA*](https://www.amazon.com/Innovators-DNA-Updated-New-Introduction/dp/1633697207) is a book on how to make disruptive thinking a core competency. Its methodology involves interviewing roughly 60 innovative entrepreneurs and senior executives in order to understand what makes them special and the common points they share. The authors found out that great innovators were exceptionally good at associational thinking, that is, "… making connections across seemingly unrelated questions, problems, or ideas…" to synthesize something new. This cognitive skill is nurtured by four behavioral skills: Questioning, observing, networking, and experimenting. Together, these five skills are dubbed the "discovery skills" throughout the book. The authors then compare innovators with non-innovators to verify their findings about skills that matter in effecting innovation. The book is organized around the four behavioral skills of questioning, observing, networking, and experimenting. It lays out how great innovators put these skills to use and how processes and philosophies built around these skills can pave the way for success.
While deciding which innovative entrepreneurs and executives to interview, the authors focus on a list of most innovative companies by Businessweek, which relies on a company's past performance to judge how innovative it is. The authors challenge this approach with a creative method they devised, called “innovative premium.” This metric refers to the part of a firm's market value that cannot be accounted for by its cash flows generated by its products or services. It helps explain why companies like Google, Apple, or Amazon are valued much more highly than their cash flows can justify, and why the valuations of more traditional companies like Toyota, Nokia or Sony are so modest in comparison despite their relatively high revenues. It turns out that investors appreciate the innovative approach of the first group of companies—these companies keep bringing more innovative products and services to the market that generate profits. The second group of companies, even if they are engaged in innovative activities, rarely bring to market products and services that will disrupt the market and spur growth.
However, the overall methodology of the book lacks the creativity that the authors exhibited in conceiving the innovative premium concept. To be fair, introducing scientific methodology into social sciences has always been tricky since social or psychological phenomena do not easily lend themselves to quantification. The same issue arises in *The Innovator's DNA*: How do we measure skills such as questioning, observing, networking, and experimenting? The authors conducted a survey to measure these skills, asking interviewees questions and eliciting answers on a scale where 1 corresponds to *strongly disagree* and 7 corresponds to *strongly agree*. The rest follows from this subjective analysis of a person's assessment of herself or a colleague or an associate.
Another issue with the book is the confirmation bias that kicks in from time to time. Authors incorporate data and stories that will support the point they are driving home and leave out parts that will contradict the main argument. The discovery skills examined in the book cannot be the only factors that make people like Jeff Bezos and Marc Benioff so successful. But for the sake of convenience, data fitting into the theoretical framework of the book are emphasized, while attributes that do not corroborate the theory are left out. The same tendency applies to the anecdotes narrated to emphasize why some select qualities are the key difference-makers, although the same anecdotes could have been interpreted in a way that emphasizes completely different qualities as well.
Despite some methodological problems that come with the territory and are hard to overcome in this specific genre, *The Innovator's DNA* is a powerful book that does a good job of dissecting disruptive innovation. It makes clear that innovative thinking should be the responsibility of everyone in an organization, not just the R&D department. A culture and philosophy of innovation have to permeate every corner of the organization if it is to stay ahead of the game and ensure sustainable growth in the future. The book's continuous focus on skills required to drive innovation can help entrepreneurs and executives fast-track a program of innovation in their respective companies. In addition to determining the skills key to associational thinking, the book wraps up with an appendix where readers can find advice on how they can hone their discovery skills. Still, for readers who would like to see a more scientific approach to innovation, Anthony W. Ulwick's [*Jobs to Be Done: Theory to Practice*](https://jobs-to-be-done-book.com/) and its ODI (Outcome-Driven Innovation) framework would be a better choice.
--- START: blog/book-review-jobs-to-be-done-ulwick/book-review-jobs-to-be-done-ulwick.md ---
# **Book Review: Jobs to Be Done by Anthony Ulwick**
Understanding what makes some products significantly more successful than others in this day and age, and how innovation should be carried out have been the running themes in the [books reviewed](/category/book-review/) on our blog so far. Our last attempt in this regard was our review of [*The Innovator's DNA*](/blog/book-review-innovators-dna/) by Clayton Christensen et al., which suggested a rather descriptive, qualitative approach to improving the innovation process. This month's book, [*Jobs to Be Done: Theory to Practice*](https://www.amazon.com/Jobs-be-Done-Theory-Practice/dp/0990576744) by Anthony W. Ulwick, with its methodology firmly planted in the fundamentals of scientific management, offers a stark contrast to *The Innovator's DNA*.
Anthony Ulwick is no stranger to researching and writing on innovation. Actually, it turns out that the *job-to-be-done* concept, which focused on customer needs and was widely publicized by Clayton Christensen, was developed by Ulwick. *Jobs to Be Done* is built around what the author calls "the Outcome-Driven Innovation (ODI) framework" (more on this later), and he tells us that he got his inspiration for this from techniques such as [Six Sigma](https://en.wikipedia.org/wiki/Six_Sigma) and [Five Whys](https://en.wikipedia.org/wiki/Five_whys). These techniques aim to improve quality by focusing on the root causes of defects and minimizing variability. Ulwick seems particularly influenced by Six Sigma, with its emphasis on statistical modeling and iterative processes. Throughout the book, the author strives to quantify the innovation process so that it becomes more of a science than art.
Ulwick's North Star in his analysis is the customer needs. He asks himself two questions: “How do the customers define success? What metrics do they use to assess a product?” Relying on customers' perception of a product to understand how much the product help them solve their pain can sound somewhat “unscientific,” especially for someone willing to give innovation a more scientific footing. However, there is a logic to Ulwick's approach. Although a customer's evaluation of a product is purely subjective, it is the right kind of subjective, because it looks at a product through a customer lens and the purchase decision itself is a subjective one, based on the customer's opinion of the product.
Ulwick's technique is based on uncovering the customer needs, discovering the customer-defined metrics, and using those metrics to improve the product. He calls his approach the Outcome-Driven Innovation. The ODI framework defines outcome as a metric the customer uses to measure success while executing a job. Desired outcome statements are formulated in a certain way that describes what the customer wants to do and how, like "cut wood in a straight line," or "automatically turn on the heater every time it is below 7°C and I start the engine." There can be 50 or more outcomes while dissecting a core functional job. Actually, the case studies in the book cite 165 or even 300 desired outcome statements.
After the desired outcome statements are formulated, the customer is asked to put a number on how important he thinks a particular outcome is and how satisfied he is with the current offerings. Then all the outcomes are laid out in a diagram that depicts the "Opportunity Landscape" and shows the company which segment of the market to target.
The outcomes that are satisfied at a high level despite not being valued by the customers are deemed “overserved.” In this overserved segment where there is an abundance of options and no pressing need for the solution to a problem, offering a more affordable option and better value for money can disrupt the market. Gaining this understanding can be invaluable as it prevents a company from investing in features that sound cool but doesn't serve a vital need for customers.
The outcomes that are not satisfied well enough by the product despite being highly valued by the customers are considered "underserved." This segment lends itself to a dominant strategy where a company can offer a product that will do the same job better and at a lower price point.
Linking customer needs to market segments, and market segments to market strategies are what set *Jobs to be Done* apart. The book starts with a focus on individual customer needs and minor complaints, and paves its way to a full-fledged company strategy that works. ODI reportedly raises the success rate of the innovation process from 17 percent to 86 percent by shedding light on what customers value in a product, which is undoubtedly impressive.
Ulwick also argues against the wisdom behind the “fail fast” mantra common among today's startups. This mantra advises startups to act upon their ideas quickly, test them, and pivot to something else without having to invest significant resources in ideas that don't work. For Ulwick, though, a strategy that depends on churning out as many ideas as possible without understanding first what the customers need is a waste of time. In his opinion, any innovation effort should be informed by what customers look for in a product.
The point Ulwick makes about the uselessness of customer personas built around demographic data or psychological traits is a true revelation. We are accustomed to categorizing people according to various combinations of attributes such as age, sex, profession etc. *Jobs to be Done* makes it clear that any categorization that cannot be validated by statistical analysis is bogus. We need to study customer needs like a statistician would do and try to turn them into metrics so that they become actionable and a common language can be built around them.
Although the ODI framework is, in theory, applicable to every industry, it doesn't look easy to implement for startups. Tasks like defining the job map, interviewing customers to ascertain desired outcomes (Ulwick suggests administering the survey to a group of 180 to 3000 job executors), and statistical analysis of the data gathered are quite resource-intensive and are well beyond the means of a startup. That's why the author advises these organizations to outsource such tasks to his company, [Strategyn](https://strategyn.com/). Enterprises have the money and human resources necessary for such an ambitious task. Not all enterprises may stand to benefit the same from the ODI framework, though. Manufacturing companies may expect to gain more as processes involved in the use of products like cars, machinery, home appliances, etc., which customers physically interact with, better lend themselves to statistical scrutiny.
On the other hand, software products should be harder to crack for the ODI framework as the customer experience offered by these products involves cognitive processes that are more challenging to decipher. Still, the analytical approach introduced by the ODI framework can help executives at a software company or even a startup analyze the product, consumption chain, and customer experience they offer and make high-impact changes to the processes that need to be improved.
*Jobs to be Done* is an exciting book for readers interested in the literature on innovation. It encourages readers to think in terms of customer needs instead of products, features, or ideas, and delves deeper into the innovation process than most other books in the genre. By teaching you how to uncover customer needs, it shows you where you should invest your time and money, and charts an open route to success. The Outcome-Driven Innovation is no walk in the park, but the promise of success makes it worth a shot.
--- START: blog/book-review-just-enough-research/book-review-just-enough-research.md ---
# **Book Review: Just Enough Research by Erika Hall**
If you happened to found a startup, you probably know that feeling of helplessness that engulfs you when the initial excitement wears off a few months into your journey and you realize that your business plan is not working. The product that you thought people would flock to use failed to gain traction. What little user base you had looked confused and lost as they tried to use it, and you didn't even know what was wrong because you had so little data.
This scenario is so common in the startup world that management gurus and entrepreneurs who made it coined catchy expressions to define it: *The Trough of Sorrow*, *the Struggle*, *the Traction Gap*, or *the Chasm*. However, the prevalence of this problem doesn't mean that there is an easy solution. Many startups learn this the hard way.
The real chasm exists between the fantasies of the product team and the surprise customers prepare for them. When you find out that you missed the mythical product-market fit by a mile and start looking into the chasm, you are actually looking into your lack of information on your customers. What do they think? What motivates them to buy the products of your rivals but not yours? Why all the angry comments under your Twitter posts?
## **How to make people talk**
The only way out of this situation is by getting to know more about your customers, their pain points, and the obstacles they run into when they try to use your product. But this is easier said than done. "*Talk to your customers! Listen to what they say!*" is one of the cure-all advice you hear from self-proclaimed marketing experts all the time. Erika Hall, in her book [*Just Enough Research*](https://www.amazon.com/Just-Enough-Research-Erika-Hall/dp/1937557103/), shows that talking to your customers is not the panacea that some people make it out to be, and it sometimes may even be counterproductive. Getting people to give you the kind of information you need is an art unto itself, and *Just Enough Research* shows you the fine points of this art.
*Just Enough Research* focuses on design research, the kind of research that aids and informs the product design process. The book targets non-professional researchers who want to become better at extracting information from diverse sources such as customers, stakeholders within the organization, competitors, or the public at large. From preparation to the actual research to evaluation of the results, *Just Enough Research* lays out the stages of research for the uninitiated and dives deep into what the researcher should do for good results.
## **Not the silver bullet you hoped for**
Design research is a lever you can pull to improve your product design, positioning, and marketing efforts. However, it can't create miracles. Erika Hall warns the readers against the limitations of different research methods and where they come up short. Among the "don'ts" Hall lists are techniques such as focus groups, surveys, and split-testing praised to no end by marketing specialists. Here is a synopsis of how Hall sees them:
+ **Focus groups:** Research theater conducted in an artificial setting that will compromise the validity of the results.
+ **Surveys:** A common cop-out used whenever a serious business decision has to be made. Surveys are a waste of time and resources when the sample is not representative of the population. Even when you manage to solve the representation issue, there is the problem of interpretation. "*Quantitative data doesn't guarantee objective interpretation.*"
+ **Split-testing:** A corporate favorite that creates an illusion of mathematical certainty and gives testers peace of mind while implementing ideas. Split-testing kicks off an endless chain of gradual optimizations that can go on forever. However, making big leaps requires taking risks, something marginal adjustments hardly provide.
Then there is the Net Promoter Score (NPS), the darling of every SaaS startup nowadays. Despite its popularity, NPS is of little use to a company because it tells nothing about what people do not like about you and what you can do to get a better score. It doesn't give you actionable insights and thus offers you no help in crossing the chasm.
## **Final thoughts**
Underestimating the challenges of getting information from people is one of the grave mistakes you can make if you are running a startup. Talking to people is easy, but getting useful information from them is not. Without a methodology, you are certain to waste your already scarce resources to collect data that won't make your decisions any better. *Just Enough Research* gives you a blueprint to follow during your in-house research endeavor, increasing your chance to make better decisions.
While showing you how to improve your research performance, Erika Hall also emphasizes the empty promises of specific techniques and their proponents that you should be wary of. You will be disappointed if you are banking on a few surveys and focus group studies to help you nail the product-market fit. *Just Enough Research* is a good book for non-professional researchers looking to educate themselves on design research.
--- START: blog/book-review-life-after-google/book-review-life-after-google.md ---
# **Book Review: Life after Google by George Gilder**
> *'Under the leadership of Larry Page and Sergey Brin, Google developed the integrated philosophy that currently shapes our lives and fortunes, combining a theory of knowledge (nicknamed “Big Data”), a technological vision (centralized cloud computing), a cult of the commons (rooted in “open source” software), a concept of money and value (based on free goods and automated advertising), a theory of morality as “gifts” rather than profits, and a view of progress as evolutionary inevitability and an ever diminishing “carbon footprint.”'*
George Gilder, previously of the *Life after Television* fame, is angry. He is angry at the way things are going around the world. He is angry about the economic system that took hold in the last decades. He is angry about what has become of the American technology industry. He sees a common thread linking all these problems and does a wonderful job of linking them together in a book full of analyses, insights, and forecasts about the future.
Gilder begins [*Life after Google*](https://www.amazon.com/Life-After-Google-Gilder/dp/9388423682) by giving us a view of how the economy functioned for centuries when it was based on gold—a chemically-irreversible metal whose value has always been a function of the time required to extract it. Then, he pans over to today, where gross world product stands at $78 trillion with global debt at $257 trillion, with currency trading 73X more voluminous than the commercial trade in goods and services, and oil-futures and real estate derivatives dominating the economy news. Gilder laments America's transformation from a superpower energized by heavy industry and high-tech hardware to a fiefdom of financial institutions gambling on fiat money and tech firms like Google, Amazon, Meta, and Apple that want to control everything in the pursuit of big data. He describes the incumbent world order as such:
> *'Birthed in the fogs of Stanford, hosted in the clouds of Google, and aiming at superhuman artificial intelligence, that system exalts academic honors, all-purpose Turing machines, software supremacy, open-source modularity, and secret-sauce integration.'*
According to the author, this world order is faulty by design because it gives away services free of charge and thus has no customers. Due to that lack of customers, it is not guided by market signals. Giant data centers digging into petabytes of data to find the most suitable ads for internet users is no way of creating real wealth, Gilder states. Wealth is to be created by creativity and tested knowledge, of which there is none in the Google system.
American industry is completely destroyed in the eyes of Gilder, and so is the American academia: Full of people flaunting degrees and titles, advocating reactionary causes, and virtue signaling without producing anything meaningful. However, not all hope is lost. Organizations like the 1517 Fund and Peter Thiel's Thiel Foundation, which support college dropouts who can defy the Silicon Valley norms and think out of the box, keep the hope alive for Gilder. These organizations advocate a science without scientists and back people like Stephen Balaban of Lambda, Austin Russell of Luminar, and Vitalik Buterin of Ethereum. These people give Gilder hope: Creative geniuses in the mold of the great American inventors of old, who are concerned with getting the job done and creating value instead of blending into the existing order.
Gilder believes that trying to predict the future by analyzing the patterns hidden in the past data is not the way to create wealth, either. This is why he argues that investing in artificial intelligence and machine learning will not be the panacea they are made out to be. Gilder's money is on the blockchain-based distributed technologies to save humanity from the grasp of this despotic, power-hungry, and clumsy monster created by the Silicon Valley giants. He expects blockchain to unbundle financial conglomerates into "transactions, loans, crowdfunds and crypto-assets." However, blockchain-based coins like Bitcoin, with a hard cap of 21 million units imposed on it, cannot function as a currency because its value will remain artificially high compared to gold, whose amount increases at 1.6 percent per year. In Gilder's opinion, blockchain-based coins should dump the dream of becoming currencies and focus on offering "security, identity, and trust," just like Muneeb Ali's Blockstack.
*Life after Google* is a frontal assault on the big tech companies best epitomized by Google. These companies love to monopolize and feast on our private data while failing to protect it. They funnel money into their coffers through a "porous, perforated internet stack," accumulating power in their hands and imposing their own version of morality on society. As he reckons with Google et al., Gilder delves deep into the history of information theory and weaves a thread linking Kurt Gödel, Andrey Markov, Clause Shannon, and Alan Turing to Larry Page, Sergey Brin, Urs Hölzle, Elon Musk, and Tim Cook. These sections can be difficult to grasp for the uninitiated as the author seriously philosophizes on what information science and computing have been and should be. Still, he does a masterful job of putting things into perspective.
Gilder is openly rooting for the unlikely heroes like Vitalik Buterin and Muneeb Ali, who have shown promise in building an alternative to "Big Data." Having read *Life after Google*, one cannot help but hope that these young Davids find a way to take down Goliath for the sake of all of us.
--- START: blog/book-review-move-fast-and-break-things/book-review-move-fast-and-break-things.md ---
# **Book Review: Move Fast and Break Things by Jonathan Taplin**
The authors of the books we review every month tend to be quite special people: Inspiring entrepreneurs, venerable scholars, and engineers who made it. Jonathan Taplin is no different. He is currently serving as the director emeritus at the Annenberg Innovation Lab at the University of Southern California. So he is part of a group of leaders guiding the digital revolution we have been going through in the last three decades. He is also a visionary, having founded with two friends a streaming-video-on-demand company, Intertainer, in 1996, long before the introduction of broadband internet network. In a sense, he had launched what could have become the "YouTube before YouTube" if it weren't for the lack of infrastructure.
## Feeling the pain
It would have been a familiar "what-could-have-been" story if this was all there was to Taplin. However, he isn't your run-of-the-mill tech entrepreneur. He spent years working as the tour manager for the Band. A music and movie producer, he rubbed shoulders with the likes of Bob Dylan and Martin Scorsese. He was there when the music and movie industries peaked in the 1960s and 1970s and also witnessed how the advent of the Internet destroyed them.
What dealt these two industries the first blow was platforms like Napster and pirate sites that acted as though copyrights never existed. Later, Youtube emerged, hosting pirated content and claiming ignorance while reaping the benefits in terms of ad revenues. Today, people are spending more money on music, books, and movies than they ever did, but the portion of that money going into the bank accounts of creators is getting smaller. It is the usual suspects that are pocketing the difference. As a result of this sea change, the majority of artists find it impossible to live on the income generated by the royalty fees of their past works.
[*Move Fast and Break Things*](https://www.amazon.com/Move-Fast-Break-Things-Undermined/dp/0316275751) is a manifesto against the tech industry that knows no bounds in its quest for ever bigger profit margins. It is written by someone who has seen friends get taken advantage of and live personal tragedies while the rewards of their hard work accrue to others. Selfish Silicon Valley moguls destroyed the lives of Taplin's friends, and he is in no mood to let it pass.
## **Newer, bigger, stronger gatekeepers**
Taplin is talking on behalf of many of us when he criticizes what has become of the Internet. The twentieth century was not an egalitarian utopia as it had its share of gatekeepers in show business—producers, record companies, and studios who decided which songs or movies would meet the masses. The twenty-first century, though, has replaced them with even more ruthless gatekeepers and turned artistic creation into a matter of 1s and 0s, with creators having almost no control over how their works are consumed.
Taplin gives us a glimpse of the market in the tech industry, which goes a long way toward explaining what we are faced with:
+ YouTube enjoys a 52 percent market share in the music-streaming business.
+ Amazon controls 70 percent of the ebook business and receives 51 cents of every dollar spent on online commerce.
+ Google has an 85 percent share among search engines.
Does that sound like an equal-opportunity arena to you?
The object of Taplin's ire is libertarians, disciples of the economist Milton Friedman and the philosopher Ayn Rand, who shun government control or any form of regulation that can reign in the forces of the market. Among them are people like Google executives and the Koch brothers. They penetrate the U.S. government, recruit ex-government officials and send their employees to work for the government, meddle in the legislative process, and make sure that nothing can threaten their grasp on power.
Leveraging their political clout, companies like Google, Amazon, and Facebook have built a moat around their businesses. Typically, highly profitable businesses make an industry attractive for newcomers, and the latter's entrance brings the profits down. The tech industry seems insulated from any such effect as technical barriers are high, and the incumbents can easily change the rules of the game as they have massive control over the government. Therefore, they continue extracting monopoly rents from services that have become utilities of our age.
## **No saint at all**
One interesting character among the libertarian mob is Peter Thiel. Thiel was one of the good guys in George Gilder's book, [*Life after Google*]( https://www.peaka.com/blog/book-review-life-after-google/). He was the standard-bearer who led the assault on the alliance between the PhD-holding Silicon Valley elites and academia. In Gilder's eyes, Thiel was the protector of college dropouts who wanted to overthrow the existing order in the tech industry. He was the brains behind the Thiel Fellowship, which encouraged young people to stop chasing pointless degrees and pursue meaningful change instead. Gilder presented him as a guy who mentored rebels like Vitalik Buterin against the Big Data tyranny.
Jonathan Taplin disagrees with this "Saint Peter of Silicon Valley" image Gilder paints. Peter Thiel, in his own words, "the godfather of the PayPal Mafia," is the main villain in Taplin's account. He is a libertarian with a Darwinian view of life who is out to destroy anything on his way, including regulation, taxes, copyrights, and democracy, to secure money and power for himself. This contrast between the two accounts of the same man reminds us of the complexity of the politics of tech business today. One party's hero turns out to be another party's thief.
## **Final thoughts**
Jonathan Taplin fondly remembers the heyday of show business. His book is an emotional account of the demise of the pre-digital age entertainment industry. He is bitter against the perpetrators who enjoy fame and wealth despite building those two on the ruins of the livelihoods of artists. He is realistic in thinking that the golden age of music and cinema will never come back. The emergence of technologies like artificial intelligence and machine learning will make matters worse as what was successful in the past will determine what will be produced in the future, killing human creativity.
*Move Fast and Break Things* was written in 2017, at the beginning of the Trump presidency. It is disheartening that the last few years haven't seen much improvement with regard to copyright infringement by the usual suspects. However, the public has become more sensitive to issues like data privacy and the control a few tech companies enjoy over our politics and the democratic process. The best days of music and cinema may be behind, but maybe we can save our democracy.
--- START: blog/book-review-obviously-awesome/book-review-obviously-awesome.md ---
# **Book Review: Obviously Awesome by April Dunford**
Positioning is the bane of any tech startup. Complain to founders about a feature, and it will get fixed right away. Do you want better customer support? The whole team will sacrifice their night’s sleep to make sure that customers are satisfied with the support they get. Startups can solve most of their problems by putting in more effort. However, product positioning is not one of them. It is witchcraft to tech founders: They have a general idea of what it is and how it is supposed to be done but can't seem to nail it for some reason.
## **Chasing the ever-elusive product-market fit**
Discussions on “product-market fit” dominate the product team meetings held during the initial stages of a startup. Product-market fit is defined by [Gartner](https://www.gartner.com/document/4016082) as "_the milestone in the development of a new product or service when the customer acquisition processes have become repeatable and predictable._" The term refers to that particular state of affairs where your company is ready to scale. Once you are there, your business plan starts to work like a well-oiled machine, demand surges, word-of-mouth kicks in, and you hop on the tide that will take you to glory.
It is the dream of every startup founder to achieve the mythical product-market fit as soon as possible. But how do you get there? Even the most acclaimed management gurus have a hard time giving a definite answer to that. "When you find the product-market fit, you will know it," is the standard answer, meaning that it will be impossible to miss once you are there. It is not much of a help for founders trying to chart a route for themselves, though.
In this month’s book review, we are taking a look at [_Obviously Awesome_](https://www.amazon.com/Obviously-Awesome-Product-Positioning-Customers/dp/1999023005), written by April Dunford, a business professional with sixteen product launches under her belt over twenty-five years as VP of marketing. Dunford tackles the product positioning problem in the book and has refreshing insights for founders and marketers looking to achieve product-market fit.
## **How it used to be**
Getting the product positioning right is the _sine qua non_ for product-market fit—you don’t get the latter without the former. What should a company do to position its product correctly? The conventional quest for the product-market fit used to start with the formulation of a "[positioning statement.](https://www.lennysnewsletter.com/p/positioning)"
> _Our product is a_ (**MARKET CATEGORY**) _that does_ (**UNIQUE ATTRIBUTES**)_, which enable_ (**VALUE**) _for_ (**TARGET CUSTOMERS**)_, unlike_ (**COMPETITORS**)_._
Once you filled in the blanks, you ended up with a riddle-like statement that was supposed to guide your marketing efforts from that point onwards. But it never worked because it said nothing about how the positioning would be implemented. Therefore, the issue was assigned to a junior marketer, brought up in a marketing meeting for a brief discussion, and then left behind as one of the numerous "feel-good" exercises a startup does early on in its journey, similar to what Dunford experienced as a marketer at IBM.
## **Challenges of positioning**
There is a reason it takes even the most experienced marketers months, even years, to position a product correctly. The process is fraught with challenges. Dunford calls those challenges "traps" and points out two:
- Not realizing that the product you built is not what you intended to build.
- Finding out that the market is no longer the market you designed your product for.
When you are not aware of what you are building and who you are building it for, any attempt at positioning becomes nothing more than shooting in the dark. Getting out of this situation takes a methodical approach, which April Dunford offers us in her book.
## **A new way forward**
Having faced time and again the problem of positioning at every startup she worked for, Dunford felt pressed to devise a technique that could be applied to different environments. She decided to break successful product positioning into five components, plus a bonus one:
- Competitive alternatives
- Unique attributes
- Value
- Target market characteristics
- Market category
- Relevant trends, if there are any
However, identifying the positioning components does not suffice because the components are interdependent. One component interacts with others, making it difficult for a novice to decide where to start. Dunford arranges the positioning components in a flow that guides the practitioners of the framework to success.
{{ resize_image(path="../static/assets/images/blog-images/obviously-awesome-positioning-flow.png", width=759, height=400, op='fit_width', alt="The product positioning flow") }}
Product positioning flow.
Image credits: April Dunford, _Obviously Awesome._ The image was modified to optimize page layout.
This analytical approach is one of the points that set _Obviously Awesome_ apart from similar books: It goes beyond just describing the lay of the land and provides the reader with a road map to help her get to where she wants.
## **A game of manipulation**
Dunford believes that positioning is all about context-setting: It involves changing what your customers think about your product. People see a product as part of a context and later use that context as a frame of reference to decide whether they want the product or not.
Positioning is a way to tinker with this frame of reference and bring your product to the attention of a particular customer group that will make the most use of it. The author calls this group the "_best-fit customers._" According to her, you should narrow this group down to the point where it is just big enough to allow you to realize your business goals. Forgoing a big portion of the market right from the start may sound counterintuitive to ambitious founders. However, it is the right thing to do as it helps a startup gain traction faster without wasting the already scarce resources to lure customers who will never buy the product. This also ties in nicely with [Paul Graham's famous maxim](https://www.techinasia.com/airbnb-co-founder-brian-chesky-make-100-people-love-product):
> _“It’s better to have 100 people [who] love you than finding a million who just sort of like you.”_
## **Time to unleash your inner Draper**
Having noticed the lack of a product positioning theory in the marketing literature, Dunford has spent time thinking, writing, and talking about positioning, becoming a prolific keynote speaker and a sought-after consultant in the process. The Peaka team was privileged to attend one of her webinars at a ScaleX event on June 30, 2022, and we were dazzled by her communication skills and wit as she talked about one of the more challenging topics in marketing.
_Obviously Awesome_ is the culmination of Dunford's efforts to distill a repeatable process out of her experience. It gives startups an actionable plan to nail positioning once and for all. The book serves as a concise guide for founders and marketing people, helping them understand what positioning is and how to tackle it. _Obviously Awesome_ presents successful product positioning as a sequence of ten steps and provides the readers with relevant real-life examples of companies that managed to turn things around with smart moves. That it is also a very enjoyable read is another plus.
Like [Don Draper said to a client](https://www.youtube.com/watch?v=ijJonVw7YPY) during a dinner meeting in a Mad Men episode, “_If you don’t like what is being said_ [about your product]_, then change the conversation._” April Dunford is showing you how.
--- START: blog/book-review-product-led-organization/book-review-product-led-organization.md ---
# **Book Review: The Product-led Organization by Todd Olson**
Remember how big of an event a software launch would be 15 to 20 year ago? And the boxes, CDs and all that documentation that came with every software purchase? Every major release or update would be an event in its own right. We don’t have those anymore. ‘Product release’ as we knew it seems to be dead. Today, subsequent versions of a software product are rolled out in a more seamless and sometimes completely unnoticeable fashion. This is the age of continuous integration (CI) and continuous deployment (CD). What changed?
## **Adapting to changing times**
A new approach to software development has emerged in the last decade or so with the proliferation of SaaS (software-as-a-service) companies. Capitalizing on the capabilities offered by cloud-based systems and built on principles of Agile project management, this new approach is characterized by shorter and faster iterations, constant path corrections informed by heavy utilization of usage data, continuous integration and more frequent deployments. It emphasizes customer experience over product features, not because that is the cool thing to do but because it makes perfect business sense:
> *[Research by Forrester](https://www.forbes.com/sites/forbestechcouncil/2015/11/19/good-ux-is-good-business-how-to-reap-its-benefits/?sh=4229ee504e51) shows that every dollar spent for customer experience generates 100 dollars in return.*
Improved customer experience is the way to achieve higher customer retention rates and reduce the cost of customer acquisition. The idea to use the product as an engine for acquiring and retaining customers and driving growth, in short making the product the experience itself, has simply come to be known as “product-led growth” and inspired quite a bit of literature lately.
## **The right man for the job**
Product-led growth envisions an evolutionary approach to product development. At the centre of this strategy is the product manager who plans, guides and oversees the effort to develop the right product in light of the usage data gathered from customers. This month’s book, [*The Product-led Organization*](https://www.amazon.com/Product-Led-Organization-Putting-Customer-Experience/dp/1119660874), is, in a sense, a handbook for product managers who are willing to pursue a product-led strategy for their SaaS companies. The book makes a good job of laying out which metrics a product-led organization should keep an eye on, explains how to combine hard data with customer feedback, and describes the composition of a good product team.
The author of the book, Todd Olson, is the CEO and co-founder of [Pendo](https://www.pendo.io), “*a platform that accelerates and deepens software product adoption,*” which has so far [raised $356 million](https://www.prnewswire.com/news-releases/pendo-raises-150-million-to-help-companies-deliver-software-that-meets-rising-user-expectations-301342064.html) worth of funding. Pendo is valued at $2.6 billion as of the time of the writing and currently boasts an annual recurring revenue of more than $100 million. So, it is safe to assume that Olson knows a thing or two about being a product manager. Having also had his fair share of failures in his career, he sets out in his book to find an answer to the question “*Is it possible to build a sticky product right from the start?*” He quotes from the Standish Group that “*nearly 84 percent of projects will either fail or go over budget,” and that “most features are rarely or never used.*”
## **The basics of being product-led**
There is something fundamentally wrong with the way most projects are developed and Olson’s data-driven approach aims to fix that. What guides his philosophy is the famous maxim by Peter Drucker, the management guru: “*You can’t manage what you can’t measure.*” Olson’s ‘north star’ metrics in his quest to develop better products are the ones that show product adoption and usage. Throughout his book, Olson endorses giving up the old way of innovation, which mostly depended on unvalidated assumptions and gut feeling, and suggests instead taking advantage of cloud-based platforms that can provide a product team with more data about the users than they can handle.
A product-led team, according to Olson, should focus on minimizing the friction a customer experiences once he enters the funnel. The idea is to make him discover value as soon as possible. In this model, interactive in-app help replaces old-school documentation and a customer success team is at work to make sure that problems are tackled before they become widespread. Every action taken within the organization is geared towards the goal of giving the customer the best possible experience.
Olson is quite shrewd in the way he gives reasons why product development at a software company today has to be product-led. He reminds the reader that shipping features without paying attention to what customers want can ruin the whole customer experience, and brings up the case of Wall Street traders and investors who saw their productivity plunge when the keyboards at the Bloomberg terminals they used were replaced with mouses. The gist of the story is, *it is not an improvement if the customer does not want it*.
## **Final thoughts**
*The Product-led Organization* is a lot like [*Hooked*](/blog/book-review-hooked/), the book we reviewed last month, in that they both focus on how to form customer habits. However, Olson’s book goes about it in a more data-driven and quantitative way, while *Hooked* follows a more descriptive and qualitative path. The two complement each other rather well, with *The Product-led Organization* demonstrating how to leverage data to make sure that every decision made is data-informed, and *Hooked* delving into the psychological mechanisms that bear on those decisions.
*The Product-led Organization* offers a reality check to anybody dreaming of founding the next SaaS unicorn. It sheds light on the challenges of building the right type of software the customers will love using, one that nails the product-market fit. Having read it, one automatically gains a different perspective on why some firms are able to grow at a stunning pace without any problems attracting investment, while others fizzle out. Todd Olson knows how to overcome the challenges of a SaaS business, as he did more than once in his career, and provides product managers and entrepreneurs with a blueprint for success in this particular sector. You would be well-advised to read his book before spending a dime or writing a single line of code for your next project.
--- START: blog/book-review-rocket-surgery-made-easy/book-review-rocket-surgery-made-easy.md ---
# **Book Review: Rocket Surgery Made Easy by Steve Krug**
> *"Usability testing? Man, that's rocket science to me."*
> *"I know nothing about usability testing. You could as well ask me about brain surgery."*
These imaginary statements could very well belong to a startup founder, and they might be responsible for the inspiration Steve Krug received to name this month's book.. Usability testing of any kind is the bane of decision-makers at companies. Whether it is a landing page, an app, an e-commerce interface, or just a good ol' conventional website, you know that you have to conduct a usability test to see what works and what doesn't. But it keeps getting delayed because there is always something more urgent and, more importantly, you don't know where to start. In his book, *Rocket Surgery Made Easy*, Steve Krug lays out a blueprint for usability testing so simple that you would feel bad if you did not give it a shot.
## **"When fixing problems, try to do the least you can do"**
Krug is aware that usability testing is never high on the to-do lists of companies. He takes utmost care not to further complicate the process, which would only make any amendments less likely to be implemented. The title of one of the chapters sums up the author's rationale: "*The least you can do.*" He cheers on the reader throughout the book, telling him that, when it comes to usability testing, "doing something, anything, is better than doing nothing." He keeps the bar so low that you will have no excuses to postpone this task or cancel and feel like a traitor if you fail him.
The author thinks most of the design problems are quite obvious, and even a short test will be enough to reveal them. It's great if you can commit time and resources to run tests with more participants and more frequently, but it's highly likely that you won't. So, Krug's bare-minimum testing is your best bet. And "*it works because:*
+ *All sites have problems.*
+ *Most of the serious problems tend to be easy to find.*
+ *Watching users makes you a better designer.*"
## **The how and the why**
Steve Krug's ideal usability testing consists of three 50-minute tests you conduct one morning every month and a debriefing session afterward. This is how he describes the event:
> "*Basically, a facilitator sits in a room with the participant, gives him some tasks to do, and asks him to think out loud while he does them.*
> *There's no data gathering involved. Instead, members of the development team, stakeholders, and any other interested parties observe the session from another room, using screen-sharing software. After the tests are finished, the observers have a debriefing session where they compare notes and decide what problems should be fixed and how to fix them.*"
The key here is to get the participants to keep talking as they navigate the website or app. Hearing what they are trying to do on the tool, what gets them confused, or where they are failing can be an eye-opening exercise for the development team. The team should take notes, write down questions, and discuss the session over lunch to identify the most urgent problems and appropriate fixes.
Krug advises his readers not to obsess over recruiting people who are like their "actual users," reminding them that testing more than three participants generates too much information to digest. These suggestions may sound counterintuitive, but they are perfectly in line with his "simple, informal, small-sample, do-it-yourself usability testing" approach. Keeping that in mind, the book's title could as well be "*perfect is the enemy of good.*"
## **Conclusion**
*Rocket Surgery Made Easy* is a short, easy-to-read book that removes all the excuses decision-makers list to avoid conducting usability tests. It recommends picking the low-hanging fruit first, no matter how small it is in size. Any improvement is better than no improvement. *Rocket Surgery Made Easy* provides you with the minimum requirements to get off on the right foot in your usability testing journey.
--- START: blog/book-review-superconsumers/book-review-superconsumers.md ---
# **Book Review: Superconsumers by Eddie Yoon**
How to find and sustain growth is the question that haunts founders and executives in today’s hyper-competitive world. Many books we have reviewed in this column so far were part of the literature that strived to find a solution to the growth problem.
Andrew Chen’s [The Cold Start Problem](/blog/book-review-cold-start-problem/) featured network effects as the solution to the problem. [For Tony Hsieh](/blog/book-review-delivering-happiness/), it was the company culture that held the keys to extraordinary growth. [Geoffrey A. Moore’s cure](/blog/book-review-crossing-the-chasm/) was based on a strategy focusing on a niche you could dominate from the start and expanding from that.
This month’s book, *Superconsumers*, is written by Eddie Yoon, a growth strategist and a business consultant. In Yoon’s perspective, companies willing to nail the growth game should find, nurture, and capitalize on a group he calls superconsumers (*surprise, surprise*).
## **The theoretical framework**
Superconsumers are your best-fit customers who immediately recognize the value of your product, make it a central part of their lives, and simply can’t get enough of it. These people are different from heavy users who buy a product in large quantities. They are passionate about a product in a way that other customers are not. They have a quest in life, and the product they identify with plays a big part in satisfying that quest. Yoon shares two facts to illustrate the impact superconsumers can have on whole industries:
+ One-third of all consumers in the office supplies market drove 70 percent of the profit,
+ 0.15 percent of gamers account for 50 percent of in-app purchase sales (that is, just 15 out of 10,000 gamers create as much as the remaining 9,985).
The book is heavily built on the job theory of Clayton Christensen. It defines superconsumers as people who develop a strong bond with products they use to satisfy certain jobs or quests. Eddie Yoon also borrows from Christopher Lochhead and his friends the “category creation” idea. According to this perspective, superconsumers are the customers who help a product realize its potential in a category it created. No brand gets to be a category king without understanding and leveraging its superconsumer base first.
## **What makes superconsumers so special?**
Yoon’s focus on superconsumers as the engine of growth stems from his work as an analyst and consultant over the years. Having studied Nielsen’s Homescan database, Yoon and his friends were able to create a data set of 125 consumer goods categories with a total sales volume of $400 billion. His four key observations are:
+ Superconsumers offer a higher ROI on the marketing dollars spent. They buy more products at higher prices, and they don’t mind price increases as long as they get a better product or experience. They not only spend more money than regular customers, but their enthusiasm can be infectious, too. **Regular consumers spend 20 percent more in markets with a high concentration of superconsumers.** Shops and stores frequented by this particular customer profile draw in other customers as well.
+ Superconsumers form clusters called ***super geos.*** It is these communities that create the buzz and drive most of the profit for a category. These people spread the word on social media, discuss the product in forums, and influence potential superconsumers. It is thanks to super geos that products become trends.
+ Superconsumers are not a fickle bunch. They have immense brand loyalty, and the products they like help them satisfy a quest in life, which makes their spending behavior more predictable. Strategies built around them are easier to communicate, implement, and more likely to win buy-in from decision-makers.
+ Superconsumers are a valuable source of insights and feedback. They understand a product better than anyone else and can even have their own unique ways of using it. Therefore, co-opting them as informal consultants can broaden the horizons of the product team. Companies should also find ways of tapping into the experience and insights of employees who are superconsumers at the same time.
## **Final thoughts**
Eddie Yoon’s observations come from the consumer goods sector. Although they make a lot of sense, it is safe to assume that some of them will not readily translate into other fields like the tech industry. The business advice that Yoon provides throughout the book is quite descriptive in nature. Actually, the book reads like a collection of sensible recommendations but lacks a coherent, actionable plan. It tells you what to do but not how you can do it.
There is a lot of literature written on the customer groups that we refer to as ideal customer profile, best-fit customers, or superconsumers, all of which roughly describe the same concept. Yoon’s explanation of super geos and the impact they have on regular customers is an impressive contribution to the business literature. But for readers looking for a game plan to follow, authors like [Clayton Christensen](/blog/book-review-innovators-dna/), [April Dunford](/blog/book-review-obviously-awesome/), and [Anthony W. Ulwick](/blog/book-review-jobs-to-be-done-ulwick/) offer far better alternatives.
--- START: blog/book-review-talk-to-your-customers/book-review-talk-to-your-customers.md ---
# **Book Review: Talk to Your F\*\*\*ing Customers by Steli Efti**
Data has become something like a cult in Silicon Valley. While it is touted as the "new oil" for the rest of the world, data is the "new air" for Silicon Valley companies and especially startups fighting to gain traction. Collecting and studying data even becomes an end in itself nowadays, with product teams not knowing what to do with the data they have at hand.
Not everybody agrees with the importance attached to data, though. Steli Efti, founder and CEO of Close, a CRM platform helping salespeople close more deals through more effective calls and emails, thinks data is overrated. He objects to people's obsession with data and proposes an alternative method for startup success in his book *Talk to Your F*\*\*\*ing *Customers.* This alternative method starts and ends with, yes, you guessed it right, talking to your f**\*ing customers.
Efti's thought process seems to have been shaped by two people we are all familiar with: Eric Ries and Paul Graham. Let's take a brief look at the impact these two thought leaders had on Efti and the framework he developed.
## ***The Lean Startup* with a sales touch**
Eric Ries's influential book *The Lean Startup* has shaped the way many founders saw business and managed their startups for years. Inspired by the lean manufacturing philosophy of the Japanese industrialists, the book suggested a new perspective on innovation that prioritized efficiency while cutting waste. Its main premise was "validated learning," which was based on the now-well-known Build-Measure-Learn feedback loop. Ries preached to his readers to act quickly to validate their assumptions and develop a product through continuous, frequent iterations. Basically, what he said was to"*fail fast so that you won't have to invest time and money in dead-end projects.*"
*The Lean Startup* emphasized that the best way to cut costs was to build what customers wanted. It prioritized user experience and, in a sense, paved the way for modern approaches like product-led growth popular among SaaS companies today.
Steli Efti's *Talk to Your F*\*\*\*ing *Customers* is a sales-focused interpretation of Ries's framework. Efti suggests an "Ask-Iterate-Analyze-Adjust" cycle to improve sales performance. The process starts with a cold email, followed by a call during which the founder inquires about what worked or didn't work in the cold email. The same applies to cold calls. Turning to customers is the go-to move in this approach whenever the founder feels stuck.
## **Do things that don't scale… and lots of them**
Efti's insistence on talking to customers gets its inspiration from [Paul Graham's well-known advice to founders.](http://paulgraham.com/ds.html) The author is a firm believer in the benefits of a hands-on approach in leading a startup. That's why he keeps urging founders to get on the phone themselves rather than tell the marketing team to contact customers.
Efti believes that personal contact with customers can tell founders what's wrong with their products in a way that data cannot. You see this piece of advice come up throughout the book multiple times:
+ Wanna know if people have real buying intent? Ask them and see if they do.
+ Are you curious about how your customers would respond to cold calling? Call them and see for yourself.
+ How effective are your cold emails? The recipients can tell you.
+ Are you having difficulty upselling? Ask your customers what else they need.
+ What's your best marketing channel? Call your customers and ask them how they found out about you.
Efti envisages a customer-led sales process. Ask your customers what they want to see from you, learn how they want to be treated, and do as you are told. Do not spend hours analyzing metrics and what they tell you. The quote from Ezra Fishman at the beginning of a section perfectly summarizes what Efti thinks is wrong with data:
"*When we let data drive our marketing, we all too often optimize for things that are easy to measure, not necessarily what matters most.*"
## **No silver bullet**
However, Efti might be going overboard with this insistence on talking to customers at the risk of oversimplifying things and underestimating the value of hard data. Designing a whole funnel on customer feedback may sound like a good idea at first. Still, sometimes customers do not know what they want, may fail to effectively communicate their opinions, or are not aware of better ways of solving a problem. By taking your conversations with customers as gospel, you might be sentencing your startup to mediocrity, which is akin to a long-drawn-out death in the startupland.
The real challenge remains the same whether you are looking at a data set on a computer screen or running a focus group: Converting information into knowledge and using it to solve problems. Asking your customers how likely they are to recommend you to a friend and colleague can give you a nice Net Promoter Score you can hang on your door. But it says nothing about why you got the score you did and what you should do about it. Learning what people think about you will not help you much unless you map those comments to business actions.
## **Conclusion**
Although Steli Efti's advice may not be the silver bullet founders have been hoping for, it still makes a lot of sense for early-stage startups that have little data to analyze. Doing things that don't scale is the right thing to do when you feel lost, not knowing which way to go. Hustling, going the extra mile to listen to the customers, and sacrificing sleep to give better customer support can help you "[cross the chasm,](/blog/book-review-crossing-the-chasm/)" get out of the "[trough of sorrow,](https://twitter.com/davemcclure/status/497537488156512256)" or figure out a solution to "[the cold start problem.](/blog/book-review-cold-start-problem/)"
However, you'd better have a capable data integration infrastructure and a good grasp of data concepts for what comes next because you won't get to the promised land by just chatting with your customers.
--- START: blog/book-review-the-alliance/book-review-the-alliance.md ---
# **Book Review: The Alliance by Reid Hoffman et al.**
The 1950s and 1960s were the golden age of American capitalism. Having emerged victorious from the bloodbath that was World War II with a booming economy, life in the U.S. was transformed by the development of suburbs, middle-class access to TVs and cars, and the beginning of consumerism.
That stability and ever-rising living standards, which at the time looked like they would go on forever, required a new bargain between the employers and the workforce. The employers would invest in their workforce and guarantee them lifetime employment in return for loyalty from the workforce. In this framework, an employee would join a company at a young age, climb up the corporate ladder through promotions, and gracefully graduate in his sixties.
This is no longer the case. Globalization, the rise of the Internet, and the commoditization of software put an end to Industry 2.0 of the mid-twentieth century. Markets today are much more competitive and more easily disrupted than they were sixty years ago, which has rendered long-term, stable employment a distant memory. Nowadays, after two consecutive quarters of poor performance, a CEO starts to feel the heat from the shareholders, which usually ends with a massive layoff. The employees are aware that the old bargain no longer holds. That's why they don't hesitate to resign in droves as they did through the pandemic and hop from one job to another with the hope that things can improve somewhere else.
This month's book, *The Alliance* by Reid Hoffman, Ben Casnocha, and Chris Yeh, tackles the problem of stable employment in the corporate world. The book emphasizes that employers won't invest in employees who can leave at any time, and there will be no innovation without long-term investments. Looking for a way out of this situation, the authors propose a new kind of employer-employee relationship based on "mutual trust, mutual investment, and mutual benefit." *The Alliance* expounds on this viewpoint and makes use of a few key concepts while laying out the framework.
## **"Tour of duty"**
The central concept in the book is the "tour of duty." It is a phrase borrowed from the military and diplomacy, denoting the fixed term a soldier or a diplomat serves in a foreign country. The authors use the phrase to describe a specific, clearly-defined project an employee completes. "Tour of duty" strictly refers to a "transformational tour" in this context, although the authors explain the two other tours (rotational and foundational). A transformational tour is a personalized mission with clear goals negotiated between an employer and an employee. As part of this mission, the employee acquires new skills that will transform her future career while transforming her current company through the successful completion of a major project.
A transformational tour of duty usually does not involve a promotion or a change in the employee's job title. It is an "alliance" between the employer and employee who both realize that lifetime employment is no longer possible in today's gig economy and try to derive lasting value from an existing relationship. At the end of a tour, the parties can extend the current tour, design a completely new one, or give it up altogether.
The tour of duty concept reimagines professional life as a series of productive tours stitched together. There is no long-term commitment in this type of relationship. On the contrary, both sides are aware that it is bound to end at some point, but this does not stop them from engaging in a constructive alliance for mutual benefit.
## **Network intelligence and the alumni network**
Another important concept from the book is "network intelligence," which is the byproduct of an alliance. When the employee leaves for greener pastures, she does that on good terms with her company because both parties benefited from the relationship. There are no grudges, so future cooperation is possible and desirable for both sides. This employee becomes a trusted source of intelligence whenever her previous company turns to her for information about what's going on in her new industry.
With many sources of network intelligence at hand, a company has to institute a formal structure to capture, evaluate, and leverage the information gathered. There needs to be a push mechanism to collect information from past workers, pass it on to decision-makers, and use it to draw insights. This kind of an arrangement could give a company an edge over the competition at no cost.
The authors advise corporate decision-makers to engage with alumni of the company and try to give their networks a somewhat formal character. Such a step may not appeal to the bean counters on the board as it does not offer any short-term, tangible benefits. But the small expenses made to hold occasional dinners for these networks, buy small gifts for the alumni, and send them regular newsletters eventually pay off.
Nurturing the alumni network allows a company to tap into the problem-solving skills of a group of experts who still have some kind of a bond with the company. Feedback from such people is extremely valuable as they know the company, understand what it aims to achieve, and can offer an objective outside opinion. However, the greatest benefit of alumni networks involves the recruitment process. Knowing the values of the company in question and what it seeks in new employees, these people tend to make excellent scouts of talent, referring candidates that will be a great fit.
Taking these points into account, it is safe to say that building and sustaining an alumni network is one of the highest ROI investments a company can make.
## **Conclusion**
> *Amazon to axe 18,000 jobs as it cuts costs* — [BBC News](https://www.bbc.com/news/business-64171008)
> *Alphabet cuts 12,000 jobs after pandemic hiring spree, refocuses on AI* — [Reuters](https://www.reuters.com/business/google-parent-lay-off-12000-workers-memo-2023-01-20/)
> *Microsoft is laying off 10,000 employees* — [CNBC](https://www.cnbc.com/2023/01/18/microsoft-is-laying-off-10000-employees.html)
> *Salesforce to lay off 8,000 workers in latest tech purge* — [LA Times](https://www.latimes.com/business/story/2023-01-04/salesforce-cuts-10-percent-workforce)
Almost 50,000 people working for four tech giants have lost, or are about to lose, their jobs. This figure is the equivalent of the population of a mid-sized town in Europe when you take their families into account. Similar news involving smaller purges barely grabs any attention. It is the order of the day. *C'est la vie!* But it wasn't always like that. Layoffs like these would be unthinkable for Ford, Chrysler, or General Motors in the 1950s. It is a different world we are living in.
*The Alliance* acknowledges the best days of the employer-employee relationship are behind us and searches for the second-best formula for a long-term, productive relationship between employers and employees. It offers no earth-shattering revelations; many companies have been taking their workers on 'tours' for years. However, the book does a great job of distilling those practices into an actionable playbook and highlights what both parties stand to gain from an alliance.
Mission statements, lectures on values, and banging on about how culture matters... These won't amount to much in the absence of an honest and transparent employment strategy that benefits everybody involved. It all starts with accepting that nothing lasts forever and having more modest goals, like building an alliance that will go beyond the duration of employment. *The Alliance* shows you how.
--- START: blog/book-review-traversing-the-traction-gap/book-review-traversing-the-traction-gap.md ---
# **Book Review: Traversing the Traction Gap by Bruce Cleveland**
Founding a startup and leading it to success is an uphill battle. It is akin to stocking up on food and fresh water at your homeport, weighing anchor, and sailing off into the ocean to find that distant land ancient sagas talk about. So many things can go wrong in the journey, and so much is at stake that the rationale behind the decision to set off can be impossible to understand for regular people. Founders are like explorers in that sense. They are special.
The stats confirm the kind of uphill battle founders have to fight. 80 percent of startups fail. Only 5 percent of them produce the projected ROI, and according to a survey conducted by OpenView among 300 software companies, only 0.01 percent of SaaS companies manage to achieve $100 million in Annual Recurring Revenue (ARR). That is one in ten thousand companies.
These stats are from the book that we reviewed this month, [*Traversing the Traction Gap*](https://www.amazon.com/Traversing-Traction-Gap-Bruce-Cleveland/dp/1635766249), by Bruce Cleveland and his fellow partners at the venture capital firm Wildcat Partners. This is not a book on innovation or secrets of successful product management. Being a book written by venture capitalists, *Traversing the Traction Gap* looks into the founder’s journey from the other side of the table. It leaves it up to you how you should develop your product and instead deals with how founders should manage the whole process from the conception stage through the eventual successful exit. The authors even coach you on how you should run a board meeting. How cool is that?
The book’s primary focus is on B2B startups developing enterprise-grade software products. However, it is easy to see that most of the advice given by the authors should also apply to B2C firms. The authors define seven milestones in the startup journey: Ideation, Minimum Viable Category (MVC), Initial Product Release (IPR), Minimum Viable Product (MVP), Minimum Viable Repeatability (MVR), Minimum Viable Traction (MVT), and Scale. This heavy use of three-letter initialisms makes the book a bit confusing at the beginning. Americans love their alphabet soup, for sure.
The phrase “traction gap” refers to the stage that extends from the IPR, when the product is launched, to the MVT, when the business model and the market are finally validated with the company starting to show signs of robust, sustainable growth. This approximately 36-month span defines whether the company will sink or swim. During the traction gap, there is very little data to analyze, very little demand for the product, and too little revenue to help you gauge whether you are on the right path or not. Trying to navigate the traction gap on your own is like sailing into the [Drake Passage](https://en.wikipedia.org/wiki/Drake_Passage) at the southern tip of South America, with little more than sailor’s tales handed down from one generation to another. Cleveland and his friends are volunteering to get you out of that gap.
In addition to these startup lifecycle stages, the authors use a framework of four pillars to evaluate how a startup is doing at each stage. These four pillars consist of product, revenue, team, and systems architecture. Leaning on their vast experience in the VC business, Cleveland and his friends lay out metrics a startup must have achieved in terms of product development, revenue stream, team configuration, and the technology being used at any particular stage like the MVP or MVT. These rough guidelines are to serve as lighthouses dotting the shoreline of a stormy sea. Here are a few examples from the book:
>*In an enterprise SaaS company, for example, ACV usually needs to be north of $75K to produce enough margin to fund a direct sales team.*
>*As we’ve discussed, to be on model with the growth rates of the successful startups that came before you, you must roughly triple your customers and your revenue from MVR and reach MVT in about one year.*
>*After MVT, a startup must be prepared to triple, then double year over year for at least the next 3 years on its way toward a liquidity event, either an IPO or an acquisition.*
*Traversing the Traction Gap* doesn’t offer its readers the uber-scientific approach like Anthony W. Ulwick’s [*Jobs to Be Done: Theory to Practice*](/blog/book-review-jobs-to-be-done-ulwick/) does. The former is more of an account of observations, best practices, and rules of thumb founders can leverage—it basically provides founders with a proven template to increase their chances of success.
What sets *Traversing the Traction Gap* apart from other books written for startups is the fact that its authors are successful VC executives. As you read the book, you get to understand how investors think and what they look for when they evaluate whether to invest in a startup. Founders are naturally inclined to focus on the features of their products, and they can miss the bigger picture in the process. But the book reminds them that it will be all for naught if they fail to solve a pain point in a scalable way. If a founder is to attract investment, he should remember that he is selling the investors a financial product first and foremost. There are a lot of technical founders around who could use a reality check like that.
Remember the notorious [Trough of Sorrow](https://twitter.com/paulg/status/1316661104911806465) publicized by the YC founder Paul Graham? *Traversing the Traction Gap* reminds you that you are not all that helpless in dealing with that trough. Some wise people managed to navigate those waters before you—all you need to do is listen to their advice and hope for some favorable tailwinds.
--- START: blog/book-review-zero-to-one/book-review-zero-to-one.md ---
# **Book Review: Zero to One by Peter Thiel**
> *"We are in a deadly race between politics and technology."*—Peter Thiel
There he is, finally. The visionary mentor of the likes of Vitalik Buterin, St. Peter of Silicon Valley, according to [George Gilder.](/blog/book-review-life-after-google/) Or, [in Jonathan Taplin's eyes](/blog/book-review-move-fast-and-break-things/), the Godfather of PayPal Mafia, the villain behind what's wrong about the Big Data economy, who rubbed shoulders with everyone that produced the likes of Youtube, LinkedIn, Yelp, and Palantir. This month's book review features *Zero to One* by Peter Thiel, who is not only a polarizing figure in the tech circles but also a contrarian full of contradictions. We previously saw Thiel through the eyes of other authors. Now, it is time to let the man speak for himself.
[A math prodigy and an elite chess player](http://fortune.com/2014/09/04/peter-thiels-contrarian-strategy/) in his age group at the age of 12, and one of the co-founders of a company that ushered in a new age of entrepreneurship, Thiel is a difficult figure to categorize. Here are of some of the contradictions that combine to make up the enigma that is Peter Thiel:
+ He is the son of immigrant parents from Western Germany but cannot even stand the word "multiculturalism."
+ Thiel demonstrated an open hostility to homosexuality for years, only to later declare his own homosexuality in 2003.
+ He shuns politics, but that did not stop him from donating to Tea Party candidates in elections.
+ Thiel doesn't think highly of the social media economy, which in his eyes cannot compare to the scientific achievements of the past. But he owes a significant part of his wealth to his investments in social media platforms.
What probably best defines Peter Thiel is his stubborn objection to feminism, multiculturalism, political correctness, and anything the liberal left endorses. For Thiel, the selfish pursuit of happiness justifies every action. Politics is an obstacle to the progress of capitalism, but he seems to disregard the role of politics in resource allocation. He probably realizes that avoiding politics does not solve a thing, hence his donations to the Tea Party cause. Maybe he is just one of those people who likes to avoid anything that can challenge his convictions. Thiel looks like someone more interested in playing the conservative-minded contrarian than in genuinely changing our world.
## **A revolutionary committed to fighting evolution**
*Zero to One* stems from a course on startups that Thiel taught at Stanford. The book's title is a clear allusion to creating something anew instead of growing or multiplying something already existing. In Thiel's eyes, there is no feat more significant than achieving a technological breakthrough, that is, making one out of zero. This attitude sums up what Thiel claims to stand for in business.
Peter Thiel's thinking seems to have been shaped by the consequences of the dot-com crash of the early 2000s. The crash eradicated the confidence in grandiose visions of technological progress and instead started an era of incremental modifications made to risk-free ideas that were proven to work. This incrementalism, epitomized by the "lean startup" philosophy and the Japanese-inspired scientific management school that values improvement through continuous process refinement, is the enemy of revolutionary entrepreneurship in Thiel's eyes. He opposes the intellectual struggle scholars have been waging to save innovation from the grasp of luck and instead throws his lot with "the great men" of the tech industry like Elon Musk, Mark Zuckerberg, Steve Jobs, and Bill Gates, who just happen to have the "it" factor.
If there is anything that Peter Thiel detests as much as multiculturalism, it must be competition. He regards competition as an extension of simple one-upmanship: Copying what works and fighting to defend the marginal advantage you gained vis-a-vis your competitors. Thiel argues that the education system is designed to foster this meaningless competition, goading people to chase empty academic credentials instead of nurturing their talent to revolutionize the world. He established his Thiel Fund solely to guide students from academic competition toward more productive areas. That's why he gives scholarships of $100,000 to twenty university dropouts under the age of twenty every year, the rebels who probably remind Thiel of a young math prodigy in the 1990s.
## **An ode to monopoly**
Thiel loves his monopolies. He yearns for the days of scientific breakthroughs that took men to the moon or added decades to the average life span with a single invention like penicillin. He thinks monopolies offer the shortest route to such breakthroughs because nothing other than the promise of monopoly profits can incentivize expensive, ambitious projects. His advice to startup founders is to avoid competition like the plague and find a niche they can dominate from day one.
Being a libertarian, Thiel is not immune to usual libertarian themes. Taxes, regulations, and copyrights are bad. Monopolies are good because…. Yes, the mythical trickle-down economics. Does trickle-down economics really deliver on the promise of creating jobs, or does it benefit a small group of businessmen while the society at large has to feed on the bread crumbs?
However, the author fails to explain why the huge profits tech giants like Microsoft, Apple, Amazon, and Google reaped did not trickle down to fuel revolutionary progress but ended up being spent for political clout and lower corporate tax rates. If tech monopolies were to bring about world-changing breakthroughs, the plan doesn't seem to have worked so far.
## **Looking for greener pastures or just escapism?**
Peter Thiel must have recognized that tech giants being run as per his philosophy have failed to deliver the goods we were promised. He must have realized that the industry he has been involved in and shaped with his money and ideas has taken us to the land of likes, dislikes, and retweets, instead of other galaxies. It must be to escape this reality that Thiel is investing in firms looking to reverse human aging, build [anarchic off-shore communities](https://www.theatlantic.com/technology/archive/2011/11/peter-thiel-stutters-wants-live-forever/335005/), or develop computers that can replicate themselves.
George Packer is probably right in arguing in his [New Yorker piece](https://www.newyorker.com/magazine/2011/11/28/no-death-no-taxes) that Peter Thiel —consciously or subconsciously—knows that this utopia offers very little to the public at large and is unlikely to make our lives better if he somehow got his way. That might also explain why Thiel devotes a substantial part of his book to convincing us that computers will not replace humans but complement them and that anybody opposing the endeavor of developing such sentient computers is a Luddite.
## **What's in it for the founders?**
The book contains very few actionable insights for regular startup founders (unless you think "be like Elon" is good advice). "Avoid competition," "start with a niche you can dominate," and "take sales and distribution seriously as they can help you create a monopoly" are the ones that immediately come to mind. The seven questions he brings together for startup founders are good for a reality check before setting out to start a business. Additionally, his emphasis on the company culture and giving entrepreneurs free reign may resonate well with the startup ethos thriving today. However, Thiel seems to think that anything will sound like a law of nature if you utter it with enough confidence:
+ *"[That's why hiring] consultants doesn't work. Part-time employees don't work. Even working remotely should be avoided…"*
+ *"[N]ever invest in a tech CEO that wears a suit."*
+ *"Don't disrupt... Disruptors are people who look for trouble and find it. Disruptive kids get sent to the principal's office. Disruptive companies often pick fights they can't win."*
For a book written by someone considered a genius, an accomplished entrepreneur, and an acclaimed investor, *Zero to One* imparts surprisingly little wisdom to its readers. Maybe that was the plan all along, as Thiel wanted nobody to learn his secret sauce. Or maybe there wasn't much wisdom, to begin with, other than a utopian political stance of a man who refuses to grow up. Regardless, there are more than a few scholars—the type Thiel despises—who have produced much better guides for entrepreneurs than the *Godfather of the PayPal Mafia*.
--- START: blog/cdata-vs-embedded-peaka/cdata-vs-embedded-peaka.md ---
# **"Why Embedded Peaka Outperforms CData for Embedded Analytics**
Customer expectations have evolved over the years to the point that customers now want their data embedded into the products they use in real-time. But delivering this kind of data experience, one that is complete with connectors, query logic, and UI, is no small feat.
If you’re evaluating solutions like CData and Embedded Peaka, it’s critical to understand what each platform offers and what each one leaves up to your team to build.
Spoiler: Only one gives you everything you need to ship a full embedded data experience.
## **1. CData connects data, Embedded Peaka delivers it**
CData specializes in connectivity infrastructure. Their solution helps teams move data from external sources into local systems or data warehouses. That’s useful for backend analytics, but it falls short of creating the immersive customer-facing analytics experience SaaS platforms seek.
Embedded Peaka is a full-stack embedded data delivery platform. It combines connector infrastructure with **fully customizable embeddable UI components** and **white-labeling** capability so SaaS teams can deliver in-product analytics seamlessly.
| Feature | Embedded Peaka | CData |
| :--------------------- | :------------------------------------- | :------------------------------------ |
| **Deployment Mode** | ✅ Purpose-built for embedding | ❌ Drivers for internal use |
| **UI Components** | ✅ Dialogs, query editor, autocomplete | ❌ None |
| **Branding & Theming** | ✅ Full white-labeling | ❌ None |
### **What this means for you**
If your goal is to deliver analytics inside your product, not just connect data, Embedded Peaka is the platform that does it all.
## **2. Query-ready, without replication headaches**
CData’s model relies on pulling data into your environment, whether that’s a database, local system, or third-party warehouse. This process involves data replication and movement, introducing **latency, data duplication, and governance challenges**.
Peaka enables live **querying without data replication**. And when performance demands it, Peaka adds Iceberg-compatible smart caching, optimizing speed while minimizing API calls.
| Feature | Embedded Peaka | CData |
| :----------------------- | :--------------------------------------------------- | :--------------------------------- |
| **Data Access Model** | ✅ Live querying (no replication) | ❌ Data moved into local systems |
| **Query Engine** | ✅ Built-in (Trino-based) | ❌ No query engine |
| **Caching & Rate Limit Handling** | ✅ Rate limit-aware caching built-in | ❌ No caching or retry logic |
### **What this means for you**
For SaaS products needing real-time dashboards, campaign performance views, or AI-powered copilots, Peaka delivers governed access without the overhead.
## **3. Built-in UI and governance features = Faster time-to-market**
With CData, your dev team is on the hook for building an OAuth logic, multi-tenant isolation, and maintenance and updates over the life of the connectors.
Peaka handles all of this out of the box:
+ Hosted or BYO OAuth with tenant awareness
+ Role-, column-, and row-level access control
+ Embeddable UI components for queries and connectors
+ Full audit logging and data lineage
| Feature | Embedded Peaka | CData |
| :----------------------- | :--------------------------------------- | :--------------------------------------------- |
| **OAuth** | ✅ Hosted, tenant-aware | ❌ Manual setup per tenant |
| **Multitenant Support** | ✅ Native project/catalog isolation| ❌ To be built by the user |
| **Connector Maintenance** | ✅ Peaka-managed | ❌ To be handled by the user |
### **What this means for you**
For product managers, this means fewer bottlenecks, fewer edge cases, and an accelerated product roadmap.
## **4. Developer-friendly SDKs and APIs**
CData’s conventional data integration approach leverages drivers and legacy integration points to unify data, which translates into significant engineering overhead for SaaS companies looking to stay nimble.
Embedded Peaka, on the other hand, gives your engineers the tools to plug into any workflow or architecture:
+ Connectors for 300+ SaaS tools (Stripe, HubSpot, Zendesk, etc.)
+ Modern SDKs for JavaScript, Python, and Java
+ Access via SQL, REST APIs, or drivers
+ Flexible deployment options (as a headless backend or UI+backend packaged together)
### **What this means for you**
Embedded Peaka empowers you to build scalable embedded analytics solutions without overstretching your engineering resources.
## **Key takeaways**
+ **CData provides data connectivity only**. It does not include a query engine, UI components, or access controls for embedded analytics.
+ **Embedded Peaka is an all-in-one platform**. It includes connectors, a SQL query engine, UI modules, multitenant governance, and smart caching.
+ **Peaka enables live data access**. It eliminates the need for data replication or a separate warehouse.
+ **SaaS teams can launch faster with Peaka**. It removes the need to build infrastructure, reducing development time and effort.
## **Final verdict: Peaka replaces the stack that CData requires you to build**
While CData helps you connect to data, Peaka helps you deliver value from that data inside your product, in a secure and scalable way.
**CData gives you drivers. Peaka gives you dashboards.**
If your roadmap includes in-product analytics, real-time customer insights, or embedded AI copilots powered by user data, Peaka provides everything you need in one embeddable platform.
Explore [Embedded Peaka](/embedded-peaka/) or [book a demo](https://calendly.com/peaka/demo) to see how we can help you launch faster.
Dive into our comparison series to understand how Embedded Peaka fares against other popular platforms in the market:
+ [Embedded Peaka vs. Airbyte Embedded](/blog/airbyte-embedded-vs-embedded-peaka)
+ [Embedded Peaka vs. Merge.dev](/blog/merge-vs-embedded-peaka)
+ [Embedded Peaka vs. Hevo Data](/blog/hevo-vs-peaka-comparison/)
+ [Embedded Peaka vs. Polytomic](/blog/polytomic-vs-embedded-peaka)
--- START: blog/chatgpt-ai-evolution/chatgpt-ai-evolution.md ---
# **ChatGPT: An Evolution Rather than a Revolution**
Humans are mesmerized every time they see animals or robots showing human-like abilities. That's why parrots have been a popular pet for centuries, and videos of [gorillas observing caterpillars](https://twitter.com/Rainmaker1973/status/1566047560841805825) or [dancing Boston Dynamics robots](https://www.youtube.com/watch?v=BFK9lkez32E) still garner interest years after their internet debut. Open AI's ChatGPT, an AI-powered chatbot, was the most recent example of this phenomenon, taking the internet by storm in December 2022. People rushed to find out what it was all about, and 1 million people had used it within the first week of its launch.
We previously talked about [AI-powered coding assistants](/blog/ai-pair-programmers-future-copilots-nocode/) like Github Copilot and Open AI Codex on our blog. However, neither of those two predecessors generated the buzz ChatGPT did. This might have something to do with how [Open AI trained](https://openai.com/blog/chatgpt/) its latest chatbot. While developing ChatGPT, AI trainers ranked the answers given by the language model, providing the AI with a benchmark to train on and fine-tune its answers. As a result, the ChatGPT's reactions turned out to be more human-like. The chatbot can get into lengthy arguments with users, deflect questions that can get it in trouble, and backpedal when it is wrong. Reactions like these make the experience more believable and all the more awe-inspiring for people who give it a try.
However, although ChatGPT seems to have nailed the style, its content needs to improve significantly. The good news is that ChatGPT appears to be a marked improvement over its predecessors when it comes to bias and discrimination in the texts generated. While Copilot and Codex were frequently criticized for insensitive remarks, ChatGPT does a much better job in this regard, which is a testament to Open AI's meticulous moderation efforts to avoid scandal.
## **Not the search tool we all hoped for**
The real surprise here is the failure of ChatGPT to reliably retrieve factual information, something one would think would be one of the strong suits of such a tool. But it turns out context matters more than we give it credit for, and ChatGTP is not as good at reasoning as it is at [pattern recognition](https://clivethompson.medium.com/on-bullshit-and-ai-generated-prose-611a0f899c5). Failure to retrieve information spelled doom for Galactica, too. Meta's attempt at creating an AI-powered chatbot, Galactica, was launched with the express purpose of finding facts and information, but it was [pulled out of service](https://www.msn.com/en-us/news/technology/meta-ai-bot-contributed-to-fake-research-and-nonsense-before-being-pulled-offline/ar-AA14qKEZ) after just two days of operations as it provided its users with wrong information. Similarly, ChatGPT tends to make up facts whenever it feels like it, and it may be challenging to determine how much of what it says is pure fabrication. The fact that it lets you down when you want precise, factual information is what will keep ChatGPT from replacing Google as the go-to search engine unless Open AI does something about it.
For now, ChatGPT looks like a social media trend that we go through every few months. However, the AI power that underpins this tool can have dramatic effects on different aspects of our lives once it gets more polished. Here are three possible implications of ChatGPT that is worth keeping an eye on:
## **Content writing**
One of the first areas of implementation for ChatGPT will be content writing. AI-powered apps have been helping creative people produce content for some time. SEO-oriented texts lend themselves particularly well to this type of arrangement. Ranking high on a Google search becomes the priority over content quality, and AI can do a great job of generating texts that tick all the boxes for SEO success. If content quality is not a concern, ChatGPT will churn out as much content as you like at an incredible rate and saturate certain communication channels.
[Cassie Kozyrkov](https://www.linkedin.com/in/kozyrkov/), Chief Data Scientist at Google, demonstrated ChatGPT's writing skills [in a blog post](https://medium.com/@kozyrkov/introducing-chatgpt-aa824ad89623). While reading her piece on Open AI's latest tool, you find out halfway through that what you read up to that point was written by ChatGPT and, thus, not factually correct. The style was a bit cheesy compared to Cassie's usual writing, but the extent to which ChatGPT can mimic a human writer is quite scary.
## **Academic essays**
Essays have been part and parcel of scholarly work for centuries. Scientists wrote essays to expound their theories or refute existing ones. Scientific essays not only helped communicate knowledge but also built the scientific community as we knew it. It seems this is about to change as ChatGPT enters the picture.
Texts generated by ChatGPT will not automatically replace scientific essays as they include glaring factual errors that are easy to detect. But with a little bit of improvement, this tool can soon be expected to write essays for college students, rendering these assignments useless as a way of performance assessment. Then, it will be just a matter of time before ChatGPT starts writing master's and Ph.D. theses and articles. Considering the central role of academic writing in college education and scholarly work, it looks like how we define academic competence will need a thorough revision soon.
## **Big Data**
The average person is producing multiple orders of magnitude more data than his parents were doing a few decades ago. We use a plethora of electronic devices every day that generate data in different formats and employ software specifically designed to create, aggregate, and organize data. Most of this data is unstructured: Audio files, video footage, photos, etc.
However, unstructured data does not readily lend itself to use unless you are a data scientist. Converting it to structured data and presenting it in a tabular form would make it easier for people without a data science degree to search and work on unstructured data. It turns out ChatGPT can help with that: Maximilian Evans from Climate AI has [demonstrated](https://www.linkedin.com/feed/update/urn:li:activity:7007029782597009409/) how ChatGTP can convert field notes from a farm into a CSV table upon being given a simple prompt. In another example, it can help [analyze a given text](https://twitter.com/jwblackwell/status/1599700695833538562), extract relevant information, and present it as JSON.
## **Conclusion**
ChatGPT is an impressive tool for demonstrating the current capabilities of AI and giving us a hint of its future potential. However, it is not the radical AI breakthrough that people have been looking forward to for some time. It is not dependable and polished enough to produce end products yet. But it still is a step up from tools like Copilot and Codex in terms of taking some burden off people and increasing efficiency. The hope is that ethical concerns will be front and center while using tools like ChatGPT, and they will be employed with an eye to taking humanity forward.
--- START: blog/choosing-a-no-code-platform/choosing-a-no-code-platform.md ---
# **3 Points to Keep in Mind While Choosing a No-code Platform**
You have been reading about no-code technology, educating yourself on what you can do with no-code tools. You have come to the realization that this is the way to go for your startup, local business or career, and decided to put a no-code platform at the heart of your work life. Of all the platforms available, which one should that be? Here are a few points to remember when you finally go out to choose the no-code platform for your business.
## **Specify the features you need to prioritize**
No-code platforms are highly capable tools and this renders them suitable for different use cases. However, choosing one for your particular scenario can be difficult as it involves striking a delicate balance between ease of use, on the one hand, and capabilities, on the other. The ideal no-code platform should not only suit your current skill level, but also be capable enough to satisfy your present and future needs. It is no easy task to find one that checks both boxes. Focusing on the most relevant features for your needs could be a good first step towards making the right choice, though.
If you want to design a website, responsive design capability has to be a priority for you because your website should feel the same whether it is on desktop, tablet or mobile. Drag-and-drop interface, which makes the design process easier and less stressful, is another feature you should seek.
If it is an application that you are willing to build, things get a little bit more complicated. Time and budget constraints usually rule out developing [native apps](https://ionic.io/resources/articles/what-is-hybrid-app-development) for both iOS and Android—that’s probably one of the reasons you are interested in low-code/no-code platforms and building web apps in the first place. The audience for your web apps and the technical skills you possess to a large extent come to determine which no-code platform you should choose—and also what you can offer your audience. Provided that you have the time and effort to explore the features of a no-code platform and train yourself, the wise choice here would be to go with a more capable tool even if that means sacrificing a little bit of UI practicality.
## **Long-term needs over short-term gains**
Looks seem to matter more than substance in most aspects of our daily lives—at least at the beginning. It is the brash designs that make the headlines every time a new model is launched at a car show or a new line of clothing or furniture is introduced. But in the long-run, it is the reliable Toyotas, affordable GAP or sensible IKEA products that survive because they get the job done. Every time.
The same applies to no-code platforms where fancy UI or ease of use can be tempting because we all want quick results. However, it is better to think ahead and invest in what will serve your future needs even if this requires a bit of a steeper learning curve. Quickly validating your idea and producing an MVP right away can be satisfying, but this usually comes at the price of future problems. The higher the level of abstraction, the easier it becomes to use a platform although this also takes away from its flexibility. Just as your business is taking off, you might discover that your no-code platform doesn’t scale in sync and be forced to shift to another which will fit your use case better. It is important to pick a no-code platform that hits the balance between abstraction and adaptability.
## **The intangibles matter**
Parameters that the user can experience dominate the decision making process during app development. Speed and usability naturally take precedence but the not-so-sexy topics like hosting, maintenance and security are just as important for your long-term success. A no-code platform taking care of the hosting will save you from looking for third party solutions or maintaining your own server. The uptime is another critical parameter you should keep an eye on—your efforts will go to waste if your app is down frequently and the resultant revenue loss can be crippling.
The margin for error shrinks when you venture beyond the MVP stage. You can suddenly find out that your no-code platform, which was once a joy to use, comes up short on different tasks. That’s why investing in premium no-code platforms like Webflow, Integromat or Peaka is the safe option—these tools have the capabilities to take you all the way. Your business doesn’t deserve anything less as it should be built on sure footing.
Trying to choose a no-code platform from among the multitude of options available in the market can be a daunting task for the uninitiated. You can soon find yourself looking at feature sheets or comparison tables, trying to decipher acronyms you haven’t seen before. In addition to the three key points we listed above, a comprehensive guide prepared by [UserGuiding](https://userguiding.com/blog/no-code-tools/#ftoc-heading-2) comes in handy here. The guide categorizes no-code platforms according to their purpose and capabilities and lays out the respective pricing plans of each option. Make sure that you check it out before making the final decision.
--- START: blog/choosing-hr-software-startup/choosing-hr-software-startup.md ---
# **7 Tips for Choosing the Best HR Software for Your Startup**
Your day starts early as a co-founder. You kick the day off by spending an hour or so on the speech you will give at the tech summit in a few days. During your commute to work, you will be listening to the recording of the latest podcast you attended. Just as you are getting midway through the product meeting, you receive a text message from one of the best developer prospects you spotted, asking you whether he should come back later for the interview, the one that was scheduled for that morning and you completely forgot about. Your latest hire, the content writer, looks completely lost during the meeting as nobody bothered to help her with her onboarding, but you are too pressed to think about that. After the lunch, you will be joining a few other founders for a webinar, but first, you should decide what to do about the leave requests your only two designers filed at the same time. It would be nice, you think to yourself, if you had a Human Resources department at your disposal that could rid you of all this hassle.
A startup may not afford to establish a proper HR department for a long while. However, it also won’t be going too far if the co-founders spend their time worrying about the chores of HR instead of the more strategic aspects of business. A good HR software can address all the HR-related needs of a startup, but with the availability of tens of different platforms, the selection process itself can prove to be overwhelming. Cloud-based, on-premise, Human Resource Information System, Human Capital Management Software, Human Resource Management System, Applicant Tracking System, Succession Management System so on and so forth. There are plenty of options, which is never a bad thing. However, it just makes it harder to make the right choice. Here are a few points that could help you out as you try to choose the right HR software for your startup:
## **1 - Define your job-to-be-done**
Modern HR software is a platform comprising different programs or modules. Most of these platforms are designed for enterprises or SMBs, which employ hundreds, if not thousands of people. Therefore, paying for such a system is probably too big of an investment for a startup to justify.
Goals of a startup wildly differ from goals of more established companies. In order to compete with the Goliaths of the industry, startups need to find talented people and be able to hold on to them for the long term. Lacking the funds to hire the stars of the industry, startups should focus on finding hidden gems and developing them. Choosing the right candidates during the recruitment process and providing them with a stress-free, welcoming onboarding experience are known to improve the loyalty of an employee. An HR software with a good Applicant Tracking and Onboarding module might go a long way towards serving this job-to-be-done.
## **2 - Look for ease of use**
Established firms are like well-oiled machines: They have detailed business plans, well-defined roles and processes, and tried-and-tested methods. Startups work in more chaotic ways. In a startup, everybody is pressed for time: There is too much work and not enough manpower. While established companies have dedicated HR departments that can spend weeks trying to master an HR software, startups cannot afford going through a steep learning process. Focusing on user-friendly packages that can be quickly deployed and integrated to other services without much fuss should be the way to go for startups.
## **3 - Make automation a top priority**
One of the reasons you are looking for an HR software in the first place is to make life easier for you and your employees. HR is rife with paper-based manual work at every stage, from the job postings to leave management to offboarding. The more manual work you can offload to an HR software, the more time you and your employees will have in your hands to create value. Make sure that the HR software you choose comes with robust workflows and integrations that will unlock efficiencies for you.
## **4 - Make your employees part of the process**
It is always a good idea to listen to your employees and let their input inform your search for HR software. Where do they think the current system is lacking? What are some of the best practices they experienced in their previous jobs? Is there a particular field like onboarding or leave management that they would like to see prioritized? Comments from your employees can change the way you look at HR. It can help you reimagine the experience you want to provide instead of just automating your existing HR processes.
Employee participation should not be limited to the searching phase, though. Once you settle on an option, having your employees personally type in their personal information, letting them review data and customize their training program will cultivate a culture of transparency and earn the trust of your employees, making them feel empowered.
## **5 - Customizability is king**
Business life is full of uncertainty and this is all the more so for startups. As a startup founder, you don’t want to get locked into a choice you made at the very beginning that you won’t be able to back out of in the future. This also applies to the HR software you will choose. No matter what your initial requirements are, you want to have the flexibility to reconfigure your system as your company scales up. That’s why it would be wise to choose an extendable platform to which you can add new capabilities with modules or add-ons.
## **6 - Go for a system with mobile option**
A founder’s life can get really hectic at times. Long trips, meetings with investors and attending all kinds of activities you will be involved in for networking purposes mean that you will spend very little time at your desk. You want to keep tabs on the HR side of things all the time, though. Being able to run your HR software on mobile gives you that chance. Signing off on leave requests and scheduling interviews on mobile and being in control of your payroll from afar could prove invaluable when you have to be out of town but your startup should keep working as usual.
## **7 - Seek capable, dedicated customer support**
Every platform runs into hiccups from time to time. In case of a platform like an HR Management System, however, those hiccups need to be sorted out really quickly because they might have serious legal ramifications. Picking a platform that prides itself on providing excellent customer support can come in handy in those situations. Free and unlimited customer support can ensure that your HR software will keep delivering value for years to come.
Founding and growing a business is one of the most challenging things one can choose to do. Thankfully, founders have now access to a host of cloud-based platforms to help them handle supplementary business functions outside their core line of work. As you try to decide on which HR software system to buy, just set your priorities straight and everything will fall into place.
--- START: blog/code-quality-no-code/code-quality-no-code.md ---
# **Code Quality No Longer a Concern in the Age of No-code**
It is never a good time to ask a developer to conduct a code review. He is just too pressed for time: Some tasks are waiting in the backlog, new projects are piling up in the pipeline, there are meetings to attend and deadlines to meet. Just like a Michelin-star chef doesn’t like tidying up the kitchen while he is focused on preparing his signature dish, asking a developer to review code, produce documentation or focus on limiting technical debt while he is struggling to meet deadlines can throw him off. But a Michelin-star chef can’t postpone tidying up forever if he is to keep those stars. Similarly, developers have to maintain a long-term vision that prioritizes code quality if they want their software products to last a long time.
The first thing we expect from high-quality code is for it to [work and do what it was intended for](https://medium.com/free-code-camp/why-i-changed-the-way-i-think-about-code-quality-88c5d8d57e68). It should also be bug-free, but these are hardly enough. Bug-free code that works while creating a lot of technical debt is not desirable at all because poor code quality and the resulting inefficiency will eventually catch up with you down the road. Thankfully, there are some parameters that can guide us when we need to gauge the quality of some piece of code.
First of all, high-quality code should be reliable as measured by the number of failures occurring over a certain period of operation. Reliable code, in turn, makes the software more predictable and robust.
High-quality code is readable. It comes with correct [indentation, comments where necessary and documentation](https://medium.com/the-liberators/teams-and-a-shared-understanding-of-code-quality-the-11-rules-of-quality-f4ab7e07304) to help reviewers, other developers and the end users. [Refactoring](https://www.codegrip.tech/productivity/how-to-format-code-for-maximum-code-readability/) legacy code might come in handy here: It not only makes code shorter and more readable but also renders it easier to manage, leaving less room for errors and security risks.
High-quality code is reusable. It is modular and lends itself to being used again.
High-quality code is easy to maintain. It requires less rework. As a result, updating or building upon it will be easy, which will drive down the cost of ownership of the particular software.
There are [well-established methods](https://betterprogramming.pub/things-that-you-can-do-to-improve-code-quality-c746c30e7521) to improve code quality: Sticking to a well-defined coding convention, having the code reviewed by at least two people, employing incremental but continuous integrations to detect problems right away, and using metrics to determine the frequency of defects and system complexity are some of them.
Another way to guarantee high-quality code is to take advantage of no-code technology.
No-code platforms are basically built on the principle of a trade-off between flexibility and system complexity: You are basically trading some of the flexibility afforded by coding for lower levels of complexity thanks to the higher level of abstraction involved. The byproducts of this trade-off are manageable [technical debt](/blog/no-code-pays-down-tech-debt/) and significantly less maintenance headache.
No-code platforms score high points on all the parameters cited above. These tools are developed with certain use cases and user personas in mind. Therefore, provided that you chose the right platform for your needs, you will find out that it is streamlined for the circumstances you will be operating in. The platform will take your [high-level directions](https://www.forbes.com/sites/nishatalagala/2021/08/21/will-ai-make-coding-obsolete/?sh=6fc60cf81049) and choose the right kind of reusable blocks to form the code. Having been tested rigorously to industry standards, no-code platforms offer you the luxury of working with chunks of code you can move around with simple drag-and-drop actions, without the hassle of testing, reviewing and maintaining code.
--- START: blog/consultants-servicetitan-kpi-dashboards/consultants-servicetitan-kpi-dashboards.md ---
# **How to Deliver KPI Dashboards for Your ServiceTitan Clients**
If you’re a consultant or tech advisor working with ServiceTitan operators, you’ve probably spent more hours than you’d like to admit wrangling spreadsheets or building dashboards from scratch.
Every new client means another round of CSV exports, data cleanup, and dashboard configuration, time that could be spent coaching or driving strategic improvements. What if you could cut that setup time by 90 percent and get straight to delivering insights?
Let’s walk through how you can speed up KPI dashboard delivery without writing custom scripts or hiring a developer.
## **Why dashboard delivery slows you down**
Your time as a ServiceTitan consultant is precious; it’s too precious to spend days building and delivering custom dashboards to clients. There are numerous areas where you can make a significant difference and add value to your clients’ operations. But if you’re manually exporting reports or relying on fragmented workflows, dashboard creation becomes a bottleneck.
+ **Each client is a custom job:** No two home service businesses track performance the same way. This change from one client to another requires constant adjustment and slows you down.
+ **Limited tools:** Many home service companies rely on spreadsheets as a data source, which are useful but not scalable for reporting purposes. Unifying data from spreadsheets and sending it to BI tools can be a real challenge for consultants lacking the proper tool for the job.
+ **Drain on resources:** Building dashboards diverts scarce engineering resources from other productive and possibly more urgent tasks. Your consulting business should focus on unlocking efficiencies for clients, rather than creating dashboards.
The result? Slower onboarding, limited insight in early engagements, and less time for high-impact coaching.
## **What ServiceTitan consultants actually need**
To move faster and serve more clients, consulting firms need a better approach that’s scalable, flexible, and easy to manage across engagements.
Here’s what that looks like:
+ Live data from ServiceTitan flowing into your reporting tools without manual exports.
+ Support for popular BI platforms like Power BI, Looker Studio, and Metabase.
+ Multi-client management from a single workspace.
+ Repeatable workflows that you can adapt and reuse across clients.
And crucially, you need all this without adding developer overhead or building a custom data pipeline.
## **How Peaka speeds up dashboard delivery**
Peaka isn’t a dashboard builder. It’s the layer that gets your clients’ data from ServiceTitan, joins it with data from other tools like [QuickBooks, Xero Accounting, or Sage Intacct](/blog/integrate-servicetitan-with-quickbooks-xero-sage/), and pushes this consolidated data into the tools you already use to build dashboards.
Here’s how it works:
+ **Direct integrations with ServiceTitan:** As an [official ServiceTitan partner](https://marketplace.servicetitan.com/partner/peaka), Peaka readily integrates with this platform, enabling you to skip manual exports and automatically sync your clients’ data to your BI environment.
+ **Multi-client support:** Peaka allows you to manage multiple ServiceTitan accounts from a single platform, which is a lifesaver for consultants juggling 5, 10, or even 50 clients.
+ **BI tool flexibility:** Thanks to Peaka’s ready-made connectors for popular data visualization tools such as [Power BI](/blog/servicetitan-power-bi-integration/), [Looker Studio](/blog/how-to-connect-servicetitan-to-looker-studio/), [Metabase](/blog/how-to-connect-servicetitan-to-metabase/), or Tableau, you can push data to whichever platform your clients prefer to see their KPIs.
+ **No-code setup:** Peaka removes the need for engineering teams, letting you configure data flows and transformations yourself.
With Peaka, you’re not just delivering data faster; you're also building a repeatable system that saves hours per client.
## **Real-world scenario: Streamline your onboarding with instant BI dashboards**
Let’s say you’re onboarding five new ServiceTitan clients this month. Each one wants a monthly KPI dashboard covering job profitability, technician performance, and booking trends.
Without Peaka, consultancy firms face an uphill battle to onboard clients:
+ 2–3 days per client to collect, clean, and structure the data
+ Logging in and out of different tools for hours to repeat the same steps
+ Increased risk of errors or versioning issues with spreadsheets
+ Automated manual exports to keep the dashboards updated
The result is a messy onboarding that fails to deliver the “aha!” moment to wow clients. Peaka revolutionizes this entire process, simplifying how you unify data scattered across different platforms, visualize, and update it:
+ Connect each client’s ServiceTitan account once
+ Retrieve client’s data from QuickBooks, Xero Accounting, Sage Intacct, or Google Sheets
+ Push cleaned, structured data into Power BI, Looker Studio, or Metabase
+ Generate real-time reports and dashboards without manual exports or copying and pasting
Total time saved? Days per engagement. Multiply that across your client base, and the ROI is immediate.
## **Faster dashboards, happier clients, increased revenue**
When you deliver dashboards faster, the benefits go far beyond time savings.
+ **Accelerated onboarding:** Show value in week one, not week four, which is a big boost to your retention figures.
+ **Stand out from competitors:** Make live dashboards a staple offering in your consulting package.
+ **Unlock new revenue:** Consider bundling reporting as a premium add-on or monthly subscription.
+ **Improve retention:** Use live KPIs in your recurring coaching sessions to demonstrate impact and ROI.
## **Key takeaways**
+ For ServiceTitan consultants, delivering dashboards can be a significant hurdle when onboarding new clients weekly.
+ Despite its challenges, fast dashboard delivery can be a source of competitive edge as it allows ServiceTitan consultants to reduce time-to-value, make a strong first impression, and improve retention.
+ Peaka automates data flow from ServiceTitan into BI tools, eliminating the need for CSV downloads and manual data replication.
+ By using Peaka’s infrastructure for data visualization, ServiceTitan consultants can channel their engineering resources to creating more value for clients.
## **Ready to supercharge your dashboard delivery?**
[Manual data exports](/blog/servicetitan-manual-data-export-costs/) and custom dashboard builds are no longer the price of doing business with ServiceTitan clients. With Peaka, you can unify and deliver the right data to the right BI tools without writing code, hiring engineers, or repeating the same work across clients.
Whether you’re serving 5 clients or 50, Peaka helps you deliver insights faster, scale your services, and reclaim your time.
To get started with instant BI dashboards for your clients, [sign up to Peaka](https://peaka.studio/signup) for free today.
[Book a quick demo](https://calendly.com/peaka/demo) and see how you can accelerate dashboard delivery for your ServiceTitan clients with Peaka.
--- START: blog/contractors-how-to-replace-spreadsheets/contractors-how-to-replace-spreadsheets.md ---
# **The Contractor’s Dilemma: How to Replace Spreadsheets**
If you run a home-service business with 50 to 500 employees, your data challenges have probably evolved faster than your tools. What once worked—a few spreadsheets, some manual exports from ServiceTitan or Sage Intacct, and a dashboard built by a helpful consultant—now feels painfully slow and brittle.
You’re managing multiple branches, juggling different systems, and tracking technician performance, job profitability, and backlog across locations. Every team wants real-time visibility, but your data lives in too many places to keep up.
The problem? You’ve outgrown spreadsheets, but Snowflake isn’t made for you either.
## **Key takeaways**
+ Large contractors are stuck in a data gap: Their operations are too complex for spreadsheets, but too lean for enterprise-grade data stacks like Snowflake or Databricks.
+ Manual reporting doesn’t scale. As data grows across multiple ServiceTitan accounts and accounting systems, spreadsheet workflows hinder decision-making and create inconsistencies.
+ Building a traditional data stack isn’t practical. It requires high costs, technical expertise, and ongoing maintenance that most home-service businesses can’t afford.
+ Peaka offers a middle ground with data virtualization and ready-made connectors. Zero-ETL, zero-copy integrations connect ServiceTitan, accounting, and BI tools in real time, without the need for engineers or data warehouses.
## **The two extremes of the data spectrum**
### **The spreadsheet trap**
Spreadsheets and manual CSV exports were great when you had one office and a handful of techs. But as your operations scaled, the limits showed quickly:
+ Each report is a minefield of human error and security issues as it requires you to copy and paste data between files.
+ The manual cleanup and validation required is a time drain, which renders data outdated by the time it’s ready. And then there is the issue of metric definitions
+ Metrics are defined differently across different spreadsheets. No two “completed job” columns mean the same.
These errors compound across locations, costing hours of staff time and eroding trust in your reports.
### **The modern data stack mirage**
At the other end of the spectrum lies the “modern data stack” consisting of tools like Snowflake, Databricks, dbt, and Airbyte that promise real-time integration, governance, and scalability.
They work beautifully if you’re an enterprise company with a full-time data team.
For most home-service contractors, this approach is overkill. The costs are daunting:
+ Cloud compute and storage fees can easily cost thousands of dollars per month.
+ Maintaining ETL pipelines, schemas, and permissions introduces new complexity, which can only be handled by a data team.
+ Data engineers and consultants command six-figure annual salaries.
For businesses whose margins depend on operational efficiency, this kind of overhead simply doesn’t make sense.
## **Why hiring a data team isn’t the answer**
When the reporting workload becomes unbearable, many contractors consider hiring a data engineer or outsourcing to a BI consultant, thinking this will solve their data integration and reporting problems without having to invest in a data stack.
But even one full-time data engineer costs upward of $120,000 per year. It’s difficult to justify such an investment for a home service business when all these qualified people will be asked to do is build and maintain ETL pipelines, not generate insights.
An alternative is to call upon consultants. However, this often leads to [automations managed by Zapier or Tray.ai](/blog/servicetitan-integrations-trayai-zapier/) that fail to cover different scenarios. If you opt for dashboards personally delivered by consultants, then you have to rely on static data that quickly goes stale when your data model changes.
The reality is simple: The home-service industry doesn’t need to mimic Silicon Valley’s data architecture. It needs something lighter, smarter, and built for operational agility—not engineering complexity.
## **The hidden costs of living between two worlds**
Many fast-growing contractors end up stuck in the middle as they are too big for manual reporting but too lean for a data warehouse. The cost of being stuck in this no man’s land isn’t just financial; it’s operational.
+ **Delayed insights:** Revenue per technician or [job-cost reports](/blog/track-job-costs-servicetitan/) arrive days late.
+ **Fragmented decision-making:** Finance, operations, and branch managers each rely on their own spreadsheets.
+ **Wasted expertise:** Skilled managers spend hours cleaning data instead of analyzing it.
+ **Reporting chaos:** Different definitions and KPIs make cross-branch comparison impossible.
Without a unified, automated data layer, your “data strategy” becomes a patchwork of exports, Google Sheets, and one-off dashboards, none of which can keep up with how your business scales.
## **The middle path: Data virtualization, zero-ETL infra, zero-copy integrations**
That’s where the next generation of data infrastructure comes into play. Instead of copying and moving data to a physical data warehouse, you can use a virtual layer that connects to your existing systems, such as ServiceTitan, QuickBooks, Sage Intacct, and others.
This approach, known as [data virtualization](/blog/data-virtualization-no-code/), eliminates ETLs from the data integration process, removing the need for data teams that would be required to maintain brittle data pipelines. Data virtualization achieves the same results as a system built around data warehouses would, but without the astronomical cost and engineering overhead needed.
Peaka leverages this technique to turn your data scattered across multiple sources into virtual tables. It then provides a virtual data layer that defines your metrics (e.g., “revenue per technician,” “gross margin per job”) once and applies them everywhere. The result is [real-time KPI dashboards](/blog/servicetitan-dashboards-no-data-team/) that don’t depend on engineers or ETL scripts.
With Peaka, you can
+ Query data where it lives, instead of relying on [manual CSV exports](/blog/servicetitan-manual-data-export-costs/) to unify it in a spreadsheet.
+ Create consistent KPIs across ServiceTitan and accounting systems.
+ Feed unified data directly into BI tools like [Power BI](/blog/servicetitan-power-bi-integration/) or [Looker Studio](/blog/how-to-connect-servicetitan-to-looker-studio/).
Contractors no longer have to invest in Snowflake or Databricks to integrate and make sense of its data integrate and make sense of their data, as Peaka gives them all the data stack they will ever need.
## **The future data infrastructure that contractors need**
The next generation of home-service leaders will win not because they built massive data teams, but because they made data access simple, affordable, and fast.
AI-driven analytics and semantic-layer platforms are removing the need for traditional ETL. Instead of copying and moving data around, you define relationships once and let automation do the rest.
For large contractors, this shift changes everything:
+ Dashboards can be built in hours, not weeks.
+ [Multi-location reporting](/blog/multi-location-servicetitan-reporting/) becomes plug-and-play.
+ Business users can finally own their data workflows without relying on IT people.
The future of reporting in home services isn’t about data warehouses; it’s about connectivity and self-service business analytics for everyone.
## **Conclusion: Rethinking data readiness**
Fast-growing contractors no longer have to choose between chaos and overkill. The middle path is here—one that helps [integrate data from ServiceTitan and finance software](/blog/servicetitan-sage-reporting-gap/) and sends it to BI tools without replication or maintenance overhead.
If you’ve ever felt “too advanced for spreadsheets, too resource-constrained for Snowflake,” it’s time to rethink what data readiness means. You don’t need to rebuild a data stack; you just need to remove the friction between your systems.
Peaka is the middleware that will turn your existing systems into a cohesive reporting infrastructure.
[Sign up to Peaka](https://peaka.studio/signup) for free today.
[Book a demo](https://calendly.com/peaka/demo) to see how Peaka helps top contractors save thousands of dollars in data integration costs every month.
--- START: blog/cultural-resistance-1/cultural-resistance-1.md ---
# **Cultural Resistance to Technology: The Never-ending Saga (1)**
> *“Those who cannot remember the past are condemned to repeat it.”*—George Santayana
New technology is always disruptive. Because [technology has a human component](https://tulip.co/ebooks/digital-culture/), the introduction of new technology changes something at the social, cultural and economic level. It puts some people at a disadvantage and gives some others an upper hand. If people can adjust to the ongoing technological change, the results can turn out to be manageable. If not, new technology will wreak havoc like a wrecking ball.
You can be sure that the invention of wheel caused a ripple effect throughout the societies that started using the wheel for the first time. It made pottery possible and overland transportation easier. The introduction of gunpowder must have raised some eyebrows among the artisans who made the bolts, arrows and bows the armies of that era used—they must have sensed that this black powder was about to put them out of work. Change triggered similar patterns of reactions every time. As the French would say: [*Plus ça change, plus c'est la même chose*](https://www.merriam-webster.com/dictionary/plus%20%C3%A7a%20change%2C%20plus%20c%27est%20la%20m%C3%AAme%20chose).
Fortunately, the destruction that Industrial Revolution caused among the working class in Britain is better documented. Actually, this is the topic of [*The Making of the English Working Class*](https://www.google.com/books/edition/The_Making_of_the_English_Working_Class/wNNzCwAAQBAJ?hl=en&gbpv=1&dq=making+of+the+english+working+class), the monumental work by the British historian E. P. Thompson. In his own words, Thompson’s effort was an attempt “to rescue the poor stockinger, the Luddite cropper, the "obsolete" hand-loom weaver … from the enormous condescension of posterity.” (Thompson, 1963, p.12) These people fell by the wayside as the industrial machinery gained more reception. They were handworkers in the textile and woollen industries who lost their jobs and were left without a livelihood after the introduction of machinery.
These people did not take it lying down, however. They fought back, first, through legal means: They petitioned the parliament and lobbied for a complete ban on industrial machinery. When that failed, they organized in armed groups and started roaming around in Nottinghamshire, Yorkshire and Lancashire, breaking machinery, threatening and attacking industrialists (Thompson, 1963, pp.472-602). They came to be called the Luddites, after a certain Ned Ludd, who was supposedly the first person to break machinery in protest.
The machine-breakers were quite clear about their demands (Thompson, 1963, p.530):
> *We will never lay down Arms [till] The House of Commons passes an Act to put down all Machinery hurtful to Commonality, and repeal that to hang Frame Breakers.*
The Luddite movement started in 1811 and was totally defeated by 1817. The determination machine-breakers showed in protest of a technological breakthrough garnered a lot of attention in the later historiography. But there might be a lesson for us in their motives. Thompson used the term 'moral economy' to account for the way machine-breakers perceived the transformation they were subject to (Thompson, 1963, pp.63, 550, 583). According to this view, the machine-breakers believed that there were social values rooted in a [traditional, paternalistic society](https://understandingsociety.blogspot.com/2008/07/moral-economy-as-historical-social.html) upholding the economic order. These people thought they were party to a social contract, and thus had a right to livelihood. But the new machinery, by driving down prices of products, was putting them out of work and violating their ancient rights. This was the reason that made them take up arms against the royal army. In other words, stockingers, croppers, weavers and the like were the casualties in the battle between a traditional moral economy and free market forces.
The machine-breaker protests and the ensuing mob violence were the symptoms of a crumbling socio-economic order. They were the signs that Industry 1.0 had arrived. [Industry 2.0](https://en.wikipedia.org/wiki/Second_Industrial_Revolution), which came with increasing electrification, expanding railway network and the first assembly lines, and [Industry 3.0](https://en.wikipedia.org/wiki/Digital_Revolution), which relied on computer technologies, all had their winners and losers. Today we are standing at the threshold of another industrial revolution—the term Industry 4.0 was not coined for nothing. This one, too, is coming with all the destructive powers of previous revolutions. Do we have a moral economy in place? Who stands to lose this time around? This discussion deserves another post.
--- START: blog/cultural-resistance-2/cultural-resistance-2.md ---
# **Cultural Resistance to Technology: The Never-ending Saga (2)**
It seems that we are going through the initial phases of another industrial revolution. This time, it is the [software threatening the way traditional companies have operated](https://www.wsj.com/articles/SB10001424053111903480904576512250915629460) for decades. Giant hierarchies are being reorganized to render them more agile and processes are being streamlined, resulting in a reduction in time-to-market. Corporate culture, from top to bottom, is going through a change and this brings about uncertainty.
Despite not being as pronounced as the traditional moral economy of the pre-industrial age, every period has its own version of a moral economy—i.e. a set of values that regulate the way economic actors act. Today’s moral economy does not put a premium on job security—unlike the machine-breakers of the nineteenth century, we recognize that unemployment and having to change careers are part of the game. Nevertheless, certain expectations are to be met to keep modern employees happy. Employees want their voices to be heard—this entails delegation of authority and a certain level autonomy. In addition to material compensation, they are motivated by a chance to [make an impact](https://www.forbes.com/sites/glennllopis/2012/06/04/top-9-things-that-ultimately-motivate-employees-to-achieve/?sh=39aa8dd2257e) and the recognition of their contributions. Other things that motivate the modern workforce include challenging but achievable tasks and opportunity to acquire new skills that will help them remain [relevant](https://www.forbes.com/sites/glennllopis/2012/06/04/top-9-things-that-ultimately-motivate-employees-to-achieve/?sh=39aa8dd2257e) while keeping them at the top of their game.
This is why there is more to digital transformation than just digitizing certain processes. Digital transformation is not only an administrative policy but a cultural phenomenon as well. The human component of technology can easily complicate things: Workers will refuse to use new technology if they [believe](https://tulip.co/ebooks/digital-culture/) that the old ways worked better or that they don’t have enough involvement in a project or that it will cause them to lose their jobs. Lack of buy-in from the workforce can stifle any wholesale transformation effort or worse, even scuttle it altogether.
A case in point where business logic might conflict with values of the workforce is the plethora of metrics being introduced to the work place everyday and how they might be perceived by the employees. Digital transformation produces an immense amount of data and this data is organized into metrics so that change can be measured. These metrics are supposed to increase visibility at work. Visibility makes the value-creation activities more transparent for the decision makers, making it possible for them to understand how employees at each work station perform. However, employees could associate such micromanagement with loss of autonomy and see that kind of data collection as a threat to their jobs.
Involving employees in the planning phase of digital transformation and letting them know what they could expect can disperse the clouds of doubt and build trust within the organization. Employees want to be heard and giving them a say in the way their work is being shaped goes a long way towards making them feel secure and wanted. This gives a company an edge in recruiting and retaining elite talent since material benefits are easily replicable for these people and what makes them jump ship most of the time tend to be factors other than money.
No-code tools provide a solution to this dilemma between organizational productivity and employee autonomy. While, on the one hand, they improve the response time and shorten iteration cycles, on the other hand, they empower the employees to devise tailored solutions to the problems they detected. No-code tools reinforce the values that the modern workforce cares about such as being able to make an impact and staying relevant.
Citizen developers will not be going on a computer-breaking frenzy anytime soon just because they feel their values are violated. But it would be unwise for any company to ignore the needs of its employees when there are no-code platforms that can harness for the common good the creative powers of these people. No-code platforms like [Peaka](/) offer companies with a digital transformation agenda the best of both worlds.
--- START: blog/customer-success-misinterpretation/customer-success-misinterpretation.md ---
# **How Founders Should Approach Customer Support**
## **Introduction**
In product development, prioritizing the end-user’s needs is paramount. Neglecting these can lead to product failure, increased churn, and the inevitable failure of a startup. With customers increasingly becoming the focal point of services they use — thanks to easily accessible pricing information, online review platforms, and social media — companies face greater challenges in persuasion and customer acquisition.
New products are continuously tested and phased out, leading to elevated customer expectations across the board.
## **Customer support or just an Anti-Lean Startup?**
Many founders mistakenly believe that constantly meeting with customers can satisfy these rising expectations. In reality, many customers prefer a functional relationship with the product itself, expecting it to deliver seamlessly without much intervention – product gives, they take, no contact made.
{{ resize_image(path="../static/assets/images/blog-images/kerem/customer-support-1.png", width=759, height=400, op='fit_width', alt="Lean Product Development for a fast growing startup") }}
Often {{ highlight_text(text="founders resort to 'Customer Success' and 'Customer Support' teams to cover products’ inadequacies, intervening between the user and the product to compensate for design flaws.", small_text="Top Highlight") }} This is especially true when the design is non-intuitive, leaving users confused without support.
While sophisticated enterprise software like B2B SaaS inherently caters to complex needs and requires Customer Success (CS) team guidance, a product’s reliance on constant customer support should not be the norm. Ideally, every product should be developed with the motivation of necessitating ZERO customer support.
Though Peaka is engineered for complex data pipelines, we take pride in dedicating months to refine our user interface to its current state – customer favorite by a mile. We continue to dedicate hours to our customers, learning from their use cases and assisting them with report creation, but the majority of our interactions are directly aligned with improving the product for the future.
## **Many startups don’t need large support teams**
Lean interaction is fundamental to understanding user experience, hinged through brief and honest communication towards improving the product. Ideally, customer success meetings should not exceed 15 minutes, conducted by people with deep technical knowledge on the product, and focus exclusively on customer feedback; guiding the startup to enhance product value and minimize support necessity. Support documentation should be succinct and readily accessible, designed to render the product intuitive enough to obviate extensive manuals and meetings.
{{ resize_image(path="../static/assets/images/blog-images/kerem/customer-support-2.png", width=759, height=400, op='fit_width', alt="Flawless UI Design for a B2B Data Startup") }}
Many founders tend to adhere to a proven framework because that's what they were taught in their consulting or IB experiences—follow a generic framework, apply it to all customers, provide minimal value, and don’t solve anything so client returns for more service:
“*[The unicorn in our space] succeeded with their initiative so let’s blindly copy them.*”
This approach is akin to how the majority of founders treat Customer Support teams. As startups scale, many founders tend to hire numerous personnel, who lack a deep technical understanding of the product, to interact with customers on behalf of the startup. Though many startups view Customer Success as a holy grail, companies mostly cannot get a good return on their investment.
I see two issues here that could and should be solved:
1. Since the majority of the CS hires aren’t familiar with the technical aspects of the product, they often fail to provide instant solutions, leading to 30-minute meetings that deliver ZERO value.
2. With remote work becoming more popular for these teams, many spend a significant portion of their day unproductive — believe me, I’ve seen enough proof.
How should we address these issues? If it were for me, I’d reduce the CS team’s headcount by half, replace the team with Support Engineers, and have them focus exclusively on understanding use cases and customer motives.
Some might argue that understanding customer experience and testing new features should be the domain of Product Managers or Design Architects. In my experience, Product and CS teams should operate in tandem. Support Engineers should be responsible for resolving ad hoc problems and interacting with customers to understand their long-term vision/expectations in using the product. These insights should then be passed on to the product team so the PMs can create or iterate on a roadmap that aligns with customer motivations.
Investing in your support team's understanding of the product details – both what it is & is not intended for – will significantly reduce the time spent on understanding what’s working, and often shed light on gaps in sales enablement.
## **Conclusion**
Ultimately, the goal for startups should be to develop products that are so intuitive and well-aligned with the user segment that the need for customer support is significantly diminished. Founders should focus on lean methodologies and follow the *Build–Measure–Learn* principle: Improve the product, ask users how they feel about it, iterate, and repeat.
This approach not only leads to a more seamless and satisfying experience but also sets the foundation for lasting success and innovation in the dynamic world of startups. This commitment to user-centric design and proactive problem-solving is what ultimately distinguishes the most successful and resilient startups from the rest.
--- START: blog/customize-complement-extend-software/customize-complement-extend-software.md ---
# **No-code Helps Customize & Extend Your Software Product**
Salesforce, SAP, ServiceNow… These are the brands that spring to mind when you think of business software. They have become household names after being highly successful businesses year in, year out. Even people somewhat allergic to them end up using them at some point. What makes them so special? What is it that they have and others don't?
## **An API-led revolution**
Before turning his company into one of the biggest brands, Marc Benioff, the founder and CEO of Salesforce, was seeking the secret sauce for success. He visited Steve Jobs in 2003 as he struggled to gain traction at the head of Salesforce. Jobs had a simple [recipe](https://www.zdnet.com/article/benioff-salesforce-was-made-possible-by-steve-jobs-meditation-and-perseverance/) for Benioff:
>"You've got to land a big customer like Avon. You've got to be ten times bigger in 24 months, or you're gone, and you've got to build an application economy."
Of all the advice Jobs gave, it was the "application economy" idea that proved to be the most transformative—a whole ecosystem of different software products capable of working together in harmony when needed. The revolutionary thing about what Benioff did afterward was his positioning of Salesforce as a development platform rather than an end product people would just pay for and use as it was.
Benioff envisioned Salesforce as an API-based development platform. He opened it up to its customers, just like Amazon, SAP, and ServiceNow did with theirs. By doing that, he let customers tinker with the platform until they came up with a configuration that would meet their needs. The result turned out to be a very flexible platform where everybody could find something for themselves.
The reason for creating an API-based ecosystem is to offer the customers the maximum amount of customization possible. The one-size-fits-all solutions no longer work in today's world. Data flows in via all sorts of different media and has to be transformed into different formats, stored, shared, or integrated with other systems. Every customer has a different set of needs. Things get even worse as these needs keep changing, creating a network of almost infinite possibilities. No stand-alone software product can keep up with this.
The best way to serve the diverse set of customer needs is to give the user a product with an extendable architecture and let him self-serve. Giving the user the tools he needs to devise solutions to his own problems takes the burden off the shoulders of developers and minimizes the risk of miscommunication.
## **Doing it the SAP way**
SAP is one of those companies that appreciated the potential of an extendable architecture in enterprise software early on. It is primarily a record-keeping software with lots of database and data operations involved. What gave SAP its extendable character was ABAP, its domain-specific language. ABAP made SAP extremely customizable and allowed the addition of new features to the platform without much hassle, giving the platform a low-code character. This increased customizability turned SAP into a very flexible platform that can serve a diverse range of use cases by offering different solutions.
SAP not only offers its customers a business model today, but also empowers them to deliver the services they promised. The result of the ABAP-induced customizability for SAP has been an ever-expanding customer base and a growing, healthy ecosystem built around the product.
SAP has also taken notice of the growth of the mobile app market. It has realized that it has to be competitive in that segment and offer mobile users similar capabilities if it is to retain its dominant position in the market. Its recent acquisition of AppGyver was an effort to plug that well-defined gap in its portfolio.
## **What if you are not a billion-dollar company?**
The strategies employed by Salesforce and SAP might be potent, but they are also difficult to replicate, especially for smaller companies. Such companies need to follow a different strategy here. A company with a CRM tool has to offer a level of customization that could rival Salesforce, which is impossible due to a lack of resources. What it can do, however, is to find an underserved segment in the market and focus on the needs of that particular segment.
The shortest route to success in this scenario? Using APIs to open the platform to users and letting users leverage no-code tools to customize the CRM tool in question. No-code platforms will be offering [ready-made templates](/blog/no-code-templates-competitive-edge/) to make it even easier for the users to customize the software for their particular use cases.
Every company in the software business today should have an extensions strategy. This is not a matter of preference but a necessity for a software company to get over the hump. Having in place a sound extensions strategy ensures the product is customizable, and thus fulfills a broader range of needs. Peaka takes care of the customization needs of its customers through APIs so that they can focus on their core line of work.
We believe that software companies should not have to diverge from their roadmaps and allocate scarce resources just to serve the specific needs of customers. Whether it is a customer portal, an internal tool, or a partner portal that your customers desire, Peaka makes sure that you deliver it to your customers with no added cost or effort.
--- START: blog/data-access-governance/data-access-governance.md ---
# Data Access Governance: Framework, Risks, and Tools
There's a particular kind of organizational panic that happens when someone asks "who looked at the customer records last Tuesday?" and the room goes quiet. Nobody answers, because nobody actually knows.
Data access governance (DAG) exists to solve that problem. Most organizations find out they need it right after something goes wrong. Maybe you already have.
At its core, DAG is the set of policies, processes, technologies, and accountability structures that control who can access specific data, under what conditions, and what gets logged when they do. It's a subset of data governance, which lives inside the broader universe of data management. Each layer narrows the scope. Data management handles the entire lifecycle; data governance adds standards and accountability; and DAG specifically handles the access-control layer. The goal (“the right people get the right data at the right time”) is simple to say but genuinely hard to pull off.
The distinction that matters most is between knowing who can access something and knowing who did access it, when, and what they did with it afterward. That second part is where organizations consistently underinvest, until a regulator or a breach forces the issue.
## Why 2026 looks nothing like 2016
The global data governance market was valued at $3.91 billion in 2024 and is projected to reach $12.66 billion by 2030 ([Grand View Research](https://www.grandviewresearch.com/industry-analysis/data-governance-market-report)). Organizations don't spend money like that because someone read a persuasive whitepaper. They spend it because something broke.
The threat environment and the regulatory floor were the two things that broke, roughly simultaneously. In 2024, internal actors were the catalyst behind 35% of data breaches, up from 20% the year before ([Verizon DBIR, 2024](https://www.verizon.com/business/resources/reports/2024-dbir-data-breach-investigations-report.pdf)). The common thread is permissions that outlasted their purpose, a failure of the principle of least privilege that eventually became a problem. Eighty-three percent of organizations reported at least one insider incident in the past year ([Cybersecurity Insiders, 2024](https://www.cybersecurity-insiders.com/2024-insider-threat-report/)). Most of those incidents were preventable.
Meanwhile, GDPR never went away, the EU AI Act entered into force in August 2024 with substantive requirements applying from August 2026, and finance and healthcare have always operated under demanding sector-specific rules. The audit log that used to be optional is now a compliance artifact someone will ask for during a regulatory review.
Then there's AI. In 2024, 78% of companies were using AI in at least one business function, up from 55% the prior year ([McKinsey, 2024](https://www.mckinsey.com/capabilities/quantumblack/our-insights/the-state-of-ai-how-organizations-are-rewiring-to-capture-value)). Every AI deployment is also a new data consumer, one that queries constantly, leaves no paper trail on its own, and lacks institutional memory about which tables to trust. Add agents, APIs, and a proliferating stack of dashboards all hitting the same infrastructure, and manual review of who accessed what becomes operationally impossible at any meaningful scale.
## What a real framework does
The core challenge is that most organizations don't have a reliable picture of what data they hold, where it lives, who can reach it, or what's happening to it in real time. Permissions compound the problem by drifting quietly over time. Without a structured framework, there's no way to close that gap at scale.
Sensitive data discovery comes first, because you can't govern what you don't know exists. Sensitive data ends up in inconvenient places, such as S3 buckets nobody's audited in two years, SaaS tools the security team forgot were connected, a spreadsheet someone exported in 2019 and emailed around. A data catalog drives discovery and surfaces what's there.
Classification tags data by sensitivity and regulatory category, so policies apply automatically. Access controls, both role-based (RBAC) and attribute-based (ABAC), define what each identity can actually reach. The critical detail is that permissions should be evaluated at query time in a zero-trust model, scoped to the actual end user making the request. Too many systems still inherit permissions from a service account that was provisioned broadly three years ago and never revisited. That's where most teams get caught. It's also exactly what Peaka enforces. When a query runs through Peaka's semantic catalog, permissions are resolved against the real end-user identity at query time, and shared service credentials never enter the equation.
Audit logging is where the accountability layer lives, and it's where most companies have a gap they don't realize exists. Logs that capture only an IP address and a timestamp are functionally uninterpretable when something goes wrong at scale. Useful logs combine identity, intent, data lineage, and business context. That means capturing who ran the query, what business question they were trying to answer, where the underlying data came from, and what happened with the result. Without all four elements together, a high-volume incident becomes a forensic nightmare on a deadline.
Automated remediation closes the loop by quarantining files, blocking access, alerting the security team, and triggering a documented response in real time when something anomalous occurs, rather than the next morning when someone checks their email.
## AI makes this harder in specific ways
Only 29% of technology leaders strongly agree that their enterprise data meets the quality, accessibility, and security standards needed to scale generative AI ([IBM Institute for Business Value, 2024](https://www.ibm.com/think/topics/ai-ready-data)). That gap is about to get much wider.
An AI agent doesn't operate the way a human analyst does. A human analyst knows which metrics finance actually trusts, which tables became unreliable after a schema change last quarter, and when to ask a clarifying question before running a number up the chain. An agent carries none of that institutional knowledge unless the context is machine-readable and embedded in the infrastructure itself. Stale or partial answers come back looking exactly as confident as correct ones; the agent returns a number either way.
Write actions sit in a different risk category than reads entirely. An agent that can modify or delete data is an actor with real operational consequences, and governance controls for write access need to reflect that distinction explicitly rather than treat it as an edge case.
Model drift is a related problem, particularly in regulated sectors. AI models degrade when fed inconsistent or outdated data, and a governance framework that doesn't track freshness won't catch it until the model is already producing bad outputs at scale.
## The semantic layer problem
AI agents resolve ambiguity probabilistically. They infer meaning from column names, schema patterns, and surrounding context. If "Customer" means one thing in the CRM and something else in the billing system, every model that touches both inherits that confusion and becomes a model-drift risk. Prompt engineering can't compensate for a schema that carries no meaning.
A semantic layer sits between raw infrastructure and the things querying it. It translates technical structures into business-meaningful terms, defines metrics once ("Revenue," "Active Customers," "Churn Rate"), and ensures every dashboard, API, and agent query works from the same definitions. The metric in your BI tool matches the metric in the Python notebook, which matches what the AI agent returns. That consistency is built into the structure itself, so it doesn't depend on everyone remembering which version of a calculation is canonical this quarter.
Governance controls belong in the semantic layer, built in from the start. An agent that can reach ungoverned raw tables through a back door makes the rest of the framework decorative. That's the principle Peaka is built around. Its semantic catalog is where both business definitions and access policies live, so there's no gap between what a query means and what it's allowed to touch. If you're evaluating how that works in practice, the documentation is a useful starting point.
## "Clean" is not the same as "AI-ready"
This distinction has real financial consequences. Gartner projects that through 2026, organizations will abandon 60% of AI projects that lack AI-ready data ([Gartner, 2025](https://www.gartner.com/en/newsroom/press-releases/2025-02-26-lack-of-ai-ready-data-puts-ai-projects-at-risk)). The pattern is almost always the same: Data was cleaned for human analysts, declared ready, pointed at an AI system, and produced confidently wrong answers.
AI readiness requires that freshness, context, permissions, and lineage be machine-accessible. A weekly snapshot that works perfectly for a Monday morning dashboard is genuinely stale for an agent making a real-time operational decision. Permissions need to match the use case rather than carry over from whatever service account was convenient to reuse. These distinctions produce different outputs, and downstream decisions depend on those outputs being correct.
{{ resize_image(path="../static/assets/images/blog-images/mathew/data-governance-vs-ai-readiness.png", width=759, height=400, op='fit_width', alt="a table comparing ai agents to human interaction") }}
## How organizations are actually handling this
The practical starting point is an honest current-state assessment laying out what's been discovered, what's classified, whether access is enforced at query time, whether there's semantic context, and whether the audit trail is sufficiently complete to be useful during an incident.
The governance layer doesn't require replacing existing infrastructure. Controls can be layered on top of what's already there, whether that's Snowflake, BigQuery, Redshift, or a Databricks lakehouse. Rebuilding from scratch would stall AI programs for years. Data product marketplaces, where producers publish governed and documented data products that consumers can discover and request access to, are becoming the operational mechanism for doing this at scale, borrowing directly from data mesh principles.
Trusted AI requires trusted data. Without governance embedded at the data layer, with semantic context, query-time enforcement, and full audit lineage, AI initiatives tend to follow the same arc which always involves a promising pilot, scaling problem, stall. Getting the governance in place before the stall is considerably cheaper than the alternative.
If you're working through what that looks like for your stack, [Peaka's platform](/) is designed to handle exactly this. It unifies data sources, adds the semantic and governance layers, and makes that infrastructure AI-ready without a ground-up rebuild. It's worth a look.
To see how you can introduce data governance into your AI project, [book a demo](https://calendly.com/peaka/demo) with Peaka.
--- START: blog/data-brief-history/data-brief-history.md ---
# **Before the Warehouse, Lake, and Hub: A Brief History of Data**
"_Data is the new oil,_" [said](https://towardsdatascience.com/is-data-really-the-new-oil-in-the-21st-century-17d014811b88) the British mathematician Clive Humby in 2006. Even the metaphor itself, whether data was the new oil, the combustion engine, or something totally different, became the subject of articles and spurred long debates. Cumby's words proved prophetic as data was central to the historic rise of Big Tech over the last fifteen years. Data-related jobs are some of the most popular, highest-paying jobs in the tech industry today and even the most modest SMBs are advised to focus on data and make "data-informed" decisions.
[Data](https://www.merriam-webster.com/dictionary/data) is defined as the "_factual information (such as measurements or statistics) used as a basis for reasoning, discussion, or calculation._" This information can be about anything, i.e., the amount of monthly traffic a website attracted, the score each student got in an exam, or the average temperature recorded at a location on a specific day over a decade. Today data may have become predominantly digital, but that wasn't always the case. Let's take a brief look at the history of data and how its nature has changed over the centuries.
## **Prehistoric Africa**
{{ resize_image(path="../static/assets/images/blog-images/data-1-history-ishango-bone.png", width=759, height=400, op='fit_width', alt="Image showing the Ishango bone") }}
The Ishango bone.
Image credits: [The Ishango Bone](https://commons.wikimedia.org/wiki/File:Osso_di_Ishango.jpg) by [Matematicamente.it](https://www.matematicamente.it/staticfiles/manuali-cc/algebra1_dolce_1ed.pdf), February 4, 2016, shared under Creative Commons [Attribution-Share Alike 3.0 Unported](https://creativecommons.org/licenses/by-sa/3.0/deed.en) license.
One of the earliest tools used for storing data was discovered in the Democratic Republic of Congo in 1950. [Ishango bone](https://en.wikipedia.org/wiki/Ishango_bone) is an animal bone with groups of notches carved on it and dates from 18,000 BCE-20,000 BCE. Whether it was a simple tally stick or a more sophisticated tool to track the lunar calendar is [up for debate.](https://www.maa.org/press/periodicals/convergence/mathematical-treasure-ishango-bone) However, it shows that humans needed data even when they were leading supposedly much more primitive lives than we do now.
## **Ancient Babylonia**
As society got more complex, so did the types of data people needed to track. Studies led by Professor Eleanor Robson of University College London have shed light on how Babylonians used clay tablets to store data. This Mesopotamian civilization took a census took a census [every six or seven years](https://www.abs.gov.au/websitedbs/d3310114.nsf/51c9a3d36edfd0dfca256acb00118404/eadaffffb171cab6ca257161000a78d7!OpenDocument) to count the people and livestock and record the amount of milk, honey, wool, and vegetables produced. The aim was to determine the number of people that could be taxed or called up for military service. With its seat of power located between the Euphrates and Tigris rivers, the Babylonian rule [depended on](https://www.historyonthenet.com/the-wonders-of-ancient-babylon) controlling water resources, expanding irrigation, and undertaking massive public works projects. This endeavor involved the mobilization of a large workforce, provisioning of supplies for these people, a bureaucracy to oversee the projects, and lots of account keeping.
Babylonians used clay tablets to create tabular accounts for keeping track of data. For example, a Babylonian tabular account dating from 2028 BC demonstrates a tally of [sheep and goats.](https://www.academia.edu/1261769/Accounting_for_change_The_development_of_tabular_bookkeeping_in_early_Mesopotamia) Later examples were more sophisticated. One tablet [found in the city of Nippur](https://www.academia.edu/1261769/Accounting_for_change_The_development_of_tabular_bookkeeping_in_early_Mesopotamia) was used to account for a ditch construction project, with headed columns and each row denoting the length and width of walls being built, the name of the worker responsible, and total wages to be paid in grain and wool.
{{ resize_image(path="../static/assets/images/blog-images/data-1-history-babylonia-larsa.png", width=759, height=400, op='fit_width', alt="The Babylonian tablet found in Larsa") }}
The Babylonian tablet found in Larsa.
Image credits: [(BM 085232)](https://cdli.ucla.edu/search/search_results.php?SearchMode=Text&ObjectID=P368686) by Eleanor Robson.
[Another tablet](https://www.datafix.com.au/BASHing/2020-08-12.html) found in the ancient city of Larsa and dating from [circa 1900-1600 BC](https://cdli.ucla.edu/search/search_results.php?SearchMode=Text&ObjectID=P368686) probably served as a payroll summary from a construction project, showing us the base rate, the amount of work done, and the wage earned. These artifacts demonstrate that the spreadsheet format was the king centuries before MS Excel was a thing.
## **Roman Empire**
Rome was a civilization that perfected record-keeping out of sheer necessity. Ruling over vast territories, building cities, roads, aqueducts, and all kinds of public works, and controlling a war-making machine that was the Roman army, the Roman Empire needed records more than anything. In order to gauge the pool of manpower at hand and determine taxes, The Roman administration conducted a census [every five years](https://www.ons.gov.uk/census/2011census/howourcensusworks/aboutcensuses/censushistory/censustakingintheancientworld), with every man and his family returning to his place of birth. Effective taxation kept the Roman administrative machine working, and it was the data collection that made this possible.
## **Early modern England**
[John Graunt](https://www.smithsonianmag.com/smart-news/people-have-been-using-big-data-1600s-180962949/) was a hat maker from London, a growing city frequently hit by bouts of plague in the mid-seventeenth century. His studies on the number of deaths resulting from plague based on the Bills of Mortality were of pioneering character.
Graunt's use of Life Tables derived from the mortality data was a first in the field. Following "a virtual population of one hundred people through the [age-specific mortality](https://www.encyclopedia.com/social-sciences/applied-and-social-sciences-magazines/graunt-john-0) rates of the actual population," these tables enabled Graunt to make projections about the future and past populations, providing an early example of data-informed policy suggestions. For these tables, Graunt used christening and burial data, aggregated it, and broke it down according to [gender](http://www.edstephan.org/Graunt/tables.html) and [causes of death](http://www.edstephan.org/Graunt/chart.html) to reach conclusions that no one else had done before. His book, [_Natural and Political Observations upon the Bills of Mortality_](https://www.scb.se/contentassets/ca21efb41fee47d293bbee5bf7be7fb3/london-plague-statistics-in-1665.pdf), first published in 1662, changed the way people saw life and death. Grant's work was so influential that he has been [credited with](https://www.encyclopedia.com/history/encyclopedias-almanacs-transcripts-and-maps/graunt-john-1620-1674) laying the foundations of modern demography and statistics.
## **Modern era**
Under the _ancien régime_, the European society consisted of three classes: Aristocracy, clergy, and peasantry. Social mobility was restricted, the state apparatus was rather small, and the bureaucracy in the modern sense was nowhere to be found. Things began to change with the rise of overseas trade and the emergence of a new class of merchants and later urban professionals. The dealings of these ambitious upstarts brought about an increase in the data produced. It was a faster, more complex world, calling for heavier data use.
{{ resize_image(path="../static/assets/images/blog-images/data-1-history-tabulating-machine.png", width=759, height=400, op='fit_width', alt="Herman Hollerith's tabulating machine") }}
The tabulating machcine developed by Herman Hollerith.
Image credits: [Tabulatrice, selezionarice e perforatrice holleritho](https://commons.wikimedia.org/wiki/File:Tabulatrice,_selezionarice_e_perforatrice_hollerith_-_Museo_scienza_tecnologia_Milano_D0779.jpg) by I.B.M. Italia, May 31, 2016, shared under Creative Commons [Attribution-Share Alike 4.0 International](https://creativecommons.org/licenses/by-sa/3.0/deed.en) license.
The second half of the nineteenth century saw a further uptick in the amount of data produced: The industrial revolution was in full swing, and another revolution in communication was unfolding. The world was a smaller place thanks to new technologies like the telegraph, telephone, and radio. However, the data produced was still at modest levels, manageable by devices like Herman Hollerith's [tabulating machine.](https://en.wikipedia.org/wiki/Tabulating_machine) Hollerith invented a way to store data in machine-readable form in punched cards. His method was used in the U.S. census held in 1890, resulting in time and budget savings. Data processing had become more efficient. The next bottleneck seemed to be data storage. Luckily, [Fritz Pfleumer's](https://en.wikipedia.org/wiki/Fritz_Pfleumer) invention of the magnetic tape in 1928 solved the data storage problem for decades to come.
There was a noticeable pattern in data production and usage up until the mid-twentieth century: The amount of data being produced and people involved in data production was on the rise, but the type of data did not change much. It was mostly structured data produced by governments and different branches of bureaucracy, traders, banks, and industrialists. The general public was not a part of the process yet. What brought the general public into the fold was the introduction of computers in the middle of the last century. The ensuing nonstop miniaturization of computers, capped with the introduction of the Internet in the 1990s, meant that billions of people were producing data in wildly different formats.
## **From 2007 onwards**
If the Internet caused a surge in the amount of data produced, what smartphones, social media, and cloud technology did was trigger a true [Cambrian explosion](https://en.wikipedia.org/wiki/Cambrian_explosion), growing the amount of raw data produced by orders of magnitude. Every like, dislike, click, or move of the mouse was a data point now.
It was around this time, towards the end of the first decade of the new millennium, that we started hearing about data science, data scientists, and data analysts. Overwhelmed by the amount of data unleashed in a short time, people decided to focus on gathering as much data as possible first and worry about making sense of it later. Collecting, sorting, transforming, making sense of, and securing the data became specialized tasks in their own right, requiring expert attention. Concepts like data warehouses, data lakes, and data hubs were all products of the efforts to tackle this sheer volume and complexity of data.
## **What changed?**
The way people treat data has gone through a transformation over the centuries. For ancient people, data was merely a record of past transactions or a predictor of a few phenomena like collectible taxes or available manpower. Today we use data to inform our every decision about the future. Data allows us to monitor the progression of certain processes, and find patterns and trends, making course correction possible. Its importance in our lives justifies further discussion.
--- START: blog/data-etl-vs-elt/data-etl-vs-elt.md ---
# **ETL vs. ELT: Different Strokes for Different Folks**
Unstructured data's sudden rise to dominance came with immense technical challenges. Managing the storage costs for vast amounts of data was one of those. Another was to ensure that the data remained accessible whenever needed, despite being scattered across many locations. Making sense of all that data on the analytics front was the third of the hurdles to be tackled. The sheer amount and different formats of data meant that old ways of working with data were no longer viable.
These challenges have been high up on the agenda for the software industry during the last decade. Tools to pull data from different sources, optimize storage usage, and improve data analytics have become mainstream. Another change involved data pipelines: They had to be reconfigured to accommodate the requirements of handling unstructured data. This change manifested itself in ELT's (Extract - Load - Transform) rising popularity against ETL (Extract - Transform - Load).
ELT hasn't replaced ETL altogether but rather proved more applicable to a broader range of scenarios as it caters to the most pressing needs in the market. Understanding why ELT is more popular and how ETL can still stick around can shed light on the future trajectory of data integration.
## **ETL (Extract - Transform - Load)**
In the ETL, you extract data and move it to a staging layer where transformation will take place. Transformation is the act of converting data to the desired format for analysis. Once that is done, you load the data into the designated storage location. Here, all three actions (extract, transform, and load) are tied together and occur in the same run. In the ETL, you basically define a transformation process that can be applied to a general use case.
ETL is more suited to handling structured data. The data is cleansed and enriched in a processing server before loading it. The user can perform [security checks](https://www.youtube.com/watch?v=8MfyfW9CeKA) and encrypt the data at the source. These steps help ensure that privacy concerns are taken into consideration (such as removing [personal identifying information](https://rivery.io/blog/etl-vs-elt/) from data) and that the data now complies with regulations.
ETL is a cost-effective data integration method. However, it is not flexible since each process is designed for a specific type of transformation. You have to [build a new ETL pipeline](https://www.youtube.com/watch?v=voC0ewDeltA) every time you want to make a change in the way your data warehouse works. The whole process has to be reconfigured when the input or output data format is changed. Therefore, ETL can be rather cumbersome to use when format changes are a regular thing.
## **ELT (Extract - Load - Transform)**
Despite its success with structured data, ETL was not a good fit for unstructured data, the [predominant form of data today](/blog/data-unstructured/). Unstructured data comes in a wide range of formats from a plethora of different sources and requires complex transformations. The more diverse data formats are, the more the number of reconfigurations you have to implement for data transformation. A sensible way to minimize the number of transformations was to extract the data, load it into a data warehouse, and delay the transformation until a specific need arose. This method was the ELT.
ELT offers the users the flexibility and scalability that ETL can not. With the ELT, you move [the whole data set](https://www.techtarget.com/searchdatamanagement/definition/Extract-Load-Transform-ELT), not just a subset of the data as you would do with ETL, to the target destination, where it will remain as raw data until you need to transform it. The ELT method decouples the "extract" function from the "transform" function— you don't have to transform the data right after extracting it.
This "decoupling" affords you the luxury of delaying the data model decisions to the moment you need to use them. Moreover, you can also configure transformation processes for different, unique use cases instead of configuring a transformation that will apply to a general use case. When you change the SQL queries you run in an ELT pipeline, you are basically changing the transformations you make.
In spite of these advantages, ELT comes with a serious [security risk](https://blog.panoply.io/etl-vs-elt-the-difference-is-in-the-how). As the data is loaded into a data warehouse or a data lake before any transformations or security checks, it is likely to contain sensitive personal or confidential data. The data will probably not comply with data security protocols at that point.
## **Final thoughts**
The bifurcation of data integration methods into ETL and ELT stemmed from real needs. Users who work with structured data on source systems with high compute power and prioritize data security keep using ETL. Users who deal with more current problems associated with unstructured data and value the flexibility in designing more complex and unique transformations can transition to ELT. It looks like ELT has nailed the product-market fit in a field dominated by unstructured data.
--- START: blog/data-infrastructure-for-ai-agents/data-infrastructure-for-ai-agents.md ---
# AI-Ready vs. Traditional Data Infrastructure
Traditional data infrastructure was built for human analysts. Humans are forgiving consumers. They ask colleagues when something is unclear, they know which numbers to trust, and they carry institutional context that no schema ever documented. AI agents cannot do any of that. They act on what the data says, with full confidence, whether it is right or wrong. That difference changes everything about how data infrastructure needs to be designed.
An AI agent cannot ask a follow-up question, infer business intent from a poorly labeled field, or distinguish between a stale snapshot and a live feed. A wrong answer stops being a misread number on a chart and becomes an action taken.
That consequence asymmetry is the defining shift, and most infrastructure decisions in enterprise data were made before it existed. Traditional architecture was optimized for batch processing, periodic analytics, and relational schemas normalized for joins. It worked because the humans consuming it compensated for its gaps. Remove the human from that loop and replace them with an agent executing autonomously, and every assumption the infrastructure was built on collapses at once.
## The collapse is already underway
The most visible collapse is latency tolerance. A [nightly batch refresh](https://ai-ready-data-69208a.letterstory-staging.com/posts/data-freshness-requirements-for-ai-agent-decision-making) that serves a morning dashboard is already stale for an agent making a real-time decision. But the deeper collapse is interpretive. Institutional memory lived in people, in the analyst who remembered the Q3 re-classification meeting, in the data engineer who knew which pipeline occasionally drops a day. Now that memory needs to live in the data itself. For most enterprises, it simply does not.
The scale of what's coming makes this more urgent, not less. Gartner projects that 40% of enterprise applications will integrate task-specific AI agents by the end of 2026, up from less than 5% in 2025. That trajectory means agent-driven query volume will rapidly overwhelm governance frameworks designed for human-paced access. And the bulk of enterprise data is unstructured, spanning images, audio, documents, and transcripts. Traditional infrastructure treated that as an edge case. For AI agents, it is the primary workload.
## The five properties that define AI-ready data
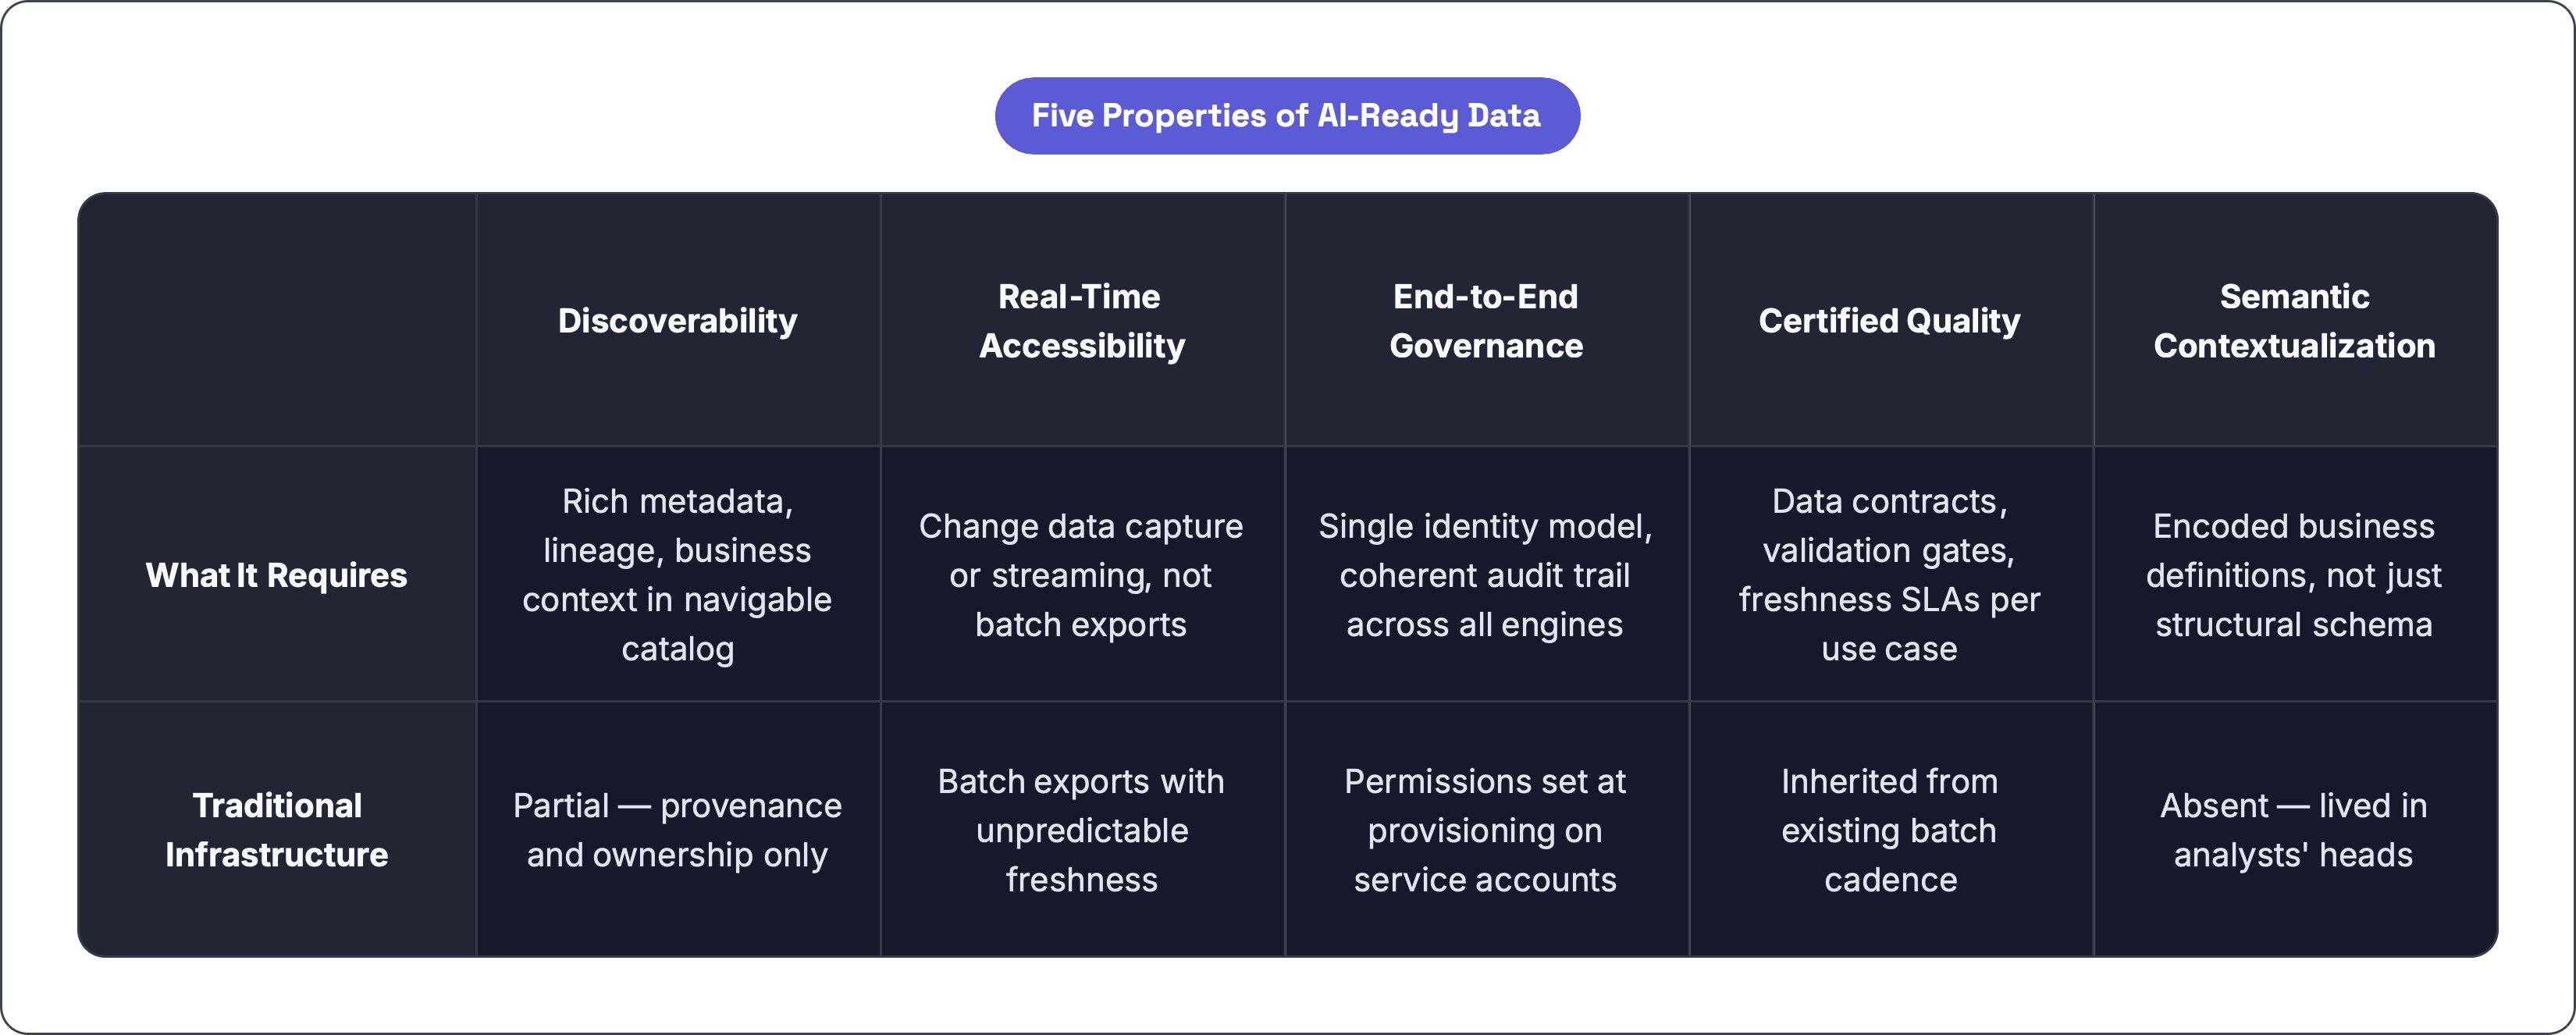
BI-ready and AI-ready are not the same thing. Conflating them is the source of most failed AI pilots, and it happens constantly. AI-ready data requires five properties that should all be upheld at once:
- Discoverability: rich metadata including ownership, lineage, and business context in a catalog an agent can actually navigate.
- Real-time or near-real-time accessibility: change data capture or streaming pipelines, not batch exports with unpredictable freshness.
- End-to-end governance: a single identity model and a coherent audit trail across every engine and every agent traversal.
- Certified quality: data contracts, validation gates, and freshness SLAs designed per use case rather than inherited from whatever the existing batch cadence happens to produce.
- Semantic contextualization: the data must carry an explanation of what it means, not just what it is.
## Where traditional infrastructure falls short
Traditional infrastructure typically addresses fragments of the first four and ignores the fifth entirely. Metadata describes provenance and ownership, useful for lineage audits, but it does not explain what a metric means to a query engine. Access controls are assigned at provisioning time on service accounts. Schemas are normalized for joins, not structured for retrieval. The semantic layer was never part of the design because it was never needed; the analyst had it in their head.
The gap isn't a lack of tooling, which exists at every layer already; it's a design failure to recognize that the consumer changed while the infrastructure did not.
The most common architectural mistake being made right now is bolting a vector layer onto a data warehouse without rebuilding the metadata layer underneath it. The demo works, but production doesn't hold up. The agent retrieves something, generates a confident answer, and the answer is wrong in ways that take weeks to diagnose because nobody instrumented the data layer to explain itself. That failure mode traces directly to the absence of those five properties.
## The semantic layer advantage
### From schema to semantic layer
A schema tells you what data exists. A [semantic layer](https://ai-ready-data-69208a.letterstory-staging.com/posts/what-a-semantic-layer-is-in-a-data-warehouse) tells you what it means. It encodes business definitions, metric logic, calculation rules, relationships between entities, and the exceptions that apply in specific contexts, all in one governed layer that every consumer queries through.
Traditional infrastructure exposed schemas because that was sufficient. An analyst could read the schema, cross-reference their institutional knowledge, and produce a correct answer. The semantic translation happened inside a human brain, informally, invisibly, non-reproducibly. Nobody documented it because nobody had to.
When an LLM is the analyst, that translation does not happen. The model generates syntactically valid SQL against a raw schema and produces an answer that is wrong in ways that look exactly like right answers. The query runs and the number appears, with confidence indistinguishable from a correct result. The error is invisible until downstream, and by then the damage is done.
### The research behind the shift
Published research shows LLM analytical accuracy improving from roughly 40% without a semantic layer to over 83% when grounded in governed semantic definitions. A 2026 arXiv benchmark found accuracy gains of 17 to 23 percentage points across multiple frontier models when a semantic-layer document was supplied alongside the raw schema. The model did not change. The context did. Organizations keep treating that finding as a footnote.
Gartner elevated the semantic layer to essential infrastructure in the 2025 Hype Cycle for Business Intelligence and Analytics. GigaOm classified the category as mature for the first time that same year, after years of it occupying an ambiguous middle ground between nice-to-have and architectural requirement. The practitioner community reached this conclusion through experience, not through vendor roadmaps. The organizations that figured it out generally did so after getting burned by the alternative.
### Built for consistency and governance
The semantic layer also resolves a consistency problem that process never reliably could. If business logic is defined once in a governed semantic layer, every consumer, BI tools, analysts, AI agents, gets the same definition. Consistency becomes an architectural property rather than a convention enforced by institutional memory that walks out the door when someone leaves.
Combined with emerging protocols like MCP ([Model Context Protocol](https://modelcontextprotocol.io/)), the semantic layer allows agents to reason over governed definitions rather than make probabilistic inferences about what a column probably means. That distinction matters enormously when the agent is acting rather than just reading. This is the design principle [Peaka](/) is built on. It's a semantic catalog where business definitions and access policies live together, exposed to agents through MCP, so what a query means and what it is allowed to touch are never defined in two different places.
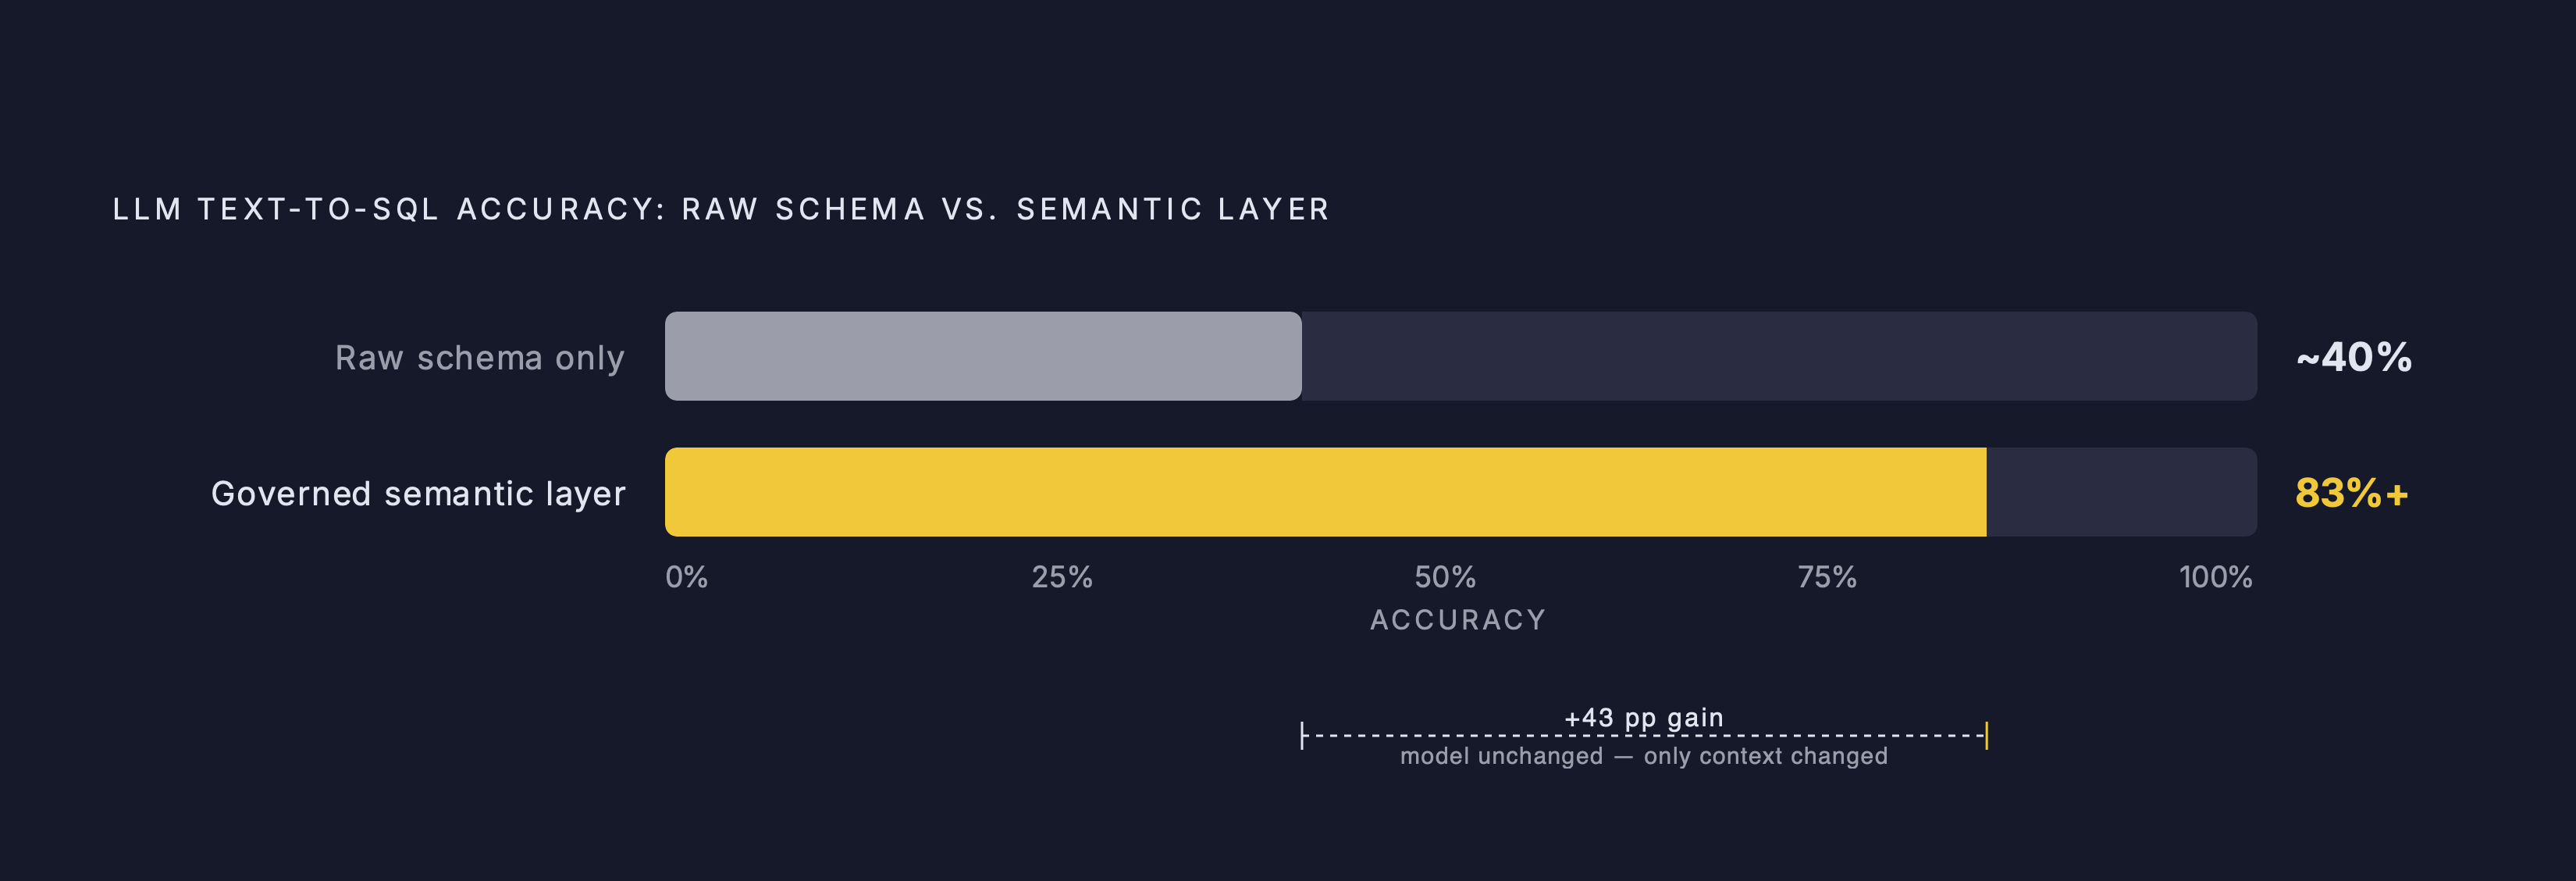
## Governance for agent-driven queries
### Three broken assumptions
Traditional governance was built on three assumptions. It assumed human-paced access, structured data, and permissions set at provisioning time. All three fail under agentic workloads, and they fail in ways that traditional frameworks have no mechanism to address.
Human-paced access meant a governance team could, in principle, review access requests, audit logs, and exception reports because the volume was manageable. Agent-level query volume is not manageable by inspection. The audit trail has to be automated, comprehensive, and machine-readable from the start.
Permissions set at provisioning time on service accounts create a specific problem. A [shared service account](https://ai-ready-data-69208a.letterstory-staging.com/posts/service-account-risks-in-agentic-pipelines) with broad access cannot be scoped to a single workload without affecting everything else relying on it. When an agent executes a query, the permissions need to reflect the actual end user's identity, evaluated at the moment of the query, not a service account provisioned months earlier. That is a fundamentally different model, and most existing frameworks were not designed for it.
### The combination risk
The governance gap that gets underestimated most consistently is sensitivity at the combination level. A field-level sensitivity label tells you that a given column contains PII. It does not tell you that combining three individually non-sensitive columns creates an exposure equivalent to direct identification. Agents traverse data in non-linear ways, joining sources that analysts would never have combined in a single session. Governance frameworks that evaluate sensitivity field by field, at ingestion time, will miss the exposures that actually materialize in production.
Write [actions carried out by agents](https://ai-ready-data-69208a.letterstory-staging.com/posts/ai-agent-read-vs-write-permission-asymmetry) require different risk calibration than reads. An agent that can execute writes, trigger downstream processes, or initiate external API calls creates a risk surface that read-only governance was never designed to constrain. This is where the gap between "we have a governance framework" and "our governance framework covers agentic workloads" becomes consequential rather than theoretical.
### Regulatory pressure is rising
IDC's 2026 enterprise AI planning data shows AI data governance became the top AI adoption priority at 45.7% of organizations, overtaking AI business strategy and AI infrastructure. That ranking reflects hard-won understanding. Organizations that moved fast on model deployment and slow on governance are now living with the consequences, and in many cases those consequences are visible enough to inform the decisions of organizations still in early deployment stages.
The EU AI Act entered into force in August 2024 and began phasing in substantive obligations in February 2025. More than half of organizations now identify compliance and regulatory readiness as their primary AI adoption challenge. Regulatory pressure is accelerating what should have been an architectural priority from the beginning.
## Why AI initiatives stall
### The numbers behind the failures
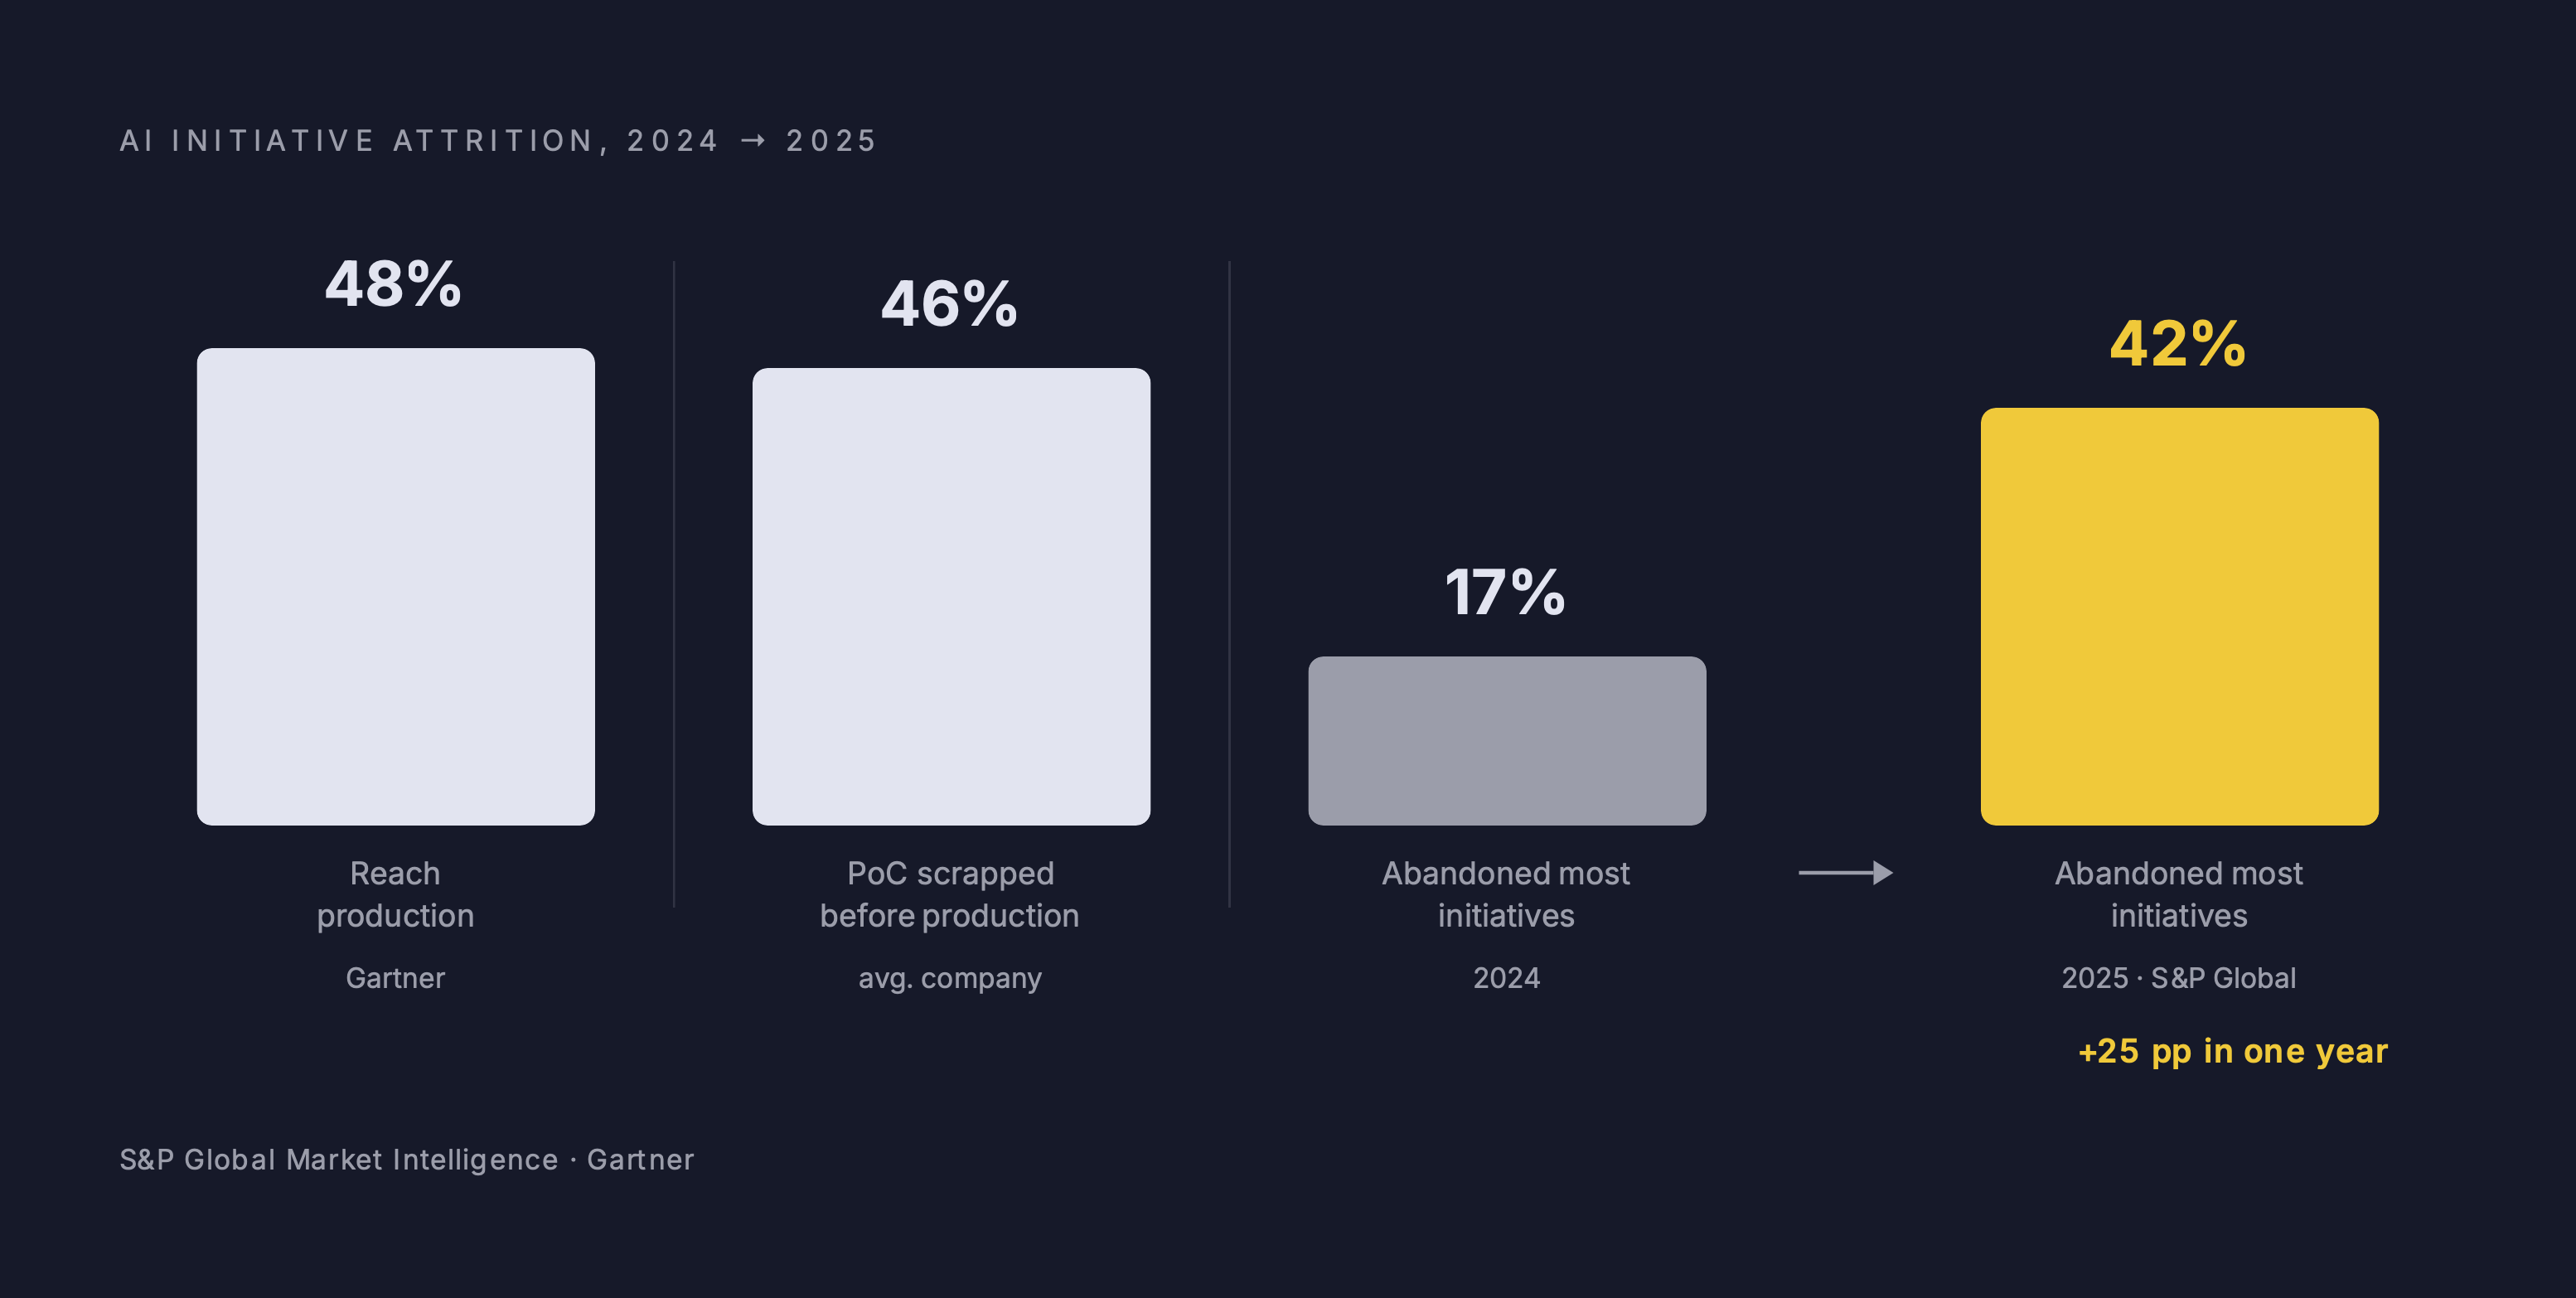
MIT Project NANDA published findings in July 2025 showing that 95% of organizations deploying generative AI saw zero measurable return. S&P Global Market Intelligence found that the share of companies abandoning most AI initiatives jumped from 17% in 2024 to 42% in 2025, with the average company scrapping 46% of proofs of concept before production. Gartner's data shows that only 48% of AI projects reach production, and the median time from prototype to production is eight months.
### The common failure pattern
The failure pattern is consistent across organizations and industries, consistent enough to be predictable. A team identifies a compelling use case, selects a capable model, builds a demo against a clean, curated dataset. The demo impresses stakeholders. Then production exposes that the actual enterprise data is ambiguous, stale, ungoverned, inconsistently defined, and structurally incompatible with what an AI agent needs. The project stalls. The prototype gets scrapped. The lesson recorded is "AI doesn't work for us," when the actual lesson is that someone tried to run AI infrastructure on top of analyst infrastructure.
Informatica's 2025 survey of 600 data leaders globally found that 43% cite data quality, completeness, and readiness as the leading obstacle preventing AI pilots from reaching production. A study from Drexel University and Precisely found that 62% of organizations cite lack of data governance as the primary barrier to successful AI initiatives. These numbers describe a sequencing problem. Organizations selected use cases and models before establishing the data foundation those models require.
### What high performers do differently
The organizations that consistently produce measurable AI returns made a different call. They built data infrastructure before selecting use cases. McKinsey's 2025 State of AI report found that high performers were nearly three times as likely to have fundamentally redesigned workflows, and that strong data infrastructure was among the practices most consistently associated with meaningful returns. Infrastructure first, use cases second. It sounds obvious in retrospect. Most organizations still have not done it.
## Building AI-ready infrastructure
### The Peaka approach
For most enterprises, replacing existing warehouses and pipelines outright isn't practical, so the architectural task has to be additive and integrative instead.
That is the approach Peaka takes. It connects the sources an enterprise already runs, from warehouses like Snowflake and BigQuery to databases and SaaS APIs, and adds the semantic and governance layer above them without moving the data. The semantic layer sits above existing storage and exposes a single interface carrying business definitions and metric logic. Agents query meaning rather than raw schema. The translation that used to happen inside an analyst's head is encoded, versioned, governed, and available to every consumer uniformly, including the ones that cannot improvise.
### Governance and data contracts
Governance enforced at the query layer, not patched at the model or prompt layer, means permissions evaluated at runtime under the real user's identity. Every query logged with full lineage capturing identity, intent, and the data traversed. Sensitivity evaluated at the combination level, not field by field. Write actions governed under stricter controls than reads, with explicit rather than implicit constraints.
Data contracts and validation gates encode freshness and quality requirements per use case. A streaming feed informing an agent decision carries different SLA requirements than a nightly batch populating a dashboard. The infrastructure should enforce that distinction explicitly. Convention has never been a reliable mechanism for managing it.
### The bottom line
The underlying shift is from infrastructure designed for consumers who fill in what the schema omits, to infrastructure that carries its own context, enforces its own permissions, and logs its own lineage. Because the consumer on the other end cannot do any of those things itself. The organizations resolving that architectural challenge first are the ones accumulating the performance gap that the aggregate statistics already reflect.
If you're assessing where your own stack falls on that spectrum, [Peaka's documentation](/docs/) is a practical place to see what an AI-ready layer looks like on top of infrastructure you already have.
--- START: blog/data-integration-architecture/data-integration-architecture.md ---
   Link copied
Table of Contents
* [From ETL to Zero-ETL: A Guide to Data Integration Architecture](https://www.peaka.com/blog/data-integration-architecture/#from-etl-to-zero-etl-a-guide-to-data-integration-architecture)
* [What is data architecture?](https://www.peaka.com/blog/data-integration-architecture/#what-is-data-architecture)
* [What are the benefits of a sound data integration architecture?](https://www.peaka.com/blog/data-integration-architecture/#what-are-the-benefits-of-a-sound-data-integration-architecture)
* [What are the different types of data integration architecture?](https://www.peaka.com/blog/data-integration-architecture/#what-are-the-different-types-of-data-integration-architecture)
* [New techniques and concepts in data integration architecture](https://www.peaka.com/blog/data-integration-architecture/#new-techniques-and-concepts-in-data-integration-architecture)
* [How Peaka approaches data integration architecture](https://www.peaka.com/blog/data-integration-architecture/#how-peaka-approaches-data-integration-architecture)
* [Final thoughts](https://www.peaka.com/blog/data-integration-architecture/#final-thoughts)
[Home](/) / [Blog](/blog) / From ETL to Zero-ETL: A Guide to Data Integration Architecture
[Data](https://www.peaka.com/category/data/)
Last updated on June 04, 2025
11 min read
From ETL to Zero-ETL: A Guide to Data Integration Architecture

Martin Carrell Peaka / Data Guru
**From ETL to Zero-ETL: A Guide to Data Integration Architecture**[](#from-etl-to-zero-etl-a-guide-to-data-integration-architecture)
====================================================================================================================================
Organizations have finally woken up to the fact that they are sitting on a heap of data that’s growing by the second. The real challenge is to access, unify, and harness this data and turn it into information that can guide decisions. Tackling this challenge requires a well-thought-out data integration architecture in place.
Data integration architecture is a blueprint depicting how different data sources, pipelines, data warehouses and lakes, transformations, and data management activities work together to enable an organization to access, unify, and make sense of its data. It is the foundation on which every data-related activity within a company takes place. Therefore, the type of data integration architecture chosen comes to determine how well a company can leverage its data.
For the uninitiated willing to understand how modern data stack works and where it comes up short, our article titled [What is the Modern Data Stack?](/blog/what-is-the-modern-data-stack/) would be a good primer. Now, let’s dive into data integration architecture and why it matters for an organization.
**What is data architecture?**[](#what-is-data-architecture)
------------------------------------------------------------
**Data architecture refers to the overall framework that governs the acquisition, storage, management, and utilization of data across an organization.**
It encompasses the technologies, tools, processes, and best practices that ensure data integrity, accessibility, and alignment with business objectives.
**Data integration architecture**, therefore, serves as a sub-discipline within this overarching framework, specifically focusing on the seamless movement of data between disparate systems.
It's the detailed wiring connecting your CRM system to your marketing automation platform, your customer databases to your financial records, and your website analytics to your operational dashboards.
### **What are the components of data integration architecture?**[](#what-are-the-components-of-data-integration-architecture)
Understanding the key components data integration architecture is crucial for implementing a robust system.
These components work cohesively to ensure the smooth flow of data through diverse nodes in an organization:
### **1\. Data sources**[](#1-data-sources)
Data integration begins with identifying and connecting various data sources. These sources can include databases, cloud applications, APIs, flat files, and more. The architecture must support a diverse range of sources to accommodate the modern data landscape.
### **2\. Data storage**[](#2-data-storage)
Once data is collected, it needs to be stored appropriately. Data integration architecture includes a storage layer that can be a data warehouse, data lake, or a combination of both, depending on the organization's needs.
### **3\. ETL processes**[](#3-etl-processes)
Extract, Transform, Load (ETL) processes are the heart of data integration. These processes ensure that data is extracted from source systems, transformed into a suitable format, and loaded into the target storage. ETL tools are a vital component of this stage.
### **4\. Data transformation**[](#4-data-transformation)
Data often needs to be transformed to meet the requirements of the target system. Transformation processes within data integration architecture handle tasks such as data cleansing, normalization, and enrichment to ensure data quality and consistency.
### **5\. Data movement**[](#5-data-movement)
Efficient movement of data between systems is critical. The architecture must facilitate secure and seamless data movement, whether in real-time or batch processing, depending on the organization's needs.
### **6\. Metadata management**[](#6-metadata-management)
Metadata, or data about data, is essential for understanding the context and meaning of the information being integrated. Effective metadata management is a key component of data integration architecture, aiding in data governance and compliance.
**What are the benefits of a sound data integration architecture?**[](#what-are-the-benefits-of-a-sound-data-integration-architecture)
--------------------------------------------------------------------------------------------------------------------------------------
Investing in a well-designed integration architecture brings forth a plethora of benefits that go beyond mere data accessibility. Here are some key advantages:
### **Unified view of the customer**[](#unified-view-of-the-customer)
Integrating data from disparate sources eliminates data silos and helps form a holistic understanding of your customers. This unlocks powerful insights to improve customer experience and drive targeted marketing campaigns.
This is where Peaka comes into play! With its many [integration](/integrations/) options, Peaka helps you bring together and make sense of your data in one place!
### **Enhanced operational efficiency**[](#enhanced-operational-efficiency)
By automating data exchange between systems, a robust data integration architecture eliminates manual data manipulation and streamlines workflows. This translates into reduced operational costs and faster time-to-insights.
### **Data-driven decision-making**[](#data-driven-decision-making)
By providing access to unified and high-quality data, a well-designed data integration architecture empowers informed decision-making across all levels of the organization. From strategic planning to daily operations, every decision can be backed by actionable data insights.
### **Improved agility and adaptability**[](#improved-agility-and-adaptability)
Resilience is the ultimate attribute organizations can hope to have in the face of uncertainty. Adaptability is how you develop that resilience. A sound data integration architecture ensures that your organization will be able to leverage different data sources and scale its operations without effort when needed.
### **Boosted productivity and collaboration**[](#boosted-productivity-and-collaboration)
Breaking down data silos fosters collaboration between teams. With access to the same unified data, departments can work together more effectively, leading to improved productivity and innovation.
**What are the different types of data integration architecture?**[](#what-are-the-different-types-of-data-integration-architecture)
------------------------------------------------------------------------------------------------------------------------------------
Data integration architecture comes in various types, each catering to specific organizational needs:
### **1\. Enterprise service bus (ESB)**[](#1-enterprise-service-bus-esb)
ESB architecture acts as a middleware layer facilitating communication and data exchange between different applications. It ensures seamless integration and scalability in complex enterprise environments.
### **2\. Hub-and-spoke integration**[](#2-hub-and-spoke-integration)
Hub-and-spoke architecture involves a central hub that connects with various spokes (applications or systems). This centralized approach simplifies management and enhances data governance.
### **3\. Data pipeline**[](#3-data-pipeline)
Data pipelines provide a structured way to move data from a data source to a target destination. This method involves a series of steps through which data is discovered, cleaned, prepped, transformed, and loaded to its destination. Once built, data pipelines ensure efficient movement of data as long as it adheres to a strict data model.
The downside of this method, however, is the continuous monitoring and costly maintenance required from expensive data teams. Therefore, data integration architecture based on data pipelines are not ideal for startups and SMBs that lack the resources to hire data teams.
**New techniques and concepts in data integration architecture**[](#new-techniques-and-concepts-in-data-integration-architecture)
---------------------------------------------------------------------------------------------------------------------------------
In addition to the traditional methods listed above, there are new approaches to data integration architecture that are revolutionizing the field:
### **Data virtualization**[](#data-virtualization)
This technique eliminates the need for data replication, allowing data to remain in the source systems. The data is assembled from distributed sources at query time, providing a unified “virtual” view without physical replication.
### **Logical data warehouse**[](#logical-data-warehouse)
This approach combines physically persisted data with virtualized views of data. A logical data warehouse offers flexibility by allowing high-value data to be moved into a warehouse while virtualizing less frequently used data.
### **Query federation**[](#query-federation)
This method is a subset of data virtualization and allows for retrieving data from distributed data sources with a single query. It achieves this by leveraging connectors and drivers and removing the need to physically move data into a central repository.
### **Zero-ETL**[](#zero-etl)
This is another technique that relies on data virtualization to eliminate labor-intensive data pipelines. By keeping the data in a single environment, zero-ETL makes data available for business analytics and facilitates near-real-time reports.
These novel methods offer users significant advantages:
### **Less physical movement**[](#less-physical-movement)
Unlike traditional ETL-based data architectures, data virtualization, logical data warehouses, and query federation reduce the need to move data from one repository to another. This translates into less need for maintenance and less workload for engineering teams.
### **Near real-time integration**[](#near-real-time-integration)
The lack of ETL pipelines means that data can be retrieved in near real time. This advantage helps improve decision-making as it allows business teams to act upon up-to-date data.
### **Enhanced flexibility**[](#enhanced-flexibility)
Organizations using federated and virtualized architectures can easily add new sources to existing systems. This allows organizations to maintain a single source of truth without letting data silos form.
**How Peaka approaches data integration architecture**[](#how-peaka-approaches-data-integration-architecture)
-------------------------------------------------------------------------------------------------------------
The current paradigm in data integration architecture emerged to cater to the needs of enterprises with thousands of employees and abundant resources to employ large IT departments. As a result, it is capital- and labor-intensive, which was no problem since this particular type of user had the resources to invest in expensive infrastructure and hire data teams.
However, the rise of the startup economy changed the picture. These small companies with limited runways could not afford to use the same data integration architecture as enterprises, but they were forced to do so because there were no viable alternatives.
Cognizant of the [data integration](/blog/benefits-of-data-integration/) pains of these smaller organizations, Peaka has used the data virtualization technology to develop a purpose-built solution for startups. Peaka’s [zero-ETL](/blog/zero-etl-vs-modern-data-stack/) approach to data integration removes the need for complex transformation processes and brittle data pipelines, allowing startups and SMBs to bring their data together without the need for costly data teams.
Peaka goes the extra mile in lowering the technological barriers for startups and offers a wide array of ready-made connectors. These connectors enable one-click integrations with the most popular SaaS tools, helping startups build their data stack in minutes instead of months and query their data from its source in real time.
To save time and minimize errors while querying data, Peaka users can use the platform’s embedded ChatGPT capability to run SQL queries using natural language. After forming new data sets from their consolidated data, users can connect these data sets to other systems and applications through APIs.
Peaka redefines data integration architecture for startups striving to stay ahead of the curve and make data-driven decisions without breaking the bank.
**Final thoughts**[](#final-thoughts)
-------------------------------------
Investing in a sound data integration architecture is one of the best decisions a startup can make, as this investment ensures that the startup’s data operations will remain scalable in the future. After a decade spent trying in vain to adapt enterprise solutions to startup problems, startups can finally enjoy built-to-purpose solutions that take into account their resource constraints.
Techniques and concepts such as data virtualization, [logical data warehouse](/blog/logical-data-warehouse/), query federation, and zero-ETL have emerged as the perfect options for the data integration needs of startups. These methods differ from conventional enterprise solutions as they don’t require an upfront investment in a new data stack or expensive maintenance teams. They provide the lightweight data integration architecture a startup needs without straining its budget and offer the best bang for the buck. Startups taking advantage of these methods will start making better decisions and gain a significant edge over their competitors.

Frequently Asked Questions
--------------------------
### What is business architecture in Data Integration?

Business architecture, in the context of data integration, focuses on aligning data strategy with overall business goals. It defines the business capabilities and processes requiring data from various sources and how integrating that data creates value.
### What is Data Architecture?

Data architecture defines the outline for data management within an organization. It outlines the technologies, tools, and standards used to collect, store, transform, and analyze data. It ensures data is accessible, reliable, and consistent across different systems and applications.
### What is the role of a Data Integration Architect?

Data integration architects design and implement data integration solutions to meet business requirements. They collaborate with business stakeholders, data analysts, and IT teams to understand data needs, identify integration points, and select appropriate tools and technologies.
### What is meant by Integrated Architecture?

Integrated architecture refers to an approach to designing and managing the interaction between various systems and platforms within an organization. It encompasses business architecture, data architecture, application architecture, and technology infrastructure.
### What are the components of Data Integration Architecture?

The specific components of data integration architecture vary depending on the organization's needs and complexity. However, some common elements include data sources, data extraction tools, data transformation tools, data integration platforms, data warehouses, and data analysis tools.
Your biweekly inspiration delivered to your inbox
Join our newsletter for news, tips, and blog posts on anything data integration!
Subscribe
 Please fill out this field
 Thank you! You have been subscribed.
Similar posts you might be interested in
[](https://www.peaka.com/blog/saas-ideal-customer-profile/)
Data February 05, 2024
[How to Create an Ideal Customer Profile for SaaS Businesses](https://www.peaka.com/blog/saas-ideal-customer-profile/)
How do you create an ideal customer profile (ICP)? Why should a SaaS company create one? How does Peaka help you hone your ICP? Find out in this blog post.
Bruce McFadden Peaka / Seasoned Taskmaster
[](https://www.peaka.com/blog/account-based-marketing-saas/)
Data February 05, 2024
[How to Create an Account-Based SaaS Marketing Strategy](https://www.peaka.com/blog/account-based-marketing-saas/)
Here is everything a SaaS founder needs to know about account-based marketing, how it works, its benefits, and how Peaka can help ABM teams implement it.
Eugene van Ost Peaka / IT Soothsayer
[](https://www.peaka.com/blog/top-saas-revenue-metrics/)
Data February 05, 2024
[Top 6 SaaS Revenue Metrics to Track in 2026](https://www.peaka.com/blog/top-saas-revenue-metrics/)
A deep dive into SaaS revenue metrics, four data integration tools to track SaaS revenue, and benefits of blending your revenue data with your CRM data.
M. Çınar Büyükakça Peaka / Prolific Polemicist
 
Begin your journey today
Start your 14-day free trial to explore Peaka!
Get started for free
Enjoying this article?
Subscribe to our monthly newsletter for insights on ServiceTitan data integration and KPI reporting.


First Name
Last Name
Email
Company Name
Phone Number (optional)
Subscribe
You can unsubscribe anytime. For more details review our [Privacy Policy](https://www.peaka.com/privacy-policy/).
--- START: blog/data-integration-architecture /data-integration-architecture .md ---
# **From ETL to Zero-ETL: A Guide to Data Integration Architecture**
Organizations have finally woken up to the fact that they are sitting on a heap of data that’s growing by the second. The real challenge is to access, unify, and harness this data and turn it into information that can guide decisions. Tackling this challenge requires a well-thought-out data integration architecture in place.
Data integration architecture is a blueprint depicting how different data sources, pipelines, data warehouses and lakes, transformations, and data management activities work together to enable an organization to access, unify, and make sense of its data. It is the foundation on which every data-related activity within a company takes place. Therefore, the type of data integration architecture chosen comes to determine how well a company can leverage its data.
For the uninitiated willing to understand how modern data stack works and where it comes up short, our article titled [What is the Modern Data Stack?](/blog/what-is-the-modern-data-stack/) would be a good primer. Now, let’s dive into data integration architecture and why it matters for an organization.
## **What is data architecture?**
**Data architecture refers to the overall framework that governs the acquisition, storage, management, and utilization of data across an organization.**
It encompasses the technologies, tools, processes, and best practices that ensure data integrity, accessibility, and alignment with business objectives.
**Data integration architecture**, therefore, serves as a sub-discipline within this overarching framework, specifically focusing on the seamless movement of data between disparate systems.
It's the detailed wiring connecting your CRM system to your marketing automation platform, your customer databases to your financial records, and your website analytics to your operational dashboards.
### **What are the components of data integration architecture?**
Understanding the key components data integration architecture is crucial for implementing a robust system.
These components work cohesively to ensure the smooth flow of data through diverse nodes in an organization:
### **1. Data sources**
Data integration begins with identifying and connecting various data sources. These sources can include databases, cloud applications, APIs, flat files, and more. The architecture must support a diverse range of sources to accommodate the modern data landscape.
### **2. Data storage**
Once data is collected, it needs to be stored appropriately. Data integration architecture includes a storage layer that can be a data warehouse, data lake, or a combination of both, depending on the organization's needs.
### **3. ETL processes**
Extract, Transform, Load (ETL) processes are the heart of data integration. These processes ensure that data is extracted from source systems, transformed into a suitable format, and loaded into the target storage. ETL tools are a vital component of this stage.
### **4. Data transformation**
Data often needs to be transformed to meet the requirements of the target system. Transformation processes within data integration architecture handle tasks such as data cleansing, normalization, and enrichment to ensure data quality and consistency.
### **5. Data movement**
Efficient movement of data between systems is critical. The architecture must facilitate secure and seamless data movement, whether in real-time or batch processing, depending on the organization's needs.
### **6. Metadata management**
Metadata, or data about data, is essential for understanding the context and meaning of the information being integrated. Effective metadata management is a key component of data integration architecture, aiding in data governance and compliance.
## **What are the benefits of a sound data integration architecture?**
{{ resize_image(path="../static/assets/images/blog-images/flatart/saas-written-floor-and-laptop.png", width=780, height=518, op='fit_width', alt='man working on laptop and saas written in the back') }}
Investing in a well-designed integration architecture brings forth a plethora of benefits that go beyond mere data accessibility. Here are some key advantages:
### **Unified view of the customer**
Integrating data from disparate sources eliminates data silos and helps form a holistic understanding of your customers. This unlocks powerful insights to improve customer experience and drive targeted marketing campaigns.
This is where Peaka comes into play! With its many [integration](/integrations/) options, Peaka helps you bring together and make sense of your data in one place!
### **Enhanced operational efficiency**
By automating data exchange between systems, a robust data integration architecture eliminates manual data manipulation and streamlines workflows. This translates into reduced operational costs and faster time-to-insights.
### **Data-driven decision-making**
By providing access to unified and high-quality data, a well-designed data integration architecture empowers informed decision-making across all levels of the organization. From strategic planning to daily operations, every decision can be backed by actionable data insights.
### **Improved agility and adaptability**
Resilience is the ultimate attribute organizations can hope to have in the face of uncertainty. Adaptability is how you develop that resilience. A sound data integration architecture ensures that your organization will be able to leverage different data sources and scale its operations without effort when needed.
### **Boosted productivity and collaboration**
Breaking down data silos fosters collaboration between teams. With access to the same unified data, departments can work together more effectively, leading to improved productivity and innovation.
## **What are the different types of data integration architecture?**
Data integration architecture comes in various types, each catering to specific organizational needs:
### **1. Enterprise service bus (ESB)**
ESB architecture acts as a middleware layer facilitating communication and data exchange between different applications. It ensures seamless integration and scalability in complex enterprise environments.
### **2. Hub-and-spoke integration**
Hub-and-spoke architecture involves a central hub that connects with various spokes (applications or systems). This centralized approach simplifies management and enhances data governance.
### **3. Data pipeline**
Data pipelines provide a structured way to move data from a data source to a target destination. This method involves a series of steps through which data is discovered, cleaned, prepped, transformed, and loaded to its destination. Once built, data pipelines ensure efficient movement of data as long as it adheres to a strict data model.
The downside of this method, however, is the continuous monitoring and costly maintenance required from expensive data teams. Therefore, data integration architecture based on data pipelines are not ideal for startups and SMBs that lack the resources to hire data teams.
## **New techniques and concepts in data integration architecture**
In addition to the traditional methods listed above, there are new approaches to data integration architecture that are revolutionizing the field:
### **Data virtualization**
This technique eliminates the need for data replication, allowing data to remain in the source systems. The data is assembled from distributed sources at query time, providing a unified “virtual” view without physical replication.
### **Logical data warehouse**
This approach combines physically persisted data with virtualized views of data. A logical data warehouse offers flexibility by allowing high-value data to be moved into a warehouse while virtualizing less frequently used data.
### **Query federation**
This method is a subset of data virtualization and allows for retrieving data from distributed data sources with a single query. It achieves this by leveraging connectors and drivers and removing the need to physically move data into a central repository.
### **Zero-ETL**
This is another technique that relies on data virtualization to eliminate labor-intensive data pipelines. By keeping the data in a single environment, zero-ETL makes data available for business analytics and facilitates near-real-time reports.
These novel methods offer users significant advantages:
### **Less physical movement**
Unlike traditional ETL-based data architectures, data virtualization, logical data warehouses, and query federation reduce the need to move data from one repository to another. This translates into less need for maintenance and less workload for engineering teams.
### **Near real-time integration**
The lack of ETL pipelines means that data can be retrieved in near real time. This advantage helps improve decision-making as it allows business teams to act upon up-to-date data.
### **Enhanced flexibility**
Organizations using federated and virtualized architectures can easily add new sources to existing systems. This allows organizations to maintain a single source of truth without letting data silos form.
## **How Peaka approaches data integration architecture**
The current paradigm in data integration architecture emerged to cater to the needs of enterprises with thousands of employees and abundant resources to employ large IT departments. As a result, it is capital- and labor-intensive, which was no problem since this particular type of user had the resources to invest in expensive infrastructure and hire data teams.
However, the rise of the startup economy changed the picture. These small companies with limited runways could not afford to use the same data integration architecture as enterprises, but they were forced to do so because there were no viable alternatives.
Cognizant of the [data integration](/blog/benefits-of-data-integration/) pains of these smaller organizations, Peaka has used the data virtualization technology to develop a purpose-built solution for startups. Peaka’s [zero-ETL](/blog/zero-etl-vs-modern-data-stack/) approach to data integration removes the need for complex transformation processes and brittle data pipelines, allowing startups and SMBs to bring their data together without the need for costly data teams.
Peaka goes the extra mile in lowering the technological barriers for startups and offers a wide array of ready-made connectors. These connectors enable one-click integrations with the most popular SaaS tools, helping startups build their data stack in minutes instead of months and query their data from its source in real time.
To save time and minimize errors while querying data, Peaka users can use the platform’s embedded ChatGPT capability to run SQL queries using natural language. After forming new data sets from their consolidated data, users can connect these data sets to other systems and applications through APIs.
Peaka redefines data integration architecture for startups striving to stay ahead of the curve and make data-driven decisions without breaking the bank.
## **Final thoughts**
Investing in a sound data integration architecture is one of the best decisions a startup can make, as this investment ensures that the startup’s data operations will remain scalable in the future. After a decade spent trying in vain to adapt enterprise solutions to startup problems, startups can finally enjoy built-to-purpose solutions that take into account their resource constraints.
Techniques and concepts such as data virtualization, [logical data warehouse](/blog/logical-data-warehouse/), query federation, and zero-ETL have emerged as the perfect options for the data integration needs of startups. These methods differ from conventional enterprise solutions as they don’t require an upfront investment in a new data stack or expensive maintenance teams. They provide the lightweight data integration architecture a startup needs without straining its budget and offer the best bang for the buck. Startups taking advantage of these methods will start making better decisions and gain a significant edge over their competitors.
--- START: blog/data-integration-misconceptions/data-integration-misconceptions.md ---
# **Top 3 Misconceptions about Data Integration Platforms**
ETLs, ELTs, data mesh, data fabric, logical data warehouse... These concepts have been making the rounds for the last few years, but they don't seem to resonate much with the community outside the enterprise segment. As a result, data integration has remained mostly an enterprise-only affair, with companies failing to tap into the startup and SMB markets.
Maybe tech companies did not make a strong enough push to expand into other segments, but startups and SMBs looked hesitant to explore the possibilities on their own as well. What has kept them from showing more interest in bringing their data together? We investigate the common myths surrounding data integration and reveal why they do not hold water.
## **"*We have too little data to worry about data integration*"**
This is the lie most startups and SMBs tell themselves to justify their inaction. These organizations do not have a fraction of the data enterprises have to deal with every day. However, the smaller volume of data does not change the fact that whatever data you have will be the basis for your decision-making. Your employees still need access to accurate, complete, relevant, and timely data regardless of the size of your operations.
Additionally, implementing a data integration plan has very little to do with where you are in your startup journey. Hence, “[it’s too early for us to think about data integration](https://insidebigdata.com/2019/09/14/data-integration-myth-busting-dont-let-these-4-misconceptions-hold-you-back/)” is not a good excuse. The more you postpone the data integration issue, the bigger the problem will be in the future. When you finally decide that you finally have enough data to justify a data integration strategy, you will realize that you are sitting on top of data silos.
The life of a founder is full of moments where he needs to make important decisions, reevaluate previous ones, and look for trends in data. Data scattered far and wide over spreadsheets and SaaS tools that don't talk to each other poses another challenge for a founder. Not having a single view of truth undermines decision-making, cripples product development, and costs time and money—two resources a startup can ill afford to waste. Even simple periodic reports will take much longer to produce than they should when data is fragmented. That's why data integration should be on the agenda right from the start, and the data infrastructure should grow with the startup.
## **"*We don’t have the resources for it*"**
The decision on data integration usually comes down to building it in-house or buying it off-the-shelf. Both options are prohibitively expensive for startups and SMBs, which causes inertia to set in. As a result, decision-makers choose to do nothing.
Building a data integration infrastructure in-house requires a talented IT team and a lot of time to design for the integration needs of different users. The in-house solution takes an ongoing effort to establish governance procedures, rebuild broken data pipelines, and uphold security, which might be more than most SMBs signed up for.
The alternative is to buy off-the-shelf, but it also has drawbacks. Most solution packages in the market cater to enterprise needs. They cost an arm and a leg while offering features a small organization would hardly ever need. Startups and SMBs need and deserve a purpose-built solution.
Luckily, the move toward data virtualization heralds a future where employees will be able to self-serve. [Data virtualization](/blog/data-virtualization-no-code/) allows startups and SMBs to lean on their frontline workers to bring together their data. By getting rid of labor-intensive transformation and minimizing maintenance, data virtualization eliminates the need for a large, expensive IT team. Therefore, startups and SMBs would be well-advised to follow the developments in the self-service data integration area. As innovations like zero-ETL or other no-code data integration approaches trickle down from the enterprise segment, new opportunities will come up for business owners who would like to be self-reliant on data integration.
## **"*A data warehouse is all we need*"**
For now, maybe. But a data warehouse cannot satisfy the data integration needs of an organization for long in this day and age. You may be happy with your data warehouse if your data is completely structured and arranged in rows and columns. But don’t hold your breath that it will remain that way in the future. [80 percent](https://www.delltechnologies.com/partner/ru-ru/partner/powerscale.htm) of data today is unstructured and growing at a rate of [30 to 60 percent](https://www.gartner.com/document/4012543) year over year. You can’t ignore the different formats data is stored in if you want to have a single view of truth.
A change in the game plan is necessary if we are to build a data infrastructure incorporating unstructured data. We are talking about a more dynamic environment where data flows in from a plethora of sources in various formats. Therefore, metadata, which describes the name, size, and type of data, becomes all too important. You either accept the challenge and look for ways to integrate all data you have, regardless of its location, or you neglect the need and settle for a small portion of the truth. The latter scenario is a recipe for disaster in a business environment where everyone strives to become more data-driven.
## **Conclusion**
It’s only natural that people have misconceptions about a technical and intimidating field like data integration. The tech industry has so far done little to correct those misconceptions. Data integration companies were comfortable serving enterprise customers, which employed technical teams that needed no education on why data integration matters. However, if we are to bring startups and SMBs into the fold, we should start by opening their eyes to their own needs first. Everything will fall into place once regular people realize the power of data and what they can do with it.
--- START: blog/data-marketplace-vs-data-catalog/data-marketplace-vs-data-catalog.md ---
# **Data Marketplace vs Data Catalog: What’s the Difference?**
You can have a best-in-class data catalog and still hear the same complaint from the business: “Great, we found it. Now, how do we actually use it?” That disconnect is why “data catalog” and “data marketplace” should not be treated as interchangeable terms. They solve different stages of the data lifecycle.
A data catalog is built for discovery and understanding: What exists, where it lives, what it means, and who owns it. A data product marketplace is built for consumption and sharing, as it turns raw assets into governed products people can request, access, trust, and reuse.
This post explains the difference, shows where each one stops, and helps you decide when you need both. If you want the foundational definition and examples of marketplaces, start with our pillar page “[What is a Data Marketplace?](/blog/what-is-a-data-product-marketplace/)”, then come back for the “vs” breakdown below.
## **Key takeaways**
+ A data catalog helps people find and understand data assets; a data product marketplace enables them to access, trust, and reuse governed data products.
+ If your pain starts after discovery (access delays, conflicting KPIs, repeated extracts), it’s likely that a data catalog is no longer enough for you.
+ A combination of a data catalog for metadata backbone and a data product marketplace for product packaging, streamlined access workflows, and visible trust signals.
+ Peaka helps teams publish governed, permissioned data products so consumption is self-serve.
## **The problem: Finding data**
Most organizations think their problem is “we can’t find data.” Often, the real problem is consuming data safely and consistently. Discovery is only the first step. After someone finds a dataset or dashboard, they still need answers to operational questions: Who can approve access? Which version is correct? Is this metric certified? How fresh is it? What happens if the schema changes next week?
Without a clear consumption path, teams fall back to workarounds. They export CSVs, copy tables into personal workspaces, or rebuild logic in spreadsheets. In addition to being inefficient, these methods also break governance. Policies may exist, but bypassing them for speed becomes tempting, leading to broken governance.
This is the gap between metadata awareness and usable value. Catalogs excel at the first part, but marketplaces are essential for the second. They facilitate packaging, access workflows, and trust signals that make compliant usage the norm.
## **Data catalog: What it does**
A data catalog is a system of record for metadata. It helps users discover assets across warehouses, lakes, BI tools, and pipelines, then understand what those assets mean. At its best, a catalog connects technical context (lineage, schemas, upstream sources) with business context (glossary terms, owners, descriptions, classifications). This is essential infrastructure. It reduces duplicate effort, improves documentation, and enables effective data stewardship at scale.
A catalog typically stops when a user attempts to take action. Catalogs rarely offer a complete workflow from discovering an asset to being able to use it. Access is often handled elsewhere through separate processes like tickets, manual approvals, or tribal knowledge. Trust is implied by documentation, not proven at the point of consumption. Even “certified” badges can become outdated if they are not backed by checks and operational ownership.
Therefore, the issue isn’t that catalogs are ineffective; rather, they are designed to excel at finding and understanding assets rather than delivering governed consumption as a workflow.
## **Data product marketplace: What it changes**
A data product marketplace transforms discovery into tangible results by treating data as a consumable end-to-end asset, not merely something to locate. The fundamental shift lies in the unit of value: moving from “a table" to a data product. Such a product is designed for reuse, featuring a clear purpose, defined interfaces (such as tables, APIs, and semantic models), version control, an owner, and quality and update standards. This productization is what makes consumption repeatable.
Next is access. A marketplace facilitates practical, governed access, where users can request access (or be auto-provisioned based on policy), approvals are captured in a workflow, entitlements are applied where data resides, and audits become straightforward. The experience is closer to “self-serve with guardrails” than “submit a ticket and hope for the best.”
Finally, marketplaces display trust signals at the decision point, such as freshness, quality checks, certification, ownership, SLAs, and usage context. This reduces debate and rework, guiding teams toward trusted products instead of quick, less reliable workarounds.
## **Data catalog vs data product marketplace**
The simplest way to differentiate is this: Catalogs specify “what exists,” whereas marketplaces focus on “how to use it safely.” Both are important, but they have distinct objectives and success measures. A catalog acts as a map, while a marketplace includes the store, checkout process, policies, and receipts.
Here’s a practical comparison you can use when explaining the distinction internally:
| Dimension | Data Catalog | Data Product Marketplace |
| :--------------------- | :------------------------------------- | :------------------------------------ |
| **Primary goal** | Discover and understand assets | Consume and share governed products |
| **Unit of value** | Datasets, tables, dashboards, metadata | Packaged data products with standards |
| **Governance** | Documented policies, classifications | Policies enforced through workflows |
| **Access** | Often external (tickets/manual) | Built-in request, approval, provisioning |
| **Trust** | Descriptions, owners, lineage | Freshness, quality checks, certification, SLAs |
| **Success metric** | “Can people find it? | “Can people use it repeatedly and safely?” |
If search and documentation are your main challenges, begin with a catalog. If issues revolve around access, trust, and reuse, you're already operating within marketplace territory.
## **When you need both**
In mature stacks, the best answer is not “catalog or marketplace.” Instead, both should be integrated seamlessly. Think of the catalog as your metadata backbone and the marketplace as your consumption layer. The catalog provides lineage, glossary alignment, technical discovery, and classifications. The marketplace builds on that foundation to publish products, enforce access workflows, and present trust signals in a user-facing way.
A healthy integration typically involves the marketplace retrieving technical metadata from underlying sources, often via the catalog’s metadata graph, and then generating product pages that link back to lineage and definitions. Certification in the marketplace should map to real checks and accountable owners, not static labels. Access decisions must translate into entitlements at the point of storage or delivery, ensuring governance is enforced where it matters most. Quality and freshness signals should update automatically, so trust does not rely on manual upkeep.
If you already have a catalog, the fastest path is to productize the top 10–20 most requested assets and publish them through a marketplace workflow.
## **Which one do you need?**
If a data catalog is working well, you will see faster discovery, clearer ownership, and fewer “unknown” assets. If you have outgrown a catalog-only approach, the pain shows up after discovery. Use the checklist below to self-diagnose. Checking five or more signs typically indicates that adding a marketplace layer is the next logical step.
### **Access and workflow**
+ Access requests take more than 48 hours on average
+ Users find assets, but do not know how to get permission
+ Approvals and audits are manual, inconsistent, or scattered
### **Trust and consistency**
+ The same KPI has multiple definitions across teams
+ “Certified” data is not obvious at the point of use
+ Data freshness and quality are not visible without asking someone
### **Reuse and scalability**
+ The same extracts are recreated every month
+ Teams build shadow pipelines or spreadsheets to move faster
+ Ownership is unclear, or the owners cannot support consumers
A data catalog improves visibility. A data marketplace improves the reliability of consumption. When trust and access become bottlenecks, you've crossed the point of optimal system design.
## **Common misconceptions**
### **“A marketplace is just a prettier catalog.”**
A better interface helps, but it is not the point. The difference is operational: Marketplaces showcase products, enforce access workflows, and highlight trust signals that influence real usage.
### **“We can do this with tickets and policies.”**
You can, at small scale. But tickets do not scale with demand, and policies do not help if they are not embedded in the workflow. When speed is prioritized, governance often gets neglected.
### **“Marketplaces are only for external monetization.”**
External sharing is one use case, but internal value is often greater and faster, as it provides fewer duplicated pipelines, faster analytics, and consistent, certified metrics across teams.
### **“If we have a marketplace, we do not need a catalog.”**
Most organizations still benefit from strong catalog capabilities for lineage and glossary management. The marketplace serves as the primary access point for consumption, not a substitute for metadata discipline.
If any of these misconceptions are driving your tool decisions, you may be solving the wrong problem with the wrong layer.
## **Practical next steps**
Start with a narrow, high-impact scope. Pick one domain where inconsistency and access delays cause major business pain: Finance metrics, customer 360, risk reporting, claims, or revenue operations. Target a single audience (analysts, product teams, compliance, or leadership) so you can measure outcomes quickly.
Next, define lightweight product standards for your first set of data products:
+ owner and escalation path
+ freshness standards and update schedule
+ automatic quality checks
+ certification criteria and review cycle
+ versioning and change communication
+ access policy (auto-provision vs approval workflow)
Then publish your first products through a marketplace-style experience featuring clear product pages, request or grant access, and trust signals that update automatically. Treat every access request and consumer question as product feedback, not as a one-off ticket.
## **Conclusion**
In the last few years, we’ve seen a flood of new terms emerge, such as data mesh, data fabric, logical data warehouse, semantic layers, data observability, data contracts, and now data marketplaces. That’s not just hype. It’s a response to a real shift.
Data has moved from a back-office byproduct to a shared, operational asset that more teams depend on, more often, with higher expectations for speed, trust, and accountability. In this new era, data catalogs and data product marketplaces solve real problems for modern enterprises. While the former helps users locate data, the latter turns datasets into governed products, streamlining access and making trust visible at the point of consumption.
If you’re ready to move from “we found it” to “we can use it safely,” [Peaka](/enterprise) is built for exactly that shift. It helps you turn datasets into searchable data products with shared definitions and granular access controls, so teams can consistently use and securely share governed data end to end.
[Book a demo](https://calendly.com/peaka/demo) to see how a data product marketplace can sit on top of your existing stack, adding permission-based discovery, product-level governance, and an AI-ready layer without disrupting current workflows.
--- START: blog/data-migration-methods/data-migration-methods.md ---
# **How to Choose the Right Data Migration Method**
Did you know, as per Bloor Research’s 2007 Data Migration Customer Survey, that more than [80 percent of data migration projects](https://curiositysoftware.medium.com/the-research-is-clear-too-many-migration-projects-fail-cff52b32e340) were either aborted or overran time and budget? Yes, you read that right! The figures may sound alarming but are true.
In our daily lives, moving data from one place to another requires just a simple copy-and-paste operation. However, things get pretty complicated when you have to transfer millions of pieces of data to a new system.
You need to migrate data to keep pace with the dynamics of the industry and technological advancements. Data migration also ensures enhanced cost savings, better accessibility, greater security, and improved compliance. However, it’s easier said than done!
Data migration comes with a lot of challenges. Identifying the right approach and solution is the key to success. Read on to explore everything in detail!
Firstly, let's understand the term ‘Data Migration’ and how it is helpful.
## **What is data migration?**
Simply put, data migration is the process of transferring data from one storage environment to another. It involves extracting data from the original source, transforming it into the desired format, and loading it into the new storage environment.
The process includes migrating data from one operating system to a new target system or moving applications and data from on-premises systems to the cloud platform. Moreover, it may even involve the migration of data from one application to another.
Data migration may appear pretty simple and straightforward. However, it isn’t! A lot of preparation and post-migration activities are essential to ensuring successful outcomes.
Check out this video for a quick intro into data migration:
{{ youtube(id="_7gmKYmzIpw") }}
## **Key takeaways**
- Data migration becomes as a necessity for organizations that are trying to move way from legacy systems.
- Data migration improves efficiency, lowers costs, enhances disaster recovery, and increases scalability.
- The process of migrating data is indeed intricate and demands careful preparation, planning, and execution for optimum success.
- Data migration is an opportunity to improve operations, future-proof your organization, and gain a competitive edge.
## **Data migration in numbers**
- The global market size of data migration is likely to reach [$33.58 billion](https://www.nextmsc.com/report/data-migration-market) by 2030.
- [66 percent of C-suite executives](https://www.oracle.com/a/ocom/docs/data-security-report.pdf) believe that security is among the top benefits of migrating data to the cloud.
- [30 percent of data migration projects](https://www.oracle.com/a/ocom/docs/middleware/data-integration/data-migration-wp.pdf) result in cost overruns, while 41 percent of projects end up with time overruns.
- Only [36 percent of data migration projects](https://www.forbes.com/sites/moorinsights/2021/03/15/overcoming-the-challenges-of-data-migration/?sh=7893f506427c) are able to remain within the set budget.
## **When is data migration essential?**
Overhauling and replacing the old systems is indeed the most common reason for data migration. However, there are several other situations when you may need to migrate your existing data into a new system:
- Upgrading data schemas or database management systems owing to the need for greater storage capacity.
- Minimizing operational costs by lowering the number of data hosting systems.
- Upgrading existing applications, hardware, and file formats.
- Setting up new data warehouses for reporting and analytics purposes.
- Shifting to the cloud computing environment from the on-premises systems.
- Removing data that is no longer useful for the organization.
- Consolidating diverse data sources following an acquisition or corporate merger.
## **Benefits of data migration**
Organizations stand to gain a host of benefits from successful data migration projects:
### **Improves business processes**
When you migrate data from the old systems to a new environment, you can easily streamline and improve various processes.
### **Enhances security**
Migrating data to modern platforms allows organizations to strengthen their security and protect their sensitive data against potential attacks and unauthorized access.
### **Ensures scalability**
Data migration provides companies with more space for their databases and makes scaling easier.
### **Easy data recovery capabilities**
Moving your data to the cloud offers you one-click data recovery and backup capabilities, saving time and labor.
### **Reduces storage costs**
Data migration enables organizations to avail themselves of the best services, and that too at a very competitive price.
## **Common mistakes made in data migration projects**
Before you proceed to identify the correct approach and strategy for data migration success, having an idea of common mistakes committed in data migration projects is a must. Make sure you take into account these six most common mistakes:
### **Lack of planning**
You may be tempted to get started with data migration without any prior planning. However, it isn’t a wise decision. Having a solid plan can actually save you hours during the data migration process.
### **Not involving the key stakeholders**
Irrespective of the size of the migration, there is always someone who is affected by the data you are moving. So, involving them in the process can increase the chances of success and prevent unnecessary disruption.
Track the key stakeholders and explain to them the need for data migration. Moreover, you can also clearly highlight the impact of the move.
### **Lack of expertise**
You need to have appropriate technical skills to ensure smooth data migration. With an incomplete understanding of data, you are likely to end up making costly errors, thereby exceeding the budget.
### **Inconsistent data**
Maintaining the consistency of the data can indeed be challenging. Especially when the data formats and structures of the old and new systems differ, it can be even more difficult.
### **Incorrect estimation**
Not estimating the time, effort, and cost accurately can complicate organizational endeavors. It may either lead to unavailability of resources or disrupt the operations of your business.
### **Inaccurate data backup**
Before you migrate data to the new system, keeping a backup is a must. However, inaccurate or incomplete data backup can be a serious threat to the organization. It will not only result in process failures but also loss of confidential and crucial organizational data.
## **Best practices to follow for successful data migration**
Following established best practices for data migration can save you significant time and effort. Let's take a brief look at some of them:
- Define and examine the data prior to migration.
- Before moving data, you need access to the source to understand what you are migrating and whether it will fit the target.
- Test and validate the migrated data properly.
- Prepare a solid data protection and backup plan.
- Properly allocate your resources for smooth operations.
- Hire specialists to run the data migration project and ensure optimum success.
## **Most popular data migration methods**
Migrating important and sensitive data isn’t a task to be taken lightly. Botched data migraton initiatives can cause issues like data loss, compatibility issues, business disruption, and downtime, affecting your overall business. That is why choosing the right approach matters a lot. Delve into the most prominent successful data migration methods below!
### **1. Big Bang data migration**
Do you have less time for data migration? Opting for the Big Bang of data migration can be an ideal solution. In this approach, you move data assets from the original source to the target system in just one operation. The overall process takes place within a short period of time.
This approach empowers organizations to complete data migration in the shortest time possible. You get to save a lot of time and effort.
A point to note here is that the source databases will remain down and unavailable until the migration of data is complete. Therefore, it is always a smart move to implement this approach during a holiday, when customers will not be using the application.
The Big Bang migration approach is suitable for small businesses working with a smaller amount of data.
#### **Pros**
**Simplicity of planning:** This data migration approach involves only one migration event. So, the planning process is pretty straightforward in comparison to the phased approaches.
**Immediate functionality:** After the migration is complete, the new system becomes completely operational. That means you can get access to all functionalities without having to wait any longer. The Big Bang data migration approach can be completed in much less time. It prevents the need to run both systems simultaneously for a prolonged period.
**Lower cost:** In this approach, the old and new systems do not run for an extended period of time. So, you can expect better cost savings in terms of support and maintenance.
#### **Cons**
**High risk:** In case something goes wrong during the data migration process, it can have a direct impact on the entire organization.
**Potentially disruptive:** The sudden change may be disruptive to business operations. Moreover, it requires significant downtime for a successful transition.
**Limited flexibility:** Making necessary adjustments to the strategy in the middle of the process isn’t possible. As a result, the issues identified later can be difficult and costly to fix.
### **2. Trickle data migration**
Trickle data migration is often referred to as iterative or phased migration, as it involves moving the data in different phases.
In this approach, the entire process is divided into sub-migrations. Each transfer comes with unique goals, scope, timelines, and quality checks.
During the migration process, both the old and new systems will run in parallel, and data transfer occurs in small increments. That means you need not worry about downtime. With this, keeping your customers happy with 24/7 application availability becomes simple and easy.
However, the iterative approach can consume a lot of time and may complicate the entire process. You need to keep track of which data has already been transported to the new system and which is yet to be sent. Moreover, you also have to ensure that data across both platforms is synchronized in real time and users are capable of switching between systems to access the required data.
The trickle data migration approach is suitable for medium and large organizations, as they cannot afford lengthy downtime.
#### **Pros**
**Minimal disruption:** Both systems will continue to operate during the migration. As a result, it can significantly lower disruptions to business processes. As you can make small changes throughout the process, it significantly minimizes the chances of failures.
**Flexibility:** This approach allows you to make refinements and adjustments to the strategies throughout the migration process.
**Easy management:** Smaller changes are easy to test, manage, and troubleshoot.
#### **Cons**
**Higher costs:** In this approach, you need to run both systems for an extended period of time. As a result, it can give rise to additional costs.
**Complexity:** Maintaining data synchronization between both systems can be resource-intensive and complex.
### **3. Lift-and-shift data migration**
Planning to transfer data to the cloud? Then lift-and-shift data migration is the most suitable approach. It reflects no or minimal changes to the data flow, multi-cloud architecture, and authentication mechanisms of the application.
When there isn’t any change required, you can easily lift the application from the source system and shift it to the new location. However, for optimum success, make sure to plan the cloud migration properly, keeping aspects like the computing, networking, and storage requirements of the application in mind.
#### **Pros**
**Speed:** In this approach, you do not have to dedicate time to code revisions or optimization. As a result, the migration can be completed in much less time.
**Minimal planning:** Planning a data migration can take up to one year. However, this approach requires the least amount of resources and strategy, thereby minimizing the need for extensive planning.
**Cost savings:** In this data migration approach, you do not have to pay for configuration or code changes. So, you can expect greater savings in the long run.
#### **Cons**
**Optimization issues:** Optimizing your legacy workload without any native environment resources can be challenging.
**Security risks:** This approach doesn’t allow you to examine potential weaknesses beforehand. Once in the cloud, the weaknesses can lead to security risks.
## **Choosing the ideal data migration solution**
With a plethora of data migration solutions available, selecting the right one can be confusing. Make sure to choose a solution that can effectively address the challenges of data migration. There are a few key capabilities you need to consider:
### **Adequate connectors**
The data migration solution should enable the source and target databases to be well connected through a variety of file types and heterogeneous sources.
### **Portability**
The data migration process of the solution needs to be functional and portable in all compatible environments, ensuring optimum convenience for ongoing migrations.
### **Convenient data mapping**
Look for an intuitive solution that comes with a graphical user interface. It will make it easier for you to visualize the entire data migration process.
A solution with drag-and-drop and a code-free GUI can easily map the source and target data. Moreover, it will completely eliminate or, at least, reduce tedious efforts during the data migration process.
### **Data integrity**
The solution you choose must be able to factor in the orchestration of the relevant tables and migrate data accordingly to ensure that the records of tables in the source and target systems are in sync.
### **Data reconciliation report**
The solution should provide detailed performance statistics on the volume of data migrated, its completeness, accuracy, and more, offering in-depth insights into the efficiency of the overall data migration process.
## **Data migration content to consume**
- Video–[Maximizing Efficiency: Data Migration and Mapping Insights from a Business Analyst and Scrum Master](https://www.youtube.com/watch?v=P6qC2ksDPRo)
- Podcast—[Data Migration Best Practice – Overcoming Persistent Missteps](https://podcasts.apple.com/za/podcast/data-migration-best-practice-overcoming-persistent/id1541321209?i=1000577093090)
- Article–[What is Data Migration?](https://www.ibm.com/topics/data-migration)
## **Conclusion**
Digital transformation may require businesses to move data to modern systems. Successful data migration necessitates careful planning and execution. You can choose between Big Bang, trickle, and lift-and-shift approaches for effective migration. Moreover, make sure to select the right solutions to perform the move in a hassle-free and convenient manner.
Recent developments in data integration technology have made techniques like data virtualization available to solve data migration problems. [Data virtualization](/blog/data-virtualization-no-code/) introduces a semantic layer over distributed data sources and enables access through SQL, REST, or GraphQL. By eliminating the need to replicate and move data, data virtualization creates a single view of truth without the hassle of data migration.
Peaka takes data virtualization to another level and puts an end to the data sprawl problem that results from data migration projects. Its zero-ETL approach makes data integration possible without any data warehouses, complex data pipelines, and expensive data teams involved.
[Book a free demo](https://calendly.com/peaka/demo) and discover how Peaka can simplify your data migration project!
--- START: blog/data-migration-post-merger/data-migration-post-merger.md ---
# **How to Simplify Post-M&A Data Migration Projects**
Mergers and acquisitions (M&As) result in a situation where many of the participating companies' assets must be combined: Workforce, tech stack, physical inventory, and data. Data integration and migration are needed to combine the two companies' data. In this blog post, we will take a look at how this process works and the steps that can be taken to ensure that it achieves the intended goals.
## **Trends in mergers and acquisitions (M&As)**
Mergers and acquisitions (M&As) tend to have a cyclical character that is closely related to macroeconomic changes. While periods of reduced economic activity, like the early 2000s recession and the 2007-2008 financial crisis, caused a sudden drop in M&A deals, times of economic growth and optimism, like the mid-2000s and 2010s, saw an uptick in M&As.
[A survey by Deloitte](https://www.telecomreview.com/index.php/articles/reports-and-coverage/4227-mergers-and-acquisitions-an-opportunity-for-telecom-companies) revealed that three main reasons drive most M&A deals:
- Technology acquisition
- Growing the market share
- Diversifying the products/ services being offered.
Besides these reasons, dealing with uncertainty can be another one leading to more M&A deals.
2021 saw the peak in global M&A activity, with [58,308 deals amounting to more than $5.2 trillion](https://imaa-institute.org/mergers-and-acquisitions-statistics/). These figures denote a 23 percent increase from the number of deals in 2020 and a whopping 60 percent increase from the total amount of deals in the same year.
This surge was a result of the pandemic's impact on the global economy. Faced with unprecedented levels of uncertainty, companies chose to join forces and combine capabilities to weather the storms. For many firms, though, being acquired was simply the only option as they lacked the resources to overcome the challenges imposed by the pandemic.
In addition to the Covid-19 pandemic, another factor in the increase in the number of M&A deals was the recent proliferation of startups. Investors poured billions of dollars into tech startups over the last decade as these companies offered high returns at a time when interest rates were low. The ones that survived among these startups became attractive acquisition targets for bigger companies and tech giants, which were looking for convenient ways to plug holes in their product ranges and acquire new capabilities as quickly as possible. Apple was particularly ambitious in its acquisition strategy in this period, acquiring close to [100 startups](https://www.cnbc.com/2021/05/01/how-apple-does-ma-small-and-quiet-with-no-bankers.html) in the second half of the 2010s.
The M&A activity subsided to a large extent after the peak in 2021. The number of deals in 2023 was just above two-thirds of what it was two years ago. The total value of deals was also less than half of what it was in 2021.
However, things are looking better in 2024. The boom in the number of AI startups has been driving this last upward trend. Determined to stay competitive in the AI race, tech giants are acquiring startups leveraging artificial intelligence in ingenious ways to solve problems: Cisco has made more than [20 AI-focused acquisitions](https://investor.cisco.com/news/news-details/2024/CISCO-LAUNCHES-1B-GLOBAL-AI-INVESTMENT-FUND/default.aspx) over the last few years. Apple made [32 acquisitions](https://www.cdomagazine.tech/aiml/ai-shopping-spree-apple-leads-charge-with-32-startup-acquisitions-in-2023) in 2023 alone, followed by Google with 21 deals and Meta with 18, signaling a consolidation of the market as the technology matures.
Check out this video on the possible trajectory of M&As in 2024:
{{ youtube(id="YNqnqJYXcYA") }}
## **Key takeaways**
- M&As are cyclical in nature and follow the ebb and flow of the economy.
- Taking stock of the data in two distinct companies, understanding the relationships between different data sets, breaking down data silos, dealing with legacy systems, and reconciling inconsistent data formats headline the major challenges in post-M&A data migration challenges.
- By virtualizing legacy data for later reference, companies can significantly reduce the amount of data to be physically moved from one storage location to another.
## **Mergers & acquisitions in numbers**
- According to Harvard Business Review, between [70 and 90 percent](https://hbr.org/2011/03/the-big-idea-the-new-ma-playbook) of acquisitions fail.
- 2024 saw a rebound in the number and total value of [mergers and acquisitions in the U.S.](https://imaa-institute.org/mergers-and-acquisitions-statistics/united-states-ma-statistics/), with 15,217 deals reaching a total value of $1.688 trillion.
- The total value of [mergers and acquisitions in China](https://imaa-institute.org/mergers-and-acquisitions-statistics/china-ma-statistics/) has declined by 71 percent since 2015, when it was $1.038 trillion, dropping to $306.14 billion in 2024.
- From 1985 to 2016, banking was the leading industry for mergers and acquisitions, with a total value of [$5.072 trillion](https://imaa-institute.org/mergers-and-acquisitions-statistics/ma-statistics-by-industries/) in deals.
## **Types of post-M&A data migration**
There are six main types of data migration, and any post-M&A data migration project will involve a combination of one of these main types:
### **Storage migration**
Storage migration refers to the process of moving data [from one physical storage medium to another](https://www.k2view.com/what-is-data-migration/). Most of the time, this is done to replace outdated storage equipment with something better performing. Examples of storage migration include moving from paper to digital documents or from on-premises systems to the cloud.
### **Database migration**
Database migration describes the process of changing the [database management system](https://www.capco.com/intelligence/capco-intelligence/mastering-data-migration-in-merger-and-integration-scenarios) (DBMS) altogether or adding a new database to the ones already in use.
### **Application migration**
Application migration occurs when an organization changes its [software vendor](https://www.zucisystems.com/blog/process-types-all-golden-rules-to-follow-for-data-migration/#6). Due to possible compatibility issues, companies try to avoid this as much as possible, preferring to upgrade their current software instead of switching vendors until a vastly superior option surfaces.
### **Cloud migration**
Cloud migration involves moving data [from on-premises systems to the cloud](https://www.altexsoft.com/blog/data-migration/) or from one cloud environment to another. While the first transition is driven by a desire to achieve scalability, flexibility, and increased accessibility, moving from one cloud vendor to another is usually motivated by cost concerns.
### **Business process migration**
Business process migration usually results from mergers and acquisitions or reorganization activities. These initiatives require moving [applications and business-critical data](https://itrexgroup.com/blog/what-is-data-migration-definition-types-process/) for optimized performance.
### **Data center migration**
A data center is the physical infrastructure comprising [servers, computers, network routers](https://softwaresupp.com/blog/data-migration), and other types of hardware. Data center migration involves the relocation of this infrastructure to a new facility or moving all digital assets to new servers and storage.
## **Post-M&A data migration challenges**
An M&A deal is one of the most complex transactions one can encounter in the business world. It involves integrating the various business functions of two distinct entities, in addition to the standard legal, financial, and personnel-related challenges found in any significant transaction.
One of the more challenging aspects of an M&A deal is the data migration needed to unify the data repositories of the companies involved in the deal. Post-M&A data migration refers to the process of transferring data from one environment to another in order to unify and harmonize data from the companies that are party to an M&A deal. It is a complicated process that involves taking inventory of the data the companies possess, transforming that data into the required format, and unifying it so the post-M&A entity enjoys a single view of truth.
### **Taking inventory**
The first challenge in post-M&A data migration is to find out where all the data is. Considering hundreds of different apps, software programs, and databases used by an enterprise nowadays, this task can turn into a massive project that can keep engineers occupied for months.
IT people should analyze the various data formats and decide how much of the data will be used by the post-M&A entity. Sifting through the different naming conventions practiced by organizations can really test patience as the data is being prepped for integration.
### **Data consolidation**
In 2023, an enterprise company used [473 SaaS apps on average](https://www.spendesk.com/blog/saas-statistics/). Add to that number all the spreadsheets, databases, and legacy systems in use, you are looking at more than a thousand data sources for most companies. The problem is these data sources will act as data silos unless you can make them talk to each other.
Data silos are a scourge on organizations and have to be dealt with properly after an M&A because:
- They damage [data integrity](https://www.talend.com/resources/what-are-data-silos/), resulting in fragmented data. Unless synced, this fragmented data causes multiple views of the same phenomenon, which reduces the [searchability and discoverability](https://datavid.com/blog/why-are-data-silos-problematic) of the data.
- Data silos come with individual [storage, maintenance, and management](https://estuary.dev/why-data-silos-problematic/) requirements, which drive up the costs. The redundant effort different departments expend to work with the same data brings about inefficiencies in allocating human resources.
- Data silos limit collaboration between teams. Working with different versions of the same data creates inconsistencies in analyses and makes it difficult to pursue organizational goals. Productivity takes a plunge when precious time is spent searching for data across different systems.
- Decision-makers lack a single view of truth in organizations where data silos are prevalent. Without deeper insight into daily operations, they cannot make data-informed decisions.
### **Handling legacy systems**
Companies tend to have various software programs that they have been using for decades. Despite being state-of-the-art at the time of their launch, these legacy systems become obsolete over time, making it difficult for companies to operate and maintain them.
Managing legacy systems becomes particularly problematic after an M&A deal as companies find it hard to tap into the data stored in different on-premises systems. Integrating these systems can be quite challenging. Decision-makers would be well-advised to first pick which systems to integrate and which to sunset as the benefits of data migration, in some cases, may not justify the efforts.
### **Reconciling inconsistent data formats**
Enterprise data tends to be structured in widely different ways depending on the departments and what the data is for. This variety has significantly increased over the last decade with the boom in the amount of data being produced and newly-introduced formats aiming to make the storage and transfer of data more efficient.
This sea change has made post-M&A data integration and migration even more complicated than they were before. Cleaning and prepping the data in various formats and changing the data format to ensure that it maps to the target schema used by the destination platform requires hundreds of hours of engineering work. This is no easy thing to do, considering that IT departments are already stretched thin by having to oversee daily operations and maintenance work.
## **Post M&A data migration best practices**
New technologies have revamped the way data migration is implemented. Cloud, AI, and machine learning are here to help engineers with labor-intensive tasks in the process. AI-powered automation tools can fast-track data mapping between the source and the destination, data transformation, and data validation processes.
Another trend that helps with data migration projects is [containerization](https://cloudnativenow.com/features/migrating-applications-to-containers/). With software packed in containers, migrating applications from one environment to another becomes a breeze. A container holds an application with all its dependencies in a self-contained unit, making the application more portable and eliminating the concerns that it may not perform in another environment.
Here are seven best practices you should follow for successful post- M&A data migration:
### **Run an audit of your data, applications, and systems**
Any data migration project should start with an audit of [systems, software licenses, and hardware](https://rivery.io/data-learning-center/data-migration-best-practices/) at hand. A data migration project can serve as a good cut-off point to get rid of underperforming legacy systems, unused applications, and obsolete hardware. Simplifying the tech stack prior to data migration can reduce complexity, minimize the risk of errors, and accelerate the project.
### **See data migration as a company-wide process**
Data is a shared asset for an organization. Therefore, it is critical to talk to the stakeholders across different departments about the scope of the changes they can expect and their [required deliverables](https://etlsolutions.com/a-six-stage-process-for-data-migration/) while giving them the chance to provide feedback. Talking to the actual users of departmental data can be a good source of insight for IT people as they work to decide which systems, applications, and data sets to migrate and which to sunset.
### **Clean the data**
Corporate data gets corrupted over time as people work on it, convert it from one format to another, and generate copies of it. Incorrect and corrupted pieces of data should be removed before the start of a data migration project. Make sure that the data you are going to migrate is of high quality, that is, correctly formatted, accurate, complete, and relevant.
### **Back up your data**
Companies should ensure that reliable copies of their data are ready before the migration starts. These copies will be used to restore the systems in case something goes wrong. Extra care should be taken while taking backups of business-critical and sensitive data.
### **Do not upgrade your systems during data migration**
Any updates to the systems and applications should be done before the data migration starts. Updating the systems during the migration can cause [compatibility issues and data loss](https://www.techrepublic.com/article/data-migration-best-practices/).
### **Follow a phased approach**
A one-and-done type of data migration can disrupt daily operations. A phased approach with goals set for the end of each phase makes data migration more manageable. Migrating the critical applications first, like IBM did after it [acquired Red Hat](https://www.appletechsoft.com/data-migration-best-practices-for-merging-companies-and-acquisitions/) in 2019, performing the migration in stages, and running tests at the end of each stage help contain possible problems and prevent compounding effects.
### **Establish a framework for data governance**
Providing governance and guidelines before, during, and after a data migration is key for resolving problems. [Data governance frameworks](https://medium.com/@williamsmth22/unlocking-the-power-of-data-integration-best-practices-for-legacy-system-migration-in-m-a-caf637cabb67) enable organizations to determine the rules of data ownership, lay out how data is to be created and consumed, and describe the data management practices to be followed. By ensuring that data is complete, consistent, accurate, relevant, valid, timely, and unique, data governance upholds [data quality](/blog/data-quality-dimensions/) throughout the data lifecycle.
## **Using data virtualization to simplify post-M&A data migration**
Today, most data migration projects involve moving databases, data warehouses, and analytical workloads to the cloud. Companies prefer [migration to the cloud](https://www.datamanagementblog.com/easy-database-migration-with-data-virtualization/) because they want to achieve scalability, reduce costs associated with operating on-premises and legacy systems, or start using cloud-optimized platforms.
[Data virtualization](/blog/data-virtualization-no-code/) is an interesting option that can be used in combination with data migration or replace the latter completely in some cases. Data virtualization establishes a virtual layer over diverse data sources and facilitates data integration without having to copy or move the data. It makes it possible for organizations to unify their fractured data without any [back-end processes](https://www.infoworld.com/article/3628448/how-to-screw-up-data-migration-to-the-cloud.html) to restructure the data and helps keep complexity low without burdening the IT people with ever-growing maintenance responsibilities. Thanks to data virtualization, users can query the data in different formats regardless of where it resides. This capability enhances [accessibility and usability](https://www.linkedin.com/advice/0/what-most-innovative-approaches-data-migration-lldmf), making it easier to run an audit of the data assets, catalog them, and analyze the relationships between them before starting a data migration project.
Most organizations follow the well-trodden path of establishing [point-to-point integrations](https://www.mulesoft.com/resources/cloudhub/mergers-acquisitions-it-integration) between different data sources during a post-M&A data migration. However, this decision is usually wrong, as each point-to-point integration entails custom coding, which is hardly practical in an enterprise with hundreds of different applications. Building those integrations one by one is a challenge for any enterprise, regardless of the size of the IT department. Maintaining them for years to come is a whole other story.
Like [technical debt](/blog/no-code-pays-down-tech-debt/) swept under the rug until it becomes too difficult to ignore, there comes a point where point-to-point integrations start to break, and IT teams become overwhelmed with maintenance tasks. Each new integration added to the system [increases complexity exponentially](https://www.mulesoft.com/resources/esb/eliminating-point-point-integration-pain-mule-esb-use-cases) and requires refactoring of existing components for smooth operation. Things can easily spiral out of control under these conditions, leaving the IT department paralyzed within a few months.
Data virtualization eliminates the need to build point-to-point integrations between systems, applications, and databases that are so commonly used to stitch systems together in a post-M&A data migration. It offers the flexibility needed in an enterprise environment where new components can be added to or removed from a system without disrupting other integrations.
In summary, data virtualization
+ Eliminates ETL pipelines and makes data available in real time, reducing time-to-insights,
+ Allows daily operations to run undisturbed during data integration,
+ Ensures that data models are in harmony without the need for physical transformation,
+ Reduces the cost of data migration and the infrastructure needed to integrate data after an M&A deal.
## **Post-M&A data migration content to consume**
- Video – [What Happens to Salesforce Data When You Acquire a Company?](https://www.youtube.com/watch?v=zyYg2Aa7XZw)
- Podcast – [Hub & Spoke | Assessing a Company’s Data Asset during M&A](https://open.spotify.com/episode/5p1DdjnDd1kk5wdmgyvYm8)
- Article – [IT Mergers & Acquisitions: A Guide for Seamless Migrations](https://sharegate.com/blog/it-mergers-and-acquisitions-a-guide-for-seamless-migrations)
## **Conclusion**
The increasing pace of digital transformation has made data migration inevitable for healthcare organizations. However, medical data migration projects can pose a significant challenge due to the complexity of the data landscape in such organizations and the rules and regulations at play. Adopting a systematic approach to medical data migration, leveraging specialized data migration tools, prioritizing data security and compliance, and following the rules and regulation go a long way toward successfully migrating data.
[Peaka](/) uses data virtualization to bring data together from a wide range of databases, data warehouses, SaaS tools, and APIs. Peaka’s innovative zero-ETL approach eliminates brittle ETL pipelines, allowing users to access and query data wherever it resides without any maintenance or data teams involved.
With Peaka, companies can virtualize their legacy data for later reference and migrate just a minimal amount of data, simplifying the gigantic task of data migration by multiple orders of magnitude.
[Book a free demo](https://calendly.com/peaka/demo) and discover how Peaka can simplify your data migration project!
--- START: blog/data-product-vs-dataset/data-product-vs-dataset.md ---
# **Data Products vs. Datasets: What “Productizing” Data Means**
If your organization is building a data marketplace (or even just thinking about it), a key question determines whether it becomes a durable capability or another short-lived portal:
What exactly are you publishing?
If the answer is “datasets,” you will eventually hit the same wall when users can locate data but cannot confidently use it without reinventing context, validation, and controls every time. A marketplace only works when its contents are designed for reuse.
That is what “productizing” data is all about.
This post clarifies the difference between a dataset and a data product, explains why the distinction matters most in regulated environments like banking and insurance, and provides a minimum specification you can adopt without turning it into a year-long governance program.
For a broader framing of the marketplace concept, start with our pillar page “[What is a Data Marketplace?](/blog/what-is-a-data-product-marketplace/)”, then come back for the “vs” breakdown below.
For a deeper dive into modern data concepts, check out our blog explaining the [difference between a data marketplace and a data catalog](/blog/data-marketplace-vs-data-catalog/).
## **Key takeaways**
+ A dataset is records. A data product is a reusable offering with ownership, meaning, reliability, and controlled access.
+ In banks and insurance, reuse fails when consumers have to re-interpret, re-validate, and re-secure data every time.
+ You can ship data products quickly with a minimum set of specs: Purpose, owner, definitions, SLA, quality checks, and access rules.
+ Marketplaces succeed when they publish products people can trust, not just artifacts people can find.
## **Why “dataset thinking” falls short in banks and insurance**
Financial services handle large amounts of data, and the fragility of the processes used to share it poses a significant challenge for these organizations.
+ Each team needs to reinterpret the data, as the same field name can mean different things across various lines of business, jurisdictions, products, or time periods.
+ They also must re-validate the data, since issues like freshness, completeness, and edge cases often only become apparent when something fails.
+ Additionally, teams must re-secure the data, as controls are applied downstream in tools, spreadsheets, and custom pipelines, leading to audit difficulties.
“Dataset thinking” falls apart at this point because, once you share a dataset broadly, the cost of safe reuse is borne by every consumer.
In banks and insurers, the consequences of unsafe data reuse are tangible, manifesting as:
+ Inconsistent regulatory reporting across departments
+ Duplicated anti-money laundering (AML), fraud, and risk procedures in parallel pipelines
+ Delayed decision-making due to a lack of trust in the existing datasets
+ Ongoing access reviews caused by controls implemented across various areas.
A dataset simply contains records. When dealing with large volumes, you need a reliability guarantee. A data product offers this guarantee.
## **What makes a data product?**
A dataset becomes a data product when you can quickly and confidently answer these questions:
1. What is it for?
2. What does it mean?
3. Who is accountable for it?
4. How reliable is it?
5. Who is allowed to use it, and under what rules?
So a practical definition looks like this:
A data product is a reusable data offering with clear ownership, business meaning, reliability standards, and policy-aware access, packaged for safe discovery and use by other teams.
Notice how this definition makes no mention of the tables users can query. That is necessary, but not sufficient.
A data product is not just “more data.” It is data with a service boundary, which establishes responsibility, standards, and controls that go with it.
## **The minimum spec a data product must have**
When teams say they are building data products, the gap is usually not technical. It is missing components that make reuse safe.
Here are the parts that turn a dataset into something other teams can adopt without calling you every week.
### **1. Business purpose**
+ Primary use cases
+ What it is not intended for
+ Well-defined scope
If a consumer can’t answer “Should I use this?” within 30 seconds, you haven’t productized it; you've just published a new dataset.
### **2. Meaning that survives handoffs**
+ Definitions of core concepts and important fields
+ Clear inclusion and exclusion rules
+ Assumptions and known limitations
In financial services, meaning must also survive time. If rules change (new product structure, new KYC policy, new claims categorization), the product should clearly reflect those changes.
### **3. Ownership and support**
+ A named owner specifying a team and an accountable person
+ A support channel showing consumers how to report issues, request changes, or ask questions
+ A lifecycle clarifying whether the data product is active, in review, deprecated, or replaced
Without ownership, products decay into “shared assets” that no one can safely depend on.
### **4. Reliability signals**
+ Freshness standards laying out how often the product is updated
+ Quality checks clarifying what is being monitored
+ Stability standards that determine how often the schema or logic changes
+ Operational signals indicating last refresh time, recent incidents, and whether quality checks passed
These signals make quality measurable, helping create a shared understanding of what “good” looks like and how drift is detected.
### **5. Policy and access rules at the boundary**
+ Who can discover it
+ Who can request it
+ What needs approval
+ How sensitive elements are handled (masking, redaction, restricted fields)
With access rules embedded at the product level, teams no longer have to repeatedly address security downstream or inherit untracked risk.
## **Data productization use cases in financial services**
Data productization turns operational feeds into reusable building blocks that teams can trust without having to reinterpret rules or reapply controls.
For example, KYC and onboarding data becomes a consistent status product that defines what “verified” or “pending” means, how statuses take effect over time, and how exceptions are handled, while separating identity attributes from anonymized signals.
AML alerts can be shipped with standardized stages, unambiguous closure outcomes, and built-in quality checks, so risk teams can measure throughput and effectiveness without exposing sensitive notes.
Dispute and chargeback data can be packaged with a shared taxonomy, cross-system mapping rules, and predictable arrival expectations, making it reliable for fraud strategy and customer experience reporting.
In insurance, underwriting decision factors can include model context, drift signals, and restrictions on sensitive attributes, enabling monitoring and oversight while keeping decision logic from becoming a compliance risk.
## **What to avoid in data productization projects**
For a quick test, give your “data product” to a new team and see if they can use it without a lengthy explanation. When it doesn’t transfer smoothly, it often gets stuck in a few familiar traps.
### **Trap 1: The “crowned table”**
The first trap is the “crowned table,” which refers to datasets labeled “gold,” “final,” or “official.” These datasets are trusted by everyone, despite the lack of a clear explanation for that trust. Over time, the rationale for trusting them changes quietly, edge cases emerge, and downstream teams start duplicating the data because they no longer feel confident building on top of it. The solution is to publish the dataset with a designated owner, clear definitions, visible quality checks, and a straightforward change policy, thereby making trust and responsibilities explicit rather than assumed.
### **Trap 2: The “single-purpose extract”**
The second trap is the “single-purpose extract.” It starts as a pragmatic pipeline built to answer one team’s urgent question, then gets promoted into a shared asset because it exists and seems useful. The problem is that it carries hidden assumptions tailored to the original use case, so it breaks or misleads when other teams apply it to different workflows. A better approach is to separate what should be reusable from what is team-specific by publishing a domain-level product and letting each team build local views on top of it.
### **Trap 3: “The dashboard is the product”**
The third trap is viewing the dashboard as the ultimate product. When definitions and metric logic are embedded within a BI report, the “truth” becomes tied to that specific tool, model, or even an individual analyst’s modifications. This complicates testing, governance, and reuse across workflows such as automation, risk monitoring, or downstream systems. To address this, the solution is to deliver the core metric set as a data product, complete with definitions and signals of reliability, and have dashboards serve as consumers of that data, rather than being the definitive source of truth.
### **Trap 4: “Just export it”**
The fourth trap is the “just export it” mentality. CSV files, emailed extracts, and one-off pulls feel fast, but they quietly bypass consistent controls and create data copies that you cannot track, revoke, or audit. Once distribution becomes informal, security and compliance quickly turn into guesswork, especially when sensitive fields are involved. The safer strategy is to enforce policy at the product boundary so people request access to the product itself and receive governed access, instead of receiving bespoke files that immediately escape your control.
## **How data products make a data marketplace actually work**
A data marketplace offers more than just simplifying data discovery; it also ensures secure, hassle-free data sharing.
That only happens when what you publish is:
+ Easy to evaluate (meaning and intended use are clear)
+ Safe to request (access rules are explicit, approvals are standardized)
+ Reliable to run on (freshness and quality are visible)
Data products create consistency by letting the marketplace operate as a repeatable path:
Publish → Govern → Consume → Monitor
If you publish raw datasets, the marketplace becomes a repository of tables. If you publish products, it becomes a collaborative environment.
## **Conclusion**
Data products package data in a reusable way to power operations, going beyond datasets that lack a clear purpose and ownership. With data products, you can scale self-serve analytics, operational monitoring, and AI initiatives using the same trusted building blocks without having to rebuild definitions and logic in every tool.
Peaka simplifies the data productization process, enabling you to turn existing datasets into searchable data products with shared definitions and granular access controls. You can then publish them into a marketplace organized by domain, category, and business use case.
[Book a demo](https://calendly.com/peaka/demo) to see how you can transition from datasets to data products in days.
--- START: blog/data-quality-dimensions/data-quality-dimensions.md ---
# **The 6 Dimensions of Data Quality Explained**
Most organizations today, from startups to enterprises, profess to be data-driven. Putting data at the center of the business operations and making data-informed decisions are sound strategic objectives, but they are easier said than done. Very few organizations seem to have grasped what that entails, let alone harness the potential of data to achieve business goals.
## **The enigma called 'data'**
Companies experience problems in leveraging data. [A report commissioned by Seagate](https://www.seagate.com/files/www-content/our-story/rethink-data/files/Rethink_Data_Report_2020.pdf) revealed that only 32 percent of data available to enterprises was properly used. The remaining 68 percent was left unexploited, showing us the extent of missed opportunities despite all the talk around data and its value.
The data organizations were able to use was not without flaws, either: A study conducted with [75 executives in Ireland](https://hbr.org/2017/09/only-3-of-companies-data-meets-basic-quality-standards) found that 47 percent of newly-created data records contained a work-impacting error. Only 3 percent of the organizations in the study scored 97 or higher error-free records out of 100.
What happens when data quality decreases? Confidence in analyses dependent on that data plunges; customers [lose trust](https://www.gartner.com/smarterwithgartner/how-to-stop-data-quality-undermining-your-business) in the organization; costs increase as more time and resources are expended, and the [reputation](https://www.experian.com/blogs/news/2021/02/25/highlights-2021-global-data-management-research/) of the organization takes a big hit.
Data is piling up at an ever-faster pace as you read these lines. Without a holistic and systematic view, no organization can keep up with that growth or tap the potential of data. Improving the quality of the data should be the first step in that regard. Such an endeavor should start with understanding the six dimensions of data quality:
## **Accuracy**
This dimension measures how well the data maps to reality. Compromise in this department can seriously hamper business operations. For example, suppose the bank account number of a customer asking for a refund is not correctly recorded in your database. In that case, the refunding process will take longer than it should. You can expect winning over that frustrated customer to be a formidable challenge.
## **Completeness**
This dimension refers to the data conveying enough information to make a [productive engagement](https://www.collibra.com/us/en/blog/the-6-dimensions-of-data-quality) possible. If you are running a pizza parlor and trying to improve your delivery performance, getting the customer address right without missing parts is the prerequisite. The data in question would be deemed complete if it allows business operations to go on smoothly, even without other details like the customer's gender or age.
## **Consistency**
Consistency refers to a situation where data stored in different locations matches. If two different departments like customer support and sales have different data for a customer's phone number, confusion ensues. The presence of hundreds of inconsistent data entries can paralyze business operations at a company.
Sorting out conflicting pieces of data can be a challenge. This is where data lineage comes into play. Understanding how data was moved from one location to the other and how it was transformed go a long way toward preventing discrepancies in data. That's why having a data governance policy in place is critical.
## **Validity**
Data is considered valid when it conforms to the predefined format requirements of a special domain and falls within the specified ranges. Different domains may require different formats for things like birthdays (MM/DD/YYYY in the U.S. or DD/MM/YYYY in Europe) or phone numbers (starting with either a zero or plus before the international dialing codes). Entries incompatible with the requirements are rendered invalid, providing no benefit to the data user.
## **Timeliness**
This dimension [refers to](https://icedq.com/6-data-quality-dimensions#what_is_timeliness_data_quality_dimension) the lag between the actual time of an event and the time it was captured as data on a system. While some bureaucratic jobs are insensitive to this lag or are even defined by using outdated data, some professions like air traffic controllers rely on real-time data. Organizations should define the maximum data lag they can tolerate and take necessary measures to ensure data is captured with acceptable promptness.
## **Uniqueness**
Uniqueness is about data being stored in a single location without any redundancy or duplication. It ensures that one identifier (for example, a name like James Thompson) corresponds to a single individual and that individual, in turn, is identified by a single identifier (strictly as James Thompson, not as "Jim" or "Jimmy"). Ensuring that data entries are unique prevents confusion. Verifying whether these two entries belong to the same person takes time and effort, making data processing needlessly difficult.
## **Final thoughts**
Any attempt at making data-informed decisions is doomed to be a futile exercise in trendiness so long as the data quality remains low. Improving the quality of data at hand and making sure that it is reliable, accessible, and up-to-date for the data users is the first step in transforming your organization into a data-driven one. How that can be achieved deserves another post in its own right.
--- START: blog/data-quality-tips/data-quality-tips.md ---
# **Top 4 Tips for Improving Data Quality**
Becoming data-driven is the trend everyone subscribes to nowadays. But other than being the cool thing to talk about, data is paramount to your company's success. Data quality impacts your bottom line.
The quality of your analyses suffers, and your decision-making falters when you work with low-quality data. The cost of acting on flawed data can be staggeringly high according to the [1-101-100 rule](https://www.makingstrategyhappen.com/the-cost-of-quality-the-1-10-100-rule/). Suppose you are verifying data as you enter it, and this costs you $1. Then, correcting inaccurate data after the fact will cost $10, and not correcting the data at all will set you back $100. Therefore, [being proactive](https://www.dqglobal.com/blog/why-data-should-be-a-business-asset/) in maintaining data quality makes much more financial sense than relying on correction mechanisms after the fact or accepting failure.
When you take the "correction" path and focus on fixing data errors after they occur, a few things happen: You lose time, incur high processing costs for the same job, and risk tarnishing your brand image. When you choose to do nothing at all in the face of poor data quality, then you basically accept to live with bad analyses and wrong decisions and guarantee that your reputation will be ruined in the long run.
So, being proactive in ensuring data quality data makes sense for many reasons. However, a single individual or a department cannot improve data quality on their own. This task cannot be left to the IT department. It takes a holistic, strategic view that encompasses every phase of the data lifecycle to improve the quality of the data. Here is how you should go about it:
## **Starting off: Plan, observe, measure**
You should define what success means at the outset. [Determine the metrics](https://www.techtarget.com/searchdatamanagement/feature/Proactive-practices-for-data-quality-improvement) you will use to measure data quality. Show your employees what high-quality data will look like. Map out how your organization is expected to achieve those metrics.
A good starting point would be to take an inventory of all the locations where data is stored within the organization. This catalog of data assets should identify all the sources and point out all the data lineages, underlining how data was aggregated, manipulated, or transformed.
Conduct a data audit (check out the [Friday Afternoon Measurement](http://hbr.org/2016/07/assess-whether-you-have-a-data-quality-problem), it offers a good template for the uninitiated). Bring together the last 100 records processed in your department or company. Identify a set of critical data attributes you need to focus on, evaluate each record for data errors, and determine the error-free ones. The number of perfect data records will be your Data Quality Score. This score will be a yardstick you will use to measure performance when you repeat the audit after you start implementing data governance policies.
## **Eliminate data silos**
Pay attention to data silos. A data silo is a [repository of data](https://www.techtarget.com/searchdatamanagement/definition/data-silo) accessible to a business unit but isolated from the rest of the organization. Most of the time, this data is stashed away somewhere in the organization, and most employees are not even aware of its presence. The possibility that there might be a pile of inaccurate, inconsistent, incomplete, obsolete, and redundant data which does not conform to predefined formats is enough to give any IT manager nightmares.
Data silos are caused not only by the organization's verticals but also by every single application used by the employees. Each application functions as a data silo unless it is integrated with others. The situation may be direr than any of us could have imagined. A recent [Mulesoft report prepared in collaboration with Deloitte Digital](https://resources.mulesoft.com/ty-report-connectivity-benchmark.html#loaded) found that organizations have an average of 976 discrete applications in 2022, an increase of 16 percent over the 2021 figure. The same report pointed out that only 28 percent of those applications were integrated. So, around 700 applications work on their own, serving as bonafide silos.
High-quality data has to be consistent and unique, as we touched upon during our discussion of the [dimensions of data quality.](/blog/data-quality-dimensions/) Data entries stored in different locations should match, and there should be no duplication or redundancy in what a data entry corresponds to. The mere presence of data silos breeds inconsistent and duplicate data. The elimination of data silos has a direct impact on data quality.
## **Establish a data governance culture**
Of all the definitions of data governance being thrown around, [this one](https://profisee.com/data-governance-what-why-how-who/) makes the most sense: A set of principles and processes that ensure high data quality throughout the data lifecycle.
However, like all policies that set out with lofty goals, data governance, too, needs to be connected to the realities of the field if it is to be successful. That's why you should make sure that the data governance policies and measures you introduced to raise data quality align with business operations. Employees will shun your suggestions unless they see how improved data quality helps their work and have a positive impact on their day-to-day activities.
Establish linkages between the improvement recorded in data quality and the actual business KPIs. For example, if your organization has achieved a 20 percent reduction in invalid customer phone numbers that do not conform to the predetermined format and your NPS increased by 10 percent in the meantime, that connection deserves emphasis. That kind of tangible, meaningful connection between policies and outcomes will motivate your employees to embrace a data governance plan.
## **Go for quick wins**
Establishing data governance is a long process during which lots of ideas will clash. There will be a lot of hearts and minds for you to win. That's why targeting the low-hanging fruit is key. Scoring quick wins in some areas will alleviate resistance and help promote new policies in the eyes of the stakeholders.
## **Final thoughts**
Upholding data quality is an ongoing process, just like quality management in the manufacturing industry is a never-ending endeavor. Data governance should permeate every major decision taken at an organization. Are you planning to hire for a vacant position? Not everybody you hire will be a data scientist. But recruiting people who are data-focused or capable of understanding the implications of being data-driven goes a long way toward establishing the right culture. Organizations do not become data-driven without integrating this mindset into every aspect of business operations.
--- START: blog/data-unstructured/data-unstructured.md ---
# **What is Unstructured Data?**
We had only structured data in the good ol' days, and it was pretty straightforward to deal with. That's no more the case: We have semi-structured and unstructured data to worry about today. We will ignore semi-structured data for the purposes of this blog post, but the latter is about to become the data for us. IDC predicts that the total data will amount to [175 zettabytes](https://venturebeat.com/data-infrastructure/the-new-metrics-for-unstructured-data-management/) by 2025, and 80 percent of that will consist of unstructured data. We are being bombarded by unstructured data, people.
Think about how many photographs you receive on WhatsApp or how many files you share daily with friends at work. Your favorite culinary channel on Youtube must have uploaded a few videos since last week, right? The surveillance cameras scattered all over the city keep recording nonstop. Hundreds of [satellites](https://www.pixalytics.com/earth-observation-satellites-2022/) flying over the Earth take snapshots of certain locations at regular intervals, creating terabytes of imagery per day. These are all various forms of unstructured data, and our civilization generates a staggering amount of it every day.
Understanding the nature of unstructured data, the mind-boggling increase in its volume, and its implications can be key to understanding some of the problems the tech industry is trying to solve nowadays. Without further ado, let's dive in.
## **Data yesterday**
The best days of structured data seem to be behind us. Most of the data we generated before the rise of cloud technology and the explosion of social media was structured. Structured data is arranged in a predefined format, most of the time in rows and columns. A relational database is a good example of this type of data which is formatted into fields such as "customer name," "age," "phone number," etc. This type of data [lends itself to SQL queries](https://www.talend.com/resources/structured-vs-unstructured-data/), can be stored in data warehouses and leveraged by machine learning tools, and has a large user base and a wide ecosystem built around it. However, its use cases and storage options are limited by its predefined purpose, rendering it rather inflexible.
Enterprise Resource Planning (ERP) systems were the stars of the corporate world in leveraging structured data and generating reports on business operations. These reports helped professionals keep an eye on the financials, sales performance, efficiency, and guided decision-making. It was a time when data was in fairly standardized formats and came from a limited number of sources. In today's world, where every person and every digital device has become a source of data in a plethora of different formats, on-premise ERPs can no longer be effective business intelligence tools.
## **Data today**
At the heart of business operations today is the drive to understand the way customers think and their motivations. Gone are the days when you just looked at financials and reports of how your business was doing to decide what you should do next. You need to be proactive today, and understanding the nature of unstructured data can shed light on how data needs to be used today.
Unstructured data is information communicated in different forms (audio, video, satellite imagery, text, etc.) and stored in wildly different formats. Thanks to its ability to convey information in so many different forms, it expands the definition of data and allows for faster data accumulation. That it can be dumped into data lakes makes its storage easier. However, the real challenge begins once data is stored.
## **Two challenges: Storage cost and the data interpretation problem**
Gartner reports that unstructured data is growing at a rate of [30 to 60 percent](https://www.gartner.com/document/4012543) year over year. Storing that much data brings about a huge data management problem. As the data stored grows, costs associated with it increase at an even greater pace because of all the [backup copies](https://venturebeat.com/ai/why-unstructured-data-is-the-future-of-data-management/) needed for data recovery. For organizations looking for efficiencies, optimizing data storage costs is paramount. Organizations should distinguish between actively-used data and data that is rarely accessed. Storing the latter in low-cost storage is a good first step in bringing down the cost of data storage.
Another challenge aggravated by the ever-increasing amount of data at hand involves analyzing the data and making sense of it. A simple content search conducted across unstructured data is not enough to unlock the potential of this precious source. Tapping into the wealth of information that can be gathered from unstructured data takes expertise. That's why data science has been one of the most popular fields for over a decade. You need data scientists and specialized tools to find out what kind of insights can be drawn from the terabytes of unstructured data your organization is sitting on.
## **Possible use cases for unstructured data**
The biggest gain that could result from unlocking the potential of unstructured data is the social listening ability it affords organizations. The Internet is choke-full of social media accounts, forums, and e-commerce websites where people keep talking about your brand and product all the time. Listening in on that chatter can reveal valuable insights about how people are using your product, what they like or don't like about it, and how it compares to rival products. Armed with this kind of information, companies become more agile, correcting mistakes on the fly, pivoting and changing course when needed, or doubling down without having to wait for the quarterly financial reports.
Unstructured data can also be used to boost [data mining](https://www.youtube.com/watch?v=5UH6PDPTbB4) practices, resulting in much better decisions. Tasks like credit risk assessment and insurance claims management would benefit from incorporating outputs from unstructured data into their business flow. An insurance company can employ ML to analyze a person's Facebook and LinkedIn pages to gain visibility into her travel and driving habits. This information can then be used to revise her car insurance premium for the upcoming year. Likewise, a bank can pick up on the high level of activity in a brand's social media accounts or capture insider gossip in an internet forum and learn about an impending product launch, which can significantly change the brand's credit standing.
Another wide-scale use of unstructured data involves analyses of digital communications to detect criminal activity or enforce [content moderation](https://www.youtube.com/watch?v=ADTPRTlWKE0) against online mobbing and harassment. Signals suggesting such actions are not out in the open: They are buried in the millions of discrete interactions between people. Audio files, surveillance camera footage, satellite imagery, and social media are fertile grounds for the kind of unstructured data that some people would like to keep hidden from the eyes of authorities. Unstructured data plays a prominent role even in international affairs nowadays. As the recent Russian invasion of Ukraine proved, analysis of unstructured data offers an endless amount of open-source intelligence (OSINT) information regarding troop movements, logistics, and possible war crimes committed.
## **Final thoughts**
Harnessing the power of unstructured data has been one of the biggest drivers of innovations in the software industry lately. The challenges regarding storage cost and making sense of huge amounts of data in a short time still remain. The hope is that artificial intelligence and machine learning technologies will help with those challenges once they are mature enough. Only then will we unlock the full potential of unstructured data.
--- START: blog/data-virtualization-no-code/data-virtualization-no-code.md ---
# **Data Virtualization with a No-code Touch**
The [challenges](https://www.tibco.com/reference-center/what-is-a-data-federation) of data management today are evident. The sheer amount of data needing storage, all the different data formats and the plethora of locations data is scattered over, the lack of data consistency… How to deal with those challenges is up for debate. The challenge becomes even more daunting when the data must be real-time. The conventional data architecture built around data warehouses can no longer deliver the results sought by data users.
The billion-dollar question is:
> “*Is data integration possible without a data warehouse?*”
In other words, can we integrate our data in real-time without having to copy and move it or invest in expensive hardware? Proponents of the data virtualization concept think that it is possible.
## **What is data virtualization?**
Data virtualization is a data integration technique that introduces a [semantic layer](https://www.denodo.com/en/webinar/modernizing-integration-data-virtualization?display) on top of a host of distributed data sources. This semantic layer can be accessed via SQL, REST, or GraphQL. In a sense, data virtualization merges all the different data sources into a single database users can access in real-time. The advantages of data virtualization are manifold:
## **Pros of data virtualization**
+ Real-time data availability is the biggest appeal of data virtualization. Data virtualization is based on the “[zero replication, zero relocation](https://www.denodo.com/en/webinar/data-virtualization-introduction-4?display)” principle: Data does not have to be copied, moved, or synced—all processes that take time. Data virtualization not only allows for access to real-time data but also minimizes the risk of data loss since data is not moved.
+ Data virtualization helps eliminate data silos and presents a single source of truth for everyone in the organization to draw their data from. This single source of truth provides the decision-makers with a holistic view of their data and makes it easier to receive buy-in from other stakeholders.
+ By not moving the data, data virtualization puts an end to the [data sprawl](https://www.gartner.com/document/4002921) problem. It stops data from continuously getting duplicated and modified in different locations without any syncing in between and thus prevents the degradation of data quality.
+ Data virtualization also empowers knowledge workers to self-serve—something Zhamak Dehghani envisioned with her “[data mesh](/blog/data-warehouse-vs-data-mesh/)” concept. Without an ETL process to curate data and prepare it for consumption, data consumers will no longer be reliant on an IT department overwhelmed by demand.
+ Finally, data virtualization replacing a data warehouse-based architecture removes the need to build and maintain data warehouses. Thanks to the lack of physical data integration in data virtualization, organizations do not have to invest in expensive hardware. Normally, adding new nodes to a data warehouse is a time-consuming process that takes a lot of work hours from highly-skilled personnel. With data virtualization, the process is straightforward, requiring no extra effort to reconfigure the system.
## **Cons of data virtualization**
+ While enjoying all these benefits brought to you by data virtualization, you are sacrificing data historicity. The data that this technique brings together and displays is just a snapshot. The lack of historicity prevents you from tracing the data back to its earlier version and tracking its change over time. Combining data with a data warehouse would overcome this hurdle if data historicity is indispensable to your organization.
+ Servicing a host of improvised data analytics requests from different users can put stress on the source systems, raising scalability issues. [Caching](https://datavirtuality.com/en/blog/data-virtualization-the-complete-overview/) can help compensate for the dip in performance in such cases, but it comes at the expense of a slight increase in latency.
+ [Downtimes of the source systems](https://medium.com/swlh/the-5-data-store-patterns-data-lakes-data-hubs-data-virtualization-data-federation-data-27fd75486e2c) may render data virtualization unusable. Therefore, a holistic approach to maximize source system uptime is required.
## **Data virtualization and Peaka**
Every organization, regardless of its size, needs to harness the power of data one way or another. You can be the founder, CEO, and product development team of your startup all at the same time, and you still must gather data to inform your decision-making. Current solutions in the market are optimized for the enterprise segment: They are good at managing a sophisticated data infrastructure and integrating massive amounts of data. They come at a considerable price, though. Therefore, these solutions are a bit of an overkill for the needs of startups and SMBs, which neither require such sophisticated capabilities nor possess the means to pay for them or maintain them.
In today’s hyper-connected world, data gets created in multiple locations, flows from one platform to another, and blends into other data. We at [Peaka](/) recognize the need for startups and SMBs to bring together data from various SaaS tools, whether it is Stripe, Zendesk, Twilio, Shopify, or Hubspot. The new version of Peaka allows you to access real-time data and consolidate it without copying or moving it. You can then query your data and execute the analytics tasks as you see fit.
The dreaded scalability issue is no longer a problem with Peaka. The scalability problems usually arise from the limited capacity of the APIs to service queries. When you send a query with Peaka, the platform caches your data for a few minutes just in case you may need it for further queries. The later queries you send during that time frame get answered from the cached data without putting any stress on the APIs.
In addition to the slick data integration, Peaka’s new version also allows you to automate tasks that you otherwise have to do manually every day. You can even create triggers for the scheduled batch jobs and access real-time data without paying for extra features that you will never use. For example, would you like to nudge the users on your e-commerce platform when they have items remaining in their shopping carts at the end of the day? What if you want to send an email to every user who quits the onboarding walkthrough on your app? Peaka takes care of such tasks with ease.
The true distinguishing aspect of Peaka lies in how it blends data integrations with app building. Our platform lets you build responsive web apps or internal tools on top of the data you brought together from different sources. Using data to improve decision-making makes you more efficient at work. Using it to create apps that can get things done has the potential to transform your whole business.
Peaka shows you the no-code way of harnessing the power of your data. Whether you will use it to generate reports, metrics, or tools that will give you a leg over your competition is up to you.
--- START: blog/data-visualization-with-looker-studio-integration/data-visualization-with-looker-studio-integration.md ---
# **Simplify Data Visualization with Looker Studio Integration**
Becoming data-driven is a two-step process: First, you must break down data silos and bring your data together. Then, you must employ the necessary tools to make sense of your data. The second step in the process entails business intelligence (BI) tools, and Peaka spent the 2024 summer launching integrations with some of the most powerful of such tools.
Our latest integration in the BI series connects Peaka with Looker Studio, Google’s data visualization tool catering to users looking for a simple solution to set up and use.
## **What is Looker Studio?**
Google’s naming convention for its products in the data analytics/BI space leaves a lot to be desired. The company has two products, Looker and Looker Studio, with different but complementary capabilities, but this inevitably creates some confusion among the uninitiated. However, they are clearly differentiated in their capabilities:
Looker is a data analytics platform that uses a modeling language (LookML) to define data relationships in a relational database. It was acquired by Google in 2020, and the tech giant positioned its new acquisition as an umbrella under which other BI products would be placed. Looker handles data modeling, harmonizes what different metrics refer to, and promotes a uniform understanding of data across an organization. By doing that, it ensures that different data users who look at a data point such as “monthly sales” understand the same thing.
Looker Studio, on the other hand, is how Google renamed Data Studio in 2022. It is Google’s answer to other popular data visualization tools, such as Tableau and Power BI, but with significant differences. It serves the BI needs of non-technical people and functions as the go-to data visualization solution within the Google ecosystem.
+ Looker Studio features an easy-to-use drag-and-drop interface. This makes it a popular choice among marketing and growth teams, who want to draw insights without much fuss.
+ It seamlessly integrates with tools in the Google ecosystem. Just like Power BI boasts native connectivity with other Microsoft products, Looker Studio offers hassle-free integration with Google Analytics, Google Ads, and BigQuery.
+ In addition to 21 connectors built in-house, the platform offers a collection of more than 1000 third-party integrations that are built and supported by its partners.
+ Looker Studio comes with 40 pre-made visualizations for basic data visualization tasks. Users needing more advanced charts and graphs can tap into the collection of visualizations created by Looker Studio partners.
+ Users can utilize LookML to define data relationships and create consistent data models that can be shared across the organization.
These features make Looker Studio a good option for business teams looking to generate reports and build dashboards without IT involvement. True, the platform lacks the endless customizability offered by some of its rivals. However, this lack of control over the minute details of a report's layout and appearance translates into ease of use and improved self-serve capability, which may be desirable in some use cases.
## **What is Peaka?**
Peaka is a data platform specifically developed to cater to the data integration needs of startups and SMBs. Lacking a purpose-built option in the market, these organizations usually have to pay for the modern data stack, which is overkill for their needs, or get by relying on spreadsheets.
Peaka turns data integration into a smooth, one-click process where users can aggregate data from distributed sources and expose their consolidated data to other applications. It currently serves two use cases as a zero-ETL data integration platform and a serverless connector infrastructure:
### **Zero-ETL data platform**
The extract-transform-load (ETL) process is the backbone of the modern data stack and is essentially what makes it inflexible, costly to run, and troublesome to maintain for startups and SMBs. Lacking the precious engineering hours needed to build and maintain ETL pipelines, these companies either end up paying for a solution they cannot utilize properly or resort to copying data from one spreadsheet and pasting it to another to unify their data.
Peaka’s [zero-ETL approach](/blog/zero-etl-vs-modern-data-stack/) approach relies on [data virtualization](/blog/data-virtualization-no-code/) to eliminate the transformation stage from the ETL process. It turns your data into virtual tables and removes the need to physically copy and move your data from one location to another. Thanks to this single virtual layer, you can query every data source, execute join queries on them, and form a single view of truth.
### **Serverless connector infrastructure**
Peaka not only simplifies data integration for startups but also helps them ship connectors at scale, giving them a serverless connector infrastructure.
One of the most formidable challenges keeping startups from gaining traction is the sheer number of connector requests they receive from prospects before they can close deals. Building a connector takes weeks, if not months, and doing this at scale takes a big engineering team, which most startups cannot afford. Once built, every connector demands years of maintenance and updating, which requires a long-term commitment of resources.
Peaka’s serverless connector infrastructure offers an innovative way of launching “white-label” connectors and ensures that these connectors are always up-to-date and scalable. This allows startup founders to close deals faster and expand into new markets by shipping the popular connectors in that market while channeling engineering resources to other productive tasks.
## **What does Peaka’s Looker Studio integration do?**
Peaka has become a [Looker Studio partner](/partners/looker-studio/) by launching an integration with this popular BI tool. This integration provides Peaka users with another option to turn their data into visualizations. Non-technical users stand to benefit more from this integration, considering Looker Studio’s user-friendly interface, simple report generation, and scheduled automated reports. Thus, Peaka’s Looker Studio integration democratizes access to reports without creating a burden on IT people.
As stated above, Peaka enables users to establish a semantic layer over all data sources, allowing them to view and query their data as relational databases. Peaka users can pull in data from various SaaS tools like HubSpot, Stripe, and Zendesk or even a [specialized CRM like Provet Cloud](/provet-cloud-connector/) and join it to form new datasets. They can then push the resulting dataset to Looker Studio for visualization.
Looker Studio’s native integration with other Google products pays dividends for users who are comfortable working within the Google ecosystem. Marketing teams using Google Ads and Google Analytics can turn their marketing data into charts and graphs with Looker Studio’s pre-made templates and quickly gain insights into their ad spend.
## **Conclusion**
Data is just a cost factor unless it is turned into information and put into use. BI tools do a great job of extracting value from data as they turn tabular data into visual representations and reveal hidden trends and patterns. The question is, which BI tool suits your needs the best?
Peaka’s recent series of BI integrations solve this problem, giving users access to a range of highly capable tools with different areas of focus. [Metabase](/blog/data-visualization-with-metabase-integration/), [Apache Superset™](/blog/data-visualization-with-superset-integration/), and [Power BI](/blog/data-visualization-with-power-bi-integration/) all have their strengths and fit different use cases. Our Looker Studio integration is a nice addition that complements this group well with its ease of use and emphasis on simplicity. With many options in the market, there is a BI tool for every user persona, and Peaka is making sure that you will find the best one for your needs.
Check out Peaka’s growing [library of custom connectors](/integrations/) and [book a free demo](https://calendly.com/peaka/demo) to see Peaka in action!
--- START: blog/data-visualization-with-metabase-integration/data-visualization-with-metabase-integration.md ---
# **Visualize Your Data with Peaka’s Metabase Integration**
Having introduced an innovative way of integrating data with data virtualization and zero-ETL, our next task at Peaka was to help our users make the most of their unified data.
Instead of investing precious engineering hours into building a more-of-the-same data visualization module, we’ve decided to pair Peaka with top-notch business intelligence (BI) tools you are familiar with. These BI integrations will allow you to turn your tabular data into charts and dashboards that tell a story. The first such tool is Metabase.
## **What is Metabase?**
Metabase is an open-source business intelligence (BI) tool that connects to more than twenty commonly used data sources. In addition to its free open-source tier, the platform offers different packages with varying levels of capability at different price points.
Here’s a quick look into some of the features that set Metabase apart in a crowded BI tool market:
### **Visual Query Builder**
Metabase removes a technical barrier with its Visual Query Builder, facilitating self-serve analytics for everyone in an organization. Thanks to this feature, even non-technical employees with limited or no knowledge of SQL can query and dissect their data for business insights. In addition to drag-and-drop querying, Metabase also offers highly adjustable access controls, helping determine who gets to access what.
### **Native Query Editor**
For those proficient in SQL, Metabase’s native query editor is the way to go when they need to drill down into the data. Developers, data analysts, and data scientists can use this tool to write queries as text, slice their data as they see fit, and create templates and reusable code snippets for later use.
### **Pre-built visualizations**
A host of pre-built visualizations make it easy for Metabase users to view their data as charts and dashboards and share their insights. They can embed these visualizations, dashboards, or the entire Metabase app in their products and web pages.
### **X-ray**
Once you turn your data into charts and dashboards, Metabase also allows you to analyze your data from different perspectives. With Metabase, users can apply different filters and break their data down into its components as they look for explanations for changes. The X-ray feature facilitates data exploration and insight generation, providing users with an automatically generated dashboard of questions, which helps when you don’t know where to start.
## **What is Peaka?**
Peaka is an innovative data integration platform that makes it easy to bring together data from different sources and share the consolidated data across different systems and applications.
### **Zero-ETL data platform**
Peaka was developed as a [zero-ETL data platform](/blog/zero-etl-vs-modern-data-stack/) for startups and SMBs to replace the modern data stack, which is too expensive to set up, too complicated to use, and too demanding to maintain.
Peaka leverages [data virtualization](/blog/data-virtualization-no-code/) to unify data without complex and time-consuming ETL processes. It turns your data into virtual tables, creating a semantic layer over relational and NoSQL databases, SaaS tools, and APIs. This semantic layer allows users to query disparate data sources as a single source right away.
### **Serverless connector infrastructure**
In addition to its zero-ETL data integration capability, Peaka also functions as a serverless connector infrastructure for its customers.
Building connectors at scale is a formidable challenge for even enterprises, much less startups. Shipping a single integration can take weeks or even months. Due to the scarcity of engineering resources, startups find it extremely difficult to build the connectors their customers demand at a quick rate. Maintaining these connectors is even harder, especially because version changes in third-party APIs cause connectors to malfunction and require extensive work to fix.
Peaka’s serverless connector infrastructure empowers startups to quickly launch “white-label” SaaS connectors without hassle. These connectors are always up-to-date, scalable, and capable of performing at a high level, which reduces development costs for startups, enables them to respond to connector requests right away, and minimizes maintenance costs.
## **What does Peaka’s Metabase integration do?**
Peaka’s Metabase integration adds new dimensions to Peaka’s data integration capabilities.
### **Extensibility**
Metabase currently integrates with more than twenty databases and data warehouses. Thanks to data virtualization, Peaka can go beyond this and connect Metabase with other data sources like SaaS tools and Google Sheets documents. Peaka’s Metabase integration extends this capable BI platform so it can visualize data regardless of where it resides.
### **Single view of truth**
Nowadays, even a typical startup or SMB has fragmented data due to the tens of different SaaS applications and spreadsheets they use. Without breaking down these silos and incorporating SaaS data, it is impossible to form a single view of truth. Peaka’s new integration solves this problem by connecting Metabase to SaaS platforms it currently does not support.
### **360-degree view of customers**
Users can leverage Peaka to run join queries on disparate data sources and view the results with Metabase, thanks to Peaka’s Metabase integration. Incorporating data from different sources allows for a 360-degree view of customers, making it easier for decision-makers to spot patterns and trends and create more effective marketing campaigns.
## **Conclusion**
Data visualization is a powerful instrument for extracting information from your consolidated data and making sense of it. That’s why at Peaka, we put a special emphasis on building integrations with the most popular BI tools. These integrations will enable you to form a single view of truth for your business and unlock insights that you would not be able to draw from tabular data.
[Click here](/docs/bi-tools/metabase) to access the how-to guide on on Peaka's Metabase integration.
Check out Peaka’s growing [library of custom connectors](/integrations/) and [book a free demo](https://calendly.com/peaka/demo) to see Peaka in action!
--- START: blog/data-visualization-with-power-bi-integration/data-visualization-with-power-bi-integration.md ---
# **Power BI Integration for Better Business Intelligence**
At Peaka, we've replaced tedious ETL processes with an innovative zero-ETL approach, allowing our users to unify their data from different sources without brittle data pipelines. The next step was to ensure that users would make sense of their data. That’s why we launched our business intelligence (BI) blitz this summer, announcing integrations with the most popular BI tools in the market every two weeks.
Our Metabase integration expanded the capabilities of this data visualization tool that is popular with non-technical users. Then came our integration with Apache Superset™, a rather technical open-source tool supported by a huge community. Our latest integration connects Peaka to Power BI, a tool that appeals to a broader range of user personas than the other two integrations.
## **What is Power BI?**
Power BI is Microsoft’s data visualization solution designed to work in complete harmony with other Microsoft products. Power BI unifies the data from different Microsoft platforms and turns the result into powerful visualizations, making analytics accessible to users.
Power BI offers two capabilities that set it apart from other BI tools in the market:
### **Native connectivity within the Microsoft ecosystem**
Product ecosystems offer more value to customers because individual products within an ecosystem are better integrated and, therefore, complement each other better. Successful digital ecosystems simplify workflows, streamline operations, and create value for customers. Despite the fears of vendor lock-in and limited customization options available to users, the benefits of well-designed product ecosystems far outweigh the potential downsides.
Power BI’s native integration with other Microsoft solutions, such as Teams, SharePoint, and Microsoft 365, makes it easy for users to draw insights from their data no matter where it’s located. Users can then embed their reports in other Microsoft services and share them with other data consumers, fostering a data-driven culture across the organization.
### **Versatility**
As the top software company for decades, Microsoft develops software for the masses. Each software product they launch is designed for millions of users with varying levels of technical capabilities, which enables these products to serve wildly different use cases.
This holds true for Power BI as well, allowing it to cater to the data visualization needs of organizations of different sizes, such as startups, SMBs, and enterprises. Optimized for different user personas, Power BI empowers users to self-serve regardless of their technical proficiency. A business analyst from a non-technical background can leverage the platform to generate reports, just as a data scientist can rely on it for deeper analysis. Luckily, Power BI offers the same polished user experience for every type of user.
## **What is Peaka?**
Peaka is a data platform developed mainly for startups and SMBs. It replaces the modern data stack, which has proved too complicated and too expensive for these organizations to run.
Peaka streamlines the data integration process so users can unify data from scattered sources and share the results across different systems and applications. The platform functions as a zero-ETL data integration platform and a serverless connector infrastructure, serving different needs in different use cases.
### **Zero-ETL data platform**
The modern data stack relies on ETL pipelines to extract, transform, and load data. Building and maintaining these data pipelines requires a lot of engineering hours, which renders ETLs unfeasible for startups and SMBs.
Leveraging the [data virtualization](/blog/data-virtualization-no-code/) technique, Peaka’s [zero-ETL approach](/blog/zero-etl-vs-modern-data-stack/) eliminates complex and time-consuming ETL processes from data unification. It establishes a semantic layer over your data sources—relational and NoSQL databases, SaaS tools, and APIs. This semantic layer allows you to query disparate data sources, providing a single view of truth without having to maintain a data team.
### **Serverless connector infrastructure**
In addition to its zero-ETL data integration capability, Peaka also doubles as a serverless connector infrastructure for its customers.
Startups face the challenge of satisfying a large number of connector requests from their prospects to convert leads and close sales. This challenge is two-fold:
+ Building the connectors usually takes weeks or even months for a single connector.
+ Maintaining these connectors is a hassle that continues for years and gets more complicated with version changes in third-party APIs.
Peaka’s serverless connector infrastructure helps startups overcome this challenge by enabling them to quickly launch “white-label” SaaS connectors that are always up-to-date, scalable, and highly capable. This service removes the development and maintenance hassle for startups, allowing them to focus on nurturing leads, closing deals, and growing their business.
## **What does Peaka’s Power BI integration do?**
Peaka’s Power BI integration gives our users another superb option for visualizing their data. Having established a semantic layer over all the data sources, Peaka users can execute join queries to retrieve data from disparate sources, form new datasets, and feed them to Power BI for visualization. Power BI then turns these datasets into reports and dashboards, which makes it easier for data users to detect trends and patterns hidden in the data and draw insights that lead to data-informed decisions.
Unlike [Metabase](/blog/data-visualization-with-metabase-integration/) and [Apache Superset™](/blog/data-visualization-with-superset-integration/), Power BI benefits from the synergies resulting from being part of a product ecosystem. That’s what makes it such a good choice for a Peaka user working with Microsoft products and looking for a BI solution. Power BI seamlessly integrates with the apps deployed in the Azure cloud environment and other Microsoft solutions like Teams, Excel, and PowerPoint.
Peaka’s Power BI integration further extends this impressive platform by allowing it to bring in data from SaaS tools that it currently does not support, such as HubSpot and Stripe. As a result, it helps break down data silos and gives users a single view of truth, facilitating improved decision-making.
## **Conclusion**
At Peaka, we believe in the power of choice: Our users must have access to whatever data warehouse, CRM, or BI tool they like to work with. That’s why we’ve launched integrations with powerful BI tools that cater to different needs, user personas, and use cases. We know that your data has a story to tell and we make sure that you unlock that story with your favorite BI tool.
Check out Peaka’s growing [library of custom connectors](/integrations/) and [book a free demo](https://calendly.com/peaka/demo) to see Peaka in action!
--- START: blog/data-visualization-with-superset-integration/data-visualization-with-superset-integration.md ---
# **Elevate Data Visualization with Apache Superset™ Integration**
At Peaka, we decided at the beginning of this summer to launch a series of integrations with top-notch business intelligence tools. Having unified your data via innovative techniques like data virtualization and zero-ETL, it was time to provide you with the best data visualization capabilities so you could make the most of your data.
Our [Metabase integration](/blog/data-visualization-with-metabase-integration/) went live a few weeks ago so we could democratize data visualization for non-technical users. This time around, we are unveiling an integration with Apache Superset™, a more technical tool that performs at a high level in the most demanding corporate settings.
## **What is Apache Superset™?**
Apache Superset™ is an open-source, Python-based platform for data visualization, exploration, and analytics.
Superset started as an in-house project to develop a data visualization tool at AirBnB in 2015. In 2017, it became a part of the [Apache Incubator program](https://news.apache.org/foundation/entry/the-apache-software-foundation-announces70), which ensures the smooth development of software projects according to the principles set forth by the Apache Software Foundation. Superset graduated from the program in 2021, officially becoming a “top-level project.” Today, Apache Superset is available as an open-source platform under the [Apache License 2.0](https://en.wikipedia.org/wiki/Apache_License), and it offers a way out of the “Build vs. Buy” dilemma for organizations in need of a capable data visualization platform.
### **Build or buy? Why not use open source?**
Most tech companies face the “build vs. buy” dilemma at some point. When you need a particular kind of software, do you buy it off-the-shelf or develop it in-house?
The first option provides a well-designed product with some highly sought-after features. However, it might fall short for domain-specific tasks, and because they are a bit of a black box, customizing them to accommodate those needs may be impossible. Then there’s the price issue: Enterprise-grade products can be prohibitively expensive for some use cases.
Building in-house, on the other hand, can be a viable alternative for organizations with ample engineering resources. These organizations can specify the features they want and build software that is tailor-made to their specific needs. However, not many companies can undertake such projects due to resource constraints and the challenges of maintaining and managing such software.
Open-source software, when supported by a lively community, can offer a third option. For tools that are not part of the core business functions and where there are established standards, using the open-source alternative makes sense, especially when you don’t want to incur high costs to buy off-the-shelf and commit engineering resources to build in-house.
Data visualization is not a core business function for most companies and does not offer a competitive advantage when implemented one way or the other. Moreover, metrics and KPIs vary from one company to another, leading to an increased need to customize data visualization tools as required by the workflows. Open-source platforms tick all the boxes here and are perfect fits for data visualization.
### **Superset: Customizable and enterprise-ready**
Superset offers the Goldilocks solution for the common data visualization problem many startups and SMBs suffer from. A few pros make it stand out among the alternatives in the market:
- User-friendly interface,
- More than forty pre-built visualizations,
- Granular access control with table- and metric-level restrictions,
- Reduced query time for frequently used and elaborate dashboards thanks to cache warmup.
However, Superset’s true strength lies in customizability. Members of the Apache community can influence the roadmap, propose new features, or develop features for common use. Developers have access to the source code, which allows them to modify existing features for their use cases. As a result, Superset users end up with made-to-order data visualization capabilities for their organizations instead of trying to fit squares in round holes.
Another point that distinguishes Superset is its enterprise-readiness. Most open-source projects disappoint when it comes to user experience and polish. That’s because they are developed and maintained by rather small teams of volunteers who have other responsibilities and find it difficult to continuously improve the user experience and fix glitches. That’s not the case for Apache Superset™.
The standards observed by the Apache Software Foundation and the continuous support from the community solve this problem, ensuring that the platform is always up-to-date and scalable. As a result, companies from different industries, such as [tech, gaming, media & entertainment, e-commerce, healthcare, finance, and energy](https://github.com/apache/superset/blob/master/RESOURCES/INTHEWILD.md), rely on Superset for data visualization. AirBnB, Lyft, Wise, Rakuten Viki, Nielsen, Udemy, and Dropbox have been using Apache Superset and contributing news features to this platform for years. If something is good enough for AirBnB, it will probably be good for your SaaS company as well.
## **What is Peaka?**
Peaka is a cutting-edge data platform that simplifies the process of consolidating and sharing data from various sources across different systems and applications. Peaka is capable of serving as a zero-etl data integration platform and a serverless connector infrastructure.
### **Zero-ETL data integration platform**
Developed as a [zero-ETL data integration platform](/blog/zero-etl-vs-modern-data-stack/) for startups and SMBs, Peaka replaces the modern data stack for these companies. The modern data stack has proved to be overkill for startups and SMBs, whose data integration needs do not justify expensive and complicated systems that are also maintenance nightmares.
Peaka is a good fit for startups and SMBs because it eliminates complex and time-consuming ETL processes from data unification thanks to [data virtualization](/blog/data-virtualization-no-code/). Turning your data into virtual tables, Peaka establishes a semantic layer over your data sources—relational and NoSQL databases, SaaS tools, and APIs. This semantic layer allows you to query disparate data sources, providing a single view of truth.
### **Serverless connector infrastructure**
In addition to its zero-ETL data integration capability, Peaka also functions as a serverless connector infrastructure for its customers.
Building connectors at scale poses two serious challenges for organizations. The first involves building the connector, which may take weeks or even months for a single connector. Doing this at scale even stretches the engineering resources of enterprises. The second challenge arises from the maintenance hassle, which continues for years to come and gets more complicated with version changes in third-party APIs.
Thanks to Peaka’s serverless connector infrastructure, startups can quickly launch “white-label” SaaS connectors that are always up-to-date, scalable, and highly capable. This reduces development costs for startups, enables them to close deals faster, gain traction, and save on maintenance costs.
## **What does Peaka’s Apache Superset™ integration do?**
Peaka’s Apache Superset™ integration expands this platform’s already impressive skill set.
### **Further extends Superset**
Apache Superset™ currently integrates with more than twenty SQL-based databases and data warehouses, including PostgreSQL, MySQL, Snowflake, Google Big Query, and Amazon Redshift. Peaka maximizes the potential of Superset by connecting it to the most popular SaaS tools. Users can leverage Peaka to pull in their SaaS data from tools such as HubSpot, Salesforce, and Stripe and use that data to enrich the data they keep in SQL databases.
### **Allows for deeper analysis of data**
Every time you run join queries on Peaka and filter your data, you create new datasets. Peaka’s Apache Superset™ integration allows you to visualize these newly-formed datasets as charts and dashboards, helping capture the story they tell. By enabling you to slice & dice your data every which way, this integration makes it possible for you to make the most of your data and draw insights from it, which would not be possible otherwise.
### **Improves decision-making**
Data visualization tools are critical to data-driven decision-making. They help you uncover the trends and patterns hidden in gigabytes of data, which would not be possible in tabular form. However, these tools are limited by the data sources they can connect to. Peaka turns Apache Superset™ into a core part of your decision-making process by letting it retrieve data from all kinds of data sources and establishing a semantic layer over them.
## **Conclusion**
Data visualization is a powerful instrument for extracting information from your consolidated data and making sense of it. That’s why at Peaka, we put a special emphasis on building integrations with the most popular BI tools. These integrations will enable you to form a single view of truth for your business and unlock insights that you would not be able to draw from tabular data.
[Click here](/docs/bi-tools/superset) to access the how-to guide on on Peaka's Apache Superset™ integration.
Check out Peaka’s growing [library of custom connectors](/integrations/) and [book a free demo](https://calendly.com/peaka/demo) to see Peaka in action!
--- START: blog/data-visualization-with-tableau-integration/data-visualization-with-tableau-integration.md ---
# **Reveal What Your Data Has to Tell with Tableau Integration**
One of the biggest challenges for companies today is putting data in the hands of domain experts who can use it for insights. This requires unifying the data that is scattered across different systems, applications, and databases and then serving it to users searching for that specific piece of data. Business intelligence (BI) tools play a crucial part in this process as they convert tabular data into visualizations and help form a narrative out of it.
Peaka launched a series of BI integrations in the summer of 2024 to give users a set of first-rate options for viewing their data. The last of these integrations brings you Tableau, the popular BI tool known for its dazzling visualizations.
## **What is Tableau?**
Tableau was founded by three Stanford University researchers in 2003. After becoming one of the most popular BI tools in the market, Tableau was acquired by Salesforce for $15.7 billion in 2019. Today, the platform’s free version, Tableau Public, boasts more than 3 million user accounts, which is a sign of its reach and monetization potential.
If you care about the visual appeal of your reports, hardly any product offers nicer visualizations than Tableau. In addition to a large suite of charts, Tableau also comes with various maps to communicate geospatial data, adding a new dimension to the story your data can tell. Tableau accelerators, pre-made dashboard templates users can leverage to visualize their data right away, make self-service data visualization possible, enhancing ease of use for users with limited technical skills.
Tableau has been the gold standard in data visualization for the last decade. Its visual appeal and high customizability played a big part in the platform’s success. However, there is more to its success than meets the eye:
+ The platform can handle large datasets, making it a good fit for the enterprise use case.
+ It offers some data modeling capability along with well-defined access permissions.
+ It supports both SQL and visual querying, although the latter (called VizQL) involves a steep learning curve.
+ The Level of Details (LOD) feature provides advanced analytics at different levels of visualization, enabling users to customize their calculations according to their needs.
+ On the connectivity side of things, Tableau integrates with a wide range of data sources, including major data warehouses and databases. Its native connectivity with the apps within the Salesforce ecosystem gives the platform a leg up in the enterprise environment, where both Salesforce and Tableau are rather popular.
## **What is Peaka?**
Peaka is a platform that is purpose-built to serve the data integration needs of startups and SMBs. Before Peaka, these organizations used to either pay for enterprise-grade solutions they did not need or had to make do with spreadsheets to unify their data.
Data integration is a highly technical process that can be intimidating for the uninitiated. Peaka simplifies this process by eliminating the ETL process. As a result, users can retrieve their data from disparate systems and applications with one click and push this consolidated data to other applications.
In addition to being a zero-ETL data integration platform, Peaka also serves as a serverless connector infrastructure. Let’s take a brief look at these two use cases:
### **Zero-ETL data integration platform**
The modern data stack is a set of tools and technologies to collect, process, store, and analyze data. The cornerstone of the modern data stack is the extract-transform-load (ETL) process. Since ETL is a complex process built around data pipelines that are hard to build and maintain even with a data team, startups cannot afford these enterprise-grade solutions.
Peaka revolutionizes this field with its [zero-ETL approach](/blog/zero-etl-vs-modern-data-stack/), which removes the transformation stage from the ETL process. Zero-ETL is based on the [data virtualization](/blog/data-virtualization-no-code/) technique, which virtualizes data as relational databases, removing the need to physically copy and move data from one location to another. Establishing a semantic layer over your data sources, Peaka allows you to query every data source using SQL, run join queries to merge data from different sources, and create a single view of truth for everyone in the organization.
### **Serverless connector infrastructure**
Another use case Peaka excels at is basically functioning as a serverless connector infrastructure and helping startups launch connectors at scale.
Tech startups find it hard to gain traction because responding to the connector requests of their prospects can be an overwhelming task. Building a single connector takes weeks, if not months, so a founder willing to close deals should employ a large data team that can ship connectors at a fast enough rate so leads can be converted before they turn cold. Building those connectors in-house also means a long-term commitment to maintain and update them, which multiplies the effort needed from a team already stretched thin with daily operations.
Peaka provides users with a serverless connector infrastructure they can use to launch “white-label” connectors that are scalable and always up-to-date. By shipping tens of connectors in the time it would take to ship just a few, startups can close deals faster and focus on growing instead of allocating resources to maintain and update connectors.
## **What does Peaka’s Tableau integration do?**
Peaka’s collection of BI integrations aims to meet users where they are the most comfortable, enabling them to view their data with their favorite BI tools. Our Tableau integration serves the same purpose and gives users another option to view the data they unified with Peaka.
Although Tableau supports integrations with a host of data sources, Peaka goes beyond that as a dedicated data integration platform, allowing users to retrieve data from relational and NoSQL databases, APIs, and hundreds of SaaS platforms. Users can leverage Peaka to join data from different tools and create new datasets. They can then expose those new datasets to other systems and applications or feed them to a BI tool like Tableau to generate reports and dashboards.
Tableau seamlessly integrates with other apps in the Salesforce ecosystem, making this BI tool all the more attractive to Salesforce users. Peaka empowers these users to merge their Salesforce data with data from other platforms and gain visibility into different aspects of their operations. Thanks to Peaka’s Tableau integration, sales and marketing people can conduct customer segmentation at a more granular level and turn their reports into visualizations that tell a story.
## **Conclusion**
The different offerings in the BI tools market have their strengths and shortcomings. Each choice comes with a trade-off. Therefore, it is essential to pick the right tool for the job to be done.
If you work for an enterprise, deal with vast amounts of data, and prioritize the visual appeal of your charts and dashboards while having access to a capable IT team for data modeling purposes, Tableau is the tool for you. If this description does not fit your use case, you can always try one of [Metabase](/blog/data-visualization-with-metabase-integration/), [Apache Superset™](/blog/data-visualization-with-superset-integration/), [Power BI](/blog/data-visualization-with-power-bi-integration/), and [Looker Studio](/blog/data-visualization-with-looker-studio-integration/) integrations for your data visualization needs.
Check out Peaka’s growing [library of custom connectors](/integrations/) and [book a free demo](https://calendly.com/peaka/demo) to see Peaka in action!
--- START: blog/data-warehouse-limitations-ai/data-warehouse-limitations-ai.md ---
# **Why Data Warehouses Aren’t Enough in the AI Era**
Today, data warehouses aren’t enough.
The pitch was always simple: Connect a warehouse to BI tools and you'd have analytics. That model assumes data sources and query needs stay largely static. Neither does, and data warehouse maintainers are stuck in an endless cycle of building connectors and reshaping data structures. When the world around a data warehouse moves faster than it can adapt, its usefulness falls apart.
This issue is getting worse with AI. On a weekly basis, AI agents add new tools and modify schemas, changing the source side. At the same time, they're tweaking BI dashboards, pulling data for RAG, and changing the use cases. Because we’re wrangling with a static system in a dynamic world, everything keeps breaking, and it’s why your average warehouse maintainer and warehouse user are frustrated.
How do we avoid a warehouse that's perpetually out of sync? One option is to let AI agents own the warehouse's configuration and automate maintenance. But if we've learned anything over the last few years, it’s that agents tend to degrade code quality over time. Instead, we need a system that runs parallel to the warehouse and can adapt to constant change.
That’s what we’re building at Peaka. The goal of Peaka isn't to replace a data warehouse. Warehouses still earn their keep on OLAP workloads where sources and schemas are stable enough to amortize the cost of pipeline maintenance. Instead, we're building a dynamic layer on top of your existing data infrastructure that queries and joins data at runtime, handling all the performance sub-problems under the hood. It's not as fast as a fully tuned data warehouse, but it's significantly faster than a warehouse that requires hours of engineering time just to stay in sync.
Today, we want to discuss our vision at length.
## **Why warehouses struggle to keep up**
At the risk of over-categorizing, I want to break the problems with data warehouses into three buckets.
### **The shaping problem**
A data warehouse’s underlying data shape is a complex problem. A warehouse isn’t just a massive USB drive. It de-normalizes data into an ordered structure so that diverse sources can be joined and collectively queried. Without this work, information would be stored in a crooked fashion and be fundamentally useless at query time.
This raises many sub-problems for engineers. How do you join an application’s Postgres state with a customer’s Stripe records? How should the web-app’s PostHog events be joined with an Amplitude instance? This is the purpose of the “T” in ETL: Transform.
To add to the chaos, many data sources produce redundant or out-of-order events: CDC pipelines emit duplicate change events, retried syncs push the same rows twice, and webhooks fire more than once. Engineers end up writing dedup logic to enforce idempotency into nearly every pipeline they own.
### **The moving target problem**
The shaping problem is complicated by schema drift, the constantly changing inputs and outputs of warehouses.
{{ resize_image(path="../static/assets/images/blog-images/mathew/data-source-warehouse-query.png", width=759, height=400, op='fit_width', alt="how data warehouses struggle to keep up with the evolving data environment") }}
Sources change, and use cases change. New SaaS tools are added, new data stores are created by AI agents, and operators are constantly asking new questions. This puts engineers in a never-ending spiral of maintaining their data warehouse. Even well-funded data teams with mature Snowflake or BigQuery deployments feel this. The warehouse is *always* catching up.
### **The separation of duties problem**
For many companies, the biggest issue is the separation of duties.
The data warehouse’s users are typically distinct from its maintainers. Operators and product teams need to query data to make decisions. But they don’t build the data warehouse; that responsibility falls on data engineers.
A warehouse's configurations trail behind real-time demand as engineers get bogged down by other tickets (especially since a warehouse is rarely considered an urgent issue), causing a lag. Even worse, indecisiveness and poor communication from operators slow down the necessary changes.
## **AI raises the stakes**
Thus far, the answer has been more workarounds. ETL layers on top of ETL layers, pipelines slapped on top of pipelines, trying to create clean views out of already-messy data. There are entire schools of thought around navigating this complexity (the lambda vs. kappa architecture debate being a prime example).
Enter AI. AI needs data. Not just data, but metadata. It wants to know what the tables and columns mean, the relationships between them, and the statistics. For RAG, it needs recent information.
Broadly speaking, we’re entering an age of copious prompts that are data hungry. Queries that multiply into dozens of queries. A warehouse that can't keep up with these demands becomes a bottleneck for AI adoption.
Speaking candidly, it's a tricky situation. On one end, leaders are yelling "go, go, go" to integrate AI, while builders are rigging things together haphazardly. On the other end, data teams are struggling to build a data operation that can keep up, relying on Claude Code to plug the holes.
There's a different option. Keep the warehouse and add a data layer on top that queries the root sources at runtime and fills in where the warehouse falls short. That's how Peaka is designed.
## **Consolidation at the query level**
Peaka might seem like a “yeah, but…” product. *Yeah, that sounds straightforward, but what about the speed?*
The skepticism isn’t unwarranted, but there are significant optimizations that can happen under the hood to deliver near-data-warehouse efficiency while keeping joins at runtime. Simultaneously, you’ll net massive benefits by using a product like Peaka:
- **Federated querying:** Peaka connects directly to databases, SaaS APIs (Stripe, HubSpot, etc.), and your existing warehouses, sitting on top of them without mandatory data movement. This is an optimal design: data is accessible whenever, yet doesn’t need to be ported over prematurely.
- **Selective caching:** With federation as a default, Peaka still supports optional caching. With incremental sync on configurable schedules (down to 1-minute intervals), Peaka users can achieve data warehouse performance through materialized views for BI and RAG use cases despite the data layer being virtualized. The short interval window also ensures cached content is minutes, not hours, old. This piece of the puzzle is critical when understanding Peaka alongside data warehouses: it's a dynamic layer that delivers warehouse-like performance while remaining flexible and up-to-date.
- **Semantic layer:** Peaka's users compose their own views from modular building blocks without waiting on the data team. They can also publish or discover reusable data products in a shared marketplace, assembling their own data space à la carte. Especially now with AI tooling, anyone can construct a complex query without worrying about the underlying data shape.
- Observability:** All queries are sent to Datadog, Grafana, OTel, or a built-in observability layer.
These benefits also collapse security into a single control plane: Masking, row- and column-level filtering, and user permissions are enforced once, across all connected sources.
## **From hand-tuned servers to managed data**
We believe Peaka is part of the natural evolution of software infrastructure.
Years ago, teams hand-orchestrated servers on EC2 before Kubernetes ate the world. Now, most teams push to an orchestration platform and let it handle the complexity. Peaka applies that same philosophy to data.
Peaka doesn't ask you to rip out your warehouse. It sits alongside it, absorbing the parts of the workload your warehouse can't keep up with, and grows in scope as your sources and questions keep changing.
--- START: blog/data-warehouse-vs-data-mesh/data-warehouse-vs-data-mesh.md ---
# **Data Mesh: Rethinking Our Data Infrastructure**
Enterprise data warehouse (EDW) has been around for a long time. The story begins more than forty years ago, when [Oracle invented the first database in 1979](https://www.denodo.com/en/webinar/data-virtualization-introduction-4?display), which offered fragmented analytics at best if any. This problem was solved at the end of the 1980s, with EDWs emerging and consolidating in one server data gathered from multiple nodes. EDWs provided their users with unified analytics, serving them well for decades when the bulk of data was structured.
## **EDWs: Pros and Cons**
EDWs make things easier for users as they keep the data [pre-aggregated and sorted](https://datavirtuality.com/en/blog/data-virtualization-the-complete-overview/) in a predefined format, which facilitates faster access. The data can easily be converted into business reports and give decision-makers visibility into where a company stands at a certain point in time. Another advantage EDWs offer concerns the historicity of data: One can dive into data stored in an EDW and come up with a time series analysis.
Despite these advantages, EDWs saw their popularity fade over the years, especially with the explosion of data format types and the emergence of cloud technology. Data grows [three times](https://www.youtube.com/watch?v=ZGF0nAS28mA) as fast as data storage does in this new era. Most of the data today is unstructured, and it keeps piling up, giving users no chance to pre-aggregate it. The most one can do about this problem is to stash the data somewhere until it is needed. The data warehouse lacks the scalability to keep up with this dramatic growth in the amount of data produced. The system can only scale by adding new nodes to the central data warehouse, which gets more challenging as the number of nodes increases.
Another area where EDWs come up short is providing users with real-time data. With e-commerce booming, inventory management and logistics have become more important than ever. These operations rely on real-time data: Your three-month-old data won’t help you much when you are amidst a supply chain crisis.
Finally, there is the data ownership issue. The data stored in a data warehouse is static, waiting to be discovered by a user in need. Modifying that data in a way that can serve the needs of different users is a serious hurdle as it means reconfiguring the entire ETL/ELT process. More frequent data transformations mean more changes to the data pipeline. Treating data as a product and curating it as close to the source as possible can solve this problem.
## **Enter data mesh**
One of the concepts proposed to revolutionize data integration is the “data mesh.” Coined by [Zhamak Dehghani](https://www.linkedin.com/in/zhamak-dehghani/), the concept arises from the current circumstances caused by the monolithic data infrastructure developed over decades and describes how we should rethink data infrastructure.
Dehghani argues in [a long essay](https://martinfowler.com/articles/data-monolith-to-mesh.html) that the [first generation of data architecture platforms](https://martinfowler.com/articles/data-monolith-to-mesh.html#TheCurrentEnterpriseDataPlatformArchitecture) was built upon EDWs centralizing data storage. In the second generation, this architecture was complemented with data lakes that were capable of integrating to the big data ecosystem. [According to Dehghani](https://martinfowler.com/articles/data-monolith-to-mesh.html#ArchitecturalFailureModes), while trying to avoid monoliths, this path led to an even bigger monolith, which made it difficult for people to bring together and use their data. The monolithic infrastructure suffered from scalability problems, which Dehghani hopes to solve by [decomposing it into business domains](https://martinfowler.com/articles/data-monolith-to-mesh.html#DomainOrientedDataDecompositionAndOwnership). Her data mesh concept aims to tackle this structure and features three key principles:
### **1 - Domain focus**
In the traditional monolithic approach, one central data warehouse handles the ingestion, transformation, and storage of data. The data mesh approach replaces this outdated view with a more distributed model that transfers the [ownership of data](https://www.youtube.com/watch?v=_bmYXWCxF_Q) from a central IT department to those who create it.
Conventionally, it is the central IT department that manages the different data pipelines of various departments, which can cause [bottlenecks](https://www.eckerson.com/articles/the-data-mesh-re-thinking-data-integration). The resultant delays are unacceptable in today’s dynamic business environment, where some domains can’t do without real-time data. On the other hand, a distributed data mesh approach empowers domain experts to handle their own data pipelines.
In addition to creating backlogs, the conventional approach is doomed to fail because IT teams know very little about the respective contexts in which each department generates its data. These teams are disconnected from business operations and are not well-versed in what business units use the data for. In the data mesh model, domain experts are responsible for generating, curating, and serving the data for consumption by others while ensuring the quality of data. In a sense, this shift resembles the emergence of citizen developers in the enterprise segment, who are expected to leverage no-code/low-code tools to solve their own problems at a time when IT talent is scarce.
### **2 - Data-as-a-Product**
Enterprises have finally woken up to the value of data and started to treat it as their most valuable asset. Although this is a step in the right direction, it is still not good enough. The data mesh concept replaces this approach with a data-as-a-product perspective.
According to this perspective, domain experts are to produce and curate data, keeping in mind that it will be consumed by other people across the organization. Data owners are expected to treat their data as a product and potential users of that data as customers. Therefore, the needs of these people should be a priority, and data owners must strive to make the user experience as frictionless as possible, with an emphasis on [delighting their customers](https://martinfowler.com/articles/data-monolith-to-mesh.html#DomainDataAsAProduct). That’s why data owners should focus on ensuring that the data is accurate, timely, discoverable, and accessible to people who need it.
### **3 - Establishing a self-serve infrastructure**
The third principle of the data mesh approach follows immediately from the product thinking in the second principle. The aim of the data-as-a-product is to help consumers of data self-serve. The data generated should be [cataloged and published](https://siliconangle.com/2021/08/06/data-warehousing-problems-data-mesh-solution/) in such a way that other users should easily be able to find it and use it to achieve their own ends. Making the data more discoverable results in less hand-holding needed from the IT department.
Empowering consumers of data to self-serve takes some of the burden off the IT department and removes bottlenecks. Moreover, it has the potential to unlock the creativity of data users without engaging in a back-and-forth with the IT people at every step.
## **Final thoughts**
Data mesh is a useful framework, a mental exercise offering us a fresh look at the data infrastructure, its problems, and what needs to be done about them. It is not a tool we can buy off-the-shelf and deploy, though. It is more of a vision about how we should treat data. Data mesh involves a set of technologies we can leverage to make the most of data and tap into its potential. It is not the last word on data infrastructure, but it shows how our thinking needs to evolve to tackle today’s data challenges.
--- START: blog/delivering-happiness-hsieh-book-review/delivering-happiness-hsieh-book-review.md ---
# **Book Review: Delivering Happiness by Tony Hsieh**
Culture must be one of the most overused but least understood terms in the business world. Today it has turned into a buzzword without which you cannot prepare a press release or make an announcement. What it refers to in the business context and what it does for a particular company rarely get more attention than a few sentences in a mission statement, though.
However, this does not mean that there aren’t companies that live and die by their culture. Despite being a rare sight, such companies are built around a few core values that define their *raison d'être*, rely on these core values to develop sustainable competitive advantage and try to beat their competition in the long game. Some companies put so much value on culture that they go to extreme lengths to promote their corporate culture, just like Zappos did by publishing the Culture Book explaining what culture means to them.
Starting out as your run-of-the-mill online shoe retailer, the Las Vegas-based Zappos was acquired less than a decade later by Amazon in 2009 for more than $1 billion and it happens to be the subject of the book we review this month: [*Delivering Happiness*.](https://www.amazon.com/Delivering-Happiness-Profits-Passion-Purpose/dp/0446576220) The book narrates the Zappos story through the eyes of Tony Hsieh (pronounced as ‘Shay’), the Harvard-graduate entrepreneur who led the company from 1999 to 2020 after having sold his former company, LinkExchange, to Microsoft for $265 million when he was just 25 in 1998.
## **A man looking for a tribe of his own**
Tony comes across as a man who dislikes formalities, and his style throughout the book reflects that: Casual, fun, readable with a “substance over form“ approach. He is an eccentric man who values sincerity in relationships and never settles for anything less than genuine experiences. He is almost childishly transparent in what he wants: He doesn’t like working a lot or getting bored. It looks like there is nothing he can’t get bored with within a few weeks. He develops an interest in something, devours it, and then moves on because he no longer sees any point in doing it further. However, when he is engaged, he is locked in. Tony is one of those people who jump in with two feet when he is engaged. He takes an interest in rave parties, but he won’t be content with just dancing, so he will rent a warehouse to organize the best rave parties in town. He takes an interest in poker, but just playing won’t be enough for him; he studies it religiously as if it were a course he took at Harvard.
Tony does not want to be around people he does not like. He wants to become a part of a bigger whole, a *tribe*, in his own words. Tony wants to be happy. Actually he is obsessed with the concept of happiness. He wants to be happy so much so that understanding, experiencing and delivering happiness becomes his life goal. This is where awkward and silly details in the book start to come together and the reader gradually realizes that Tony the fun-seeking guy and Tony the millionaire entrepreneur kind of align: Tony’s story is a struggle to be himself while chasing success in business.
## **Turning corporate culture into a business strategy**
*Delivering Happiness* is a book about culture. It reveals how culture, not some new technology or an ingenious idea, can be the source of lasting competitive advantage and the foundation upon which a billion-dollar company can be built. Tony draws parallels between his character and his company’s culture throughout the book. When he draws parallels between what makes someone happy (pleasure, passion, purpose) and a company great (profit, passion, purpose), it occurs to you that this man did business just like he lived his life.
Tony recounts that his happiest moments in life were when he felt like he was part of a bigger whole—that was the reason he was obsessed with rave parties for a while in his life where it would feel like taking part in a tribal ritual. Getting to know new people and increasing the number and depth of his relationships are principles he discovered to be extremely rewarding.
One cannot help but notice that Tony Hsieh pursued similar feelings in business. He left $40 million on the table by quitting Microsoft because he was not happy sitting around doing nothing after they had bought LinkExchange for $265 million. Money is a non-issue; Tony is at his best when he is part of a group perfectly aligned behind a single purpose. The core group of guys at Zappos turning his loft into a dorm, or majority of his employees moving to Las Vegas with him when he decides to move the Zappos headquarters from San Francisco to the City of Lights… Moments like those are when the culture he has built crystallizes.
## **Customer service as the engine of growth**
While finding, understanding and giving happiness is at the center of his personal life, customer service—delivering happiness to customers—stands at the center of the company culture Tony and his partners instilled in their employees. Instead of investing in marketing, Zappos chose to invest in customer service and the personnel that would provide that service, which eventually paid off.
The obsession with customer service is what led Zappos to resort to some counterintuitive practices like making phone calls a central part of the marketing effort. However, such tricks worked because Zappos had positioned itself as a high-touch company that valued personal contact.
Another of such counterintuitive practices was giving vendors full visibility into inventory levels, sales, and profitability figures of Zappos. This aimed at leveraging the vendors’ expertise, treating them in a fair manner and creating a collaborative environment as opposed to a hostile one, and fit perfectly with one of the core values of Zappos: *Build Open and Honest Relationships with Communication*.
But it wasn’t all smooth sailing for [Zappos](https://www.zappos.com). The company had to weather storms during its first few years and was on the brink of going out of business a couple of times. Still, it managed to remain loyal to its core values to ensure long-term success while chasing short term goals to make its runway a bit longer.
## **Final thoughts**
Can anyone else borrow Tony’s playbook? How likely is it for an entrepreneur to have such a good fit between his character and the company he helped build? These are difficult questions to answer. However, focusing on things you like doing often and turning them into a strength for your company, devising a game plan to capitalize on that strength, building a culture around it, and supporting it with core values your employees can embrace would be a good start.
People like Tony Hsieh are not immune to failure; they do fail. What they excel in is building resilience through culture—building a structure that can keep functioning in the face of adversity and failure. It is the kind of spirit that gets a company back on its feet to fight back every time its existence is on the line.
Tony Hsieh is no longer with us, unfortunately, but his body of work and *Delivering Happiness* keep reminding us about one of the golden rules of doing business: A good business idea might suffice to get you in the game. However, it is the culture that will make you play that game out.
--- START: blog/deskless-workers/deskless-workers.md ---
# **The Neglected Majority: Deskless Workers**
Digital transformation has been all the rage in the last few years, dominating the agenda during the pandemic. Some companies botched it. Some undertaking digital transformation initiatives faced numerous obstacles and settled for less-than-desirable results. Despite all the talk, digital transformation remained confined to a limited portion of the active businesses, with many firms still a long way from entering the Industry 3.0 era, let alone digital transformation.
The category that did not receive its fair share of technology investments is the deskless workforce. Making up 80 percent of the global working population, this category of employees numbers around 2.7 billion, mostly concentrated in [eight industries:](https://venturebeat.com/entrepreneur/the-deskless-workforce-a-massive-opportunity-for-entrepreneurs/) Agriculture, education, healthcare, retail, restaurant and hospitality, manufacturing, transportation and logistics, and construction. By 2018, only 1 percent of the venture funding going into the software industry was invested in projects designed for deskless workers.
The pandemic served as a crash course on the software industry’s perspective on deskless and desk-bound workers. With the introduction of lockdowns and other limitations on the number of people allowed to be in a confined space, software companies raced to provide remote-working employees with the solutions they needed. Video-conferencing and online collaboration tools really took off, receiving new functionality to make remote work more effective.
While desk-bound workers were spoiled for choice, deskless workers experienced difficulty in finding even the basic productivity tools for their jobs. Deskless workers never received even a fraction of that attention paid to the pains of desk-bound workers. This was the case even though deskless workers in industries like health, logistics, and agriculture kept our world going round during the pandemic. In a world where [45 percent](https://www.raydiant.com/blog/state-of-deskless-work-2021) of deskless workers do not have a corporate email address, a digital transformation not addressing the needs of this group is bound to fail.
## **The problem: One-size-fits-all approach to technology**
Of the 1,532 deskless workers surveyed in a [2020 study], 60 percent stated that they were unsatisfied with the technology they were given at work, and 56 percent brought their own technologies to work. Imagine the risks associated with such a move, starting with data security and increased technical debt. However, workers are the least to blame as the market lacks the tools they need–they are just improvising with the tools available to them.
This lack of purpose-built technology for deskless workers stems from a basic fact: Tech entrepreneurs do not usually come from backgrounds in deskless jobs, so their insight into the needs of deskless workers remains limited. While developers can empathize with potential customers and feel at home working on tools like Jira, Confluence, or some other online collaboration tool, they cannot put themselves in the shoes of deskless workers. As a result, most of the time, deskless workers have to make do with desktop computers or laptops when they actually need tablets, wearables, and drones.
[Another study from Australia, India, and Japan](https://www.workplace.com/blog/deskless-frontline-workers-asia-pacific#failure-to-provide-even-basic-tools-makes-the-day-job-harder) drives this point home: Although 85 percent of managers believe they give deskless workers the right digital tools, only 32 percent of employees agree that they have the tools to connect, collaborate, and do their jobs. This is a critical point as software designed for office use may prove difficult to use at a construction site, a mine, or a busy warehouse. The usability needs of deskless workers are entirely different than those of desk-bound workers, so pouring more effort and money into UX design is well justified.
The lack of purpose-built technology products for deskless workers results in two major problems:
### **1 - Lack of autonomy and flexibility at work**
Flexible work options that appeared during the pandemic saved whatever remained of the employee morale during that awkward time. People could work from home and exercise more control over how and when they would get things done. The resulting autonomy was a welcome change for employees at a time of great uncertainty. Spending more time with loved ones and polishing baking skills between Zoom calls while still hitting business goals proved that there could be another way.
Few people realized, though, that deskless employees also want and need that alternative to achieve better work-life balance and increased motivation. Indeed, remote work is not an option for most, if not all, deskless workers. However, having more control over work routines is an issue for these people as well. This desire is backed by a figure from a study: [51 percent](https://info.skedulo.com/rs/960-CDH-700/images/State-of-Deskless-Work-Report-2022_Skedulo.pdf) of the deskless workforce would even change jobs for more autonomy and flexibility.
Delegating more authority to deskless workers would be a good start to demonstrate that their input is valued by the organization. Empowering these people with tools and software products that are fit for the job would go a long way toward boosting their morale. Imagine all the paperwork that you need to do during an inspection at a construction site while you walk around and pause to fill out forms using pen and paper. Replacing that process with digital forms that you can fill out on your tablet and a drone shooting videos of the site would be safer and more practical, making life much easier for employees without compromising the quality of the job done.
### **2 - High levels of employee churn**
Deskless jobs are prone to high employee turnover. Industries like restaurant and hospitality and retail are particularly plagued by this problem. According to [the Bureau of Labor Statistics](https://www.bls.gov/news.release/jolts.t16.htm), the turnover rate was 86.3 percent in the accommodation and food services industry and 64.6 percent in retail in 2021. Partly responsible for this outcome is the fact that employers in these industries see deskless workers as replaceable. In return, employees turn to industries where they can build themselves a career.
In jobs characterized by high employee churn, onboarding becomes more crucial than ever. Employee motivation tends to be lower in these jobs. The lack of a proper onboarding process introduces further friction into an already non-ideal situation. Online onboarding tools and walkthroughs can make the transition easier for jobless people. Furthermore, leaning on apps for training and reskilling deskless workers can help improve the abysmal retention rates so much so that deskless employees equipped with sufficient technology are [50 percent](https://www.skedulo.com/blog/announcing-2022-state-of-deskless-work-report/) more likely to stay at their job for the next five years.
## **The solution: No-code**
The challenge is crystal-clear: Providing deskless employees with the technology they need to succeed in their jobs, feeling valued and part of the organization. There are three options here:
+ Developing the software in-house. This is an expensive option that takes too much time with the already strained IT resources at hand. Maintaining and updating the software down the road are further hurdles.
+ Buying software off-the-shelf. This option is bound to be inflexible, as the capabilities of the software will not be a perfect match for the needs in the front lines. This situation sustains the flawed policy of offering one-size-fits-all solutions to problems that require purpose-built solutions.
+ Leveraging no-code platforms to design internal tools for deskless workers. Frontline workers are well-placed to diagnose the technology requirements of their jobs. No-code platforms can empower these people to develop solutions for the problems that they diagnosed and management does not care much about.
No-code tools minimize paperwork and clutter and save time for employees. A no-code platform like Peaka can automate tasks for the deskless workforce, create workflows, and even trigger batch jobs so that certain actions follow when the worker completes a task at hand. For example, a warehouse worker using Peaka will not have to send emails to vendors after taking inventory every time. Instead, emails will be automatically sent to relevant vendors when the inventory on an item is below a certain threshold.
In addition to automation and internal tools, Peaka can bring together your data from different sources in real time, which is a huge plus in a distributed work environment. Data coming from the warehouse, the sales team, and the customer support team can be integrated into one single view of truth, keeping everyone in the organization up-to-date at all times.
Combined with modern hardware, no-code can give the silent majority a voice at work.
--- START: blog/developer-shortage-revisited/developer-shortage-revisited.md ---
# **The Developer Shortage Revisited: Where from Here?**
The developer shortage was on top of the agenda in 2021. Digital transformation was picking up speed, there was labor shortage everywhere due to pandemic restrictions, and something needed to be done to keep the economy rolling. Almost a year has passed, and it is time to take another look at the labor market for developers.
## **Stating the problem in numbers**
While the U.S. Bureau of Labor Statistics expects the number of developers employed to grow by [22 percent](https://www.bls.gov/ooh/computer-and-information-technology/software-developers.htm) from 2020, it forecasts an average of 189,200 job openings every year during the same period. Therefore, the developer shortage is here to stay, and decision-makers had best plan ahead.
The increased demand for developer skills calls for an accompanying increase in the supply of developers, which is impossible to accomplish in the short run. The resulting gap between supply and demand translates into more workload for developers currently in the workforce. 83 percent of these people report feeling some level of burnout, [according to a study.](https://haystack-books.s3.amazonaws.com/Study+to+understand+the+impact+of+COVID-19+on+Software+Engineers+-+Full+Report.pdf) This burnout is the main reason for the developers’ share in the Great Resignation. Senior developers are taking time off to rethink their priorities and change their lives to gain more control over how they work. The surge in the number of startups founded and the capital flowing to them attest to that. Developers who decided to stay in their jobs insist on remote or hybrid work arrangements to improve conditions at a stressful time.
Recruiting new developers and retaining those you already have on your team have become more critical than ever in this age of developer shortage. [A study conducted by Reveal](https://www.revealbi.io/whitepapers/software-developers-biggest-challenges) indicates that employers agree. 53 percent of the employers responding to the survey see recruiting developers with the right skills as their biggest challenge, while 46 percent of the respondents cite retaining the current talent at hand as a business challenge.
## **Employers make their move**
Recruiters are taking steps to mitigate the effects of the developer shortage. Some of these steps involve expanding the talent pool they are recruiting from. According to the findings of the [2022 Tech Hiring Survey](https://www.codingame.com/work/codingame-coderpad-tech-hiring-survey-2022/) conducted by CodinGame and CoderPad, employers are dropping CVs as the decisive criteria during recruitment. This move gives self-taught people a better chance to get hired for positions previously reserved for employees with college degrees. The recent hiring practices of recruiters reflect this change: There has been a [17 percent increase](https://www.techrepublic.com/article/how-developers-face-a-changing-job-market-in-2022/) (from 22 percent to 39 percent) in the number of employers hiring people without college degrees. A more merit-based future seems to be awaiting us instead of one where academic background matters a lot.
A second measure to deal with developer shortage involves giving employees training to help them undertake different responsibilities. The same CodinGame and CoderPad report mentioned above cites two-thirds of recruiters stating that they invest in reskilling efforts, while around 50 percent push for upskilling initiatives. However, upskilling and reskilling are complex and expensive undertakiings. Identifying the skill sets of the employees, deciding which skills they need to have, and finding ways to bridge the gap between the two can be quite challenging. For a training program to achieve its goals, it must be tailored to the specific needs of an employee, which is no easy task. Failure in giving employees the kind of training they need causes them to question the wisdom of the program, as indicated by [44 percent](https://www.techrepublic.com/article/how-developers-face-a-changing-job-market-in-2022/) of employees stating that the training they received at the office had no impact on their work.
Another challenge stems from the fact that technical skills tend to [age rather quickly.](https://trainingindustry.com/articles/content-development/the-challenges-of-reskilling-and-how-to-overcome-them-spon-allencomm/) The time and effort invested in teaching employees a certain programming language can be all for nothing when that programming language becomes obsolete within a few years.
## **The promise of low-code/no-code**
The Reveal survey cited before draws attention to another measure employers are taking to tackle the developer shortage: 54 percent of the respondents state that they would invest in low-code/no-code (LCNC) tools. These tools can help employers at two levels: First, they can bring structure to the ongoing upskilling and reskilling initiatives that lack a clear direction. Once they get proficient in using LCNC platforms, employees themselves can tailor these tools for their own needs, eliminating the risk that training may not fit the actual requirements of the work. Such domain experts leveraging the LCNC technology to improve productivity have come to be defined as “citizen developers” in the corporate world. These people are well-positioned to take some burden off the shoulders of developers and IT departments as they can easily self-serve with the LCNC tools at their disposal.
The second way LCNC platforms can help employers in these tough times is by enabling developers to do more in less time. LCNC tools not only help developers with mundane, repetitive tasks, but they also fast-track the development process by reducing the time needed to produce proofs of concept or MVPs. The recent [Zapier no-code report](https://zapier.com/blog/no-code-report/) we [reviewed last week](/blog/zapier-no-code-report/) demonstrates that 35 percent of no-code users are actually professional developers and corroborates the notion that these tools can solve real problems for developers. With developers no longer having to spend that much time on boring parts of the work, we can expect them to experience less burnout, which should help with their retention rates.
We launched Peaka almost a year ago with the manifest aim to cure the developer dearth problem. The feedback we receive from our community is a sign of the great strides we have made in that regard, with people coming from non-technical backgrounds launching apps with little help. Yes, the developer shortage will be there for the foreseeable future. But thanks to no-code platforms like Peaka, people and businesses will be better equipped than ever to deal with it.
--- START: blog/digital-nomadism/digital-nomadism.md ---
# **Digital Nomadism: Can Work and Travel Coexist?**
The workplace will never be the same after the pandemic, that's for sure. According to some reports, office attendance is at around one-third of its pre-pandemic levels in 10 major U.S. cities. This is in line with prior reports stating that [almost three-fourths of employees](https://www.microsoft.com/en-us/worklab/work-trend-index/hybrid-work) want some sort of flexible work. Americans expect to work from home [25 percent of the time](https://www.theatlantic.com/ideas/archive/2022/02/work-from-home-revolution/622880/) in the next decade. While most people choose between hybrid and remote work, some take it up to 11 and become digital nomads, successfully blending remote work with travel.
A [digital nomad](https://www.masterclass.com/articles/what-is-a-digital-nomad) is someone who works remotely while traveling to new places. Digital nomads bring together work and travel by taking advantage of the advances in communications technology and the fact that air travel has become more affordable and convenient. These people value experiences over careers. They want to see new places, immerse themselves in new cultures, and meet new people while making a living working remotely.
The inflationary period the U.S. is going through recently fuels the interest in this lifestyle. Seeing that inflation is canceling the salary raise they receive and eating into their earnings, people are looking to relocate to places where the U.S. dollar retains its purchasing power or home currency is hit by inflation even harder than the U.S. dollar was. Digital nomadism can be a fun way of preserving the standard of life one is used to.
The interest in this way of life has reached such an extent that governments are passing new legislation to attract digital nomads. Countries like [Estonia, Greece, Thailand, and the United Arab Emirates](https://andysto.medium.com/spains-digital-nomad-visa-is-in-the-making-andy-sto-8f771ab5e13a) offer digital nomad visas. Spain takes it up a notch by combining digital nomad visas with a favorable tax code and promoting its [small towns and villages](https://andysto.com/spains-small-towns-are-opening-their-arms-to-digital-nomads/) as ideal stops for digital nomads. Already one of the favorite destinations for digital nomads, Spain aims to leverage the interest from these people to revitalize its economy while offering them the authentic life experience they are after.
The appeal of digital nomadism is evident. Being able to choose where you will work from, meeting new people, turning boring work into an exciting adventure, setting off once again when another opportunity arises… The whole experience sounds too good to be true. But it's not without its challenges.
+ Freedom without any structure can lose its appeal quickly. Like many other phenomena, boundless, unchallenged freedom loses its meaning. Having the freedom to work from anywhere without the constraints of office life may translate into doing too little with your day. Preserving the work-life balance can prove difficult for some people in the absence of a traditional office. Digital nomads are [splitting the difference between vacationers and expats](https://eubanks.medium.com/i-traded-my-digital-nomad-life-for-a-job-offer-in-nyc-6d87f132f9cd), not having as much fun as the former and not earning as much as the latter. Not putting down roots may make it difficult for a person to work with dedication, which translates into settling for less than you can achieve. It's no wonder that some digital nomads report being disappointed by the experience.
+ Work has a social side to it and suffers immensely when it is reduced to emails and Zoom calls. When you are working remotely, you are denied social contact with your colleagues, which holds you back at your job. People peg you into the "tourist" category and treat you like one.
+ The bureaucratic work involved in travel, renting a place, dealing with legal matters, and the inconsistent internet infrastructure across different countries can create an unnecessary burden on people. Time spent dealing with such issues is time you can neither spend on travel nor work.
With travel restrictions coming to an end after the pandemic, we may expect digital nomadism to become even more popular. The deferred demand for travel will definitely translate into more people ending up in Phuket, Tuscany, or Zanzibar for "work purposes." Bloggers, artists, and authors might have dominated the ranks of digital nomads for years, but the rapid advances in no-code technology and SaaS platforms are telling us that this is about to change. Developers and web designers who led the Great Resignation and the Great Exodus out of Silicon Valley can end up in different corners of the world, knowing full well that they can now run a full-fledged business from thousands of miles away. It takes a bit of self-discipline, no doubt, but it is doable. And you only live once, don't you?
--- START: blog/digital-transformation-composable-enterprise/digital-transformation-composable-enterprise.md ---
# **Composable Enterprise: Shortcut to Digital Transformation**
No-code, low-code, SaaS, iPaaS, IoT, citizen developer… It feels like not a week passes without us coming across a new term in the software industry. From the CEOs to publications like Gartner, opinion leaders in the tech industry definitely have a knack for coming up with colorful new phrases and acronyms to describe new phenomena taking place in the industry, and the tech community, being steeped in the characteristic dynamism of the industry, has been quite receptive to all that. The new term of the week is “composable enterprise,” and we’ll take a look into what it stands for.
Gartner [defines](https://www.gartner.com/en/doc/465932-future-of-applications-delivering-the-composable-enterprise) the composable enterprise as such:
*An organization that delivers business outcomes and adapts to the pace of business change. It does this through the assembly and combination of packaged business capabilities (PCBs). PCBs are application building blocks that have been purchased or developed.*
Basically, the term refers to a particular approach aimed at rendering a company more flexible and agile in a cloud-driven world. A composable enterprise is [a highly connected organization](https://www.mulesoft.com/ty/wp/rise-composable-enterprise) that leverages on-demand services from the cloud and APIs. Most of the time, this organization tends to be one with a legacy on-premise system that has served it well for a long time, but is no longer capable of keeping up with the times.
We had previously [touched upon](/blog/cultural-resistance-2/) how digital transformation could prove to be a tough nut to crack for some companies—not every company is ready for or capable of managing such a drastic change. The composable enterprise is a good, middle-of-the-road-solution for such companies.
Organizations used to have monolithic systems in place before the cloud-based systems gained wide reception. Monolithic systems are no longer deemed suitable for the modern companies because they are quite difficult to modify—[changing or updating](https://www.europeanbusinessreview.com/are-you-ready-to-become-a-composable-enterprise/) part of the system can render the whole monolithic system unusable. The dynamism of the market requires a more nimble system that is easy to modify and composed of services that are [independently scalable and deployable](https://martinfowler.com/articles/microservices.html). This problem is solved by a microservices architecture—a collection of loosely coupled, independently deployable services that are organized around certain business capabilities. The previous capabilities of a monolithic structure are distributed among services within a microservice architecture that communicate with each other through APIs. The idea is that you can put these services together to “compose” your enterprise from scratch. The end result is a composable enterprise, which turns a monolithic structure into [flexible, scalable, extensible, and customizable](https://www.processmaker.com/blog/composable-enterprise/) bundle of workflows and processes. In the meantime, by equipping legacy systems with the new capabilities of brand-new cloud-based systems, this approach saves the legacy systems from falling into complete disuse.
The fact that the composable enterprise is organized around certain business capabilities put frontline employees under the spotlight. Business users are to be the real “composers” here. Information delivery in a composable enterprise works on an on-demand and self-service basis provided via the APIs. The business users, in other words “domain experts,” will be the ones leveraging services to find solutions to the problems they face in their fields of expertise. “Citizen developers,” anyone?
With the business users no longer having to run everything through the IT department, the role of the IT looks slated to change, too. In a composable enterprise, the IT should see itself as a [strategic partner](https://www.mulesoft.com/ty/wp/rise-composable-enterprise) to business operations. It should assume responsibility to provide business users with the capabilities they need rather than delivering complete projects.
In this new role, the IT will be more of a coordinator and worry about the technology-level steps it needs to take instead of racing to supply business users with finished products. It will strive to ensure governance and established guardrails for non-technical users to follow. The IT department should act with the understanding that non-technical users, under pressure to do more work in less time, will look for solutions that can help them become more productive and efficient, whether the IT likes it or not. It is best that this happens under the guidance of the IT with a view to limit shadow IT and technical debt as opposed to a situation where business users would take matters into their own hands and start using software without any supervision at all.
A more [flexible, agile organization](/blog/innovation-in-the-age-of-no-code/); [frontline workers being empowered](/blog/no-code-for-manufacturing-industry-2/) as business users; IT shifting to a [supervisor role](/blog/no-code-shadow-it/); part of a legacy system being [renovated](/blog/no-code-do-not-rewrite-but-renovate/)… Our long-time readers must be noticing a pattern here. All of these outcomes are perfectly in tune with the results of the no-code revolution we have been advocating for some time. The details of the fit between the composable enterprise and no-code technology deserves [another post](/blog/no-code-recomposing-enterprise/).
--- START: blog/digital-transformation-dos-donts/digital-transformation-dos-donts.md ---
# **Dos and Don’ts of a Successful Digital Transformation**
Companies worldwide are projected to [spend $1.78 trillion](https://www.statista.com/statistics/870924/worldwide-digital-transformation-market-size/) on digital transformation in 2021 alone. Despite the reports of low success rates and unmet expectations, it is obvious that most companies believe that they should get on the bandwagon in one way or another. [Having recently covered](/blog/digital-transformation-false-hope/) the main reasons why digital transformation attempts fail, we feel it is about time that we focus on the common points in the stories of companies that succeeded in their digital transformation attempts.
## **1 - The top management should lead the way**
IT might be expected to lead any tech-related process in a company, but that does not apply to digital transformation. Digital transformation is too complex and multi-faceted a process for a single department to oversee. Since it is more than a technical renovation of the existing system or installation of new software, it cannot be solely left to the IT—the C-suite members are the ones that should lay out the vision, scope and goals of the process, define what success will look like and assure key stakeholder buy-in. Nothing can be transformed without commitment from the top-level leadership.
## **2 - Eliminate interdepartmental data silos and unify data**
In order to be able to set realistic goals and define key parameters, top management needs to have a clear understanding of the current situation. This is all about setting a baseline and gaining a clear bird’s-eye view of all the data available in the system. [Eliminating data silos and integrating the whole corporate data](https://digileaders.medium.com/poor-data-quality-is-the-leading-cause-of-digital-transformation-failure-4e4e68bafa15) give you that. Once your roadmap is formed, this integrated data structure will help you create standardized decision-making procedures and eventually [automate decision-making processes](https://blog.palantir.com/levels-9be772098942) regarding certain situations.
## **3 - Break the whole thing into sprints**
Breaking your digital transformation project into [shorter sprints](https://enterprisersproject.com/article/2019/8/why-digital-transformations-fail-3-reasons) and setting actionable goals for each sprint ensure your control over the progress being made. Just like Rome was not built in a day, you, too, will be building your success one brick at a time. Moreover, defining limited, meaningful goals will help keep your team motivated as opposed to working towards a distant, vague “nirvana state” nobody in your organization truly believes in. Harvesting the low-hanging fruits first and scoring wins that are limited in scope is a much better option than aiming for the best but failing completely.
## **4 - “Good enough” is good enough**
Chasing the perfect strategy during digital transformation that will take you to the “[nirvana state](https://medium.com/@TheDigitalTP/5-steps-to-digital-transformation-success-c61248197cc0)” we talked about can turn the whole thing into a never-ending saga—you are more than likely to get stuck in the analysis stage without being able to take much action. Sometimes just “good enough” [should suffice](https://www.cmswire.com/digital-experience/why-digital-transformation-fails/) so that you can focus on other areas where you can make high-impact changes. It is a folly to think that something perfect can be achieved right away at the start of a digital transformation. One should be mindful that progress will take a series of iterations and constant adjustment.
## **5 - Throwing money at every problem won’t take you too far**
Making big software and hardware purchases that rarely deliver the promised benefits is never a good idea in digital transformation projects. Not only it is a waste of money, but it also causes the illusion that the management has done its part by picking the tab without doing much else and that things should be radically different with new tech stuff in place. Digital transformation is not about acquiring the latest fancy technology but [business disruption](https://www.cio.com/article/3240978/digital-transformation-five-critical-success-factors.html)—modifying your processes and finding new ways of engaging with your customers.
A successful implementation does not mean that the challenges of digital transformation are over. As the company adapts to the market conditions and the competition, this whole process will have to be revisited and modified—it is never one-and-done. The costs, complexity and uncertainty involved could be intimidating for both decision-makers and employees, and have the process put on hold for a long while. For such cases, our friend Bruce [suggests](/blog/digital-transformation-composable-enterprise/) another way.
--- START: blog/digital-transformation-false-hope/digital-transformation-false-hope.md ---
# **Is Digital Transformation a False Hope?**
It is a single-food diet for the enterprises nowadays and the only thing on the menu is digital transformation. It is the panacea. The cure-all. The silver bullet. But, is it, really? Some recent figures cast doubt on the effectiveness of digital transformation. For example, [70 percent](https://edvinicombe.medium.com/the-people-paradox-human-natures-impact-on-digital-transformation-be1640e16e32) of the $1.3 trillion spent on digital transformation in 2018 failed to generate the intended results. The success rate in [tech-related industries](https://www.mckinsey.com/~/media/McKinsey/Business%20Functions/Organization/Our%20Insights/Unlocking%20success%20in%20digital%20transformations/Unlocking-success-in-digital-transformations.ashx) like high tech, media and telecom is not more than 26 percent. So, what’s going on? Was digital transformation an illusion all along?
Probably not. It is just that implementing digital transformation is more difficult than it seems—there is no one-size-fits-all solution. Every company should have a custom-designed roadmap addressing their particular needs, and factors like the industry a particular company is operating in, its size and how tech-heavy its processes all play a role in the formulation of the right recipe. The reasons for failure, however, are more easily identified. Here are three of them:
## **1 - Absence of a strategic vision in the leadership**
The prime responsibility in digital transformation lies with the corporate leadership. A huge endeavor like digital transformation effects so many different aspects of the business such as finances, human resources, culture and technology that it is doomed to fail without the engagement of and coordination from the C-suite. In the absence of a whole-hearted buy-in from the top management and the necessary changes in the organizational hierarchy, any attempt at a digital transformation will have to be led by middle management and it will amount to [little more than mere window dressing](https://www.forbes.com/sites/stevedenning/2021/05/23/why-digital-transformations-are-failing/?sh=1e0324657617).
## **2 - Undefined scope, vague goals**
*“When you don’t know where you are going, any road will get you there.”* Companies that lack a well-thought-out roadmap fail to bring their means and ends together. They will have difficulty in prioritization of tasks and allocating resources in an efficient way. Soon, different departments will be working at cross purposes, fighting for funds to carry out their own plans instead of that of the company. It will be every man for himself and the most likely end result in such a situation will be empty coffers without [any meaningful change having taken place at all](https://www.cnbctv18.com/views/no-code-automation-from-hrs-marketers-to-salespersons-how-non-techies-can-build-applications-11017552.htm).
## **3 - Lack of transparency**
Without the human component, digital transformation would be just another project for replacing the legacy systems in place with new, cool stuff. The human component is what makes it so complex. The leadership should invest in, work with and consider making changes to the workforce if necessary. People might have their reasons for opposing change—they might simply prefer the status quo, or they might be intimidated by the possible ramifications of change. It is only natural that employees feel threatened by the increasing automation and the ongoing fundamental change in the way tasks are done in an organization. They need to know the scope and goals of the transformation and be told how they will fit in the new situation where IT responsibilities will be more distributed across the organization.
Although digital transformation can be a difficult beast to tame and control, it is neither a false hope nor an illusion. Digital transformation can breath new life into traditional companies if done properly. It is the breadth and depth of the change involved, that is the complexity of the whole process, which causes things to spiral out of control in the absence of a roadmap. However, companies and decision-makers are not completely helpless. Our friend Eugene will be focusing on the kind of specific steps companies can take to improve their odds of success in our [next blog post](/blog/digital-transformation-dos-donts/).
--- START: blog/embedded-bi-tools-for-saas/embedded-bi-tools-for-saas.md ---
# **Why SaaS Needs Embedded BI for Customer-Facing Analytics**
Data is the lifeblood of the SaaS concept. SaaS companies use data to perfect their products through iterative design-build-test-learn cycles. Simultaneously, for SaaS users, data is needed for the smooth running of daily operations and insights. These people want their data delivered right into the platforms they use without disrupting their workflows. As a result, data analytics has become table stakes for every SaaS product.
SaaS companies now feel the need to integrate customer-facing analytics into their product experience. That is easier said than done, though. Building this capability in-house requires significant investment in time, engineering, and money. Using the traditional embedded BI tools is an option. However, these tools present challenges in terms of implementation and scalability.
Enter **[Embedded Peaka](/embedded-peaka/):** A modern, full-stack solution that helps SaaS teams deliver powerful in-product analytics, without the data infrastructure burden.
## **What are embedded BI tools?**
Embedded Business Intelligence (BI) tools refer to software that allows users to access analytics and reporting capabilities directly through an application’s user interface. This enables users to view, analyze, and act upon data without leaving the platform, providing them with a better user experience.
Embedded BI tools become part of your application’s core UX, unlike standalone BI tools that live outside the product and expect you to adapt to their own mechanics.
## **Embedded BI vs. Traditional BI**
To understand why embedded BI is so compelling for SaaS products, it helps to contrast it with traditional BI:
+ **Workflow integration:** Traditional BI tools require users to leave their main application and switch to a separate analytics platform whenever they need insights. This disrupts their workflow and often slows down decision-making. Embedded BI, on the other hand, brings analytics directly into the tools users already work with, ensuring seamless workflow integration and real-time access to insights without logging in and out of different apps..
+ **User experience:** Traditional BI solutions can feel complex and intimidating, especially for non-technical users. They often demand learning a new interface and adapting to unfamiliar processes. Embedded BI, by contrast, is designed to feel native within your application’s UI. This makes analytics accessible and intuitive, encouraging adoption across all user types, not just data experts.
By embedding analytics into the heart of your product, you’re not just delivering another feature but also enhancing the overall user experience and making data-driven decisions a natural part of every workflow.
## **Why traditional embedded BI tools fall short for SaaS**
Building [customer-facing analytics](/blog/top-mistakes-customer-facing-analytics/) with traditional embedded BI tools is a tall order due to several shortcomings that these tools come with:
+ **Technical complexity:** For many tools, creating an embedded analytics experience requires cobbling together separate pipelines, query engines, and UIs.
+ **Performance bottlenecks:** Unifying the data before sending it to the BI tool requires pushing large volumes of data to a warehouse. This adds significant latency and cost.
+ **Customization limitations:** Introducing dashboards from standalone products into your own platform is bound to undermine the style and feel you strive to establish for your product.
+ **Poor multitenancy support:** Due to the variety of analytics needs in a company, data teams struggle to isolate customer data, implement fine-grained access controls, and maintain security across tenants.
## **Benefits of embedded BI**
Embedded BI addresses many of the limitations of traditional BI, providing benefits such as
+ **Increased user engagement and stickiness:** Embedded BI tools deliver analytics through your product’s UI and eliminate one of the major reasons that cause users to leave your app. This drives greater adoption, making your product a bigger part of the user’s daily workflow.
+ **Differentiated product value:** The seamless analytics experience offered through your product’s UI adds a new capability, helping it stand out from the crowd.
+ **Faster decision-making for your users:** Embedded BI tools reduce time-to-insight, letting users access reports and dashboards while using your app. This helps eliminate dragged-out processes and inertia that all too often plague business operations.
## **How to track the success of an embedded BI project**
When it comes to evaluating your embedded BI rollout, simply tallying up dashboards or counting monthly report downloads won’t cut it. To truly measure the success of embedded BI, you need to look beyond surface-level metrics like the number of dashboards created or reports generated. The real sign of value comes from user adoption and engagement:
Are users interacting with the analytics regularly?
Are these insights driving better, faster decisions that actually move the needle for their business?
To get a pulse on your implementation, keep an eye on these essential metrics:
+ **User adoption rates:** Track how many users regularly explore analytics features within your app, rather than bouncing over to external tools.
+ **Time-to-insight:** Measure whether users are getting answers faster—think hours instead of days—by having data woven right into their workflows.
+ **Depth of engagement:** Look at session length, frequency of report access, or custom dashboard creation. These signal whether users are moving beyond casual glances to meaningful analysis.
+ **Actionability:** Assess whether embedded analytics are prompting users to make more or faster decisions, or changing the way teams approach daily operations.
These KPIs help you determine not just if embedded BI exists in your product, but how deeply it’s become a part of your users’ everyday decision-making. When you see sustained growth in these areas, it’s a good sign your embedded BI isn’t just embedded but indispensable.
## **Embedded Peaka: A simpler way to deliver in-product analytics**
Embedded Peaka was purpose-built for SaaS platforms to simplify their access to analytics. Rather than stitching together backend data systems, query engines, and frontend libraries, Peaka offers a fully integrated solution that covers the entire data delivery pipeline from connector to dashboard.
Here’s a brief look at some of the features that set Peaka apart from the competition:
### **Seamless data integration**
+ Connect to 300+ data sources, from CRMs and billing systems to support platforms and ad tools
+ No need to build and maintain your own connectors
+ [Zero-ETL](/blog/zero-etl-vs-modern-data-stack/) data integration with live querying or smart-cached data access
### **High-performance query engine**
+ Built on an enhanced Trino-based federated SQL engine
+ Smart caching via Iceberg to handle rate limits and reduce latency
+ Real-time data access through APIs or SQL
### **Embedded, customizable UI components**
+ Prebuilt, brandable UI elements such as connector dialogs, SQL editor, data browser
+ Full white-labeling and theming support
+ Light, dark, or custom themes that match your product’s UX
### **Multi-tenant and secure by design**
+ Native support for project and catalog separation
+ Row-, column-, and role-based permissions for fine-grained access control
+ Built-in OAuth flows, audit logging, and compliance readiness
## **Why SaaS companies choose Embedded Peaka**
For SaaS teams, Embedded Peaka offers several strategic advantages:
+ **Faster time-to-market:** Ship analytics features in weeks, not months.
+ **Reduced engineering overhead:** Let your engineering team focus on creating value instead of spending hours to maintain a fragmented BI stack.
+ **Scalable governance:** Manage user permissions, tenant isolation, and audit logs with the same efficiency regardless of the level of demand for analytics.
+ **Differentiated UX:** Give your users a branded, embedded analytics experience that feels native to your product without building UI components from scratch.
## **Real-world use cases**
Embedded Peaka has been used in different scenarios by companies from a variety of industries:
### **Martech**
Embedded Peaka enables a marketing SaaS to pull campaign and ad data from HubSpot, Meta Ads, and Google Ads and visualize performance metrics inside the product.
### **Fintech**
A B2B payments platform uses Embedded Peaka to retrieve data from Stripe and QuickBooks, turn it into financial dashboards, and embed them in the product.
### **E-commerce SaaS**
Embedded Peaka provides an order management tool with [real-time dashboards](/blog/data-visualization-with-power-bi-integration/) sourced from Shopify and Amazon. It lets merchants track order fulfillment, returns, and inventory.
While giving SaaS platforms the data access, transformation, and UI components they need, Embedded Peaka saves SaaS teams from the burden of building infrastructure from scratch to achieve this.
## **Final thoughts**
Customer-facing analytics has become a key product differentiator for SaaS platforms. But achieving this capability is a challenge, as traditional embedded BI tools often fall short when it comes to speed, flexibility, and scalability.
Embedded Peaka changes that. This full-stack embedded BI solution is designed specifically for SaaS products that need to deliver governed, analytics-ready data and visualizations natively, without the data engineering burden.
Whether you’re embedding your first dashboard or scaling analytics across thousands of customers, Embedded Peaka gives your team the edge.
[Schedule a demo](https://calendly.com/peaka/demo) and see how easy it is to embed BI into your SaaS product.
Or skip the demo and start building your first dashboard right away, with step-by-step instructions from our blog post on [how to build a churn analysis dashboard in one hour](/guides/how-to-build-churn-dashboard/).
--- START: blog/employee-directory-template/employee-directory-template.md ---
# **Peaka's Employee Directory Template Fosters Harmony at Work**
Frost & Sullivan, the reputable business strategy, consulting, and research firm, reports that "[only 1 percent of new products recoup their product development costs.](https://strategyn.com/wp-content/uploads/2019/10/Innovation-Track-Record-Study-Strategyn-1.pdf)" This figure reminds us of the kind of uphill battle building a startup and launching a product can turn out to be for founders.
The odds are stacked against you when you set off as a founder. You are practically venturing into the unknown. To make it worse, your organization is fragile, and the margin for error is really small. A few bad calls, and you can say goodbye to your dreams. To change circumstances and pull off a miracle, you not only need stars to align but have to make the right decisions over and over.
Paul Graham's now-famous advice for founders to "[do things that don't scale](http://paulgraham.com/ds.html)" is the most surefire way of tackling this initial fragility. Those things Graham alludes to involve actions that are impossible to copy and paste a million times without incurring the same cost every time. For example, every time you pitch to prospective customers or personally give your customers support, you are, in a sense, starting over. There are no efficiencies for you to take advantage of from one time to the next.
Another measure to deal with startup fragility would be to invest in the intangibles and build a resilient culture within your team. A shared culture and harmony can help a startup preserve composure in the face of adversity and bounce back every time.
How do you engender harmony at work? Let's take a look at a few steps you can take at different levels.
## The co-founder question
Co-founders should possess complementary skills for the startup to have a chance of succeeding. It is widely assumed that if one of them has expertise in technical matters, it would be great for the other to specialize in management, finance, or networking. With primary skills covered between them, lacking skills can always be added later when investors become part of the board during the fundraising rounds.
However, there is no cure for the conflicting visions of the co-founders. As İlker Köksal argues in his book [*Founders' FAQ*](/blog/book-review-founders-faq/), co-founders need to engage in some kind of soul-searching to find out their own 'Why?' If their visions are not compatible, the startup is shot, and it is better to liquidate it before wasting resources.
Conflicting visions between co-founders translate into conflicting roadmaps and deadlines for the startup in later stages. Two leaders trying to pull an organization in opposing directions causes stress on employees and if not properly dealt with, paralyzes the company. Without harmony between the co-founders, what you have is a mess, not a startup.
## Recruiting the right people
After the harmony between the co-founders, it is the recruitment strategy that makes or breaks a startup. Lacking the reputation and the vast financial resources to attract top talent, startups must bank on discovering hidden gems, training them, and giving them the opportunity to move the company forward.
Startups can ill-afford a lack of harmony within the team. They already suffer from a shortage of resources. A wrong hire not only means a waste of scarce resources, but it also risks throwing off the working parts of the team.
Bringing a toxic personality into what is essentially a small team of specialists can thwart whatever chances of success a startup has. Any newly-hired employee should be someone that can play a meaningful part, add value, and have the personality traits necessary for blending in.
## Inclusive decision-making
Startups are prone to making wrong decisions because they know very little about their customers, rivals, and even their own capabilities. The way to cope with this fallibility is to stay nimble and flat, always capable of pivoting easily. The co-founders might aspire to grow their startup into a behemoth with different departments and hundreds of employees. However, a staff of 20-25 people at most is the sweet spot, ensuring that the startup is both capable and agile at the same time.
A flat organization with an egalitarian culture promotes free speech and discussion, which in turn spurs innovative thinking.
On the other hand, a hierarchical organization where the CTO calls the shots and developers merely do his bidding without any discussion or brainstorming leads to a dead-end. This is the shortest route to failure.
Co-founders willing to get their money's worth should encourage their employees, even the junior ones, to speak their minds. Inclusive decision-making that seeks participation from everyone and helps people buy into the eventual roadmap maximizes your odds of success.
## Keeping the human touch alive
No matter how technical your field of work may be, your employees will still want to feel special and cared about. Just think about how you felt when your phone rang during the lockdowns last year, and it was a friend calling. The pandemic taught us several lessons, and one of them is that hardships are easier to overcome when you have your friends with you.
Here are a few sensible steps to make your teammates feel that they matter to you and the organization:
+ Make sure that you have the full contact details of your employees so that you can reach them when they are away for whatever reason. If your employee is away for health reasons or tends to an ailing family member, check upon her to see how she is doing. Those contact details will come in handy in case of an emergency.
+ If an employee remembers a colleague's birthday, she will expect hers to be remembered, too. Not only birthdays but work anniversaries are important, too. Veterans of the company would like to see their contributions recognized. Congratulating them on career milestones achieved goes a long way toward boosting their spirits.
With those points in mind, [Peaka](/) has recently published the [Employee Directory](/templates/) app template to help users keep the human touch alive at work. The template basically works like a good ol' notebook you kept for birthday and anniversary reminders. Employee Directory provides the users with a practical way of keeping employees' contact details, birthdays, and career milestones. It is a treasure trove of little acts of kindness that will nurture harmony at your startup.
--- START: blog/freelancer-way-of-life/freelancer-way-of-life.md ---
# **No-code: Tailor-made for the Freelancer Way of Life**
Freelancing has become a big part of the job market in the last decade. The expansion of the internet infrastructure, introduction of smartphones and 5G network encouraged a new breed of self-reliant professionals. The pandemic also accelerated what was already a fast transformation. It provided a new incentive for many people to pull away from corporate jobs in office buildings and start anew as freelancers.
However, there are two sides to freelancing. For some, it means freedom: Freedom from an office space, fixed working hours, fixed salary etc. For others, it is a true ordeal: Something you just have to put up with when you lose your job and hit rock bottom or something like a life raft you should feel thankful for a chance to hold on to. It can be a struggle haunted by uncertainty and insecurity.
Regardless of whether it involves copy writing, translation or app development, freelancing can be [extremely demanding](https://medium.com/@aizawanana/the-neoliberal-trap-of-freelancing-17e0696085d3) at times—despite the freedom and flexibility it affords freelancers. It is an environment where [merit comes to replace seniority](https://medium.com/@aizawanana/the-neoliberal-trap-of-freelancing-17e0696085d3) and you come to be seen as good as the last project you delivered.
Freelancing opens doors for an app developer, especially one from a non-Western country. It expands your reach like you never thought was possible. If you are venturing into the freelancing world, it is safe to assume that you were a relatively small fish in your pond and have now found a way to venture into the ocean. The upside is more promising in the ocean, but the threats are just as big: More competition from professionals scattered across the world, the continuous presence of someone out there who is ready to do the same job for less than you charge and having to work for much less than you deserve (or even for free) until you get good reviews. You have to come to terms with the reality that you basically start off somewhere around the bottom of the food chain.
Success in freelancing does not happen out of the blue; you have to build it brick by brick. First of all, freelancing is no different than any other business. It involves different tasks such as job search and application, networking, negotiating, project management, accounting, collection of payments etc. Your success depends on your ability to find your way around all these tasks and remain productive at the same time. Delivering on time is the primary criterion a freelancer is evaluated on at the beginning. One of the better pieces of advices for freelancers is summed up by the dictum "[underpromise-overdeliver](https://betterprogramming.pub/hard-truths-about-being-a-freelance-software-developer-bebbda366329)"—offering the best bang for buck and earning goodwill in the eyes of the clients is the shortest way to success for a freelancer. This is where no-code tools come in. These tools significantly reduce app development time, helping developers ship more apps in a shorter period of time. No-code platforms like Peaka and Webflow make it possible for freelancers to over deliver in the UI department, too, offering pixel-perfect designs that can dazzle clients.
Additionally, being a freelancer means that you are deprived of the [talent pool and peer review](https://medium.com/hackernoon/being-a-freelance-software-developer-is-awesome-5849b7db59fe) a traditional office environment would offer. There are no colleagues to fall back on when client has demands requiring skills you lack as a developer. That’s why freelancers need all the help they can get, and unlocking a freelancer's full potential as a developer is key. Premium no-code platforms, coming with industry-best practices out-of-the-box, can pick up the slack here and fill in for talents a freelancer does not possess. In that sense, whenever you use a no-code platform, you are actually putting to work the skills of an elite group of developers that created the no-code platform you are using.
Premium no-code platforms may require somewhat of a learning curve. Freelance developers are unique among the customer base of these tools because they have both the skills and the motivation to leverage the capabilities of these tools. Not much can be done about the disadvantages of freelance life—they come with the territory, but no-code tools can at least make it worth your while and help you build a lucrative career out of it.
--- START: blog/fundraising-3-questions/fundraising-3-questions.md ---
# **3 Questions Every Startup Founder Should Ask Themselves**
What do investors do when they want to cut to the chase and quickly evaluate the potential of your startup? What are some of the questions they ask to separate the wheat from the chaff? Let's take a look at three curveballs you can expect from investors during a meeting.
## **1 - *Can you explain to me like a five-year-old what problem you are trying to solve?* — Dave Peterson, Celonis**
Investors want to see founders who attack urgent, frequently occurring problems. Actually, it should be so urgent that people are willing to "[try half-baked ideas,](https://www.youtube.com/watch?v=ugmjf0fJY84)" as Michael Seibel suggests. As Dave Peterson and his co-authors lay out in their book [Play Bigger](https://www.amazon.com/Play-Bigger-Dreamers-Innovators-Dominate/dp/0062407619), the business idea can be based on a technology insight or a market insight.
Technology insight arises from an advanced skill your company possesses that you want to apply to a problem. For example, mRNA technology has been around for a few decades. But its widespread application for vaccine development only happened during the Covid-19 pandemic. Faced with the pressing need to fight Covid-19, scientists looked for a way to put this technology to use and came up with the mRNA vaccines.
On the other hand, market insight receives its inspiration from an underserved need in the market. That's how [Jeep launched Cherokee XJ](https://en.wikipedia.org/wiki/Jeep_Cherokee_(XJ)), the first modern SUV, in 1984. There was a glaring need in the market for a vehicle with enough interior space for a full family, a big trunk, good ground clearance, and a commanding view of the road. Something that would bring together the strengths of a station wagon and a truck would corner the market. Jeep did not need to develop some deep tech to serve this need. It looked at its capabilities in a new light and repackaged its existing mobility solutions in a new, attractive fashion. There was nothing revolutionary about Cherokee XJ's technology. It was all about finding out what the market wanted.
When you start with a technology insight, you move from a skill to a solution that will solve a problem. With a market insight, you start from a gap in the market and use that information to develop a product that will plug that gap. Both are viable ways and good templates to introduce a problem to prospective investors.
## **2 - *Can your startup become a ten-billion-dollar company?* — Sam Altman, Open AI (previously, the Chairman of Y Combinator)**
Everybody dreams of building a unicorn, but very few can because all the stars should align for a startup to become a billion-dollar company.
The founder, her idea, and the team she built all play roles in determining the potential of a startup. However, the most significant parameter here is the size of the total addressable market (TAM). The market trumps every other concern. That's why Sam Altman has that [10-billion-dollar rule](https://www.youtube.com/watch?v=s-4QqHHE16s): He will invest in any startup that he believes can become a 10-billion-dollar company, regardless of the valuation. Altman is not interested in things that worked a few years ago. He's looking for that new iPhone or Facebook that will shape our lives in the coming decades.
For founders, proving the market's potential, as in TAM, is getting half the job done in fundraising.
Dave Peterson looks at the same problem from a different perspective and asks the entrepreneurs pitching at the Fullpen sessions (Play Bigger, pp.145-6):
> "*If you win 85 percent of your category, what's the size of your category potential?*"
With this question, Dave Peterson is encouraging entrepreneurs to think about category design. Peterson and his co-authors promote category design (or creation) as a strategic move to gain market dominance. This involves building a new category around an unsatisfied need in the market and becoming the king of that particular category. Category kings are known to capture 70 to 80 percent of the profits and market value. Peterson basically wants entrepreneurs to think about their odds of achieving that:
> "*Can you build a new category and become so dominant as to capture 85 percent of it?*"
> "*If the answer is yes, is that category worth billions of dollars?*"
## **3 - *How big is your moat?* — Omri Amirav-Drory, NFX**
In startup talk, moats are the defensibilities or sustainable advantages you have that can stop other companies from eating your lunch. The moat is the barrier to entry you build around your category. Omri Amirav-Drory, an Israeli biotech entrepreneur and a general partner at NfX, refers to moats as the "[defensible magic](https://www.nfx.com/masterclass/network-effects/network-effects-in-techbio)" and regards them as one of the three parameters to take note of during an investment decision.
Most founders claim to have some sort of a moat, but in reality, that's hardly the case. Because, as Elad Gil states, there are [real and fake moats](https://www.youtube.com/watch?v=VThN7kpjRpM). Here are the two most prominent real moats a startup can hope to have while looking for investors:
Network effects: The term refers to how a new node added to a network makes the network more valuable to all nodes. It has, in time, turned into a buzzword that comes up in almost every pitch deck, although not many founders understand them properly. According to the venture capital firm NfX, there are [16 different network effects](https://www.nfx.com/masterclass/network-effects/mapping-the-16-network-effects) with varying degrees of applicability, strength, and defensibility.
Patents and other forms of IP: Deep tech companies rely on patents and IP for lasting competitive advantage. A piece of proprietary software, a process, or a production method can give companies a healthy head start and acts as a deterrent against the competition.
Other moats like economies of scale, brand equity, or big, long-term contracts are not very realistic to achieve for early-stage startups. On the other hand, fake moats are features that promise defensibility but fail to deliver it when it counts. Just having a two-sided marketplace would offer one such elusive moat, as network effects take much more than building a marketplace. Another fake moat can be data, according to Elad Gil. You can keep hoarding data, but data can't serve as a moat on its own outside of particular fields like genomics unless you can leverage it to build an entry barrier.
Among the signs that you have a reliable moat are your revenue renewal rate and customer mix. If you have contracts locked in and people have to pay for your product every year, you are in good shape. That's why some deep tech ideas are not suitable for startups: It is difficult to monetize them and build a predictable revenue stream on top of them. The presence of a few big accounts in your customer mix hurts your bargaining power as a startup since you rely on them to survive. Thousands of small accounts that regularly pay for your product and keep renewing their commitment… That's the dream scenario for a startup.
## **Conclusion**
Investors are busy people. They meet thousands of entrepreneurs every year, evaluate hundreds of projects and negotiate tens of deals. As a result, they have had their fair share of buzzwords like "network effects," "viral loops," or "disruption." They need no more.
To stand out from the crowd, a founder would be well-advised to do away with the marketing talk and get to the point right away. Succinctly laying out the problem you are going to solve, providing a rough estimate of the TAM you are looking at, and listing a set of durable defensibilities you can rely on go a long way toward convincing investors to back your project. Just tell them what you are trying to do, how you are going to do it, and what will happen when you finally do. If for nothing else, being remembered as "the only founder who took just 5 minutes to explain his vision" can be a good enough reason to give it a shot.
--- START: blog/generative-ai-hard-tech/generative-ai-hard-tech.md ---
# **Top 3 Generative AI Use Cases for Hard Tech**
2022 saw many hard tech startups emerge with a bid to solve real problems in fields like health, agriculture, and energy security. Hard tech's comeback was a welcome change for investors, too, who wanted to chase big ideas instead of the next social media app. [In the words of Peter Thiel](https://thevcfactory.com/we-wanted-flying-cars-instead-we-got-140-characters-peter-thiel/), "*we wanted flying cars; instead, we got 140 characters,*" and some people took issue with that.
Generative AI's sudden rise to fame dominated headlines in the last few months. From tools like Lensa and Midjourney that help you generate visuals to ChatGpt and GPT-4, which you can use for creating various kinds of content, generative AI looks poised to transform marketing and content production. However, is there anything in all this for people who want to tackle hard problems? Can generative AI make life easier for entrepreneurs pursuing hard tech projects? We have three cases that demonstrate that it can.
## **Drug discovery**
Developing new drugs is one of the most capital-intensive and time-consuming industrial processes. According to the consultancy firm Deloitte, the top 20 pharmaceutical companies spend [an average of $2.3 billion](https://www.genengnews.com/gen-edge/the-unbearable-cost-of-drug-development-deloitte-report-shows-15-jump-in-rd-to-2-3-billion/) on research and development of new drugs. On average, it takes [12 years](https://www.biostock.se/en/2023/01/drug-development-the-four-phases/) to bring a new drug to market. Drug discovery stands out as one of the most promising use cases for generative AI because any reduction in the cost of developing drugs and accelerating clinical trials can save lives.
An early mover in this field is Absci, which uses machine learning to figure out the relationship between a gene sequence and the function of a protein. The company employs generative AI to engineer E. coli and develop antibodies that will [bind to specific targets](https://www.forbes.com/sites/johncumbers/2023/01/10/this-company-is-using-generative-ai-to-design-new-antibodies/) in a single trial without having to run the full design cycle to exhaust all possibilities. The generative AI approach shrinks the time frame to develop antibodies from the five and a half years it took in the past to [18 to 24 months](https://venturebeat.com/ai/how-generative-ai-and-e-coli-are-speeding-up-new-drug-discovery/) and improves the 4 percent success rate of the previous method. This breakthrough opens the door for us to a future wherein we can have personalized drugs for illnesses.
## **Materials discovery**
It turns out that generative AI has capabilities other than making up pseudo-scientific explanations for scientific inquiries. Researchers have recently been using it to speed up the usual cycle of scientific research that consists of forming hypotheses, testing them, and iterating on the original question.
Victor Fung, an assistant professor from Georgia Tech, demonstrated one of the more creative uses for generative AI. In layman's terms, Fung developed an algorithm that studies the structure of materials possessing required properties. This technique allows scientists leveraging generative AI to build new materials with desired properties via a technique called [inverse design.](https://www.cc.gatech.edu/news/new-research-explores-using-generative-ai-technology-materials-discovery) Basically, it will be possible to pick and choose specific attributes and create materials that are purpose-built and customized to individual specifications.
Studies carried out by IBM Research [illustrate](https://research.ibm.com/blog/generative-models-toolkit-for-scientific-discovery) the practical applications of this technology. IBM's generative AI model studies a data set of known molecules and their corresponding properties. Then, scientists determine the parameters they want in a material like the photoacid generator (PAG), a material used in semiconductor manufacturing, and the model comes up with all the possible configurations for scientists to choose from. In other words, the model works backward from the desired properties of the PAG to [reverse engineer](https://research.ibm.com/science/generative-models/) the molecules that fit the bill. Thanks to generative AI, scientists were able to develop an innovative method that reduces from [ten years to ten months](https://research.ibm.com/interactive/photoresist/) the time it takes to discover a new molecule.
## **Manufacturing**
Generative AI has the potential to revolutionize the manufacturing industry as it can introduce efficiencies into every single process, redesign components, and discover new materials. It can help reduce the complexity of processes and designs and bring down costs as a result. The industry will be able to do more with less and become more agile as generative AI comes to play a bigger role.
Airbus has been reaping the benefits of generative AI for quite some time. The European aerospace giant used this novel approach to manufacture [a partition wall for its Airbus A320 aircraft.](https://www.autodesk.com/customer-stories/airbus) The Airbus design team started with the target attributes they wanted to achieve and let the algorithm explore all the possible permutations of parameters that produce the desired goal. The result was a partition design that met the strength and volume targets while weighing 45 percent less than the standard partition did. This small case illustrates that generative design in aerospace holds the key to lighter and more efficient designs, which will translate into lower fuel consumption and a smaller carbon footprint at the end of the day.
We can expect generative AI to power breakthroughs in manufacturing in the near future. New alloys, counterintuitive designs that get the job done, standard components reimagined in new forms… Generative AI is slated to make us rethink what is possible in manufacturing.
## **Conclusion**
The massive challenges we face today cannot be tackled with some of the old methods because those methods themselves were what brought about the problems in the first place. Old ways no longer work, and new ones need to be discovered. Now that we are under pressure from climate change, "thinking out of the box" should become the norm rather than an exception.
Generative AI is the right technology for a civilization that can't afford to leave any stones unturned. It allows us to explore all the choices available to us, discover new relationships between phenomena, and develop novel solutions to our problems in a short time. Knowing that hard tech has an ally in generative AI that it can rely on gives us a glimmer of hope that we can find a way out of the situation we are in today.
--- START: blog/great-reset-tech-layoffs/great-reset-tech-layoffs.md ---
# **The Great Reset: A Tsunami of Tech Layoffs**
The long-awaited economic downturn is finally here. We survived the pandemic, navigated our way through a supply chain crisis, and even held on tight as one former super-power invaded its smaller neighbor. But the ensuing inflationary tide, triggered by the rise in energy prices, proved too much to bear.
The tech industry seems to be looking at rough times. The days when money printed by the Fed found its way into Big Tech stocks are over. In May 2022, rumors surfaced that Meta was planning to [freeze hiring for the rest of the year.](https://www.businessinsider.com/leaked-facebook-memo-details-hiring-freeze-negative-business-impacts-2022-5) The company's stock price had already been tumbling before those rumors started and kept going downhill throughout 2022, having lost half of its value in the last twelve months at the time of writing. Apparently, that hiring freeze did not produce the desired results, and Meta ended up firing [11,000 people](https://techcrunch.com/2022/11/09/meta-confirms-11000-layoffs-amounting-to-13-of-its-workforce/), who made up 13 percent of its workforce.
All in all, over [150,000 employees](https://www.businessinsider.com/tech-layoffs-in-2022-vs-2020-and-whats-next-2022-12) lost their jobs in the tech industry last year. Judging by the figures in January 2023, the tide does not look like it will subside any time soon. [Amazon](https://www.reuters.com/business/retail-consumer/amazon-lay-off-over-17000-workers-wsj-2023-01-04/) fired 18,000 tech workers at the beginning of the year, followed by [Salesforce](https://observer.com/2023/01/salesforce-layoff-software-revenue-slow/), which decided to eliminate 8,000 roles. [Alphabet](https://www.npr.org/2023/01/20/1150234270/google-layoffs-12000-jobs), Google's parent company, parted ways with 12,000 of its employees, and most recently, [Microsoft](https://edition.cnn.com/2023/01/18/tech/microsoft-layoffs/index.html) announced that it was purging 10,000 jobs. The extent of layoffs tells us we are looking at the symptoms of a systemic crisis in the tech industry.
## **The canary in the coal mine**
Looking in hindsight, the economic downturn was the worst-kept secret in town. Everybody knew it was coming but kept pretending all was good. The signs were already there in spring 2022 when Softbank announced [a loss of $27.7 billion](https://news.crunchbase.com/venture/softbank-vision-fund-didi-uber-son/) on its investments making up its Vision Fund for the fiscal year ended March 31, 2022. 2022 saw startup valuations starting to fall after a long time. Something was wrong, and investors were quick to reach out to startup founders to draw their attention to changing conditions and give them a reality check.
[Sequoia](https://www.sequoiacap.com/adapting-to-endure-2022/) held a series of sessions where they discussed with founders different scenarios for the near future, and YC sent founders a letter titled "[Economic Downturn](https://siliconangle.com/2022/05/19/y-combinator-warns-startup-founders-wary-economic-downturn/)" to prepare them for the worst. The message was to cut costs, prioritize profitability over growth, do whatever was necessary to extend their runway in the next 24 months, and buckle up for a hard landing. YC was particularly frank with its [prediction](https://techcrunch.com/2022/05/19/yc-advises-founders-to-plan-for-the-worst/):
> *"If you are post-Series A and pre-product market fit, don't expect another round to happen at all until you have obviously hit product market fit."*
In other words, *"stay away from vanity expenses, make sure that you stay afloat until this is over, and don't expect any money until you show some results first."*
## **But why now?**
It turns out the pandemic was not the historic watershed moment analysts made it out to be. The labor market is seeking a new equilibrium after the pandemic. The layoffs are part of the return to the previous normal. Let's take a closer look at this Great Reset and its causes.
### **E-commerce losing steam**
The pandemic seemed to herald the advent of a new era in tech business: E-commerce exploded, which also drove up ad revenues for Google and Meta. Platforms like Amazon and Shopify were enjoying unprecedented growth. In those days, you would be forgiven for thinking this would be the new normal. Even [Mark Zuckerberg](https://about.fb.com/news/2022/11/mark-zuckerberg-layoff-message-to-employees/) thought so:
> *"At the start of Covid, the world rapidly moved online, and the surge of e-commerce led to outsized revenue growth… Many people predicted this would be a permanent acceleration that would continue even after the pandemic ended. I did too, so I made the decision to significantly increase our investments. Unfortunately, this did not play out the way I expected. Not only has online commerce returned to prior trends, but the macroeconomic downturn, increased competition, and ads signal loss have caused our revenue to be much lower than I'd expected. I got this wrong, and I take responsibility for that."*
Additionally, companies experiencing supply chain problems strived to streamline processes through digital transformation. Labor shortages caused by Covid-19 restrictions and remote or hybrid work practices made firms increasingly rely on online collaboration software. With the demand for software shooting through the roof, software companies went on a hiring spree, recruiting anyone who knew how to code. Because, if they did not snatch up those people, a competitor certainly would. Among these decision-makers who overrecruited was [Marc Benioff](https://fortune.com/2023/01/05/tech-layoffs-amazon-18000-salesforce-8000-largest-company-history-recession-downturn/), the co-founder and CEO of Salesforce, and the godfather of SaaS platforms:
> *"As our revenue accelerated through the pandemic, we hired too many people leading into this economic downturn we're now facing, and I take responsibility for that."*
All good things come to an end, and this one did, too. The problem is whether some of this turmoil could have been avoided had celebrity tech leaders shown a little more prudence.
### **Overinvestment in me-too industries**
The favorable market conditions in the software industry were to come to an end sooner or later. Lately, there was too little authentic innovation and too many "me-too" projects that just copied another successful product. Investors, too, favored those proven ideas rather than backing moonshot projects that venture to solve a real problem. How many more project management, note-taking, or dating apps do we need? Most startups developing such software were not viable businesses, to begin with, but they still employed substantial numbers of developers, pulling away resources from the more productive segments of the economy.
2022 spelled the end for these companies, and the first signs of an economic downturn were enough to pull the rug out from under their feet. With software startups facing dire straits, layoffs were the natural outcome. The very real problems that surfaced in the last couple of years set the stage for [the emergence of hard tech startups](/blog/investors-hard-tech-revival/), which also attracted strong support from investors. It is safe to assume that startups operating in sectors like aerospace, defense, biotech, and agrotech will be hiring more developers in the near future as software companies try to reduce their payrolls.
### **Loss of ad revenue**
Platforms like Google, Youtube, Facebook, and Instagram have relied on user data to bring hyper-personalized ads to people, which has become a major source of revenue for them. However, since the [Cambridge Analytica scandal](/blog/web3-better-internet/), people are not as comfortable sharing their private data with big tech firms as they were in the past. Data privacy is a primary concern among users, tech leaders, and policy-makers today, which threatens the corporate hold over the private data of people using these platforms.
The last blow to ad revenue came from Apple. The company launched an [App Tracking Transparency](https://techcrunch.com/2021/04/26/apples-app-tracking-transparency-feature-has-arrived-heres-what-you-need-to-know/) feature in its mobile iOS operating system, allowing users to opt out of in-app tracking so that their data will not be shared with third parties. It is no wonder that Meta's ad revenue suffered after this development, experiencing a year-on-year decline of [4 percent](https://searchengineland.com/meta-q3-earnings-ad-revenue-declined-4-but-monthly-users-showing-promise-389112) in the third quarter of 2022. Additionally, Meta faces intensifying competition from TikTok and struggles to attract young people. [Zuckerberg's push for the metaverse project](https://www.forbes.com/sites/danielnewman/2022/10/31/big-tech-earnings-put-advertising-privacy-and-user-experience-in-focus/) can be interpreted as a move to reach out to this demographic in the long term, although it makes little sense for the short-term goals of the company.
The slump in ad revenue is bound to have a profound impact on how Meta and Alphabet operate. It is naive to expect them to go back to recruiting at the levels they used to before unless they increase their ad revenue.
## **Conclusion**
[The Great Resignation](/blog/great-resignation-no-code/) involved tech professionals quitting their jobs in droves throughout 2021. These people took some time to reflect on their lives and got more proactive about their lives, starting more meaningful endeavors during the pandemic. The Great Reset, on the other hand, refers to the layoffs corporate decision-makers are undertaking to correct the mistakes they made during the pandemic. It is a desperate attempt tol signal to shareholders that they are in control of the situation and doing whatever is necessary to correct the course.
It is the employees and their families who pay the price for the baseless optimism of corporate leaders. Thousands of people who previously changed jobs and made long-term commitments suddenly found themselves unemployed because can-do-no-wrong visionaries like Zuckerberg and Benioff dropped the ball this time. The hope is that they will learn from this and act more responsibly in their future decisions.
--- START: blog/great-resignation-no-code/great-resignation-no-code.md ---
# **The Great Resignation: Symptom of a Bigger Change?**
We will realize how transformative the years 2020 and 2021 have been for our personal lives, careers, and the economy at large only when we look back and reflect in a decade or so, it seems. The health concerns, recurring lockdowns, uncertainty surrounding the business environment, employees waiting in suspense for the clouds to clear out, chip shortages, the unraveling supply chain chaos… We have witnessed more change and drama in just two years than we would expect to see in a generation.
We have drawn attention to some of these drastic changes in our previous blog posts. [Freelancing](/blog/freelancer-way-of-life/) has been [on the rise](/blog/top-freelancing-sites-for-developers/) for quite some time. Some people chose to become digital nomads, setting off with a backpack, setting up camp in exotic places, and working from there. Then "[the Great Exodus](/blog/after-deluge-post-pandemic-business-world/)" happened—tech workers started to leave the Bay Area, where life can be rather expensive, for places like Miami, Atlanta, or Austin, where they can find more affordable housing.
The most drastic of such changes took longer to attract attention and grab headlines, but it will probably be the most fateful among them in terms of consequences. We are talking about the Great Resignation, a recent trend of people leaving their jobs and refusing to return to the workforce. Stats tell us that [11.5 million workers](https://www.inc.com/jessica-stillman/great-resignation-work-meaning-esther-perel.html) quit their jobs in April, May, and June 2021. [4.4 million workers](https://thehill.com/policy/finance/581314-quits-reach-record-high-in-september-as-tight-market-boosts-workers) in the U.S. quit their jobs in September alone. Unsurprisingly, the health industry, which has borne the brunt of the fight against the pandemic, had the highest number of resignations. The tech industry was in second place, with resignations in 2021 [increasing by 4.5 percent](https://hbr.org/2021/09/who-is-driving-the-great-resignation) over the 2020 figure.
The most interesting point about the Great Resignation is that it does not fit the pattern we observed in the previous economic downturns. With economy contracting and job opportunities disappearing during an economic downturn, employers usually have the upper hand vis-à-vis the employees. The latter cannot afford to risk unemployment during an economic downturn. Instead, they bite the bullet and try to ride out the storm, no matter how unhappy they are with the working conditions. This time, things have panned out differently, though. Having done well financially in the last decade and having access to better social security and stimulus payments during the lockdowns, people in the tech industry were better positioned to say “no” to working conditions they no longer found agreeable.
People generally quit their jobs primarily for tangible reasons like low compensation or a better opportunity elsewhere. However, millions of employees coming to the conclusion that they deserved better pay over a few months sounds rather implausible. A more plausible explanation would be the pandemic’s impact on the way people saw life and what they wanted from it. Stuck at home, worried about the future, and reevaluating their priorities, people engaged in some kind of soul-searching during the lockdowns. They are keener to balance work and family and demand remote or at least hybrid work arrangements now. Companies that did not offer their employees [remote work possibillity](https://medium.com/geekculture/great-resignation-programmers-and-why-companies-should-care-89e2bb5adedd) were the first to lose workers. That some companies made rushed decisions and laid off employees in order to further cut costs alienated members of the workforce. People were once again reminded that corporate decision-makers could act selfishly without any regard for the well-being of their employees in moments of crisis.
Another fact is that people have come to take their health more seriously during the pandemic. They simply decided that the [grind of office life](https://www.inc.com/jessica-stillman/great-resignation-work-meaning-esther-perel.html) with its long commutes, accompanying stress, and little chance for physical exercise was not worth it anymore. The majority of software developers who quit their jobs are senior developers [aged between 30 and 45](https://medium.com/codex/why-senior-developers-are-leading-the-great-resignation-movement-37b93ab9a634). Being financially secure and already fed up with the corporate world, these people seem to have found the courage in themselves to chase their dream jobs or even start their own businesses that could bring some purpose to their lives.
That experienced software developers have been leaving their jobs to start their own businesses ties in well with the latest figures regarding startup funding. U.S. startups raised a total of [$240 billion](https://qz.com/2074714/2021-has-already-shattered-yearly-records-for-startup-funding/) in only the first nine months of 2021, which is 45 percent more than the $166 billion funds invested in the U.S. startups in all of 2020. Recognizing the abundance of capital in the markets, some software engineers must have decided to put their talents to work not to enrich other people but to realize their own projects.
It is safe to say that the booming SaaS ecosystem and the proliferation of low-code/no-code platforms have made it easier for startup founders to attract investment. SaaS companies have recently productized many services such as website design, payment processing, and email marketing, which every newly-established business needs nowadays. Software engineers can also deploy low-code/no-code platforms to automate the tedious parts of their work, quickly whip up proofs of concepts, and put together an MVP without having to spend months.
These two developments mean that developers no longer need to bring together crowded teams of experts to try their luck in entrepreneurship. Using a tech stack of existing SaaS products and low-code/no-code platforms, this new breed of entrepreneurs enjoy a shorter time-to-market than it was ever possible before.
With the introduction of [no-code templates](/blog/no-code-templates-competitive-edge/), we can expect more business ideas to come to fruition in the near future and startups to raise even more money. The number of unicorns, private companies with a valuation over $1 billion, stands at [more than 800](https://www.cbinsights.com/research-unicorn-companies) as of November 2021, with more than half of them joining the list in 2021. You can bet that this number will surpass 1000 in the first half of 2022 as more entrepreneurs start to leverage the no-code technology to turn their dreams into reality.
--- START: blog/hard-tech-challenges/hard-tech-challenges.md ---
# **Top 3 Ways to Solve the Biggest Challenges in Hard Tech**
Hard tech startups make up only a small fraction of the overall number of startups. Investors, most of the time chasing safe bets despite claiming otherwise, bear only part of the blame for the lack of interest hard tech projects suffered from for a long time. That situation is finally changing, as our friend Eugene explained in our [previous blog post](/blog/investors-hard-tech-revival/), but hard tech founders still face some formidable challenges.
Some of these challenges involve project management issues we are familiar with from other startups. Still others entail high capital requirements or the day-to-day running of a business. It’s time we take a deep dive into the challenges that may hold hard tech founders back.
## **Shorten the iteration cycles**
Modern software development is characterized by short iteration cycles inspired by the “Build-Measure-Learn” principle. Publicized by Eric Ries in his book *The Lean Startup*, this method seeks to ensure that the development process is informed by customer reactions so that resources can be used in the most efficient manner. The teams leveraging the Build-Measure-Learn cycle analyze customer feedback to execute a series of course corrections instead of sticking to an initial plan until it falls apart.
Hard tech startups, on the other hand, usually have longer iteration cycles. A hard tech startup developing a cure for cancer cannot build an MVP or a prototype as quickly as a SaaS startup. Industries like health, defense, aviation, and transportation are strictly regulated, which makes the development process more complicated and time-consuming. Testing different hypotheses at a high pace is impossible when other actors control the pace.
However, this does not mean that hard tech founders should lock themselves in a garage, only to come out when the product is 100 percent ready. One idea proposed by Y Combinator to overcome this hurdle involves [identifying in the business idea a smaller project](https://www.ycombinator.com/library/4r-yc-and-hard-tech-startups) that lends itself to quick iterations without demanding huge sums to implement. Just like you start with building an ‘atomic network’ of a few nodes before unlocking network effects, this smaller project would be ideal for testing the waters, engendering interest and feedback from customers, and pitching to investors.
## **Use hacks to reduce the need for capital**
Bringing a new piece of hardware to market is a daunting challenge, even in the comparatively well-understood segments like consumer goods. When you are trying to revolutionize the energy industry like [Oklo](https://www.youtube.com/watch?v=MEfkW9IyYfI) is trying to do, though, the numbers involved can be intimidating for even the most risk-tolerant entrepreneurs.
Frugality makes a lot of sense when you are running a hard tech startup. The good news is that founders have the technological means to pitch and validate ideas without incurring millions of dollars in costs. Avoiding bespoke designs and parts at first and going with the standard, mass-produced components can save founders a lot of money while testing hypotheses.
Most of the time, a simple proof of concept can go a long way toward convincing an investor to back a project. When you need to create a proof of concept, hacking together off-the-shelf components or different commercial products may be more than enough. The emergence of 3D printing and the proliferation of suppliers all around the world have already lowered the barriers for founders chasing big dreams. In capital-intensive industries like defense and aviation, [computer simulations and plastic scale models](https://youtu.be/C1DlZWfI6rk?t=480) can do a fairly good job of serving as proofs of concept.
## **You are running a business, not a lab**
Hard tech founders usually come from academic backgrounds and prefer "just doing their thing" as researchers. However, a hard tech startup cannot afford to sacrifice the business side of things for incremental gains on the R&D front. Those two should go hand in hand if the idea in question is to go beyond the realm of an academic article.
Hard tech startups face [two types of risks:](https://ecorner.stanford.edu/clips/market-risk-and-technology-risk/) Technical and market risk. R&D can take care of the former, that is, the risk of failure to find a solution to a problem. But founders should get involved in the nitty-gritty of running a startup if they want to tackle the market risk, which involves whether there is a market for that solution. Usually, while overcoming the technical risk is a matter of science, dealing with the market risk proves to be more of an art than science and, thus, quite difficult.
As an extension of the incremental approach to developing and validating an idea we suggested above, founders should not shy away from looking for ways to monetize the idea at every stage possible. The monetization efforts can kick off with a simplified version of the product or a related service. Sam Altman calls this tactic “[taking a detour,](https://www.youtube.com/watch?v=r7HyWFJMAxg)” i.e., diverging from your road map a little bit if it will help you generate some customer demand and revenue. Notable Labs is a good case in point. A YC company focusing on [personalized cancer treatment](https://www.ycombinator.com/companies/notable-labs), the company started offering [tumor screening services](https://youtu.be/C1DlZWfI6rk?t=622) to fund its core operations.
Once there is some semblance of a product at hand, another trick up the sleeve for founders can be to get creative with the sales process. Hard tech founders should explore opportunities to secure [pre-sales contracts](https://youtu.be/C1DlZWfI6rk?t=769) from interested parties. When that is not possible, the next best thing would be to pursue [letters of intent](https://youtu.be/C1DlZWfI6rk?t=807), non-binding documents expressing the intention of a potential buyer to buy a product once it is launched. Letters of intent can detail the sales price, order size, and features required, thus removing uncertainty for a startup.
Pre-sales contracts and letters of intent allow founders to mitigate risks and secure future revenue streams without committing to costly manufacturing processes. Armed with these two documents, founders will have proof of existing demand and be able to raise money from investors.
## **Conclusion**
Problems like climate change, migration, affordable housing, and food and energy security are at the top of the agenda in every country nowadays. These issues are here to stay, and software offers very little in terms of solving them.
Therefore, it is a given that people will turn to hard tech for solutions to these big problems. Turning an idea into a life-altering product is rife with challenges. But do not despair: As they say, "*where there is a will, there is a way.*"
--- START: blog/healthcare-data-migration/healthcare-data-migration.md ---
# **Data Migration in Healthcare: Challenges and Best Practices**
There are only a handful of industries where data security and privacy are as mission-critical as they are in healthcare, which happens to be one of the most tightly governed sectors. However, the ever-growing amount of data being stored and processed by healthcare organizations begins to outstrip the existing infrastructure at some point, making data migration a necessity.
Migrating data from one system to another is one of the most complex projects that can be undertaken in healthcare. This post will help you determine the medical data migration approach that suits your medical business goals and priorities.
## **What is healthcare data migration?**
Healthcare data migration is the process of transferring healthcare data from one eHealth environment to another. It’s usually a necessary step if you choose to abandon your legacy system and move on to one that has a greater capacity to securely store patient-related medical data.
In this way, you’ll manage to improve data storage and integrity, increasing your trustworthiness as a medical institution. On top of that, a well-conducted data transfer enables you to significantly improve patient care, contributing to more precise diagnoses.
Check out this video for a quick intro to healthcare data migration:
{{ youtube(id="kOK0iNrceNk") }}
## **Key takeaways**
- Healthcare data migration involves the transfer of healthcare data from one environment to another.
- Changing data formats, the growing need for data connectivity, and the increasing complexity of data are the most common drivers of data migration in healthcare.
- The volume and complexity of data, interoperability between different systems, and resource constraints pose challenges for healthcare data migration projects.
## **Healthcare data migration in numbers**
- RBC Capital Markets [claims](https://www.rbccm.com/en/gib/healthcare/episode/the_healthcare_data_explosion) that the healthcare sector generates 30 percent of the global data volume.
- According to a 2023 HIMSS Analytics Report, [78 percent](https://www.himss.org/resources/himss-healthcare-cybersecurity-survey) of healthcare organizations have either completed or are in the process of migrating their data to the cloud.
- A 2021 survey by KLAS Research reported that [82 percent](https://klasresearch.com/) of healthcare facilities observed improved patient care after migrating medical data to a centralized platform.
- A 2022 study published in the Journal of Medical Systems found that medical data migration can improve operational efficiency by up to [25 percent](https://www.twopoint.com/why-is-data-migration-important-in-healthcare/).
## **Reasons for healthcare data migration**
Why exactly do medical establishments choose to conduct data migration? Below are the five main reasons for data migration:
### **Adoption of cloud storage**
The most common reason for medical data migration is the inability of the current software system to handle the increasing volume and complexity of stored data.
The healthcare sector deals with large amounts of data, which usually requires significant investments in infrastructure, hardware, and server maintenance. That’s why cloud storage is now gaining popularity. Cloud data storage solutions allow for quick and cost-effective scaling of storage infrastructure without reliance on physical servers and with predictable spending.
Additionally, the majority of cloud-storage service vendors provide solid data backup options, making your healthcare data migration less risky and facilitating an additional layer of security for patient data.
### **Data consolidation**
Usually, a lot of healthcare service providers have more than one eHealth platform. Consequently, each type of software contains drastically different data types that somehow have to be gathered within a unified data storage. The medical data migration process engages a wide range of useful tools and algorithms that make it possible, such as:
+ Data encryption algorithms,
+ Data correctness validation algorithms,
+ Machine Learning (ML) algorithms,
+ Mapping algorithms.
### **Electronic Health Record (EHR) updating**
Unfortunately, your EHR software can become outdated, prompting the need to modernize it or switch to new software. By choosing to conduct [EHR data migration](https://www.youtube.com/watch?v=nCC1IfpX6Lo), you are taking a step toward enhancing the quality and accuracy of medical services. Then, you'll need to consider how to transfer data without any issues and ensure carefully planned [data management](https://digitalknowledge.cput.ac.za/bitstream/11189/3516/1/Fakier_Muhammad_Naasih_De_la_Harpe_Retha_FID_2008.pdf). Here are the key ways proper data migration can help during the adoption of a new EHR:
**Smooth new feature implementation:** A newly upgraded EHR will most likely include new features and interface variations. Data migration ensures that new features are effectively utilized in all patient data.
**Optimized eHealth environment:** EHRs are supposed to work tightly with other software systems within your digital health environment, including Laboratory Information Systems, Remote Patient Monitoring Software, and telemedicine applications. Proper data migration enables seamless data exchange, bringing about a wholesome treatment journey for your patients.
## **Challenges of healthcare data migration**
There are a number of common challenges medical enterprises encounter during healthcare data migration:
### **Data volume and complexity**
Healthcare data often comes in large volumes and a wide diversity of formats, which may make it challenging to migrate effectively at once. Additionally, medical data like images, multi-level patient records, and diagnostics are quite complex to operate, adding another layer of difficulty to the migration process.
**Solution:** To overcome issues associated with increased data complexity and volume, start off with a thorough assessment of the current data landscape. Then, leverage data cleansing tools to get rid of inaccurate or damaged data and establish unified data standards.
### **Interoperability failures**
As the amount of data increases, ensuring its seamless flow within other medical software solutions becomes more complicated. If you’ve lost track of formats, data types, and standards, you may experience difficulties during data mapping and migration.
**Solution:** To avoid problems with data interoperability, strictly follow unified standards like HL7 and FHIR and ensure seamless data flow across different digital healthcare systems.
### **Regulatory compliance and security**
Keeping up with medical industry laws and regulations appears to be the most significant challenge for many healthcare providers. In addition to the industry-specific legislation, there are also ever-evolving privacy laws one needs to keep tabs on.
**Solution:** Make sure to conduct in-depth research on all healthcare regulations that can be applied in your location and strictly follow them during your healthcare data transfer.
### **System disruptions**
Given the challenges of migrating huge volumes of healthcare data, a total collapse of the system may not be excluded from the list of potential risks. This could result in downtime and have a potential negative impact on patient care, causing treatment delays and compromising overall patient safety.
**Solution:** The best way to mitigate these risks involves carefully planning and implementing data migration strategies in incremental stages. Furthermore, scheduling healthcare data migration during off-peak hours can help reduce the impact on medical services.
### **Resource constraints**
Healthcare data migration projects require highly qualified and experienced experts, which may be quite challenging to find initially. A lack of sufficient numbers of well-qualified technical experts can result in poor execution and delay the completion of healthcare data migration initiatives.
**Solution:** To address this issue, invest more time and resources into training programs to upskill existing staff members. Another option is to outsource particular tasks and data migration project scopes to a third-party vendor with strong technical expertise, experience, and a deep understanding of the eHealth domain. Additionally, you may want to explore relevant tools that can assist you in implementing a more organized approach to data migration with limited resources.
## **Healthcare data migration best practices**
So, what do you need to prioritize to ensurea properly executed data migration in healthcare? Here is a short 6-step list for a sound medical data migration flow:
### **1. Define why you need medical data migration**
Understanding your specific migration needs, identifying requirements, and setting goals will help transform an undefined migration strategy into a precise plan. Healthcare businesses undertake such an initiative to
+ Reorganize data and improve consistency,
+ Enhance data integrity,
+ Ensure scalability for future data volume growth,
+ Bolster data security.
### **2. Conduct an audit of the data ecosystem**
An audit of your current data environment may provide you with a 360-degree view of the current data storage picture, enabling you to prevent potential major risks like significant loss of data. Here is what you should check out primarily:
+ Common and repetitive data patterns, types, formats, and data sources,
+ Common data inaccuracies and inconsistencies,
+ Data protocols and standards,
+ Transmitted data complexity and volume,
+ Essential health regulations to comply with,
+ Financial planning and assessment.
### **3. Choose the right medical data migration tools**
There is a wide range of tools in the market that can be used for data migration in healthcare. To find the most suitable instruments for your use case, start by making a list of the qualities you should seek in medical data migration tools:
+ Ability to support your data standards (FHIR, HL7, etc.),
+ High interoperability bandwidth,
+ Ease of use within your existing tech infrastructure,
+ Vast customization options to meet your unique requirements,
+ Scalability for your current migration needs.
### **4. Ensure regulatory compliance**
Healthcare services providers encompass a wide range of industry regulations. HIPAA (Health Insurance Portability and Accountability Act) is the most common regulation your medical software solution has to meet (if in the US) to be reliable in terms of protecting patient-related medical information. However, in addition to [HIPAA compliance for software development](https://www.cleveroad.com/blog/hipaa-compliant-software-development/), data migration in healthcare is also sensitive to a lot of international medical security standards, including:
+ eHealth Action Plan, GDPR (in Europe),
+ PIPEDA, PHIPA (in Canada),
+ Data Protection Act 2018 (in the UK),
+ Australian Digital Health Agency Standards (in Australia).
The set of essential regulations may differ depending on your location, so make sure to conduct thorough research before starting the data transfer process.
### **5. Safeguard medical data**
Complying with medical regulations requires robust data security, which, in turn, helps mitigate risks, including data leaks, data disruptions, and invalid data. Here are basic data security measures you can utilize:
+ Medical data encryption,
+ Role-based access controls,
+ Data retention and residency,
+ PHI (Protected Health Information).
### **6. Keep track of migration**
Usually, medical data migration requires a systematic approach to transferring the data from a source system to a destination system. That’s why you’ll need to plan the medical data migration as well as monitor its flow. Additionally, a sound plan also helps you identify the potential risks involved and establish robust error-handling processes.
This strategy enables you to detect errors, record details, and apply off-the-shelf issue resolution algorithms promptly. You can automatically resume the medical data migration process after the resolution of the main issue, thanks to advanced error-handling capabilities.
A well-executed data migration process consists of many stages. To simplify this task, you can utilize tools such as:
+ **Splunk** - for medical data migration troubleshooting
+ **Dynatrace** - for end-to-end monitoring of the infrastructure
+ **SolarWinds** - for tracking database state and performance during migration.
## **Benefits of data migration in healthcare organizations**
Healthcare organizations reap the benefits of successful data migration projects in several key areas:
### **Improved patient care**
Succesful data migration helps break down data siloes and unifies healthcare data, facilitating better diagnostics and even personalized treatments.
### **Enhanced data security and compliance**
Replacing legacy systems with modern infrastructure introduces modern security approaches that reduce data exposure risks. Modern cloud-based and hybrid systems are more resilient than legacy systems thanks to disaster recovery mechanisms, redundancy, and automated backups that safeguard critical data during failures.
When it comes to handling sensitive data, modern systems are designed to comply with regulations such as HIPAA and GDPR, prioritizing data security and privacy.
### **Increased operational efficiency and cost savings**
Eliminating data siloes and centralizing healthcare data through data migration results in streamlined workflows for every department and reduces the burden on IT teams. Maintaining cloud and hybrid systems tends to be less resource-intensive than maintaining legacy systems, which translates into cost savings for organizations.
### **Better decision-making**
Migrating data away from legacy systems improves data discoverability and accessibility. This allows healthcare organizations to generate timely and accurate reports, run predictive analytics, and leverage cutting-edge data visualization technology to view their data. As a result, these organizations can uncover new insights from their data and take prompt action in clinical and operational matters.
### **Scalability**
Migrating data to cloud systems ensures better scalability, which will be sorely needed as healthcare data keeps growing at a dizzying pace. Cloud systems are also extendable as they can incorporate new technologies, AI-powered apps, and state-of-the-art devices, which increasingly tend to be designed for the cloud.
## **Healthcare data migration content to consume**
- Video – [Migrating Clinical Data in Various Formats to a Clinical Data Management System](https://www.youtube.com/watch?v=LVS7JJU_BFc)
- Podcast – [The Good, Bad, Ugly, and Even Uglier of Healthcare Data Migration; Will Erskine, PBT Australia](https://www.talkinghealthtech.com/podcast/231-the-good-bad-ugly-and-even-uglier-of-healthcare-data-migration-will-erskine-pbt-australia)
## **Conclusion**
The increasing pace of digital transformation has made data migration inevitable for healthcare organizations. However, medical data migration projects can pose a significant challenge due to the complexity of the data landscape in such organizations and the rules and regulations at play. Adopting a systematic approach to medical data migration, leveraging specialized data migration tools, prioritizing data security and compliance, and following the rules and regulations goes a long way toward successfully migrating data.
A relatively new technique that caters to the specific needs of healthcare organizations is data virtualization, which facilitates the creation of a single view of truth from different data sources. It establishes a semantic layer over distributed data sources, enabling users to access data via SQL, REST, or GraphQL. This capability makes data virtualization ideal for healthcare organizations striving to break down data silos and form a single view of truth from their scattered data.
Data virtualization eliminates the need for copying or moving data, simplifying data management for healthcare organizations where huge amounts of data need to be migrated. It minimizes the risk of data loss and reduces data storage requirements. Thanks to the absence of complex and brittle data pipelines for moving data, data virtualization removes the need for large data teams and brings about cost savings.
[Peaka](/) leverages data virtualization to combine data from a wide range of databases, data warehouses, SaaS tools, and APIs. Its zero-ETL approach allows users to access and query data wherever it resides without any maintenance or data teams involved.
[Book a free demo](https://calendly.com/peaka/demo) and discover how Peaka can simplify your data migration project!
--- START: blog/hevo-vs-peaka-comparison/hevo-vs-peaka-comparison.md ---
# **Why Embedded Peaka Beats Hevo Data for In-Product Dashboards**
Building embedded analytics into your SaaS product sounds simple until you realize what it actually takes: connectors, query infrastructure, data caching, governance, UI components, and tenant-level control.
Hevo Data and Embedded Peaka both help you bring data into your app, but they take radically different approaches. One gives you the infrastructure for ETL to your warehouse. The other gives you a drop-in data delivery layer with a built-in UI, query engine, and live data access—no warehouse required.
Here’s why Embedded Peaka is the better fit if you want to ship customer-facing analytics faster.
## **1. Peaka unifies and embeds data at the same time**
Hevo is built for internal analytics. It’s a classic ETL pipeline that syncs data from various sources into your cloud warehouse. After that, you’re on your own: you still need to manage query performance, frontend UIs, data governance, and multi-tenant access control.
Peaka surpasses conventional data integration by providing a comprehensive data management solution that simplifies embedding analytics in SaaS products. Peaka not only unifies data from distributed sources, but it also gives you the UI components and white-labeling support to present that data as dashboards in your product.
| Feature | Embedded Peaka | Hevo Data |
| :--------------------- | :------------------------------------- | :------------------------------------ |
| **Deployment Mode** | ✅ Purpose-built for embedding | ❌ ETL for internal analytics |
| **UI Components** | ✅ Dialogs, query editor, autocomplete | ❌ None |
| **Branding & Theming** | ✅ Full white-labeling | ❌ None |
### **What this means for you**
Peaka enhances data connectivity and helps you create a plug-and-play embedded data experience.
## **2. Peaka eliminates data replication and data warehouses**
Hevo’s data integration model relies on replicating data into a data warehouse such as Snowflake, BigQuery, or Redshift. This results in latency, ongoing need for maintenance, and security issues.
By leveraging data virtualization and federated queries, Embedded Peaka eliminates the need for a data warehouse and all associated maintenance costs. It enables users to query the data at the source, while smart caching reduces query execution time and lowers costs for frequently accessed data.
| Feature | Embedded Peaka | Hevo Data |
| :----------------------- | :--------------------------------------------------- | :--------------------------------- |
| **Data Access Model** | ✅ Live querying (no replication) | ❌ Data replication to destination |
| **Query Engine** | ✅ Built-in (Trino-based) | ❌ No query support |
| **Caching & Rate Limit Handling** | ✅ Rate limit-aware caching built-in | 🟡 Basic retry logic only |
### **What this means for you**
While Hevo Data refines the traditional ETL method, Embedded Peaka removes the need for ETLs and simplifies the data stack for SaaS teams working to embed analytics into their products.
## **3. Peaka offers advanced features to accelerate development**
Hevo requires you to manage all the customer-specific logic yourself: from securing OAuth credentials to building tenant-level isolation and row-level access.
From the start of its development, multitenancy was baked into Embedded Peaka, which offers
+ Hosted or BYO OAuth with full tenant awareness
+ Row-, column-, and role-level access controls
+ Audit logs and lineage tracking
+ Isolated projects, catalog, and schemas for multi-tenant control
| Feature | Embedded Peaka | Hevo Data |
| :----------------------- | :--------------------------------------- | :--------------------------------------------- |
| **OAuth** | ✅ Hosted, tenant-aware | 🟡 To be handled by the user |
| **Multitenant Support** | ✅ Native project/catalog isolation | ❌ None |
| **Connector Maintenance** | ✅ Peaka-managed | 🟡 To be maintained by the user |
### **What this means for you**
OAuth flows, multitenancy, and governance are typically pushed to the end of the development cycle or completely ignored, as is the case with Hevo. Embedded Peaka handles allBy offering them out of the box, Embedded Peaka ensures that product velocity remains high.
## **4. From backend to UI, Embedded Peaka has the entire stack**
Hevo gives you a data pipeline. That’s it. No query editor, connector dialogs, or theming.
Embedded Peaka comes with premium features such as
+ AI-enhanced query editors
+ Connector dialogs
+ Autocomplete
+ Visual theming
Instead of building every component from scratch, product teams embed them in their platforms and channel their resources to more productive tasks.
### **What this means for you**
The advanced feature set offered by Embedded Peaka helps product teams save weeks in engineering effort that would otherwise be used to develop such features.
## **Key takeaways**
+ **Hevo Data is an ETL platform** that replicates data to warehouses, but doesn’t provide query engines, UI components, or multitenant controls.
+ **Embedded Peaka delivers a complete embedded analytics stack**, including live querying, smart caching, governance, and white-labeled UI.
+ **Embedded Peaka eliminates the need for data replication**, allowing SaaS teams to access real-time data without setting up a data warehouse.
+ **Embedded Peaka shortens time-to-market**, enabling teams to embed dashboards and analytics directly into their products with minimal engineering effort.
## **Final verdict: Embedded Peaka helps you deliver value, not just integrate data**
Hevo is an excellent choice for centralizing data into a warehouse for internal analytics.
But if your goal is to **embed real-time data, analytics, or AI insights** directly into your product without building all the infra yourself, Embedded Peaka is purpose-built for you.
Don’t build a stack to deliver analytics. Embed one with Peaka.
Visit [Embedded Peaka](/embedded-peaka/) to see how it powers embedded analytics for SaaS teams or [book a demo](https://calendly.com/peaka/demo) to watch it in action.
Want to explore how Peaka compares to other data platforms?
Check out our in-depth comparisons with other leading tools:
+ [Embedded Peaka vs. Airbyte Embedded](/blog/airbyte-embedded-vs-embedded-peaka)
+ [Embedded Peaka vs. Cdata](/blog/cdata-vs-embedded-peaka)
+ [Embedded Peaka vs. Merge.dev](/blog/merge-vs-embedded-peaka)
+ [Embedded Peaka vs. Polytomic](/blog/polytomic-vs-embedded-peaka)
--- START: blog/how-to-build-churn-dashboard/how-to-build-churn-dashboard.md ---
# How to Build a Churn Analysis Dashboard in 1 Hour Using Peaka and v0.dev
# Project Overview
What if your high-paying customers try to tell you something before they churn, and you don’t catch it?
In this tutorial, you will build a dashboard that identifies **Pro- and Enterprise-tier subscribers who contacted support shortly before canceling** their subscriptions. The goal is to help support and product teams understand churn patterns and take action before it’s too late.
This dashboard provides real value for:
- **Customer support teams** looking to spot at-risk users,
- **Product managers** needing context around cancellations,
- **Growth and revenue teams** focused on reducing churn.
Best of all, instead of spending days coding, you will build this entire system in **just 1 hour** using **Peaka** for data integration and **v0.dev** to generate the frontend.
## The Tools You’ll Need / The Stack
Here’s what you’ll use to bring everything together:
- **Peaka** – A no-code data integration platform that connects and joins data from Stripe and Zendesk, then turns those queries into APIs you can consume.
- **v0.dev** – An AI-powered tool that generates a full-stack dashboard UI based on a simple natural language prompt.
- **Stripe + Zendesk** – The core data sources providing subscription details and customer support tickets, respectively.
---
### Why Peaka?
Peaka is a no-code data operations platform that enables you to:
- Connect to external data sources like APIs, databases, and SaaS applications,
- Model your data as **virtual tables** without moving or duplicating it,
- Create APIs on top of those virtual tables to serve your applications.
For this dashboard, Peaka provides:
- A seamless way to **connect Zendesk and Stripe data** by matching customer emails,
- A flexible query builder that lets you **join support tickets with subscription data** using SQL,
- Ready to use API endpoints that you can call directly from your app.
By using Peaka, you avoid building and maintaining a custom backend, saving significant development time and complexity.
---
### Why v0.dev?
With v0.dev, you can:
- Skip writing any frontend code. Just describe your app in a prompt,
- Get a fully functional, developer-friendly UI generated for you,
- Automatically generate backend integration logic that connects to Peaka’s APIs,
- Easily adapt your app by updating prompts or API specs and regenerating the code.
## Let's Start
### Step 1: Setting Up Your Peaka Project
Before you start building, you need to set up your Peaka workspace and generate an API key for authentication.
Follow these steps:
1. Go to [peaka.studio](https://peaka.studio/) and log in.
> If you don’t have an account yet, sign up. It only takes a minute.
2. Create a **new project** from your dashboard.
3. Open your new project, then click the gear icon (⚙️) in the bottom left sidebar to open **Settings**.
4. In **Settings**, navigate to the **API Keys** tab and create a new API key.
5. Copy your **Project ID** from the URL in your browser’s address bar. It should look like this:
```javascript
`https://peaka.studio/studio/${project_id}/..`
```
Save both the API key and Project ID safely, you’ll need these when connecting Peaka to v0.dev.
### Step 2: Connecting Data Sources in Peaka
With your project set up, it’s time to bring in your external data.
In this example, you’ll connect **Stripe** and **Zendesk** to Peaka. These will serve as the foundation for your churn and support analysis.
---
#### ✅ Connecting Stripe
- In your Peaka project, click the **➕ Add** button on the left sidebar to open the **Connector List**.
- Use the search bar to find **Stripe** among the available connectors.
- Select it, give the connection a name (e.g., `stripe_main`), and enter your **Stripe API Key**.
- Click **Connect,** and you’re done!
Your Stripe data will now appear under your connected data sources.
{{ resize_image(path="../static/assets/images/blog-images/churn-analysis-dashboard/image.png", width=786, height=636, op='fit_width', center='true', alt="Search Datasource to Connect", bordered="true") }}
{{ resize_image(path="../static/assets/images/blog-images/churn-analysis-dashboard/image1.png", width=548, height=554, op='fit_width', center='true', alt="Connecting Stripe Account", bordered="true") }}
---
#### ✅ Connecting Zendesk
- Back in the **Connector List**, search for **Zendesk** and select it.
- Since Zendesk supports **OAuth authentication**, setup is quick and easy.
- Provide a **connection name** and your **Zendesk subdomain** (e.g., `yourcompany.zendesk.com`).
- Peaka will redirect you to Zendesk for login and authorization. Once approved, the connector will be activated.
- You’ll now have access to **Zendesk tickets and user data** within Peaka, no API handling required.
{{ resize_image(path="../static/assets/images/blog-images/churn-analysis-dashboard/image2.png", width=506, height=756, op='fit_width', center='true', alt="Connecting Zendesk Account", bordered="true") }}
---
By the end of this step, both **Stripe** and **Zendesk** will be live in your Peaka project fully authenticated and ready to query.
### Step 3: Writing Queries in Peaka
With Stripe and Zendesk connected, it’s time to extract insights by writing queries across both data sources.
---
#### 🧠 Creating a New Query in Peaka
- From the left sidebar, go to the **Queries** section.
- Click **➕ New Query** to create a new SQL query.
- Choose **Start from Scratch** instead of using a template.
> (You can explore Peaka’s templates later for common use cases.)
- Write the following SQL queries and click **Run** to preview the results.
{{ resize_image(path="../static/assets/images/blog-images/churn-analysis-dashboard/image3.png", width=786, height=344, op='fit_width', center='true', alt="Create a New Query", bordered="true") }}
{{ resize_image(path="../static/assets/images/blog-images/churn-analysis-dashboard/image4.png", width=786, height=581, op='fit_width', center='true', alt="Query Screen", bordered="true") }}
---
#### 📊 Query 1: Support Tickets Submitted Shortly Before Churn
This query finds **Pro or Enterprise users** who submitted a support ticket **within 14 days before canceling** their subscription.
Use it to identify customers who might have been unhappy or struggling and possibly prevent future churn.
```sql
SELECT
u.name,
prod.name AS plan_name,
z.subject,
z.description,
u.email AS customer_email
FROM
"zd"."public"."tickets" z
JOIN
"zd"."public"."users" u ON z.requester_id = u.id
JOIN
"stripe"."payment"."customers" c ON u.email = c.email
JOIN
"stripe"."payment"."subscriptions" sub ON c.id = sub.customer_id
JOIN
"stripe"."payment"."plans" p ON sub.plan_id = p.id
JOIN
"stripe"."payment"."products" prod ON p.product_id = prod.id
WHERE
prod.name IN ('Pro Plan', 'Enterprise Plan')
AND sub.canceled_at IS NOT NULL
AND z.created_at BETWEEN (sub.canceled_at - INTERVAL '14' DAY) AND sub.canceled_at
ORDER BY z.created_at DESC
LIMIT 100;
```
---
#### 📊 Query 2: All Tickets from Premium Users
This query retrieves **all support tickets** submitted by **Pro and Enterprise plan** users, whether they churned or not.
It’s useful for exploring the overall support volume, issue trends, and satisfaction signals from your premium customer base.
```sql
SELECT
u.name AS customer_name,
prod.name AS plan_name,
z.subject AS ticket_subject,
z.description AS ticket_description,
u.email AS customer_email,
z.priority,
z.status,
z.updated_at
FROM
"zd"."public"."tickets" z
JOIN
"zd"."public"."users" u ON z.requester_id = u.id
JOIN
"stripe"."payment"."customers" c ON u.email = c.email
JOIN
"stripe"."payment"."subscriptions" sub ON c.id = sub.customer_id
JOIN
"stripe"."payment"."plans" p ON sub.plan_id = p.id
JOIN
"stripe"."payment"."products" prod ON p.product_id = prod.id
WHERE
prod.name IN ('Pro Plan', 'Enterprise Plan')
ORDER BY z.created_at DESC
LIMIT 100;
```
### Step 4: Integrating Peaka Queries into the Frontend with v0.dev
With your Peaka queries ready, you can now build a complete frontend dashboard using [v0.dev](https://v0.dev/). This step shows how to integrate live query results into your UI, entirely through prompt-based generation.
#### 💬 Start with a Prompt
Begin by opening [v0.dev](https://v0.dev/) and entering a prompt like this:
```
I have a Peaka account and a Peaka project that contains two queries.
I want to create a dashboard with the following charts:
- A table listing users who contacted support shortly before canceling. (You can execute the tickets_by_pro_enterprise_customers query from Peaka)
- A list of recent feedback entries from premium subscribers. (You can execute the zendesk_tickets_with_stripe_customer_and_plan_info query from Peaka)
It should be a full-stack system. The design should be developer-friendly and backend should be integrated with Peaka.
You can check the API reference here: https://docs.peaka.com/api-reference/introduction
```
{{ resize_image(path="../static/assets/images/blog-images/churn-analysis-dashboard/image5.png", width=786, height=477, op='fit_width', center='true', alt="V0 initial prompt", bordered="true") }}
---
#### 🔐 Set Environment Variables
v0.dev will likely ask you to define the following environment variables to authenticate with Peaka:
- `PEAKA_API_KEY`
- `PEAKA_PROJECT_ID`
Use the values you obtained earlier from your Peaka project’s settings and paste them into v0.dev’s environment configuration.
{{ resize_image(path="../static/assets/images/blog-images/churn-analysis-dashboard/image6.png", width=551, height=207, op='fit_width', center='true', alt="v0 Api Key Screen", bordered="true") }}
---
#### ⚠️ Fix the API Base URL
By default, v0.dev may try to connect to `https://api.peaka.com/v1`, which is not the correct base URL for query execution.
You can fix this by prompting v0.dev with:
```
API Endpoint base is different than api.peaka.com/v1.
It should be https://partner.peaka.studio/api/v1
```
If you're using the **EU zone**, use:
```
https://partner.eu.peaka.studio/api/v1
```
{{ resize_image(path="../static/assets/images/blog-images/churn-analysis-dashboard/image7.png", width=687, height=470, op='fit_width', center='true', alt="Base URL Fix in v0", bordered="true") }}
---
#### 📄 Use the Correct Request Format
After correcting the base URL, you’ll also need to make sure the request payload matches Peaka’s `execute-query` API format.
You can provide v0.dev with this sample request and response structure, based on the [official documentation](https://docs.peaka.com/api-reference/data-queries/execute-query):
**Sample request:**
```tsx
const options = {
method: 'POST',
headers: {Authorization: 'Bearer ', 'Content-Type': 'application/json'},
body: '{"from":[{"catalogName":"peaka","schemaName":"query","tableName":"samplequery"}]}'
};
fetch('https://partner.eu.peaka.studio/api/v1/data/projects/{projectId}/queries/execute', options)
.then(response => response.json())
.then(response => console.log(response))
.catch(err => console.error(err));
```
**Sample response:**
```json
{
"columns": [
{
"catalogId": "2",
"catalogName": "peaka",
"schemaName": "query",
"tableName": "samplequery",
"columnName": "amount"
}
],
"data": [
[
{
"name": "amount",
"displayName": "amount",
"dataType": "bigint",
"value": "75",
"order": 0
}
],
[
{
"name": "amount",
"displayName": "amount",
"dataType": "bigint",
"value": "75",
"order": 0
}
],
[
{
"name": "amount",
"displayName": "amount",
"dataType": "bigint",
"value": "75",
"order": 0
}
]
]
}
```
{{ resize_image(path="../static/assets/images/blog-images/churn-analysis-dashboard/image8.png", width=743, height=423, op='fit_width', center='true', alt="Example Payload and Response prompt", bordered="true") }}
---
#### 🪄 Final Touches via Prompt Iteration
Once your frontend is connected to Peaka and fetching live data, you can polish the UI using plain prompts.
For example:
```
Map the "date" field to the "updated_at" column in the recent feedback table, and remove the "rate" field.
```
v0.dev will apply your changes automatically, no need to manually edit code.
---
> ✅ At the end of this step, you’ll have a dynamic frontend powered by Peaka’s live query data fully operational in under an hour.
### Step 5: The Final Dashboard
After hooking up Peaka as the data layer in a [v0.dev](https://v0.dev/) dashboard, you’ll have a clean, fully functional, and developer-friendly interface, powered entirely by live data from Stripe and Zendesk.
The dashboard consists of two key components:
---
#### 🧯 1. Users Who Contacted Support Shortly Before Churning
This table lists:
- Customer name
- Email address
- Plan type (Pro or Enterprise)
- Ticket subject & description
- Ticket creation date (within 14 days before cancellation)
This component highlights **last-minute support activity** from users who churned, providing early-warning signals of dissatisfaction or friction. It’s an invaluable tool for customer support and product teams to spot trends behind cancellations.
{{ resize_image(path="../static/assets/images/blog-images/churn-analysis-dashboard/image9.png", width=786, height=238, op='fit_width', center='true', alt="Support Before Cancellation screen", bordered="true") }}
---
#### 💬 2. Recent Feedback from Premium Subscribers
This section displays all tickets submitted by **current** Pro and Enterprise users, regardless of churn status. It includes:
- Customer name
- Plan name
- Ticket subject & description
- Ticket priority, status, and last updated date
This real-time view helps teams **monitor ongoing support needs** and stay ahead of potential churn risks before they escalate.
{{ resize_image(path="../static/assets/images/blog-images/churn-analysis-dashboard/image10.png", width=786, height=234, op='fit_width', center='true', alt="Premium Subscribers' Ticket Screen", bordered="true") }}
---
#### 🚀 Why This Dashboard Delivers Value
This dashboard isn’t just a data visualization, it enables action. Here's how different teams benefit:
- **Product teams** can identify recurring friction points.
- **Support teams** can evaluate whether unresolved tickets correlate with churn.
- **Revenue & growth teams** can track churn trends across plan tiers.
- **CSMs** can proactively reach out to users showing warning signs.
---
#### ⏳ Time and Effort Saved
Traditionally, building this system would require:
- Manual API integrations
- Authentication handling
- SQL joins and data modeling
- Backend service development
- Frontend component coding
…resulting in **days or even a week** of effort.
By using **Peaka + v0.dev**, the same outcome can be achieved in **under an hour**, with:
- No custom backend development
- No manual UI coding
- Just clear prompts and a few API keys
---
> 💡 This is a fast, scalable way to ship internal tools or MVPs using live SaaS data without compromising on developer experience.
## Real-World Use Cases
This exact approach can be adapted for various needs:
- **Support teams**: Proactively identify at-risk customers.
- **Product teams**: Spot recurring feedback from premium users.
- **Growth teams**: Understand why high-value customers churn.
All without hiring a data team or building internal tools from scratch.
## The Conventional Way
The traditional approach would have looked like this:
- ETL pipeline to pull data from Stripe and Zendesk,
- A data warehouse to store and query the results,
- A backend service to expose APIs,
- A frontend team to build a dashboard.
Estimated time: **2–3 days, at minimum**.
Peaka + v0? **1 hour.**
## Key Takeaways
- **Churn signals often hide in support data:** Users who reach out to support shortly before canceling are waving red flags. Surfacing these interactions helps teams take proactive action before it's too late.
- **Peaka makes integrations painless:** Connect to platforms like Stripe and Zendesk without writing any code, model the data with SQL, and instantly turn queries into APIs.
- **v0.dev eliminates frontend overhead:** With natural language prompts, you can generate fully functional dashboards that connect to live data, no UI or backend coding required.
- **1 hour = days of saved effort:** What would normally take days, building data pipelines, backend services, and frontend components, can now be achieved in under an hour.
- **Accessible for non-technical teams:** PMs, support leads, and growth managers can gain insights without needing to write a single line of code.
- **Flexible and reusable:** The same structure can be repurposed for different queries, data sources, or dashboard layouts with minimal changes.
> 🎯 Bottom line: Skip the complexity, accelerate insight.
>
>
> Peaka + v0.dev is a turbocharged way to build MVPs and internal tools.
## Conclusion
By simply:
- Connecting Zendesk and Stripe to Peaka,
- Writing two SQL queries,
- Prompting v0.dev to generate the frontend,
I built a fully functional, data-powered churn insight dashboard in just **1 hour**.
If you’re a developer, or even a PM who wants results without the overhead of building everything from scratch, give this combo a try.
--- START: blog/how-to-connect-servicetitan-to-looker-studio/how-to-connect-servicetitan-to-looker-studio.md ---
# **Connecting ServiceTitan to Looker Studio with Peaka**
Being data-driven is the goal for every organization today, be it a startup, a conglomerate, or a government agency. It might be the tech companies that popularized the concept, but data lies at the heart of every major strategic decision, performance evaluation initiative, or the culture of accountability leaders are willing to establish. That’s why even the modest plumbing business in your neighborhood is seeking ways to make better use of its business data.
In this blog post, we are looking into ServiceTitan, a popular platform for the trades and filed service businesses, and how its data can be leveraged to provide the insights its users seek.
## **What is ServiceTitan?**
ServiceTitan is a specialized platform that home service businesses (“the trades,” in ServiceTitan speak), such as plumbing, electrical, and HVC services, can use to manage their operations. Developed to provide an end-to-end experience for home service businesses, ServiceTitan streamlines the process of scheduling appointments, managing customer calls, tracking and documenting progress through forms, photos, and videos, and monitoring customer satisfaction.
In addition to centralizing business data, ServiceTitan also presents all this information as a dashboard. This dashboard offers a quick view of the state of business through charts, graphs, and metrics. It comes with a certain level of customization so users can view the job status, bookings, cancellations, revenue, and other valuable information, depending on the specific needs of a business.
One of the more versatile platforms in the market, ServiceTitan doubles as a CRM and a communication panel you can use to keep tabs on the fieldwork being done. Its marketing tab combines marketing analytics with Google Ads campaigns being run, providing an integrated user experience for business teams.
## **What is Looker Studio?**
Looker Studio is Google’s business intelligence solution. This platform went by the “Data Studio” name until 2022 when Google decided to rename it “Looker Studio.” This rebranding led to some confusion as Google also has the Looker platform for data modeling.
Just like Power BI is the go-to platform for visualizing data within the Microsoft ecosystem, Looker Studio functions as the default data visualization tool for users in the Google ecosystem. Looker Studio addresses the needs of business teams that are willing to generate reports and draw insight from their data without relying on a data team.
One of the defining characteristics of Looker Studio is its ease of use. While Tableau requires users to possess technical skills to fully leverage its capabilities, Looker Studio targets a non-technical user base and offers a few features that enable these users to self-serve:
+ **Simple UI:** An easy-to-use interface makes Looker Studio accessible to marketing and growth teams willing to make data-driven decisions without waiting for engineers to generate reports for them.
+ **Native integration with Google products:** Looker Studio supports seamless connectivity with Google platforms such as Google Analytics and Google Ads, which are extremely popular with marketing and growth teams.
+ **An extensive library of connectors and integrations:** Looker Studio boasts a collection of more than 20 connectors for the most popular data sources that were built in-house. Additionally, it offers over a thousand partner connectors that are built and maintained by third parties, so users can pull in data from almost any source.
+ **Pre-made visualizations:** Another way Looker Studio empowers non-technical users is through the pre-made visualizations it provides. These templates give users a simple and creative way to turn their data into slick charts and graphs that communicate a story.
+ **Data modeling with LookML:** Tech-savvy users can connect Looker Studio to LookML and define data relationships, creating a data modeling layer so other users do not need to access the database or the data warehouse.
## **ServiceTitan’s dashboard capabilities**
ServiceTitan does a great job of unifying all the data that managers and field workers in the home service business need. It can pull in data from a host of data sources. As of November 2024, it supports integrations with over a hundred different platforms, from accounting and tax software to business intelligence tools and human resource management platforms.
ServiceTitan has a very robust reporting feature that allows you to pick from hundreds of different attributes to build custom reports. You can then leverage the platform’s built-in dashboard to visualize these reports.
For administrators and managers, the ServiceTitan dashboard offers a wide range of metrics and KPIs:
+ Company metrics related to revenue and sales that help monitor how well the business is doing,
+ Metrics related to calls, bookings, and conversions that sum up the business opportunities these decision-makers are interested in,
+ Scorecards for Customer Service Representatives that help link the performance of call center staff to leads and bookings,
+ Scorecards for technicians that help link job completion rates and average response times to the performance of field workers.
All these metrics can be further broken down by using date filters, making trend analysis possible by visualizing the data from the last 18 months or 26 weeks.
## **Why should you connect ServiceTitan with Looker Studio?**
What if you want to go off the beaten path and improvise with the metrics and KPIs you’re tracking on ServiceTitan? Then, things get more complicated.
Metrics to gauge overall business performance (revenue, operational expenses, financing), job progress (inbound calls, job completion rates, average response times, and materials used), and customer sentiment (customer reviews or survey results) are infinitely customizable according to a company’s needs. ServiceTitan’s dashboard is good at providing the basics, but will probably come up short for niche data visualization needs. That’s when purpose-built business intelligence tools come into play.
There are several reasons for using a dedicated data visualization tool like Looker Studio to view your ServiceTitan data: You may already be familiar with the capabilities of Looker Studio or just find it convenient to stay within the Google ecosystem.
However, the fact that ServiceTitan does not support integration with Looker Studio makes things a little bit tricky. Left to your own devices, you can manually export your ServiceTitan data to a spreadsheet and then feed this data to Looker Studio for visualization. But keep in mind that this spreadsheet will not update automatically and will require you to keep exporting data whenever you want to update your dashboard.
## **Benefits of using Peaka to visualize your ServiceTitan data with Looker Studio**
Wouldn’t it be nice if you had a data platform that supports integration with both ServiceTitan and Looker Studio? You’re in luck because that would be Peaka.
Peaka is the ideal platform to bridge the capabilities of ServiceTitan and Looker Studio. Being a Looker Studio partner, it offers seamless integration with this BI tool. Peaka is also a [ServiceTitan partner](/partners/servicetitan-integration/) and boasts a ready-made connector for the platform, facilitating seamless data extraction.
Make sure to visit our documentation to see how you can [connect ServiceTitan to Peaka](/docs/integrations/service-titan#servicetitan) and read our step-by-step how-to guide on [Peaka-LookerStudio integration](/docs/bi-tools/looker-studio).
Peaka [virtualizes](/blog/data-virtualization-no-code/) your ServiceTitan data, allowing you to join it with data from sources like other CRMs, relational databases, and SaaS tools. Having formed a new dataset from your consolidated data, you can send it to Looker Studio and leverage the pre-made visualizations to whip up dashboards instantly.
This effortless data flow from ServiceTitan to Looker Studio via Peaka reduces the workload on data teams, which business units depend on to generate reports. It helps minimize the IT backlog from the marketing and growth teams and channels precious engineering hours to more productive tasks. This kind of connectivity also eliminates the risk of human error that would result from having to continuously update spreadsheets manually. It is a no-brainer for any organization invested in these two platforms and willing to unlock efficiencies.
## **Conclusion**
ServiceTitan serves as a central repository of knowledge for the trades. It not only collects a huge amount of data from the field but also turns that data into detailed reports decision-makers can use. However, some of its users might be looking for more advanced dashboard capabilities, which dedicated data visualization tools like Looker Studio can provide in spades.
Peaka is the ideal middleware for connecting ServiceTitan to Looker Studio. As a result of this connection, tradespeople end up having a top-notch CRM like ServiceTitan with top-notch data visualization capabilities.
If you’re using Power BI, check out our blog on [how to connect Servicetitan to Power BI](/blog/servicetitan-power-bi-integration/).
If you prefer Metabase, read our blog post on [how to connect ServiceTitan to Metabase](/blog/how-to-connect-servicetitan-to-metabase/).
Check out Peaka’s growing [library of custom connectors](/integrations/) and [book a free demo](https://calendly.com/peaka/demo) to see Peaka in action!
--- START: blog/how-to-connect-servicetitan-to-metabase/how-to-connect-servicetitan-to-metabase.md ---
# **Connecting ServiceTitan to Metabase with Peaka**
How do you grow a home service business? By expanding into new locations, so you can be closer to your customers? By adding new trades to the services you provide? Or by just running a tight ship, filling every empty slot in your schedule, and making the most of every customer call? Regardless of which option you choose, you need data to implement your strategy.
This is not an ordinary plea for being data-driven just because it’s the trend now. Being data-driven is the only way out of mediocrity if you don’t have a cool app with virality built in. In a commoditized service industry, home service businesses should leverage their data and drive efficiencies if they are to grow.
Luckily, blue-collar services like the trades have ServiceTitan to centralize their data. The California-based software company has carved out a niche for itself by building a platform that caters to the needs of the plumber, electrician, or HVAC service in your neighborhood. The company successfully nurtured this segment, reaching thousands of customers and hundreds of millions in ARR and eventually [going public](https://www.reuters.com/technology/software-startup-servicetitan-valued-897-bln-shares-jump-42-nasdaq-debut-2024-12-12/) in December 2024 at a valuation of nearly $9 billion.
## **What is ServiceTitan?**
ServiceTitan is a CRM platform purpose-built for the needs of home service businesses or trades. It is a one-stop shop for these organizations, assisting them in scheduling appointments, assessing employee performance, managing customer calls, tracking job progress, and measuring customer satisfaction.
Recognizing that home service businesses, too, have varied software needs, ServiceTitan expanded, eventually encompassing modules that can handle purchasing, communications, and inventory management tasks. For local businesses planning to lean into paid ads to grow market share, the platform offers a Google Ads integration. Combined with the reporting and dashboard capabilities of ServiceTitan, this integration empowers business teams to turn their insights into timely ad campaigns.
We will go into the details of the ServiceTitan dashboard below, but suffice it to say that it brings to the table a much-needed capability, allowing users to turn their data into visualizations and metrics that reveal hidden trends. Although it does not have the customizability that the best business intelligence (BI) tools offer, the ServiceTitan dashboard still allows users to view the essential metrics and KPIs their business requires.
## **What is Metabase?**
Metabase is a popular BI platform going up against some of the powerhouses in the market, like Looker Studio, Power BI, and Tableau. Metabase stands out from the competition with its open-source foundations, but the platform offers paid tiers for advanced features and more comprehensive customer support.
Unlike Looker Studio, Power BI, and Tableau, which cater to more varied customer profiles ranging from startups to enterprises, Metabase boasts a feature set that is a better fit for startups and SMBs. It packs a few capabilities that should appeal to organizations with small data teams:
### **Models**
One of the biggest challenges organizations face is making data accessible to domain experts with limited technical skills. Metabase offers models to fix that problem. Models are templates that combine queries with meta descriptions, giving data a more uniform structure. Thanks to this feature, users can bring in data from different tables, change the column names, and add calculated columns, ensuring teams work with the most relevant data for their roles.
### **Query builder**
Metabase turns SQL querying into a point-and-click kind of task with its visual query builder. If you are a non-technical user or someone just not confident in your rarely-used SQL skills, this feature allows you to query your data to draw business insights.
### **Pre-made visualizations**
Metabase comes with sixteen built-in visualizations that facilitate creating dashboards. Users can further customize these templates to create the perfect visualizations for their datasets.
### **SQL editor**
Most startups and SMBs rise on the shoulders of one or two data professionals if they have any. Metabase offers a query editor that enables these people to use the language they are fluent in: SQL. Technical people can use this powerful tool to generate the more detailed reports requested by business teams.
Metabase leverages these features to serve two use cases: **Self-serve analytics** and **embedded analytics**.
**Self-serve analytics** describes the primary use case wherein Metabase connects to various data sources to turn tabular data into visualizations. This is how users generate reports and create dashboards with their data by filtering it with the SQL Editor or the Query Builder.
**Embedded analytics** use case applies to B2B businesses that want to add a customer-facing analytics capability to their feature set. Instead of building a data visualization tool from scratch, businesses can embed Metabase components into their product and customize the access controls and the level of interactivity they want to offer their customers.
## **The ServiceTitan dashboard**
ServiceTitan functions as a command-and-control system for a home service business. It supports integrations with more than a hundred different data sources, which centralizes data for analysis and insights. Tax data, accounting records, payments processed, or HR-related information… ServiceTitan connects with the relevant platform to fetch whatever data you need. Moreover, it helps align the office teams with the teams in the field.
The reason for centralizing data from different sources is to turn it into actionable insights. That’s what reports do. ServiceTitan provides users with a robust reporting capability that can be tailored to the requirements of a specific business. Users can pick from tens of different attributes to generate the perfect report for their purposes.
ServiceTitan’s built-in dashboard helps users turn their tabular data into visualizations so they can track metrics and KPIs. There are four main types of metrics the platform provides:
+ Business metrics (sales, revenue, conversion, etc.) to track overall business performance.
+ Call metrics (calls, bookings, and conversions) to generate new leads.
+ Customer Service Representative metrics (inbound calls booked, taken, and leads generated) to evaluate the performance of a call center employee.
+ Technician metrics (average response time and job completion rates) to monitor the performance of field workers.
The ServiceTitan dashboard facilitates trend analysis as it produces historical data for the last 18 months or 26 weeks. A careful study of this data can reveal insights that can be used to make projections for the future.
In addition to the pre-made visualizations, ServiceTitan offers two types of ready-made dashboards to make things easier for non-technical people: The business status dashboard for monitoring business opportunities and job completion rates and the commercial dashboard for viewing business metrics like revenue and sales. These dashboards can be tailored to a certain extent to provide more granular information.
## **Why should you connect ServiceTitan with Metabase?**
The data needs of organizations can be surprisingly diverse. Even in a seemingly uniform industry like home service, location, regulations, local customs, and customer demographics have an impact on the way companies are run. This, in turn, informs how data will be reported and visualized.
ServiceTitan is a CRM platform, first and foremost. Its dashboard is an add-on that does a respectable job of visualizing data. However, it lacks the customizability to respond to niche visualization requirements, for which a purpose-built BI tool will be a better fit. These tools offer proven solutions that can be infinitely customized to specific needs.
Metabase is a particularly good fit for ServiceTitan customers as it prioritizes ease of use and primarily serves startups and SMBs. Home service businesses are highly unlikely to employ data professionals who can use highly technical data visualization platforms. Metabase’s simplicity, customization options, and pre-made visualizations allow non-technical users to self-serve, which is exactly what a typical home service business needs.
However, ServiceTitan does not readily integrate with Metabase at the moment. Manually copying your home service business data to a spreadsheet and importing that data to Metabase for visualization can be an option. However, in a dynamic work environment where data keeps flowing in from the sales, marketing, and fieldwork teams and dashboard needs abound, this is neither sustainable nor realistic. Fortunately, there is a more practical and scalable solution.
## **Using Peaka to visualize your ServiceTitan data with Metabase: Benefits**
A seamless integration between ServiceTitan and Metabase can combine the former’s reporting capability with the latter’s slick data visualization, unlocking immense value for users. Such an integration can significantly lower the technical barriers to data analytics, allowing even non-technical employees to draw insights from their data.
You can always solve this problem in the conventional way using a data warehouse and a data team. In this scenario, the data warehouse acts as the spreadsheet in the above example: It is where you move your data after copying it.
However, it is not as straightforward as copying & pasting data because you need to build data pipelines between the source and the destination so the data gets transferred with the necessary format changes. These data pipelines need to be rebuilt whenever the input or output format changes, causing a huge maintenance task that requires a data team to handle. The cost of running a data warehouse and employing a data team renders this option unfeasible for home service businesses and SMBs.
Peaka has a unique approach to this problem: Using [data virtualization](/blog/data-virtualization-no-code/), which lets you view all your data as a relational database, regardless of the source. You can then join this virtualized data with data from other sources, form new datasets, and expose them to other systems and applications.
Data virtualization simplifies how you can access your ServiceTitan data and enrich it with data from other sources, as well. Peaka, a [ServiceTitan partner](/partners/servicetitan-integration/), offers a ready-made connector for this capable platform and minimizes the data engineering challenges. Moreover, Peaka also integrates with Metabase along with other popular BI tools.
Thanks to this approach, you can query your ServiceTitan data, join it with your CRM or SaaS data, and send the end result to Metabase for visualization. As you probably noticed, there is not a word of a data warehouse or a data pipeline in the whole process.
Peaka’s ServiceTitan-Metabase integration produces four major benefits for a home service business:
+ Reduces backlog for data teams as it empowers non-technical employees to self-serve and generate reports on their own.
+ Allows home service businesses to use their scarce technical sources for more critical tasks.
+ Minimizes human error by eliminating manual copy & paste from the data integration process.
+ Helps save money as it removes the need for a data warehouse or employing a bigger data team.
## **Conclusion**
One of the goals of data integration is to break down data silos, bring together the data scattered across multiple systems, and form a single source of truth for data users. Another goal is to share your data with other applications and systems so you can take advantage of synergies and leverage new capabilities.
Our ServiceTitan-Metabase integration does just that, combining a specialized CRM like ServiceTitan with a dedicated BI tool like Metabase, giving you the best of both worlds. Although conventional data integration can be too costly and complicated for SMBs, Peaka simplifies things for these organizations with a universal middleware. The result is a seamless data flow from ServiceTitan to Metabase, slick visualizations, and profound business insights.
Visit our documentation to see how you can [connect ServiceTitan to Peaka](/docs/integrations/service-titan#servicetitan).
For step-by-step instructions on Peaka-Metabase integration, see [this document](/docs/bi-tools/metabase).
Make sure you read our blogs on connecting ServiceTitan to [Looker Studio](/blog/how-to-connect-servicetitan-to-looker-studio/) and [Power BI](/blog/servicetitan-power-bi-integration/) if you’d like to see more BI tool options.
Check out Peaka’s growing [library of custom connectors](/integrations/) and [book a free demo](https://calendly.com/peaka/demo) to see Peaka in action!
--- START: blog/how-to-create-roles-in-discord/how-to-create-roles-in-discord.md ---
# **How to Create Roles and Manage Permissions in Discord**
First launched in 2015, Discord has become one of the most popular VoIP, or voice over IP, applications with more than 140 million monthly users. The software was developed by game developer Jason Citron who had noticed how difficult it was to communicate and work out tactics with his team. Citron decided to move away from game design and create Discord with the primary goal of bringing players together and allowing them to connect with others about the games they love. Since then, the app has grown significantly, creating partnerships with companies like Xbox to enable gamers to connect their accounts, making communication even more straightforward.
Discord has also expanded beyond the gaming niche and is now used by countless other communities to allow individuals worldwide to connect. Today, some of the largest servers on the platform, such as [MrBeast Gaming](https://discord.com/invite/mrbeastgaming), [Anime Soul](https://animesoul.com/), and [Roblox](https://www.roblox.com/), have more than half a million members each.
## **What is Discord?**
Discord has gained so much popularity over the last six years with both gamers and other communities because of its unique ability to meet a variety of needs in one place. Users join a server that is dedicated to a specific game, interest, or [community](/community/). This server is made up of channels which can be VoIP, video or text channels, allowing users to communicate in multiple ways simultaneously. Having numerous channels allows messages to stay more organized by topic or group rather than just having one giant chatroom. Servers can also have read-only channels, which are a great way to keep announcements or important messages from getting lost.
Each [Discord](https://discord.com/) channel can be set as public, meaning that all server members are automatically added to the channel or private, where they need to be specifically invited. Outside of the server’s channels, users also have the ability to send direct messages to other members. They can be a member of multiple servers and easily switch between them through the Discord app.
## **How to Assign Roles in Discord**
With so many options for servers and channels, there needs to be a straightforward way to manage everything, and this is where roles come into play. Roles have assigned permissions and determine what different users can do within the server and within each channel. Discord’s default role is @everyone, which is part of every Discord server, and every user on the server is assigned this role.
Custom roles can be created in a matter of minutes and allow for more of a hierarchy within the server so that not every user can make changes to the server or channels. Roles are created within server settings, which can be accessed by clicking the down arrow next to the server’s name. In server settings, find the Roles tab to create as many roles as you’d like. When creating a role, you get to choose a name for that role as well as assign permissions.
### **To assign your new role to a server member**
+ Navigate to the Members tab within the server settings,
+ Find the user you want to assign the new role to,
+ Click the plus sign next to their name once you find the user and select the name of your new role.
The main benefit of using custom roles on a Discord server is that they allow you to meet the needs of your specific server, whether that’s by creating moderators or limiting users' permissions until they reach a certain point.
## **How to Manage Permissions in Discord**
Another aspect of creating roles in Discord is managing the permissions assigned to each role. Discord has 29 permissions ranging from administrator and management permissions to the ability to send messages or view channels.
Discord also uses a permission hierarchy, making it easy to determine what a specific user or role can and cannot do. Server wide permissions are determined by looking at the permissions given to each role an individual is assigned as well as the permissions granted to @everyone.
More specific permissions can be assigned using channel permissions which only apply to that channel. These permissions build off the server permissions and also take into account the user’s roles for that [specific channel](/integrations/) as well as the channel’s permissions.
It’s important to note that channel permissions override server permissions.
To manage permissions, go to either the channel settings or role settings, depending on which type of permissions you want to change. There you’ll see the list of permissions with a checkmark to apply the permission or an x to deny it.
## **The Bottom Line**
While all the options available to users for creating and maintaining roles and permissions in Discord can feel daunting, the documentation available on their website makes it simple to quickly and easily determine how to add or remove a role or permission from your server. As with many other popular platforms, Discord regularly releases updates and looks for ways to increase its functionality by adding new permissions and role abilities.
--- START: blog/how-to-eliminate-data-silos/how-to-eliminate-data-silos.md ---
# **Top 3 Data Integration Methods to Eliminate Data Silos**
SaaS tools are meant to increase efficiency, streamline processes, and overall make it easier for companies to compete. They are great equalizers, offering top-notch software technology in packages that even startups and SMBs afford. Without them, the startup revolution we witnessed in the 2010s would probably not be possible.
However, the proliferation of SaaS tools also causes problems for organizations. A Forrester study commissioned by Airtable revealed that companies with more than 20,000 employees “[use an average of 367 software apps and systems.](https://www.airtable.com/lp/resources/reports/crisis-of-the-fractured-organization)” The problems that this sprawl can cause were laid out by a [research conducted by Productiv:](https://productiv.com/blog/saas-statistics-that-every-it-manager-should-see/)
+ 56 percent of the apps are not managed by IT,
+ 97 percent of the IT leaders participating in the study do not have complete visibility into how these apps are used by employees.
Things are not that different on the startup front, either. A typical startup begins its journey with a bunch of SaaS tools and keeps adding to its collection as the business becomes more complex, easily ending up with tens of them in a year. Some of these apps have a limited scope, being used for certain processes and not much else. Therefore, founders need a great many of them to conduct daily operations. Others are abandoned in time as users upgrade to something better. All of these tools act as repositories of data, and unless they talk to each other, the data on one source is not available to other users.
## **An unlikely culprit**
Another factor complicating the situation is the rise of low-code and no-code tools. This huge leap in software development has caused some complications, it seems. Equipped with low-code and no-code platforms, domain experts called citizen developers can create internal tools and solve problems on their own instead of relying on central IT departments. As professionals become familiar with this technology, the pace of software development improves as well.
While companies benefit from the decentralization of app development makes organizations more agile, they have to be wary of the app sprawl it may spur. With no data integration policy in place, every app functions as a data silo and contributes to the fragmented nature of data in companies today. Companies counting on low-code/no-code technology to unlock efficiencies should do this under the guidance of the IT department in order to rein in data silos.
## **Data silos: How bad are they?**
+ Data silos [undermine the data quality](https://hevodata.com/learn/why-are-data-silos-problematic/#problematic), as isolated clusters of data become outdated, inaccurate, and inconsistent in time. Updating, correcting, and reconciling different data sets is always possible (albeit costly), but good luck finding a volunteer for that.
+ Data silos compromise the integrity of an organization’s data by denying people some part of the data produced by others. This leads to duplication of efforts as people unaware of existing data spend extra time and effort to reinvent the wheel, taking away resources that could be used for value-creating activities.
+ Teams lacking visibility into each other’s data will find it more difficult to [collaborate](https://datavid.com/blog/why-are-data-silos-problematic/#4_Less_collaboration_between_end_users), which will push them toward pursuing individual goals instead of a shared vision.
+ Data silos reduce productivity and cause employee disengagement, as employees spend up to [2.4 hours a day](https://blog.airtable.com/how-software-is-fracturing-your-organization/) trying to locate the information they need.
+ Eventually, a fragmented body of data will hamper data analysis, stifle innovation, and increase the odds that decision-makers will make wrong choices.
## **How do we tackle data silos?**
You should make data searchable and discoverable so that it will be accessible to everyone if you are to eliminate data silos. These two attributes (searchability and discoverability), combined with a data infrastructure that lets data consumers self-serve, can go a long way toward breaking down data silos. There are three concepts that embody these principles:
### **Data mesh and data fabric (for enterprises)**
Data mesh is an analytical approach that regards data silos and data sprawl as a result of [top-down data management.](https://www.zuar.com/blog/data-mesh-vs-data-fabric-vs-data-lake/#data-mesh) It proposes a decentralized data management concept built on three principles:
+ **1. Domain-oriented data ownership:** With data mesh, the ownership of data is transferred from a central IT department to people in business units who created that data. Data is owned by people who create it and know it better than anyone else, as opposed to a central IT team with little knowledge of operational domains and what users need data for.
+ **2. Data-as-a-product:** The data mesh framework regards data as a consumable product. People who produce and curate data should keep in mind that it will be consumed by a particular user profile for a particular purpose. This “product thinking” permeates the data creation process and is treated as a priority by data creators. Making data easy to find and consume prevents data silos from forming in the first place.
+ **3. Self-serve data infrastructure:** Data mesh reduces IT’s role to building and maintaining the data infrastructure. Individuals leverage that infrastructure to find and access the data they need. This arrangement lightens the workload of the central IT department and ensures that business units will be able to carry on with their operations without having to wait for IT involvement.
Data fabric shares the same principles with data mesh but involves a more [technology-centered approach](https://www.zuar.com/blog/data-mesh-vs-data-fabric-vs-data-lake/#data-fabric) to data management. While data mesh suggests a decentralized framework for data access, a data fabric makes data available through APIs or direct connection. This technology-driven method also requires a more centralized data governance under an IT department, unlike the domain-centric approach of data mesh which delegates governance to individual domains.
### **Data virtualization (for startups and SMBs)**
Although startups and SMBs have to deal with data silos at some point, the problem is not as grave as the one enterprises face. These organizations do not need sophisticated approaches like data mesh and data fabric. Considering the scale of the problem and the modest resources they possess, data virtualization offers a good solution.
Data virtualization introduces a semantic layer between data sources and data consumers, providing the latter with a unified view of data. This technique puts an end to the data sprawl because there is no need for copying or moving data during the process. A data consumer using [data virtualization](https://www.ericsson.com/en/blog/2022/1/data-virtualization-integrate-bss-data-slios) pulls in data from different sources, joins with performing ETL, and creates a single view of truth without even knowing where the data was originally located. Thanks to data virtualization, startups, and SMBs do not have to build and maintain pricey data warehouses and employ expensive data teams. This particular technique fits the needs and means of startups and SMBs like a glove.
Peaka’s new version leverages data virtualization to help startups and SMBs break down data silos. Peaka users can [integrate data in real time](/blog/data-virtualization-no-code/), form a unified view of it, and then send queries and execute analytics. By giving different users and teams visibility into the whole body of data an organization possesses, Peaka promotes collaboration and boosts employee engagement without the need for employing large data teams or needlessly complicated data infrastructure.
## **Conclusion**
Data silos are a nuisance, and a stealthy one at that. The scale of the problem they cause can be hard to gauge, and its ramifications can spread far and wide, undermining everything from daily operations to employee morale to strategic plans.
Thankfully, today, we are better equipped to deal with this problem than we were a few years back. The new concepts like data mesh, data fabric, and data virtualization are more than fancy buzzwords. They are the levers we can use to unlock the full potential of data while eliminating the headache data silos pose.
--- START: blog/how-to-get-started-with-customer-360/how-to-get-started-with-customer-360.md ---
# **How to Get Started with Customer 360**
## **Introduction**
Ever since COVID, raising capital has become increasingly challenging, with the market growing more competitive by the day. One crucial insight I've gained over the years is the immense value of your data. The more you analyze your product/customers, the higher your chances of success.
Businesses are flooded with an unprecedented volume of data, necessitating the need for a more data-centric approach. From website interactions to social media engagements and the comprehensive spectrum of customer journeys, companies are collecting extensive datasets, often characterized as a Customer 360° view. However, without suitable tools and methodologies, this data remains merely a non-aggregated collection of numbers and statistics. This is where the importance of data unification and data stack initiatives becomes evident.
{{ resize_image(path="../static/assets/images/blog-images/kerem/customer-360-data-sources.png", width=759, height=400, op='fit_width', alt="an overview of data sources available in Peaka") }}
Customer 360° encompasses the acquisition channels, 'aha moments,' preferences, and behavioral patterns of customers when interacting with a product. Various tools are designed to collect data across these customer journey stages, each catering to specific aspects of Customer 360°. By integrating these data sources onto a unified platform, businesses can significantly improve their understanding of customer behaviors.
Before exploring data source unification in detail, let's examine the components of Customer 360° and the importance of each step.
## **Components of Customer 360°**
Software solutions typically navigate through four stages of the customer journey: Awareness, consideration, evaluation, and decision.
+ **Awareness:** Potential customers are often unaware of your product; they recognize that they have a problem needing a solution, so they commence their search.
+ **Consideration:** Upon discovering your product, they start considering various options at their disposal.
+ **Evaluation:** After narrowing down their options, they evaluate how your product addresses their pain point (often signs up for free trials)
+ **Decision:** Ultimately decide if they want to convert or switch to an alternative.
### **Acquisition**
Customer acquisition marks the beginning of the awareness stage—the crucial process of finding your ideal customer profile (ICP) and raising awareness about the solution you offer. This phase involves a series of well-defined marketing and sales strategies aimed at creating brand recognition and capturing the interest of the target audience. While crucial, focusing solely on top-of-the-funnel activities without refining other stages may hinder conversion rates. It’s undeniably vital, but an excessive focus on top of the funnel (ToFu) can let your customers down over time. Filling up the ToFu without perfecting the other stages will fail them to convert into your product.
Some effective tools companies use at this segment are Google Ads, GA4, CRMs, and Intercom.
### **Activation**
The activation process guides customers to the 'aha moment,' showcasing the advantages of your product and encouraging its full use. By doing so, you’ll motivate them to use your product frequently. Without a proper onboarding and a customer activation funnel, the leads a company generates usually fail to convert into active users. The activation phase is often the most challenging in the early days, as it necessitates customers interacting with the product—hence, it often gets pushed to later days (will be the end of your venture). One should get qualified people on board and get them to interact with the product, even if they come in as a design partner (basically non-paying customer who helps with the design). As mentioned earlier, getting rich engagement data is the way to go.
To navigate your customers towards your value proposition, one has to capture their behavioral data. This can be done through various means, including databases, NoSQL databases, and event data capture tools like Segment and Jitsu.
### **Conversion**
At the end of a free trial, customers face a decision: convert to a paying customer or churn. At this juncture, the conversion process should be seamless. The pricing model should be clear, the backend transaction architecture—ideally utilizing solutions like Stripe—should operate seamlessly, and the user interface (UI) must be intuitive, avoiding unnecessary complexity.
While seemingly straightforward, many companies often struggle with conversions due to complex UI designs. Tools like Stripe or Chargebee are commonly used for payment data capture, with B2B witnessing the emergence of startups like Slope.
### **Retention**
Transitioning to a paid subscription marks a new journey—the metrics previously collected about the customers become less relevant. I can’t emphasize enough how important collecting data is at this stage—yet many startups lack the infrastructure for data analysis; many cannot even articulate the basics of their user engagement. This is the biggest problem with modern-day startups: {{ highlight_text(text="Most founders are unaware of the need to establish a pipeline for analyzing and cross-referencing engagement data.", small_text="Top Highlight") }}
Many studies revealed that more than 50 percent of the customers churn within the first year. It’s highly likely that the main reason is that the company has no idea what customers like or hate about the product. Up until this point, most efforts are focused on pre-sales activities. For many companies, post-sales engagement is limited to launching an affiliate or referral program, often without any supporting data.
Those who succeed in scaling always show post-sale tests as one of the main reasons for their scale. [YC Group Partner Gustaf highlights](https://www.youtube.com/watch?v=T9ikpoF2GH0) how Airbnb conducted thousands of A/B tests, focusing on details as little as the shape of the Gmail logo in their referral emails. EVERY. DATA. COUNTS.
## **Why Customer 360°**
Now that we’ve gone through all the segments, we can talk about why implementing a Customer 360° is not just beneficial—it’s essential for survival and growth in the early stage companies. Implementing Customer 360° is essential for startups seeking to understand their customers comprehensively, combining pre-sales and product analytics data for a holistic view.
## **Peaka: The Backbone of Customer Insights**
Tools like Peaka stand as the foundation for initiating a robust Customer 360°, allowing for the consolidation of diverse data sources into a central repository, simplifying the management and retrieval of information. Users can connect to a wide range of integrations—CRM systems, social media interactions, transaction records, or support engagements—to offer a holistic view of the customer.
{{ resize_image(path="../static/assets/images/blog-images/kerem/customer-360-integrations.png", width=759, height=400, op='fit_width', alt="a visual displaying the webhooks in Peaka") }}
The challenge of dealing with siloed customer data is common among startups. Each platform collects data in its unique format, resulting in fragmented insights. Data unification brings consistency and ensures a smooth data flow, revealing hidden patterns and insights that would be difficult to discern from isolated data sources.
The effectiveness of Customer 360° is enhanced through cross-sourcing. For example, behavioral data collected on a website via Posthog can be combined with transactional data and customer feedback gathered through Stripe and Typeform. This comprehensive dataset offers a multi-dimensional view of customers, enabling startups to refine their products, personalize marketing campaigns, and accurately anticipate customer needs.
Peaka can connect to more than 300 databases + SaaS tools + NoSQL + APIs in minutes… with a few clicks (yes, even to Snowflake). It processes real-time data directly from its sources, querying, caching, and blending data to establish a single source of truth. With its cutting-edge technology, Peaka is instrumental in supporting its customers' Customer 360° endeavors.
Peaka provides a scalable data infrastructure foundation, facilitating growth without the necessity for major system overhauls. This has led to our clients experiencing improved churn rates and a significant reduction in data warehouse and ETL expenses by up to 90 percent.
--- START: blog/how-to-trim-video-quicktime-others/how-to-trim-video-quicktime-others.md ---
# **How to Trim a Video with QuickTime and Other Alternatives**
When creating videos, it's essential that you **trim and split** your video down to keep your viewer's attention. Did you know that the average attention span of a person is now 8 seconds?
Viewers are much more likely to keep on scrolling or click away if the first couple of seconds of your video is a blank screen or in complete silence. Creating videos that are either **too long** or have too much **dead space or silence** in them can seriously harm the success of your video content – potentially impacting your viewer retention or marketing success.
However, [trimming videos](https://motionbox.io/features/trim-video) is quite a straightforward task, and you can do this directly from **Quicktime**. This method only works on devices running macOS. Therefore we will also introduce you to some compelling alternatives for trimming video quickly for PC/Windows.
## **QuickTime**
[QuickTime](https://support.apple.com/en-gb/guide/quicktime-player/welcome/mac) is Apple's default media player, but you can also use it as an editing tool to trim and cut your videos. Among QuickTime Player's features are trimming, rearranging, and rotating videos. You can also split a video into separate clips and edit each one separately. As Quicktime comes bundled with macOS, it's always going to be free to use.
Here's a quick guide to how to trim a video with Quicktime.
### Step 1: Open the QuickTime Player
On your Mac, head over to the Applications folder and find **QuickTime Player**. Alternatively, you can press **Cmd + Space** to open **Spotlight** search, type in 'QuickTime,' and hit **Enter**.
### Step 2: Find your target video
This will open up a new Finder window in which you can select your video. Find the video file and click **Open**.
### Step 3: Trim the Video
Once you open the video, select the **Edit** button and click **Trim**. You will then be met with a trim bar. Drag the yellow handles in the trimming bar to select what you need to trim.
For more precise editing, click and hold the handle to see the individual frames. Then, once you're happy with your edit, hit **Trim**.
## **InVideo**
[InVideo](https://invideo.io) is a browser-based online video editing tool with a user-friendly interface that helps you edit and create great videos in the blink of an eye. This tool allows you to trim a video with precision. You can also use this video trimmer to cut certain scenes. Follow the simple rules below to trim a video using InVideo:
### Step 1: Start a project
Once you've logged in or signed up to InVideo, you will find the option to start a new project with either a blank canvas, a premade template, or text-to-audio. Select the aspect ratio of your video canvas and start the project.
### Step 2: Trim the clip
When you have your video uploaded or created on the canvas, you will find the editable video timeline at the bottom of your canvas. Drag the ends of your video time. There is a clear mention of the minutes so that users can maintain precision while trimming a video.
### Step 3: Download and share
Now that your video is ready, you can click on the option "Download & share" in the top-right corner. You will find the option to choose the video quality (720p or 1080p). When your video is fully rendered, you can share it on the internet or save it to your system.
## **DaVinci Resolve**
[DaVinci Resolve](https://www.blackmagicdesign.com/products/davinciresolve) is a **video editing program** developed by Blackmagic and comes with features such as color correction and visual effects. It's designed for seasoned video professionals. But given that it's **free to use** and can work as an **online video editor**, many amateurs also use it to trim videos.
### Step 1: Import your video and enter “Edit” mode
First, open the DaVinci Resolve application and create a new timeline. Next, press **Control + I** to import your target video. Then, we'd want to drag that from our sources into the new timeline.
To make this edit, place the program into **Edit** mode from the bottom toolbar.
### Step 2: Enter Trim Edit Mode and Trim Your Video
Next, we'll want to hit the Trim Edit Mode selector. You can find this as the first icon to the right of the Cursor pointer at the top of the timeline. You can use the keyboard shortcut **T** to do this.
Next, select the end of your clip on the timeline. If you drag from the start or end of the video, you can cut it.
### Step 3: Export
Then, once you're done, hit **File** in the top toolbar and click **Quick Export**. This will save the video to your device.
## **OBS Studio**
[OBS Studio](https://obsproject.com/) is a free and open-source **multi-platform streaming and recording platform** mainly used to stream games and live broadcasts on the Internet. However, the program can be used to trim videos.
This method is a little more complicated than others, and therefore we'd reserve this as a last resort for tech-savvy pros. Here's a step-by-step guide to using this video trimmer.
### Step 1: Open OBS and Create a Scene
Open the **OBS Studio** app and create a scene by hitting the + button under the Scenes list. The program will prompt you to give this a name and create a blank canvas for us to play with.
Click on the new scene in the Scenes tab to launch our brand-new workspace.
### Step 2: Add a media source
Turn to the Sources tab to the right of Scenes. It should be blank. Next, let's hit the + button to add a new source. Select **Media Source** and give the source a placeholder name.
OBS Studio will then open the media properties tab. Under **Local File**, click Browse and find your target video.
It's useful to click 'Restart playback when source becomes active'. This will ensure the video starts playing once you click on the scene. Click OK, and this will add a media source to your workspace.
### Step 3: Record your Edits
Next, we'll want to click away from your scene by creating a new blank scene with the + button. This will reset the scene to be ready for our edits.
When you click on the scene with your media source, the video should start playing. Then, when you reach the point at which you'd like your final video to start, press **Start Recording**. This may take a few tries to get right. Press **Stop Recording** at the end of your desired clip. This recording will then be saved to your Videos folder.
## **Adobe Premiere Pro**
[Adobe’s Premiere Pro](https://www.adobe.com/uk/products/premiere.html) is one of the **most popular editing programs** creators, and professionals use to trim and cut videos. Unlike Quicktime, DaVinci Resolve, or OBS Studio, Premiere Pro is not free, with the service being part of the Creative Cloud subscription model.
If you're an avid video creator, Premiere Pro is a great tool. However, if you just want a video cutter to split a few videos, we'd suggest a free program to start off with.
### Step 1: Create a new Project and Import the File
First, open up Premiere Pro and insert your target video. The easiest way of doing this is finding the video in Finder or File Explorer and dragging it onto the timeline.
### Step 2: Drag the ends of the clip
To trim the video, use the select tool and hover over the ends of the clip. Drag them to the left or right to adjust the beginning and end of your video. It's that simple.
If you need to slice your video in half, use the razor tool by selecting the razor icon to the left of the timeline.
### Step 3: Export
Then, once you're happy with your clip, you can hit **File > Export > Media** to export your video. In the **Export Settings** box, select **Format: H.264** from among the available video formats and **Preset: Match Source – High Bitrate**. This is the most popular option.
## **Camtasia**
[Camtasia](https://www.techsmith.com/video-editor.html) from Techsmith is a **professional video editor designed for simplicity**. Like Premiere Pro, it's a paid platform. The program requires a one-off $249.99 payment, but TechSmith does offer a 30-day free trial. .
### Step 1: Import or record a video and insert it to the timeline
Once you've opened Camtasia, drag and drop the video from your File Export onto your timeline. The video file should already be in your clip bin if you're using the Camtasia Recorder for screen recording.
### Step 2: Drag the ends of the clip
Click and drag the ends of the video clip to trim the video. Select the video and drag it to move the clip to the beginning of the timeline.
### Step 3: Export the Video
Once you're happy with your edit, click the **Share** button in the top-right corner. Hit **Local File** to save to your device. Run through the Camtasia Production Wizard to complete the export. It's that simple!
## **Conclusion**
Apple has created a **straightforward** and **convenient way** to trim, cut, and split video clips on Mac. It's a shame this feature isn't included on the Windows version of the QuickTime player. For users on Windows, there are a whole host of free video editors for quick trims, alongside fully-fledged professional video editing programs.
Adobe Premiere Pro is a feature-rich video editing program that has become the industry-standard for seasoned pros and video creators. It's a bit overkill for a simple trim and cut, but it is nice to have if you need to create lots of videos for your social media channel or business.
Video editing is a crucial part of creating engaging video content. Make sure you've got your viewers hooked on your movies or videos by trimming and cutting your video down to remove silences, blank screens, and boring sections. Once you've mastered the art of the cut, you'll find your viewer engagement and retention sky-rocket.
--- START: blog/hrm-comprehensive-look/hrm-comprehensive-look.md ---
# **Human Resource Management: A Comprehensive Look**
Human Resource (HR) refers to all the people that work for or contribute to an organization. In addition to the regular employees of an organization working on a traditional labor contract, this term also applies to independent workers who work for the organization on a temporary basis, workers of subcontractors, freelancers and other types of people who provide services based on short-term contracts. Human Resource Management (HRM), on the other hand, is the [effective and efficient management](https://en.wikipedia.org/wiki/Human_resource_management#Birth_and_development_of_the_discipline) of these people in a way that gives their organization or company a competitive advantage.
Human Resource Management started as a one-to-one relationship between the employer and employee on issues like payment and leave at the beginning of the twentieth century. It turned into a professional and academic discipline as corporate giants employing thousands of people came to recognize the value they could further extract from their workforce with the help of a strategic management approach. Today, Human Resource Management has to be on the agenda of every organization whether it is a startup, an SMB or a global conglomerate, if they are to gain and maintain a competitive advantage over rivals.
Human Resource Management covers a host of functions that start from the day the need for hiring new people is recognized to the day the employee leaves the organization and even after. Here is a quick look at the main functions that together make up Human Resource Management.
## **Key tasks that make up Human Resource Management**
### **1 - Recruitment**
One of the most critical functions of the whole Human Resource Management process, recruitment is the way for a company to bring in new talent to sustain its value creation activity and expand its operations. It starts with the recognition that the company needs to hire new people because there is a new job created within the organization or a position has opened up. After the identification of the need, the immediate line manager works with the Human Resources department to determine the job specifications. If the internal talent pool within the company fails to produce a suitable candidate for the open position, the company will be tapping into the wider labor market to reach out to possible candidates, screen them and interview the best among them.
When the interviewers decide to hire a candidate, an offer will be prepared, followed by a contract. The new employee will then go through an onboarding process. Onboarding is a form of [organizational socialization](https://johncousins-68418.medium.com/hrm-human-resource-management-6663b3eb261e) where the new recruit hands in necessary documents and gets acquainted with skills, values and day-to-day requirements associated with the job.
All in all, recruitment might easily be the most consequential phase of the Human Resource Management process. A new employee may contribute to and enrich the existing work environment, bringing in a set of skills that makes significant contribution to the company, or undermine cohesion among the employees and cause problems that might hold the company back. Human Resource Management is definitely an area where the company cannot risk taking chances.
### **2 - Performance management**
Performance management concept is actually an evolution of the performance reviews of the past. While performance reviews were mostly an annual evaluation of an employee’s performance during the year prior, performance management takes a more dynamic approach, providing feedback on the employee’s performance supplied by different stakeholders like clients, vendors and colleagues more frequently throughout the year. Compared to a simple review, performance management is more in the mold of mentoring, with a view to improve the employee’s performance and bring it in line with the company’s goals.
### **3 - Training and development**
A significant part of modern Human Resource Management practices is based on investing in your employees so that they can reskill and upskill. This contributes to the overall satisfaction employees derive from their work while at the same time turning them into more versatile team members. Having more versatile people on your payroll in turn helps increase the the productivity of your company and its resilience in the face of adverse situations like the global pandemic we have been fighting through.
The ongoing digital transformation and automation have made it necessary for companies to invest [billions of dollars](https://learning.linkedin.com/content/dam/me/business/en-us/amp/learning-solutions/images/wlr21/pdf/LinkedIn-Learning_Workplace-Learning-Report-2021-EN-1.pdf) in upskilling training for their employees since they aim to achieve flexibility in an increasingly volatile business environment. Members of the Gen Z are known to value [career growth and mobility](https://www.forbes.com/sites/markcperna/2021/03/02/why-skill-and-career-advancement-are-the-way-to-gen-zs-heart/). Therefore, as they enter the workforce in greater numbers, it is safe to assume that they will show more interest in joining companies willing to invest in their employees. Companies that don’t offer reskilling and upskilling opportunities won’t stand much chance in hiring talented young people.
### **4 - Establishing a talent pipeline**
Companies should think long-term and make preparations for potential crises. One of the decision-makers occupying a key position may decide to quit, retire or switch to another organization. A company cannot afford to become paralyzed and lose precious time in such a situation. The wise thing to do would be to set up a pipeline and groom certain employees in the organizations for certain vacancies that can open up in the future. The pipeline can even be extended to college students by way of internships. By doing this, the company can start vetting promising talent and instilling in them its values long before these people graduate from school and join the professional life.
### **5 - Compensation**
Both monetary and non-monetary compensation play a big role in attracting and retraining talented people. It is the responsibility of Human Resources department to make sure that pay is fair with respect to the market average and the finances of the company. The global pandemic has shown that perks such as offering flexible or remote work arrangements, fitness and wellness memberships and child care could go a long way towards making a company stand out among other recruiters and attract talent who are no longer solely motivated by higher salaries.
### **6 - Termination**
Nothing lasts forever and there are many scenarios where the relationship between the employer and employee comes to end in [one form or another](https://johncousins-68418.medium.com/hrm-human-resource-management-6663b3eb261e):
- The employee might quit and look for other job opportunities in the market
- He might be fired on the grounds of low performance or problems he might be causing for the company
- The employee might be laid off as a result of measures to cope with a downturn in economy
- The employee might decide to retire
All of these scenarios come with different legal ramifications a company should consider. If the parties part ways on bad terms, the situation can pose significant risks for the employer. In addition to possible legal issues, the employee's access to databases, certain passwords and intellectual property could put the company at risk. Therefore, just like a company stands to benefit from frictionless onboarding of an employee, it also has a stake in frictionless termination of a contract with an employee.
## **What does a Human Resource Management software do?**
A Human Resource Management software automates many tasks from among the plethora of ones Human Resource people have to tend to:
- It can offer templates that expedite job posting, screen the candidates, schedule interviews in a way that best leverages empty time slots, produce offers and contracts, and facilitats the onboarding process for a newcomer by sending automated emails and offering guidance. An HRM software can also keep a detailed record of employee skills and support the talent pipeline by highlighting the suitable candidates for a job opening.
- An HRM software makes performance evaluation easier. It can use data analytics to analyze the key performance metrics, report its findings and make recommendations on how to improve the performance.
- A good HRM software can help with talent management at a company. It analyzes the skills of the workforce, the skills they can work to improve, and provide a roadmap for reskilling and upskilling initiatives.
- An HRM software can streamline payroll management tasks. It can help professionals monitor promotions and terminations, manage insurance plans for employees and put an end to miscalculations regarding the overtime work.
- An HRM software can help HR professionals manage the onboarding and contract termination phases. Automating such well-defined processes not only increases efficiency but also limits the margin for error and prevents costly mistakes.
## **What are the benefits a company can expect to derive from using an HRM software?**
- A company starts reaping the benefits of using an HRM right from the onboarding stage onwards. The frictionless onboarding eases the strain of the first few days at work for a new recruit and boosts employee morale.
- Automating certain tasks reduces the paperwork and this in turn saves time and money for the company. Automation can help reduce the HR payroll and allows HR professionals to focus on tasks where their expertise would be better employed.
- Companies can better organize their training and development needs with the help of an HRM software. The software makes it easy for the management to keep an inventory of employee skills, and invest in and develop them in a way that will contribute to the strategic goals of the company.
- Companies using HRM software can trust that there will be fewer errors during data input and reporting.
- Ensuring that a company complies with the body of rules and regulations is a difficult task that takes a full-time employee or even a team to oversee. Fortunately, legal compliance is built into HRM, which stamps out issues before they even show up.
- HRM software scales up as the company grows and eliminates the need to introduce new practices and applications just because the company grew in size.
HRM software has to be an integral part of how companies big or small operate today. In the second post of this mini series, we will be looking at what startups in particular stand to gain from using a capable HRM platform and the best options available to them.
--- START: blog/impressive-startups-no-code/impressive-startups-no-code.md ---
# **Impressive Startups Built with No-Code**
No-code platforms are disrupting the startup industry in an exciting way. With the recent developer shortage, no-code solutions allow startups to avoid paying sky-high salaries for new talent and quickly shift those resources to getting a prototype out. They also enable more startups to grow from non-tech founders that no longer need to bring in partners with direct programming experience.
Sure, it always helps to have some team members with a background in mobile app development or something similar, but the flexibility and power of the no-code or low-code movement is revolutionizing the startup industry. People with little to no experience in programming are crafting new companies faster and with less initial capital than ever before, all because of no-code platforms.
## **What does no-code mean?**
No-code is an easy-to-manage software platform that empowers people with non-technical backgrounds to create programs, mobile apps, web apps, websites, and more without using any code in the conventional sense. No-code platforms usually have a drag-and-drop interface, and help founders and entrepreneurs get their products to the MVP (Minimum Viable Product) stage and beyond much more quickly than would be possible with conventional coding.
The number and variety of digital products you can build using a no-code platform is only capped by your imagination. You can use no-code platforms for side projects to hone your skills, or you can build a full-fledged online business. Let’s take a look at some of the more impressive startups built using a no-code system.
## **1 - Lambda School**
One of the best startup examples using no-code products has got to be [Lambda School](https://lambdaschool.com/). It is somewhat ironic that an educational platform helping students learn full-stack development, blockchain, or other programming subjects was founded by utilizing a no-code system.
Lambda School is an online tech company helping students learn skills to enter the software and app-related fields. Their main competitive advantage is their ISAs or income share agreements that allow students to pay nothing upfront. Instead, they will be on the line for roughly 17% of their income after graduation until they pay back an agreed-upon amount.
The entire company was crafted with many different no-code platforms until they received enough funding and investment to create a more customized website. The point is, their MVP built with no-code was enough to grow into an exciting new business with a much smaller team than usual.
Lambda School was built using a combination of a variety of SaaS products and no-code platforms. While choosing the tools they would use to create school admission forms, manage contact scheduling or automate email, the decision makers at Lambda School made sure to pick the tools their instructors were already familiar with, and by doing that, avoided a steep learning curve.
## **2 - Kollecto, Inc.**
There is a renaissance of artistic indie creatives happening right now. All they need is a TikTok or Instagram account with a decent following, and a new business is born. The only problem is that keeping track of all these fantastic artists is next to impossible for collectors.
That is why [Kollecto](https://kollecto.com/beta/) was born. This is a web app built with no-code to connect artists and collectors, much like Spotify suggests playlists or Netflix for movies. With Kollecto, ordinary people can manage and curate their own digital galleries with direct links to the artists they love for others to purchase their creations.
The founder, Tara Reed, was able to start her no-code project for less than most waiters make in a week. Since Tara was not coming from a coding background, she leveraged no-code tools and readily-available SaaS products to get Kollecto up and running in a short time. An accelerator quickly scooped up the MVP, and the business scaled up really fast, giving Tara thousands of active users actively creating new artist portfolios.
## **3 - Rebel Book Club**
Do you want to meet a no-code startup with a ton of tenacity? Then, you need to check out [Rebel Book Club](https://rebelbook.club/). This company was founded as a subscription business where active members are sent a monthly non-fiction book and a secret meeting location in their area where they will discuss the book they read over book-inspired cocktails.
The tenacity part comes from the fact this company started close to the beginning of the pandemic. They saw massive crowds at their monthly meetings and then moved to a Zoom model to stay afloat. The good news is, their MVP was flexible enough to adjust without needing a team of programmers on the back end. Two guys run this company, and they are still getting a ton of buzz from investors because they are offering an exciting way for people to get back into the habit of reading. This is an excellent way to leverage a no-code platform with one of the greatest traditions of knowledge and entertainment around the world—reading.
The interesting part about Rebel Book Club is that, like its funding sources, all their no-code solutions were suggested by the crowd. From the very beginning of this company in May 2015, they have relied heavily on the input and influence of their community. They used no-code tools to design their website, manage member applications and integrate different SaaS products for event creating and email marketing.
All of this worked well for their guerilla-style meetings, but to get the Subscription Management toolkit, they began asking around to their community. Unfortunately, that part of the system was placed on hold due to the global pandemic. They began leveraging Zoom as their primary platform for delivering the same experience until restrictions begin to lift once again.
## **4 - Qoins**
Everyone wants a little help every now and then to keep their finances in check. [Qoins](https://www.qoins.com/) was created to save a little money while automatically setting aside portions of daily transactions to pay down any debt. It is a mobile app that takes the guesswork out of overcoming financial worry like startup Acorns has been helping investors develop a portfolio.
This system was built with low-code and no-code platforms and the product quickly moved from ideation phase in 2017 to the MVP stage in 2018. It was around this time that the investors started to show interest in the company and it received a significant amount of angel investment. Although the company later moved some of its processes to conventional code, it is still running on a no-code infrastructure to a large extent.
## **5 - Switchboard**
If we’re talking about revolutionary no-code startups, we need to mention [Switchboard](https://switchboard.media/). This company started as a way to place ad-screens on Uber and Lyft driver's vehicles. That way, you’d see an ad for your local pizza joint as you ordered an Uber to get home from the clubs. The founders quickly realized they had stumbled upon a bigger problem. Getting all those screens to sync the ads they wanted to display was next to impossible because they were using different software.
They created Switchboard to manage DOOHs (digital out-of-home media) accessible to the general public all from a single platform. Their web app allows marketing teams to easily control all the screens displaying their campaigns without contacting each one individually. Switchboard’s SaaS model is exploding in interest and drawing in investors, all from a no-code MVP.
Switchboard was another project completed using only no-code tech stack. The real fantastic point of their process was the speed with which they went from concept to MVP within 30 days, all thanks to the no-code technology.
## **What about your startup?**
The point of all this is that it is easier than ever to launch a tech-driven startup. No-code and low-code capabilities are transforming how we do business, and it begins with you.
If you have a brilliant new idea ready to move to the app stage, why not give no-code a try? That is where the expert team at [Peaka](/) can help. Our no-code development platform lets you create fully-responsive web apps in an easy-to-understand drag-and-drop visual designer and helps you take the first step to build your own successful startup!
--- START: blog/innovation-in-the-age-of-no-code/innovation-in-the-age-of-no-code.md ---
# **Innovation in the Age of No-code**
Napoleon Bonaparte is the man usually credited with the phrase “An army marches on its stomach.” He was right because the range of military operations at the beginning of the nineteenth century mostly depended on availability of food supplies. Apparently a man who put his money where his mouth was, Napoleon [offered a prize of 12,000 francs](https://www.cancentral.com/can-stats/history-of-the-can) to anybody who would invent a technique for preserving food. By doing that, he had officially kicked off the research into canned food and started an era of continuous improvements in food preservation, packaging and transportation technology. The effort eventually paid off by making possible even overseas military operations that mobilized millions of soldiers in the two World Wars. Tin and food had been available for centuries. Figuring out a way to use the former to preserve the latter—that was innovation.
Innovation is one of those terms whose definition changes according to the context, and thus might be tricky to put your finger on. It may refer to processes that bring about a novelty or to products or services that are the outcomes of these processes. For these products, services or processes to be seen as innovations, they should capture or redistribute value. Anthony W. Ulwick, in his book [*Jobs to Be Done*](https://www.amazon.com/Jobs-be-Done-Theory-Practice-ebook/dp/B01M73AP2I/ref=sr_1_2?dchild=1&keywords=jobs+to+be+done&qid=1626610531&sr=8-2), defines the goal of innovation as devising “solutions that address unmet customer needs” (Ulwick, 2018, p.51).
In the past, innovation was considered a result of a eureka moment where a gifted person, as if guided by divine inspiration, would come up with a bright idea. This approach viewed innovation as a game of chance that was not repeatable at all (Ulwick, 2018, p.51). This last point spurred attempts throughout the twentieth century aiming to place innovation on a more scientific footing.
We have previously seen how the [Japanese school of thought](/blog/no-code-for-manufacturing-industry-1/) handled this issue and came up with some of the most ingenious ideas in scientific management. The Americans, too, produced their fair share of thinkers and concepts in this field. Engineers like [W. Edwards Deming](https://en.wikipedia.org/wiki/W._Edwards_Deming) and [Joseph M. Juran](https://en.wikipedia.org/wiki/Joseph_M._Juran) and concepts like Six Sigma and Total Quality Management helped save innovation from the grips of happenstance and the heroics of a few insanely talented people. It was finally conquered, having been made predictable, continuous and sustainable through the use of particular techniques. Today innovation arises from well-designed processes in an incremental fashion.
Then, there is the issue of building a sustainable competitive edge on innovation. The late American scholar Clayton Christensen, in his book [*Competing against Luck*](https://www.amazon.com/Competing-Against-Luck-Innovation-Customer/dp/0062435612/ref=sr_1_1?crid=NPSBQQOMHN88&dchild=1&keywords=competing+against+luck&qid=1626608826&sprefix=david+landis,aps,296&sr=8-1), argued that processes specifically designed to satisfy unmet customer needs would do the job (Christensen et al., 2016, pp.139-40). Processes have human and social components and this renders them virtually theftproof, serving as a source of competitive advantage. But for this to happen, innovation should become part of a shared culture and mindset first.
Innovation is a costly endeavor. It takes quite a lot of time and money to bring a new product to the market. Too long of a development phase could mean losing the market to early movers. Too high of a production cost could scuttle the project from the start. Frost & Sullivan [argues that](https://ww2.frost.com/growth-opportunities/new-product-development/) only 1 in every 100 new products cover their development costs. This stat alone is enough to rule out the conventional waterfall project management practices. Today more than ever, companies have to remain agile, nimble on their feet rather than commit to a project whether it’s sink or swim. The idea is to act fast, form a hypothesis as quickly as possible, build a prototype to test the hypothesis and modify it in case it does not hold, which is highly likely. Expediting failure rather than postponing it, learning from failure and pivoting as necessary is what drives innovation. This gradual approach makes much more sense than going all in on a risky project and investing months and significant sums of money.
For tech startups, there is no-code technology, thankfully, which negates the risk of investing in a project that might potentially turn out to be fruitless. No-code platforms such as [Peaka](/) make it easier for tech entrepreneurs to test their business ideas without having to hire developers, let alone make even bigger investments in staff or equipment. Once it is safe to say that there is a business case for a particular idea, it is easy to launch and scale up in sync as the volume of business picks up. [Eliminating the need for technical co-founders](/blog/non-technical-founder-no-code/) and making it possible to develop proofs of concept on the cheap—no-code platforms are removing one by one the entry barriers for tech entrepreneurs.
--- START: blog/integrate-servicetitan-with-quickbooks-xero-sage/integrate-servicetitan-with-quickbooks-xero-sage.md ---
# **How to Integrate ServiceTitan with Accounting Software**
Consultants working with ServiceTitan operators already know the drill: Clients want visibility into both field performance and financial health, but those numbers live in separate systems. ServiceTitan tracks jobs, bookings, and technician KPIs. Revenue, expenses, and margins are best handled by QuickBooks, Xero, and Sage Intacct.
To deliver meaningful insights, you need to bring those datasets together. If you’re still relying on spreadsheet exports, VLOOKUPs, or copy-paste routines to achieve that, you’re not just losing time but also accuracy, scalability, and revenue opportunities.
Luckily, there’s a better way.
## **Why combining operational and financial data leads to actionable insights**
What your clients want is answers, not just. Answers to questions like:
+ Are we making money on every job?
+ How much revenue does each technician generate?
+ What’s our actual gross margin after labor and materials?
To answer these, you need to join ServiceTitan’s operational data with accounting data from platforms like QuickBooks, Xero, or Sage Intacct.
But here’s the problem: Those systems don’t talk to each other out of the box. So, consultants spend hours exporting reports, cleaning data, and trying to manually stitch them together. While feasible for an individual client, this approach quickly proves unmanageable when dealing with multiple clients.
## **Why traditional workflows break down**
Most consultants cannot readily access engineering resources or custom ETL pipelines. They often fall back on low-code products on the market, which tend to overpromise and underdeliver, and frequently require technical adjustments to work across clients using different platforms.
Left to their own devices, consultants resort to traditional methods, which come up short:
+ **Every client uses a different setup:** Some use QuickBooks Online, others use Xero or Sage Intacct. Different platforms mean different standards and more manual work.
+ **Manual exports are error-prone:** One change in a client’s report layout and your formulas break.
+ **Data is stale:** You’re coaching off static snapshots, not live KPIs.
+ **Scalability is impossible:** The more clients you take on, the more spreadsheet chaos you inherit.
## **Meet Peaka: Your integration layer for financial + ops data**
Peaka, [an official ServiceTitan partner](/partners/servicetitan-integration/), provides a data integration layer that unifies ServiceTitan data with financial information from platforms like QuickBooks, Xero, and Sage Intacct. This unified data can then be seamlessly exported to your preferred BI tool (e.g., Power BI, Looker Studio, Metabase) without requiring any coding or custom development.
Peaka is not a dashboard tool, but rather an innovative solution that simplifies data integration and visualization with
+ **Prebuilt connectors:** Peaka offers native integrations for ServiceTitan, QuickBooks, Xero Accounting, and Sage Intacct.
+ **Zero-ETL data integration:** Peaka eliminates brittle ETL pipelines and expensive data warehouses from the data integration process.
+ **Multi-client workspace:** Consultants can use Peaka to manage accounts for multiple clients from a single interface without having to reinvent the wheel every single time.
+ **Push to BI tools:** Send the cleaned, combined data to Power BI, Looker Studio, or Metabase—whichever platform your client prefers.
With Peaka, consultants eliminate repetitive tasks, reduce risk, and deliver insights that actually move the needle.
## **Consultant workflow: Before and after Peaka**
**Before Peaka:**
+ Consultant manages 12 ServiceTitan clients.
+ Six use QuickBooks, three use Xero, and three are on Sage Intacct.
+ For each client, the consultant downloads reports, cleans data manually, and joins datasets in Excel.
+ Time spent per client: 5–8 hours/month.
+ Risk of errors, high; scalability, low.
**After Peaka:**
+ The consultant connects each client’s ServiceTitan account with their accounting platform only once.
+ Peaka enables the consultant to query data across different sources, filter the results, and create new datasets.
+ The consolidated data is then sent to a standard BI template.
+ This entire setup is easy to replicate across similar clients with one click.
+ Time spent per client: ~1 hour/month.
+ Live, reliable KPIs in every coaching session.
## **The business case for doing this the Peaka way**
In addition to making you more efficient, integrating ServiceTitan data with accounting data also makes your services more valuable.
+ **Less room for error:** With CSV downloads, spreadsheets, and manual data replication out of the way, data errors are minimized.
+ **Faster time-to-value:** Show ROI faster during onboarding.
+ **Enhanced offerings:** [Offer real-time KPI dashboards](/blog/consultants-servicetitan-kpi-dashboards/) as part of your consulting packages.
+ **Client retention:** Use live financial + ops metrics in monthly coaching to draw insights, drive action, and improve customer retention through value creation.
+ **Light on engineering resources:** Your team owns the process, from start to finish.
## **Getting started is simple**
With Peaka, you’re just a few steps away from building smarter, scalable reporting for every client:
1. Connect ServiceTitan with your client’s accounting tool
2. Query the data sources you connected to and filter your data
3. Send the data to [Power BI](/blog/servicetitan-power-bi-integration/), [Looker Studio](/blog/how-to-connect-servicetitan-to-looker-studio/), or [Metabase](/blog/how-to-connect-servicetitan-to-metabase/)
4. Repeat the process and adapt across clients in minutes
## **Key takeaways**
+ Peaka automates **data integration between ServiceTitan and accounting platforms** like QuickBooks, Xero, and Sage Intacct, eliminating the need for manual exports.
+ Consultants can use Peaka to **deliver unified, BI-ready data** across operational and financial systems, which facilitates insights and more strategic client coaching.
+ No technical expertise is required, allowing boutique consulting firms to **scale reporting services** without hiring developers.
## **Conclusion: Skip the spreadsheets, keep the insight**
For ServiceTitan consultants, integrating operational and financial data has always been necessary, but until now, it’s also been painful.
Peaka gives you the automation, scalability, and control you need to deliver fast, accurate insights to your clients without exporting another CSV.
Ready to streamline reporting and scale your services?
[Sign up to Peaka](https://peaka.studio/signup) for free today.
[Book a quick demo](https://calendly.com/peaka/demo) and see how Peaka can help you integrate ServiceTitan with accounting platforms for your clients.
--- START: blog/integrations-hubspot-stripe/integrations-hubspot-stripe.md ---
# **How to Create One-Click Reports with HubSpot and Stripe**
## **Introduction**
How can you make sure that your product meets the type of customer you built it for? Have you completed your ideal customer profile? Who are your best-fit customers? These are the million-dollar questions marketing teams have to find answers to. Peaka's HubSpot-Stripe integration gives marketing professionals a tool they can use to perfect their customer segmentation.
## **Key takeaways**
+ Peaka's HubSpot-Stripe integration brings together the data stored on these two platforms.
+ This integration enables marketing and sales teams to break down data into its country- and company-based constituents for further analysis.
+ Peaka's HubSpot-Stripe integration reduces the workload of frontline workers who would otherwise have to manually enter the data in spreadsheet software and consolidate it through copy-and-paste actions.
+ Integrating the HubSpot data with data from Stripe helps a company pursue an **Account Based Marketing** strategy and focusing resources on targeted high-value accounts.
+ The HubSpot-Stripe integration gives decision-makers real-time access to critical [SaaS business metrics](/blog/saas-business-metrics/) like MRR or revenue from a deal and how they change in relation to country, industry, or company size.
## **What's HubSpot?**
HubSpot is a one-stop shop for inbound marketing, sales, and customer service. It's a cloud-based CRM platform that allows users to build marketing and sales funnels and take action to improve customer service.
## **What's Stripe?**
Stripe is a payment processing platform used primarily for e-commerce transactions. Stripe users take advantage of a suite of APIs to make payments with their credit or debit cards.
## **What does Peaka's HubSpot-Stripe integration offer?**
Bringing HubSpot and Stripe data together can provide users (especially marketing and sales teams) with valuable customer information. This integration allows users to break the data down into country- and company-based constituents. Companies that can analyze their data at the country and company level can refine their customer segmentation and implement an **[Account Based Marketing strategy](/blog/account-based-marketing-saas/)**.
Account Based Marketing involves targeting and reaching out to specific customer groups using material customized to their needs. Instead of engaging in blanket marketing and diluting the message by trying to address everyone, this strategy channels marketing resources to high-value accounts.
[Peaka's HubSpot-Stripe integration](/integrations/hubspot-stripe/) lets users dive deep into customer data and pinpoint who they should target. Here's a brief look into the kind of insights users stand to gain from a country- and company-based breakdown of their data:
### **1. Country-based data**
Customers from different countries tend to have different spending habits as purchasing power, demographics, and attitude toward online shopping may differ. A country-by-country breakdown of the customers can be very informative for understanding customer behavior and help guide future communication and marketing efforts.
The HubSpot-Stripe integration allows the user to pull 'country' data from HubSpot and combine it with 'pricing plan selected,' 'amount charged,' and 'invoice paid' data from Stripe. This integration gives you valuable insights into how your MRR and revenue differ from one country to another. It also reveals whether the demand for different pricing plans varies depending on the location.
#### **What can marketing and sales teams do with country-based data?**
+ Design new campaigns for upselling to companies from specific countries that predominantly opted for certain pricing plans
+ Single out the most promising countries to start high-impact campaigns
### **2. Company-related data**
The HubSpot-Stripe integration makes it possible to break company-related data down into lower-level metrics based on industry, staff size, and annual revenue.
#### **2a. Industry-based breakdown**
An industry-based segmentation of customers lets you see the impact macroeconomic conditions like a recession, inflationary tide, or a pandemic have on companies from different industries. This kind of data comes in handy as you try to forecast future revenue and prepare marketing and sales plans.
Take subscriptions, for example. Some industries have cyclical characteristics regarding when the majority of subscriptions start or get renewed. Having this information at hand, one can devise different outreach campaigns, schedule marketing activities to nurture the buying intent of potential customers well in advance, and, as a result, achieve higher conversion rates.
If you wish to see how your MRR and revenue from a deal or the selected pricing plan interact with the industry a company operates in, just get the 'industry' data from HubSpot and combine it with the 'pricing plan selected,' 'amount charged,' and 'invoice paid' data from Stripe. Now you can see how parameters like MRR and revenue from a deal or the pricing plan selected change in relation to the industry a company operates in.
#### **2b. Size-based breakdown**
The number of employees is a telling figure widely used by marketing teams for segmentation purposes. Knowing how many employees work for customers can help marketing and sales teams anticipate their customers' future needs and spending habits.
To gain a better understanding of your customers, all you need to do is to bring together the 'company size' data from HubSpot with the 'pricing plan selected,' 'amount charged,' and 'invoice paid' data from Stripe. Now, you can analyze how parameters like your MRR and revenue from a deal or the pricing plan selected change in relation to the company size.
#### **2c. Annual revenue-based breakdown**
Seeing a breakdown of your customers by the annual revenue they earn speaks volumes about who your product resonates with. It's an indispensable metric if you want to identify the characteristics of your best-fit customers.
Connecting HubSpot to Stripe makes it easier to gain this kind of insight. Pull the 'annual revenue' data from HubSpot and join it with the 'pricing plan selected,' 'amount charged,' and 'invoice paid' data from Stripe. Now you get to see how parameters like your MRR and revenue from a deal or the pricing plan selected vary in relation to annual revenue. Combine your findings with 'country' and 'industry' data, and your segmentation gets even more precise.
#### **2d. IPO-based breakdown**
You can also take advantage of the HubSpot-Stripe integration to determine the public companies among your customers.
Combining the 'IPO' data from HubSpot with the 'amount charged' and 'invoice paid' data from Stripe allows you to find out how much of your revenue comes from public companies. Armed with this information, you will be in a better position to adjust your marketing and sales plans accordingly.
#### **2e. Funding-based breakdown**
The HubSpot-Stripe integration also gives you visibility into how your product is received by venture-backed companies.
To achieve that, you just have to bring in the 'total money raised' data from HubSpot and join it with the 'amount charged' and 'invoice paid' data from Stripe. Now you can analyze how your MRR from a particular company changes in relation to the funding raised by that company.
#### **What can marketing and sales teams do with company-based data?**
+ [Form an ideal customer profile](/blog/saas-ideal-customer-profile/) using the industry, staff size, and MRR figures
+ Single out industries with the highest-value accounts to target
+ Run more effective marketing campaigns with material tailored to the needs of the target group
+ Harmonize marketing and sales efforts
+ Achieve a more rational use of marketing dollars by focusing on better prospects to target with paid ads
+ Shorten the sales cycles by prioritizing outreach to more receptive prospects
+ Measure the marketing ROI in a more precise manner
## **Conclusion**
The HubSpot-Stripe integration can provide marketing and salespeople with a treasure trove of information. It is the kind of tool that puts a face to being data-driven and ensures a better allocation of resources.
The HubSpot-Stripe integration saves frontline workers a lot of time and effort in unifying their data and planning their marketing activities. It serves the lofty goal of "eliminating data silos," which can be a challenge in the absence of a [top-notch data integration tool.](/blog/top-data-integration-tools/) Without properly integrating HubSpot and Stripe, an employee would have to first enter the data in spreadsheet software and manually merge it through copy-and-paste actions. Considering this alternative method, the HubSpot-Stripe integration is a total revelation.
For managers and corporate decision-makers, this integration provides a single view of truth, leading to a better strategy. Real-time access to country- and company-based MRR can help them better understand the current situation, gain actionable insights, form new hypotheses, and adjust plans as needed.
--- START: blog/investors-hard-tech-revival/investors-hard-tech-revival.md ---
# **The State of Hard Tech**
The last two decades were all about cloud and SaaS tools built on top of that for the tech industry. What we witnessed was "the end of software," as Marc Benioff of Salesforce had prophesied in 1999. The software sold in boxes and came in CD-ROMs was no more.
This development particularly transformed startups and SMBs, making software more affordable for them. Cloud and SaaS turned out to be great equalizers, leveling the playing field for startups, SMBs, and enterprises. These two innovations helped promote online collaboration, streamline processes, increase efficiency, and reduce costs for every customer. Looking back, what cloud and SaaS accomplished was nothing short of a “revolution in business operations.”
## **"*Where is my flying car, dammit!*"**
The democratization of software and efficiency gains achieved in daily operations are laudable outcomes. However, despite these wins, the digital revolution is not comparable to the scientific achievements of the previous century. No matter how impressive the technologies of the last two decades are, apps and widgets can't hold a candle to the life-altering developments of the previous century: The invention of penicillin and the resultant increase in average life span, the Moon landing, the emergence of air transport, the successful commercialization of new technologies like electricity, internal combustion engine, telephone, etc.
The disillusionment with the achievements of the tech industry in the last two decades is best summed up [in the words of Peter Thiel](https://thevcfactory.com/we-wanted-flying-cars-instead-we-got-140-characters-peter-thiel/):
> "*We wanted flying cars; instead, we got 140 characters.*"
But how did that happen? Did we lose our mojo in the last quarter of the twentieth century? Was it because people just had bigger dreams in the 1960s? Do we lack the audacity of the previous generations to try and change the world?
## **"Me-too" investors for "me-too" ideas**
While analyzing why the tech industry is not interested in tackling big problems, part of the blame must go to the institutional and individual investors controlling billions of dollars of capital. Investing acts as a signaling and incentivization mechanism for entrepreneurs. Ideas that get rewarded with funds inspire similar ideas elsewhere. As a result, founders are drawn to developing "me-too" products that do not define a new product category but remain content with copying a successful incumbent in the market. Investors tend to favor these "safe bets" and steer clear of projects exploring uncharted territory.
However, founders are not the only stakeholders guilty of imitation in the startup world. Just as cloning ideas is seen as a viable business model among founders, imitating fellow investors has become the order of the day for investors. [Paul Graham](http://www.paulgraham.com/hiresfund.html) puts it succinctly:
> "*By far the biggest influence on investors' opinions of a startup is the opinion of other investors. There are very, very few who simply decide for themselves. Any startup founder can tell you the most common question they hear from investors is not about the founders or the product, but 'who else is investing?'* "
So, it turns out that the majority of investors we admire for their foresight and business acumen are just bandwagoners copying their rivals. That is surprising, considering that most venture capitalists and angel investors profess to chase outsized returns in light of the famous "power law." Apparently, they talk the talk, but only very few of them dare to walk the walk.
The herd mentality demonstrated by investors during decision making contradicts the ambition to win big with the next investment. How can you expect to beat your rivals by 100x or 1000X when you copy their investing practices? [Consensus investments](https://foundersfund.com/the-future/#/conclusion), even when they pan out, do not produce spectacular gains.
Still, not every investor is happy following the crowd. For example, Peter Thiel is charting a different course nowadays, focusing on projects attacking big problems. Thiel was one of the co-founders of PayPal. He wrote the first cheque for Facebook in 2004 and went on to become one of the godfathers of the prevalent Silicon Valley culture. Today, Thiel seems to have seen the light finally, distancing himself from the conventional investing practices of the day. He is mentoring young rebels like Vitalik Buterin, funding ambitious college dropouts, and backing projects that will reverse human aging or build [anarchic off-shore communities](https://www.newyorker.com/magazine/2011/11/28/no-death-no-taxes).
Whether it is his guilty conscience for his role in creating the app-driven tech culture or escapism from this reality, Thiel is putting his money where his mouth is. At Founders Fund, where he is a partner, [20 percent of the capital](https://foundersfund.com/the-future/#/introduction) comes from the partners themselves. In an investment world where investors like to gamble with other people's money, that speaks volumes about the man.
## **The winds of change**
The last few years have proved Peter Thiel right. There is a renewed interest in hard tech companies seeking solutions to big problems. Hard tech refers to initiatives "[that require immense imagination and innovation](https://www.pcmag.com/encyclopedia/term/hard-tech)" to develop breakthrough products. The technology and engineering involved in these initiatives tend to be so complex that the risk of failure is deemed quite high.
This revival of interest benefits from how our daily lives have come to be threatened by unusual developments lately. It was first the climate-related problems like extraordinary droughts or extreme summer floods that opened our eyes to the fact that we could no longer ignore global warming. This awareness triggered a novel look at industries like energy, automotive, agriculture, and construction.
Then the Covid-19 pandemic happened. It proved that a single virus could hold the whole of humanity hostage for months, urging us to keep investing in health, biotech, genetics, and chemistry to stop that from happening again.
In February 2022, it was the war that disrupted our lives regardless of where we lived. The Russian invasion of Ukraine reminded us that food security was something a country could not delegate to another country and that energy security was a strategic issue. A winter with rising food and energy prices will make sure that these topics remain popular.
It is no surprise that people are turning to hard tech companies to deal with these big problems. Thankfully, the interests of humanity at large and those of the investors finally seem to have aligned. We may hope to see real progress (not mere efficiency gains) really soon.
## **Final thoughts**
"*Necessity is the mother of invention,*" as the proverb goes. If that holds true, we may expect a new wave of inventions at a time humanity is tested by monumental challenges. The stage seems set for the return of hard tech. Maybe it is time for investors to stop worrying about "*Who else is investing?*" and back those founders who have the audacity to envision a radically different and better world.
--- START: blog/job-marketplace-template/job-marketplace-template.md ---
# **The JobPointer Template Facilitates the Ideal Job Search**
No other phenomenon since World War II has made as significant an impact on the labor market as the Covid-19 pandemic has. What we have been through in the last two years might have forever transformed work and office life as we knew them.
The technology sector traditionally had a high turnover rate for years. This is partly a result of the dynamism of the sector, with startups turning into unicorns in a few years and attracting talent like a magnet. Part of it is due to the characteristics of the workforce—highly educated and always in demand regardless of the location. Switching careers every few years for higher pay and more responsibility is nothing unusual in the software industry. What is unusual is this phenomenon spreading to other sectors.
[47.4 million Americans](https://www.cnbc.com/2022/02/01/roughly-47-million-people-quit-their-job-last-year.html) quit their jobs in 2021, with 4.3 million in December alone. Termed as “[The Great Resignation](https://www.businessinsider.com/why-everyone-is-quitting-great-resignation-psychologist-pandemic-rethink-life-2021-10)” by Anthony Klotz, an associate professor of management at Texas A & M University, this phenomenon baffled scholars and economists. Theories as to its causes abound.
+ The pandemic prompted older employees to seek [early retirement.](https://www.npr.org/2021/08/23/1028993124/these-older-workers-hadnt-planned-to-retire-so-soon-the-pandemic-sped-things-up) They probably thought continuing their careers during the pandemic was not worth it.
+ Some people took this opportunity to realize their business ideas and try their luck as entrepreneurs.
+ The health risks and lockdowns forced employees in their primes to get their priorities straight and act accordingly. These priorities are particularly reflected in employees’ preference for a hybrid work arrangement. The 2021 Work Trend Index commissioned by Microsoft found that [73 percent of employees](https://www.microsoft.com/en-us/worklab/work-trend-index/hybrid-work) wanted flexible remote work options to continue in some form after the pandemic.
+ [Low-wage earners](https://www.investopedia.com/the-great-resignation-5199074) got a chance to receive better pay by changing jobs.
It was this last point that made scholars and HR people rethink the massive transformation in the labor market. Low-wage earners were thought to be more conservative in changing careers and value job stability more than high-wage earners did. Not anymore. The accommodation and food services sector in the U.S., which is traditionally characterized by low wages, saw [a spike](https://fred.stlouisfed.org/series/JTS7200JOL) in job openings in 2021, with [more than 10 percent of jobs](https://www.restaurantbusinessonline.com/workforce/restaurant-workers-are-quitting-historically-high-rates) remaining vacant as of August 2021.
It turns out what has been coined as “The Great Resignation” was low-paid employees taking a page out of developers’ books. Low-wage workers are enjoying an unusually high level of bargaining power vis-à-vis the employers. There are more jobs than ever before, people are leaning on their savings and stimulus checks they received from the governments to weather the storm, and nobody seems to be in a rush to work in less than ideal conditions. Apparently, the easing of lockdown measures has created a great demand for workers. Some employees left their jobs for greener pastures with better terms and higher pay, luring others to take their places and setting off a chain reaction of sorts.
Bharat Ramamurti, the National Economic Council Deputy Director, defines this phenomenon as “[The Great Upgrade](https://twitter.com/BharatRamamurti/status/1480590753592135693).” It involves companies [vying to attract talent](https://edition.cnn.com/2022/02/07/economy/great-resignation-jobs/index.html) and offering higher salaries, signing bonuses, remote and hybrid work arrangements, and other perks to sweeten the pot. Some others prefer describing this as “[The Great Negotiation](https://www.npr.org/sections/money/2022/01/25/1075115539/the-great-resignation-more-like-the-great-renegotiation)” or “[The Great Reshuffle,](https://www.weforum.org/agenda/2022/02/great-reshuffle-jobs-market-resignation/)” but the main idea stands.
Pandemic had a serious impact on the traffic job search websites attract. Job search websites saw a significant decline in traffic during the first half of 2020. The traffic for the whole segment was down [14.6 percent](https://www.similarweb.com/corp/blog/research/market-research/digital_100_revisited/) on the year. Long lockdowns, non-existent demand in many industries, and the uncertainty about the possible trajectory of the pandemic all played a role in that sharp decline.
As the economic prospects improved in 2021, so did the traffic and revenue for those websites. The financials of Recruit Holdings Co. Ltd, the parent company of top job search websites like [Indeed](https://www.indeed.com/) and [Glassdoor](https://www.glassdoor.com/index.htm), offers us a peek into this remarkable turnaround. The company’s HR Technology segment, under which Indeed and Glassdoor are listed, enjoyed a [107.3 percent](https://www2.staffingindustry.com/Editorial/Daily-News/Recruit-revenue-up-23-in-fiscal-Q2-but-increase-in-Indeed-Glassdoor-division-is-more-than-100-59743) year-on-year increase in revenue in the second quarter of 2021, showing us that the pandemic is behind us as far as the job market is concerned.
For people willing to take advantage of this surge in interest in job search websites, Peaka has launched a job marketplace app template: [JobPointer.](/templates/) This template lets you build a marketplace app that brings together employers and employees. The former can use the app to handle job postings and keep track of applications for vacant positions. Employers cannot risk making the wrong call in hiring at a time when the labor market is unusually active, and they no longer enjoy the upper hand. JobPointer will give them the best chance to attract talent. On the other hand, employees can upload their resumes to the app and manage their applications. With so many options to choose from, they will benefit from the structure JobPointer will introduce into their job hunting processes.
For people willing to capitalize on the sea change taking place in the job market, JobPointer is ready to show the way.
--- START: blog/list-calls-multiple-servicetitan-accounts/list-calls-multiple-servicetitan-accounts.md ---
# **Listing Call Data from Multiple ServiceTitan Accounts**
As a ServiceTitan consultant, you're constantly juggling calls data across dozens of client accounts. Whether you're preparing monthly [KPI dashboards](/blog/consultants-servicetitan-kpi-dashboards/), analyzing call performance for coaching sessions, or delivering dashboard updates to multiple clients, [manual data exports](/blog/servicetitan-manual-data-export-costs/) from each ServiceTitan instance are eating up your billable hours.
Peaka transforms how consulting firms deliver ServiceTitan analytics. Instead of building custom dashboards for each client or wrestling with spreadsheet exports, you can instantly [unify data from multiple ServiceTitan accounts](/blog/manage-multiple-servicetitan-accounts/) using natural language queries—no coding required.
In this guide, we'll show you how to connect multiple client ServiceTitan accounts to Peaka and use our AI chatbot to instantly retrieve calls data for any client—turning hours of manual work into minutes of automated insights.
## **Setting Up Your ServiceTitan Connections**
Before you can query calls data for your clients, you'll need to connect their ServiceTitan accounts to Peaka. The process is straightforward and takes just a few minutes per client.
First, navigate to the Connections section in your Peaka workspace and select ServiceTitan from the available integrations. You'll need API credentials from each client's ServiceTitan admin panel—most clients can generate these quickly with your guidance.
Once connected, Peaka will automatically sync each client's ServiceTitan data, including calls records, customer information, and call tracking data. This gives you immediate access to query calls data across your entire client portfolio from a single workspace.
For detailed step-by-step instructions, check out our comprehensive guide: [Connect your ServiceTitan Account to Peaka](/docs/integrations/service-titan)
## **Getting Client Calls Data in 4 Simple Steps**
Once your clients' ServiceTitan data is flowing into Peaka, retrieving calls information for any client becomes incredibly straightforward. Here's how to pull calls data from multiple client accounts:
### **Step 1: Write your query**
Navigate to your Peaka workspace and create a new query. Select the **AI|GPT** section to access our natural language query interface.
_Pro tip: New to Peaka queries? Check out our [comprehensive guide](/docs/connecting-your-data/peaka-query#what-is-a-peaka-query) to get up to speed._
### **Step 2: Ask in natural language**
Simply type your request in natural language. For example:
```
List all calls from all of my ServiceTitan accounts.
```
{{ resize_image(path="../static/assets/images/blog-images/list-calls-multiple-service-titan-accounts-1.png", height=450, width=750, op='fit_width', center='true',alt="Entering prompt to Peaka AI chatbot") }}
### **Step 3: Select your data sources**
Peaka will automatically suggest the relevant tables. For calls data, you'll typically need:
- **Calls Table**: `your_service_titan_connection > telecom > calls`
{{ resize_image(path="../static/assets/images/blog-images/list-calls-multiple-service-titan-accounts-2.png", height=450, width=750, op='fit_width', center='true',alt="Selecting relevant tables in Peaka") }}
### **Step 4: Execute and analyze**
Hit run and watch Peaka generate the SQL query behind the scenes. Your results appear instantly, showing all calls from your client's ServiceTitan account with complete details—ready to drop into your monthly KPI report or coaching session.
{{ resize_image(path="../static/assets/images/blog-images/list-calls-multiple-service-titan-accounts-3.png", height=450, width=750, op='fit_width', center='true',alt="Query results showing calls data") }}
## **Conclusion: Deliver premium analytics without the overhead**
As a ServiceTitan consultant, your time should be spent coaching clients and growing your practice—not wrestling with data exports and dashboard builds. With Peaka's AI chatbot, you can deliver professional calls analytics to any client in minutes, not hours.
Whether you're preparing monthly KPI reports, analyzing call performance trends, or building premium dashboard offerings, you now have the tools to scale your consulting practice without hiring developers or learning complex [BI tools](/blog/how-to-connect-servicetitan-to-looker-studio/).
Ready to transform your ServiceTitan consulting delivery? Your next client success story is just one conversation away.
[Sign up to Peaka](https://peaka.studio/signup) for free today.
[Book a quick demo](https://calendly.com/peaka/demo) and see how Peaka can help simplify ServiceTitan reporting for you and your clients.
--- START: blog/list-employee-jobs-servicetitan/list-employee-jobs-servicetitan.md ---
# **Listing All Jobs for an Employee in ServiceTitan Using Peaka**
Managing employee performance in ServiceTitan requires quick access to job data. Whether you're tracking technician productivity, analyzing job completion rates, or preparing performance reviews, you need an efficient way to pull all jobs assigned to specific employees.
Peaka offers multiple ways to access and analyze your ServiceTitan data—through SQL queries, table views, or our AI chatbot. This flexibility means you can get the employee job data you need, regardless of your technical background.
In this guide, we'll walk you through connecting ServiceTitan to Peaka and use our AI chatbot to instantly retrieve all jobs for any employee in your organization—no SQL required.
## **Setting Up Your ServiceTitan Connection**
Before you can query employee job data, you'll need to connect your ServiceTitan account to Peaka. The process is straightforward and takes just a few minutes.
First, navigate to the Connections section in your Peaka workspace and select ServiceTitan from the available integrations. You'll need your ServiceTitan API credentials, which you can generate from your ServiceTitan admin panel.
Once connected, Peaka will automatically sync your ServiceTitan data, including employee records, job assignments, and scheduling information. This gives you immediate access to query any employee's job history through our platform.
For detailed step-by-step instructions, check out our comprehensive guide: [Connect your ServiceTitan Account to Peaka](/docs/integrations/service-titan)
## **Getting Employee Job Data in 4 Simple Steps**
Once your ServiceTitan data is flowing into Peaka, retrieving employee job information becomes incredibly straightforward. Here's how to pull all jobs for any specific employee:
### **Step 1: Start a New Query**
Navigate to your Peaka workspace and create a new query. Select the **AI|GPT** section to access our natural language query interface.
_Pro tip: New to Peaka queries? Check out our [comprehensive guide](/docs/connecting-your-data/peaka-query#what-is-a-peaka-query) to get up to speed._
### **Step 2: Ask in Plain English**
Simply type your request in natural language. For example:
```
List all jobs assigned to the employee named Can Tuna, filtered by the user who created them.
```
{{ resize_image(path="../static/assets/images/blog-images/list-employee-jobs-service-titan-1.png", height=450, width=750, op='fit_width', center='true',alt="Entering prompt to Peaka AI chatbot") }}
### **Step 3: Select Your Data Sources**
Peaka will automatically suggest the relevant tables. For employee job data, you'll typically need:
- **Jobs table**: `your_service_titan_connection > job_planning > jobs`
- **Employees table**: `your_service_titan_connection > settings > employees`
{{ resize_image(path="../static/assets/images/blog-images/list-employee-jobs-service-titan-2.png", height=450, width=750, op='fit_width', center='true',alt="Selecting relevant tables in Peaka") }}
### **Step 4: Execute and Analyze**
Hit run and watch Peaka generate the SQL query behind the scenes. Your results appear instantly, showing all jobs assigned to your specified employee with complete details.
{{ resize_image(path="../static/assets/images/blog-images/list-employee-jobs-service-titan-3.png", height=450, width=750, op='fit_width', center='true',alt="Query results showing employee job data") }}
## **Conclusion: Fewer manual steps, faster decision-making**
With Peaka's AI chatbot, you can instantly pull any employee's job data from ServiceTitan using simple prompts—no SQL or manual exports needed. Get immediate insights for better workforce management and faster performance reviews.
Ready to streamline more ServiceTitan workflows? Explore our complete [ServiceTitan Reporting Cookbook](/category/servicetitan-reporting-cookbook/) for step-by-step guides on consolidating data across multiple accounts.
[Sign up to Peaka](https://peaka.studio/signup) for free today.
[Book a quick demo](https://calendly.com/peaka/demo) and see how Peaka can help simplify ServiceTitan reporting for you and your clients.
--- START: blog/list-invoices-multiple-servicetitan-accounts/list-invoices-multiple-servicetitan-accounts.md ---
# **How to List Invoice Data Across Multiple ServiceTitan Accounts**
Managing invoice data across multiple ServiceTitan accounts is a common challenge for PE firms and multi-location service businesses. Whether you're consolidating financial reports, analyzing revenue trends across brands, or preparing investor updates, you need an efficient way to pull invoice data from all your ServiceTitan instances.
Peaka offers multiple ways to access and analyze your ServiceTitan data—through SQL queries, table views, or our AI chatbot. This flexibility means you can get the consolidated invoice data you need from multiple accounts, regardless of your technical background.
In this guide, we'll walk you through connecting multiple ServiceTitan accounts to Peaka and use our AI chatbot to instantly retrieve and consolidate invoice data across your entire portfolio—no SQL required.
## **Setting Up Your ServiceTitan Connections**
Before you can query employee job data, you'll need to connect your ServiceTitan account to Peaka. The process is straightforward and takes just a few minutes.
First, navigate to the Connections section in your Peaka workspace and select ServiceTitan from the available integrations. You'll need your ServiceTitan API credentials, which you can generate from your ServiceTitan admin panel.
Once connected, Peaka will automatically sync your ServiceTitan data, including employee records, job assignments, and scheduling information. This gives you immediate access to query any employee's job history through our platform.
For detailed step-by-step instructions, check out our comprehensive guide: [Connect your ServiceTitan Account to Peaka](/docs/integrations/service-titan)
## **Getting Invoices Data in 4 Simple Steps**
Once your ServiceTitan data is flowing into Peaka, retrieving invoice information becomes incredibly straightforward. Here's how to pull all invoices from multiple ServiceTitan accounts:
### **Step 1: Start a New Query**
Navigate to your Peaka workspace and create a new query. Select the **AI|GPT** section to access our natural language query interface.
_Pro tip: New to Peaka queries? Check out our [comprehensive guide](/docs/connecting-your-data/peaka-query#what-is-a-peaka-query) to get up to speed._
### **Step 2: Ask in Plain English**
Simply type your request in natural language. For example:
```
List all invoices from all of my ServiceTitan accounts.
```
{{ resize_image(path="../static/assets/images/blog-images/list-invoices-multiple-service-titan-accounts-1.png", height=450, width=750, op='fit_width', center='true',alt="Entering prompt to Peaka AI chatbot") }}
### **Step 3: Select Your Data Sources**
Peaka will automatically suggest the relevant tables. For employee job data, you'll typically need:
- **Invoices Table**: `your_service_titan_connection > accounting > invoices`
{{ resize_image(path="../static/assets/images/blog-images/list-invoices-multiple-service-titan-accounts-2.png", height=450, width=750, op='fit_width', center='true',alt="Selecting relevant tables in Peaka") }}
### **Step 4: Execute and Analyze**
Hit run and watch Peaka generate the SQL query behind the scenes. Your results appear instantly, showing all jobs assigned to your specified employee with complete details.
{{ resize_image(path="../static/assets/images/blog-images/list-invoices-multiple-service-titan-accounts-3.png", height=450, width=750, op='fit_width', center='true',alt="Query results showing employee job data") }}
## **Conclusion: Less data wrestling, more strategic thinking**
With Peaka's AI chatbot, you can instantly pull invoice data from multiple ServiceTitan accounts using simple prompts—no SQL or manual exports needed. Get immediate insights for better financial reporting and portfolio-wide invoice analysis.
[Sign up to Peaka](https://peaka.studio/signup) for free today.
[Book a quick demo](https://calendly.com/peaka/demo) and see how Peaka can help simplify ServiceTitan reporting for you and your clients.
--- START: blog/list-technician-multiple-servicetitan-accounts/list-technician-multiple-servicetitan-accounts.md ---
# **Listing Technician Data from Multiple ServiceTitan Accounts**
Managing technician data across multiple ServiceTitan accounts is a common challenge for PE firms and multi-location service businesses. Whether you're consolidating workforce reports, analyzing technician performance across brands, or preparing operational updates, you need an efficient way to pull technician data from all your ServiceTitan instances.
Peaka offers multiple ways to access and analyze your ServiceTitan data through SQL queries, table views, or our AI chatbot. This flexibility means you can get the consolidated technician data you need from multiple accounts, regardless of your technical background.
In this guide, we'll walk you through connecting multiple ServiceTitan accounts to Peaka and use our AI chatbot to instantly retrieve and consolidate technician data across your entire portfolio with no SQL required.
## **Setting Up Your ServiceTitan Connections**
Before you can query technician data, you'll need to connect your ServiceTitan account to Peaka. The process is straightforward and takes just a few minutes.
First, navigate to the Connections section in your Peaka workspace and select ServiceTitan from the available integrations. You'll need your ServiceTitan API credentials, which you can generate from your ServiceTitan admin panel.
Once connected, Peaka will automatically sync your ServiceTitan data, including technician records, job assignments, and scheduling information. This gives you immediate access to query technician data across all your connected accounts through our platform.
For detailed step-by-step instructions, check out our comprehensive guide: [Connect your ServiceTitan Account to Peaka](/docs/integrations/service-titan)
## **Getting Invoices Data in 4 Simple Steps**
Once your ServiceTitan data is flowing into Peaka, retrieving technicians information becomes incredibly straightforward. Here's how to pull all technicians from multiple ServiceTitan accounts:
### **Step 1: Start a New Query**
Navigate to your Peaka workspace and create a new query. Select the **AI|GPT** section to access our natural language query interface.
_Pro tip: New to Peaka queries? Check out our [comprehensive guide](/docs/connecting-your-data/peaka-query#what-is-a-peaka-query) to get up to speed._
### **Step 2: Ask in Plain English**
Simply type your request in natural language. For example:
```
List all technicians from all of my ServiceTitan accounts.
```
{{ resize_image(path="../static/assets/images/blog-images/list-technicians-multiple-service-titan-accounts-1.png", height=450, width=750, op='fit_width', center='true',alt="Entering prompt to Peaka AI chatbot") }}
### **Step 3: Select Your Data Sources**
Peaka will automatically suggest the relevant tables. For employee job data, you'll typically need:
- **Technicians Table**: `your_service_titan_connection > settings > technicians`
{{ resize_image(path="../static/assets/images/blog-images/list-technicians-multiple-service-titan-accounts-2.png", height=450, width=750, op='fit_width', center='true',alt="Selecting relevant tables in Peaka") }}
### **Step 4: Execute and Analyze**
Hit run and watch Peaka generate the SQL query behind the scenes. Your results appear instantly, showing all technicians from your connected ServiceTitan accounts with complete details.
{{ resize_image(path="../static/assets/images/blog-images/list-technicians-multiple-service-titan-accounts-3.png", height=450, width=750, op='fit_width', center='true',alt="Query results showing technicians data") }}
## **Conclusion: Convert manual chaos into organized intelligence**
Managing technician data across multiple ServiceTitan accounts doesn't have to mean juggling spreadsheets and manual exports. With Peaka's AI chatbot, you can consolidate workforce data from your entire portfolio using natural language just ask and get instant results.
Whether you're tracking performance metrics, planning resource allocation, or preparing executive reports, you now have the tools to make data-driven decisions across all your ServiceTitan instances. No technical expertise required, no time wasted on manual processes.
Ready to transform how you handle multi-account ServiceTitan data? Your technician insights are just one conversation away.
[Sign up to Peaka](https://peaka.studio/signup) for free today.
[Book a quick demo](https://calendly.com/peaka/demo) and see how Peaka can help simplify ServiceTitan reporting for you and your clients.
--- START: blog/logical-data-warehouse/logical-data-warehouse.md ---
# **What is a Logical Data Warehouse?**
Are you having trouble managing and making the most of your data? If the answer is yes, I have good and bad news for you.
The good news is that you are not alone—we’re all struggling to find our way through heaps of data.
The bad news is that it will only get worse: We will be generating [175 zettabytes](https://venturebeat.com/data-infrastructure/the-new-metrics-for-unstructured-data-management/) of data in 2025 according to IDC, which is almost 50 percent more than the total amount of [data created in 2022](https://explodingtopics.com/blog/data-generated-per-day), which was 120 zettabytes. The fact that more than [80 percent](https://www.forbes.com/sites/forbestechcouncil/2022/02/03/the-unseen-data-conundrum/) of this amount will be unstructured data will make things even more difficult.
So, we need to find new ways of storing, managing, unifying, and consuming our data. We are up against some serious [data management challenges](https://www.datavirtualizationblog.com/does-data-always-need-to-end-up-in-a-centralized-repository/), though:
- Our data is scattered over multiple geographic locations hosting data storage.
- Different business units use different—and sometimes incompatible—technologies.
- Decisions like who is responsible for data and who gets to access it further complicate the issue of data integration.
Managing scattered data is expensive; time-sensitive operations demand real-time data; and we must ensure that data is timely, accurate, reliable, discoverable, and accessible. Thankfully, smart people all around the world are working to solve these problems and coming up with creative concepts. Of these concepts, data mesh and data fabric has become quite popular in the last couple of years, as demonstrated by this graph below:
{{ resize_image(path="../static/assets/images/blog-images/data-mesh-data-fabric-g-trends.png", width=759, height=400, op='fit_width', alt="Google searches for 'data mesh' and 'data fabric'") }}
Graph showing the increase in the global Google searches for the terms "data mesh" (blue) and "data fabric" (orange) in the last five years. Image credits: [Google Trends](https://trends.google.com/trends/explore?date=today%205-y&q=data%20mesh,data%20fabric&hl=en). The image was slightly modified for aesthetic purposes.
Underpinning all these ideas is the concept of Logical Data Warehouse (LDW). Although Bill Inmon is credited with coining the term [in 2004](https://datawarehouseinfo.com/logical-data-warehouse/), it was [Mark Beyer of Gartner](https://blogs.gartner.com/merv-adrian/2011/11/03/mark-beyer-father-of-the-logical-data-warehouse-guest-post/) who used it in 2009 in the sense that it is used today. We’ll take a closer look at the LDW architecture and what it promises to enterprise users in this blog post.
## **Logical Data Warehouse—what does it do?**
An LDW is a data architecture specifically designed to overcome the geographic, technological, and data ownership constraints cited above. This architectural layer is built on top of data warehouses and data lakes in this concept. It harmonizes different components within the data infrastructure to create a single, integrated view of the data scattered across different storage locations. While achieving this feat, LDW makes no use of [physical ELT and ETL processes](https://bookshelf.erwin.com/tag/iot-data-warehouse/) generally used to copy and move data into a single storage.
## **Key takeaways**
- An LDW is a composable data architecture that unifies data stored in different locations.
- The LDW takes advantage of the data virtualization technique to unify data without copying or moving it.
- The LDW makes it easier for domain experts to bring together their data without relying on an IT department since there is no need for ETL or ELT processes involved.
- The LDW lends itself to the SaaS-heavy work environment where pulling in data from various SaaS tools is key.
## **Data in numbers**
- The latest estimates put the amount of [data being created every day](https://explodingtopics.com/blog/data-generated-per-day)
at 328.77 million terabytes.
- The [global data storage market](https://www.fortunebusinessinsights.com/data-storage-market-102991), valued at $217.02 billion in 2022, is expected to reach $777.98 billion in 2030.
- The demand for data scientists won’t slow down any time soon. [The number of data scientist jobs](https://www.bls.gov/ooh/math/data-scientists.htm) is expected to increase by 36 percent from 2021 to 2031, with 13,500 job openings on average every year throughout the decade.
- 41 percent of C-suite executives consider [metadata and governance](https://www.g2.com/articles/big-data-statistics) as the biggest challenges, while 31 percent are concerned about slow data ingestion.
## **How does an LDW work?**
How does an LDW manage to bring together all the data regardless of its format when the user has no idea where the data resides? The power of the LDW architecture lies in how it can capitalize on metadata. An LDW does not physically house data but holds metadata that defines the context of data, making it possible for data consumers to find and access a specific piece of data without having to know where it is [stored.](https://www.datavirtualizationblog.com/emergence-logical-data-warehouse/) Metadata eliminates the need to perform ETL processes or replicate data and presents the users with a unified view of data upon a simple [information request](https://datawarehouseinfo.com/logical-data-warehouse/) they send.
The data needs of a modern enterprise are so sophisticated that no single data management system can address the demands of [all user types and use cases.](https://www.gartner.com/document/3994138) The LDW offers an all-encompassing, versatile, and flexible model that can do that by utilizing data warehouses, data lakes, [Hadoop clusters, NoSQL databases, or cloud-based platforms.](https://www.datavirtualizationblog.com/logical-data-warehouses-matter/) Different components work in sync within an LDW framework to handle structured or unstructured data, and relational or non-relational databases. The result can approximate real-time or provide a single view of truth with data historicity, depending on what the user seeks. Imagine two hypothetical data consumers: One prioritizing data quality over access speed and another who doesn't have high standards for data consistency while showing no tolerance for latency. The LDW can lean on different components to satisfy both.
## **Comparison: Strengths and weaknesses of the LDW**
- An LDW [lowers the technical barriers](https://www.tibco.com/reference-center/what-is-a-logical-data-warehouse) for knowledge workers or "domain experts," practically turning them into "citizen data analysts." These people can self-serve without having to execute physical ELT and ETL processes. An LDW architecture empowers them to find and access data without relying on an already-overwhelmed IT department.
- The [centralized data source](https://www.gartner.com/document/4013222) built by an LDW minimizes the need for data movement and replication. This prevents data sprawl and degradation, improving data governance.
- An LDW architecture allows for data historicity, the lack of which was a weak point for data virtualization, as [our CEO Mustafa explained](/blog/data-virtualization-no-code/) earlier. The LDW can harness the capabilities of a [Hadoop cluster](https://www.datavirtualizationblog.com/logical-data-warehouse-common-patterns/) to provide users with historical analysis. Coupled with real-time or near-real-time data analysis, it offers users the best of both worlds.
- The flexibility an LDW architecture affords its users is immense compared to conventional enterprise data warehouses. The LDW represents a composable architecture. New components can be added and removed with ease, which is a huge plus in an age where people use multiple SaaS products and have difficulty integrating them into the existing data infrastructure. An LDW removes the need to establish new ELT and ETL processes every time a new data source is added to an existing data infrastructure.
An LDW architecture is not without its weaknesses. Those weaknesses follow directly from data virtualization, which is the technique it utilizes for implementation. Luckily, we have the caching to mitigate the scalability problems. Additionally, different components of the architecture being down renders data analysis temporarily inaccessible. This is a problem that takes a holistic maintenance approach to deal with, as is the case with data virtualization.
## **How does the LDW fit with data virtualization, data mesh, and data fabric?**
- Data virtualization is a specific data integration technique to realize the LDW principles. It is what an LDW uses to bring together disparate sources of data without copying or moving the data.
- Data mesh is an approach that redefines how we think about data. It is basically a mental exercise in developing a novel way of focusing on knowledge domains, treating data as a product, and prioritizing the empowerment of knowledge workers. The data mesh concept leverages the LDW to transform the existing data infrastructure in a way that can accommodate the needs of a modern enterprise.
- Data fabric is [defined by Gartner](https://www.gartner.com/document/4011535) as "_an emerging data management design,... not one single tool or technology._" It is based on active metadata practices incorporating artificial intelligence (AI) and machine learning (ML). Thanks to AI and ML, data fabric can learn patterns of data usage and better service information requests over time. Data fabric is an end state for an LDW to reach once it matures.
## **What about artificial intelligence (AI) and machine learning (ML)?**
It is unthinkable to wrap up a post without making a reference to AI and ML nowadays. A partnership between the LDW, on the one hand, and AI and ML, on the other, promises to deliver lasting advantages. According to Mayank Talwar, an analyst at Gartner, [AI and Logical Data Warehouse are complementary technologies](https://www.gartner.com/document/4005916) (“Adopting a Logical Data Warehouse,” September 17, 2021, pp. 19-21). Talwar gives us a glimpse into a few scenarios where these two can create synergies:
- While AI allows the LDW to better understand the data structure and metadata and helps with workload management, the LDW provides the robust infrastructure AI and ML need to deliver the results.
- Users of an LDW architecture stand to benefit from the analytical tools and methods AI and ML can offer. In return, the LDW generates high-quality data that AI and ML algorithms can train on.
Let’s take a deep dive and see how these two technologies make each other better:
### **How AI/ML helps LDW**
#### **1. Smart query optimization**
By analyzing query patterns, AI/ML models predict frequently accessed data, recommend query rewrites, and dynamically optimize query execution paths. As a result, users enjoy shorter query response times and minimal resource consumption.
#### **2. Automated data integration**
AI/ML streamlines data integration by classifying and mapping incoming datasets through schema matching and entity resolution and automating ETL/ELT tasks. This accelerates data onboarding, reducing time-to-insight.
#### **3. Metadata and semantic enrichment**
AI identifies data relationships and hierarchies, helping users make sense of data and enhancing metadata as a result.
#### **4. Intelligent data virtualization**
ML models can help optimize source selection and data routing and analyze usage patterns to determine whether to retrieve live data or use cached data. This brings about enhanced performance and lower costs in federated queries across heterogeneous sources.
#### **5. Anomaly detection and data quality monitoring**
Users can leverage AI/ML to monitor data streams for anomalies and sift through large datasets to identify data quality issues. This ensures that data consumers are fed reliable data.
### **How LDW helps AI/ML**
#### **1. Unified access to scattered data**
LDWs eliminate the need to physically move data from the data integration process, virtualizing access to disparate data sources. This allows AI/ML to train on more diverse datasets.
#### **2. Faster data availability for model training**
LDWs facilitate real-time data integration, which lets ML models train on up-to-date data.
#### **3. Contextual data enrichment**
LDWs are used with semantic layers and metadata catalogs, helping users better interpret data. This improves data discoverability and facilitates self-service analytics for business teams.
## **Conclusion**
The LDW is a data architecture modern enterprises should aspire to have. It does not replace the existing enterprise data warehouse but complements it with new components, turning the latter into one of the cogs in a well-oiled machine and reducing the cost of data management. It is the current best practice in data management right now. At least until the next concept with an even cooler name emerges, that is.
--- START: blog/low-code-vs-no-code/low-code-vs-no-code.md ---
   Link copied
Table of Contents
* [Differences between Low-code and No-code](https://www.peaka.com/blog/low-code-vs-no-code/#differences-between-low-code-and-no-code)
* [1\. What is low-code?](https://www.peaka.com/blog/low-code-vs-no-code/#1-what-is-low-code)
* [2\. What is no-code?](https://www.peaka.com/blog/low-code-vs-no-code/#2-what-is-no-code)
* [3\. Main similarities between low-code and no-code](https://www.peaka.com/blog/low-code-vs-no-code/#3-main-similarities-between-low-code-and-no-code)
* [4\. Major differences between low-code and no-code](https://www.peaka.com/blog/low-code-vs-no-code/#4-major-differences-between-low-code-and-no-code)
[Home](/) / [Blog](/blog) / Differences between Low-code and No-code
[No-code](https://www.peaka.com/category/no-code/) [Low-code](https://www.peaka.com/category/low-code/)
Published on May 04, 2021
6 min read
Differences between Low-code and No-code


Eugene van Ost Peaka / IT Soothsayer
**Differences between Low-code and No-code**[](#differences-between-low-code-and-no-code)
=========================================================================================
Every few years, a new trend in the tech industry gets hyped up as the next big thing. You don’t even remember Segway, that weird two-wheeled vehicle that was expected to revolutionize transportation, do you? How about virtual reality, which was supposed to get us all hooked but instead fizzled out without any of us noticing?
The “next big thing” of the last decade in the software industry was low-code. As people felt the need to automate business processes and create applications, the interest in low-code technology grew. Today it is accompanied by no-code. But can these two live up to the hype?
**1\. What is low-code?**[](#1-what-is-low-code)
------------------------------------------------
Low-code is an approach to building applications that uses a drag-and-drop interface and involves a high level of abstraction but minimum coding. What is being dragged and dropped in low-code application platforms (LCAPs) are existing blocks of code. Actually, programs like MS Excel and Powerpoint were nothing more than early forms of low-code, so we have been quite familiar with the concept for decades.
**2\. What is no-code?**[](#2-what-is-no-code)
----------------------------------------------
No-code takes the low-code approach to an extreme, where there is no traditional coding involved in the way an app is designed and built. In other words, it raises the abstraction level present in the LCAPs up a notch. By doing that, a no-code application platform (NCAP) allows the user to build applications through a visual interface only, eliminating code altogether.
In their idealized, puristic forms, low-code and no-code are located on the two extremes of a spectrum. But in reality, every low-code and no-code platform occupies a different spot along that spectrum. They share common points and differ on some others at the same time. Let’s dive in and have a look at the similarities and differences between the two approaches:
**3\. Main similarities between low-code and no-code**[](#3-main-similarities-between-low-code-and-no-code)
-----------------------------------------------------------------------------------------------------------
### **A visual approach to app building**[](#a-visual-approach-to-app-building)
Both low-code and no-code tools simplify the app development process by providing the user with a drag-and-drop user interface (UI). This kind of UI helps users bring together predefined blocks of code and create applications through point-and-click motions. While low-code platforms combine visual modeling with conventional code, no-code application development takes it one step further, completely turning coding into visual modeling.
### **Filling in for developer skills**[](#filling-in-for-developer-skills)
> _A recent survey conducted by [Tonkean](https://go.tonkean.com/State_of_BizOps_2021_Report_LP.html) has found out that 24 percent of employees working at enterprises are not happy with the tech stack at their disposal. 49 percent of the respondents in the same survey have complained about the lack of access to IT/engineering. That's because professional developers are under serious workload, buried in thousands of lines of code._
Low-code and no-code platforms help bridge this gap and reduce the IT backlog by empowering frontline employees to develop tools that their jobs demand.
### **Dealing with the shadow IT problem**[](#dealing-with-the-shadow-it-problem)
The term shadow IT [refers to](https://kissflow.com/workflow/bpm/should-it-directors-eradicate-shadow-it-or-embrace-it/) any IT programs or solutions used in an organization without the knowledge of the in-house IT team. Companies might be using [tens or even hundreds](https://www.quickbase.com/blog/5-shadow-it-statistics-to-make-you-reconsider-your-life) of different programs outside the IT department’s blessing at anytime. This creates problems with respect to security, integration, and scaling. Low-code and no-code tools help deal with this phenomenon, streamline processes, and bring cohesion to the systems run by a company.
### **Speed**[](#speed)
Both low-code and no-code platforms reduce the time it takes to build and launch an app. They reduce the time between successive iterations, shorten the app development process, and tie in really well with agile development principles.
**4\. Major differences between low-code and no-code**[](#4-major-differences-between-low-code-and-no-code)
-----------------------------------------------------------------------------------------------------------
### **Cost**[](#cost)
While LCAPs help companies save on money that would otherwise be spent on expensive developer skills, they are still significantly more expensive than NCAPs. LCAPs may charge thousands of dollars per month, which is a good deal higher than the couple of hundreds of dollars per month that NCAPs charge for comparable capabilities.
### **Ease of use**[](#ease-of-use)
Users of LCAPs have to be familiar with the fundamental concepts in software development. LCAPs also require their users to be able to inject code in order to tweak the apps according to their wishes. NCAPs, on the other hand, come with more strictly defined constraints and do not require coding knowledge as long as the user stays within those boundaries. Therefore, no-code application development is better suited for the skill sets of people coming from non-technical backgrounds.
### **Functionality**[](#functionality)
Because of the cost and the skill level required to operate an LCAP, it tends to be a better fit for enterprises with the means to justify such an investment and the personnel to handle it. LCAPs are also better at serving the needs of enterprises (wholesale digital transformation, data management, elimination of shadow IT, deployment of complex workflows, integration with legacy systems).
Citizen developers are central to how low-code app development works in enterprises. These people are domain experts skilled in developing applications for their particular field of work. They assume responsibility to fill in for professional developers.
On the flip side, NCAPs are better positioned to cater to the needs of startups, SMBs, solo entrepreneurs, and freelance developers. Tasks like designing landing pages, building software to monitor a sales team, or creating a fancy user interface for an existing system lend themselves better to no-code solutions.
What about [Peaka](/)? We at Peaka like to describe our platform as “no-code-first.” I can almost hear you exclaim, “_Oh no… Another fancy term._”
Bare with me here: Peaka comes with a very easy-to-use, intuitive UI, but it also offers the ability to handle complex workflows and integrations as well. A person with no coding background can easily create a landing page or a fully-functioning app on Peaka.
However, the platform also enables users to embed code in, if need be, letting them work with code or no-code as they see fit. Thus, on the spectrum extending from no-code to low-code, Peaka is situated closer to the former while catering to a broader range of needs than platforms that are purely no-code. To put it simply, it is the best of both worlds.
Your biweekly inspiration delivered to your inbox
Join our newsletter for news, tips, and blog posts on anything data integration!
Subscribe
 Please fill out this field
 Thank you! You have been subscribed.
Similar posts you might be interested in
[](https://www.peaka.com/blog/saas-ideal-customer-profile/)
No-code Low-code May 04, 2021
[How to Create an Ideal Customer Profile for SaaS Businesses](https://www.peaka.com/blog/saas-ideal-customer-profile/)
How do you create an ideal customer profile (ICP)? Why should a SaaS company create one? How does Peaka help you hone your ICP? Find out in this blog post.

Bruce McFadden Peaka / Seasoned Taskmaster
[](https://www.peaka.com/blog/account-based-marketing-saas/)
No-code Low-code May 04, 2021
[How to Create an Account-Based SaaS Marketing Strategy](https://www.peaka.com/blog/account-based-marketing-saas/)
Here is everything a SaaS founder needs to know about account-based marketing, how it works, its benefits, and how Peaka can help ABM teams implement it.

Eugene van Ost Peaka / IT Soothsayer
[](https://www.peaka.com/blog/top-saas-revenue-metrics/)
No-code Low-code May 04, 2021
[Top 6 SaaS Revenue Metrics to Track in 2026](https://www.peaka.com/blog/top-saas-revenue-metrics/)
A deep dive into SaaS revenue metrics, four data integration tools to track SaaS revenue, and benefits of blending your revenue data with your CRM data.

M. Çınar Büyükakça Peaka / Prolific Polemicist
 
Begin your journey today
Start your 14-day free trial to explore Peaka!
Get started for free
Enjoying this article?
Subscribe to our monthly newsletter for insights on ServiceTitan data integration and KPI reporting.


First Name
Last Name
Email
Company Name
Phone Number (optional)
Subscribe
You can unsubscribe anytime. For more details review our [Privacy Policy](https://www.peaka.com/privacy-policy/).
--- START: blog/manage-multiple-servicetitan-accounts/manage-multiple-servicetitan-accounts.md ---
# **How to Unify Data from Multiple ServiceTitan Accounts**
For a consultant working with ServiceTitan operators, reporting becomes the thing that quietly caps growth. It is not the lack of dashboards. It is the constant overhead of switching accounts, exporting data, rebuilding the same metrics, and answering the same questions in slightly different formats for every contractor you work with.
This guide is for ServiceTitan consultants, agencies, and coaches who manage five, ten, or even more client accounts and want a repeatable way to deliver KPI dashboards without turning every new client into a custom project. You will learn what a multi-client reporting system looks like, what should be standardized first, and how to keep your templates consistent as you onboard more contractors.
If you are a contractor trying to unify reporting across branches within a single company, start with our piece on [multi-location ServiceTitan reporting](/blog/multi-location-servicetitan-reporting/) instead. If you are a PE firm building portfolio-level reporting across acquisitions, see our [PE reporting guide](/blog/unify-servicetitan-data-pe-firms/).
## **Why multi-account Servicetitan reporting is so painful**
Let’s break down what makes creating consolidated reports from multiple ServiceTitan accounts such a nightmare for consultants:
+ **Separate logins and disconnected data:** Each ServiceTitan account is its own data repository. If you’re managing 10 clients, that’s 10 different systems to navigate.
+ **Manual data wrangling:** Downloading reports, cleaning them up, and merging them into a single spreadsheet becomes your full-time job.
+ **Inconsistent structures:** What one contractor calls “Technician hours” is “Field Time” to another. Good luck joining that data.
+ **No portfolio view:** Without a unified data model, it’s almost impossible to benchmark performance or deliver strategic insights across clients.
Building a single view of truth out of this maze is a huge drain on your resources and undermines the scalability of your processes.
## **The cost of doing it the conventional way**
Consulting firms that rely on manual workflows for multi-account reporting run into a few common issues:
+ **Slower onboarding:** Building new dashboards from scratch for each client delays time-to-value, increasing the risk of customer churn.
+ **Limited capacity:** Integrating data manually sets a cap on how many clients you can serve with the resources at hand, requiring you to hire more analysts to serve more clients.
+ **Missed upsell opportunities:** Without a single source of truth to draw insights from, you can’t show contractors how they compare or what “success” looks like.
+ **Burnout:** Instead of refining strategy, coaching, or optimizing processes, your team is buried in spreadsheets and manual exports.
However, there is a more serious risk for consulting firms reliant on [manual data exports](/blog/servicetitan-manual-data-export-costs/) for multi-account reporting: When a competitor walks in with automated reporting and real-time insights, your spreadsheets won’t stand a chance. Your slow onboarding, sloppy reporting, and obsolete dashboards suddenly begin to look too bad for clients to stick with you.
## **How Peaka simplifies reporting for multiple ServiceTitan accounts**
Peaka is designed to tackle this exact problem.
In addition to simplifying how ServiceTitan consultants join [job data with accounting data from QuickBooks](/blog/integrate-servicetitan-with-quickbooks-xero-sage/), Xero Accounting, and Sage Intacct, Peaka can unify data from multiple ServiceTitan instances scattered across multiple accounts and locations.
Having unified your data, you can then standardize it and push it into your preferred BI tools (Power BI, Looker Studio, Metabase, etc.).
Here’s how it works:
+ **One workspace for all clients:** Connect every ServiceTitan instance you manage into a single Peaka environment.
+ **Standardized KPIs:** Define key metrics once and apply them across clients, regardless of naming conventions or account structure.
+ **BI tool flexibility:** Push the unified data into the dashboard tools you already use with your clients.
+ **Automated refreshes:** Eliminate manual exports and ensure that your data stays up to date, automatically.
The result? One-click reports that provide a 360-degree view of your operations, [KPI dashboards](/blog/consultants-servicetitan-kpi-dashboards/) that are faster to build, and clients recognizing the difference your coaching makes.
## **Use case: A consultant supporting 15 contractors**
Integrating data from multiple ServiceTitan accounts also entails pulling in and joining data from branches in different locations. Imagine you support 15 different contractors, consisting of six HVAC businesses, four plumbing companies, and five multi-location franchise groups.
Each one has its own ServiceTitan account. Typically, you’d have to manage 15 reporting setups, 15 dashboard builds, and 15 ongoing update routines.
With Peaka, you connect each account once. Then:
+ Define a shared KPI model across all clients
+ Push data into a BI tool like Power BI or Looker Studio
+ Filter by client, region, or business type
+ Deliver customized dashboards based on the same underlying logic
This setup helps you save dozens of hours per month while giving clients insights they can trust.
## **The strategic upside for your consulting firm**
Nailing data management between multiple ServiceTitan accounts opens new doors for your business and enables you to
+ **Scale without extra headcount:** You get to serve more clients without having to expand your team.
+ **Monetize new capabilities:** You can offer real-time dashboards as a subscription or premium add-on.
+ **Minimize time-to-value:** Onboarding becomes easier, and new clients get up and running in days instead of weeks.
+ **Gain a competitive edge over rivals:** Being able to serve multi-location clients expands your customer base and helps you tap into a lucrative market, which competitors find impossible to serve.
For growing consulting firms, this is the foundation for long-term profitability and impact.
## **Getting started with Peaka**
You don’t need a developer or a data engineering team to pull this off. Here’s how to get started:
1. Connect each ServiceTitan account to your Peaka workspace
2. Create standardized workflows for cleaning and joining key datasets
3. Push the data into [Power BI](/blog/servicetitan-power-bi-integration/), [Looker Studio](/blog/how-to-connect-servicetitan-to-looker-studio/), or [Metabase](/blog/how-to-connect-servicetitan-to-metabase/)
4. Duplicate and adapt your setup across clients with just a few clicks
From there, you can manage everything from one place, keep dashboards live and up to date, and spend your time doing what actually moves the needle, such as coaching and advising.
## **Key takeaways**
+ **Peaka creates a unified data foundation** that makes it easier to evolve from one-off reports to standardized, scalable consulting.
+ **Automating how data is integrated from multiple ServiceTitan accounts** allows consultants to scale operations and boost growth without adding headcount.
+ **Consolidated data from multiple ServiceTitan accounts** powers strategic insights, helping consultants compare data from different branches and provide clients with more granular guidance.
## **Conclusion: More clients, less chaos**
Managing multiple ServiceTitan accounts used to mean fragmented data, messy spreadsheets, and endless manual work. With Peaka, that’s no longer the case.
[An official ServiceTitan partner](/partners/servicetitan-integration/), Peaka offers a scalable, no-code platform that consolidates all your client data into one place, enabling you to provide better insights, quicker reports, and high-value services that grow with your business.
[Sign up to Peaka](https://peaka.studio/signup) for free today.
[Book a demo](https://calendly.com/peaka/demo) and see how you can automate data integrations from multiple ServiceTitan instances.
--- START: blog/medical-appointment-template/medical-appointment-template.md ---
# **PrestoMD: The Practical Way of Handling Patient Appointments**
The last two years have been transformative for all of us. They have changed how we work, socialize, travel, etc. It was all due to the pandemic, the most extraordinary phenomenon the world has witnessed in generations. The health industry was, naturally, one of the hardest-hit sectors and had to reinvent how it operates.
Not knowing how to tackle this new beast called Covid-19 and how it behaved, we were being extra careful, erring on the side of caution. We did everything to avoid hospitals or dental clinics for the last two years unless it was something major: Regular checkups were postponed, and dental visits became anathema considering the risk they posed for the transmission of the disease.
Now that “the new normal” has set in, it is back to business as usual, albeit in a more hesitant way. The previously postponed visits are back on the schedule. However, you may be surprised to find out that getting a medical appointment may have become a little bit harder compared to the pre-pandemic experience you had. All that postponed demand has come to overwhelm the phone lines. There are still restrictions in place regarding the number of people allowed in closed spaces, which further complicates how the demand needs to be managed. It might get quite stressful for the front desk staff at a clinic as they try to maximize the number of patients served while struggling to accommodate requests from patients as to the timing of their appointments.
An online appointment app makes things easier for all the stakeholders involved in such situations. Such an app lets patients check the time slots available to them days and even weeks in advance and choose the most convenient slots for their schedules. Doctors and other health personnel get a chance to see the upcoming workload and plan ahead. The front desk staff can focus on tasks other than answering phone calls as they no longer have to help patients schedule their visits on the phone. An online medical appointment app also allows administrators of medical institutions to be on top of the incoming demand in the near future. Using this information, they can make better decisions on the procurement of supplies and leave requests from the personnel.
Bearing those points in mind, Peaka recently published the PrestoMD template, which lets users quickly access the basic functionality they expect to see from a medical appointment app. With PrestoMD, patients can easily pick a date and time slot on the calendar and make an appointment. It eliminates the need for patients to wait on the phone for minutes or deal with an answering machine. PrestoMD caters to the needs of the administrative staff at a medical institution as well. The template allows administrators to add and remove doctors and view the appointments made.
A clumsily executed appointment process gives rise to misunderstandings and double bookings, causing patient churn and loss of revenue. [PrestoMD](/templates/) is the cure to that problem—a straightforward, easy-to-use alternative to lengthy phone calls and cumbersome appointment books kept in drawers.
--- START: blog/merge-vs-embedded-peaka/merge-vs-embedded-peaka.md ---
# **Merge vs. Peaka: Which to Choose for In-Product Analytics?**
If you’re building a SaaS platform that pulls in data from tools like Stripe, HubSpot, Zendesk, or QuickBooks, you’ve likely come across Merge and Embedded Peaka. Both promise faster integration with third-party APIs. But when your end goal is to go beyond syncing data to your backend and embed customer-facing analytics inside your product, there’s a big difference in what each platform delivers.
Here’s why Embedded Peaka is the better fit for product teams looking to ship dashboards, reporting, or AI-driven insights that users interact with inside the app.
## **1. You need an embedded data platform, not an API aggregator**
Merge is excellent for connecting to APIs, especially if you’re dealing with HRIS, CRM, or accounting systems. But you are left to your own devices once that data reaches your backend, and you must develop an entire infrastructure to transform that data into the dashboards your customers desire.
Peaka collapses all of that into a single embeddable platform: Embedded Peaka. It not only pulls in data from scattered sources but also provides the **UI components** and **white-labeling** capability to make real-time in-product analytics possible.
| Feature | Embedded Peaka | Merge |
| :--------------------- | :------------------------------------- | :------------------------------------ |
| **Deployment Mode** | ✅ Purpose-built for embedding | ❌ Backend APIs only |
| **UI Components** | ✅ Dialogs, query editor, autocomplete | ❌ None |
| **Branding & Theming** | ✅ Full white-labeling | ❌ None |
### **What this means for you**
Merge is a good iPaaS solution, but if your goal is to facilitate customer-facing analytics, Embedded Peaka is the one to pick here.
## **2. Peaka supports live queries**
Merge simplifies syncing data into your system. However, it still needs good ol’ **ETL pipelines and data warehouses** to serve the data. Building and maintaining such a stack can be rather costly, which SaaS companies can hardly afford.
Embedded Peaka removes that overhead. It allows **live or cached queries** without replication, giving you real-time insights from third-party data with no additional infrastructure investment.
| Feature | Embedded Peaka | Merge |
| :----------------------- | :--------------------------------------------------- | :--------------------------------- |
| **Data Access Model** | ✅ Live querying (no replication) | ❌ Requires syncing to DB |
| **Query Engine** | ✅ Built-in (Trino-based) | ❌ No SQL engine |
| **Caching & Rate Limit Handling** | ✅ Rate limit-aware caching built-in | ❌ No caching built-in |
### **What this means for you**
For SaaS teams developing modern data products and AI tools, Peaka’s zero-ETL approach offers speed and agility that Merge simply doesn’t.
## **3. Peaka handles OAuth, governance, and multitenancy**
Merge offers hosted OAuth flows, but leaves you to build tenant-level logic and access governance yourself. That means more code, more edge cases, and more delays.
Embedded Peaka takes a multi-tenant-first approach with:
+ Hosted or BYO OAuth with full tenant awareness
+ Project-, catalog-, and schema-level isolation
+ Role-, column-, and row-level permissions
+ Audit logs and data lineage tracking for compliance
| Feature | Embedded Peaka | Merge |
| :----------------------- | :--------------------------------------- | :--------------------------------------------- |
| **OAuth** | ✅ Hosted, tenant-aware | 🟡 Hosted flows only (non-customizable) |
| **Multitenant Support** | ✅ Native project/catalog isolation | ❌ To be built by the user |
| **Connector Maintenance** | ✅ Peaka-managed | 🟡 Backend APIs maintained by Merge |
### **What this means for you**
In short: Merge connects. Peaka integrates, governs, queries, and displays, ensuring that product teams can focus on improving the embedded analytics experience they provide.
## **4. Peaka includes the frontend, so you don’t have to build it**
Merge doesn’t provide frontend components. Want your users to explore their connected data? You’ll have to build an entire suit of components, including:
+ Query editors
+ Connector dialogs
+ Schema browsers
+ Visual theming
Embedded Peaka ships all of this, branded, styled, and ready to be embedded inside your platform.
### **What this means for you**
Embedded Peaka gives you the tools you need to accelerate your road map, enabling you to make the most of your engineering resources.
## **Key takeaways**
+ **Merge.dev aggregates APIs**, but it doesn’t provide a query engine, UI components, or multitenant governance for embedded analytics.
+ **Embedded Peaka offers a full embedded data stack**, including federated querying, smart caching, white-labeled UI, and OAuth handling.
+ **Embedded Peaka eliminates the need for warehouses or ETL**, allowing teams to query third-party data in real time, without syncing or replication.
+ **Embedded Peaka reduces engineering overhead**, enabling SaaS teams to ship in-product dashboards and analytics much faster than with Merge.
## **Final word: Embedded Peaka helps you build data products**
Merge is a powerful backend integration tool. But for product managers, platform teams, and founders focused on delivering embedded data experiences to users, it’s only half the story.
Peaka gives you everything you need to integrate, govern, query, and visualize third-party data without standing up a warehouse or frontend framework.
Embedded Peaka = Merge + Trino + Looker + OAuth + Multi-tenant governance, all in one embeddable platform.
Explore [Embedded Peaka](/embedded-peaka/) or [book a demo](https://calendly.com/peaka/demo) to see how Peaka replaces entire stacks of backend and frontend work.
Still comparing your options for embedded analytics?
We’ve broken down how Embedded Peaka compares to other platforms to help you make the most informed decision:
+ [Embedded Peaka vs. Airbyte Embedded](/blog/airbyte-embedded-vs-embedded-peaka)
+ [Embedded Peaka vs. Cdata](/blog/cdata-vs-embedded-peaka)
+ [Embedded Peaka vs. Hevo Data](/blog/hevo-vs-peaka-comparison/)
+ [Embedded Peaka vs. Polytomic](/blog/polytomic-vs-embedded-peaka)
--- START: blog/micro-saas-marketplaces/micro-saas-marketplaces.md ---
# **What to Know about Micro SaaS Marketplaces**
Exits are not just for VC-backed startups. Your side project deserves an exit, too, if you so wish. And so does your nicely bootstrapped, trouble-free micro SaaS startup that has been generating recurring revenue for you for some time. An exit with a hefty paycheck is not the primary goal with a side project or a micro SaaS. But being able to sell your project right away would be nice when you are forced to make that decision [for one reason or another:](https://news.ycombinator.com/item?id=27626508)
+ The project owner may be in urgent need of cash for a health issue, a down payment for a car or a house, or something else.
+ Priorities change, and finding time for the project becomes almost impossible for the project owner.
+ The technology changes over time, and the project owner lacks the dedication to invest time and effort to learn new technologies that can keep the project alive.
+ The project owner realizes that the project's ceiling is not as high as he previously hoped.
Whether you are trying to sell a micro SaaS startup that you have grown into a legitimate business or salvage whatever you can from a side project you have to quit, micro SaaS marketplaces are where you need to be. There are different marketplaces catering to different market segments, which interestingly creates opportunities for arbitrage, as [Eyal Toledano observes.](https://newsletterest.com/message/56524/The-math-behind-MicroSaaS-exits-guaranteed-microangel-returns) The offers you receive from buyers who ran into your project in a marketplace or vetted parties a brokerage firm found for you or a strategic investor will be significantly different. Therefore, a buyer can buy a project on the cheap from Tiny Acquisitions or MicroAcquire, grow it to an annual recurring revenue that will appeal to more upscale customers, and turn around and sell the project for a much higher multiple.
Here is a quick look at the most popular marketplaces for micro startups and the differences between them:
## **Flippa**
[Founded in 2009](https://en.wikipedia.org/wiki/Flippa), Melbourne-based Filippa is the oldest marketplace for [buying and selling](https://flippa.com/sell) e-commerce sites, content websites, SaaS startups, apps, and domains. Today, it stands out as the largest marketplace for web businesses in a segment it single-handedly created. The company raised $11 million in Series A funding in 2021, which was a testament to the effectiveness of its business model.
Flippa [boasts](https://firstsiteguide.com/flippa-stats/) 3 million users worldwide and an average of 1.3 million monthly visitors as of June 2022. On top of a subscription fee starting at $29 a month, members pay the platform a [success fee of between 5 and 10 percent](https://flippa.com/pricing), which gets lower as the sale price increases in the event of a sale. These figures are low compared to rivals, making Filippa a competitive offering in the market.
Flippa allows you to sell any site or project, making the platform more inclusive than any other in the market. However, this flexibility also lowers the overall quality of the offerings. [Shill bidding](https://empireflippers.com/the-problem-with-flippa/), lack of vetting for sellers, and the absence of a mechanism to verify the veracity of the sellers' financial claims have hurt the platform's reputation for a long time. Buyers who fell for projects with little to no revenue went on to publicize the scams they were subject to.
Flippa remains the [cheaper option](https://www.nichepursuits.com/flippa-review/) in terms of commission fees compared to its rivals, but the hassle involved makes it hardly worth it. Its failure to move upmarket like MicroAcquire managed to do and offer reliable complementary services has condemned the platform to serving the low-end portion of the market.
## **Tiny Acquisitions**
Founded by Stephen Campbell in May 2021, [Tiny Acquisitions](https://tinyacquisitions.com/home) fills a big void in the market, giving people a platform where they can buy and sell digital projects for $100,000 or less. Members can have lifetime access to Tiny Acquisitions features for a one-time payment of [$997.](https://tinyacquisitions.com/home?pricing=yes) They may also opt for a subscription model ($149 for a 6-month subscription or $199 for an annual subscription). If the buyer and seller use Tiny Acquisition's services for the transfer of funds and the project, then the company charges [9.5 percent of the sale price.](https://www.businessinsider.com/tiny-acquisitions-lets-developers-sell-projects-for-5000-2021-9)
Tiny Acquisitions had set off as a platform strictly focused on hobby projects selling for less than $5,000. The founder, Stephen Campbell, set his sights on taking his company upmarket, where projects valued at up to $100,000 would be listed. This move targeted a market segment different from hobby projects and necessitated the provision of complementary services that could help reposition the platform. As part of this plan, Tiny Acquisitions [partnered with DueDilio](https://www.duedilio.com/tiny-acquisitions/) to make the due diligence process easier for the buyers. It looks like Tiny Acquisitions is gradually perfecting its business model, creating a winning formula for the buyer, seller, and the community at large.
## **MicroAcquire**
Andrew Gazdecki has been the face of the micro SaaS segment as of late. His platform, MicroAcquire, has put the micro SaaS marketplaces on the map, publicizing the different needs companies in this particular segment have and solutions that work for them.
Gazdecki's main focus has been to standardize the micro SaaS acquisition process from start to finish. Unlike well-regulated fundraising rounds where a venture capital firm invests in a startup, the deals in the micro SaaS segment were improvised between two usually inexperienced parties. It was a stop-and-go process, starting with a manual outreach and rife with pauses. MicroAcquire's [Guided Acquisition Process](https://resources.microacquire.com/introducing-the-microacquire-guided-acquisition-process-and-workflow/) provides the buyers and sellers with a road map, reducing friction, ensuring the predictability of the whole process, and increasing the chance of success.
MicroAcquire is trying to differentiate itself and hoping to move upmarket with its [Platinum](https://microacquire.com/platinum/) service. This option is only available to startups with $1 million in trailing-twelve-month revenue. In return for a 5 percent "success fee" in the event that the project is sold, MicroAcquire vets the potential buyers, offers legal advice during the negotiations, and helps with the due diligence part, where the buyer works to verify the claims by the seller. MicroAcquire is basically trying to reposition itself as a brokerage firm with its Platinum service.
Another ace MicroAcquire has up its sleeve is the [partnership it has built with Pipe.](https://resources.microacquire.com/3-ways-to-make-growing-and-selling-your-startup-easier/) [Pipe](https://pipe.com/) is a fintech firm specializing in revenue-based financing for startups generating recurring revenue. While MicroAcquire takes care of the matchmaking part by bringing together the buyer and the seller, Pipe streamlines the acquisition process by providing the buyer with funds in return for a portion of the future revenue. The partnership helps the buyer avoid taking on debt and dilution and keep its acquisition as a privately-owned micro SaaS project.
## **FE International**
[FE International](https://feinternational.com/blog/how-to-sell-your-online-business-with-fe-international/) is a brokerage firm that stands apart from the rest of the pack in the SaaS marketplaces segment with the way it works. Once hired to manage the sale of your micro SaaS business on your behalf, the company interviews you to learn about your expectations and conducts an audit of your firm to conduct an accurate appraisal of your firm. FE International employees build a file of your firm and reach out to a pool of vetted buyers to find parties that may be interested in buying your startup. The brokerage firm engages in acquisition negotiations with the potential buyers, and the process culminates in the preparation of a formal Letter of Intent by the FE International legal team. Once a contract is signed by both parties, the assets of your business are transferred to the buyer, and you will receive the funds after that.
FE International will charge a 10 to 15 percent commission fee on that sale price. Still, it will help you sell your business at a significant premium compared to other marketplace alternatives. This model seems like a no-brainer considering the completely hands-off approach it affords the founders.
## **Conclusion**
Projects listed on marketplaces are like fancy storefronts. You don't really know what is hidden behind, and it is difficult to vet these startups by just looking at the data made available to you. This sets the stage for scams where misinformed buyers are deceived into buying startups with copyright issues, [forged financials, and fake website traffic figures.](https://thewebsiteflip.com/guide/buy-website/flippa-scams/)
A noticeable trend in the micro SaaS marketplaces is the emergence of extra services like legal counseling and brokerage offered to complement the core business. This shift to a more comprehensive service policy is designed to mitigate the risks involved with the acquisition and help buyers with the due diligence process.
That's why brokerage firms and services like FE International are becoming more popular, and marketplaces like MicroAcquire are offering similar services. By verifying the financial data of the startups and taking care of the due diligence on behalf of the buyer, marketplaces and brokerage firms are offering end-to-end services, which reduce the burden on the buyers. This end-to-end approach to matchmaking allows for higher margins for the marketplaces opting for such a business model. It looks like complementary services should become part of the core business if the micro SaaS segment is to fulfill its potential.
--- START: blog/micro-saas-recession/micro-saas-recession.md ---
# **Bracing for the Impact: Micro SaaS on the Eve of a Recession**
## **Is winter coming for tech startups?**
The second quarter of 2022 was not so bright for tech startups. The [Federal Reserve raised the interest rates](https://www.cnbc.com/2022/03/16/federal-reserve-meeting.html) for the first time in more than three years, followed by two further increases [in May and June](https://tradingeconomics.com/united-states/interest-rate), setting the alarm bells for tech startups that benefited from the funds flooding the market for years. Venture capital firms like [Sequoia Capital](https://twitter.com/thealexbanks/status/1529865275876659218) were quick to awaken to the [possible ramifications](https://www.sequoiacap.com/adapting-to-endure-2022/) of this development, reminding their portfolio companies that this is a different market now and that they must become cash flow-positive.
## **The exit challenge**
Founding and leading a startup was no walk in the park even before the recent downturn in the investment markets. Setting off, a startup founder has his eyes set on the ultimate prize of making an exit in the form of the sale of the company for a huge sum or an IPO. However, making a successful exit is an uphill battle. [Reports](https://review42.com/resources/what-percentage-of-startups-fail/) tell us that 90 percent of the startups and 75 percent of the venture-backed startups fail, with only less than half making it to their fifth year.
A regular SaaS business requires a serious commitment in terms of time and resources to be successful. Not everyone might have the means or the willingness to invest huge sums in building infrastructure, hiring a large staff of developers to build a product, and sustaining that effort for a long time. The median time for a SaaS startup to make an exit or IPO was [9 years.](https://blossomstreetventures.medium.com/how-fast-startups-exit-fb8cc0bfa033) In Europe, it takes companies an average of [15 years](https://startupsandplaces.com/startup-exits-europe-2021/) to make a successful exit. Very few people can cope with the demands of running a startup for such a long period.
Such a long journey is only possible if the startup achieves profitability or finds ways to extend its runway. Achieving profitability is a distant dream for a startup because growth is king for a SaaS business, and investing in staff and marketing are the only ways to keep growth going. However, this kind of investment brings diminishing returns in terms of growth as the market gets saturated. So, a dollar spent on hiring new developers and launching new marketing campaigns does not generate as much growth in later stages as it did at the beginning. In other words, sustaining a certain level of growth requires the investment of increasingly more resources. As a result, SaaS startups are always cash-hungry.
## **The not-so-bright side of entrepreneurship**
The life of a startup founder isn’t an easy one. He has to work on his product to make sure that it is positioned right, leverage new marketing channels to sustain a high growth rate, expand his staff, and deal with personnel-related issues. Another task that needs constant attention from the founder involves talking to potential investors to solve the cash drought and prolong the runway.
Family, friends, and angel investors can offer support in the early stages of a startup. But a journey that may take years is not viable without some institutional investors chipping in. Pitching to investors and trying to lure them becomes a staple in the schedule of a founder who wants to keep his business growing. In the meantime, he has to ensure that his company remains attractive for a possible acquisition. Networking and engaging in negotiations to look for a possible buyer for a company can come to occupy an outsized part of a founder’s schedule, distracting him from other duties. This can be a costly mistake, as it usually results in lower performance of the company and a lower valuation.
Just like looking for suitable investors, planning for an exit cannot become the only task on a founder’s agenda. And neither is planning for an exit something you can delay until the time comes. You have to plan your exit [right from day one](https://resources.microacquire.com/why-you-must-start-exit-planning-from-day-one/), the day you found your startup. Starting to think about your exit after you land an offer to sell your SaaS would be too late for making the necessary preparations. A founder would be well advised to keep his financial data in order, receive expert mentoring, work on different acquisition scenarios with conditional payments (earnouts), and ensure that the company achieves its business goals even before receiving a single offer for his company.
## **Life without an exit**
The micro SaaS concept shows us an alternative way: Not chasing exits at all. At the heart of a micro SaaS endeavor is the product that solves a well-defined customer pain, not investor interest. In time, the product gets better at solving the customer pain, nurturing loyalty among the existing but limited customer base, and triggering word-of-mouth to entice new customers.
A micro SaaS startup is a bare-bones, no-nonsense type of organization. It avoids vanity expenses many venture-backed, cash-rich startups are prone to and runs quite efficiently. Therefore, it can stay on a budget and finance its operations with its income, leaving the founder a healthy profit so that he doesn’t need an office job. With the looming economic downturn and dwindling prospects of free money, we can expect more entrepreneurs to set out with a micro SaaS game plan instead of trying to lure investors. The stars are lining up for micro SaaS businesses.
--- START: blog/micro-saas-revenue-based-financing/micro-saas-revenue-based-financing.md ---
# **How to Boostrap a Micro SaaS Venture**
Bootstrapped startups are becoming more popular by the day. Among them, micro SaaS ventures offer entrepreneurs the best of both worlds: The chance to build something of one's own without getting tangled up in the intricacies of attracting investors. People know that venture capital comes with strings attached. Once aware of that, they start to believe that it may not always be worth the dilution and loss of independence unless you hit the jackpot and win big.
## **Financing just in case**
However, remaining bootstrapped has its challenges, too. Bootstrapping does not work in every market. Markets that reward growth at all costs are not suitable for bootstrapped companies. Bootstrapped companies do not enjoy the resource abundance that VC-backed companies enjoy, which shows in their performance. Compared to a VC-backed company, a bootstrapped startup takes [two more years to $1.5 million in ARR](https://www.saastr.com/bootstrapping-in-saas-it-does-work-but-add-4-years-to-the-timeline/) and four more years to $10 million in ARR. These figures underline the fact that bootstrapped companies will fall behind VC-backed companies in the race to scale and may have to be content with a tiny slice of the pie.
Micro SaaS companies usually enjoy a small cash buffer until they scale. Just a few months of weak performance can spell doom for them. They could use a capital injection when the situation becomes too dire, but micro SaaS startups that refuse to receive venture capital do not have that many options to access capital.
Banks are reluctant to lend to these companies, which lack the assets and inventory to collateralize a loan. So, apart from a scenario where the founder's personal assets underwrite a loan, banks do not prove much help to micro SaaS businesses. Luckily, micro SaaS founders who value independence and are unwilling to chase high growth are not beholden to venture capitalists. Revenue-based financing offers a viable alternative here.
## **Revenue-based financing explained**
In revenue-based financing, an investor [agrees to invest in](https://www.investopedia.com/terms/r/revenuebased-financing.asp) a startup in return for a flat percentage of the gross revenues. The monthly payments generally amount to between [2 to 8 percent](https://www.chargebee.com/blog/alternative-saas-financing/) of the startup's revenue, continuing until the investor receives 1.35 to 2.0 times the principal amount he invested.
### **Pros**
Revenue-based financing involves no sale of equity; therefore, it is non-dilutive. The founders remain independent in their decision-making and just have an obligation to pay back the loan as a portion of the monthly revenue until they hit the cap.
The repayments are [flexible](https://www.weareuncapped.com/blog/revenue-based-finance) in this form of financing. If you have had a rough month in terms of revenue, the amount you pay back will be smaller, too, so that your cash flow problems are not compounded in an already bad month. If your company is doing well, you will hit the cap sooner. This flexibility can be invaluable to a micro SaaS company.
Revenue-based financing stands [somewhere between equity financing and bank financing](https://en.wikipedia.org/wiki/Revenue-based_financing) in terms of cost. Bank financing is cheaper than revenue-based financing because the assets used as collateral in bank financing reduce the risk for the bank and bring down the interest rates. However, revenue-based financing is preferable to equity financing for two reasons: The interest paid counts as a tax deduction for the startup, and the effective interest rate resulting from the sale of the company turns out to be much higher in equity financing.
### **Cons**
Revenue-based financing resembles [invoice factoring](https://www.businessnewsdaily.com/6659-revenue-based-financing-tips.html) in that the future revenue is collateralized in the former, just like how invoices or money owed underwrite a loan in the latter. For a startup to be able to receive revenue-based financing, it should be generating revenue, though. [E-commerce businesses and SaaS companies](https://dealroom.co/blog/reinventing-business-capital-revenue-based-financing) with monthly recurring revenue are good candidates for this kind of financing. Very early-stage startups that struggle to generate revenue will not be able to access funds using this method.
Another downside of revenue-based financing is the relatively small size of the funds available compared to equity financing. [The average loan size](https://fitsmallbusiness.com/revenue-based-financing/) in this type of financial arrangement rarely exceeds a few million dollars.
## **Conclusion**
Micro SaaS companies have different needs than regular SaaS companies and thus need custom solutions. It takes some creativity to stay independent and cash-solvent without diluting ownership and sacrificing control over the company's future. Revenue-based financing is one of those creative alternatives that can help micro SaaS businesses deal with a temporary cash drought. As long as your micro SaaS startup has a sound business plan and just needs a bridge loan to overcome a financial hurdle, revenue-based financing is not a bad option.
--- START: blog/micro-saas-valuation/micro-saas-valuation.md ---
# **The Art of Micro SaaS Valuation**
Micro SaaS marketplaces are all fine and dandy, but what is a founder to expect when he puts up his startup for sale? Should he jump on the first offer or spend months waiting for an offer he won't be able to refuse? Making an informed decision is impossible without first knowing the value of the asset at hand.
This is where things get a little bit tricky. A micro SaaS is, by definition, a bootstrapped endeavor and it shuns outside funding for the purpose of remaining independent. Hence, there is no prior investment. To make it worse, most micro SaaS companies are listed for sale at the idea stage, with no revenue to speak of. With no quantitative data available to serve as a basis for valuation, we are wandering into the field of prophecy if we want to put a price tag on a project.
## **Putting a price on potential**
Somebody trying to appraise a micro SaaS business is in the same position as the general manager (GM) of an NBA team, weighing if he should offer a nine-figure contract extension to a player on a rookie contract. During his 4-year long rookie contract, a player is bound to have many ups and downs, run into the infamous "rookie wall," and get injured, which combine to limit the body of work a GM can use to gauge the player's potential. The glimpses of greatness might be there: A few nights of scoring outbursts here and some defensive stops there. However, the player most likely has weaknesses in his game, too, or maybe even injury concerns. Does he have the work ethic to improve his game? Can he stay healthy?
Giving a big contract to a player who later turns out to be a flop can cripple a franchise for years to come. On the other hand, if the GM lets the player walk, there is always the risk of him turning into a star one day, leaving the GM with the guilty conscience of a decision-maker who discovered a diamond in the rough but gave it away. Long story short, assessing potential is an art unto itself.
This applies to the micro SaaS segment, too. Whether you are a seller or a buyer in the market, you want to get a good deal. Learning that you could have gotten much more than you did for your startup or that you paid more than you should as a buyer stings. Even a ballpark figure can help start off the negotiations on the right foot. Luckily, angel investors have been dealing with the problem of appraising pre-money (i.e., a company that has never received outside funding before) pre-revenue startups. Their methods can be used to determine the valuations of micro SaaS projects.
## **The Berkus Method**
[Dave Berkus](https://www.berkus.com/?page_id=54) is an early-stage venture capitalist who had first-hand experience with the pain of putting a price on a pre-revenue startup. Unable to find a way, he decided to make one for himself, as [one North African general](https://quotepark.com/quotes/1863678-hannibal-i-will-either-find-a-way-or-make-one/) had once said. Berkus designed a technique to help evaluate early-stage startups without financials.
Early-stage startups operate in a sea of uncertainty and risks. Berkus concluded that any steps taken to mitigate major risk factors should reflect as a premium on the valuation of a startup. He [defined](https://berkonomics.com/?p=2752) four pre-revenue risk-mitigating factors and an additional post-revenue one:
+ Sound Idea (basic value)
+ Prototype (reduces technology risk)
+ Quality Management Team (reduces execution risk)
+ Strategic Relationships (reduces market risk)
+ Product Rollout or Sales (reduces production risk)
Berkus hypothesized that the presence of each risk-mitigating factor added half a million dollars to the startup's valuation. So, a startup that has ticked off the first four items would be valued at $2 million. While developing this framework, Berkus took care that the startup would be valued at a low enough price to give investors enough room to achieve [at least a 10X return](https://berkonomics.com/?p=1214) on their investments. Therefore, investors could expect the hypothetical startup above to reach a valuation of $20 million at the end of its fifth year.
The Berkus Method was developed in the mid-1990's, so it needed revisioning more than once during the past three decades. Berkus adjusted the method in a way that would reflect the sharp increase in tech startup valuations over time. He also acknowledged that users should allow for the influence geographical differences had on valuations. So, a startup based in Silicon Valley and focusing on a trendy problem like "big data" could justify a $1.5 million per element, while the price tag would be significantly lower for startups operating out of a Midwestern city.
In addition to providing founders and investors with a valuation figure, the Berkus method also establishes a direct link between the risks surrounding a startup and its appeal in the eyes of investors. Founders would benefit immensely from incorporating this approach into how they run their startups.
## **Scorecard Valuation Method**
Another methodology used to assess the value of a pre-money startup is the Scorecard Valuation Method, which was devised by angel investor Bill Paine. This method compares a target company to the other companies in the same industry with a similar stage of development. [Regionality](https://www.forbes.com/sites/mariannehudson/2016/01/27/scorecard-helps-angels-value-early-stage-companies/) is another criterion in this method as geographic location (i.e., the ecosystem, networking opportunities, and concentration of entrepreneurs and investors) tends to have a big influence on the valuation of startups.
The first step in the Scorecard Valuation Method is to establish the [median pre-money valuation for similar pre-revenue startups](https://medium.com/humble-ventures/how-angel-investors-value-pre-revenue-startups-250b5fdcd1e6) located in the region where your target company is based. This number will later become the yardstick for the appraisal you will conduct.
The second step involves [a list of factors](https://www.angelcapitalassociation.org/blog/scorecard-valuation-methodology-rev-2019-establishing-the-valuation-of-pre-revenue-start-up-companies/) that guide the appraisal process and the weights you assign to each one of them:
+ The strength of the management team (0–30%)
+ Size of the opportunity (0–25%)
+ Product/technology (0–15%)
+ Competitive environment (0–10%)
+ Marketing/Sales channels/Partnerships (0–10%)
+ Need for additional investment (0–5%)
+ Other factors (0–5%)
With the Scorecard Valuation Method, you are basically trying to find out how your company stacks up against the competition. As can be seen from the list above, the method privileges the quality of the management team above everything else, even the product itself. This fact stems from Bill Paine's belief that a good management team can correct early product flaws, while a good product will eventually succumb to bad management.
Assigning weights to each factor is a subjective process, as is the self-assessment you will conduct about your capabilities compared to your competitors. You go through the list of parameters and put a number on how much better or worse you think you are than the average competitor in that particular area. Do you believe that your management team is significantly, like 50 percent, better than your average competitor? Then you can assign a 1.5 coefficient to the first factor. If you think your product isn't at the same level as the rival product and lagging behind by, for example, 20 percent, your coefficient for the third factor is 0.8. A coefficient of 1.0 denotes that the startup matches the industry average in that factor. Let's take a look at an example to see how this works:
{{ resize_image(path="../static/assets/images/blog-images/micro-saas-valuation-table.png", width=759, height=400, op='fit_width', alt="Sample Scorecard Valuation table") }}
This example takes a hypothetical company with a management team that is 50 percent more effective than the rivals. The founder assesses that the opportunity he is looking at is 20 percent bigger than what his rivals are looking at, while his product is not at the same level as the competing products. The startup is in a harsh competitive environment; hence, the 0.8 coefficient for both the product and the competitive environment factors. The marketing team and the need for additional investment are on par with the competitors, and the influence of other factors is 80 percent of what it is for rival companies.
The sum of factors in this example is 1.12, meaning the startup in question is 12 percent more valuable than the median valuation of the startups in the region. So, if the median valuation is $3 million, our startup is worth $3.36 million. This method involves a lot of qualitative judgment in deciding the weights of different factors and how the startup stacks up against the competition in each of them. But, the result is as good as any valuation in the absence of financials and prior investment.
## **Cost-to-duplicate Method**
Pre-revenue micro SaaS startups are like the rookies of the startup world: They are difficult to read. They have no recurring revenue that a potential buyer can use as a base for valuation. Their metrics are sparse and, most of the time, meaningless. The product features may imply high potential, but there is too little body of work to justify a lucrative offer. When it is difficult for a micro SaaS startup founder or a prospective buyer to implement the Berkus Method or the Standard Valuation Method for whatever reason, one has to make do with what is available. The Cost-to-duplicate Method is the last resort founders and investors can use when nothing else works.
The Cost-to-duplicate Method is based on appraising the [value of a startup's physical assets, real estate, and inventory](https://www.investopedia.com/articles/financial-theory/11/valuing-startup-ventures.asp) to determine how much it would cost for an investor to build the same company. For a software startup, the valuation would be based on the cost of the engineering hours spent on the product because these companies have no inventories or capital investments in real estate or machinery.
The Cost-to-duplicate Method has two disadvantages: It does not factor in things like [intellectual property, brand value, or the growth potential](https://resources.microacquire.com/5-valuation-methodologies-financial-acquirers-may-use/) of the startup, and it does not work with older startups as more projects are considered failures after a few years without traction. This particular method gives us a "lowest acceptable offer," a base price to use during negotiations. It helps founders salvage some value from a project they would otherwise quit and serves as a nice fallback plan for a project that did not gain any traction.
## **Conclusion**
Founders of micro SaaS startups are in this game for the long run. Their primary areas of focus are bonding with their customer base and nurturing their loyalty. In the meantime, a founder should also be ready for an exit right from day one. That requires coming up with a sensible valuation for the startup.
Micro SaaS startups do not easily lend themselves to traditional appraisal methods. However, "when there is a will, there is a way," as they say. With a little bit of creativity and the three methods listed above, micro SaaS appraisal is no longer the hurdle it might seem to be at first.
--- START: blog/micro-saas-way-motives/micro-saas-way-motives.md ---
# **'Investor Money? Thanks, But No Thanks'—The Micro SaaS Way**
A micro Saas startup is an interesting phenomenon. It is an entrepreneurial initiative built around modest aspirations. The sky is not the limit for a micro Saas because it operates within self-imposed limits: It has a small total addressable market and relatively low revenue potential from the get-go. But why? Why would one settle for a business with a low ceiling when one could go for one with seemingly unlimited potential?
The difference between a regular SaaS startup and a micro SaaS, to a large extent, arises from the financing methods associated with each choice. Generally, whether a startup is bootstrapped or VC-backed has ramifications for the ownership structure, the growth strategy to be pursued, and how the company is run. The origin of the funds comes to define how the journey will shape up for a startup.
Of the two methods in question, bootstrapping refers to financing a startup using the founders' funds or the revenue generated by the product without any money raised from investors. On the other hand, when you raise funds from investors, you are actually selling them a portion of your ownership stake in your startup. This creates a whole different dynamic than bootstrapping.
Here are a few points to keep in mind while deciding whether to bootstrap your startup or look for venture capital.
## **Market dynamics**
Whether you are venturing into a red or a blue ocean will determine your marketing strategy and the budget you will need to implement that strategy.
As per Wes Bush's definition in his book [Product-led Growth](https://www.amazon.com/Product-Led-Growth-Build-Product-Itself-ebook/dp/B07P6288ZF), a red ocean is a mature market where different companies compete with each other to grab a bigger share of the existing demand. The growth in such a market comes only gradually and at the expense of the competitors.
On the other hand, a blue ocean is an uncontested market space where the first player has to create and capture demand. This kind of market lends itself to highly profitable, high growth as long as the product-market fit is realized.
Questions to ponder about before deciding on whether to bootstrap your company or look for investors include:
+ Are you defining a new market category that you want to dominate?
+ Do you have the intelligence that a potential competitor is working on a product like yours?
When you are racing against time, funds from venture capital investors can fuel your growth and help you gain strategic dominance over the market. You will certainly be bleeding money during the growth phase as your revenue growth won't be big enough to cover the increase in your marketing and development-related costs. This is where outside funding comes in handy.
Bootstrapped startups are, most of the time, also cash-strapped. They are used to operating at the edge of insolvency. They can't afford high rates of cash burn as they have a very little buffer, so they learn to prioritize profitability over growth.
## **Managerial independence**
Fundraising involves a trade-off—you accept some level of ownership dilution in return for capital injection. A decrease in your stake in the company will also translate into a decrease in your control over the company's direction.
Most institutional venture capital firms will look to have [seats on the board of directors](https://www.feeltheboot.com/blog/bootstrapping-vs-vc-funding) when they make a substantial investment in a startup. This might both be a curse and a blessing for the founders. Sure, it denotes a loss of independence and can trigger a set of events at the end of which the investors can look to oust the founders. However, the presence of investors on the board also brings accountability to the way founders lead the startup. The experience, vision, and network investors can leverage for the project can be a real asset to founders.
## **Risk tolerance**
[Risk-averse founders](https://www.bitsfordigits.com/resources/bootstrapping-and-vc) find themselves more at home leading bootstrapped companies where they can set the pace in accordance with the resources at hand without chasing aggressive growth. Founders willing to take more risks, on the other hand, will find that they can easily ally with VC firms willing to make a quick buck. After all, such firms tend to have a similar attitude toward risk.
The need to take risks follows from a startup's need to scale quickly. Once they secure VC backing, founders can quickly test out new ideas and experiment with new marketing tactics to fuel growth, subscribing to the "fail fast" mantra. Such a risky, growth-at-all-costs approach works for VC firms as they have many startups on their portfolios at any given time. They only need one or two of them to really pan out so that they can [turn a profit on their whole portfolio](https://vistapointadvisors.com/perspectives/bootstrapping-vs-venture-capital).
## **Micro SaaS as the quintessential bootstrapped startup**
A micro Saas startup is a textbook example of a bootstrapped company: A group of maximum five people with no aspirations to set the market on fire, led by a risk-averse founder who values managerial independence over liquidity and profitability over scaling. A company happy in its own skin, catering to and maintaining a personal touch with a limited customer base having a well-defined pain. A micro SaaS startup does not chase ambitious target metrics but instead tries to minimize customer churn and build brand loyalty.
Micro SaaS startups are proof that one can build a life-changing venture without engaging in endless marketing wars, experimenting with fringe business tactics, or answering to investors. These companies can generate healthy five-figure MRRs without the added stress of having to achieve year-on-year exponential growth. Micro SaaS startups are built to make their founders happy, investors be damned!
--- START: blog/microservices-challenges/microservices-challenges.md ---
# **How to Solve the Top 7 Microservices Challenges**
Microservices are becoming increasingly popular these days. A microservice is an architectural approach to software development that regards a software application as a series of independent services. And all of these services are connected using well-defined APIs, which also enables them to communicate with each other. Indeed, businesses can effectively leverage [microservices best practices](https://www.tatvasoft.com/blog/microservices-best-practices/) to offer a large array of benefits, but building microservices comes with its own set of challenges.
In this article, we are going to discuss some common problems you might face during the development and usage of microservices. Additionally, we are going to suggest ways to address these issues, with a focus on novel methods powered by artificial intelligence (AI) and machine learning (ML).
## **Top microservices challenges and solutions**
### **1. Service discovery and registry**
Microservices are just one type of architectural style used for distributed computing. Here, the application is formed by combining various independent services that are capable of communicating through a network. When a customer wants to use this service, they must know the specific location of the network. In the case of one available location, there wouldn't be much of a problem. But if the location keeps on changing, then we have a very complex problem at hand.
To resolve this issue, the designers must install a service registry along with the database of every service network location. Service discovery and registry could also be accomplished using a third party with a common registry. A common registry will enable the customers to quickly discover the network locations of services. Such solutions are already implemented in the Kubernetes service and Netflix Eureka service registry.
#### **How AI and ML can help**
Machine learning algorithms can improve service discovery mechanisms by using historical data to predict optimal service instances. Through the analysis of service usage and performance patterns, machine learning models can recommend the most efficient service instances for request handling, which results in improved load balancing and reduced latency.
### **2. Unified access to services**
As we already discussed, microservices are the combination of loosely connected multiple services. These services are rendered to a large number of customers. Not every customer would want the same thing in the same way. Everyone might have different requirements. For example, for a web application, you will need a set of information that is grained coarsely, but for a mobile application, you need a set of information that is grained finely. And things might get worse if these services are implemented with protocols such as REST and JMS.
To simplify the process of accessing these different services, you might need something called a unified access mechanism. This mechanism can be built by utilizing a simple API gateway as a single-entry point for every service associated with the microservices architecture.
To access the services, the customers would have to call the API gateway. Then the [API will route](/blog/no-code-api-deployment/) the users to their requested services. On top of that, the API gateway also offers additional services like security metering, aggregation of services, and more. You can see such a mechanism implemented in Apigee, Amazon API Gateway, and Spring Cloud Zuul.
#### **How AI and ML can help**
AI-driven API gateways can optimize response times and resource utilization by intelligently routing requests to the most suitable microservice instances. Learning from traffic patterns, these gateways dynamically adjust routing strategies and maintain peak performance.
### **3. Authentication and authorization**
Security will be one of the main concerns no matter what software services you are using. The same is true for microservices. To make your services secure, you can apply a simple centralized authentication service. It will ensure that all the customers who want to utilize the microservices are authenticated first. On the other hand, every single service should be charged with authorizing their customers as well.
#### **How AI and ML can help**
AI-powered security tools can enhance authentication and authorization processes by detecting abnormal access patterns and potential unauthorized access attempts. Machine learning models can analyze user behavior to establish baselines and flag deviations, identifying security threats before they materialize
### **4. Logging and debugging**
To fulfill some of your needs, only a single service in microservices architecture can be enough, but other times, it may require multiple services to work together to meet your demands. In microservices, every service has its log. It would be overwhelming for a developer to go through these logs manually, aggregate all the services, and then troubleshoot the bugs.
The alternate way to accomplish logging and debugging is to play it smartly. All you have to do is use a simple logging service every service will be connected to for writing their logs. Some common examples of such technical implementation are Kibana, Logstash, and Elasticsearch.
#### **How AI and ML can help**
Machine learning algorithms leverage automated log analysis to pinpoint patterns and anomalies that could signify problems. This method fast-tracks root cause analysis and improves the precision of debugging efforts.
### **5. Configuration**
Configuration in a microservices architecture can be complex due to the independent nature of each service. Each service requires individual configuration, which can be challenging when running the application in different environments without modifications. Configuration settings can include network locations, database credentials, environment variables, and other parameters, further complicating the process.
One way out of this jam is to enable centralized configuration services wherein every service is connected with this service to configure itself. Now this service must have a common configuration repository that allows the centralized service to read the configurations of all the services. One example of such a system is Kubernetes configmap.
#### **How AI and ML can help**
Dynamic configuration management is another process that can be enhanced through the use of AI. By predicting the effects of configuration changes and suggesting ideal settings, AI can minimize human error and find the optimal configurations for operating conditions.
### **6. Services communication**
Another challenge you might face is that your services can't work together in sync to fulfill your needs. One possible cause for that is a lack of a communication medium between various services. There are three ways to resolve this issue and establish communication among microservices:
+ Service mesh
+ Point-to-point using API gateway
+ Using a messaging event drive platform
#### **How AI and ML can help**
AI can be used to enhance inter-service communication through the analysis of traffic patterns and the prediction of potential bottlenecks. This can lead to improved performance and reduced latency thanks to recommendations on how to adjust communication protocols or service placements from machine learning models.
### **7. Testing**
Testing the services can be challenging when there are a lot of them to deal with. If you want to conduct a [unit test or an integration test](https://revdebug.com/blog/unit-tests-vs-integration-tests/), you can do it by either mocking the microservices individually or mocking the dependent APIs available for the test. You can conduct various mock tests with the help of Cucumber, BDD, WireMock, etc.
#### **How AI and ML can help**
AI-driven testing tools can improve the reliability of microservices deployments by intelligently selecting test scenarios based on code changes and historical defect data. This automated approach to test case generation and execution enhances both test coverage and efficiency.
## **Final thoughts**
There can be a lot of problems when you are dealing with microservices, and we can hardly get to address a few. But the ones we discussed here are some of the common problems that you might face while developing or working with microservices. We hope that this article can be helpful to you in overcoming the microservices challenges.
--- START: blog/multi-location-servicetitan-reporting/multi-location-servicetitan-reporting.md ---
# **How Contractors Integrate Multi-Location ServiceTitan Data**
As home service companies grow, they often find themselves juggling more than just new customers, technicians, or trucks. With each new location or acquisition, the business adds another layer of operational complexity, and that complexity is reflected in the data.
In many cases, each branch or business unit operates its own ServiceTitan account, often due to legacy setups, regional independence, or the company's gradual scaling over time. While this structure may work operationally, it creates a serious challenge when it comes to reporting. Leaders are left asking, "How do we see the whole picture?"
The answer begins with unifying that fragmented data into a single source of truth.
This guide is for owners, GMs, and operations leaders at multi-location home service businesses who want a single, clear view of performance across locations, without relying on weekly exports or spreadsheets. We will cover what “good” multi-location reporting looks like, why common workarounds fail at scale, and how to roll up KPIs consistently across branches.
If you are a consultant delivering dashboards for many different ServiceTitan clients, see the guide we created for [multi-account ServiceTitan consultants](/blog/manage-multiple-servicetitan-accounts/). If you are a PE firm unifying reporting across a portfolio of brands, check out our [PE reporting guide](/blog/unify-servicetitan-data-pe-firms/).
## **Key takeaways**
+ **Growth often leads to fragmented ServiceTitan data:** As businesses expand into new regions or acquire other companies, they typically end up managing multiple ServiceTitan accounts, each with its own structure.
+ **Manual reporting across accounts is slow and error-prone:** Exporting and merging data from different accounts in spreadsheets wastes time and prevents real-time decision-making.
+ **Peaka unifies data from all ServiceTitan accounts:** With native multi-account support, Peaka standardizes your data and sends it to your BI tool of choice for fast, company-wide visibility.
## **The multi-location challenge**
Running multiple ServiceTitan instances is common among growing contractors, particularly those expanding into new markets or rolling up regional players. But it quickly creates barriers to visibility. Each instance might use different job codes, technician naming conventions, or service categories. Even something as simple as “Job Type” or “Lead Source” might be tracked differently across accounts.
This inconsistency makes it difficult to compare performance from one location to another. A CFO might see rising revenue in one region but have no way to measure profitability in a comparable way elsewhere. Ops leaders may want to benchmark close rates or dispatch efficiency, but the data lives in silos. At the executive level, this fragmented view creates delays, confusion, and missed opportunities.
## **Why the workarounds fail**
To solve the problem, many companies fall back on manual methods. They [manually export data](/blog/servicetitan-manual-data-export-costs/) from each ServiceTitan account and try to merge them in Excel. This often involves aligning columns, correcting inconsistencies, and copying data into a master sheet. What starts as a temporary fix soon becomes a full-time job for someone on the team.
These stopgap measures introduce risk:
+ Spreadsheets are slow to update, difficult to standardize, and prone to human error
+ Consultant-built dashboards rely on static data and break when business logic changes
+ BI tools fail to deliver value if your data is not integrated in the first place
In the end, teams spend more time preparing reports than acting on them. And real-time visibility becomes an unattainable goal.
## **What a unified view should look like**
A properly unified ServiceTitan reporting setup gives decision-makers the ability to:
+ Combine ServiceTitan and accounting data
+ [Track job costs](/blog/track-job-costs-servicetitan/) and revenue across all business units
+ Compare technician performance by region
+ Monitor close rates, margins, and backlog in real time
+ Filter reports by location, service type, or team
+ Standardize KPIs so comparisons are meaningful
With a unified view, teams get not only better data but also faster decisions and tighter accountability.
## **How Peaka solves multi-account integration**
Peaka was built with this exact challenge in mind. It connects to multiple ServiceTitan accounts simultaneously and unifies the data behind the scenes. Whether your business operates three locations or thirty, Peaka aligns fields, reconciles naming conventions, and delivers a consistent reporting layer.
With Peaka, you can:
+ Connect multiple ServiceTitan instances with no engineering effort
+ Normalize naming conventions and standardize job types, tech IDs, and cost fields
+ [Integrate ServiceTitan and QuickBooks data](/blog/servicetitan-finance-integration/) into a single dataset
+ Send analysis-ready data directly to your BI tool ([Power BI](/blog/servicetitan-power-bi-integration/), [Looker Studio](/blog/how-to-connect-servicetitan-to-looker-studio/), [Metabase](/blog/how-to-connect-servicetitan-to-metabase/), or Tableau)
No spreadsheets. No custom scripts. No delays.
## **The strategic advantage of unified data**
When ServiceTitan data is fragmented, growth introduces more confusion than clarity. But when it’s unified, the story changes.
Leaders gain the ability to benchmark performance across markets, track key metrics like gross margin and job cost at scale, and drive company-wide alignment. New acquisitions become easier to onboard, and teams across locations can operate from shared KPIs.
In short, a unified data foundation helps home service businesses act like one company, not ten disconnected ones.
## **Conclusion: Centralized data for decentralized teams**
Multi-location growth should increase your opportunities, not your reporting burden. If your team is spending more time cleaning up ServiceTitan data than using it, it is time to rethink your approach.
Peaka gives growing contractors the ability to consolidate their data, eliminate reporting silos, and power [real-time dashboards](/blog/servicetitan-dashboards-no-data-team/) across all business units.
The result is better visibility, faster insights, and smarter decisions at every level.
Want to unify ServiceTitan data across multiple accounts?
[Book a demo](https://calendly.com/peaka/demo) to see how Peaka helps home service companies connect the dots across their entire business.
--- START: blog/network-effects-benefits/network-effects-benefits.md ---
# **The Top 3 Benefits of Network Effects**
Our last blog post established that network effects have been integral parts of products and services that have created most of the value created in the last few decades. But why do networked products generate more value than products without network effects? Are there any specific problems decision-makers can use network effects to solve?
Here are three major benefits companies hope to gain by taking advantage of network effects:
## **Helping solve the cold start problem**
Achieving the product-market fit (PMF) is the bane of all founders and corporate decision-makers launching a product. Finding the way to PMF is more of an art than science, and people who came up with viable solutions to this problem are regarded as gurus. Geoffrey Moore describes the struggle to find traction and reach PMF as 'crossing the chasm.' But I think Andrew Chen, in his book *[The Cold Start Problem](/blog/book-review-cold-start-problem/),* does a better job of naming it by calling it 'the cold start problem,' as in getting a car started on a winter morning, and offers network effects as the solution.
According to Chen, there has to be an atomic network, the smallest possible network that is stable and can grow on its own, in place for network effects to kick in. The good people at NfX call this unit a "[minimum viable cluster,](https://www.nfx.com/masterclass/network-effects/network-theory-properties)" but the idea remains the same. This small community consists of people who share a common pain. Solving that pain in a simple, frictionless manner wins these people over and turns them into evangelists. The size of an atomic network is the smallest allowing its members to fully experience the product and extract the intended value. For Slack, the atomic network is made up of three users, meaning that it's only with the addition of the third user that one gets to enjoy the benefits of Slack.
The idea is to multiply the number of these atomic networks and bring it up to a certain density in a specific city, campus, or market segment to create a critical mass. Reaching that critical mass gives rise to word-of-mouth and starts a flywheel effect among people with similar needs. The more users join the network, the better the experience for everyone. Effortless customer acquisition that does not need marketing resources—it's every entrepreneur's dream.
## **Building a moat around the business**
An [economic moat](https://www.investopedia.com/ask/answers/05/economicmoat.asp) refers to the competitive advantage a business enjoys over rivals, which helps it protect its profits and market share. Network effects, when successfully implemented, can work like a water-filled ditch surrounding a castle, allowing a company to preserve its hard-won market position.
Entrepreneur and NfX general partner James Currier [counts](https://www.nfx.com/post/defensibility-most-value-for-founders) network effects among the four sources of defensibility, together with economies of scale, brand, and embedding (increased switching costs). Products leveraging network effects become more than a sum of their features. People use these products because they offer the best experience while solving a problem. As the network grows with the addition of like-minded people, it becomes a source of value for users. Unfortunately for competitors, while features can be copied, networks can't.
Think about all the Facebook and Twitter clones you have seen, none of which went anywhere. They offered functionality similar to the original idea but failed to dislodge the incumbents because social media platforms are nothing without their networks. As a user, you want to be where your contacts are. If your friends start quitting a messaging app you use, you, too, will be on your way out before long.
## **Increased customer lifetime value**
Companies taking advantage of indirect network effects are known for the products or services they give away for free. The idea is to achieve spectacular levels of growth in user numbers, get people hooked on the product, and then use this user base to generate other sources of revenue.
Meta used its social media platform (Facebook), and Google capitalized on its dominant search engine to create an ads business that earned them billions of dollars. They did this without charging their users for using their main products. The better the user experience on Facebook and Google, the more Meta and Google are able to charge another group (media buyers) for their ads. This model increases the customer lifetime value by preserving the already top-notch user experience and increasing the users' engagement through different levers.
Gaming companies have masterfully combined the [freemium model](https://edvice.pro/articles/en/220/free-to-play-games-how-they-work-and-generate-revenue) with network effects to earn billions of dollars every year. These companies initially release free-to-play games to attract casual gaming fans. As a casual gamer becomes part of a network and the game becomes more competitive, he is more likely to pay for extra features and in-game items. This model replaces a one-off purchase, which the player will stop playing in a few days and remove from his device, with a long-lasting, dynamic model leveraging the engagement generated by a network.
## **Final thoughts**
There is a reason startup founders and corporate decision-makers are dying to incorporate network effects into their services and products. Network effects cure the traction issue from the get-go, give your product defensibility vis-à-vis the rivals, and extract more lifetime value from each customer—killing many birds with one stone. Turning great products into generational trends, network effects are the closest thing to Iron Man's armor you can hope to have.
--- START: blog/network-effects-types/network-effects-types.md ---
# **The Types of Network Effects Explained**
What do Apple, Alibaba, and Visa have in common? All American companies? Nope. All tech companies? Not really. All three have a lot of cash? Yeah, but c'mon, that does not count. These companies have all leveraged network effects to become what they are today now, consistently ranking high in the list of the most valuable companies in the world year in and year out.
## **What network effects unlock for us**
Network effects refer to a phenomenon whereby the value of a good, a service, or a platform increases as the number of users grows. Before diving deep into what these forces are, it is essential to understand the [two types of value](https://amt-lab.org/blog/2020/4/reid-manning-framework-post-draft) we derive from goods and services with network effects.
### **Inherent value**
This corresponds to the kind of value an individual derives from using a good or a service. This is the value we enjoy from just solving a pain by using a product for the job it was designed for. Think about your favorite video game. It's a source of entertainment for you, giving you a much-needed distraction from life, even when you play in the single-player mode all by yourself.
### **Network value**
This is the compounded overall value derived from a good or a service when it is used by a community. To continue with the video game example, [platforms like Steam](https://www.nfx.com/masterclass/network-effects/network-effects-in-gaming) help you unlock the network value hidden in your favorite game. You can tap into the game modes developed by your fellow gamers, exchange in-game items with them, and form online tribes you can take to other games. Network value builds upon the inherent value and enriches it to such an extent that the product feels transformed.
Tech companies have become particularly good at combining these two. They first develop killer products that deliver users instant value from usage. Then, they layer the network value on top of that, revealing a new set of benefits once the product becomes popular in a community of users.
A good example would be Twitter. You could use Twitter as a microblogging service if you had no other contacts on the network. However, the presence of a network, the likes, retweets, and the embedding function completely transform the Twitter experience, turning it into a habit-forming product. The network effects are the difference between an isolated personal microblog and an addictive social media app.
## **Types of network effects**
Although sometimes grouped into two categories (direct and indirect), network effects make better sense when they are classified into three types:
### **Direct network effects**
Direct network effects describe the increase in value users get to enjoy thanks to the growth of a network. For example, the bigger your LinkedIn network is, the more valuable it becomes for you with regard to accessing knowledge or becoming aware of job opportunities.
These effects are particularly prominent in communication networks and let you see [Metcalfe's law](https://en.wikipedia.org/wiki/Metcalfe's_law) at work. Metcalfe's law states that the value generated by a network is proportional to the square of the number of nodes in that network. Therefore, as the number of users with a phone line, fax machine, or WhatsApp on their phones increases, the network comes to generate increasingly more value for the existing users.
### **Indirect network effects**
Some network effects are more subtle and operate in more mysterious ways than direct network effects do. However, despite not being out in the open, their impact can be astonishingly significant. Indirect network effects occur when increased usage of a product or a service creates value for another product, which, in turn, adds to the value of the first product. Andrew Cheng provides an inspirational example to this phenomenon in his book [The Cold Start Problem.](/blog/book-review-cold-start-problem/)
IBM struck a deal with Microsoft in the 1980s for a partnership that would change the tech industry forever. According to the deal, IBM's hardware components and applications would work on the MS-DOS operating system. The deal required Microsoft to develop a custom operating system for IBM PCs. An underestimated clause in the agreement gave Microsoft the right to sell the operating system it would build for IBM to other brands (*The Cold Start Problem*, pp.120-22).
This clause triggered a chain reaction.
+ Manufacturers copying IBM's proven formula also inadvertently started developing products compatible with MS-DOS.
+ Users appreciated the wide range of applications on PCs that came with MS-DOS.
+ With more people using PCs running on MS-DOS, developers were incentivized to prioritize developing applications for this particular operating system.
+ Of course, manufacturers would not be indifferent to this sea change. They licensed MS-DOS because products running on MS-DOS were what customers demanded.
Microsoft had successfully built an ecosystem around MS-DOS, with users, developers, and PC manufacturers deriving value from it. This clever game plan created a sustainable, lucrative business on top of indirect network effects. Using this blueprint, Google and Apple were able to leverage Android and iPhone, respectively, to tap into the app store business.
### **Two-sided network effects**
Two-sided network effects exist in platforms that bring together two distinct groups of users, like buyers and sellers, or drivers and riders. The increase in the number of one group creates more value for the other.
Ride-sharing platforms provide a good case in point. When more drivers join these networks, it becomes easier for customers to find a driver nearby, bringing down the estimated time of arrival (ETA). The same phenomenon applies to marketplaces like Amazon and eBay as well. As the number of sellers on these platforms increases, buyers enjoy a wider range of options and lower prices.
However, the value resulting from two-sided network effects tends to be [asymptotic](https://www.nfx.com/masterclass/network-effects/network-theory-properties), that is, the growth in the supply side (sellers or drivers) results in diminishing returns. Having 200 different options, though, is not necessarily better as it will lead to confusion. Likewise, an Uber driver showing up at your door in 5 minutes is ace. But an ETA of one minute will not generate extra value as you will still take a few minutes getting prepared before going out.
## **Final thoughts**
Analysts at the venture capital firm NfX conducted a study of digital companies from 1994 to 2017. They concluded that companies relying on network effects were responsible for [70 percent of the value created in the last 25 years.](https://www.nfx.com/post/70-percent-value-network-effects) From American and Chinese social media platforms to Google and Tesla, it is difficult to think of a company that has dominated its respective industry without taking advantage of network effects in the last quarter century.
But what exactly do these forces do for companies? What do they bring to the table that catapults its practitioners into industry leadership? The answers to these questions justify another blog post. Stay tuned.
--- START: blog/nft-showcase-template/nft-showcase-template.md ---
# **How to Showcase Your NFT Collection**
If you are an avid follower of technology and the software industry, you must be used to freqeuntly being introduced to new concepts and ideas, some of them outrageous. The last few years have been particularly fertile in that regard, giving us blockchain, Ethereum, Metaverse, and the like. However, one recent invention, Non-Fungible Token (NFT), sounds crazy even by the standards of the tech industry.
An NFT is a [blockchain-based cryptographic asset](https://www.investopedia.com/non-fungible-tokens-nft-5115211) containing a piece of metadata and, therefore, is unique. Unlike other blockchain-based tokens like Bitcoin and Ethereum cryptocurrencies, which are interchangeable, NFTs [derive their value from an underlying asset](https://en.wikipedia.org/wiki/Non-fungible_token), making them non-fungible. An NFT is a token that is considered unique because of the data attached, which turns the token into a [medium of creative expression.](https://nftschool.dev/concepts/non-fungible-tokens/#what-makes-a-token-non-fungible) All digital artwork consists of 1s and 0s. It is when you [tokenize](https://shinhyungchoi.medium.com/proof-of-provenance-why-nfts-can-be-valuable-1489ed1395fd) that artwork as an NFT that it becomes recorded on a blockchain ledger and one of a kind.
People are coming up with creative use cases for NFTs recently. Some of these use cases can be confusing, prompting you to ask yourself, "who needs something like that?" For example, a marketing agency has minted NFTs of the sounds of 10 automobile engines from BMW for its "[Museum of Sound](https://www.youtube.com/watch?v=U4gJPra97W8)" project. Who knows, maybe they are banking on the assumption that those NFTs will probably be worth something in an EV-only future, where the sound from an internal combustion engine will be a distant memory.
Without any sensible use cases, the ongoing NFT mania would be another [Tulip mania](https://en.wikipedia.org/wiki/Tulip_mania), that surge, and the subsequent collapse, in the prices of tulip bulbs in the seventeenth-century Netherlands. However, people experimenting with different uses of new technology, pushing the envelope at times for results with questionable value, is nothing unusual. As the new technology matures and becomes more mainstream, those extreme proposals fall by the wayside. Here are a few use cases for NFTs that are not too far-fetched and might fill a void today:
## **Art**
Artworks minted as NFTs have been fueling all this talk about NFTs and grabbing the headlines. Digital artist Beeple selling an NFT of his work for [$69 million](https://www.theverge.com/2021/3/11/22325054/beeple-christies-nft-sale-cost-everydays-69-million) was what opened people's eyes to the NFT market. This deal was not an isolated case but rather part of a larger trend, reflected in the spike in the trading volume NFT marketplace OpenSea has enjoyed recently. The platform recorded a trading volume of more than [$5 billion](https://decrypt.co/91748/opensea-record-5b-ethereum-nft-market-swells) in January 2022, about 50 percent higher than its previous record of nearly [$3.5 billion](https://decrypt.co/82564/ethereum-nft-market-opensea-record-cryptoadz-sales-surge) in August 2021.
The boom of the NFT market follows from the fact that NFTs serve a purpose for both buyers and producers of artwork. Customers seek authenticity and uniqueness in art, two attributes NFTs can verify for them. On the producer side, NFTs can be a game-changing technology for artists who feel they haven't been compensated enough for their work. NFTs facilitate the monetization of work like murals or graffiti, which were previously difficult to monetize, and create new revenue streams for the artists. NFTs also make it easier for the artists to track and collect royalties on their work. A simple smart contract can give an artist [a portion of the revenue](https://www.coindesk.com/markets/2021/03/07/how-nfts-became-art-and-everything-became-an-nft/) every time her work is sold.
Art has become a legitimate investment option in the last quarter-century, consistently delivering an annual return of [7.6 percent](https://www.forbes.com/sites/forbesbusinesscouncil/2022/01/18/art-investment-trends-to-look-out-for-in-2022/?sh=3f602bf62fa0) and outpacing the S&P 500 by around [180 percent](https://smithandpartner.co.uk/blogs/news/why-right-now-is-the-best-time-to-invest-in-art) from 2000 to 2018. However, most artwork is considerably more expensive than regular people can afford. NFTs [fractionalize the ownership of the artwork](https://www.navascusi.com/en/fractional-nfts/) and make it more accessible to regular people who want to invest. Once a work of art is minted into an NFT, it can be divided into shares and jointly owned by a group of people who would otherwise not be able to invest.
## **Collectibles**
Collectible is an item that does not have an intrinsic artistic value but is worth more than its initial sale value due to its [rarity and/or popularity.](https://www.investopedia.com/terms/c/collectible.asp) So, the value of a collectible does not reflect its functional utility or aesthetic quality but what people are willing to pay for it for the privilege of ownership. The fact that Jack Dorsey, the co-founder and former CEO of Twitter, sold the first-ever tweet for [$2.9 million](https://www.cnbc.com/2021/03/22/jack-dorsey-sells-his-first-tweet-ever-as-an-nft-for-over-2point9-million.html) provides a good case in point.
NBA Top Shot, a partnership between NBA and the Canada-based Dapper Labs, has proved that NFT collectibles can be the basis for a viable business model. The app sells digital assets based on NBA highlights minted as NFTs, or "moments," and started the year strong with a [72 percent](https://markets.businessinsider.com/news/currencies/dapper-labs-nba-top-shots-crypto-blockchain-art-kevin-durant-2022-1) increase in trade volume in the first month of 2022. Considering the worldwide following the NBA and its stars enjoy, it is safe to say that the sky's the limit for the NBA Top Shot NFT
## **In-game items**
Buying and selling in-game items have been familiar concepts for us. Fans of online video games like World of Warcraft have been purchasing weapons, armor, accessories, or potions and upgrading their characters for close to two decades now. However, the marketplaces for these items were previously fenced-off within the gaming platforms. Today, NFTs are taking in-game item trading out into the real world, letting gamers buy and sell items regardless of time and place.
NFTs are powering the [play-to-earn model](https://decrypt.co/resources/what-are-play-to-earn-games-how-players-are-making-a-living-with-nfts) of gaming, in which gamers earn real-world rewards for their success. Some gamers [in the Philippines](https://identityreview.com/10-nft-future-use-cases/) can even make a living by doing that. Axie Infinity, the most popular play-to-earn game where you get to collect and battle Pokemon-like monsters, is the gold standard in such games nowadays. Boasting [2.8 million fans](https://decrypt.co/87334/facebook-metaverse-battle-for-future-internet-axie-infinity) currently, the game awards its players [Smooth Love Potion](https://www.binance.com/en/price/smooth-love-potion) crypto tokens and has generated more than $3.5 billion in revenue so far.
## **Events**
For decades, tickets have done a fine job of letting people partake in concerts, rave parties, and other events. But there are issues like secondary ticketing or counterfeit tickets that still stand. NFTs can fix these problems by making tickets completely traceable and introducing transparency into the process. Thanks to NFTs and smart contracts, not only will the organizers be able to see every time a ticket changes hands, but artists, crew, and other workers working backstage will be able to receive a percentage of the resale value in every transaction. Letting artists tap into the secondary ticketing market and access [an ongoing revenue stream](https://cointelegraph.com/news/showtime-nft-tickets-take-the-stage-in-2022-connecting-artists-and-fans) is one of the most important features of NFTs.
What about the fans? NFT tickets can be used to change the way fans interact with artists. These tickets can be minted with [exclusive rewards and perks](https://cointelegraph.com/news/nft-powered-startup-aims-to-revolutionize-events-and-ticketing-industry) such as backstage access, meet-and-greets with the performers, limited audio and video copies from the event, and free tickets for future events. These rewards and perks can be used to create one-off offers that can be sold for a premium or personalize the experience for fans.
## **Digital identity, proof of provenance, and supply chain management**
You may be thinking, "What do these three have to do with one another?" They may sound unrelated, but they have one concern in their focus: Verifying the authenticity of a claim.
- You want to know whether the person you are dealing with is who he says he is.
- You want to make sure that the candidate you are interviewing graduated from the school she claims to have graduated from.
- If you are paying thousands of euros for a single bottle of Bordeaux wine, you want to be certain that it is made from the grapes harvested from that particular vineyard you have been hearing about.
The immutable character of NFTs makes them perfect for verifiable documents of identification like ID cards or passports, or professional qualification documents like diplomas. Being based on blockchain technology, NFTs can serve as immutable proof of provenance, which is what you want to see if you are shelling out big bucks for artwork or luxury goods. By making materials and processes traceable, NFTs give end-customers visibility into the supply chain. This kind of traceability means a lot to customers who are keen on buying ["organic" or "ethically sourced" products.](https://www.foley.com/en/insights/publications/2021/11/not-by-the-same-token-nfts-in-supply-chain)
We have covered blockchain technology extensively [on our blog.](/category/web-3-0/) To complement that coverage, we recently launched an [NiftyExpo template](/templates/), letting our users create pixel-perfect landing pages for their [OpenSea](https://opensea.io/) collections. Instead of watching your collection get lost in a sea of collections, you can now bring your NFTs under the limelight and feature them on a customized landing page. If you want to give your digital artworks the stylish stage they can shine on, Peaka's NiftyExpo template is the tool for you!
--- START: blog/no-code-africa-tech-revolution/no-code-africa-tech-revolution.md ---
# **Can No-code Lead the African Tech Revolution?**
What spurred the low-code/no-code technology was the chronic shortage of developer talent the tech industry was facing. Software was eating the world, and the number of graduates from computer science-related departments just couldn't keep up with the increase in demand. It all started with automating repetitive tasks and boilerplate code. Today, low-code/no-code technology can produce enterprise-grade internal tools, web apps, and SaaS tools on which whole businesses are built.
The global low-code market, enjoying a decades-long head start over the no-code technology, stood at $16.3 billion in 2019 and is projected to reach [$148.5 billion by 2030](https://www.globenewswire.com/news-release/2022/09/15/2517120/0/en/Low-Code-Development-Platform-Market-Size-is-projected-to-reach-USD-148-5-Billion-by-2030-growing-at-a-CAGR-of-27-8-Straits-Research.html), growing at a compound annual growth rate (CAGR) of 27.8 percent. The global no-code market, on the other hand, was valued at $12.13 billion in 2021 and is predicted to grow at a CAGR of 24.1 percent, [reaching $68.03 billion in 2030.](https://www.prnewswire.com/news-releases/global-no-code-development-platforms-market-set-to-reach-usd-68-03-billion-by-2030--with-a-sustainable-cagr-of-24-1--growth-market-reports-301664362.html)
## **Tech jobs migrating to developing countries**
It is safe to assume that a large chunk of this growth will come from developing countries where no-code satisfies a vital need. India has become to software development what China ("the workshop of the world") was to manufacturing. As the demand for software drove up developer salaries in the West, companies and individuals worldwide started o to look for alternative sources of developer talent. Outsourcing work to Indian developers has become a common practice in this process, helping integrate the Indian workforce into the global job market.
Another region looking to take a larger share of the world economy in the twenty-first century is Africa, and it looks well-positioned to do so. The continent has a population of around 1.4 billion as of 2022. [According to the UN](https://www.macrotrends.net/countries/AFR/africa/population), the population is expected to hit 2.5 billion by mid-century and 4 billion by the end of the twenty-first century. African countries lack the industrial infrastructure to employ the young and growing population or the capital to build up their industrial capacity. That's why they turn to foreign capital and know-how to diversify and add complexity to their economies so that they can accommodate this tide of youth about to join the workforce.
## **The dragon with an agenda**
China looks to be benefiting the most from this African appetite for foreign direct investments. As part of its Belt and Road Initiative, the country lent money to African countries and invested heavily in ports, railway networks, and mining concessions, especially in the eastern part of the continent. However, there are serious claims that China is engaging in [predatory lending practices](https://thediplomat.com/2022/03/how-chinas-ambitious-belt-and-road-plans-for-east-africa-came-apart/): Lending money at high interest rates, demanding quick repayment, and deliberately targeting countries that will not be able to pay off the loans. Once the borrowers default on the loans, China can ask for geopolitical concessions and take over the infrastructure it built in those countries. This practice has become so common that people coined a word for it: [The debt-trap diplomacy.](https://en.wikipedia.org/wiki/Debt-trap_diplomacy)
Countries wary of falling captive to Chinese lending schemes are looking for other ways to spur economic growth. Taking a page out of India's playbook seems to be a wise move for African countries. Copying the Indian model involves building a healthy startup ecosystem and promoting organic growth that can African ingenuity and creativity. African governments, too, have finally woken up to the bottom-up growth startups can engender.
## **The no-code way**
No-code tools can play a special role in transforming Africa into the new tech frontier. There are two factors that make no-code a great match for the African startup ecosystem:
### **Technology: Starting with a blank canvas**
Africa was regarded as a technological backwater for decades. However, the fact that Africa is an uncharted territory for conventional technologies might be a blessing in disguise. The continent achieved impressive levels of mobile phone coverage and penetration without having a landline network to speak of. The proportion of households having a landline in countries like [Senegal, South Africa, Kenya, and Tanzania](https://www.pewresearch.org/global/2015/04/15/cell-phones-in-africa-communication-lifeline/) never surpassed a few percentage points. The countries completely skipped the landline stage and leaped to the digital era.
The same is true for the internet infrastructure. Today, African service providers don't have to concern themselves with fixing or maintaining copper wire internet infrastructure, as there was very little of that to begin with. They can start with fiber optics right away.
Likewise, African startups can take advantage of a level playing field and turn their solutions into mainstream business models. African fintech companies show us how. While European fintech companies live solely on transaction fees and struggle to survive against traditional banks, [African fintech companies](https://www.youtube.com/watch?v=DDD4ZRdMGpI) are generating multiple revenue streams and creating a whole new industry on their own without having to worry about established players.
In such an environment, no-code can offer tremendous advantages to its practitioners. No-code technology makes it easier for entrepreneurs to test ideas and significantly reduces the time-to-market. This capability makes a huge difference in a "blue ocean" market like Africa, where the first mover can create a category, condition the customers, and reap the benefits for years to come.
### **Demographics: A match made in heaven**
The population boom mentioned above translates into a new generation of African entrepreneurs. These people are digital natives. They are tech-savvy people determined to transcend local boundaries and engage with their peers in the rest of the world. This new breed of African entrepreneurs can use no-code tools to acquire a set of skills that they would otherwise have to acquire through traditional means like education.
No-code technology has the potential to become a big part of education in Africa. No-code education in Africa can turn millions of tech-savvy Africans into freelancers and introduce them to the global job market. Western tech companies would love such a development as they are faced with increased developer salaries and are always looking to cut costs. With the help of no-code tools, Africa can become another market Western companies can outsource services from. Africa's journey to becoming a software development hub like India can start with the no-code movement.
Aware of the potential no-code has for African people, tech education platforms are including no-code education in their portfolios. For example, Kabakoo, a leading tech education platform in Africa, partnered with Contournement, the European leader in no-code education, to hold [the first no-code training initiative in West Africa](https://aithority.com/technology/education-and-research/kabakoo-academies-edtech-leader-and-pioneer-of-no-code-training-in-africa/) in 2021. It is safe to assume that the next generation of tech founders and freelancers in Africa will leverage no-code tools to realize their dreams.
[Check DC](https://www.youtube.com/watch?v=f45YYKuHDPc), a design agency based in Lagos, Nigeria, successfully implemented a strategy based on no-code tools to put itself on the map. The company won web design contracts, used no-code web design platforms like Webflow to complete projects, and made a name for itself. In the time it takes for the African education system to train the developer talent the continent needs, no-code can help companies like Check DC to plug skills gaps and generate significant levels of revenue.
## **Conclusion**
Africa taking its rightful place in the forefront of technology is not a matter of if but when. With the insatiable demand for developer talent in the West and African youth entering the workforce, the stars are finally aligning for the continent. No-code technology will be a significant part of the puzzle here, helping bridge the gap between the Africa of today and the Africa of the future.
--- START: blog/no-code-agility-marketing/no-code-agility-marketing.md ---
# **No-code Brings Agility to Marketing**
Do you also feel like the pace of life is picking up? Like you are having more and more trouble keeping up? Like the tricks that had served you so well at work or in your daily life for years no longer seem to work, forcing you to change? That’s because the pace of life is really picking up. The sheer amount of information we have to process and the number of decisions we have to make have increased by orders of magnitude compared to a few decades ago. The speed of communication has multiplied the amount of information we have at our fingertips at any given moment. This meant that we would either change the way we work or risk falling behind.
Marketing, too, had to adapt. The old ways of long-drawn-out marketing campaigns, linear funnels and one-way message delivery no longer work because the customer today is [more connected and better informed](https://chiefmartec.com/2013/03/agile-marketing-for-a-world-of-constant-change/) than ever. He is no longer the passive object getting bombarded by messages; he interacts with the marketer, takes short cuts in the funnel and poses more of a challenge for anybody willing to impress him.
The social media revolution completely changed the marketing landscape: It put the marketer in direct contact with the customer and rendered the impact of a marketing campaign much more visible and measurable. Having become the contact patch between the marketer and customer, social media has produced an incredible amount of data that could inform future decisions, only if you could gather and correctly interpret it. The new situation in a way forced marketing to get inspiration from the “agile” philosophy. Instead of sticking to a plan until everything falls apart, the new game plan requires marketing people to make constant adjustments in light of the data collected.
The agile mindset is best summarized by Eric Ries in his book [*The Lean Startup: How Today’s Entrepreneurs Use Continuous Innovation to Create Radically Successful Businesses*](http://www.amazon.com/Lean-Startup-Entrepreneurs-Continuous-Innovation/dp/0307887898). In the book, Ries introduces the “Build-Measure-Learn” feedback loop idea, which truly embodies the agile mindset (Ries, 2011). According to this model, once ideas are turned into products and offered to customers, customer reactions have to be quantified and necessary lessons need to be taken to either stay the course or pivot. The *Learn* part here actually stands for *validated learning*, an empirical technique used to find out what the customer truly wants (Ries, 2011). It replaces the guesswork or gut feeling with hard data drawn from a series of experiments. In order to make validated learning the basis of progress at your firm, you need to formulate your ideas as hypotheses and run a series of small experiments to test them. As Scott Brinker, the marketing guru from HubSpot, [succinctly puts](https://chiefmartec.com/2013/03/agile-marketing-for-a-world-of-constant-change/), there should be many small experiments instead of rolling the dice on a few large bets.
The need for validated learning is what makes the no-code technology the premium tool in a marketer’s toolbox. No-code platforms reduce the time needed to develop software and shorten the iteration cycles, making it possible for people to tend to [underserved tasks](https://martech.org/no-code-tools-are-transforming-marketers-into-makers/) that were previously neglected— because they did not justify the time developers would spend on them or the investment management would have to make. Do you want to test two different color schemes for your landing page? Do you need to run an A/B test to learn which one of the two features you are planning to ship will be received better by your customers? Are you in need of a CRM tool but working under a management unwilling to commit significant resources before making sure that it will work? A marketer with a no-code tool will be empowered to take care of such tasks instead of waiting for assistance from the IT or allocation of resources by the top management. Giving employees autonomy, achieving a flatter organizational structure and a faster response time have become the holy grail today, but these do not happen on their own: No-code technology makes it possible for the employees to form hypotheses, validate them and make informed decisions based on these experiments, in the meanwhile bringing about significant gains in time-to-value and time-to-market.
If you are a marketing professional, you are probably witnessing the pace of change in your industry more closely than anybody in your organization does. It takes a different kind of organization to succeed in the age we live in: Vigilant, nimble, conscious of the change it needs to master. Does yours have what it takes? If you are not sure, do not fret—there is no-code for you.
--- START: blog/no-code-api-deployment/no-code-api-deployment.md ---
# **No-code and APIs to Redefine Software Customization**
APIs are making the world go round nowadays. They are changing the way manufacturing is done at the enterprise level, and thus making Industry 4.0 possible. The previous phase in manufacturing, Industry 3.0, was limited by the [need for constant human presence](https://www.youtube.com/watch?v=WYXzJoewGLw) on the site or nearby to do controls and monitoring during the production process. Not only that, but it was also a closed-off proprietary system that didn’t accommodate third-party integrations. APIs have revolutionized manufacturing by [enabling remote command and control](https://nordicapis.com/how-apis-are-powering-the-next-industrial-revolution/), which facilitates a distributed, global manufacturing network. It is through the APIs that orders can be automatically diverted from a plant in a particular country to another plant overseas, improving logistics and bringing down costs, and running an around-the-clock global operation. APIs also enable monitoring and reporting and give decision-makers unique visibility into processes so that they can be improved.
Giant manufacturing plants are not the only places where APIs are making a difference. The tasks for which people depend on APIs are almost endless today: Developers count on APIs [to import ready-made capabilities](https://library.mulesoft.com/api-programs/wp-api-strategy-essentials) without spending days to code a similar capability from scratch. Businesses rely on APIs to extend functionality and perform security functions. Decision-makers in companies leverage APIs to gain a deeper understanding of the processes so that they can make data-informed decisions. All in all, APIs help users automate existing processes, expand their businesses into new segments, expedite innovation and facilitate collaboration among different users.
This whole activity going on around APIs has created an API-based economy. Whenever an organization opens up its systems, processes, or data to external use through APIs, it [creates value and potential revenue streams](https://dzone.com/articles/what-is-the-api-economy-amp-why-it-matters-to-your) for itself and its partners. The shared value becomes the basis for an ecosystem that grows as more business capabilities are shared through APIs. In such an environment, companies can capitalize on their strengths, things that they do exceptionally well, and monetize them by opening up those skills to be consumed by customers who need similar capabilities. Monetization of APIs requires a product-centric approach, though. Every internal service offering should be developed with a view to open them up to external use one day. It was this mindset that made API-based innovative thinking a significant component of the culture at companies like Salesforce and Amazon and drove their impressive growth over the years.
However, the most significant benefit APIs offer is that they let you take customization out of your system and migrate it over to the customer-side. Customizing a software product for numerous different use cases is easier said than done. The product gains a life of its own once it is launched. That’s why it is impossible for a product owner to foresee how it will be put to use and in what ways it will be complemented. After opening your product up to others to modify and integrate to their own systems, it no longer is your duty to come up with innovative ways to complement and extend your product—the market takes care of it for you as people “hack” your product to meet their needs. The more capable your API is, the easier for others to tailor your product to their own needs.
Amazon wrote the book on API-based customizability. Around the year 2002, Jeff Bezos [enforced](https://library.mulesoft.com/api-programs/wp-api-strategy-essentials) that all business functionality within Amazon would be designed as reusable services and exposed over APIs to outside users. This decision single-handedly prevented the calcification of the company as a monolith and ensured that no business capability would be offered internally or externally unless it could be opened up through APIs. The ecosystem that gradually developed around Amazon resulted from this strategic decision Bezos made.
No-code platforms, too, have been involved in the API landscape for quite some time, effecting meaningful change. Tools like Zapier have taken over API orchestration duties, which previously were done by developers. No-code technology now looks poised to take customization to another level as well. In the near future, the company publishing an API will be offering the end-users [no-code templates](/blog/no-code-templates-competitive-edge/) to customize the product without having to do any customization on its own platform. This will let companies focus on their core line of work and leave customization to the end-users as they know better than anyone the daily problems and needs in their operations. APIs and no-code will be natural allies in the quest to take software to the masses.
--- START: blog/no-code-apps-to-build/no-code-apps-to-build.md ---
# **4 No-code Apps that You Can Build on Peaka**
In previous posts, we covered why [no-code](/) platforms [have gained popularity](/blog/why-is-no-code-becoming-in-all-of-a-sudden/) recently and gave our readers the lay of the land in the [low-code/no-code world](/blog/low-code-vs-no-code/), describing where Peaka fits in. This is all fine and dandy, but what exactly does Peaka do for your business? What can you—as a startup founder or an SMB owner—expect from Peaka? Here are four possibilities:
## **Full-fledged e-commerce business**
We are currently in the fifteenth month of the global pandemic, and the effect it has had on the economy is almost palpable. Lockdowns have added to the challenges of startups and altered the way established SMBs conduct business. However, one segment of the economy kept thriving during the pandemic: [E-commerce](https://www.salesforce.com/products/commerce-cloud/resources/what-is-ecommerce/)—it practically made the world go round.
The Peaka team is aware of the challenges the pandemic brought about, and we equip you with the tools you need to take on those challenges. If you have decided to take your business online, you can start by building your pages by dragging and dropping the components on Peaka. First, start with creating necessary lists and tables. Then, generate forms where user inputs are needed. You can also create data models with a few clicks from the forms you just generated. Once you are done, install the necessary plug-ins such as User Management, Payments (PayPal, Stripe) from the App Settings. Click the Preview, and you are good to go.
## **Order Management System**
As your business grows, so does the number of your supply and delivery channels. The way you manage these channels will
make or break your business, deciding whether you will be able to scale or hit a wall. Using different interfaces and
authorization processes for each channel [creates unnecessary clutter and puts strain on your personnel.](https://www.bigcommerce.com/blog/order-management/#key-features-of-effective-order-management)
Consolidating different interfaces in one user-friendly environment on Peaka will reduce the time and effort needed to
track supplies and fulfill orders while minimizing the potential for human error.
## **Sales Management System**
Standardized sales processes help increase productivity and revenue, facilitate the training of personnel and improve
accountability across the sales department. CRM tools help companies [standardize their processes](https://www.yokellocal.com/blog/how-does-a-crm-improve-the-sales-process),
from generating leads to closing deals to customer service. Peaka allows you to design and build a Sales CRM tool that you can use to track and measure the performance of your sales team, and centralize information flowing in from different channels and salespeople.
## **Customer Support System**
Customer support can put a lot of pressure on a small firm with limited resources, but it is an integral step in building
a lasting bond with the customer base. Also, the price of coming up short on this front can be disproportionately dear,
so you would be well-advised to take it seriously. Automating major transaction messages such as [order confirmations,
receipts, and various notifications](https://www.groovehq.com/blog/ecommerce-customer-service) can save your team a lot
of time and energy. Building an app to manage support tickets and provide customers with continuous support through
channels of their choice (social media, email, live chat, etc.) is one of the best investments a small firm can make.
The possibilities are almost endless with Peaka. Whether it is a responsive landing page design or an app involving a
complex web of integrations with a third-party system, it offers a wide range of abilities and a lot of flexibility.
Just define your needs, design your solution, build the tool you need and let Peaka transform your business.
--- START: blog/no-code-benefits-life/no-code-benefits-life.md ---
# **No-Code as a Force for Good (1): Turning around Lives**
Attributing lofty missions to emerging technologies is nothing new. We have all come across novel ideas that are
supposed to transform this or revolutionize that. [No-code](/) platforms on their part have been associated with
democratizing the app development and the software industry in general. For instance, the San Fransisco-based no-code
platform [Airtable](https://airtable.com/about) has adopted democratization of software creation as its mission, but
what does democratization involve and how can no-code platforms achieve that?
Here is what [Gartner](https://www.gartner.com/en/newsroom/press-releases/2019-10-21-gartner-identifies-the-top-10-strategic-technology-trends-for-2020)
has to say on this trend:
> “Democratization is focused on providing people with access to technical expertise (for example, ML, application
> development) or business domain expertise (for example, sales process, economic analysis) via a radically simplified
> experience and without requiring extensive and costly training.”
In short, democratization involves rendering technical expertise accessible to masses in a simple and efficient way.
If there will ever be a development in the tech industry worthy of the epithet “revolution,” expanding the reach of
software and letting people become app developers on their own right could be it. This approach could benefit
underprivileged individuals all over the world.
## **Social mobility: The age-old chicken-egg problem**
What is undemocratic about modern society mostly stems from the level of people’s access to educational resources. Once
we understand what needs to be fixed, we can also understand how the transformative power of no-code can be of help.
Education is a powerful engine of social mobility and one of the most effective tools to contain and reverse the effects
of poverty. However, we have a chicken-egg problem here. Our chances of getting a good education are highly predicated
on wealth and good education creates more wealth in return. For example, [almost 75% of the children of
university-educated parents in the UK received university degrees, as opposed to just 20% of children from low-income
families.](https://www.bbc.com/news/education-44489556) The situation doesn’t seem to have got any better in the last
half century: An [OECD report](https://www.oecd.org/social/broken-elevator-how-to-promote-social-mobility-9789264301085-en.htm)
published in 2018 found out that people born between 1955 and 1975 enjoyed high social mobility while later generations
were not that fortunate, facing stagnant social mobility, which meant improving the quality of life was harder. Lower
upward social mobility feeds higher income inequality. To the contrary, better education translates into higher salaries
and a longer life expectation in OECD countries. Here is another striking and painful stat: The statistical model
employed in the report predicts that it would take 9 to 11 generations for children of low-income families in Brasil,
South Africa and Colombia to reach the mean income in their respective societies. That is almost three centuries. 300
years, just to reach the average income. It doesn’t have to be that way.
## **Educational _equity_ instead of _equality_**
This is where the concept of [educational equity](https://www.nsba.org/-/media/NSBA/File/cpe-educational-equity-research-brief-january-2016.pdf)
comes in. Unlike equality, which implies that everybody should have equal access to educational resources, educational
equity focuses on equipping disadvantaged people with the tools to neutralize those disadvantages. It emphasizes the
result, which is the net increase in quality of life, as opposed to equality, which focuses on the process itself. Not
everybody will be able to attend Oxbridge or an Ivy League school, but people can be taught the skills needed to get
them over the hump and improve their lifetime earnings potential. App building is one such skill and with no-code
platforms lowering the entry barrier, it has become easier than ever.
## **What no-code platforms can fix for the society**
In a world where there is insatiable appetite for software but not enough developers, no-code platforms can play a role
in turning people with no coding background into app developers. Online courses offered by [Makerpad](https://www.makerpad.co/),
[Appswithoutcode](https://www.appswithoutcode.com/) or [No Code MBA](https://www.nocode.mba/) give people a chance to
acquire new skills, further their current careers or make the switch to completely new ones. In fact, it is not
far-fetched to think that [government-sponsored bootcamps](https://bubble.io/blog/uk-no-code-bubble/) will soon become
quite common at a time when governments are looking for ways to stem rising youth unemployment rates. Additionally,
no-code platforms could have a significant impact on the lives of developers in developing countries with degrees from
middle of the pack schools. These people tend to be underemployed, unable to benefit from the increasing wages in the
software industry and settle for much less due to linguistic, geographic or personal reasons. On the other hand, there
are people out there who are in need of apps for their businesses but either are not aware of no-code or just
intimidated by tech stuff. No-code platforms like Peaka can bring these two groups of people together. This arrangement
can help developers monetize their skills in a way they could not before and solve problems for startups and SMBs that
cannot afford elite developer talent.
When we launched Peaka, we envisioned that it would become more than a no-code platform. Peaka aims to give strength to
the ongoing bottom-up change in the software industry, empowering regular people and bringing them onboard. We believe
that this will open up new horizons for people and help turn around lives. There is infinite demand for software out
there and a place-big or small-for anyone willing to take part in. All some people need is a helping hand. We hope
that Peaka will be just that.
--- START: blog/no-code-benefits-work/no-code-benefits-work.md ---
# **No-Code as a Force for Good (2): Changing the Work Life**
Our previous blog post was about how [no-code](/) movement had the potential to democratize software development and change
the lives of underprivileged individuals. That’s not all there is to it, though. The democratization of software
development through low-code/no-code platforms will have two other major impacts on the business world: i) Changing the
organizational culture in enterprises that are going through a digital transformation and ii) mitigating the effects of
a very tight job market that makes it difficult for startups and SMBs to attract talented developers. Let’s first start
with what is new with the enterprises.
## **What is digital transformation?**
Digital transformation [refers](https://www.techrepublic.com/article/digital-transformation-a-cheat-sheet/) to making
processes more efficient and effective through the use of technology. It is a catch phrase, most of the time used in the
context of enterprises, and involves taking advantage of technologies such as machine learning, AI, data analytics or
cloud computing. It is a way of leveraging technology to better understand customer demand and modify products and
processes in a way that satisfies that demand. Digital transformation entails more than just implementing certain
technologies, though; it is about [building business capabilities](https://www2.deloitte.com/us/en/insights/focus/digital-maturity/digital-maturity-pivot-model.html)
that render a company more agile and responsive to the changes taking place in its environment. In this day and age,
achieving agility and responsiveness in an organization requires turning employees into decision makers and innovators
at their jobs. This is what triggers the change in the corporate culture.
## **Digital transformation and the accompanying change in corporate culture**
Low-code tools might be more suited to the needs of an enterprise compared to no-code tools, but the latter is also
making some headway in the enterprise domain at the individual employee level. In an enterprise where thousands of
processes run in parallel or in sequence, low-code/no-code tools can be used to automate repetitive tasks and ease the
burden on the employees. While digital transformation efforts led by IT department feature low-code platforms, no-code
platforms are used to empower employees so that they can diagnose the problems they encounter and devise tools to tackle
them. Delegating authority from a central IT department to the frontline employees in this manner ties in well with the
democratizing philosophy behind the low-code/no-code tools. In this scenario, the IT department leaves aside its
hands-on approach and assumes more of a coordinating role: It sets guardrails, ensures visibility so that confidential
data does not get exposed to outsiders, and prevents shadow IT that might stem from individuals developing apps on their
own. The result is a workplace where people feel a stronger sense of belonging and are more motivated to contribute.
## **Startups and SMBs: The recruitment challenge**
The no-code tools have a role to play in leveling the playing field for startups and SMBs that do not have the means to
hire elite developer talent, and thus risk falling behind against their competitors. In order to understand what
low-code/no-code tools bring to the table, we should first have a look at where the current labor market stands. As of
2021, [the average salary of a software engineer in the U.S. is $110,000.](http://www.daxx.com/blog/development-trends/it-salaries-software-developer-trends/)
For senior developers, this figure can easily rise above $200,000. The average salary of a software developer is bound
to go up as the number of students graduating every year from departments like computer science is [significantly lower than the number of open tech positions.](https://goremotely.net/blog/how-many-software-engineers-are-there/)
The labor market is so tight and the developers have such a strong hand that companies have to throw in perks such as
[remote working possibility, six-figure signing bonuses and attractive equity grants](https://www.wsj.com/articles/americas-got-talent-just-not-enough-in-it-11571168626?mod=hp_featst_pos1)
to sweeten the pot and lure top talent. It is impossible for startups and SMBs to offer prospective employees comparable
terms and this ends up ruling them out of the recruiting game. These companies can rely on no-code platforms to remain
competitive. At a couple of hundred dollars per month, they can design and build the no-code tools they need without any
professional help from a developer, streamline processes and unlock efficiencies they did not know existed before.
Similar to how it opens up new possibilities for underprivileged individuals, Peaka has a vision to both democratize the
workplace for corporate employees and arm the startups and SMBs with the tools that can make them more competitive. With
its visual design capability, Peaka caters to the needs of users with no coding knowledge. It is here to render app
development - for long thought to be preserve of professionals - achievable for rank-and-file as well.
--- START: blog/no-code-commoditization-of-software/no-code-commoditization-of-software.md ---
# **No-code Accelerating the Commoditization of Software**
Very few people knew what a computer was in the mid-twentieth century. Only few among the baby-boomer generation would have been lucky enough to see a mainframe computer when they were kids if their parents were working at some of the institutions that housed one of those computers. For the next generation, a few desktop PCs in the office became a common sight. Then PCs made their way into our homes, and now into our pockets. What made computer technology accessible to the general public was a process called *commoditization*.
The computer hardware technology was transformed by commoditization, but it turns out that the software side of things was not immune, either. We’ll have a look at the role no-code is playing in that process, but, first of all…
## 1 - What is a commodity?
A [commodity](https://en.wikipedia.org/wiki/Commodity) is a good or resource whose specimens are treated as equivalent regardless of who produces them. Basic agricultural products like wheat and rice, mining products like gold and silver and oil are widely traded commodities with globally set prices and futures markets. There might be differences among the varieties of a commodity, but these varieties, too, are well-defined to the point of having their respective global prices and markets.
In the case of products, a commodity [refers to](https://openviewpartners.com/blog/how-saas-companies-can-compete-under-commoditization/#.YQT7VC3OlmA) the point where seller’s value proposition perfectly matches the expectation of the buyer. The product definition is clear and different products can substitute for each other. The success of a particular product in the market can accelerate commoditization by setting an industry standard and offering a blueprint for innovation that others can use to build similar products.
## 2 - EVs and autonomous driving: Full-throttle commoditization
The automotive industry’s recent trajectory illustrates the point. In light of the latest developments, it is safe to say that cars are on course to becoming a commodity soon. For over a century, cars had been something like artistic objects, highly customizable and built on different chassis types suitable for different use cases, offering varying levels of luxury and wildly different interpretations of the internal combustion engine. The introduction of electric vehicles dealt the first blow to the car as we knew it: Gone were the engine sound and characteristic torque curve of the internal combustion engine—driving experience in different EVs are eerily similar to each other regardless of their price points. The fact that electric engine and battery technology are so well-understood made it possible for Tesla to become an automotive giant in a decade and Rimac, a Croatian upstart, to challenge century-old companies in the high-end sports car segment. The second blow to the idea of car-as-an-artistic-object will come from autonomous driving, it seems. With the advent of Level 5 autonomous driving technology, a car will become nothing more than an appliance used for a single job-to-be-done: Transportation. At that point, the differentiation in the automotive industry that has turned people into fans of certain brands and petrolheads will be no more.
## 3 - Commoditization in the software industry: Modest beginnings, major implications
It might be argued that certain segments of the software industry experienced a similar process of commoditization a long time ago. MS Excel, which immensely expanded the reach of spreadsheet programs, was one of the pioneers of this trend, making the power of software accessible to masses without the need for extensive training (defined by Gartner as “[citizen access](https://www.gartner.com/en/newsroom/press-releases/2019-10-21-gartner-identifies-the-top-10-strategic-technology-trends-for-2020)”). What started as democratization of software in the case of MS Excel became commoditization, thanks to its incredible success whereby it has become *the* spreadsheet program in the minds of people.
Commoditization naturally [opens up](https://openviewpartners.com/blog/is-your-saas-business-being-commoditized/#.YQV7-i3OlmA) the lower end of the market to newcomers, brings about a decrease in prices and erodes profits. In that regard, it can be seen as the curse of success: The product achieves such a high level of success and gains such widespread acceptance that it becomes an industry standard and comes to stand for something bigger than itself while losing much of its revenue stream in the process due to increased competition. The market segment that MS Excel helped establish is now crowded with a plethora of free online spreadsheet applications like Google Sheets, a fact that has rendered a once successful business model no longer viable.
## 4 - Two trends shaping the present and future
The rise of AI is will definitely change the way society, economy and military operates, triggering outcomes that might be too broad for us to fully comprehend right now. However, one thing is certain: AI-based software will transform the software industry, accelerating the commoditization of software in the meantime. Programming assistants training themselves on the open-source material available on the internet have for some time been assisting coders as they write code, a development which already spurs debates on who owns the AI-generated code. AI will also change the way software is [updated and released](https://venturebeat.com/2021/08/23/how-ai-will-reshape-software-development/). Guess which option people will pick when they are faced with either having to pay software companies big bucks to update software or going with AI-supplied updates.
The other trend fueling the commoditization of software will be the widespread adoption of no-code technology. Following in the footsteps of MS Excel, no-code technology will expand the accessibility of software to masses. It is already pushing the boundaries of what a user coming from a non-technical background can do with software on his own, making it possible for him to complete tasks with ever higher levels of complexity. As no-code platforms become more capable, people will be able to create apps for tasks which previously could only be handled by expensive software. The growth of the no-code market particularly in the enterprise segment attests to that. There will definitely be niches remaining in the software realm inaccessible to the general public. However, there will come a time when masses will have mastered software to such an extent that calling it a commodity will be justified.
[Peaka](/) is the outcome of a vision to expand the domain of software and make it accessible to people who never knew they needed it. Just like MS Excel eased the work load of office people dealing with the chores of daily work years ago, we believe there is much that no-code can do to make life easier for people who are not familiar with coding. No-code technology will be more than enough for tasks people outside the technology sector could reasonably be expected to face in their lives.
--- START: blog/no-code-do-not-rewrite-but-renovate/no-code-do-not-rewrite-but-renovate.md ---
# **Rewrite or Renovate? No-code Revitalizes Old Projects**
It is a dreadful moment for a development team when the CTO says “we should rewrite the whole thing from scratch.” It is both a declaration that the current problems are bigger than you think they are and that the Pandora’s box is about to be opened, with its ensuing uncertainties. Despite often being sugarcoated as “taking a step back to leap forward,” rewriting a project rarely goes so smoothly. It is why people like [Michael Fowler](https://martinfowler.com/aboutMe.html) and [Joel Spolsky](https://www.joelonsoftware.com/about-me/) are against rewriting code, with the latter even calling it the “[single worst strategic mistake](https://www.zabanga.us/marketing-disasters/an-interview-with-joel-spolsky.html) that any software company can make.”
The case against rewriting software is strong: First of all, it requires you to throw away the old code, with all the solutions it brought to problems. What you are throwing away in fact is, despite its shortcomings, a tried and tested solution, and a body of accumulated knowledge. Secondly, rewriting the code does not guarantee that the new one will be better. As Joel Spolsky [argues](https://www.joelonsoftware.com/2000/04/06/things-you-should-never-do-part-i/), you won’t necessarily have more experience under your belt when you attack the same problem with a different team. To the contrary, you will most probably run into similar problems and the code will get messy once again, but this time your new team will be working on [two projects](https://www.method.com/insights/when-to-do-a-software-rewrite/) at the same time. Thirdly, by throwing away code and starting over from scratch, you will be endangering the viability of your business if it is running on the old code. No matter how hard you and your team work, your new system will never be able to catch up with the requirements of the ongoing business, which means that you are giving up your old way of making money and won’t be able to introduce a new one for a long while. That has the potential to scuttle any business model.
For a complete rewrite to be considered feasible, starting over should [cost less](https://jessewright-31185.medium.com/when-to-do-a-software-rewrite-277d93bb7cc8) than just modifying the existing code, which is not the case most of the time. Michael Fowler uses the now-famous [strangler fig](https://martinfowler.com/bliki/StranglerFigApplication.html) metaphor to offer another way: “… [T]o gradually create a new system around the edges of the old, letting it grow slowly over several years until the old system is strangled.” This approach helps mitigate the business risk and ensures that the system will keep delivering value and avoid the [notorious mistake Netscape made](https://medium.com/@herbcaudill/lessons-from-6-software-rewrite-stories-635e4c8f7c22) by deciding to scrap the old structure and rewrite the code, which ended up putting them out of business.
Sometimes a wholesale rewriting of the code is not necessary. The current technology might still be considered acceptable so it might stay. Some improvement in user experience might be all that is needed. This is exactly where no-code shines. If you already have a solid data model in place, no-code lets you easily build apps on that data model. Making changes to the user interface, removing friction or offering a mobile version or responsive screens are a walk in the park with no-code. This allows you to keep your solutions to past problems without disrupting the operation of your business.
No-code allows developers to make incremental, targeted changes to the existing code structure. This approach maximizes the impact while affording developers the safety net of an already working solution. Continuing to reap the benefits of the old structure, into which a lot of time and money had been invested, and improving just the parts that need to be improved—this will be the no-code way of software renovation.
--- START: blog/no-code-ends-maintenance-drama/no-code-ends-maintenance-drama.md ---
# **No-code to Put an End to the Software Maintenance Drama**
The software industry has peculiar dynamics. It differs from the traditional sectors of the economy with its culture, high turnover rate and dizzying speed of technological change. Another huge difference between the software industry and other traditional sectors of the economy involves the product development process. In the manufacturing sector, the product development process is over once the product hits the market: Following the launch of a new model of car or home appliance, the design and development teams can focus on another project, having only to revisit the earlier project to assess customer feedback and work on a facelift model. In the software industry, however, the launch of a product is only the start of a more dynamic process in the [Software Development Life Cycle](https://en.wikipedia.org/wiki/Systems_development_life_cycle) (SDLC).
Maintenance is the biggest part within the SDLC because, according to [Meir M. Lehman](https://en.wikipedia.org/wiki/Meir_M._Lehman), the scholar who canonized the laws of software evolution, [maintenance](https://en.wikipedia.org/wiki/Software_maintenance) is nothing but evolutionary development. In other words, it is not a particular stage that kicks in at some point in the product’s life cycle, but rather the whole development the product goes through after its launch. If the pre-launch development is the tip of the iceberg, maintenance is the huge mass of ice submerged in water.
Software maintenance is not only the biggest but also the most costly stage of the SDLC. Maintenance costs have been rising steadily over decades. Their share in the total cost of ownership (TCO) can be as high as [60 percent](https://www.baytechconsulting.com/blog/projecting-costs-in-software-maintenance) and there are studies showing that maintenance costs make up around [90 percent](https://www.researchgate.net/publication/236189469_Which_Factors_Affect_Software_Projects_Maintenance_Cost_More) of total cost of software development cycle. In the case of an app, maintenance costs may account for [70 percent](https://www.econnectivity.se/app-maintenance-cost-can-be-three-times-higher-than-development-cost/) of TCO during the life of the app.
Not all maintenance is routine and pre-planned, either. Once a software product is introduced to the market, it gains a life of its own. The customer demand and feedback given cause significant shifts in the post-launch product roadmap. As a product owner, you might find out that people have hacked your product and started using it in ways that you never imagined were possible, creating a series of bugs you did not expect at all. The dynamic competitive environment might also require your company to prioritize things that were not in the plans before.
Maintenance can be a nightmare for anybody developing or owning a software product. Here, no-code technology offers significant advantages. The fact that no-code platforms make possible up to 10 times faster software development translates into much lower maintenance expenses because this allows for more efficient use of developers’ time. Developers tend to command pretty high salaries, therefore better employment of their talents unlocks efficiencies for a company. In conventional software development, even simple changes requested by customers has to be carried out by the development team. But no-code changes that, too. No-code platforms empower support people outside the developer community to take care of routine maintenance tasks, driving down costs considerably. Faster software development on no-code platforms also expedites time-to-market and time-to-value, giving a company advantage over its competition.
That’s one of the reasons we at [Peaka](/) think that it is not a good idea to export code out of a no-code platform and revert to conventional software development after the MVP stage—that is almost akin to quitting your weight loss program after losing a few pounds and going back to old habits. The MVP stage in the SDLC corresponds to something like the fifth lap in a 60-lap race in Formula 1—definitely not the right time to abort a strategy that has served you well. Maintenance makes up most of the post-MVP stage of a product and hides within it significant costs. Migrating your product from no-code to conventional coding after the MVP stage will deny you the true long-term benefits of no-code technology. Why be content with just having saved time and money while developing your MVP when you can keep reaping the benefits for years to come?
--- START: blog/no-code-fast-track-product-development/no-code-fast-track-product-development.md ---
# **No-code Helps Fast-track Product Development**
Time is money if you are running a SaaS business. You most probably lack the necessary funds to build your ideal development team and product, so you need to prioritize and make trade-offs on the one hand, while trying to manage the cash burn, on the other, as your runway becomes shorter. Odds are that the first version of your product won’t be a success. Then the right thing to do is to expedite failure, instead of delaying it, and start learning from the mistakes as soon as possible. But how do you achieve that? Is there a way to fast-track product development? Let’s take a look at the levers entrepreneurs can pull to increase the velocity of product development.
## **1 - Team composition**
The composition of your product team depends on which stage your company is in. At the beginning, the roles in a startup will not be clear-cut due to lack of funds, and it will be a never-ending race to put out fires: Your CEO will be sending out emails, joining the daily product meeting and writing a blog post all in the same day, while your product manager holds demos and wrestles with usage analytics. The other factors bearing on your product team structure is the kind of product you are building and the market segment you are addressing.
Among the roles a product development team in a SaaS startup is expected to have, four need to be emphasized:
**Domain expert:** If you are fortunate enough, one of your co-founders will be able to undertake this role. It will be a huge plus if the people setting the vision of a company also know the potential customer base and their needs. However, it may be that the company is venturing into an entirely different industry which no one on the team knows enough about. Then it would serve the company well to bring in [some expert opinion to learn about the pain points](https://medium.com/swlh/design-to-delight-raising-the-bar-on-software-design-a1eec234188b) and jobs-to-be-done that will be addressed.
**Product manager:** He is the coach who ensures that everybody in the organization is aligned to the common goal of developing the right product. Product manager’s authority does not stem from his title but from his role as a leader—his position is an ephemeral one, limited in time and scope. He is [responsible of](https://www.atlassian.com/agile/product-management/product-manager) putting employees in a position where they can make their own decisions and contribute to the company vision.
**UX designer:** UX designer is the one who fleshes out the conceptual idea with details and product feeling, showing everybody how the functional product operates and feels when complete. He lays out possible use cases for the product, [conducts A/B tests](https://blog.adobe.com/en/publish/2017/01/10/the-evolution-of-uiux-designers-into-product-designers.html#gs.9giqad) to faciitate validated decisions and communicates the visions using wireframes.
**Developer:** Developer is the guy who will tell the other members of the product team with a straight face “no, we can’t do that” when the limits of what is technically possible is being pushed.
## **2 - From ideation to prototypes: Wireframes and Rapid Prototyping**
Every product should be built to solve a problem identified by the product team. How the product will solve the problem is first presented in a wireframe format. A wireframe shows the [layout of a web page](https://www.experienceux.co.uk/faqs/what-is-wireframing/) in a low-fidelity fashion, without the bells and whistles of a corporate presentation. It is both a design and a communication tool. It is basically a flow diagram of how the company should create the value it will offer its customers. In addition to demonstrating how the UX designer plans to fill the gap between the idea (solution) and code (product), wireframes are good for seeking the approval of interested parties since they express the [functionality, features, content and user flow](https://www.youtube.com/watch?v=KnZrypOaVCg). Wireframes are cheap and easy to make. They are deliberately simple and austere in the way they look because the attention has to be on the proposed solution.
Another design tool used in product development is [Rapid Prototyping](https://betterprogramming.pub/the-5-ws-of-the-rapid-prototype-8e7614f82d29), which refers to a functional proof of concept that demonstrates the key value proposition of a product and simulates the user experience without the bloated feeling extra features would give. This is generally completed in a single sprint. Although different projects could justify Rapid Prototypes with different levels of fidelity, a Rapid Prototype has a higher level of fidelity than a wireframe. This leaves less room for imagination and increases the quality and relevance of the feedback received during a product meeting. Rapid Prototypes can be used to [simulate and test crucial use cases](https://devsquad.com/blog/what-is-rapid-prototyping-and-why-is-it-used-in-development/) in a fast and cost-effective way, limiting the business risk involved. A more realistic user experience increases the likelihood of stakeholder buy-in.
## **3 - Design**
The design phase in a SaaS product should focus on minimizing time-to-value: It should be all about expediting that “aha” moment when the user experiences the value proposition. Therefore, focusing on how best to deliver the core feature and delaying for some time the delivery of less sought-after features is the smart thing to do. Coined by the UX guru Jacob Nielsen as “progressive delivery,” this technique involves taking advantage of the SaaS infrastructure to ship features in an incremental fashion through continuous delivery (Todd Olson, The Product-led Organization, 2021).
While designing a SaaS product, designers should understand [who the end-user is](https://betterprogramming.pub/what-are-the-fundamentals-of-good-software-design-5eda80f5f32b) and try to speed up his journey to value. [Counting clicks and eliminating the unnecessary ones](https://medium.com/swlh/design-to-delight-raising-the-bar-on-software-design-a1eec234188b), automating certain steps and always looking for a simpler solution are keys to good product design. The solution should be easy to maintain and not increase complexity.
Luckily, designers today do not lack tools that can help accelerate their work. For prototyping, Figma has become something like an industry standard. It [bridges the gap](https://techcrunch.com/2020/10/27/animas-latest-update-draws-on-the-popularity-of-design-and-no-code-tools/) between designers and developers, and accelerates the design process. The fact that it makes collaboration possible is a further plus for the whole design process. Designers today have the chance to leverage new tools like the no-code platform Anima 4.0, which imports designs from Figma and turns them into HTML code.
## **4 - Coding**
Once your design is ready, you are faced with the difficult task of choosing a method to build your product out. The first option coming to mind would be conventional coding, which requires you to assemble a group of developers and start from scratch, writing the code all by yourselves. However, hard coding is not cheap. Actually, the total cost of product development is most likely not properly understood by even the people working in the software industry. Unless you are one of the co-founders and witness the drain in your bank account, it is hard to comprehend how fast a startup burns through its cash. Conventional coding is a time-consuming process and the associated costs can easily get out of control as the product team goes through the iterations, trying to perfect the product.
Then there is the maintenance issue, which comprises up to [two-thirds](https://www.baytechconsulting.com/blog/projecting-costs-in-software-maintenance) of the costs associated with software development. Trouble shooting and maintenance will take up human and financial resources for years to come, adding to the hurdles awaiting a startup.
No-code platforms offer a wholistic solution to the product development problem. From the prototyping stage onwards, no-code platforms unlock significant efficiencies and become a game changer for a startup. No-code tools reduce by up to 10 times the time required to build a proof of concept, a prototype or an MVP. Iterations between different versions of the product become much more dynamic without the need to commit any long-term resources. Time is money in product development; therefore, faster product development brings about considerable cost savings, too.
The immense visibility that no-code platforms bring into the development process allows the product team to make data-informed decisions at every step. No more shooting in the dark, no more wasting resources to build castles in the air—no-code technology turns product development into more of a science than before. For SaaS startups that are already time-pressed and cash-strapped, no-code is truly a godsend.
--- START: blog/no-code-for-fresh-start/no-code-for-fresh-start.md ---
# **No-code for Anyone Planning a Fresh Start**
Everybody is talking about coding these days. Coding is what some know-it-all types are offering as a panacea for every problem: Whether you were laid off from your job or are not happy with the general course of your life or failed in your attempt to build a startup, somebody comes out and urges you to learn to code. Coding apparently has become the “break glass in case of emergency” plan for people looking to shake up things in their lives. But why now? What is behind the recent surge in interest in coding?
There are two factors at play here—one of them, a decade-long transformation and the other, a more recent [*force majeure*](https://www.merriam-webster.com/dictionary/force%20majeure). The long-term factor is the fact that [software is eating the world](https://www.wsj.com/articles/SB10001424053111903480904576512250915629460) and people, even the most technophobic among them, are taking note. They understand that software is playing an ever bigger role in their lives. As a result, best paying jobs are often software-related (with a median income of 86,550 in the U.S. and $164,610 for the state of Washington) and developers are so distracted by constant job offers that they have to specify that [they are not looking for work](https://skillcrush.com/blog/laurence-bradford-10-reasons/).
The high salaries developers command not only make computer science one of the top choices among high school graduates but also attract people who contemplate a fresh start in their careers, thinking that their education led them into a dead-end. Graduates of liberal arts and social sciences are in this group. The value of a humanities and social sciences education is being questioned all over the world. Some governments are actively talking students into pursuing careers [more in line with the market demand](https://www.timeshighereducation.com/news/course-closures-inevitable-consequence-westminster-policy) and some universities are already closing programs such as [history and modern foreign languages](https://www.timeshighereducation.com/news/sunderland-and-soas-cuts-expose-market-dangers-say-scholars). Graduates of humanities see the writing on the wall. They are frantically investing in acquiring new skills that will make them relevant in the job market, which nowadays usually means taking up coding.
The second factor at play, the act of God driving the interest in coding, involves the global pandemic and how it changed the way people see the world around them. Governments and institutions are not the only ones second-guessing their previous decisions; one and a half years of pandemic, intermittent lockdowns and working from home have triggered in some people a feeling of “being stuck”. Being stuck in a life they have very little control over and no longer find satisfactory. There are more people than ever questioning their life choices, asking themselves “what if”s, followed by a series of “should have” and “could have” answers. Some of them think that coding will give them problem-solving skills that will help them perform better at their current jobs. For some, coding is the gateway to a better paying job or a remote working arrangement they noticed that they needed during the pandemic. It was this sort of questioning that has caused the recent spike in what was already a high level interest in coding.
Getting into coding is the way to go, but how? Attending online courses on platforms such as [Codecademy](https://www.codecademy.com/), [Coursera](https://www.coursera.org/) or [Udemy](https://www.udemy.com/) is an option. Another option is to join bootcamps, which serves the same goal and comes with the added benefit of networking opportunities. Some ambitious people are taking it to another level and going back to school to study computer science. In short, *where there is a will, there is a way*, as the saying goes. In a [recent tweet](https://twitter.com/paulg/status/1433725939071004704), Paul Graham basically advised his followers to follow their hearts in learning how to code and not worry about being perfect in all the aspects. That’s both a sound advice and a realistic take, since coding is not as easy as some bloggers make it out to be: It takes serious investment in terms of time and effort, and comes with significant opportunity cost, i.e. what you could be doing instead, in case you quit before you turn it into a skill you can depend on. In order to monetize that skill, you will have to have a great idea you can [implement and find a market for](https://jproco.medium.com/why-entrepreneurs-should-learn-to-no-code-instead-of-learn-to-code-1ae7efbe36af).
Moreover, knowing how to code or even being [a veteran of the industry](https://medium.com/writers-blokke/an-old-programmer-loses-his-job-caa4670f34dc) does not seem enough to shield people from the winds of change. Software industry is the most dynamic one that there is; the programming languages in vogue change from time to time and staying ahead of the curve is not easy. You might take online coding courses or even receive a college degree in computer science, but that won’t automatically bring you success as you will need to strive forever to keep yourself up-to-date. Learning to code, despite being one of the best decisions you can make, might be something of an overshoot taking your goals into account. Not only because learning to code takes serious investment and motivation but also because there is another way now.
For people willing to kick off their [startup](/blog/no-code-apps-to-build/) or try their hands in [freelancing](/blog/tips-for-freelancing-success/) or boost their problem-solving skills as [white collar workers](/blog/cultural-resistance-2/) in their existing line of work, no-code technology offers the best of both worlds. No-code puts an end to the predicament of choosing the right programming language. If the end goal is finding a solution to a problem rather than learning to code for its own sake, no-code tools make a lot of sense. They are perfect for people who want to be a part of the software industry despite not being a coder. No-code gives you a head start without the need to invest at least a few months worth of effort before you can start a project of your own.
No-code platforms offer the shortest route to the proof of concept and MVP stages for any idea. Additionally, premium no-code platforms like [Peaka](/) go beyond that and can take you all the way through to a fully-functional product. The capabilities they offer easily take care of hosting and security, which could otherwise be a thorn on your side. Then there is the beauty of being able to go back to coding whenever you want, this time focusing on the parts that will bring about the most payoff. No-code affords you the luxury of making coding your hobby rather than a challenge you have to overcome as soon as possible in order to make your life better.
--- START: blog/no-code-for-highschool/no-code-for-highschool.md ---
# **To Code or not to Code: What to Teach High Schoolers**
There is a certain correlation between the job market and the interest certain college programs attract. Of course,
these two are not totally in sync, with the 4-year delay stemming from the college education causing shortages or
oversupply of certain skills in the job market. Except for mainstays like medicine and law, most programs see their
popularity fluctuate in time depending on how the economy at large is faring.
Nowadays, fields such as computer science and software engineering are immensely popular, with parents hysterically
urging their kids to learn coding. A case in point could be the introductory Computer Science 50 course at Harvard,
which has become [one of the most popular courses, if not the most popular](https://www.thecrimson.com/article/2018/9/21/course-enrollment-fall-2018/),
offered, consistently attracting [10-12 percent of all students](https://www.thecrimson.com/article/2014/9/11/cs50-breaks-enrollment-records/)
for years.
## **Computer science courses in high schools: Yea or nay?**
This enthusiasm has brought about calls for high school curricula to include courses on coding. The proponents of the
idea, [like the Princeton professor Robert Sedgewick](https://www.wsj.com/articles/should-all-children-learn-to-code-by-the-end-of-high-school-11582513441),
argue that coding skills will be indispensable in the near future, just as reading and writing are now, and underscore
how learning to code can foster logical thinking and creativity in high school students. Those who are against the idea
have no problem with kids becoming logical thinkers, obviously, but they regard this “everybody-should-code” movement as
[something promoted by corporate giants for their own profit.](https://www.wsj.com/articles/should-all-children-learn-to-code-by-the-end-of-high-school-11582513441)
In their eyes, this is very much like the twentieth century campaigns to train students on industrial and agricultural skills
because that was what the times called for back then. The naysayers believe that modifying high school curricula
according to the wishes of corporate leaders could turn schools into vocational workshops, when they should be
focusing on culture and promoting social mobility.
Regardless of the ongoing debates, [33 states](https://www.k12dive.com/news/33-states-adopted-57-computer-science-ed-policies-since-2018/562530/)
in the U.S. have already moved to adopt policies requiring public high schools to have computer science courses in their
curricula. As of 2020, 47 percent of high schools in California already had realized that goal. [Alabama](https://codeorg.medium.com/32-states-expand-access-to-k-12-computer-science-education-in-2019-7d2357fe6f3d)
devised an ambitious plan, making it mandatory for every K-12 school to offer computer science courses by 2022-2023.
## **Is it possible?**
That U.S. is leading the way in teaching high school kids how to code shouldn’t surprise anyone, considering the wealth
of this country, and the ability of its high-tech industry to influence policymakers. [Scandinavian countries](https://www.telenor.com/wp-content/uploads/2019/09/The-Gender-Gap-in-Technology-in-Scandinavia_Full-report.pdf),
too, are teaching computing in high schools in one form or another. However, it wouldn’t be realistic to expect this to
become a worldwide trend, since most developing countries in Asia, Africa and South America lack the resources,
technological infrastructure and the manpower to adopt such policies. On the other hand, limiting this initiative to
high-income neighborhoods where infrastructure is ready will just aggravate the already deep-rooted inequality among
children of different socio-economic backgrounds.
## **Is it even necessary?**
Even in the event that all the stars somehow align and there is a will and resources to introduce computer science
courses into high school curricula, the question we have to face is, ‘is it even necessary?’ It turns out that the
answer is “not really.” The programming languages being taught in high schools will probably no longer be relevant by
the time the students enter the workforce. They might start to go out of fashion even before the kids get into college.
We also have to remember that staying up to date on the most relevant programming languages will be a huge challenge for
CS teachers in high schools and this will put further stress on the already scarce resources.
## **A better option**
There is an alternative, though. Making use of low-code/no-code application platforms (LCAPs/NCAPs) to familiarize
students with the basic skills needed to develop apps, without getting into hard-core programming, seems to be a logical
middle ground. The low-code platform Mendix does that with its [Mendix University Program](https://www.mendix.com/university-program/),
where university students in more than 100 universities around the world are learning how to build apps without coding
knowledge. The graduates of the program are expected to successfully bridge the gap between the technical and
non-technical teams in their work places in the future.
This formula could easily be adapted to high schools through the use of no-code platforms, which require no coding
knowledge at all. After all, NCAPs take the abstraction level a little bit higher than the LCAPs, making it easier to
create apps for the uninitiated. Teaching high school students how to use no-code tools could give them the necessary
tech-literacy this day and age demands, without turning high schools into a feeder system for corporate firms.
Despite being notorious for having a shorter attention span than previous generations, members of the Gen Z are
characterized as [“pragmatic and realistic.”](https://www.mckinsey.com/industries/consumer-packaged-goods/our-insights/true-gen-generation-z-and-its-implications-for-companies)
Thus, it is safe to assume that, instead of looking at endless lines of code on a screen, they will be much more
comfortable interacting with “blocks of code” on NCAPs that they can drag-and-drop to build apps they can use on their
phones. They will experience instant gratification right away, going through back-to-back “aha!” moments and realizing
value in a short time. NCAPs could nurture the skills like creativity and logical thinking in all students and help some
of them develop enough interest to become professional developers one day, without taking away much time from maths,
science and arts that all students should be exposed to as teenagers.
Peaka envisions a future where app development will not be the prerogative of a select few, but a mainstream skill. In the
near future, people will no longer turn to developers for apps they need to have in their lives and choose to do it
themselves. That’s why Peaka team has been making painstaking efforts to perfect its UI—because that’s where the
future will be shaped.
--- START: blog/no-code-for-manufacturing-industry-1/no-code-for-manufacturing-industry-1.md ---
# **No-code for the Manufacturing Industry (1)**
No-code tools are both a product and an enabler of the new economy. In the minds of outsiders, they evoke cliches associated with the technology sector: Company names that sound like they were randomly generated by AI, soaring stock prices, startups dwarfing century-old established firms in valuation and a new breed of twenty-something founders who tell business people at least twice their age what they should do to be successful. For some people, the no-code movement is just a fancy way of producing toy-like apps for smartphones and nothing more than one of those bubbles we come across every few years.
Nevertheless, this time it is different. Recent signs tell us that people outside the tech industry have taken note of the transformative power of no-code. The manufacturing industry, always looking to integrate new technology into existing processes, could not remain indifferent in the face of efficiencies no-code is promising to unlock and is increasingly making use of no-code tools. The fact that decades-old companies in century-old business segments are turning to no-code platforms gives further credence to capabilities of no-code and proves that it is not a passing fad as some try to make it out to be. In this blog post and the next, we will take a look at what kind of a role no-code platforms are slated to play for manufacturing companies. But, first of all…
## **Who are Ohno and Shingo?**
Introduction of no-code tools into the manufacturing industry will not be the first time it has adopted a new approach in a wholesale manner to remain competitive. In the 1980s and 1990s, the inspiration came from Japan. Concepts such as lean (just-in-time) manufacturing, *kaizen*, *kanban*, *genchi gembutsu* and Five Whys, which had combined to create an industrial giant out of the ashes of World War II in Japan in the past, were imported to the U.S.
We owe most of this to two Japanese engineers. Taiichi Ohno (1912-1990) was a Japanese industrial engineer and innovator who is credited with laying down the principles of Japanese scientific management. Eric Ries, in his book [*The Lean Startup*](https://www.google.com/books/edition/The_Lean_Startup/r9x-OXdzpPcC?hl=en&gbpv=1&dq=the+lean+startup+2017&printsec=frontcover), describes him as “the father of the Toyota Production System”, which was developed in 1930s (Ries, 2011, p.230). The concepts like Five Whys (a logical tool for root cause analysis) (Ries, 2011, pp.229-40) and [*Muda*](https://www.pocketbook.co.uk/blog/2018/03/13/muda-7-wastes/) (‘7 Wastes’ or sources of productivity loss) that he popularized later became inspiration for concepts like lean manufacturing and just-in-time in the U.S. Shiego Shingo (1909-1990), on the other hand, helped codify the Toyota Production System and introduced what is today known as the SMED (Single-Minute Exchange of Dies) (Ries, 2011, p.186). [SMED](https://www.leanproduction.com/smed.html) is a collection of practices that reduces machine changeover times from hours to single-digit minutes after a certain process. With machine changeover becoming less tedious, the manufacturer is able to work with smaller batches, better respond to the customer demands and rely on less inventory.
## **What Ohno and Shingo achieved**
Ohno and Shingo together revolutionized the Japanese manufacturing industry and inspired a tide of innovations that changed the American industrial landscape in the last quarter of the twentieth century. These concepts imported from or inspired by Japanese business leaders prioritized nurturing a relationship of trust with suppliers and focused on building quality into the production processes, swift response when something went wrong and empowerment of frontline employees to inspect and correct faulty production (they all deserve a look—look them up if you are interested scientific management and business strategy). Although claiming that these concepts democratized the Japanese business environment would be an exaggeration (it remained quite patriarchal), these concepts elevated the status of the employees and empowered them to make decisions on their own. They were like a much-needed update to the Taylorist scientific management principles of the past. The results were astounding. Production cycles got shorter, employee morale improved and warranty payments resulting from low quality products significantly decreased, helping the corporate bottom line.
## **Final thoughts**
Decades later, we stand at the threshold of another transformation, but the goals remain the same. Companies still strive to reduce production cycles, boost employee morale and cut down costs, but in an entirely different context. This time, the manufacturing industry is trying to cope with the impact of a pandemic and adapt to a future where automation, data collection and analysis and connectivity will be the key determinants of success. The companies that can adapt will see their prospects improve, while the ones that can’t will fall by the wayside.
“Employee empowerment” has become trendy once again. Today, domain experts, people with deep knowledge in their respective fields of work, are well-positioned to take on more responsibilities than their predecessors. They are armed with no-code tools and stand at the forefront of the digital assault, taking the initiative to solve problems rather than looking for instructions from upper management. How no-code is putting into action what Ohno and Shingo preached will be the subject of our next blog post. Stay tuned.
--- START: blog/no-code-for-manufacturing-industry-2/no-code-for-manufacturing-industry-2.md ---
# **No-code for the Manufacturing Industry (2)**
The no-code platforms have been assessed mostly from the point of view of startups and SMBs so far. However, corporate giants with thousands of employees, where everything from cars to tankers are manufactured, are just getting their feet wet and starting to give no-code platforms a bigger role in their production processes.
## **What is in it for the manufacturing companies?**
Why are the corporate manufacturers opting for no-code platforms? First of all, there is a shortage of skilled manpower that can operate the new generation of machinery at the shop floor. There are only [32,000 robotics engineers in the USA](https://www.roboticsbusinessreview.com/interview/no-code-programming-unleashs-the-transformational-power-of-robotics-an-interview-with-ready-robotics-juan-aparicio/), which translates into only one robotics engineer for every 11 factories. Training workers to pick up the slack is neither easy nor cheap. As a result, no-code assuming bigger responsibility seems to be the only viable solution.
Secondly, software systems being used in manufacturing [are notoriously expensive and do not lend themselves to customization.](https://tulip.co/resources/no-code/#chapter_2) This is where the no-code tools step in: They are easy to configure and make it possible for engineers to supervise and coordinate machines and people in real-time, with little cost to the company.
Thirdly, no-code platforms foster delegation of authority, empowerment of frontline employees who have first-hand experience of problems and a general democratization of the work environment. They have the potential to breathe new life into the Japanese-inspired scientific management principles that became popular at the end of last century. Just like an [andon cord](https://en.wikipedia.org/wiki/Andon_(manufacturing)) at a Toyota factory—by giving the workers the authority to stop the whole assembly line in the event of a problem—significantly improved quality and productivity, delegating authority to domain experts and letting them devise solutions to the problems they face can be expected to do the same.
Democratization in the workplace and giving power back to the workers may sound good on a press release but such outcomes are not ends in themselves for manufacturing companies. These companies are in this for their own gain. The interest the manufacturing industry has taken in no-code platforms stems from the digitization and digitalization agenda that it has been following. This may sound tricky but these two terms have different meanings: While digitization involves [a change in form from analog to digital,](https://johnmaeda.medium.com/digital-transformations-fail-because-they-miss-the-difference-that-just-four-letters-can-make-fb5ea5305520) digitalization implies [a change in the business model](https://johnmaeda.medium.com/digital-transformations-fail-because-they-miss-the-difference-that-just-four-letters-can-make-fb5ea5305520) whereby digital technologies come to play a bigger role in value creation. Digital transformation aims to make companies more competitive by rendering them more agile and responsive to the market demand, while significantly bringing down development costs. A case in point is provided by electronics companies, [90 percent of which](https://spectrum.ieee.org/consumer-electronics/standards/why-smart-manufacturing) are investing in digital factories according to a report, hoping to cut time-to-market by half and reduce development costs by a quarter.
## **Picking up from where Shingo left off**
What do no-code platforms bring to the table for the manufacturing industry? For starters, these tools can facilitate visual quality inspections and ensure zero defects, [eliminating the need for end-of-the-line quality inspections.](https://www.industryweek.com/technology-and-iiot/article/21157325/democratizing-smart-manufacturing) Moreover, no-code platforms can [gather data](https://tulip.co/ebooks/no-code/) from different work stations in real-time and form aggregate stats, making performance monitoring and evaluation much easier. Still another benefit involves [line clearance](https://tulip.co/ebooks/no-code/) at the assembly line, which makes sure that tools and materials from a previous process are swiftly removed so that the machinery can be set up for the next process. This brings to mind Shiego Shingo’s SMED (Single-Minute Exchange of Dies) concept, which focused on minimizing machine changeover times. This similarity is further proof that no-code platforms are poised to realize the vision of the Japanese innovators of the previous century.
There are numerous cases where manufacturing companies leveraged no-code platforms to achieve operational goals. For instance, the Orlando-based Nautique Boat Company [used Tulip’s](https://tulip.co/blog/case-studies/nautique/#download) no-code solution to increase product visibility and monitor what employees at each work station are doing, achieving a meaningful increase in productivity.
The Netherlands-based no-code platform Betty Blocks [developed](https://www.industryweek.com/technology-and-iiot/article/22027178/citizen-developers-on-the-shop-floor) two solutions (MySepp and GPI) to improve safety in the workplace and construction sites.
Rolls-Royce Germany has [partnered with](https://www.industryweek.com/technology-and-iiot/article/21157235/rollsroyce-and-altair-collaboration-leverages-ai) Altair’s Knowledge Works to leverage low-code/no-code tools to acquire the data analytics capability it needed.
The list can go on and on. All of these companies are trying to adapt to a new era of manufacturing, dubbed Industry 4.0. Just like textile machinery prevailed over handiwork during the First Industrial Revolution (Industry 1.0), this time it will be the smart manufacturing processes that beat the legacy manufacturing methods thanks to no-code platforms.
## **Final thoughts**
It is clear as day that the no-code revolution is here and does not look like it will be limited to mobile apps, either. At Peaka, just as we are getting ready to come out of early access, we can’t wait to see what citizen developers will be able to do on our platform once they unlock its capabilities.
--- START: blog/no-code-fostering-collaboration/no-code-fostering-collaboration.md ---
# **No-code Fostering Collaboration in Cross-functional Teams**
The stereotypical coder in people’s minds is a modern hermit, someone working in a cubicle in an office building or his family’s garage, having minimal contact with the rest of the human civilization until he is ready to unveil the next big thing. The reality is quite different, though. Coding has always been a [social and collaborative process](https://pearlchen.medium.com/there-is-no-i-in-coding-2e2ed4daeb99). Nowadays, even more so. According to a survey carried out by the National Association of Colleges and Employers (NACE), collaboration-related skills are among [the most wanted by employers](https://www.forbes.com/sites/susanadams/2013/10/11/the-10-skills-employers-most-want-in-20-something-employees/?sh=7f6ad2a56330): 3 of the top 4 and 4 of the top 10 skills involve collaboration in one form or another. The rise of SaaS businesses seems to have further put a premium on collaboration skills.
## **Different approaches to project management, wildly different results**
The SaaS revolution changed the way projects are implemented. The waterfall project management, which previously was quite popular, gave way to Agile in keeping with the spirit of the time. Waterfall was not without its [merits](https://softwarehut.com/blog/it-project-management/introduction-to-agile-software-development-methodology): It was designed to meet certain deadlines and watch budget constraints. However, it lacked flexibility and did not take into account the changes the market went through, risking that the demand may not be there when the product is finally ready.
Agile, on the other hand, divides the project into short sprints and continuous iterations, continuously touching base with the market in order to develop a product that will nail the product-market fit. Agile did not start with SaaS companies, but this segment of companies, thanks to their ability to collect and process immense amounts of usage data, lend themselves so well to Agile that they have become almost synonymous with it. Agile can be seen as a modern interpretation of the [Japanese management concepts](/blog/no-code-for-manufacturing-industry-1/) like lean manufacturing and aims to cut waste by running constant tests and basing decisions on validated learning.
## **Test, measure and learn: Data is the new king**
The data-driven approach to decision making in a sense makes employment of cross-functional teams a necessity. The waterfall project management style can tolerate and even trigger siloed organizations; most important decisions are made at the beginning of the project and by decision-makers high up the chain of command. Agile cannot work that way—the need to constantly collect feedback and data, assess them and make course corrections where needed require a cross-functional team to work together with a wholistic view to develop the best product possible.
These cross-functional teams should bring together people like UI designers, UX designers, products designers, developers, product managers and marketing people. A product designer decides how the product should feel and work, and provides the design parameters for UI and UX designers. A [UX designer](https://blog.adobe.com/en/publish/2017/01/10/the-evolution-of-uiux-designers-into-product-designers.html#gs.9giqad) prepares use case scenarios, runs A/B tests and lays out a basis for the user interface and product logic. UI designer is the person who executes this product logic through screens and pages. Marketing people arrange focus groups and collect customer feedback to assist the validated learning process. [Product manager](https://www.atlassian.com/agile/product-management/product-manager) oversees this whole process, puts design, marketing and engineering people in a position where they can succeed, and aligns internal and external stakeholders behind the same goal.
The idea here is to bring all these people [as close to each other as possible](https://pearlchen.medium.com/there-is-no-i-in-coding-2e2ed4daeb99) and put them in the same room so that they can exchange ideas, which will stop needless investment into things that will eventually be vetoed by colleagues. An environment where people with different functional roles could sit around a table and share their visions for the same product in light of market reports, usage data and changing regulations is what makes Agile so productive. The course corrections and pivots resulting from these discussions ensure that the product will meet the customer requirements when it is finally launched.
## **Bringing the no-code touch to project management**
No-code can be the catalyst in this collaborative process. It can eliminate the silos employees are used to working in and facilitate teamwork instead. In traditional product development, different teams have their specific tools: Prototyping, design, front end and back end development all have their dedicated tools to work with. When all these phases are over, the DevOps people finally show up and tie up the loose ends.
This process involves minimal cooperation. Additionally, different tools used can be a source of waste. No-code replaces much, if not all, of those. Prototyping is the strong suit of no-code platforms—they are tailor-made for testing different ideas and finding out which one deserves to be the basis for the project. These platforms allow product and marketing teams to [run tests](https://taplytics.com/blog/no-code-experimentation-creates-cross-team-collaboration/) on their own and validate their hypotheses. Design and front end, too, can be easily taken care of on the platform. Moreover, there are no-code tools like Integromat that can be employed for back end service. This kind of an arrangement removes the need for DevOps altogether. As a result, a single platform can easily bring together all stakeholders working on a project, align them with the previously set goals and facilitate data sharing. No-code technology basically creates a highway on which ideas can move back and forth freely, expediting iterations and reducing time-to-market.
Nothing capitalizes on the social and collaborative nature of software development like no-code platforms can. The sooner business leaders understand this and join the movement, the bigger the benefits that they will reap will be.
--- START: blog/no-code-future-of-software/no-code-future-of-software.md ---
# **Is No-code the Future of Software?**
The dizzying speed of technological change raises all sorts of questions among the tech audience. Some of those questions naturally involve the future of coding. Coding may look enigmatic and scary to regular people—it evokes something like alchemy or black magic in their minds. Even the mere promise of a breakthrough that can possibly replace coding with something more intelligible to the general public is enough to grab headlines. But is it possible? Are the days of text-based coding numbered? And will it be no-code that replaces it?
Code is basically a medium to tell your computer what to do. Everything in our daily lives that run on a piece of software is actually running on code. As a result, the hectic change going on around us that we witness everyday is driven by code. The only thing slowing down this process is the bottleneck caused by the availability of the developer talent. We don’t have enough developers, and the pace at which our education system produces developers cannot keep up with the increase in demand for developer talent. Software will keep diffusing throughout our lives regardless, from our smart homes to self-driving cars to task automation apps we use for our jobs. If there aren’t enough developers around, smart people will find new ways of producing software and fill in for developers.
The future of software will not be so much about replacing text-based code but making software more accessible to the general public. Satisfying the ever-increasing demand for software will be a tall order for the limited number of developers, so more people should join the ranks. However, there is a catch: Learning how to code is no easy business, and training more developers to satisfy the demand for software is not a feasible idea. Thankfully, there is no-code, which can take care of the majority of use cases regular people need software for. With that in mind, emergence of some kind of stratification looks highly likely in the production of software: While products that require sophisticated engineering will rely on text-based code, regular people, most of them domain experts, will be creating the bulk of less complex software products on no-code platforms.
No-code is currently the most promising solution to deal with the bottleneck checking the further diffusion of software into our lives . As of now, well-defined and repetitive tasks are the low-hanging fruits for no-code technology—it already works wonders with such stuff. However, with no-code platforms acquiring new capabilities, they will start to branch out into fields where text-based code has been the only option so far.
So, yes, no-code is the future of software. It is what will take the software to the masses. But no, no-code will not replace coding. Principles of text-based programming languages will still hold for the foreseeable future. Understanding the fundamentals of and the logic behind coding will give no-code users a [huge advantage](https://www.unqork.com/resources/articles/4-predictions-for-the-future-of-no-code) in creating sophisticated apps. After all, the boxes and arrows we use to form workflows in a visual design environment are nothing but representations of functions and data, respectively. And the drag-and-drop design itself is a programming language, albeit one that is not text-based. It just happens to operate at a higher abstraction level with more constraints in place. Therefore, coding will not be replaced but rather transformed, and no-code is the next step in its evolution.
--- START: blog/no-code-hands-free-coding/no-code-hands-free-coding.md ---
# **Can No-code Make Hands-free Coding Easier?**
We have been arguing in this blog that no-code is here to change the future: It will basically change the way software is produced, take the software production capability to masses and everything will follow from that. Our very own [Beyza Özkan](https://www.linkedin.com/in/fatos-beyza-o-831b7879/) (Product Manager, Peaka) recently got rather specific in [one of her tweets](https://twitter.com/nocodesigner/status/1422561379995852812?s=21) about a possible scenario where no-code could allow people to use voice commands to create apps. Sounds intriguing, doesn’t it?
Dictation software has been around for a while. You come across its applications every time you use Alexa or Siri or adjust the temperature in your car by simply talking to it. However, coding by voice is tricky because it involves [non-dictionary words and syntax rules](http://betterprogramming.pub/how-to-write-code-using-your-voice-f1bf42952075). Your commands should conform to a predefined form for the software to implement them. But this hurdle hasn’t stop coders from taking advantage of this technology. For example, the voice-coding app, [Serenade](https://serenade.ai/), serves as a digital assistant for the coder while the hands-free coding platform [Talon](https://talonvoice.com/), which replaces mouse with a mic and an [eye-tracker](https://www.joshwcomeau.com/blog/hands-free-coding/), has introduced a comprehensive body of commands that make more control over the code possible. These two apps have been a great help to coders who suffer from work-related repetitive strain injuries that threaten to put an end to their careers due to severe pain and numbness in hands.
No-code definitely has a role to play here. It can be expected to set the basis for a system that can turn voice into commands, build up a library and lay out the use cases. Just like no-code technology is used today to move around predefined blocks of code to carry out certain tasks, most of the time using a drag-and-drop UI, hands-free no-code applications can use designated voice commands to carry out certain functions.
This sounds exciting, but is it really revolutionary? Is it a clear breakthrough considering where the no-code technology is at now? Probably not. The abstraction level in hands-free coding will most likely not be any higher than what is possible with no-code platforms today. The system will be able to operate within the boundaries set previously, carrying out certain tasks using commands mapped to predefined actions and components. In order to effect changes at the granular level, separate commands will have to be assigned to every little separate action. In other words, no-code will be facilitating what’s already on the menu. Therefore, high-level instructions such as “Siri, create me a web app that works as a CRM suite for my sales force” will probably find itself a reply along the lines of “Come again, please?”
In the short-to-medium term, it is safe to say that no-code will only be limited to facilitating what’s on the menu—it will serve as the navigation bar for software in carrying out what is possible from among the predefined options. This means that we have to lower our expectations with regards to what no-code will achieve at the beginning. The true revolution will possibly come with the wide-scale introduction of machine learning and the collaboration no-code will build with this transformative technology.
--- START: blog/no-code-low-code-advantages/no-code-low-code-advantages.md ---
# **Top 5 Advantages of No-code Platforms for Startups**
In today’s world, technology is front and center. Smart home assistants, virtual chatbots, self-driving cars… All these are modern world innovations that seemed impossible a decade ago! And with the rise of the tech industry, the market for IT professionals has also become intensely competitive.
As the demand grows for skilled developers and software engineers, businesses are in a race to offer the sweetest deal to land the services of these professionals. The result? Startups and small businesses are finding it difficult to keep up with large corporations, as they lack the means to attract the best talent in a tight job market.
The good news is that startups and SMBs no longer have to struggle as much just to keep up with the big businesses, thanks to no-code and low-code development platforms! These technologies have changed the digital landscape. Previously, only professional developers could build functional programs and software. But today, even citizen developers can build applications in a matter of minutes.
No-code and low-code platforms appeal to startups for a number of reasons. If you are a startup looking to build a complex application quickly and efficiently, a no-code or low-code platform may be the right choice for you! Check out the advantages of [no-code and low-code development](/blog/low-code-vs-no-code/) below.
## **What are no-code and low-code development platforms?**
In 2022, global enterprises are projected to spend a whopping [$675 billion on enterprise software](https://www.statista.com/statistics/203428/total-enterprise-software-revenue-forecast/) alone! And a big chunk of that will go to no-code and low-code development platforms. But what are they and how do organizations utilize them?
Both no-code and low-code development platforms require zero to minimal coding or programming knowledge to create applications and software. This means that anyone, regardless of their technical skills, can create apps and software using these platforms.
No-code is often used by businesses to develop customer-facing apps, including customer portals and forms. But these platforms may also be used to create internal tools such as HR or CRM systems. On the other hand, businesses utilize low-code platforms to build customized applications such as data management systems.
While traditional code is usually written by professional developers with years of experience, both no-code and low-code platforms are designed for use by citizen developers to quickly build applications without writing code from scratch.
With the minimal technical skills required by both no-code and low-code platforms, they become much more accessible to a wider range of users. This also makes these platforms more appealing to startups because they can create working prototypes quickly and without the need to hire expensive developers.
## **What are the advantages of no-code and low-code development for startups?**
No-code and low-code development are becoming increasingly popular among startups. This is because these platforms offer a number of advantages that are appealing to companies in their early stages. Here's a list of five advantages of no-code and low-code development:
### **1 - Saving on resources**
No-code and low-code development platforms allow startups to build complex applications quickly and efficiently. This can be done without the need for costly and time-consuming custom coding—effectively helping startup’s save on its valuable resources.
Instead of spending limited funds on hiring developers, no-code and low-code platforms allow startups to create their own applications using a drag-and-drop interface. This means that startups can focus their resources on other areas of their business, such as marketing or product development. In a company where resources are scarce, every last penny counts. In this aspect, no-code and low-code development can be a real game-changer.
### **2 - Reduced time-to-market**
Another advantage of no-code and low-code development for startups is the ability to get to market faster. Startups often have to move quickly to gain a competitive edge and no-code and low-code platforms allow them to do just that.
These platforms make it possible for startups to create a working prototype, called a minimum viable product or MVP, with ease. By using these platforms, an MVP could be built in a fraction of the time it would take with traditional development tools!
### **3 - Keeping the focus on the product, not the technology**
Many startups begin with just an idea. And an idea can grow and evolve with the use of technology until it is successfully transformed into reality! However, with traditional development tools, technological challenges often take center stage. This can be a problem for startups that don’t have the time or resources to focus on the nitty-gritty of various technological tools.
When using no-code or low-code platforms, startups can focus on developing their product. Although technical limitations may still arise on these platforms, these platforms can help alleviate the said limitations and make it possible for users to create complex applications.
This is a major advantage for startups as these platforms already take care of the technical aspects of application development, such as hosting, scaling, and security. By using no-code or low-code platforms, startups can avoid these problems altogether and focus on what’s important: Developing a great product!
### **4 - Increased agility**
Agility is the ability to rapidly respond to change. In the startup world, being agile means prioritizing flexibility over fixed —and sometimes unrealistic—goals. The willingness to quickly pivot within a dynamic environment and accommodate the necessary changes contribute to creating an agile organization. Basically, startups need to be able to swiftly adapt and change their products and processes to meet the ever-changing needs of their customers.
In an agile environment, startups can validate their ideas quickly and efficiently, without spending months or even years developing a product that may not be successful. Developing an MVP also allows startups to test their products with potential customers and get feedback early on, which can be invaluable in the development process.
No-code and low-code platforms are the perfect tools for startups that need to be agile. These platforms make it possible to quickly apply development changes. This means that startups can rapidly respond to customer feedback and make changes to their products on the fly.
Being agile gives startups a major advantage over their competition. They can quickly pivot their products to meet the evolving needs of their customers and stay ahead of the curve. This increased agility can also spell the difference between success and failure for a startup.
### **5 - Expanding into new markets**
New markets are constantly emerging, and startups need to be able to quickly enter these markets to stay ahead of the competition. No-code and low-code platforms make it possible for startups to enter these markets with minimal effort—markets that would otherwise be inaccessible!
For example, a startup that wants to enter a certain market such as the healthcare or finance industry may need to develop an application that needs to comply with strict regulations. No-code and low-code platforms would allow them to do this quickly and efficiently, without the need for expensive developers.
## **The bottom line**
Overall, no-code and low-code development platforms offer a number of advantages that can be incredibly helpful for startups. And as the adoption of these technologies continues to grow, the outlook is extremely positive for the years to come. By 2030, an [estimated 75 percent of businesses](https://www.forbes.com/sites/forbestechcouncil/2021/05/13/low-code-and-no-code-in-2021-are-they-as-useful-as-they-seem/) worldwide are projected to adopt no-code or low-code platforms - or both! The market for these platforms is also forecasted to grow by [approximately 23 percent](https://www.grandviewresearch.com/industry-analysis/low-code-development-platform-market-report) in the same period. So, if you are a startup looking to create internal applications with ease to remain competitive and relevant in the years to come, then no-code and low-code development are definitely worth considering!
--- START: blog/no-code-myths/no-code-myths.md ---
# **Dispelling 5 Myths and Misconceptions about No-code**
No-code has been the talk of the town lately, but one has to take with a grain of salt some of the stuff being tossed around.
While some tend to overestimate the capabilities of no-code platforms and prophesy greatness for them, others underestimate them,
predicting that their impact will only be ephemeral. We need to make a shortlist of the most common myths and misconceptions
about no-code and see whether they hold up under scrutiny.
## “It is not for developers”
Professional developers [scoff at](https://www.wired.com/story/databases-coding-real-programming-myth/) no-code platforms and that’s understandable. Some of the hype around no-code is clearly unfounded (we’ll get back to that in a bit) and if you are a developer who spent years writing thousands of lines of code, an amateur posing as a coder just because he could drag-and-drop some components on the screen can get on your nerves.
It shouldn’t, though. There are so many tedious, repetitive tasks that developers could do without. No-code platforms are perfectly capable of handling those tasks and empowering citizen developers in an organization to build apps for their own jobs. This
frees up developers’ precious company time for things that require more creativity and coding prowess.
There is no harm in an non-coder hacking a tool to satisfy a daily need. Let regular people spread the
word and culture and create more demand for coding, which will be done by none other than developers.
## “It is only good for MVPs”
Some people think that no-code platforms are only good for validating ideas, prototyping and developing a minimum viable product (MVP) that will be just good enough for the early adopters of an app. The MVP consists of just the core features of a product.
The skeptics tend to doubt claims that apps can go beyond the MVP stage on a no-code platform. They are wrong, though. The premium no-code platforms have long achieved a level of maturity where, once you build your MVP, you can go and turn it into a full-fledged, real-time web app.
## “It is not scalable”
Scalability refers to a system’s capability to handle spikes in load and stay responsive in the face of rising demand
and increasingly more complex requests. This has been another concern of no-code-skeptics. Existing cloud architecture
and cloud service providers already offer some kind of scalability. However, not many developers have the skills to properly leverage cloud computing in a way that promotes scalability at a satisfactory level. This issue is already dealt with
within the architecture of premium no-code platforms like Peaka. These platforms utilize the cloud infrastructure in the best possible way, facilitating scalability and taking a good deal of workload off developers at the same time.
## “It is not as secure as conventionally developed software”
Conventional software development requires large, dedicated teams or sometimes even departments of expert developers
that can oversee the system and step in when a security issue arises. There are well-known vulnerabilities such as XSS,
SQL Injection and CSRF that pose a threat to systems. Most developers don’t know much about these threats, let alone devise solutions for them. Luckily, a well-designed infrastructure can eliminate such attacks. No-code platforms come with built-in industry-best practices out-of-the box. These platforms are developed with a focus on abiding by OWASP criteria, which help them mitigate a significant portion of the risk posed by common types of attacks.
## “It will eliminate the need for developers”
No, it won’t. Developers are here to stay and the demand for their skills will keep rising for years to come. They will be expanding the horizons of software, designing cutting-edge architecture, bringing into fold tasks which software had nothing to do with previously. This will trickle down to low-code/no-code platforms, improving their capabilities and reception. In fact, what developers refer to as “real coding” will be running the world in one form or another.
No-code might be a fairly new term for regular people. But the technology behind no-code has been around for some time and is already mature. Although they are not silver bullets by any means, premium no-code platforms like Peaka have delivered on their promises and proved that creating real-time apps on a scalable, secure environment is possible for anyone.
--- START: blog/no-code-pays-down-tech-debt/no-code-pays-down-tech-debt.md ---
# **How No-code can Help Pay Down Technical Debt**
The ongoing digital transformation is no easy business. Planning and optimizing it requires a lot of effort from an organization and adds to the already daunting challenges of an IT department. One such challenge that digital transformation exacerbates is technical debt. The pressure to digitalize an organization within a certain timeframe and budget constraints can lead to rushed decisions and solutions that are far from being technically ideal. Decision makers might be forced to [cut corners](https://www.meraksystems.com/blog/2019/10/14/technical-debt-the-promise-and-peril-of-low-code-applications.html), but in the meantime, they should gear up for the inevitable roadblocks they will eventually run into.
## **1 - What is technical debt?**
Technical debt refers to the deferred cost of extra maintenance and rework incurred when a solution that is easier to implement in the short run [is chosen over the best overall solution in the long run.](https://www.corporatecomplianceinsights.com/implications-technical-debt/)
It involves sweeping the nasty stuff under the rug and promising yourself to deal with it at a later time. Technical debt is a [manifestation of mismatch](https://www.mckinsey.com/business-functions/mckinsey-digital/our-insights/tech-debt-reclaiming-tech-equity) in an organization-mismatch between resources and goals, between IT practices and strategy, between the target architecture and the existing one.
## **2 - Why should we care about technical debt?**
First of all, technical debt slows down [innovation and growth](https://appian.com/blog/2021/how-low-code-helps-technical-debt-management.html) as it takes resources away from activities that create business value: IT departments spend [38 percent of their resources](https://appian.com/blog/2021/how-low-code-helps-technical-debt-management.html) on tasks related to dealing with technical debt. These are the same resources that would otherwise be used for value creation activities for the company and its customers.
Secondly, technical debt brings about a fragmented structure where different portions of the system are not in sync with each other. This creates bottlenecks and severely handicaps the scalability of the overall system.
Lastly, technical debt increases the [total cost of ownership](https://medium.com/serious-scrum/the-hidden-cost-of-technical-debt-1963b958e5ed) over the lifetime of a product. The slow down in iterations during product development, increased need for testing and rework, and higher frequency of complaints and support tickets all contribute to a spike in the total cost of ownership.
## **3 - How can no-code help with technical debt?**
Completely eliminating technical debt is neither easy nor feasible considering the amount of resources such an ambitious attempt would require. Every change in code [creates debt](https://www.outsystems.com/blog/posts/avoiding-legacy-trap-low-code/). Therefore, the more realistic approach would be to try to contain technical debt and have a plan in place regarding how it will be paid down.
The focus should be on the simplification of processes, getting rid of redundant software and investing in [high-impact measures.](https://www.mckinsey.com/business-functions/mckinsey-digital/our-insights/tech-debt-reclaiming-tech-equity) No-code platforms do just that. Their level of abstraction reduces system complexity to a level that is easier to manage. In addition to the high level of abstraction built into them, these tools can actively help deal with the shadow IT arising from hundreds of different apps being used in an organization at any time. After conducting a triage and deciding which apps get to stay and which need to go, citizen developers can leverage no-code tools to replace the purged apps with ones that are much better in terms of security, integrations and scalability.
There is one caveat, though. Dealing with technical debt is not something that can be undertaken on a whim - there needs to be a long-term strategy and the IT department should oversee the whole process. Without the IT oversight, integration of no-code tools will add to the shadow IT problem instead of curing it. The IT giving its sanction to the no-code platforms that will be used and making periodic interventions to pay down any resulting technical debt would be the ideal case.
--- START: blog/no-code-podcasts/no-code-podcasts.md ---
   Link copied
Table of Contents
* [No-Code Podcast Episodes of Note](https://www.peaka.com/blog/no-code-podcasts/#no-code-podcast-episodes-of-note)
* [Vlad Magdalin, Webflow CEO](https://www.peaka.com/blog/no-code-podcasts/#vlad-magdalin-webflow-ceo)
* [David Siegel, CEO of Glide](https://www.peaka.com/blog/no-code-podcasts/#david-siegel-ceo-of-glide)
* [Howie Liu, CEO of Airtable](https://www.peaka.com/blog/no-code-podcasts/#howie-liu-ceo-of-airtable)
* [Emmanuel Straschnov, co-CEO of Bubble](https://www.peaka.com/blog/no-code-podcasts/#emmanuel-straschnov-co-ceo-of-bubble)
* [Gary Hoberman, CEO of Unqork](https://www.peaka.com/blog/no-code-podcasts/#gary-hoberman-ceo-of-unqork)
* [No-Code Podcasts to Keep Tabs On](https://www.peaka.com/blog/no-code-podcasts/#no-code-podcasts-to-keep-tabs-on)
[Home](/) / [Blog](/blog) / No-Code Podcast Episodes of Note
[Startups](https://www.peaka.com/category/startups/) [Podcasts](https://www.peaka.com/category/podcasts/)
Published on June 04, 2021
10 min read
No-Code Podcast Episodes of Note


Danielle Boyd Peaka / No-Code Dabbler
**No-Code Podcast Episodes of Note**[](#no-code-podcast-episodes-of-note)
=========================================================================
If you are looking for some inspiration, what better way than to listen to some of the CEOs of the many no-code platforms that color the software landscape? Below are some notable episodes that you might find to be worthwhile.
**Vlad Magdalin, Webflow CEO**[](#vlad-magdalin-webflow-ceo)
------------------------------------------------------------
### **Notes:**[](#notes)
* Vlad views "Webflow-as-we-know-it" to be the 5th attempt after four failed attempts at the same idea. And all within a span of nine years (2004-2013).
* When trying to raise money in the beginning, post-YC, they found themselves in one of those precarious situations familiar to many no-code/low-code startups: "Half of the investors said it was too complicated for them to understand and wasn't easy to use, and on the other side we had half of them saying it wasn't powerful enough. So we were in this no-man's land -- 'there's no market here etc.'"
* The actual product market fit moment came when they were able to move beyond just landing pages and ship their visual CMS builder.
* Walking the fine line of growth: "We have enterprisey customers paying 50k per year, but we definitely never want the product to go beyond what an individual can be empowered by. It's hard to take an enterprise product and make it a consumer product. But it's magical when you can have an individual use your product from start to finish and then have teams be able to 10x that and still find success. "
* Hilarious Moment: around the 25:50 mark, Calacanis blindsides Vlad with a "Think about this: you've got these socialist a-holes in this world...," whereupon Vlad starts laughing nervously as a puzzled expression quickly creeps across his face. He manages to cut Calacanis off with, "Uhhh..where is this going?" Calacanis refuses to relent, however, and more amusing dialogue follows.

**David Siegel, CEO of Glide**[](#david-siegel-ceo-of-glide)
------------------------------------------------------------
### **Notes:**[](#notes-1)
* Admirable clarity of thought and sympathetic posture for a startup CEO. Insistently repeats that Glide is not intended for creating apps for the App Store and that they are turning their focus towards "Apps for Work". But he manages to do it in a calm and reassuring way, and without being a jerk to all the viewers who had their dreams set on winning the App Store lottery.
* Again, love that he unashamedly says what Glide is not. "People ask every day how to make the next TikTok. It's important for people to know that it's not our agenda to help you make the next TikTok. If you're waiting for a feature in order to make the next TikTok, don't count on us making it because it's not the customer we're going after...If you're gonna try to make the next Facebook, you're probably gonna make zero -- you're probably gonna make negative." Sounds harsh on paper, but again, his delivery on Glide's mission is firm but sympathetic.
* After gently letting down all those App Store hopes and dreams, he convincingly makes the case that there's lots of opportunities to make money from apps outside the App Store, "The real way to make money is not by making the next TikTok but by making apps for companies who have a real problem, solved by an app, who will pay you money today...If you become an expert in no-code tools you can help companies solve problems 10x to 100x more quickly than custom software development." Fighting words, no doubt.
* He also touches on an all-too-familiar pain point for all those products that are focused on building web apps: "We only used the word app because we couldn't find a better one to describe custom software. We don't like saying 'create custom software' or 'custom tool' or whatever...We only started with a phone because it's the easiest thing to design."
* Like others, they have struggles with terminology: "We don't even use the term 'no code'. What we think we're doing is inventing a better way to make software."
* Hilarious moment: After spending a good deal of time hammering home the point about Glide not being suited for native apps, the interviewer asks Siegel the most urgent question on everyone's mind: "How do you create a native app in Glide?" Siegel's split second expression is priceless, but again, he lays the law down with grace.
**Howie Liu, CEO of Airtable**[](#howie-liu-ceo-of-airtable)
------------------------------------------------------------
### **Notes:**[](#notes-2)
* Airtable is an outlier in the sense there had a two/three year building phase before launching the product.
* Claims to have de-risked this phase with private prototypes developed every 3-5 months and tested with potential users. Also mentions that they talked to lots of people who had tried and failed to build similar products. The thesis they developed was that if you built anything that was not as easy to use as Excel, you would die. What needed to be done was very clear to them. His experience at Salesforce gave him an important insight into spreadsheet needs for example. Furthermore, the success criteria with respect to data was also very clear: data loss in Excel was non-existent so any data loss in an online solution would also not be acceptable.
* Didn't launch quickly because the MVP bar for an Excel replacement was very high and also because he was confident in their first-principles based long-term market strategy.
* He forced himself to become proficient in coding because potential technical co-founders wouldn't take him seriously as just an "idea man" (Nowadays, thanks to these types of tools [there are other options for non-technical co-founders.](/blog/non-technical-founder-no-code/))
* Liu doesn't explicitly mention it as the reason but I think one of the main reasons they were able to spend two/three years before launching was that Liu had sold his first company to Salesforce. I would think that track record would help with not having investors pressure him for an early launch. Also, he would probably have had some means to extend the runway if necessary.
* More discussion on how they tracked the competition during those early days and some discussion on how what they were attempting to build was going to be different than Google Sheets for example would have been nice. Added to that, I was wondering at what stage making an app from a spreadsheet became feasible.
**Emmanuel Straschnov, co-CEO of Bubble**[](#emmanuel-straschnov-co-ceo-of-bubble)
----------------------------------------------------------------------------------
### **Notes:**[](#notes-3)
* Fighting words on churn: “We have expected churn when businesses built on Bubble fail for business reasons. But what we see is that when users have a new business, they come back to build it on Bubble…if you are in the long tail it is ok to have high churn \[gives Shopify and Stripe as similar examples\]…We don’t optimize on churn, we optimize on net revenue.”
* Still views the learning curve to be something to be improved. Mentions more focused curriculum and better UX as things they aim to develop. In the early days of Bubble Emmanuel was spending an hour a day on calls with users for support, which contributed to their growth.
* On tackling the difficultly in app building: “Instead of restricting the tool to prevent users making mistakes, we want to create the tools to help users help themselves \[like the Bubble debugger\]”
* Again terminology nitpicking is a common theme: “My personal goal is that in 5 years we don’t talk about “no code” anymore. No-code just becomes a way to build things.”
* Difficulty in nailing pricing: “We have people in high-school literally just playing or building side projects. And then we have 300 million dollar companies running on us. We have to find a pricing scheme for both. The other challenge is that we target non-technical people and it is difficult for them to understand the technical resources it takes to run an application…So now we charge for performance.”
**Gary Hoberman, CEO of Unqork**[](#gary-hoberman-ceo-of-unqork)
----------------------------------------------------------------
### **Notes:**[](#notes-4)
* Fighting Words: "What's different about us from something like Wix is this: what we drag and drop can replace the most complex trading platforms, transaction systems, the 20 million transaction-per-second type systems -- all those things."
* According to Hoberman, the role of coders and developers in Unqork is to develop reusable components that users will then drag and drop without code to build their applications. What's interesting is that he takes a very firm stance against mixing no-code with code: "We say no code means 'No code you inject. No code you generate.'"
* Continuing with this approach, either someone is coding to develop reusable components or someone is dragging and dropping those components without code. He is very against writing custom code mixed in with no-code components. For him, every line of custom code seems to be a missed opportunity for a reusable component that many other customers can also use.
**No-Code Podcasts to Keep Tabs On**[](#no-code-podcasts-to-keep-tabs-on)
-------------------------------------------------------------------------
With new no-code podcasts popping up in the community from time to time it's sometimes hard to make a habit of routinely surveying the landscape. Nevertheless, I thought I would mention a couple worth keeping track of.
[](https://visualdev.fm/listen)
These guys are great to follow because they give good weekly/monthly recaps of recent developments in the no-code world. If you're too busy or lazy to check your twitter feed or those unread newsletters in your inbox, you’ll do no worse than tuning in to Visual Devs for the latest happenings and updates in the no-code ecosystem.
For those that prefer the laid back approach this podcast might fit the bill since their approach is more casual than the podcasts that primarily focus on interviewing guests. A word of caution though, the podcast titles usually refer to topics that are taken up later in the episode, so don't be surprised if they take their time getting there:) But with their thoughts and comments on no-code current events this podcast does really make you feel connected to the community, so credit where credit is due.
[](https://open.spotify.com/show/65PGDyBO0jhmhetnpSGvmv)
This one is a good podcast that's focused on interviewing app builders about their no-code trials and tribulations. From what I've listened to so far, Ayush is good at not getting in way of his guests and giving them enough space to get their interesting viewpoints and experiences across.
A sample episode I can recommend is the one with Max Haining, the founder of [100DaysOfNoCode.com](http://100DaysOfNoCode.com). In that episode Max doesn't shy away from acknowledging the learning curve of no-code tools that's completely absent from the "build in 5 minutes" marketing material. He points out that only very few of those satisfy the "low learning curve combined with the speed which you can move to build things", but those are the ones that give him the biggest hope for the future of no-code. You can check out other no-code stories [here](https://open.spotify.com/show/65PGDyBO0jhmhetnpSGvmv).
Your biweekly inspiration delivered to your inbox
Join our newsletter for news, tips, and blog posts on anything data integration!
Subscribe
 Please fill out this field
 Thank you! You have been subscribed.
Similar posts you might be interested in
[](https://www.peaka.com/blog/saas-ideal-customer-profile/)
Startups Podcasts June 04, 2021
[How to Create an Ideal Customer Profile for SaaS Businesses](https://www.peaka.com/blog/saas-ideal-customer-profile/)
How do you create an ideal customer profile (ICP)? Why should a SaaS company create one? How does Peaka help you hone your ICP? Find out in this blog post.

Bruce McFadden Peaka / Seasoned Taskmaster
[](https://www.peaka.com/blog/account-based-marketing-saas/)
Startups Podcasts June 04, 2021
[How to Create an Account-Based SaaS Marketing Strategy](https://www.peaka.com/blog/account-based-marketing-saas/)
Here is everything a SaaS founder needs to know about account-based marketing, how it works, its benefits, and how Peaka can help ABM teams implement it.

Eugene van Ost Peaka / IT Soothsayer
[](https://www.peaka.com/blog/top-saas-revenue-metrics/)
Startups Podcasts June 04, 2021
[Top 6 SaaS Revenue Metrics to Track in 2026](https://www.peaka.com/blog/top-saas-revenue-metrics/)
A deep dive into SaaS revenue metrics, four data integration tools to track SaaS revenue, and benefits of blending your revenue data with your CRM data.

M. Çınar Büyükakça Peaka / Prolific Polemicist
 
Begin your journey today
Start your 14-day free trial to explore Peaka!
Get started for free
Enjoying this article?
Subscribe to our monthly newsletter for insights on ServiceTitan data integration and KPI reporting.


First Name
Last Name
Email
Company Name
Phone Number (optional)
Subscribe
You can unsubscribe anytime. For more details review our [Privacy Policy](https://www.peaka.com/privacy-policy/).
--- START: blog/no-code-recomposing-enterprise/no-code-recomposing-enterprise.md ---
# **No-code Recomposing the Enterprise Anew**
The global pandemic put digital transformation at the top of the corporate agenda: Plans were drawn out, consultants were hired and fancy press releases were issued. But the success rate for digital transformation projects in general turned out to be [less than 30 percent](https://www.zdnet.com/article/digital-transformation-is-hot-the-success-rates-are-not-says-bcg-data/) and the figures even dipped to [as low as 4 percent](https://www.mckinsey.com/~/media/McKinsey/Business%20Functions/Organization/Our%20Insights/Unlocking%20success%20in%20digital%20transformations/Unlocking-success-in-digital-transformations.ashx) in some traditional industries. Among the reasons for this failure are a lack of strategic planning, which leaves businesses without a clue as to where to start, absence of clear goals and key performance indicators, costs involved in digital transformation, which deter decision makers, and the perceived uncertainty associated with the whole process, which could be causing resistance within the workforce.
Fortunately, this doesn’t mean that such organizations are completely doomed. The composable enterprise concept shows a way out for those companies that find a wholesale digital transformation undesirable or infeasible. Migrating parts of the monolithic system into the cloud would be a good first step towards achieving composability. Then, a [microservices architecture](https://nonamesecurity.com/learn/what-are-microservices/) and APIs make sure that your back end is composable. In this kind of an arrangement, the capabilities of the monolithic system is broken down into smaller components in the form of services and deployed on a microservices architecture. A citizen developer can pick and choose from among these services, and by having the chosen services talk to each other via APIs, compose workflows that will fit the tasks at hand. This sorts out the back end part nicely.
However, if the aim is to ensure faster product development, a composable back end alone will not cut it. The UI and front end must be composable, too. No-code platforms are tailor-made for this job as they come loaded with many features like reusable components and drag-and-drop capability that facilitate front end modularity.
This was exactly what we had in mind when [Peaka](/) [joined forces](https://twitter.com/peakacom/status/1441029123967696900) with Prime to provide Peaka users with PrimeBlocks. We believe in the value reusable components offer because they spare the users the effort needed to reinvent the wheel—it makes no sense to spend time and money to devise a solution from the scratch when there are tried-and-tested solutions available and packaged in the form of building blocks. For no-coders coming from a non-technical background, this partnership will be providing ready-made, editable templates with themes that can be updated as the user sees fit. This will significantly expedite the app building process for no-coders.
However, it is the users with a coding background who we think will appreciate the immense value the Peaka-Prime partnership will deliver. Normally, Prime users would have to write code and use PrimeReact library to build apps. Not anymore. Peaka renders all Prime components and blocks readily accessible and integrates them into Peaka’s drag-and-drop visual designer, thus eliminating the need to code to leverage PrimeBlocks.
The composable enterprise will be an organization that has made no-code an integral part of its operations and takes advantage of the no-code capabilities to gradually replace its legacy system. We believe that no-code is the shortest route to a [scalable, service-oriented and self-service](https://www.mulesoft.com/ty/wp/rise-composable-enterprise) organization, and by [bringing PrimeBlocks into the no-code world](https://twitter.com/cagataycivici/status/1441000749291409412), we are putting our money where our mouth is.
--- START: blog/no-code-shadow-it/no-code-shadow-it.md ---
# **No-code Casting Light on Shadow IT**
Having [previously](/blog/no-code-pays-down-tech-debt/) analyzed how no-code platforms can help organizations pay down technical debt, we thought it would serve well to spend some time on a particular cause of technical debt and the potential remedies for it: Shadow IT. Let’s take a deep dive into this concept, laying out its causes, associated risks and the way to tackle it.
## **1 - What is shadow IT?**
Shadow IT refers to any software, application or device used without the control and approval of the in-house IT department. It is a source of constant concern for organizations, and lack of a strategy on how to contain it could result in data security issues and waste of resources at later stages.
## **2 - What causes shadow IT?**
Shadow IT is a result of real needs: It was always there since the moment employees started using software programs and apps without the sanction of the IT departments. Its accelerated growth recently, however, stems from a few changes that have been in place in the last few years:
**The need on the part of employees to increase productivity and efficiency:** In an increasingly competitive work environment, employees feel the need to tap into the capabilities of apps and various tools for productivity gains and agility. Think about all the apps we use daily: Messaging tools like Slack or online data storage platforms such as Dropbox or apps like Calendly that we use to organize our day. Nobody is asking for the IT department’s blessing before starting to use them and this creates a lot of risks for an organization. [Bring-your-own-device](https://www.ricoh-usa.com/en/insights/articles/what-is-shadow-it-the-risks-costs-benefits) (BYOD) practices, which aim to make employees more comfortable by allowing them to keep working on their personal devices, can be another source of shadow IT. The IT department has no way of containing the risks caused by such practices simply because it isn’t aware of what’s going on. Nevertheless, as these examples illustrate, the concept of shadow IT, despite sounding quite sinister, is most of the time a result of well-intentioned actions. Nobody is using these tools to undermine the organizations they are working for; these are just means to make professional life a little bit easier. The resultant risks have to be managed, though.
**The incapability of the IT department to satisfy the demand for its services:** A recent survey done by [Tonkean](https://go.tonkean.com/State_of_BizOps_2021_Report_LP.html) gives us a clear picture of the challenge IT departments are facing: Almost a quarter of the employees responding to the survey expressed their dissatisfaction with the current technology stack at their disposal and nearly half of them complained about not having much access to IT/engineering, with around one-fifth claiming to have no access at all.
According to the Tonkean survey, 82 percent of the IT staff think that their organization is using too many apps, implying that they don’t agree with the way things are going with respect to shadow IT. In a situation where non-IT personnel feel underserved and IT can not or is not willing to satisfy the demand, something’s gotta give. People simply take matters into their own hands and let IT deal with the consequences.
**Business units rising to the occasion and starting to call the shots:** With digital transformation gaining pace, IT departments proved incapable of conducting day-to-day tasks and leading the digital transformation effort at the same time. As a result, individual [business units](https://www.snowsoftware.com/blog/what-ever-happened-shadow-it) have in the last few years come to make purchasing decisions on their own. IT departments are no longer the sole decision-makers on IT-related issues, which has to bring about a change in the way these departments operate.
## **3 - What are the risks associated with shadow IT?**
**Data security issues:** [File sharing and data storage](https://track.g2.com/resources/shadow-it) apps not only increase shadow IT but also are particularly vulnerable to data leaks. The apps you use at work and any personal device deployed for work purposes outside the supervision of the IT department compound the risk of data leaks and breaches, two of the nightmare scenarios for any organization. Having no knowledge of the apps and software programs being used in an organization, the IT department cannot ensure that they are up-to-date and necessary security patches are installed. This increases the likelihood of a data breach and the price of such an incident is always substantial in terms of financial losses, reputational damage incurred and legal consequences that might arise. [IBM](https://www.ibm.com/security/data-breach) calculates the average cost of a single data breach at $3.86 million.
**Undermining of collaboration:** Different apps, tools and output formats [may stifle](https://track.g2.com/resources/shadow-it) collaboration among different teams. Aggregating and interpreting data from different work stations can turn into a real hassle, causing unnecessary waste of time and effort.
**Inefficient use of resources:** Everest Group [has found out](https://www.cio.com/article/3188726/how-to-eliminate-enterprise-shadow-it.html) that shadow IT makes up 50 percent or more of IT spending. Not all of this amount is money well-spent, though: Shadow IT entails employees using different tools for the same tasks, which bring about duplicate spending. Moreover, many software licenses are purchased and forgotten, never to be used again.
## **4 - What needs to be done to tackle shadow IT?**
Shadow IT cannot be eliminated completely. Because it results from real needs of employees, its complete elimination, even if it were possible, would mean depriving employees of tools that keep them productive and make them feel empowered and motivated. Total IT control over the technology stack of a company is no longer a realistic goal. IT departments should assume more of a consultant or supervisor role setting guidelines, establishing guardrails and overseeing the implementation of a holistic strategy. Their aim should be to try and mitigate the risks associated with shadow IT while offering the employees safe platforms where they can develop their own solutions for problems.
Low-code and no-code platforms fit the bill for a wide range of use cases here. Coming with built-in industry-best security practices and enabling safe integrations, these platforms can help eliminate risks associated with shadow IT. Once an audit of the app inventory at an organization is conducted, the next step should be purging redundant and compromised apps. A no-code platform handpicked by the IT department can then be used to create apps that can replace the purged ones. The resultant technology stack will be leaner, much more secure and cohesive while still prioritizing employee empowerment and productivity. What’s there not to like?
--- START: blog/no-code-templates-competitive-edge/no-code-templates-competitive-edge.md ---
# **No-code Templates: A Potential Source of Competitive Edge?**
A product is more than the sum of its features. It is the whole sum of the philosophy behind it, its community, documentation, and customer support provided. Great software products today are increasingly defined by the ecosystems built around them. That’s because you can’t beat your competitors based on features alone—great platforms capitalize on [network effects](https://medium.com/lightspeed-venture-partners/product-innovation-is-not-enough-to-beat-a-competitors-network-effects-700c78942e64) to enjoy exponential growth.
Our CEO Mustafa Sakalsız recently [dwelled on](/blog/customize-complement-extend-software/) the reasons behind the success of Salesforce and SAP. Sakalsız concluded that these brands owed their success to being development platforms rather than mere software products. A platform is not merely a technology or a product; it is a “[strategy to mobilize and empower an ecosystem.](https://stories.platformdesigntoolkit.com/launching-platforms-growth-hacking-network-effects-a38f8ad0458b)” For a platform to mobilize an entire ecosystem of users, it needs to address a major pain point that they have. It should become the go-to tool for solving that particular pain and fit users’ needs like a glove. Products that people cannot make theirs do not form habits. Customization is how you make a product your own.
There were two prerequisites to building an ecosystem around your product until very recently:
+ Coding skills
+ A product vision based on a profound understanding of customer needs and different use cases
The coding part, as tricky as it might have been, was still doable. However, the ability to define all the possible use cases and the ways to address them were unattainable goals right from the start.
For that reason, it is impossible to design and bake into a platform sustainable, infinite growth at the conception stage. There is no way of accounting for all the customer needs a platform will run into in the future, and keep expanding the customer base by fulfilling all of them. Wary of the difficulty of this challenge, most platforms focus on a small part of the market whose needs they can understand and serve, settling for much less of a market share than they could aim for.
There is another way, though. Opening an API and letting customers modify the platform according to their needs is the most surefire way of nailing the product-market fit. Instead of wasting your time making baseless assumptions about what your customers want and need, opening the platform to them and letting them devise the solutions for their problems ensures customer success.
However, customization should not be solely the customers’ responsibility. Companies can guide and inspire these efforts by publishing no-code templates. No-code templates solve two problems at once: On the one hand, they negate the need for coding skills required for building an ecosystem around a product, and on the other hand, they help build and nurture that ecosystem by turning users into active participants who create value for everyone involved. No-code templates can be a great means of disseminating and sharing knowledge among stakeholders with similar needs.
Contributions from a community using a particular platform can trigger indirect network effects and unlock synergies for members. Users can integrate their solutions and solve even bigger problems than what the creators of the platform thought would be possible. These indirect network effects not only draw in more customers, but also immunize the product against the competition, for network effects are known to be much more [difficult to overcome](https://medium.com/lightspeed-venture-partners/product-innovation-is-not-enough-to-beat-a-competitors-network-effects-700c78942e64) than a feature-based competitive edge.
A flexible platform that lends itself to customization and serves a diverse range of needs—this is where people want to be. With no-code templates, you are closer than ever to building a product that can spawn an entire ecosystem around itself.
--- START: blog/no-code-templates-time-portals/no-code-templates-time-portals.md ---
# **No-code Templates as Your Time Portals**
Startup founders are no ordinary people, as we have recently discovered in our review of the book [*Founder’s FAQ*](/blog/book-review-founders-faq/). Their courage and the will to make a change should be commended regardless of the result. Mike Maples, co-founder at the investing firm Floodgate and renowned for his eye for startups with potential, [attributes a mission](https://www.joincolossus.com/episodes/61719/maples-a-playbook-for-startups?tab=transcript) to startups and founders. Maples thinks that startups should not just offer incremental change but radical change so that they can transform the way people think and act. He argues that companies like Amazon, Tesla, and Spacex, which only entered our lives after the internet revolution and thus are fairly young, are the most powerful engines of change today. That’s why he urges entrepreneurs to go for the big upside projects because he pictures them as agents of change. Entrepreneurs, to Maples, are people who can envisage a future and turn that vision into reality. That’s why he calls them “time travelers.” According to Maples, entrepreneurs can see further into the future than regular people can do, and they build businesses that can bring that future to the present.
This “entrepreneurs-as-time-travelers” concept ties in well with the vision Peaka has for no-code templates. We see no-code templates as a potent means of know-how delivery that punches a hole through time. Each template is a pre-packaged bundle of UI, UX and data modeling know-how that accrues from the software company to the customers. No-code templates take the customers to their desired state of success right away, without having to spend months or even years to accumulate that know-how. If visionary startup founders are time travelers, we think it would be fair to call no-code templates “time portals” in the same vein.
No-code templates make it easier for customers to customize a product for their own needs and extend it, facilitating the growth of an ecosystem around the product. The best example of such an ecosystem would be the [TM Forum](https://www.tmforum.org/), the global association of service providers in the telecommunications industry. TM Forum was founded with an aim to solve a very real pain point for service providers: Lack of standardization in telecom software. Major American service providers like Verizon, Sprint, and AT&T were pouring millions into software at the beginning of the millennium. The lower tier operators under these companies, too, needed CRM, billing, and support software. To avoid redundant effort in software production, save money, and standardize the operating procedures, these companies agreed on a set of frameworks: eTOM (Enhanced Telecom Operation Map), SID (Shared Information Data), and TAM (Telecom Application Map).
[eTOM](https://www.tmforum.org/business-process-framework/) (renamed as Business Process Framework in 2013) is the result of efforts to determine the processes a telecom service provider would need. It is akin to building a telecom service providers’ glossary, detailing the processes a typical business workflow entails and what they map to. Whether it is order placement, pricing offer or billing, eTOM precisely defines what stakeholders should understand from each concept, and thus creates a common language each stakeholder can understand.
[SID](https://www.tmforum.org/information-framework-sid/) clarifies the kind of data model a telecom operator needs. It standardizes the data entities used in the industry. SID ensures that there is no doubt as to what a “customer” is, or what a command like “retrieve customer data” refers to.
[TAM](https://www.tmforum.org/application-framework/) describes how a CSP (Communication Service Provider) can map to its eTOM a third-party application that carries out a specified set of processes manipulating a specified set of data.
Today, these three frameworks have become a part of the [Open Digital Architecture](https://www.tmforum.org/oda/) (ODA), which provides a CSP with a composable, cloud-based blueprint. Thanks to this blueprint, CSPs no longer have to reinvent the wheel at every step of their operations and spend money to develop solutions when there are tried-and-tested solutions in place. This is as close to creating economies of scale in the service sector as you can get.
The three TM Forum frameworks promote interoperability among different stakeholders at different tiers and disseminate know-how across the industry. In that regard, they are serving as time portals and empowering CSPs to become time travelers, accelerating the growth of individual players without the need to invest in lengthy R & D processes. The whole industry benefits from the quick expansion of the ecosystem.
Any startup adventure is a race against time. Money is scarce and dwindling, and the window of opportunity—if there is any— is small. The TM Forum frameworks illustrate how the injection of know-how into a startup can turbocharge growth as it runs out of runway. These frameworks are the perfect example denoting what you can achieve if you heed Mike Maples’s advice to think big and leverage well-thought-out blueprints or templates to build a resilient ecosystem around your product. We envision Peaka’s no-code templates to do the same for our customers: Solve their problems quickly and teleport them to a future state of success.
--- START: blog/no-code-to-democratize-ai/no-code-to-democratize-ai.md ---
# **Can No-code Democratize AI, too?**
Artificial intelligence (AI) has remained somewhat of an enigma in the tech industry since its inception. It was initially touted as the next breakthrough that would take humanity into a new age. However, the evidence of those transformative capabilities has been scant so far.
The real-life experience with AI has produced much more modest results than was promised at the beginning. For example, coders using AI pair programming tools such as [Open AI Codex or Github Copilot](/blog/ai-pair-programmers-future-copilots-nocode/) realized that these tools were far from taking over developer duties. They provided broken code; their outputs were sometimes biased, discriminatory, and offensive; and vetting their suggestions actually slowed down the coding process.
AI might have fallen short of the initial hype, but there are industries where it has made a difference. The finance industry has been at the forefront of AI adoption.
## AI in the finance industry
Banks have been making heavy use of a particular technology lately: [Natural language processing](https://en.wikipedia.org/wiki/Natural_language_processing) (NLP). This technology helps users create chatbots that can understand human language and generate replies as a human would. Thanks to these chatbots, banks can provide customers with personalized service 24/7, serve more customers without increasing their headcount, and improve their bottom line.
Machine learning models, too, made their way into the technology stack of financial institutions. These tools help decision-makers make better decisions regarding [lending money and managing risks.](https://builtin.com/artificial-intelligence/ai-finance-banking-applications-companies)
Another area where AI has proved effective for financial institutions is security. AI is great at pattern recognition, and it can be trained to recognize [irregularities in financial transactions.](https://www.insiderintelligence.com/insights/ai-in-finance/) This capability makes it a perfect fit for banks trying to prevent fraud and cyberattacks.
## Two hurdles to overcome
However, in the grand scheme of things, very few industries have been able to adopt AI to the extent that the banking industry has. Despite all the fanfare and buzz surrounding AI, the rollout has been slower than expected. AI integrations currently lag behind projections. [A study commissioned by IBM](https://filecache.mediaroom.com/mr5mr_ibmnewsroom/191468/IBM's%20Global%20AI%20Adoption%20Index%202021_Executive-Summary.pdf) surveyed IT professionals from 5,501 companies around the world and produced insights that shed light on the rate of AI adoption:
+ 43 percent of the respondents said that their companies were exploring AI,
+ Only 31 percent reported having already deployed AI at their companies.
Introducing AI into an organization is no easy task, apparently. The IT professionals responding to the above mentioned IBM study cite two particular challenges that slow down the AI rollout:
+ Limited availability of AI expertise (39 percent)
+ Lack of tools or platforms for developing AI models (28 percent)
These two barriers to AI adoption illustrate how similar the current state of the AI domain is to that of app development a few years back. The developer shortage that plagued app development is, this time, replaced by the scarcity of experts with degrees in data science, computer science, or statistics. The problem may be all the more severe today because some AI projects require leadership from experts with Ph.D. degrees, who are not easy to find.
Enterprises are throwing big bucks at AI experts to lure them and carry on with their projects. A solution to the second challenge, the lack of AI-specific tools or platforms, can actually help with the scarcity of AI experts. Once capable AI platforms are introduced, companies (especially startups and SMBs) will be able to raise their own “citizen AI engineers” in the mold of citizen developers. Instead of relying on off-the-shelf solutions or chasing overqualified experts, these companies will be able to develop their own models, test their ideas, and find the best solutions for their use cases.
## No-code can do it again
What fueled the interest in no-code/low-code app development platforms was the shortage of developers at a time when digitalization was going on at full speed, and software was eating the world. Enterprises were offering talented developers high salaries and perks, effectively pricing SMBs and startups out of the job market. No-code platforms filled a void here, helping companies develop apps without having to hire expensive coders or outsource the development to third parties.
The AI domain is slated to go through a similar experience soon if it is to live up to the hype surrounding it. AI should become affordable for and accessible to the masses to become the transformative technology everyone hopes it can be. The prime candidate for this job today is the no-code technology. Just like it has helped bridge the gap between the supply of and the demand for developers, no-code can fill in for data scientists and enable smaller players in the market to benefit from AI technology.
The idea of no-code AI helps us realize once again what the no-code movement is all about: Democratization of software usage and empowering the masses. It was about democratizing app development and web design for the last few years. Now the focus is on democratizing AI deployment. With software becoming indispensable to how people and businesses operate, we need to find a way to multiply the number of people that can create software and deploy AI. Having proven its mettle in app development, no-code is the most promising way to do that.
--- START: blog/no-code-to-embellish-enrich-saas/no-code-to-embellish-enrich-saas.md ---
   Link copied
Table of Contents
* [No-code Helps Enrich SaaS Products without Rocking the Boat](https://www.peaka.com/blog/no-code-to-embellish-enrich-saas/#no-code-helps-enrich-saas-products-without-rocking-the-boat)
[Home](/) / [Blog](/blog) / No-code Helps Enrich SaaS Products without Rocking the Boat
[No-code](https://www.peaka.com/category/no-code/) [Innovation](https://www.peaka.com/category/innovation/)
Published on September 07, 2021
3 min read
No-code Helps Enrich SaaS Products without Rocking the Boat


Bruce McFadden Peaka / Seasoned Taskmaster
**No-code Helps Enrich SaaS Products without Rocking the Boat**[](#no-code-helps-enrich-saas-products-without-rocking-the-boat)
===============================================================================================================================
Software delivered to us over the internet via a web browser or a mobile app has been a revelation. It has transformed the industry, made way for new tech giants to emerge and empowered people to realize their previously stashed-aside business ideas. Thanks to the SaaS concept, people are developing their long-forgotten [side projects](/blog/micro-saas-attainable-dream/), building new ones and monetizing their ideas.
Not everything in the product life cycle goes according to the plans of the product team, though. As we had previously [touched upon](/blog/no-code-ends-maintenance-drama/), the product gains a life of its own after its launch. People discover new uses that you never had envisioned for your product and these new use cases bring about a need for complimentary features. These features might be totally unrelated to your core value proposition, and thus not part of your product road map. However, your customer might feel that they are exactly what he needs in order to add downstream and upstream capabilities to the product and create an end-to-end user experience.
Situations like these put tech startups in a bind. On the one hand, you want to keep your customers happy. You want your product to be able to market itself on its own and the way to do is to have satisfied customers who will spread the word about the exceptional user experience you provide. On the other hand, resources are scarce. Your resources, as a startup, is probably even scarcer. The time and effort you will spend on such features will have to come from somewhere else. That place has to be the more essential tasks for your business operation. Any feature should go through stages of wire framing, prototyping and development before getting shipped. It doesn’t end there, however. There is the maintenance stage, which could go on for years—and all this for a feature you did not think was essential in the first place.
No-code tools offer a way out of this kind of dilemma. They are great for adding to your products features that your customers demand, although they may not be on your roadmap. These are features for which you are reluctant to allocate resources to develop, but it is only natural that you will want to avoid risk losing your customers over minor stuff like that.
With no-code tools, you don’t have to go through a lengthy process to wireframe, prototype and ship the feature. It all happens via a visual interface in a short time, without having to commit precious resources for long. The platform also takes care of the maintenance tasks, saving you from the burden of maintaining a feature that is not central to your business. Moreover, you get to keep your customers happy—it is the closest you get to having your cake and eating it, too. Avoiding a PR backlash without straying from your main business goals: What is there not to like?
Your biweekly inspiration delivered to your inbox
Join our newsletter for news, tips, and blog posts on anything data integration!
Subscribe
 Please fill out this field
 Thank you! You have been subscribed.
Similar posts you might be interested in
[](https://www.peaka.com/blog/saas-ideal-customer-profile/)
No-code Innovation September 07, 2021
[How to Create an Ideal Customer Profile for SaaS Businesses](https://www.peaka.com/blog/saas-ideal-customer-profile/)
How do you create an ideal customer profile (ICP)? Why should a SaaS company create one? How does Peaka help you hone your ICP? Find out in this blog post.

Bruce McFadden Peaka / Seasoned Taskmaster
[](https://www.peaka.com/blog/account-based-marketing-saas/)
No-code Innovation September 07, 2021
[How to Create an Account-Based SaaS Marketing Strategy](https://www.peaka.com/blog/account-based-marketing-saas/)
Here is everything a SaaS founder needs to know about account-based marketing, how it works, its benefits, and how Peaka can help ABM teams implement it.

Eugene van Ost Peaka / IT Soothsayer
[](https://www.peaka.com/blog/top-saas-revenue-metrics/)
No-code Innovation September 07, 2021
[Top 6 SaaS Revenue Metrics to Track in 2026](https://www.peaka.com/blog/top-saas-revenue-metrics/)
A deep dive into SaaS revenue metrics, four data integration tools to track SaaS revenue, and benefits of blending your revenue data with your CRM data.

M. Çınar Büyükakça Peaka / Prolific Polemicist
 
Begin your journey today
Start your 14-day free trial to explore Peaka!
Get started for free
Enjoying this article?
Subscribe to our monthly newsletter for insights on ServiceTitan data integration and KPI reporting.


First Name
Last Name
Email
Company Name
Phone Number (optional)
Subscribe
You can unsubscribe anytime. For more details review our [Privacy Policy](https://www.peaka.com/privacy-policy/).
--- START: blog/no-code-to-embellish-enrich-saas./no-code-to-embellish-enrich-saas..md ---
# **No-code Helps Enrich SaaS Products without Rocking the Boat**
Software delivered to us over the internet via a web browser or a mobile app has been a revelation. It has transformed the industry, made way for new tech giants to emerge and empowered people to realize their previously stashed-aside business ideas. Thanks to the SaaS concept, people are developing their long-forgotten [side projects](/blog/micro-saas-attainable-dream/), building new ones and monetizing their ideas.
Not everything in the product life cycle goes according to the plans of the product team, though. As we had previously [touched upon](/blog/no-code-ends-maintenance-drama/), the product gains a life of its own after its launch. People discover new uses that you never had envisioned for your product and these new use cases bring about a need for complimentary features. These features might be totally unrelated to your core value proposition, and thus not part of your product road map. However, your customer might feel that they are exactly what he needs in order to add downstream and upstream capabilities to the product and create an end-to-end user experience.
Situations like these put tech startups in a bind. On the one hand, you want to keep your customers happy. You want your product to be able to market itself on its own and the way to do is to have satisfied customers who will spread the word about the exceptional user experience you provide. On the other hand, resources are scarce. Your resources, as a startup, is probably even scarcer. The time and effort you will spend on such features will have to come from somewhere else. That place has to be the more essential tasks for your business operation. Any feature should go through stages of wire framing, prototyping and development before getting shipped. It doesn’t end there, however. There is the maintenance stage, which could go on for years—and all this for a feature you did not think was essential in the first place.
No-code tools offer a way out of this kind of dilemma. They are great for adding to your products features that your customers demand, although they may not be on your roadmap. These are features for which you are reluctant to allocate resources to develop, but it is only natural that you will want to avoid risk losing your customers over minor stuff like that.
With no-code tools, you don’t have to go through a lengthy process to wireframe, prototype and ship the feature. It all happens via a visual interface in a short time, without having to commit precious resources for long. The platform also takes care of the maintenance tasks, saving you from the burden of maintaining a feature that is not central to your business. Moreover, you get to keep your customers happy—it is the closest you get to having your cake and eating it, too. Avoiding a PR backlash without straying from your main business goals: What is there not to like?
--- START: blog/no-coder-personas/no-coder-personas.md ---
# **4 More No-Coder Personas to Pick as Your Target Audience**
With the way the no-code market is booming at the breathtaking pace that it is, the no-code stage keeps getting more crowded. More platforms are added to the mix every day, catering to an ever-larger variety of user personas. The Peaka team knows particularly well how challenging it can be to keep tabs on the community, which continuously expands to involve more people from different backgrounds. It can at times feel like you are part of a Russian novel, where new characters with overly-long names enter the plot as some others whose names you have just managed to memorize vanish, only to show up later.
Helen Ryles from [Makerpad](https://www.makerpad.co) gave a [great intro](https://www.makerpad.co/blog/which-type-of-no-coder-are-you) into the various types of personalities in our community some time ago. These user personas matter because they are at the heart of the marketing efforts of no-code companies: While drawing up sales and marketing strategies, these companies focus on a target audience and try to understand its needs in order to achieve the product-market fit.
We thought it would be interesting if we picked up where she left off and gave you our own playful take on the no-coder community—different personas, their motivations, and the tools we can see them using.
## **Practical Genius**
{{ resize_image(path="../static/assets/images/blog-images/no-coder-personas/a1-practical-genius.png", width=759, height=400, op='fit_width', alt="Practical genius persona") }}
These people are the survivors. Among them are members of older generations: Baby boomers, Gen Xers, and Yers. Some of them have 20 or even 30 years of experience under their belts and sound business plans—they see a void in the market that they think they will fill. However, they did not gain this level of consciousness overnight. Practical geniuses probably spent years chasing dreams, setting up different businesses, failing, getting up on their feet only to fail once again. This determination and perseverance are the reasons they garner a lot of respect from people, especially in the United States. Now that they understand what it takes to be successful, they are looking for ways to improve their chances.
Practical geniuses are startup founders, small business owners, or serial entrepreneurs. They are highly motivated: Whether it is to grow their business or attract investment, their mindset is completely homed in on finally making it this time. They understand how short their runways are and how scarce the resources at their disposal might turn out to be. That's why no-code can be a godsend for practical geniuses. They realize that a few thousand dollars per month's worth of savings that would otherwise be paid as salary to a developer on their payroll can make the difference between success and failure.
No-code platforms such as [Integromat](https://www.integromat.com/en) or [Webflow](https://webflow.com) are good fits for these people. Such platforms can be utilized to develop proofs of concepts, build MVPs, and automate certain workflows. As the needs and requirements get more complex, a more potent tool like [Peaka](/) would be a better choice for scaling.
## **Frontline Warrior**
{{ resize_image(path="../static/assets/images/blog-images/no-coder-personas/a2-frontline-warrior.png", width=759, height=400, op='fit_width', alt="Frontline warrior persona") }}
These are foot soldiers who feel the pressure in the heat of a battle and bear the brunt of an attack. They fight at the forefront, most of the time hung out to dry. They might ask for help in the form of supplies or reinforcements, but there is no guarantee that they will get any on time.
Modern enterprises employ thousands of these frontline warriors. These are domain experts with a deep knowledge of their fields. They are motivated to get things done and further their careers to become business leaders one day, but the roadblocks they run into make maintaining that motivation really difficult. They are masters of spreadsheet tools like Excel.
Frontline warriors are always pressed for time—they have meetings to attend, product development goals to achieve, reports to write on products or services offered, and deadlines to meet. When they ask the IT department for help, they usually get very little because the IT department is already overwhelmed by similar requests.
No-code tools are great for such people, who are tech-savvy enough to fend for themselves. They are only a few steps away from becoming citizen developers, who are business professionals capable of using no-code platforms to develop business tools in their own domains of expertise. Both [Airtable](https://airtable.com) and [Appsheet](https://www.appsheet.com) are good choices for frontline warriors. These two can help citizen developers build applications, automate workflows and make integrations with the existing systems.
## **Knight-errant**
{{ resize_image(path="../static/assets/images/blog-images/no-coder-personas/a3-knight-errant.png", width=759, height=400, op='fit_width', alt="Knight-errant persona") }}
A knight-errant (literally 'wandering knight') is a character you must have come across in many medieval tales. Traveling from one town to another in pursuit of adventure, fame, and romance, this idealistic character would always be in search of a noble cause to devote his life to. He would live to right wrongs, beat the bad guys, save damsels in distress (and even slay a dragon for you if you asked him nicely), but never settle down. Think of him as a more competent Don Quixote—without the hallucinations, of course.
The knights-errant of real life are none other than the freelancers of the software industry: Moving from one gig to another, working at their own pace, looking for better opportunities but never making long-term commitments, or looking for a full-time job, if at all. These people put their developer skills in use to solve other people's problems and make their dreams come true. They are lifesavers for people who lack the technical skills to build a business or grow an existing one. Freelancers are motivated by the desire to monetize their developer skills and extend their reach to more customers.
These modern knights-errant work solo or as part of an agency. No-code platforms help them expand their customer base, find new opportunities that can better utilize their skills, and ship more apps in a shorter time. Coming from coding backgrounds, these freelancers are in a better position to leverage more capable tools like Peaka or [Bildr](https://www.bildr.com). They can take advantage of visual design capabilities of these platforms and inject code whenever they feel the need.
## **Young Grasshopper**
{{ resize_image(path="../static/assets/images/blog-images/no-coder-personas/a4-young-grasshopper.png", width=759, height=400, op='fit_width', center='true', alt="Young grasshopper persona") }}
"Patience, young grasshopper!" goes the famous internet meme. It is a reference to a quote from the 1970s TV series Kung Fu and probably a piece of advice the young grasshoppers of today, the Gen Zers, could use.
The young grasshoppers of today are at their best on social media—they are digital natives. What motivates them is a drive to express themselves and interact with their environment. Their learning process differs from that of the previous generation, too: They like to spend time experimenting with different stuff and enjoy discovering new things by themselves through trial and error.
Some young grasshoppers are young entrepreneurs starting a business or running successful tech companies in their teens already. They are learning the ropes and trying to find their way in business life while maintaining a work-life balance. However, their impatience can, at times, work against them. They are quick to take an interest in a subject, but they lose their interest just as quickly, unable to maintain their concentration for long. Because of this, their ideas rarely turn into finished products. Quick results are key to keeping these young people motivated.
A no-code platform like [Glide](https://www.glideapps.com), where this new breed of young grasshoppers can put their creativity in action and see the results in a short time, suits their needs and habits. For the more tech-savvy among them, Peaka is perfect. That’s because Peaka goes one step beyond offering a visual designer and makes it possible for youngsters to turn their ideas into powerful web apps.
## **Conclusion**
This wraps up four common user personas showing interest in no-code tools. It is highly likely that there will be even more complex no-code personas in the future as this particular technology finds new uses in new homes. We promise to keep Peaka evolving so that everyone can be a no-coder one day.
--- START: blog/non-technical-founder-no-code/non-technical-founder-no-code.md ---
# **Not Waiting is the Biggest Asset for a Non-Technical Founder**
Ever since startups replaced finance jobs as a top target for status seekers, volumes of anxiety-riddled text continue
to spill out onto the internet in search of the elusive technical co-founder.
To be fair, practical advice from Y Combinator since its inception hasn't bothered to shelter people from this notion
either. "If you can't convince at least one person to build this thing," the thinking goes, "then what does this say
about your chances of success?"
As a result, back when you wouldn't be shot on the spot for suggesting it, people who felt they lacked the resources
would be encouraged to "learn how to code" (time) or "hire an external team" (money). Especially those wanting to build
apps or SaaS businesses.
And for someone trying to build something of value, navigating your way around this stage could be a daunting experience.
So has anything changed in the past few years? Actually, yes. It has.
But first just take a step back and ask yourself: "What would I need in order to convince someone to join me, something
that would also help me even if I didn't end up convincing anyone?"
Two things, maybe:
1. The ability to hustle.
2. A visible demonstration of this ability.
Of course, the most impressive hustle here would be to just build the thing yourself.
"But wait," you say, "I thought I wasn't going to learn how to code?"
That just so happens to be one of the things that has changed recently. These days, with all these shiny new no-code
platforms, it turns out you can actually build your app or SaaS business without learning how to code.
The added bonus here is that you will probably know more about these platforms than your potential technical co-founders.
You have to remember, these people use code to build these things for a living. Why would they look into whether you can
actually build them without writing any code? As it turns out, "it is difficult to get a man to understand something,
when his salary depends on his not understanding it." (Upton Sinclair)
If you do go ahead and build the app and showcase it, you'll find that technical folks will tend be impressed. However
beware, like any magic trick, once they know how it's done they might try to [make light of your methods](https://www.wired.com/story/databases-coding-real-programming-myth/).
At the end of the day though, you will have shown them something that they never really considered before, mostly
because they never really needed to think about it all that much to begin with. Instead of having to convince them with
words, you will have exceeded their expectations with accomplishments they normally associate with software developers.
Going forward, they will no longer question your ability to get things done.
## **You've Come This Far, Why Stop?**
And now that you have actually built the app itself, you will of course realize that searching for a technical
co-founder doesn't have the critical urgency it once did. After all, now there is nothing preventing you from inviting
your users to use your app and seeing whether they like what you have built.
At this point, to many people, it will look like you've done something that doesn't scale. That's not necessarily a bad
thing. As it happens, "do things that don't scale" is another one of those useful but counterintuitive sounding Paul
Graham and Y Combinator mantras. The point is to do whatever it takes to get your early users because they will be the
ones on the street spreading the word the fastest -- more than any other group of users that will come to you
afterwards.
Several years ago, someone on Hacker News asked for real world examples of doing things that don't scale. The top
comment was from the founders of [moonlightwork](https://www.moonlightwork.com/), a tech talent agency (itself later
acquired by a YC startup). They described their process of manually stringing together a bunch of no-code tools in order
to operate their service, adding that they were able to reach $100K of monthly gross sales with this ad-hoc no-code
stack.
That's pretty good, especially since they considered what they were building to be a prototype.
Nowadays though, a different kind of wager is being placed on this generation of no-code platforms.
The bet is this: no-code will scale.
Whether this bet will be won, or whether a SaaS with $100K monthly gross sales should be considered a "prototype" may
be up for debate, but to you as a non-technical founder one thing should be abundantly clear:
There is no point in waiting anymore.
--- START: blog/online-petition-template/online-petition-template.md ---
# **Lead the Change with the CivicRebel Online Petition Template**
It is true that the internet fell short of the ideals it was expected to achieve in the last decade of the twentieth century. The egalitarian medium of uncensored and uninhibited transfer of knowledge never came to be. The emergence of social media platforms in the second half of the 2000s put an end to those dreams for good. The internet turned into a collection of fenced-off spaces where platform owners monopolized and monetized data at the expense of users' privacy.
It was not all doom and gloom, though. If nothing else, the internet connected people like it was never possible before. One area where it had a profound impact was social activism. The internet brought down the cost of activism by letting people organize and mobilize around common causes regardless of their location. In the past, affecting change in the system was impossibly difficult: You needed to bring together a critical mass of like-minded people, hold rallies, engage community leaders, try to win support from business people and celebrities, and make an effort to grab the attention of authorities who had the power to initiate change. Reaching out to politicians, providing evidence of popular support for your cause, and getting them to champion your initiative were no easy tasks. Regular citizens rarely enjoy such access, which most of the time is the privilege of a select group of wealthy, influential people.
[Change.org](http://change.org/) is the most successful one among a plethora of online petition platforms. The secret sauce for Change.org's success was its simplicity. Ben Rattray, the CEO of Change.org, thinks the platform did what Twitter did so well—responding to a human need in the simplest way possible. "Simplicity is a feature, not a bug," [he says.](https://medium.com/startup-grind/change-org-ceo-ben-rattray-when-serving-130-million-users-simplicity-is-a-feature-not-a-bug-6673453f853e) This formula helped Change.org reach out to sections of society [lacking a voice,](https://www.parliament.uk/globalassets/documents/speaker/digital-democracy/Digi067Change.pdf) like minorities, young people, and people with disabilities. This kind of online social activism garnered a lot of criticism on the grounds that it required very little effort and commitment from the participants and was labeled as [slacktivism.](https://en.wikipedia.org/wiki/Slacktivism) However, just like social media platforms proved their mettle as legitimate channels of information, online petition platforms delivered the results and earned the respect of the public. Here are a few striking examples showing the unlikely success Change.org campaigns achieved:
- The “Preventing Animal Cruelty and Torture (PACT) Act" had been stalled in the U.S Congress due to the opposition of a single representative. Sydney Helfand, a high school student, decided to take action and launched a change.org campaign calling for the U.S. Congress to pass the bill. [More than 850,000 people](https://www.change.org/l/us/victory-a-federal-law-to-protect-our-pets) signed the petition, and the bill was finally signed into law by President Trump in 2019.
- [Pediatric oncology nurse](https://edition.cnn.com/2019/12/22/us/top-petitions-decade-change-trnd/index.html) Liliana Haas thought children battling various types of cancers needed a drug called Vincristine, whose production was announced to be discontinued by Teva Pharmaceuticals. After the launch of a Change.org campaign backed by [more than 214,000 people,](https://www.change.org/p/tell-teva-pharmaceuticals-to-keep-producing-vincristine-to-save-lives-of-children) Teva Pharmaceuticals [agreed to](https://www.change.org/p/tell-teva-pharmaceuticals-to-keep-producing-vincristine-to-save-lives-of-children/responses/42568) resume the production of the drug, verifying the impact of Change.org campaigns.
- 99-year-old veteran British army officer Tom Moore pledged to walk 100 lengths of his garden in a bid to raise £1,000 for the National Health Service in the United Kingdom before his 100th birthday on April 30, 2020. Moore ended up raising £32.79 million. Sonia Wilson started a campaign on Change.org calling for Moore to be awarded a knighthood and won support from [more than 1 million people](https://www.change.org/p/war-hero-tom-moore-aged-99-to-be-knighted-captaintommoore) on Change.org. Thomas Moore was finally knighted by Queen Elizabeth II on July 17, 2020, less than seven months before his death.
Simple acts of leadership can affect meaningful change, as illustrated by the examples above. As part of our recent [template blitz at Peaka](/templates/), we have recently published a new online petition template that can get your petition campaign up and running in no time. The CivicRebel template is infinitely customizable: It lets you create a petition using dynamic forms, add explanations and visuals as you see fit, and put it up for people to sign. The CivicRebel also allows you to set a certain threshold of signatures to be achieved and share your petition on social media for it to go viral.
Just define your cause, create your page, and let the magic happen!
--- START: blog/open-source-and-tech-giants/open-source-and-tech-giants.md ---
# **Why Do Tech Giants Invest in Open-source?**
People have their reasons for pursuing open-source projects. These reasons may range from pure geekery to making a name for themselves as talented coders to monetary motives. However, why profit-seeking enterprises allocate resources to such projects may take some more explaining to do. Let's take a look at the motives behind the corporate interest in open-source projects.
## **Promoting the company and its culture**
Often receiving bad press due to selfish business practices they follow, big tech corporations can take advantage of open-source projects to present themselves to the wider public in a more positive light. Sharing knowledge and expertise with the larger coder community and giving back to them earn tech corporations brownie points with the public. Building a positive image in the eyes of developers can pay off in the long run and give those companies a leg up in [recruiting new talent.](https://www.ycombinator.com/library/56-why-the-best-companies-and-developers-give-away-almost-everything-they-do)
## **Tapping into the global talent pool**
No matter how vast your resources are as a company, you don't always get to hire the best of the best. Some employees have long-term commitments to their respective companies, while others are located in different countries with no interest in relocation or making significant changes to their lives. Open-source projects are a great way of picking the brains of such people. Seeing open-source projects as a challenge, top developers bring their A-game to these projects and add a lot of value for free.
While CVs are good for developers who can talk the talk, open-source projects are where developers that can walk the walk can differentiate themselves. Software companies scouting talent in open-source projects are like kids in a candy store. For tech companies, [open-source code samples](https://www.toptal.com/freelance/in-search-of-the-elite-few-finding-and-hiring-the-best-developers-in-the-industry) are better indicators of coding talent than vanity-filled résumés. Having spotted talent, companies can use open-source projects to vet prospective teammates before making an official job offer. GitHub co-founder [Tom Preston-Werner](https://tom.preston-werner.com/2011/11/22/open-source-everything.html) sums it up nicely:
>*"If you're hiring, the best technical interview possible is the one you don't have to do because the candidate is already kicking ass on one of your open source projects."*
## **Nurturing a community that will embrace future products**
Open-source projects give tech corporations a sound base they can build on. The products developed on top of that base will be compatible with a whole ecosystem of other products and platforms.
During a project, a company connects and interacts with a community, nurturing a bond with them that it can leverage later. People who contribute to a project tend to be more likely to speak positively of it and even become that brand's ambassadors. An extendible ecosystem and a loyal community were Android's two biggest advantages as it vied with iOS for market share. In an ultra-competitive industry, a community with a stake in a product's success can give a company a big boost against the competition.
## **Operating at the cutting edge of the technology**
Open-source projects develop best practices and industry standards so that different companies do not have to [reinvent the wheel](https://opensource.com/life/15/12/why-open-source) at every step. Once somebody comes up with a more efficient way of executing a certain task, it becomes part of the open-source lore. Thanks to this cumulative nature of knowledge, scarce resources can better be channeled to tasks where they will create more added value.
Open-source projects bring together the most talented developers from around the world. These developers offer their expertise, share knowledge, and learn from each other. The result is usually something that tests the limits of technology, broadening the horizons of the whole industry. Whether it is cloud, app deployment, or AI, open-source projects give contributors and onlookers a [glimpse into the future.](https://analyticsindiamag.com/why-do-large-companies-open-source-their-tech/)
## **Final thoughts**
Tech corporations in the past did everything in their power to stop or undermine open-source projects. However, they finally seem to have realized that such projects are a blessing rather than a threat to their businesses. Today, open-source has become an integral part of how the software industry operates. Credit goes to tech leaders who looked for a way to leverage open-source instead of swimming against the current.
--- START: blog/open-source-banking/open-source-banking.md ---
# **Can Open-source Software Revolutionize the Finance Industry?**
Financial institutions have historically been risk-averse with regard to technology. They operate under the constraints imposed by [information security requirements and legal compliance.](https://ubuntu.com/blog/building-the-bank-of-the-future-today) A radical transformation of technological infrastructure is thus quite a scary proposition for a decision-maker at one of these organizations. Banks operate expensive, on-premise monoliths. Abandoning the legacy infrastructure for an open-source one, regardless of the possible rewards, entails many risks during the transition, which few banks would be willing to undertake.
## **Grave risks**
Banks employ huge IT departments to maintain proprietary software programs and shore up security. This model gives the organization complete control over the operating system, infrastructure, and data. Switching over to open-source involves relinquishing some of that control, which banks are reluctant to do for a variety of reasons:
Decision-makers believe that switching to open-source code increases the risk of [data breaches.](https://thestack.technology/open-source-and-the-future-of-banking/)
Using open-source software has been associated with handing over to competitors any competitive advantage a bank has.
Decision-makers do not want to get tangled up in the intricacies of open-source licenses.
Although financial institutions have made piecemeal use of open-source software in the operating system, infrastructure, or database depending on their needs, wholesale adoption of open-source did not happen because of the hesitations of the decision-makers in these organizations.
These concerns were confirmed by a field study commissioned by the [Fintech Open Source Foundation](https://www.linkedin.com/company/finosfoundation/) (FINOS), a non-profit organization founded to promote the “*adoption of open source, open standards, and collaborative software development practices in financial services.*” This worldwide survey was conducted among developers, IT leaders, executive management, security, legal, procurement, and HR. The findings of the survey were gathered in [The 2021 State of Open Source in Financial Services report](https://www.finos.org/hubfs/LFResearch_FINOSSurvey_Report_20211005.pdf), which revealed some interesting points about the corporate attitude toward open source in the finance industry:
+ Although open-source consumption is encouraged throughout organizations, there are rules and restrictions in place that deter employees from contributing code to open-source projects. Only 8 percent of the respondents said that upstream contributions were encouraged in their companies, which is less than a quarter of the average figure in other industries.
+ Concerns about exposing intellectual property and thus losing part of the competitive advantage were limiting factors in open-source use for about 70 percent of the respondents. Around 60 percent agreed that the complexity of open-source licensing played a role in holding back more liberal usage of open-source.
+ DevOps, cloud, and AI/ML are thought to be the top three areas where open-source can make a difference.
## **Enticing rewards**
However, staying away from open-source software is akin to swimming against the tide nowadays. The banking sector has been undergoing a digital transformation for the last few years, and fintech applications are expanding the sector’s reach into the three billion unbanked people worldwide. These huge changes cannot be managed by proprietary software bought off-the-shelf and implemented by the in-house IT department. Adapting to this sea change is only possible if the industry leverages continuous, iterative innovation through open-source code development, to which thousands of developers around the globe consistently contribute.
In addition to promoting continuous innovation, open-source also helps with cost reduction in the banking sector. Thanks to open-source projects, financial organizations do not have to reinvent the wheel whenever they want to launch a new future. Instead, they can take advantage of and build upon proven code in an open-source repository. Using open-source code also lowers license costs significantly, although open-source does not necessarily mean “for free.”
## **Adopting FINOS as the open-source mentor**
Aside from conducting surveys on open-source adoption in the finance industry, FINOS has also assumed a leading role in introducing financial organizations to open-source. Here are a few projects from notable finance companies that open-sourced projects their projects under the guidance of FINOS:
### **Goldman Sachs**
Big players in the finance industry believe that there are efficiencies to be unlocked through standardization of data modeling and management across the industry. These organizations are subject to the same [regulatory frameworks](https://www.linuxfoundation.org/press-release/goldman-sachs-open-sources-its-data-modeling-platform-through-finos/), face [similar challenges](https://www.finos.org/press/goldman-announces-pure-alloy-contribution) in defining data and standardizing the way it is shared, and engage in high-volume daily trading. Solving a problem for one of them will solve it for the whole industry, promoting easier data sharing and trading.
In accordance with these goals, the investment bank Goldman Sachs collaborated with FINOS to open-source its Alloy database management platform in 2019, which it [developed over 14 years.](https://www.cnbc.com/2019/11/20/goldman-sachs-is-giving-away-software-to-wall-street-for-free.html) For years, the company used Alloy to reconcile the thousands of different databases used across different departments. By open-sourcing it, the company aimed to contribute toward the creation of a standardized data modeling form, which would bring down transaction costs. It would also be passing on to the open-source community the burden of developing and maintaining Alloy.
### **Deutsche Bank**
People in the finance industry use various tools for messaging, data sharing, and news. This lack of standardization renders collaboration and knowledge sharing difficult, posing an obstacle to trade. Deutsche Bank developed [Plexus Interop](https://plexus.finos.org/) to solve this problem. The platform makes [interoperability](https://www.db.com/news/detail/20171004-deutsche-bank-makes-its-computer-code-publicly-available-for-the-first-time) among all these different apps possible, helping different organizations talk to each other. Deutsche Bank open-sourced this solution in 2017.
Having reaped the benefits of open-sourcing projects, the German finance giant made two further contributions to the open-source community: First, in 2018, it open-sourced [Waltz](https://www.finos.org/blog/introduction-to-finos-waltz), a platform that shows where different applications and data sets reside in an organization, lays out how they are connected, and opens them up to all employees. Then, in 2020, it contributed [Symphony Java Toolkit](https://www.bloomberg.com/press-releases/2020-11-13/finos-launches-open-regtech-initiative-as-it-receives-record-high-number-of-open-source-contributions), an interoperable suite of libraries facilitating tasks like identity management and building workflows.
### **Morgan Stanley**
Application development is a resource-intensive process. However, the resulting applications rarely turn out to be resilient to last long enough—[a change of technology](https://morphir.finos.org/docs/background/) renders them obsolete in a short time, making an upgrade inevitable, which means a rewrite. Determined to make sure that its internal tools would stand the test of time, Morgan Stanley used Morphir to seamlessly translate business logic into different languages and platforms for years.
Morgan Stanley [open-sourced Morphir](https://www.bloomberg.com/press-releases/2020-09-11/contributions-from-morgan-stanley-epam-and-new-board-leadership-highlight-finos-expansion-in-2020) in 2020 in collaboration with FINOS. This was an attempt to develop a standard business logic format optimized for storing and sharing across different departments. By enabling free movement of business logic within an enterprise, Morphir reduces the need for different departments to write their own code to solve the same problem, bringing about less technical debt.
## **Final thoughts**
The finance industry had its doubts regarding the open-source movement at the beginning, and not without reason. However, with digital transformation in full swing and fintech firms wanting an ever-bigger share of the pie, legacy finance organizations found themselves with their backs against the wall and had to take steps to adapt to the times. FINOS has orchestrated disparate efforts, unlocking efficiencies for the whole industry. In the end, finance organizations discovered that they could use open-source to diversify their offerings and make their code base more resilient. The whole episode illustrates how transformative open-source can be, even in one of the most traditional industries.
--- START: blog/open-source-licenses/open-source-licenses.md ---
# **Open-source Licenses: What Are They and Why Do We Need Them?**
An open-source license is a strange concept. Why would you need a license to use something that people use for free? However, open-source software is free only as in "[free speech," not "free beer.](https://www.howtogeek.com/howto/31717/what-do-the-phrases-free-speech-vs.-free-beer-really-mean/)" There are still rules and guidelines needed to regulate its use. Otherwise, it can turn into chaos real quick.
In order to understand the need for open-source licenses, one has to come to grips with one fact: Any code you write is subject to copyright laws. Why? Because software is treated as [literary work](https://en.wikipedia.org/wiki/Software_copyright) under the law. You, *and only you*, are entitled to use, publish, and modify that code, and the copyright lasts until [70 years](https://www.10duke.com/resources/glossary/software-copyright/) after your death.
That puts developers in the same position as authors, songwriters, architects, etc. They are artists, and this is not hyperbole. However, there is one problem: An author would probably not want somebody else to build upon his work and modify it. Likewise, a songwriter would not be happy if someone changed the lyrics of one of her songs. These literary works are one-and-done. Software code is not.
Some developers want to enable other people to work on, modify, and improve the code they wrote. Just putting the code out there does not cut it because the code is protected by copyright laws. Anybody, no matter the intention, would be infringing on copyright once they start modifying the code. If you want people to use your code but only on your terms, then what you need is an open-source license. These licenses afford copyright owners differing levels of control over the code they wrote, define the terms on which downstream users can make use of the code, and make collaboration on open-source projects possible.
There are [more than 80 open-source licenses](https://opensource.com/article/17/9/open-source-licensing) approved by the [Open Source Initiative](https://opensource.org) (OSI), a non-profit organization that defines what open-source is and promotes its use. However, most of the use cases in the software world are covered by a small portion of that number (around 10-15 most popular licenses).
Open-source licenses can be grouped into two main categories: Copyleft and permissive.
## **Copyleft**
[Copyleft licenses](https://opensource.org/faq#copyleft) are the ones that allow derivative works but subject them to the same requirements as the original work. Suppose you modify an existing open-source code under a copyleft license. In that case, you are liable to publish your modifications under the same license. These licenses require a developer to give back to the community after using open-source code.
This "give-back" requirement helps keep the community alive. But, on the other hand, it [stifles business growth.](https://www.youtube.com/watch?v=DDx6gjwU0K8) Every minor modification made to the code triggers the obligation to republish the work, which makes the commercialization of a product almost impossible.
Distribution is the key action for copyleft licenses. The term [refers to](https://opensource.com/article/17/9/open-source-licensing) the transferring of a copyrighted work from one legal person to another, and this transfer is what triggers the clauses in the copyleft licenses.
There are two types of copyleft licenses:
**Strong copyleft:** This license involves a "[viral effect.](https://thecybergarden.com/the-concept-of-copyleft-in-open-source-software-licensing/)" This effect requires the modified version of a source code to be distributed under the same license as the source code. If a piece of code that is under a strong copyleft license is added to a project, all the components of that project have to be licensed under the same terms. GPL 3.0 is an excellent example of this license type.
**Weak copyleft:** This particular type of license lacks the viral effect of the strong copyleft. Works under a weak copyleft license can be integrated into an aggregate project [without affecting the latter's existing license.](https://levelup.gitconnected.com/understanding-open-source-license-types-5a577c4a09d5) Among the weak copyleft licenses are [Mozilla Public License and Eclipse Public License.](https://www.youtube.com/watch?v=KI5qBAWcQv8)
## **Permissive**
Also known as "attribution style licenses," permissive licenses give users the freedom to use, modify, and redistribute open-source code while [also permitting proprietary derivative works.](https://www.mend.io/resources/blog/open-source-licenses-trends-and-predictions/) That's why people prefer permissive licenses over copyleft licenses for commercial purposes.
Application security company Mend has recently conducted a study on the WhiteSource database, which includes [4 million open-source packages and 130 million open-source files](https://www.mend.io/wp-content/media/2022/01/MEND-The-Complete-Guide-for-open-source-Licenses-2022.pdf), to determine the most popular open-source licenses. The study revealed that permissive licenses have been gaining popularity at the expense of copyleft licenses for a decade now. Only 41 percent of open-source licenses were permissive in 2012. The figure gradually increased to 78 percent by 2021. In the meantime, the share of copyleft licenses fell from 59 percent to 22 percent. Apache 2.0, MIT, and BSD have been the most popular permissive licenses in this period.
## **Choosing the right open-source license**
One of the most strategic decisions you can make at the start of an open-source project is to choose the right open-source license. Having the foresight and ability to do so helps you avoid potential roadblocks and compatibility issues down the road. Here is a [short list of guidelines](https://www.youtube.com/watch?v=OnmWFxlG2GA) to keep in mind presented by Mike Miles, Senior Technical Solutions Officer at Genuine at the time of the recording:
+ What licenses are already being used by your software? The licenses already in use by your software may dictate which licenses you may or may not choose.
+ The terms of service of the platform that hosts your software are crucial. If you are to keep your code on GitHub, you are expected to consent to the creation of derivatives on your open-source code.
+ Copyleft would be a good choice if you want derivatives, additions, and distributions to use the same license and follow the same guidelines. If not, go with a permissive license so you will only get cited for your work.
+ Whether you plan to let others use your software in their own proprietary software matters. If you don't care, go with weak copyleft. Otherwise, pick strong copyleft.
Understanding what open-source licenses are and how they work can save you a lot of headaches managing your open-source project. Make up your mind on the goals of your project (whether you are going to monetize it or keep it purely developmental); then, your decision tree will become a lot simpler.
--- START: blog/open-source-maintenance/open-source-maintenance.md ---
# **Maintaining Open-source Software: A Thankless Job**
Open-source projects are an enigma to regular people. How they start, flourish, and get maintained is not known to anyone but the geekiest of us. But there must be someone taking care of these projects upon which so much rests, right?
Maybe there are tiny people behind the scenes, who make sure that these gigantic efforts are sustained, much like the dwarves of [Erebor](https://en.wikipedia.org/wiki/Lonely_Mountain), "the Lonely Mountain," or "the kingdom under the mountain" in the Hobbit, relentlessly mining the gold and gems underground.
Or, maybe it is all thanks to the efforts of a handful of combative men and women who don't know how to quit, like the 300 Spartans who stopped the huge Persian army in its tracks at [Thermopylae.](https://en.wikipedia.org/wiki/Battle_of_Thermopylae)
The stakes associated with open-source maintenance are so high that a harder look at it is justified.
## **Getting to know the contributor funnel**
Who are these unsung heroes of the software industry that make the open-source world go round? People involved in open-source software can be grouped under [three categories](https://mikemcquaid.com/2018/08/14/the-open-source-contributor-funnel-why-people-dont-contribute-to-your-open-source-project/):
**Users:** People who just use the software and rarely interact with the maintenance crew. They don't submit code or documentation.
**Contributors:** People who care about the software enough to file good, detailed issues and open pull requests.
**Maintainers:** People who review the external contributions, conduct triage, and merge them. Maintainers are the ones who set the direction of the project because they get to prioritize the issues.
These three categories comprise a contributor funnel, a term coined by Homebrew project leader and GitHub principal engineer [Mike McQuaid.](https://www.linkedin.com/in/mkmcqd/) In a [presentation](https://www.youtube.com/watch?v=OsOZpF6LFcw) he gave in 2016, McQuaid goes into detail on the contributor funnel, which is actually a blueprint to turn some of the users into contributors and some of the contributors into maintainers so that open-source projects will not die.
## **Understaffed, underfunded, underappreciated**
Open-source projects' coming to an abrupt end is highly likely because most of these projects lack the funds and staff that could guarantee their survival. This applies to even the most popular projects out there.
When the widely-popular open-source crypto library OpenSSL was diagnosed with the Heartbleed vulnerability on April 7, 2014, it was being [maintained by just two people](https://threatpost.com/openssl-past-present-and-future/112485/) and receiving a whopping $2000 a year in donations.. Many other open-source projects are [maintained by a single maintainer](https://mikemcquaid.com/2021/10/27/open-source-economics/) who makes all releases and reviews and merges all pull requests. McQuaid gives a similar number for Homebrew, which had around 500,000 users and 5,000 contributors in 2016 but only around ten maintainers. That makes one maintainer for every 50,000 users. And remember, maintainers are not compensated for their time and effort. They have day jobs, families they need to take care of, and bills they should pay. To add to that, maintaining a project is not the most exciting job a coder can have, [as explained by Vladimir Agafonkin](https://www.welcometothejungle.com/en/articles/btc-discussion-open-source-maintenance), the creator of the Javascript library Leaflet:
>*"… once the project gets established and mature, most of your work is not about exciting features and doing cool things anymore—99% of the work is just dealing with some weird bugs, some obscure situations, and just trying to reproduce someone else's problem, and boring things like that. It can be demoralizing, and sometimes people will burn out and not be able to handle the project once it becomes really popular."*
If you think the recognition maintainers receive from the open-source community should be enough, think again because [tracking individual contributions back to contributors](https://mikemcquaid.com/2019/05/20/research-study-interview-work-of-maintaining-open-source-software/) is no easy task. Even if it is possible, very few people are interested in learning who solved which problem. So, maintaining an open-source project remains a thankless job.
## **Loosening the purse strings (at last)**
In the absence of material gain and recognition, what drives maintainers is their love for the profession and [the open-source ideals](/blog/open-source-why-bother/) they try to uphold. Keeping these people motivated is in the interests of everybody benefitting from the open-source projects. One way of doing that is to sort out the financial viability of those projects.
Humanity cannot afford to treat projects that underpin huge businesses and government institutions as hobby projects. Fortunately, corporate decision-makers and government officials seem to be awakening to this reality. Ensuring the security of open-source projects has become paramount with the recent [Log4j](https://www.zdnet.com/article/after-log4j-white-house-worries-about-the-next-big-open-source-flaw/) vulnerability and pushed the White House to call for an Open Source Security Summit. The U.S. administration mobilized companies such as IBM, Microsoft, Meta, Linux, and Oracle to take measures to counter such risks. During the summit, tech companies jointly [pledged $30 million](https://www.electropages.com/blog/2022/05/google-announces-funding-open-source-maintenance-crew) to shore up the security of open-source projects. Companies also agreed to conduct annual reviews of the 200 most popular open-source projects.
Having donated $15 million to open-source security in 2021, Google took the opportunity during the Open Source Security Summit to announce the launch of the "[Open Source Maintenance Crew.](https://blog.google/technology/safety-security/shared-success-in-building-a-safer-open-source-community/)" This team of developers is [tasked with](https://venturebeat.com/2022/05/12/google-open-source-maintenance-crew/) standardizing security procedures in open-source projects and tightening security configurations.
## **Conclusion**
Big tech and the government have stepped up to the plate and assumed responsibility for the security and sustainability of open-source software. This was long overdue, but it still is good news. However, the open-source community is not wholly dependent on others to survive. Open-source projects can become self-sufficient, take care of their maintainers, and even expand their staff if they are monetized properly. [Our next blog post](/blog/open-source-monetization/) will tell you how.
--- START: blog/open-source-monetization/open-source-monetization.md ---
# **How to Monetize Open-source Projects**
Monetization of open-source projects is a critical issue. It is a conundrum waiting for a solution: On the one hand, open-source projects underpin many services and products we use in our daily lives, so we need them. On the other hand, the maintenance crews looking after those projects are severely understaffed and underfinanced. Something's gotta give—either open-source will play a smaller role in our lives (which is unlikely) in the future, or we'll find ways for open-source projects to sustain themselves. Working toward the latter makes more sense, considering how much we have tied up in open-source.
People have been looking for ways to make open-source projects more sustainable for decades. The methods used to achieve this end evolved over time, giving us a complete range from monetary donations to more advanced models that require legal and technical infrastructure. Let's take a look at the top five most popular monetization models for open-source projects:
## **Donations**
Donations were the first step in the monetization of open-source projects. This model is the most straightforward and easy-to-implement way to provide financial support for an open-source project. It involves no cognitive load for the project team—just opening an account on Patreon, GitHub Sponsors, or [Open Collective](https://opencollective.com/) will do.
However, donations are unpredictable. An open-source project must be quite popular if it is to be sustained on donations. Even then, the most ardent users of open-source software may turn out to be reluctant to give back when it comes to donating money to a project. Therefore, donations can't be a sound basis for planning the future of a project.
With so much depending on the success of open-source projects nowadays, these projects cannot be beholden to the goodwill of the public. Companies will not pay for the value they can get for free. Therefore, the long-term survival of open-source projects rests on giving companies an incentive to support projects financially. That's why monetization efforts moved on from donations to other models that are better suited to generate a sustainable revenue stream.
## **Paid technical support**
Users of open-source projects tend to have a lot of questions, ranging from simple "what should I do?" type questions to major compatibility issues. Already the most knowledgeable people on their respective projects, maintainers are the most suitable people to deal with such questions. Although not scalable if it is just a few coding enthusiasts maintaining a project, paid technical support can help sustain it.
Red Hat's success has illustrated how paid technical support for open-source projects can be a viable business model. The company was founded in the 1990s and went public in 1999. [Red Hat Linux](https://en.wikipedia.org/wiki/Red_Hat_Linux), the company's open-source Linux distribution, was split into two in 2003: [Fedora Linux](https://en.wikipedia.org/wiki/Fedora_Linux), the open-source, free-of-charge Linux distribution for non-enterprise users, and the subscription-based [Red Hat Enterprise Linux](https://en.wikipedia.org/wiki/Red_Hat_Enterprise_Linux) for enterprise users. It is this latter product that has defined Red Hat's business model, providing a proven model for monetizing technical support in open-source projects. For a subscription fee, Red Hat provides enterprises with a pre-built version of Linux [optimized for mission-critical installations](https://www.techotopia.com/index.php/A_Brief_History_of_Red_Hat_Linux) and continuous support and updates. This Linux version affords Red Hat customers a more stable version with a robust support scheme that takes care of niggles and problems in a more professional way.
Red Hat surpassed [$1 billion in revenue](https://www.redhat.com/en/about/brand/standards/history) in 2012, becoming the first open-source technology company to do so, and it came to be relied on by more than 90 percent of Fortune 500 companies. The company was [acquired by IBM](https://www.redhat.com/en/about/press-releases/ibm-closes-landmark-acquisition-red-hat-34-billion-defines-open-hybrid-cloud-future) in 2019 for $34 billion, which is a testament to the success of its business model.
## **Dual-licensing**
This model involves offering the code under two licenses, one being open-source and the other commercial. The open-source license tends to be a copyleft license that comes with the obligation to publish any derivative work under the same license. Some companies using open-source software find this prohibitively restrictive for their respective businesses. The same code published under a permissive license appeals to such companies as it lets them use it in proprietary applications.
Qt, the cross-platform software for creating GUIs, offers its product under a [dual license.](https://www.qt.io/licensing/) The non-commercial version suitable for academic work, hobby projects, and projects without external distribution is available under GPL and GPL 3.0 licenses. Users planning to use the software to redistribute it on their own terms can buy the commercial license and gain access to technical support.
Is dual-licensing really open-source? There are criticisms that the commercial versions of dual licenses hurt the open-source ethos. Putting an open-source project under the monopoly of a profit-seeking company is unacceptable to some purists. However, some companies are forced to adopt dual-licensing as a result of the increasing [competition from cloud service providers](https://github.blog/2021-03-18-whats-up-with-these-new-not-open-source-licenses/) that enjoy an existing relationship with customers and access to open source. Thanks to these two factors, cloud service providers can offer impressive competing products. To counter that, dual-license vendors look for surgical ways to stop their code from being used by rivaling products while keeping a portion of the project strictly open-source to generate leads and attract customers. In the absence of a better alternative, this is a matter of choosing the lesser of two evils over the death of open-source.
## **Open-core**
This model involves providing people with a "core" version of the code for free while keeping certain components, features, and functionality as closed-source, most of the time accessible through subscription. The add-ons offered in the paid version tend to generate high added value for industry professionals and enterprises and thus are worth the investment. As part of this strategy, contributors to a particular open-source project can talk to companies, understand their needs, and develop and ship on-demand features that will immediately plug holes for them.
[PrimeFaces](https://www.primefaces.org/) is one of those products that has leveraged the open-core model to create a viable business. While the PrimeFaces source code is [hosted at GitHub](https://www.primefaces.org/showcase/index.xhtml) and downloadable free of charge under an MIT license, users can buy templates to achieve significant productivity gains. Another example is Tailwind UI, which successfully applied the same formula, differentiating between the needs of enterprise and non-enterprise users. The company makes [$2 million](https://www.karllhughes.com/posts/open-source-companies) a year from selling add-ons to enterprises without completely abandoning its open-source character.
Open-core has been dubbed "not-so-open-source," just like dual-licensing was. Critics claim that cordoning part of a project off and making that portion only available to paid users practically goes against everything open-source stands for. It causes the [fracturing](https://www.redhat.com/en/blog/open-source-or-open-core-why-should-you-care) of the open-source domain, they say. Additionally, it is claimed to erode all the standard benefits like the "[community profit,](https://opensource.com/article/21/11/open-core-vs-open-source)" i.e., the cumulative publicly-available knowledge created as a result of individual contributions that we expect to derive from open-source projects.
## **Open-source PaaS (Platform-as-a-Service)**
The last iteration in the quest to monetize open-source projects is PaaS. [PaaS](https://azure.microsoft.com/en-us/overview/what-is-paas/) is a cloud-based development and deployment environment in which customers get to use the resources offered by a cloud service provider on a subscription basis. This model provides users with an [out-of-the-box solution](https://www.forbes.com/sites/forbesfinancecouncil/2022/06/09/open-source-as-a-competitive-advantage) that even SMBs and startups lacking the resources can take advantage of, [relieving entrepreneurs](https://www.redhat.com/en/topics/cloud-computing/what-is-paas) of the need to invest in expensive hardware like on-premise servers. Thanks to the PaaS model, they can focus on their ideas or projects instead of worrying about infrastructure and maintenance.
Take Kafka, for example. You can download it from GitHub and pick the most suitable configuration for your use case from among the available options, which definitely would take some self-education. And all this for a message broker. The other option would be to subscribe to the PaaS solution, which would be optimized for you and save you the hassle of setting up and maintaining the system. PaaS is an outstanding value proposition for people looking to use network-based services and leverage sophisticated functions without getting their hands dirty. For the vendor, it sets the stage for a viable business as it creates recurring revenue and scalability.
In the PaaS model, the open-source portion of a project works as a lead-generating funnel. Once the project becomes a product, the non-PaaS version basically serves as the freemium model, helping acquaint users with the product. Users willing to access more advanced features and enjoy professional maintenance are incentivized to upgrade to the PaaS version.
The downside is that going back to the non-PaaS version may not always be possible—these extra features can result in lock-in, making a return to the non-PaaS version difficult once the project turns into a serious business. On the vendor side, the open-source code poses a risk as another company can build a rival PaaS product on top of it.
## **Final thoughts**
The monetization of open-source projects requires much thought and advance planning, just like choosing the right open-source license does. However, there is no perfect solution in sight. Models in agreement with the open-source ideals can't offer reliable financial support. Those that can do so turn part of the project into proprietary code and are criticized for destroying the open-source ethos.
In a world that runs on open-source software, open-source projects must have the resources to cope with security challenges. A more strategic and forward-looking approach, one orchestrated by governments and open-source organizations, can reconcile conflicting purposes and ensure that open-source projects remain viable without having to sell their souls. Actually, it might be the only way out of this puzzle.
--- START: blog/open-source-ms-intel-ibm/open-source-ms-intel-ibm.md ---
# **The Open-source Way to Success: Microsoft, Intel, and IBM**
Open-source software is a strange phenomenon for a software company to deal with. At first glance, it might seem like an existential threat for the developers of closed-source, proprietary software. On the surface, it might feel like somebody set up shop and started selling counterfeit leather goods across the street from your upscale store where you sell the finest Italian leather.
However, thinking about it, open-source software doesn't have to be the mortal enemy for conventional software companies. Well-managed companies find a way to harness open-source to turbocharge growth in certain areas. Here are three remarkable examples:
## **Microsoft**
Microsoft wasn't friendly to the open-source concept until a decade or so ago. Bill Gates saw intellectual property as the only way software companies could make money. His company was adamant in defending it. For a time, Microsoft CEO Steve Ballmer seemed to be on a one-man crusade against open-source, calling Linux "[a cancer](https://www.linux.com/news/microsofts-ballmer-linux-cancer/)" at one point.
However, that did not last forever. The age of the cloud arrived, and Satya Nadella replaced Ballmer as the CEO. Microsoft had already started participating in open-source projects before, and under Nadella, the open-source became the go-to strategy for Microsoft.
This change had nothing to do with [altruism](https://www.zdnet.com/article/why-open-source-is-so-important-to-microsoft/), though. The fact that Microsoft wanted to compete with AWS meant the company would have to rely on an open-source infrastructure. Because as Cloudera CEO Mike Olson [says](https://www.techrepublic.com/article/whats-really-behind-microsofts-love-of-open-source/), "No dominant platform-level software infrastructure has emerged in the last ten years in closed-source, proprietary form." Today, enterprises depend on open-source systems like [Kubernetes and Kafka](https://www.techrepublic.com/article/why-microsofts-linux-love-affair-was-inevitable/), and no closed-source system comes close.
The defining moment in Microsoft's new game plan came when it [acquired GitHub](https://news.microsoft.com/announcement/microsoft-acquires-github/) in 2018 for $7.5 billion in stock. This was a strategic move for the company as it had become the top contributor to GitHub in terms of the number of contributors, and so much of its business depended on it. It just couldn't afford some other company snatching it up.
## **Intel**
Software companies investing in open-source projects come as no surprise. However, it is a bit different when a hardware company, Intel, does that. The microprocessor manufacturer has been supporting open-source projects for more than two decades and hosts a vibrant community at [01.org.](https://01.org/) In the past, it grabbed the headlines by open-sourcing its [ACAT](https://www.wired.co.uk/article/stephen-hawking-software-open-source-intel) (Assistive Context-Aware Toolkit) software which the late theoretical physicist Stephen Hawking used to communicate with others.
After a brief respite, Intel is making a comeback to the open-source realm. Intel's interest in open-source is powered by the rising importance of artificial intelligence (AI). The company wants to offer a product range that will perform well with applications controlled by AI. In accordance with that goal, it recently [hired tech leaders](https://thenewstack.io/intel-poaches-open-source-execs-from-netflix-apple-to-boost-linux-efforts/) from companies like Apple and Netflix.
Another goal for Intel is to remain competitive in the age of the Internet of Things and Industry 4.0. That was the motive behind its recent [acquisition of Linutronix](https://appuals.com/intel-acquires-linutronix-a-company-that-handles-the-rt-linux-kernel-branch/), a Germany-based software company. Linutronix is the creator of the Linux-based PREEMPT_RT patch that facilitates communication between drivers, sensors, and robots. Intel hopes to capitalize on Linutronix's expertise on Linux kernel at a time when [real-time, low-latency communication](https://www.theregister.com/2022/02/24/intel_linutronix_linux/) between different types of hardware becomes of paramount importance.
## **IBM**
IBM was one of the first corporate giants to recognize the potential of open-source software and embrace it. It supported projects like [Linux, Apache, and Eclipse.](https://www.ibm.com/opensource/story/#section-before-open) As early as 2005, IBM [opened 500 patents](https://www.computerworld.com/article/2569038/ibm-opens-500-patents-to-open-source-developers.html) to the open-source community, a position diametrically opposed to Microsoft's staunch defense of intellectual property at the time.
IBM has nurtured a long-term interest in Linux. It has been consistent in its support for Linux, shelling out $1 billion in technical assistance and other resources [in 2001.](https://www.zdnet.com/article/gerstner-ibm-to-invest-1-billion-in-linux-next-year/) This investment continued [in the 2010s](https://www.crn.com/news/data-center/240161390/ibm-pledges-1-billion-to-linux-effort-to-boost-power-system.htm), and the [2020 annual report](https://www.ibm.com/annualreport/assets/downloads/IBM_Annual_Report_2020.pdf) underlined IBM's commitment to spending $1 billion over the next three years to support Linux.
IBM capped its long-standing support for open-source software with a power move: In 2019, the company acquired [Red Hat](https://en.wikipedia.org/wiki/Red_Hat), an open-source software company that delivers its customer enterprise-grade Linux-based software, [for $34 billion.](https://www.redhat.com/en/about/press-releases/ibm-closes-landmark-acquisition-red-hat-34-billion-defines-open-hybrid-cloud-future) Recognizing that it [lags behind Amazon and Microsoft](https://www.cnbc.com/2019/07/09/ibm-closes-its-34-billion-acquisition-of-red-hat.html) in cloud computing, IBM aimed to leverage open-source software to offer its customers the highest-performing cloud infrastructure.
IBM is looking toward a future where it aspires to dominate the cloud, artificial intelligence, and machine learning fields. It relies on the versatility and robustness of open-source to turn this vision into reality.
## **Final thoughts**
We probably wouldn't have the cloud infrastructure and AI as we know them today in a world dominated solely by proprietary, closed-source software. Thousands of elite developers working on open-source projects, solving bugs, and inspiring each other fast-tracked our way to a future that wouldn't be possible without open-source. It is no longer a matter of whether a company should use open-source but rather how best to leverage it for the greatest competitive advantage.
--- START: blog/open-source-why-bother/open-source-why-bother.md ---
# **Open-source Projects: Why Bother?**
Developers are in demand. Enterprises, SMBs, and startups can't get enough of them. That's why they keep throwing ever bigger salaries and more attractive perks at developers. However, some developers look unimpressed by those advances, choosing to work on open-source projects. But why?
This challenges the homo economicus, or the economic man, model that presents human beings as rational and in the pursuit of their narrow self-interests. According to the model, one would have expected developers to strive to maximize their earnings. This model and the related [rational choice theory](https://en.wikipedia.org/wiki/Rational_choice_theory) postulate that people will assess their choices in terms of costs and benefits and make the choice that will bring them the maximum benefit. They imply that people would like to be [free riders](https://en.wikipedia.org/wiki/Free-rider_problem), letting others pay when they can reap the rewards without incurring any cost. But, apparently, these models and theories fall short of explaining every human behavior.
Some people devote their time and effort to projects that require a lot of sacrifice for very little gain. Sometimes very popular projects turn out to be the work of a surprisingly low number of devoted developers in the software industry. [Hear it from Zeynep Tüfekçi](https://www.wired.com/story/altruism-open-source-fuels-web-businesses-love-to-exploit-it/) on [OpenSSL](https://www.openssl.org/), a software library used to secure and oversee web traffic:
> "*According to one estimate, OpenSSL is used by more than two-thirds of all websites. But for the longest time, the whole project was maintained by two overworked programmers with a few unpaid volunteers helping out—even though the code was being used, for free, by a host of large corporations and governments. Until 2014, OpenSSL brought in a meager $2,000 in annual donations.*"
So, not everything we do is for our selfish interests. We [tip the valet at a restaurant](https://www.nytimes.com/2005/02/17/business/the-theory-that-selfinterest-is-the-sole-motivator-is.html) we will never visit again; we go out and protest an unjust war taking place thousands of miles from our homes. The existence of collaborative projects like Wikipedia and Linux is further proof that not everybody is guided solely by self-interest and rational choice. Boundless geekery can explain how some open-source projects start, but not how they can be sustained for years. What drives contributors to open-source projects can be grouped under three titles:
## **Monetary motives**
Unlike "proprietary" software that can only be modified by people who created it or were tasked with maintaining it, open-source software can be [inspected, modified, and enhanced](https://opensource.com/resources/what-open-source) by anyone. But this does not mean that open-source software is given away for free. Creators of open-source software can charge for the software they create or the customer support they provide. The only caveat is the [prohibition of the copyrighting or patenting](https://www.bigcommerce.com/ecommerce-answers/what-open-source-and-why-it-important/) of any work built on open-source software.
Monetary motives are just one reason developers invest their precious time and effort in open-source projects. But they don't tell the whole story.
## **Intrinsic motives**
**Altruism:** Giving back to the community plays a role in developers' interest in open-source projects, albeit a minor one. Being part of a coder community and contributing to it in a spirit of camaraderie functions as an [intrinsic motivator](https://opensource.com/article/19/11/why-contribute-open-source-software) for some developers if they are already earning money to pay their bills. Without that condition, altruism won't motivate many people to go out of their way to produce for a community.
**Ethics:** Some developers believe that knowledge should be exchanged freely and not be copyrighted. They want a software industry that is more transparent in how it collects and uses data. They think people have a right to control what the software is doing with the data provided. Open-source [ticks all those boxes](https://opensource.com/resources/what-open-source) for such people, giving them a chance to ply their trade in accordance with the principles they believe in.
**Prestige:** One of the more influential intrinsic motives that make developers engage in open-source projects is the prestige they hope to gain in the eyes of their peers by doing that. These projects are great tools for developers to demonstrate their coding skills, gain recognition in the industry, and use as a stepping stone for future success.
## **Extrinsic motives**
**Better engineering:** An open-source project lends itself to inspection and auditing by anyone. [Bugs](https://www.zebanza.be/why-open-source/) get sorted out quickly; the software gets tested for edge cases, resulting in a higher quality product. Therefore, contributing to open-source projects makes a lot of sense from an [engineering perspective](https://opensource.google/documentation/reference/why); the long-term return on investment far outweighs the effort made.
**The chance to build an ecosystem:** The enhanced inspection and auditing opportunities in an open-source project help these projects grow into robust frameworks and even become industry standards sometime down the road. Such projects lay the groundwork for thriving ecosystems where community members come in, extend the platform through [plugins and APIs](https://opensource.google/documentation/reference/why) to make it fit their needs, and in the process, multiply customization opportunities for others. We like customizable platforms and software, but the real good stuff tends to be extendible, allows integrations, and can fit a plethora of use cases. Extendible by design, open-source software is tailor-made for that.
## **Conclusion**
Thanks to people who put other motives ahead of their narrowly-defined short-term interests, the world has enjoyed high-quality open-source software. Contributing to and sustaining open-source projects have become a culture for many people. Understanding the motives of these people can help shed light on the culture that has been transforming our world. We shall now move on to other aspects of open-source in the upcoming parts of this series.
--- START: blog/pe-firms-no-heavy-data-stack/pe-firms-no-heavy-data-stack.md ---
# **Why PE Firms Don’t Need a Heavy Data Stack**
Private equity firms are all about creating efficiencies, boosting productivity, and improving the margins of their portfolio companies. Data visibility is critical to this goal. Operators need to see revenue trends, technician efficiency, and close rates across all brands in the portfolio.
Faced with this challenge, the instinct for some is to build a traditional BI stack: Pull data with Fivetran, store it in Snowflake, transform it, and visualize it in Tableau. But here’s the problem: Building and maintaining a heavy stack is costly, time-consuming, and often misaligned with PE timelines. For portfolios including HVAC, plumbing, or roofing companies running on ServiceTitan, big stacks are overkill.
The smarter move is to integrate data with minimal engineering effort, so you get fast insights without burning through capital or months of setup. Let’s take a look at how PEs can achieve that in this blog post.
## **Why PE firms need unified data in the first place**
When private equity firms acquire and roll up home service companies, they inherit multiple systems of record, most commonly separate ServiceTitan instances, accounting platforms, and spreadsheets. At first glance, each company runs fine on its own. But at the portfolio level, this fragmentation quickly becomes a roadblock.
Without a unified view of performance, PE operators face serious issues:
+ [Manual data integration](/blog/servicetitan-manual-data-export-costs/) relying on spreadsheets leads to slow reporting cycles and outdated insights.
+ Inconsistent metrics render portfolio-wide comparisons unreliable, making it difficult for leaders to identify best practices.
+ Limited visibility into operations prevents leadership from seeing portfolio-wide revenue trends, technician utilization, or close rates in real time.
+ It becomes harder to spot underperforming branches or replicate best practices across brands, causing decision-makers to miss valuable opportunities.
That’s why many PE firms believe they need a data stack—to centralize and standardize reporting across the portfolio. Unified data is the foundation for benchmarking, operational improvements, and ultimately driving growth. The challenge isn’t whether PEs need unified data, it’s how they get there.
## **The traditional data stack approach**
The standard practice for enterprise companies is to build a data stack that comprises
+ data pipelines built with tools like Fivetran or Airbyte,
+ data warehouses in Snowflake or BigQuery,
+ data modeling in dbt,
+ data visualization in Looker Studio, Tableau, or Power BI.
Although regarded as the safe choice by most companies, this setup has notable drawbacks. First, it needs a team of data engineers to develop and maintain pipelines. Building this type of data stack takes weeks or even months, in addition to the six-figure costs for initial investment and salaries. Finally, the lengthy setup process and high expense do not align well with a PE firm's timeline, which presents a significant challenge.
## **Why heavy IT projects don’t work for PE timelines**
Private equity firms are different from most other companies because their business model relies on condensed value creation cycles of 3 to 5 years. That means:
+ **Every quarter counts:** Delays in generating insights undermine decision-making and waste valuable time.
+ **Lean IT teams:** PE companies lack the large data teams that can build and handle data pipelines, making them a bad fit for complex data stacks.
+ **Heavy reporting requirements:** Boards of PE firms demand clear, consistent, and trustworthy data, not technical excuses.
+ **Unclear ROI:** By the time a large data stack begins to generate returns for a PE firm, much of the value creation period might already have passed.
The capabilities of a traditional data stack are far beyond what PE firms need, and these unnecessary capabilities come at the price of time and lower margins, which PE firms can hardly afford. These companies should invest in nimble platforms that can provide answers without the need for a large data team. That’s what Peaka does.
## **The ideal integration model for PE firms**
The right approach for PE-led home service portfolios isn’t a full-blown enterprise data stack but a lean, lightweight integration that delivers fast insights without IT drag.
The ideal solution should:
+ Provide connectivity across multiple ServiceTitan accounts
+ [Standardize KPIs](/blog/standardize-servicetitan-kpis-portfolio/) for true apples-to-apples comparisons
+ Deploy within days with minimal engineering overhead
+ Integrate with popular BI tools
+ Offer scalability as the portfolio expands
This formula gives PEs all the answers they need without putting their roadmap and margins at risk.
## **How Peaka fits the need for lean integration**
Peaka was designed specifically to address this challenge: Helping PE firms simplify reporting across home service businesses in their portfolios without the engineering burden.
With Peaka, PE firms can
+ Unify data from [multiple ServiceTitan instances](/blog/unify-servicetitan-data-pe-firms/)
+ Enable portfolio operators and finance teams to query their data in natural language with text-to-SQL capability
+ Pull in data from popular accounting platforms like [QuickBooks, Xero Accounting, or Sage Intacct](/blog/integrate-servicetitan-with-quickbooks-xero-sage/)
+ Create [one-click dashboards](/blog/consultants-servicetitan-kpi-dashboards/) in BI tools like [Power BI](/blog/servicetitan-power-bi-integration/), [Looker Studio](/blog/how-to-connect-servicetitan-to-looker-studio/), [Metabase](/blog/how-to-connect-servicetitan-to-metabase/), and more that consolidate revenue, job close rates, technician utilization, and marketing ROI
+ Deploy and see results in days, not quarters
+ Incur minimal cost and overhead, perfectly aligned with PE value creation cycles.
Peaka proves that your data stack does not need to cost hundreds of thousands of dollars to build and maintain just to provide you with real-time reports from your portfolio companies.
## **Key takeaways**
+ Heavy data stacks are costly, slow, and misaligned with PE value creation timelines.
+ Home service portfolios need lean, plug-and-play data integration to unlock insights quickly.
+ Peaka provides the visibility PE firms need without the IT burden or six-figure spend.
## **Smarter data integration for PE value creation**
If you’re managing a growing portfolio of ServiceTitan-based businesses, you don’t need to keep stitching together spreadsheets or waiting on analysts. [An official ServiceTitan partner](/partners/servicetitan-integration/), Peaka can help you unify your ServiceTitan data, accelerate reporting, and create the visibility your value creation plan demands.
[Sign up to Peaka](https://peaka.studio/signup) for free today.
[Book a demo](https://calendly.com/peaka/demo) to see how Peaka helps PE firms replace IT-heavy data projects with smarter, faster reporting.
--- START: blog/peaka-servicetitan-bi-integration/peaka-servicetitan-bi-integration.md ---
# **Peaka x ServiceTitan: Instant BI Dashboards for the Trades**
We’re excited to announce our partnership with ServiceTitan, the leading software platform for home and field service businesses. This partnership will introduce Peaka’s cutting-edge data management technology to businesses using ServiceTitan, helping them extract more value from their data.
## **Key takeaways**
+ Peaka is now an [official ServiceTitan partner](https://marketplace.servicetitan.com/partner/peaka), which will make data integration easier for home and field service businesses.
+ The partnership allows users to [integrate ServiceTitan data](/partners/servicetitan-integration/) with data from CRMs, accounting software, and SaaS tools—no code required.
+ Users can build real-time dashboards in Looker Studio, Power BI, Metabase, and Tableau without manual data pulls.
+ Peaka replaces time-consuming processes with automated, self-service data workflows, unlocking faster insights and cost savings.
## **What home service pros want**
Any home service business using ServiceTitan needs no lecture on the value of data for business operations. These companies rely on data to monitor sales, optimize scheduling, and evaluate the performance of field technicians and customer service employees. ServiceTitan does a great job of centralizing business data from different functions and aligning office and field teams around the same goals.
However, things get tricky for companies in “the trades” when they want to integrate their ServiceTitan data with data from CRMs, accounting software, relational databases, or SaaS applications. Here are a few real-world problems these businesses run into:
+ Data silos resulting from all the data scattered across ServiceTitan, HubSpot, Quickbooks, Xero Accounting, and Excel,
+ Exporting data from ServiceTitan to BI tools,
+ Creating a single source of truth for different teams working with different datasets
+ Generating timely reports that decision-makers can act upon.
Like other SMBs, home and field service businesses usually lack the data teams to tackle all these problems. Peaka’s partnership with ServiceTitan lowers the technical barriers to data integration and management for these companies, enabling them to make the most of their data.
## **What this partnership means for ServiceTitan users**
With this partnership, ServiceTitan users can leverage Peaka to
+ Join their ServiceTitan data with data from other platforms,
+ Make business data accessible to all teams,
+ Visualize aggregated data with BI tools like Looker Studio, Power BI, Metabase, and Tableau,
+ Automatically update ServiceTitan reports with fresh data, eliminating the need to manually pull data to update reports.
## **Real-world impact: From raw data to actionable insights**
Whether you’re running an HVAC servicing, plumbing, lawn-moving- or cleaning service, the Peaka-ServiceTitan partnership will have an immediate impact on how you use your data.
In a scenario where you keep your operations data in ServiceTitan, customer data in HubSpot, and financial data in QuickBooks or Xero Accounting, Peaka will help you
+ Join job data from ServiceTitan with customer data from HubSpot to see which demographic drives the most revenue,
+ Match billing data from QuickBooks or Xero Accounting with work orders from ServiceTitan to nail customer segmentation,
+ Build a dashboard in your favorite BI tool to view your consolidated data.
## **Why Peaka?**
Peaka is a good fit for the data integration and management needs of home and field service businesses:
+ **Enhanced productivity:** Intimidated by the technical complexity of conventional data integration, most home and field service companies unify their data through manual processes. Peaka replaces time-consuming, error-prone manual processes with real-time, hassle-free data integration.
+ **Cost savings:** Peaka uses data virtualization to integrate data without copying or moving it, and allows users to query data at its source. This removes the need for costly data warehouses and expensive data teams.
+ **Self-service analytics:** By eliminating ETL processes from data integration and replacing them with ready-made connectors, Peaka reduces reliance on IT people and facilitates self-service analytics among non-technical people.
## **Introducing TitanSigma for home service businesses using ServiceTitan**
Since publishing our ServiceTitan partnership announcement, we have taken the next step for home service operators and launched [TitanSigma](https://titansigma.com/), our dedicated offering for ServiceTitan-powered contractors who need scalable reporting as they add locations, acquisitions, and teams.
TitanSigma is built to help multi-location businesses unify ServiceTitan data across accounts, align operational and financial reporting, and power dashboards in the BI tools leaders already use.
If you want the complete roadmap for building reporting that holds up at scale, start with our [guide for multi-location ServiceTitan reporting](https://titansigma.com/blog/multi-location-servicetitan-reporting-guide).
For contractors running multiple branches within a single company, our blog post on [the challenges of multi-location ServiceTitan reporting](https://www.titansigma.com/blog/multi-location-servicetitan-reporting/) provides a helpful introduction.
Are you a ServiceTitan consultant managing separate client accounts? Then read our blog post for [multi-account ServiceTitan consultants](https://www.titansigma.com/blog/manage-multiple-servicetitan-accounts/).
If you are a PE firm building portfolio-level reporting across acquisitions, see our [PE reporting guide](https://www.titansigma.com/blog/unify-servicetitan-data-pe-firms/).
## **Ready to get started?**
If you’re a ServiceTitan user looking to unlock more value from your data, the Peaka integration is here to help. Spend less time wrangling spreadsheets and more time growing your business.
Make sure to visit our documentation to see how you can [connect ServiceTitan to Peaka](/docs/integrations/service-titan#servicetitan).
[Book a demo](https://calendly.com/peaka/demo) or [start a free trial](https://peaka.studio/signup) to see what Peaka and ServiceTitan can do for you.
--- START: blog/play-bigger-lochhead-review/play-bigger-lochhead-review.md ---
# **Book Review: Play Bigger by Christopher Lochhead, Al Ramadan**
Having reviewed April Dunford's book, *Obviously Awesome*, on product positioning, it was about time we tackled the positioning problem at a more strategic level. How do you position your company in a way that gives you a lasting competitive edge? What about the market? Can you take your positioning efforts to a higher level and reposition the market segment you will compete in? Christopher Lochhead, Al Ramadan, Dave Peterson, and Kevin Maney, the authors of this month’s book, *Play Bigger*, think that you must. They argue that companies that can create new segments within the market stand to take in most of the profits, eventually becoming one of the companies that shape our daily lives as Apple, Google, and IKEA have done.
## **Creating a category… But why bother?**
Is category creation another shiny concept Americans have invented to describe an already existing phenomenon, or does it truly serve a purpose? In this case, the concept of category creation refers to a strategic initiative to position a product as the sole player in a segment of the market. [The authors of *Play Bigger*](https://www.youtube.com/watch?v=mS4B541m9xg) define it as such:
> "*Category design is the discipline of creating and developing a new market category, and conditioning the market so it will demand your solution and crown your company as its king.*"
The authors regard category creation as a strategy to develop businesses that will dominate their respective segments for generations to come. This belief is based on a simple premise:
> "*Change the way people think, and they will change their buying behavior.*"
What motivates the category creation efforts is the fact that category kings grab 70 to 80 percent of the profits and the market value of the category they created. As an entrepreneur, you stand a much better chance to dominate the market by defining a new category around your product instead of competing in a category defined before. Category kings can dominate the market because they define a problem for the first time, and their names become synonymous with the solution to those looking for one.
The critical point about category creation is that it is not something you can choose to ignore. If you don't design the category you are operating in, somebody else will do it for you, forcing you to play according to the rules you did not set.
## **What's in the toolbox?: The *POV* and the *lightning strikes***
*Play Bigger* argues that you need to have a point of view (POV) and execute a series of "lightning strikes" to successfully create a category.
POV is not a marketing text to advertise the features of your product. POV is the overarching narrative you build to define and draw attention to a problem, positioning your product as a unique solution. It aims to tell the world how your product is not just better than but different from the other players in the market. It starts with educating the masses about a problem they didn't know they had. Then comes your vision for a new category to tackle this problem, revealing what you think would be the ideal solution. Finally, you describe a future without that problem, detailing how your solution will have changed the world.
The second tool, the lightning strike, refers to a set of [marketing actions](/blog/account-based-marketing-saas/) you undertake to make your POV the talk of the town. A lightning strike might be a dedicated event like an Apple product launch where you announce your POV in a dazzling way. An alternative would be an act of piracy to steal the show at a trade fair or a conference. The idea is to concentrate all your resources on promoting a problem and saturating the communication channels with your proposed solution. The lightning strike informs the world of an urgent and inevitable new category, conditioning them to accept your product as the solution.
## **The good**
Personally, one thing Play Bigger has achieved is helping me understand why people like Peter Thiel and George Gilder were infatuated with monopolies. The kind of monopoly these people alluded to was nothing like the monopolies of old, such as a mining concession given by the government to an oligarch or a company becoming the sole provider of communication services in a country. It dawned on me that the "*competition is bad, monopolies are good*" mentality was based on category creation. Thiel and his comrades [believe](https://foundersfund.com/the-future/#/conclusion) “*the best companies create their own sectors.*” These companies are “*natural-born monopolies.*”
On a side note, that annoying habit of thought leaders to coin terms or acronyms for every little thing has something to do with category creation, too. Every time you coin a new word, you are actually defining a new problem. By doing that, you essentially become a category creator people like scholars, journalists, or podcast hosts can turn to. Who better to talk to than someone who defined a problem for the first time?
*Play Bigger* does a great job of driving home a few key points.
+ Category creation is a great way of training people to start feeling a need.
+ Category creation takes a holistic approach as it involves simultaneously positioning your category, company, and product.
+ You will cover more ground if you develop a category-creating product rather than another "me-too" product. Being different rather than just better is the way to go.
## **The bad**
### **Teleological perspective**
*Play Bigger* has a [*telos*](https://www.merriam-webster.com/dictionary/telos), an end state it wants to achieve, which involves proving the worth of category creation as a discipline. Therefore, every example or statement in the book is curated to elevate the image of category creation. At times, the authors are basically engaging in boxscore punditry, attributing anything good to successful category creation and anything bad to failure to properly design a category.
According to the authors, if a company increases its market share, it must be thanks to successful category creation. But when it comes to Gillette's failure to reap the benefits it expected to unlock by creating the battery-powered toothbrush category, they attribute the failure to being too late to define the category. Category creation is their panacea, the silver bullet to solve every problem. The authors seem to believe that you have to create a category, regardless of whether there is a need for one.
### **Terminology**
The book's jargon leaves a lot to be desired. Coining new expressions (*lightning strikes, thunder claps, strike master controller, chief hijacker, frotos*) every few pages can get tiresome, especially when the expressions are neither interesting nor catchy. Maybe we don't need to coin a new word for every stage or every transient role in a process.
## **The ugly**
### **The pushy salesman style**
The book was written by marketing gurus, so it is no surprise that marketing jargon is strong in this one. However, you sometimes get the feeling that the authors are pushing it a little bit, even when their theory doesn't fit the case perfectly. It is as if they have hammers in their hands and are looking for nails to hit on the head.
The authors have confidence in their theory, having seen success in their respective companies, and a brashness to go with it. However, their pompous attitude seems really out of place at times. Listing "*ten reasons you shouldn't read the rest of this book*" or telling the reader to "*... put the book down, because you are not our audience...*" This over-the-top marketing swagger seems hard to justify in a topic like category creation, even if your name is David Ogilvy or Don Draper.
### **The SAP obsession**
The authors apparently worked for SAP at some point, offering consultancy to help the German giant create a new category of cloud-based ERP, which it could dominate from day one. The partnership did not work out for some reason, and the authors seem bitter about it. They keep mocking the company throughout the book, going so far as to say that it has "old-man balls." The authors seem to appreciate edgy and confrontational characters like Marc Benioff but using a book for thrash talking is another level. I'd love to learn about the other side of the story and hear from the SAP executives why they did not buy into our fantastic four's vision.
## **Conclusion**
Category design or creation is one of the most transformative steps you can take for a company. Nail it, and you can enjoy the benefits for decades as long as you keep creating new categories. *Play Bigger* does a good job of underlining what category creation can achieve for a company and lays out an actionable plan to make it happen. The unpleasant style of the authors is just a small annoyance compared to what you stand to gain from the book.
--- START: blog/polytomic-vs-embedded-peaka/polytomic-vs-embedded-peaka.md ---
# **Polytomic vs Peaka: Which is Best for Embedded Analytics?**
SaaS companies are no longer just syncing data. They’re turning data into products by monetizing it through in-product analytics. That means embedding real-time dashboards, campaign analytics, and even AI copilots directly inside their apps. To do this well, you need more than ETL pipelines or unified APIs. You need a full embedded data stack.
Polytomic and Embedded Peaka both promise to simplify data access. But while Polytomic helps internal teams sync operational data into tools like Salesforce or Postgres, Peaka is purpose-built to help SaaS teams embed customer-facing analytics experiences into their product UI.
Here’s how the two platforms compare and why Peaka has the edge over Polytomic:
## **1. Polytomic moves data, Peaka embeds it**
Polytomic focuses on syncing data from warehouses or databases into internal business tools such as Salesforce, HubSpot, or Airtable. It’s great for making internal teams more data-driven and feeding the data into the existing stack.
Embedded Peaka, on the other hand, is built to replace that stack. It functions as a **data delivery layer** that connects to any data source, unifies the data, and serves it to customers using a platform.
| Feature | Embedded Peaka | Polytomic |
| :--------------------- | :------------------------------------- | :------------------------------------ |
| **Deployment Mode** | ✅ Purpose-built for embedding | 🟡 Early-stage embedded |
| **UI Components** | ✅ Dialogs, query editor, autocomplete | ❌ No SDK/UI |
| **Branding & Theming** | ✅ Full white-labeling | ❌ None |
### **What this means for you**
If your goal is to let users see their Stripe, GA4, or Zendesk data in your SaaS UI instead of their CRM, Polytomic simply isn’t built for that.
## **2. Peaka eliminates data replication and data warehouses**
Polytomic does not come with a federated query capability, a query engine, or smart caching. It uses data replication to integrate data. Therefore, you still need to have a storage layer, build and maintain ETL pipelines, and develop UI components.
With Embedded Peaka, you don’t have to maintain a data warehouse or replicate data into your internal systems. Embedded Peaka leverages **federated queries** to query data at the source and uses **smart caching** to offer the optimum blend of speed and cost per query.
| Feature | Embedded Peaka | Polytomic |
| :----------------------- | :--------------------------------------------------- | :--------------------------------- |
| **Data Access Model** | ✅ Live querying (no replication) | ❌ Requires pushing to DB |
| **Query Engine** | ✅ Built-in (Trino-based) | 🟡 Some query support (unclear depth) |
| **Caching & Rate Limit Handling** | ✅ Rate limit-aware caching built-in | ❌ No caching built-in |
### **What this means for you**
Peaka gives you query-ready data that you can embed inside your product right away. Polytomic gives you the pipelines you need to operate and maintain.
## **3. Peaka reduces engineering overhead**
Whether it is handling OAuth keys and credentials, introducing multitenancy, or maintaining connectors, you’re on your own when you’re using Polytomic.
Embedded Peaka offers all of this and more:
+ Hosted or BYO OAuth with full tenant awareness
+ Project-, catalog-, and schema-level isolation
+ Role-, column-, and row-level permissions
+ Audit logs and data lineage
| Feature | Embedded Peaka | Polytomic |
| :----------------------- | :--------------------------------------- | :--------------------------------------------- |
| **OAuth** | ✅ Hosted, tenant-aware | 🟡 To be handled by the user |
| **Multitenant Support** | ✅ Native project/catalog isolation | ❌ None |
| **Connector Maintenance** | ✅ Peaka-managed | 🟡 To be maintained by the user |
### **What this means for you**
Peaka reduces frontend, infra, and compliance work so you ship embedded analytics in weeks, not quarters.
## **4. Peaka offers a complete solution, not a data pipeline**
SaaS teams planning to use Polytomic for embedding analytics into their products should be prepared for increased workloads. Polytomic does not provide essential features such as UI components, multitenancy, or branding that are crucial for embedded analytics, leaving SaaS teams to develop them in-house.
Embedded Peaka, on the other hand, was built to simplify life for these SaaS teams. Its **AI-enhanced query editor, ready-made connector dialogs, autocomplete, and visual theming support** help product teams save weeks that would otherwise be spent reinventing the wheel.
### **What this means for you**
Embedded Peaaka helps SaaS companies free up their engineering resources to develop and refine business-critical capabilities instead of spending time on boilerplate items.
## **Key takeaways**
+ **Polytomic is built for internal data sync**, helping teams push data into tools like Salesforce, but not for embedding customer-facing analytics.
+ **Embedded Peaka offers a complete embedded data platform**, with live querying, smart caching, UI components, and multitenant governance.
+ **Embedded Peaka eliminates the need for a data warehouse**, whereas Polytomic requires syncing data into your own database before it can be utilized.
+ **SaaS teams can ship dashboards faster with Embedded Peaka**, avoiding the need to build OAuth flows, query infrastructure, or frontend UIs from scratch.
## **Final word: Polytomic pulls in data, Peaka turns data into a product**
Hevo is an excellent choice for centralizing data into a warehouse for internal analytics.
But if your goal is to **embed real-time data, analytics, or AI insights** directly into your product without building all the infra yourself, Embedded Peaka is purpose-built for you.
Don’t build a stack to deliver analytics. Embed one with Peaka.
Explore [Embedded Peaka](/embedded-peaka/) or [book a demo](https://calendly.com/peaka/demo) to learn how to deliver customer-facing dashboards in days, not quarters.
Each platform offers something different, but if you’re looking for the fastest path to in-product analytics, you’ll want to see how Embedded Peaka measures up across the board:
+ [Embedded Peaka vs. Airbyte Embedded](/blog/airbyte-embedded-vs-embedded-peaka)
+ [Embedded Peaka vs. Cdata](/blog/cdata-vs-embedded-peaka)
+ [Embedded Peaka vs. Merge.dev](/blog/merge-vs-embedded-peaka)
+ [Embedded Peaka vs. Hevo Data](/blog/hevo-vs-peaka-comparison/)
--- START: blog/pre-pmf-frameworks/pre-pmf-frameworks.md ---
# **How You Can Succeed in the Pre-PMF Path as a Founder**
## **What is product-market fit?**
Whenever the phrase “product-market fit (PMF)” arises, I often pose the question, “*How do you define PMF?*”
Opinions vary. Some suggest the best indicator is the net promoter score (NPS), while others associate it with retention or organic growth metrics. Rather than assigning a variable to PMF, I like to define it as a period where “you have back-to-back onboarding meetings for 10 hours a day for 10 consecutive days.”
This intense period typically corresponds with achieving an annual recurring revenue (ARR) of around $100k - $200k. So what happens before this period? How does one attain product-market fit? Which frameworks work the most efficiently and which ones should you avoid?
If you’re a ‘framework’ founder who’s obsessed with structured approaches, which I believe most of the founders are and should be. You likely read *The Lean Startup* by Eric Ries and *Zero to One* by Peter Thiel and embraced their value props. Perhaps conducted customer discovery, adopted agile methodologies you’ve learned from your previous tech job, determined a north star, monitored key performance indicators (KPIs), and followed other guidelines that the so-called “entrepreneurs” sell online. These are all valuable practices; sadly, they tend to work much better once you find product market fit. **Earn the right to think long-term.**
“*Why is this so f\*\* hard?…* *It seems as if all these idiots are succeeding without even solving a real issue*”—many founder friends to themselves in the mirror every day (including myself).
## **Frameworks: Your worst Pre-PMF friend**
As a founder, your response to “list of things I have to do?” is probably like the following:
{{ resize_image(path="../static/assets/images/blog-images/kerem/pre-pmf-frameworks-thinker.png", width=759, height=400, op='fit_width', alt="The Thinker thinking") }}
Hate to break it to you, but ‘framework’ founders often get overwhelmed & fail because there is no good framework to transition from zero to one.
From my research and conversations with seasonal entrepreneurs, the biggest advice I discovered is to engage with potential customers before writing a single line of code.
Your initial groundwork should only involve talking with over 100 potential customers and asking the simple question: "*What can I build for you, realistically, that you’ll jump on to buy?*” Don’t bother with not having “past experience” in your relative field; if you’re technical, go learn it—it’s mostly just a different application of your fundamental knowledge. If you’re not technical, well, go find yourself a technical co-founder and make sure you’re extraordinary when it comes to the operational side.
PMF hinges on three key components: Demand, Supply, and Distribution. Among these, finding demand is the hardest part because it’s beyond your control; there is nothing you can do to change it—a tough pill to swallow.
Your focus should be on finding one *pocket of intense demand* and one type of customer. Once you identify these, product development will naturally follow. In a future post, I plan to delve deeper into each of these three aspects of PMF.
## **Demand: Most important yet least understood**
I often like to explain demand as falling in love with someone. How does one approach it? Do you talk with them about your interests? Obviously not… at least, it didn’t seem to be the case in my experience.
You go next to them, understand what they are looking for in a relationship, what their priorities are, how they evaluate their options, and if there is a place for you in this story. Many times, they won’t even know what they’re looking for (I swear we’re back to talking about customers) or whether they're willing to take a chance on your solution. It’s crucial to ensure that they are clear about their needs; otherwise, you’ll just be wasting your time. A good exercise I like to do is to think about what’s causing them to say “*Today’s the day I have to change*” – not out of desire, but forced by external factors.
Getting these answers will profoundly change your perspective on how you think about your ideal customer profile (ICP), product, and go-to-market (GTM) strategy. {{ highlight_text(text="When you nail demand, you don’t sell. People buy.", small_text="Top Highlight") }}
PS – 3 good resources for the demand side (more on these later)
1. [Feature requests aren’t demand](https://www.youtube.com/watch?v=nMIZqim8iXU)
2. *Demand-side Sales 101*, by Bob Moesta and Greg Engle
3. *The Mom Test*, by Rob Fitzpatrick
## **Supply: Your value proposition**
Supply, in its simplest form, is your product, mostly your software solution. It’s important to recognize that your product is merely a means to deliver value; it's just one aspect of the value you offer.
“*Founders usually overthink supply because building a product from scratch gives an illusion of success.*”
There is a good chance that if you discovered a worthy pain-point, so did at least one other entrepreneur. Now, the challenge is to determine what unique value you can provide to distinguish yourself from competitors.
Drawing parallels with the love story analogy, this stage is about discovering commonalities between what the other party seeks and your personal experience. What unique perspectives can you bring into the other person's life? Does your solution provide a more seamless experience? Perhaps it's the pricing, or they just liked your charisma (which rarely works out in the long run).
This phase might require you to pivot your value proposition to align closely with the identified demand. If this pivot aligns with your vision and you’re confident in your understanding of the demand, then a small adjustment to stand out doesn’t hurt anybody.
**PS — One good resource:** *No Bullsh\*t Strategy*, by Alex Smith
## **Distribution: The glue of demand to supply**
Even if you’re aiming for product-led growth (PLG), it’s important to recognize that the Pre-PMF stage is purely sales-led. This is essentially about formulating your GTM strategy that will shape after understanding your demand side. There is tons of terrible sales advice out in the market, and I’m definitely not the person to educate you on selling, but I tend to approach this part with “being a software team that works for free for a while” philosophy.
This mindset reflects a commitment to deeply understanding and meeting customer needs, often necessitating some initial groundwork without immediate returns.
While building your GTM, you need:
1. Pipeline — ONE primary engine to generate conversations
2. Sales Process — Simple process to turn sales meetings into customers
3. Delivery Process — Simple process to turn contracts into raving customers & referrals
It’s easier said than done, but I genuinely believe it’s a good first step to start thinking about your go-to-market strategy, AFTER you refine the demand-side strategies.
{{ resize_image(path="../static/assets/images/blog-images/kerem/pre-pmf-frameworks-chart.png", width=759, height=400, op='fit_width', alt="How demand and supply interact with distribution") }}
## **Fancy illusions that prove zero value**
+ Top-tier investors
+ Cool office next to OpenAI’s office in the Bay Area
+ Well-designed product
+ Fancy website with cool colors
+ Hip brand
This should not come as a surprise but all the things that you eagerly wait to share on LinkedIn have no value to your startup. Understanding the three components will allow you to solve all these other fancy problems.
## **Conclusion, next steps, and acknowledgements**
The Pre-PMF phase is fundamentally about understanding customer needs before developing a product. It challenges the status quo reliance on rigid frameworks and underscores the necessity of direct customer engagement, advocating for a more flexible and responsive approach to startup development.
By prioritizing a thorough comprehension of demand, refining the supply to meet this demand, and strategizing effective distribution, founders can approach the market with greater confidence. The Pre-PMF mentality is a call to action for founders to focus on customer-centric strategies and adaptability, moving beyond traditional methodologies to create products that truly resonate with their target market.
My perspective on Pre-PMF has been shaped through conversations with startup founders, understanding what went well and what didn’t. My understanding deepened after participating in Rob Snyder’s Pre-PMF Camp. I realized that even the most accomplished founders are often clueless about Pre-PMF concepts; hence, I wanted to articulate my insights.
At this point, I hope you share my obsession with understanding demand. Moving forward, I plan to elaborate on strategies for all three components, starting with Demand. Over time, I also hope to introduce my views on “How to Approach a Potential Customer,” “First Sales Funnel,” “Initial Delivery,” and finally “Finding PMF.”
If you have any questions or would love to chat on the startup ecosystem, please reach out to me through [LinkedIn](https://www.linkedin.com/in/keremkocer/) or kerem1007kocer@gmail.com. I’m always eager to hear new stories and insights.
--- START: blog/product-hunt-launch-b2b-saas/product-hunt-launch-b2b-saas.md ---
# **How to Launch on Product Hunt as a B2B SaaS Tool**
The prevailing sentiment within the software community suggests that Product Hunt (PH) primarily benefits B2C companies, with many arguing that direct outreach surpasses wholesale approaches in the B2B sector and that B2B solutions ought to be prioritized differently. Such perspectives fuel skepticism about the relevance and impact of Product Hunt for B2B SaaS organizations, with a growing consensus that it no longer wields its former influence. Despite acknowledging the validity of these arguments, I maintain that Product Hunt can still serve as a valuable platform for B2B companies, provided they implement a strategic and nuanced approach to their launch.
Numerous guides exist on securing the "Product of the Day" title, among other accolades. These guides seem to cater predominantly to B2C enterprises, often leaving B2B companies with minimal engagement. Through this mini-blog, I aim to share our approach to launching on Product Hunt, detailing the specific strategies we employed and the metrics that informed our success.
{{ resize_image(path="../static/assets/images/blog-images/kerem/product-hunt-peaka-integrations.png", width=759, height=400, op='fit_width', alt="Peimage depicting how Peaka integrates different data sources") }}
One of the visuals created by the Peaka design team for the Product Hunt launch, symbolizing Peaka's data integration prowess.
## **Brand recognition**
Product Hunt turned out to be a “*who can reach more people on LinkedIn*” contest, which usually results in getting in touch with people who are not part of the targeted audience. Before we launched, at least 20 different “PH marketers” reached out to me, arguing that they could publish our page with their audience for a certain price. Potentially, one might spend $500 to receive 1,000-2,000 likes, but such metrics are unlikely to translate into meaningful traction for the product. Attaining "Product of the Day" status is not inherently valuable; instead, B2B companies should aim to drive traffic to their website and, ideally, secure deals through Product Hunt referrals.
>“*Our goal should be to elevate Peaka's visibility. Let's ensure the market is aware of the innovative tools we're developing.*”
When developing a solution that requires extensive theoretical knowledge of infrastructure, it's exceedingly difficult to encapsulate your value proposition within the typical 20- to 30-second elevator pitch. Thus, in addition to direct outreach, it's vital to gradually build your brand presence through blogs, product launches, and industry conferences. We target AI startups and our prospective clients may assume the necessity of building all their integrations independently, not realizing that third-party solutions exist in this space. It's our job to make these alternatives prominently known to them.
### **Strategy**
We initiated our launch preparations six weeks in advance, focusing initially on presenting our product and teaser page as clearly as possible. Given that an average product is assessed within 10 seconds, it was crucial to highlight the "aha moment" immediately.
By the third week, our efforts shifted towards building a network of allies to ensure broad reach and inclusivity for our launch. Up to this point, the emphasis was on distribution, yet in retrospect, this phase might have been overly extended, potentially achievable within 2-3 days.
The final week was particularly intense for our design team, who were tasked with creating a launch video and multiple posts—a heartfelt kudos to [Tunahan](https://www.linkedin.com/in/tunahanozer/) for his exceptional work.
Reflecting on the process, it appears the preparation phase is often overstated. Spending 15-20 minutes each day will be more than enough time if you plan early. Everything happened in the last 3 days. We’ve made sure everyone on the team knows who to reach out to, when to reach out, and what to publish. People who appeal to a larger audience started out so we could gain visibility from the start, and then our founder reached out personally to our ideal customer profile.
Gaining visibility for your product on Product Hunt often hinges on securing a spot among the top products of the day. This requires social proof that your product merits further exploration. In alignment with common practice, we leveraged LinkedIn, Slack channels, and other social media platforms to announce our launch, which initially attracted 400+ interactions from individuals outside our target demographic.
However, the real transformation began post-2:00 PM PT when we shifted our focus exclusively towards our intended audience. We succinctly notified them of our presence on Product Hunt, inviting them to view our listing and contribute feedback. While some may view this strategy skeptically, given that many users may simply 'Upvote' without engaging deeply with the product, this approach can be remarkably effective for products that immediately resonate with and offer solutions to the specific challenges faced by their target audience.
### **Metrics**
We initially anticipated a modest number of sign-ups and demo requests in the morning, placing greater emphasis on the outreach efforts scheduled for after 2 PM. Contrary to our expectations, we witnessed an unprecedented level of traffic from the outset. In the period leading up to 2 PM, our landing page saw consistent activity, with at least 40 individuals actively engaging, many of whom registered to try the product, and a notable number scheduling demos.
This interest not only persisted but also intensified with the commencement of our targeted post-2 PM efforts, culminating in a significant spike in engagement. The outcome was an influx of demo requests sufficient to occupy our schedule for the forthcoming two weeks. Writing this post five days subsequent to our launch, we continue to receive new demo inquiries, with many individuals citing our Product Hunt debut as their point of reference.
{{ resize_image(path="../static/assets/images/blog-images/kerem/product-hunt-product-of-the-day-1.png", width=759, height=400, op='fit_width', alt="Peaka's Product Hunt no.1 Product of the Day badge") }}
Peaka nabbed the # 1 Product of the Day spot on Product Hunt thanks to a well-curated strategy.
## **Conclusion**
Our journey illustrates that, {{ highlight_text(text="with a strategic approach and a product that resonates with its intended audience, Product Hunt can serve as a valuable conduit for B2B companies to not only garner attention but also translate that visibility into tangible business opportunities.", small_text="Top Highlight") }} This reinforces the importance of not underestimating the potential of platforms like Product Hunt in a B2B context, provided that launches are carefully planned and executed with a focus on reaching and engaging the right audience.
--- START: blog/provet-cloud-connector/provet-cloud-connector.md ---
# **Peaka’s Provet Cloud Connector: How to Extend Your Vet CRM**
Data integration is regarded as an enterprise-only field where organizations with thousands of employees invest millions of dollars in state-of-the-art hardware and software to break down data silos and unify their data. The data integration needs of startups and SMBs were ignored, and these companies were left to their own devices as they struggled to consolidate their scattered data without the means to buy enterprise-grade software or employ large data teams.
From day one, Peaka has focused on solving the data integration pains of startups and SMBs. That’s why we’ve launched many connectors for the most popular SaaS tools over the last two years. Although most of those connectors were for generalized tools, our last launch caters to a specific vertical: Veterinary clinics.
Vet clinics are similar to other healthcare institutions with regard to data: They create a surprisingly large amount of data, and data security and privacy concerns are paramount for their operations. Veterinary practice management software like Provet Cloud helps manage this complexity. When you need a bit more than that, Peaka’s Provet Cloud connector provides even your modest local vet clinic with cutting-edge data integration capability.
## **What is Provet Cloud?**
Provet Cloud is a cloud-based vet practice software specially built for veterinary clinics. It is an all-in-one platform, giving users a holistic view of their operations, from appointments to patient records to invoicing and payment tracking.
Here are some of the functions Provet Cloud brings to the table:
**Patient records:** Provet Cloud serves as an online repository for anything and everything related to patients, including their medical history, diagnoses, and treatments being applied.
**Online booking:** Pet owners can use Provet Cloud to make appointments, which lessens the workload of the staff at a vet clinic.
**Communication:** Provet Cloud can send pet owners emails reminding them about their upcoming appointments or vaccinations and collect feedback from them.
**Inventory management:** Provet Cloud enables users to monitor stock levels of medications, supplies, and equipment. It can automatically reorder when stock levels are below a certain threshold, ensuring that operations run smoothly.
**Reporting:** Provet Cloud unifies the data from distributed clinics, giving users a holistic view of their business operations across all branches. Users can leverage the platform to generate reports on the performance of individual clinics and employees and the overall financial performance of the business.
**Billing and invoicing:** Provet Cloud offers a one-click billing and invoicing process. It feeds invoices to the accounting software, helps track overdue payments, and sends reminders to clients with overdue payments, eliminating some of the repetitive work the accounting department has to handle.
## **What is Peaka?**
### **Zero-ETL data platform**
Peaka is a zero-ETL data platform for startups and SMBs that was developed to replace the modern data stack, which is too expensive to set up, too complicated to use, and too demanding to maintain.
Peaka offers a new way of integrating data through [data virtualization](/blog/data-virtualization-no-code/) without the need for complex and time-consuming ETL processes. By virtualizing your data tables, Peaka establishes a semantic layer over relational and NoSQL databases, SaaS tools, and APIs, immediately allowing users to query disparate data sources as a single source.
### **Serverless connector infrastructure**
In addition to its zero-ETL data integration capability, Peaka also functions as a [serverless connector infrastructure](/blog/startups-connector-infrastructure/) for its customers.
SaaS startups need to tackle a formidable challenge as they grow: Integrating with their customers' tech stacks. This wouldn’t be an issue if all companies used data warehouses, but that’s not the case. For most companies, the tech stack consists of a bunch of SaaS tools. The set of SaaS tools varies from one customer to the other, requiring a startup to ship connectors at scale if it is to close deals, gain traction, and grow.
However, this is easier said than done. Building a single integration can take weeks or even months. With a small and already overwhelmed engineering team, building the necessary connectors at a quick rate becomes a challenge. Maintaining these connectors is even harder and difficult, especially when connectors begin to malfunction due to the changes in third-party APIs.
Peaka provides these startups with a serverless connector infrastructure they can use to quickly launch “white-label” SaaS connectors that are up-to-date, scalable, and capable of performing at a high level at all times. This reduces the development costs for startups, makes them more agile in responding to connector requests, improves the conversion rates, and minimizes maintenance costs.
## **What does Peaka’s Provet Cloud Connector do?**
Provet Cloud is a dedicated CRM software for veterinary clinics, developed with their particular needs in mind. Its wide range of functionality makes Provet Cloud a popular choice among clinics in Europe. Although its capabilities extend from inventory management and reporting to communication, billing, and invoicing, Provet Cloud users may and do want to integrate their platform with other tools and platforms for some advanced features. That’s where Peaka steps in with its ready-made connector, delivering benefits such as:
### **Extendability**
Peaka provides Provet Cloud with the extendability it needs, helping this platform connect to hundreds of databases and SaaS tools out there. By allowing users to merge Provet Cloud data with data from other sources, Peaka helps data flow to and from Provet Cloud, making it more flexible than ever.
### **Single source of truth for all operations**
Among the external data sources you can connect Provet Cloud to are spreadsheet software like Google Sheets Documents or NoSQL databases like MongoDB that store different types of data. Removing the need to copy and move the data from one source to another, Peaka turns Provet Cloud into a single source of truth for your veterinary practice, where you can find any data related to your business needs and clientele.
### **Integrations with BI tools**
One of the game-changing capabilities Peaka adds to Provet Cloud is the integrations it offers with some of the most powerful business intelligence (BI) platforms out there. Peaka can send Provet Cloud data to a BI tool like Metabase, Preset, Apache Superset, or Power BI so you can view your data as slick dashboards that tell a story. When you consolidate your data from different sources and visualize it as charts and graphs, you unveil trends and patterns that you may not otherwise notice. Additionally, dashboards also make it easier for you to share your insights with key decision-makers, informing data-driven decisions across your organization.
### **360-degree view of customers**
Provet Cloud is a capable CRM platform, but there might be other CRMs like HubSpot or Teradata you’re using for different features. Pulling in customer data from other CRMs and joining it with your Provet Cloud data helps enrich the latter, giving you a 360-degree view of your customers, which you can use to improve your marketing campaigns.
### **Customer segmentation**
Taking a deep dive into your revenue data can unveil many insights about the performance of your vet clinic. By fetching your revenue data from a payment processing platform like Stripe and joining it with your Provet Cloud data, you can learn about your best customers, their demographic attributes, your best-performing clinics, and the most promising locations for future expansion plans. Such insights facilitate customer segmentation, enabling you to hone your pricing and marketing efforts for different customer segments.
## **Conclusion**
Being able to access the data you need and merge it with other pieces of data should not exclusively be for enterprises. Startups and SMBs, too, have a right to make data-driven decisions and grow. For vet clinics, veterinary management software like Provet Cloud can centralize data, which is a good first step. To extend this platform so it can work with all the data sources you use, you need Peaka’s Provet Cloud connector.
Whether you are running a single vet clinic or twenty-five of them, this connector makes it a breeze to pull in and join data from a wide range of databases and SaaS tools, helping you achieve a single view of truth for your business.
Check out Peaka’s growing [library of custom connectors](/integrations/) and [book a free demo](https://calendly.com/peaka/demo) to see Peaka in action!
--- START: blog/q-a-board-template/q-a-board-template.md ---
# **Peaka’s Pronto Q&A Template to Promote Know-how Transfer**
The power of the written word has fascinated mankind for thousands of years. The Romans were absolutely right when they said, "[Verba volant, scripta manent](https://en.wikipedia.org/wiki/Verba_volant,_scripta_manent)" ("*Spoken words fly away, written words remain*"). Once an idea is put in writing, it gains a life of its own, triggering thoughts and emotions in people in a way the original author could not have imagined.
Being a bit of a video game buff myself, I've often appreciated people who went to extraordinary lengths to educate other fans on online forums. I like replaying legacy video games that I used to play when I was in college. That hobby of mine would be torture without online forums dedicated to franchises such as [Heroes of Might and Magic](http://heroescommunity.com/) and [Civilization](https://forums.civfanatics.com/) due to the problems associated with setup, bugs, or game mechanics one inevitably runs into. A tutorial on an age-old online forum prepared by a fan fifteen years ago can still solve a problem and keep a large community engaged for decades, even long after the companies stopped caring about their products. How cool is that?
The golden age of online forums was before the social media tide inundated all of us and turned us into interaction addicts. The internet was seen as a one-way highway back then, publicized for facilitating access to information. "You can learn anything at the touch of a button" was its selling point to the internet-skeptics, especially the older generations, which spoke to the effectiveness of early search engines like Altavista, Yahoo, and later, Google. This new technology was about to revolutionize the way know-how was transferred.
Today, the general public's interest in the internet is guided mainly by entertainment purposes. Most of the user-generated content on the internet can be filed under the entertainment category. Videos and stories on platforms like YouTube, Instagram, or TikTok are curated to entertain the masses because that's what brings in the views and likes. This wasn't always the case, however. The user-generated content of the early- to mid-2000s had a more balanced flavor, with the goal of sharing information being more prominent.
Wikipedia was and remains the epitome of such platforms dating back to the early 2000s. Although the quality of the posts changes from one topic to another, and politics certainly plays a factor in the creation of content on the site, it is safe to say that Wikipedia still functions as it was intended. As of March 2022, the English-language Wikipedia hosts close to [6.5 million articles](https://en.wikipedia.org/wiki/Wikipedia:Size_comparisons#Wikipedia) and over [43 million registered users](https://en.wikipedia.org/wiki/Wikipedia:Wikipedians), [ranking no.8](https://www.alexa.com/topsites) among the most visited sites.
Reddit was another portal for user-initiated lengthy discussions before the site turned into something like a cult with a distinct sense of humor. Today it covers anything and everything, and sharing knowledge is no longer a priority outside of a relatively small, committed group.
Quora is the flag-bearer of purely Q&A-based community-driven websites nowadays. It boasts [300 million monthly active users](https://foundationinc.co/lab/quora-statistics/) writing on more than 400,000 topics ranging from technology to business, politics, history, health, military affairs—you name it. Regardless of your field of interest, Quora is capable of sucking you in like a vortex. There is always the danger of finding yourself having spent your whole Sunday reading verbal fights between anoraks of Napoleonic warfare, though.
Lately, Quora has also become an attractive outlet for tech leaders looking to be heard. Entrepreneurs, CEOs, and CTOs of software companies [with aspirations of thought leadership](https://www.vox.com/recode/2019/5/16/18627157/quora-value-billion-question-answer) in their respective domains regularly take the time to answer questions on Quora. Questions asked on the platform give these people valuable opportunities to educate the public on topics related to their line of work, explain their vision, and nurture a valuable bond with users that can pay off in the long term. Answers are there to stay, like notes pinned on a cork bulletin board, and will continue to educate people seeking answers to similar questions in the future.
Facilitating [know-how transfer](/blog/templates-know-how-transfer/) has been a focal point for us at Peaka. Our latest template, Pronto Q&A, is another contribution in that regard, letting our users easily set up a forum, receive questions from forum members and provide them with answers. We think this will make a perfect app for startups slowly gaining traction and expanding their customer base. Managing and servicing a community is relatively easy when you have just a few customers, but questions, bugs, and support requests can overwhelm your already strained staff once you are above fifty customers. Slack and Discord channels will only help so much—assigning a dedicated thread to every customer with a problem becomes unwieldy really quickly.
A forum built on Pronto Q&A will help a support team better keep track of customer questions and recurring issues, serving as a repository of knowledge to direct newcomers to. Pronto Q&A will solve a major pain point for startups and help customers self-serve while allowing teams to use their time more efficiently towards growing the company.
--- START: blog/rbac-ai-agents/rbac-ai-agents.md ---
# Why Role-Based Access Control Breaks Down for AI Agents
A role is a bet. More precisely, it's a bet that the person asking for something today is doing roughly the same kind of operation as the person who asked for it yesterday, and that both of them are who they say they are. For decades, that bet paid off reliably enough that nobody questioned it. Humans have stable job functions. One person reasonably has a consistent set of intentions per session. The whole architecture of role-based access control is built on that assumption.
Then AI agents showed up and broke that assumption in two fundamental ways. First, a single agent session now carries multiple identities, the agent itself and the entity that invoked it. Second, agents act non-deterministically, so tasks cannot be pre-provisioned. This article covers the nuances of both conditions and where that leaves teams implementing access control for agentic systems.
{{ resize_image(path="../static/assets/images/blog-images/mathew/traditional-rbac-vs-agentic-access-control.png", width=759, height=400, op='fit_width', alt="a table comparing ai agents to human interaction") }}
## The agent identity problem
An agent authenticates to your backend systems once, as itself, using its own credentials or service account. It then serves a stream of different humans through that single authenticated identity. No re-authentication happens as each new person arrives because agents were not built to work that way.
So two employees, one in finance and one in operations, ask the same AI assistant the same sensitive question on different days. The agent answers both of them from inside the same authenticated session, pulling from the same data it has access to. There is no way to distinguish who is actually asking at the moment data is touched. From the system's perspective, both employees are the same identity. The agent is correctly answering for the identity it has, which is its own. The problem is that "itself" is doing the work of a dozen different people with different clearance levels. Nothing downstream can tell the difference.
The instinct is to reach for more roles. Give the agent a more specific role. Map roles to departments, to data domains, to use cases, to teams. But a role describes a category of person. It doesn't restore the missing link between a specific question and the specific human asking it. More categories just make the composite more difficult to reason about. The issue is actually a layer deeper.
## The non-determinism problem
An agent session doesn't have a fixed shape. What starts as a simple lookup can become a cross-system (or even cross-agent) aggregation. That aggregation can become the input to a write action. All of this can happen in the same exchange, with follow-up questions that seem perfectly reasonable in sequence even if the session starts heading into sensitive territory.
This is where the other half of the original assumption falls apart. Role-based access control relies on two things being stable: who is asking, and what kind of tasks they're doing. A payroll manager doing payroll manager tasks makes complete sense; however, a payroll manager whose session has silently ventured into cross-system reporting and is now about to write a record somewhere is a different situation entirely. The common approach is to create a single role broad enough to cover every plausible action the agent might take. This prevents the system from breaking, but dissolves [least privilege](https://csrc.nist.gov/glossary/term/least_privilege) entirely.
## The same fix
The two breaks look separate only because governance efforts are typically split across teams, one for identity, one for task scope. They are the same failure, and it must be addressed at the architectural layer.
Roles operate at the level of the actor. They describe a category of person, assigned in advance, applied at login, and held constant for the session. What's actually needed is a decision made at the level of the individual query, at the exact moment it touches real data.
Evaluating policy at runtime ensures that identity and its requisite context are anchored to the data layer. As a particular query interacts with a record, the architecture identifies more than just an authenticated service account; it resolves the specific entity driving that interaction. In this model, roles are no longer the final word, but merely one signal contributing to a more granular authorization decision.
## Closing thoughts
Simply put, decisions are being made one level too high in traditional RBAC. Vetting whether a system can handle AI agents is straightforward. Ask at what level does it actually make permission decisions. Does it decide at the level of the person, the role, or the query? Most systems decide at the role level, because that's where the tooling is mature and the mental models are established.
Now, the decision must move down to the query. Peaka is built to solve this problem. It is a data virtualization layer that sits on top of the systems a team already runs, including warehouses, databases, internal APIs, and operational systems. It exposes all of these systems through a single SQL interface, so every query an agent issues passes through one place before it reaches any underlying source. Peaka resolves each of those queries under the caller's own identity and applies classification and audit at that same layer.
That design holds up in the aggregation and write scenarios described earlier. When a session drifts from a simple lookup into cross-system reporting or a write action, each step is evaluated as its own query against the acting user's permissions. No single broad role has to be provisioned in advance to cover whatever the session might become, given that the access decision is made per request rather than at login. That is what lets a single agent hold one set of credentials to your systems while still answering each person according to what that person is allowed to see.
If you’re looking to establish access controls at the query level, [book a demo](https://calendly.com/peaka/demo) with Peaka.
--- START: blog/responsible-ai/responsible-ai.md ---
# **Responsible AI, Where are You?**
Artificial intelligence (AI) technology seems to advance at breakneck speed as people expect it to solve many problems at once. Shortage of developers? Let AI pick up the slack. Traffic accidents? AI-driven cars will hopefully sort that out. Investment decisions?AI will show us the way to maximize ROI.
Time will tell to what extent these wishes will be realized, but a complex technology like AI also creates unintended consequences for people to deal with. Here are three problem points that need immediate attention:
## **Putting biases into action**
AI is not immune to acting in a biased way because the algorithm internalizes the bias inherent in the data it trains on. In a sense, what goes in predetermines what will come out in AI technology. As a result, problems like racism, sexism, and ageism are carried over from our social life to the data and the AI domain.
That’s why AI will exacerbate [social problems](https://www.xenonstack.com/blog/ethical-issue-ai) rather than cure them unless we do something about it. For example, African Americans, who tend to have fewer health expenses than whites, are deemed less in need of healthcare because of their past data. Similarly, AI favors lending money to men compared to women with identical credit scores.
The problem here is the fact that AI not only repeats the existing biases in society but also gives them a [veneer of objectivity.](https://news.harvard.edu/gazette/story/2020/10/ethical-concerns-mount-as-ai-takes-bigger-decision-making-role/) People tend to think that AI, having no thoughts or emotions, would not err, unaware of the bias fed into it.
AI operates like a [black box](https://datasciencedojo.com/blog/ai-ethics-biased-ai/), giving its operators no visibility into why it does what it does. This algorithmic opacity makes it impossible to diagnose the reasons for bias, let alone fix them. For this reason, AI should be rigorously [tested under real-life circumstances](https://news.harvard.edu/gazette/story/2020/11/risks-and-benefits-of-an-ai-revolution-in-medicine/) before wide release. Additionally, organizations should [specify KPIs](https://https//www.openaccessgovernment.org/5-ethical-ai-considerations-to-future-proof-your-business/147827//gazette/story/2020/11/risks-and-benefits-of-an-ai-revolution-in-medicine/) to encourage people to conduct responsible AI practices and raise their voices when they detect a bias.
## **Power asymmetry**
AI is an interesting technology in that it supercharges scalability of business operations and can easily go beyond the limits of different domains. That’s because it runs on data and can be applied to any domain that can benefit from data mining and analytics. There used to be different rules for different games in different industries in the past. That is no longer the case. There is a single game in town, and you don’t get to win if you can’t bring together, analyze, and interpret your data. Nailing data processing, analytics, and algorithms opens the door to success in a wide range of industries, as [Amazon’s success in retail and cloud](https://hbr.org/2020/01/competing-in-the-age-of-ai) illustrates.
However, mastering data and turning AI into the backbone of your business are expensive endeavors that take a lot of resources in terms of a skilled workforce, advanced tools, and money. Therefore, AI, in its current form, is no great equalizer. On the contrary, it makes the rich richer and the poor poorer. Unless AI is democratized, companies that can afford to invest in AI will take off and grow to dominate adjacent markets, while those lacking the resources will struggle to stay afloat.
## **Problem of agency**
Machines gaining a level of autonomy is an exciting thought, but this development might cause more problems than it solves. If AI-powered machines are to assume a bigger role in our lives, a complete overhaul of legislation regulating traffic, intellectual property and copyright, and military engagement is necessary.
Who bears the liability when two autonomous driving vehicles collide? Who gets the credit when AI produces artwork by training on the works of other artists? What about the code generated by tools like Open AI Codex? Who does that code belong to?
These are legitimate concerns. One of the popular technologies today, military drones, seem to get a pass for now because they have limited use cases and work within a human-in-the-loop framework where an operator interacts with the drone to make decisions during an operation. However, putting everything in the hands of AI in an industry like automotive seems far-fetched as the stakes are too high, where millions of people are expected to be affected. “The car is not an iPhone on wheels,” as Oliver Zipse, [the CEO of BMW](https://www.bmwblog.com/2023/01/17/bmw-skeptical-about-level-3-autonomous-driving/), says. He is clearly aware that we are a long way from self-driving cars:
> *“A Level 3 system, whether at 60, 80 or 120 kilometers per hour, which constantly switches off in the tunnel, switches off when it rains, switches off in the dark, switches off in fog – what’s that supposed to mean? No customer buys it. No one wants to be in the shoes of a manufacturer who misinterprets a traffic situation during the liability phase, for example, when control is handed back to the driver. We don’t take the risk.”*
It’s the [private companies](https://news.harvard.edu/gazette/story/2020/12/are-humans-really-the-best-role-models-for-a-robot/) that push the frontiers in AI. That explains both the speed of development and the lack of rules and regulation in the field. While the former is desirable, the latter poses risks for the industry and society. The AI sphere desperately needs a law like The General Data Protection Regulation (GDPR), which the EU ratified to check Big Tech companies that hoard data with no concern for privacy.
The GDPR brought tech giants into line by [establishing a timeline, demanding certain actions](https://venturebeat.com/ai/the-state-of-ai-ethics-the-principles-the-tools-the-regulations/), and backing those demands with hefty fines in the event of a violation. It signaled that things had to change as privacy violations had been out of control, and they would change whether the tech giants agreed or not. The AI field could use that kind of attitude from the U.S. government or the EU. Waiting for the industry to self-police and develop a regulatory framework on its own is just not realistic.
## **Solution: No-code and open-source**
AI technology needs to be democratized. The costs involved in implementing and maintaining AI projects are prohibitively high for most companies. Resource-rich companies can invest in AI and reap the benefits, pulling away from the competition that cannot afford that kind of investment. The end result of this trend would be power and capital accumulating in the hands of a select few at the expense of competition.
That’s why integrating AI with low-code and no-code platforms is key. The low-code/no-code technology will make AI accessible to those organizations that cannot afford to employ teams of engineers and data scientists. Leveling the playing field for smaller players will encourage innovation, give customers more options, and even solve some ethical problems by merely preventing some players from gaining outsized influence.
There is [a role for open-source](https://venturebeat.com/ai/the-state-of-ai-ethics-the-principles-the-tools-the-regulations/) to play on the compliance front. Regulations may come into force one day, but that will not be the be-all-end-all. To secure buy-in from companies of all sizes, hurdles to compliance will have to be removed. Governments and big tech corporations would be well-advised to support open-source projects, ensure that they are maintained, and help develop open-source AI compliance tools. Supporting open-source projects worked out really well for companies like [Microsoft, Intel, and IBM](/blog/open-source-ms-intel-ibm/) in the past. There is no doubt that they stand to gain a lot from a uniform, regulated, and easy-to-navigate AI sphere so that they won’t have to adjust themselves to different rules in different jurisdictions.
## **Conclusion**
Technology does not develop on its own in a vacuum. It is influenced by society and, in turn, impacts it. Thus, any technological breakthrough comes with a slew of problems and side effects that authorities need to take into account. AI is no exception, and considering its capabilities, the problems can be more challenging unless necessary measures are taken to ensure that it will be used in a responsible way. If AI is to be a force for good, it first needs to be brought under control. The time is now.
--- START: blog/saas-business-metrics/saas-business-metrics.md ---
# **How to Master SaaS Business Metrics**
## **Introduction**
Software-as-a-Service (SaaS) businesses have become the order of the day in today’s digital age.
***From cloud-based software to automated customer management systems, SaaS companies are changing the game by offering different services.***
Nevertheless, in order to succeed within this environment of fierce competition, it is significant for firms to excel in SaaS business metrics.
So, in this article, we’ll be explaining what SaaS business metrics are, introducing the [essential KPIs every B2B SaaS startup should track](/blog/top-saas-sales-kpis/), and discussing how these metrics can assist your company in growing and becoming profitable.
## **What are SaaS metrics?**
**SaaS business metrics** are performance indicators that assist SaaS companies in evaluating their operations, revealing the strengths and weaknesses of promoting data-driven decisions. These metrics are the industry’s lifeblood, providing insights into a SaaS company’s viability and prospects for growth.
***By mastering these metrics, SaaS businesses can streamline their operations, reduce churn rates, and boost profitability.***
These metrics are the basic units of analysis applicable to strategic decision-making—they point in a direction toward success and give an overview of the firm’s well-being, possible development, and long-term profitability.
So, in this journey to disentangle this complexity, we will first demystify SaaS business metrics.
Once we know what these metrics are, we will explain the benefits each can bring to decision-makers.
## **What are the 8 SaaS metrics you should be tracking?**
{{ resize_image(path="../static/assets/images/blog-images/flatart/man-analyzing-saas-metrics.png", width=759, height=400, op='fit_width', alt='man analyzing a saas analytics dashboard') }}
To get a real sense of the reasons behind SaaS success, we must dive deep into the essential SaaS business metrics that inform successful strategies.
SaaS business metrics guide your customer acquisition strategies, profitability, and other critical decisions in your SaaS business.
### **1. Customer Acquisition Cost (CAC)**
The first beacon on our metric map is Customer Acquisition Cost (CAC), which reflects what it has taken, in terms of expenditure, to bring a new customer on board.
This includes the cost of acquisition per customer encompassing marketing activities, expenses incurred by the sales team, and overheads.
Calculating CAC can provide important information about the effectiveness of your customer acquisition initiatives.
***A low CAC reflects cost-effective strategies, which increases profitability.***
### **2. Monthly Recurring Revenue (MRR)**
The lifeblood of any SaaS enterprise is its Monthly Recurring Revenue (MRR). It indicates reliable, recurring revenue derived from subscription-based services.
A healthy MRR figure creates a very important financial foundation that supports the budgeting, plan-making, and scaling of investments.
***It is through close monitoring of MRR that you continue to earn an income stream that sustains your business in good and challenging times.***
### **3. Churn rate**
The best analogy for describing the churn rate is a "leaky bucket." This metric shows the number of clients who have determined to jump out of a product or service by terminating their subscriptions.
High churn rates can sink your revenue and profitability.
***Therefore, understanding churn, determining its underlying causes, and taking measures to reduce it are very important for avoiding problems.***
### **4. Customer Lifetime Value (CLV)**
How much value you can extract from a customer plays a big part in determining your future earnings potential. Customer Lifetime Value (CLV) is the metric you should use to measure the future value a customer will create for your business during the full span of interaction.
This metric allows you to determine how much you need to invest in customer acquisition and retention.
***The higher your CLV, the better your chances of achieving lasting profitability.***
### **5. Gross Monthly Recurring Revenue (GMRR)**
Gross Monthly Recurring Revenue (GMRR) comprises MRR and Churn and denotes the incremental change in revenue, taking into account the revenue lost from churns and gained through upsells and cross-sells.
***A high GMRR indicates that you have not only preserved your existing customer base but also expanded it, achieving lasting revenue growth.***
### **6. Expansion Monthly Recurring Revenue (EMRR)**
Expansion Monthly Recurring Revenue (EMRR) captures revenue derived from existing clients upgrading, getting more features, or moving to bigger subscriptions.
Strong EMRR indicates a vibrant, interested customer cohort with a propensity toward checking out your complete line of offerings.
***The revenue growth rate from existing customers is a good indicator of the growth potential in the current customer segment you are serving.***
### **7. Net Promoter Score (NPS)**
Customer satisfaction and Net Promoter Score (NPS) help you gauge your reputation. They measure how well your product or service has been received by your customer base.
This metric matters because satisfied customers will stay with you longer, refer other people, and support the [growth of your SaaS business](/blog/saas-growth-metrics/).
***These metrics used in SaaS business give you visibility into your brand’s growth potential and the viability of its business model.***
### **8. Customer Acquisition Rate (CAR)**
Customer Acquisition Rate (CAR) serves as a speedometer for your company’s growth. It quantifies how fast you acquire new customers.
One of the crucial factors determining the profitability of SaaS businesses is how quickly a new customer can be acquired.
***With CAR, you gain the insights needed to inform your growth strategy.***
If you are wondering how you can measure these metrics, don't worry! With [Peaka's no-code data integration](/), you can easily bring your data together, calculate the relevant SaaS metrics, and get all the information you need for tracking your company's growth!
{{ resize_image(path="../static/assets/images/blog-images/flatart/peaka.png", width=759, height=400, op='fit_width', alt='peaka homepage') }}
## **Conclusion**
Mastering SaaS business metrics is not all about collecting data but rather making sense of it. That's why you should use a [SaaS analytics tool](/blog/why-use-saas-analytics-tools/). Keeping this in mind and focusing on the analysis of the data gathered helps lead you to growth and profitability.
***The metrics you should focus on depend on your business model and objectives, but the basics stay the same.***
The ability to measure and analyze these metrics can make all the difference in success or failure, whether you’re B2B or B2C SaaS.
Keep an eye on the pulse of SaaS business metrics such as CAC, MRR, churn rate, CLV, GMRR, EMRR, NPS CAR, and other key performance indicators to refine your strategies and make accurate decisions for the future of your SaaS startup.
In the fast-paced world of SaaS, it’s all about **understanding, adjusting to, and mastering these business metrics that will push your company toward sustainability in growth and profitability.**
--- START: blog/saas-growth-metrics/saas-growth-metrics.md ---
# **The Ultimate Guide to Key SaaS Metrics that Move the Needle**
## **Introduction**
The SaaS industry has a strong focus on growth, which can be attributed to the significant influence of venture capitalists (VCs). For a long time, VCs have prioritized high-growth projects, even if they were not generating profits and had high cash burn rates. This preference for growth has set the standard for the industry as a whole, making growth metrics essential for SaaS companies.
The emphasis on growth in Silicon Valley culture is not surprising. After all, it is what separates startups from SMBs. Startups that fail to grow fast will either go out of business or become SMBs in the best-case scenario. This cultural fixation with growth has helped produce analogies like the “hockey stick curve,” which refers to the exponential growth investors want to see from SaaS startups.
Despite the calls for prioritizing profitability over growth over the last twelve months, growth metrics are still critical for SaaS companies. We will take a long, hard look at five of them in this blog post.
## **What are SaaS growth metrics?**
SaaS growth metrics refer to the benchmarks SaaS companies can use to assess the quality of the growth they achieve. Growth metrics can be grouped into four categories:
- Acquisition-related (CAC, conversion rate),
- Activation-related (signups, number of apps created, number of contacts added),
- Revenue-related (MRR, ARR, average contract value),
- Retention-related (number of customers churned, amount of revenue churned, net revenue retention, Net Promoter Score, customer lifetime value) metrics.
## **Key takeaways**
- Growth metrics are essential to gauge the performance of a SaaS startup and decide whether it is worth an investment.
- While the SaaS industry was characterized by a “growth at all costs” mentality in the past, balancing growth and profitability has become a priority recently. As a result, the rule of 40 has become a popular metric in SaaS circles.
- A company with a high gross margin may be more highly valued than another with twice as much revenue but a much lower gross margin.
- Burn rate is a good indicator of how efficient your revenue generation activities are.
## **SaaS growth metrics in numbers**
- The average customer churn rate for a SaaS company is between [5-7 percent](https://recurly.com/research/churn-rate-benchmarks/), and a monthly churn rate of 3 percent is considered good.
- A good NRR rate for SaaS businesses is around [115 percent](https://youtu.be/D3Lwz-Pe1Yc?t=2540), according to Dave Kellogg.
- The gross profit margin for a successful SaaS company should be above [70 percent.](https://www.chargebee.com/resources/glossaries/saas-gross-margin/)
## **Why should you track SaaS growth metrics?**
SaaS growth metrics serve two fundamental purposes related to your operations and how your company will be seen by investors.
### **To monitor how the company is performing**
“_You can’t manage what you can’t measure._” Attributed to Peter Drucker, this quote sums up why you need to track your growth metrics. Quantifying your company’s performance enables you to see the things you are doing well and not so well and identify relations between different functions like customer acquisition, onboarding, sales, and marketing.
Growth indicates to outsiders a lot of information about your business. Strong growth validates the initial hypotheses you made about the market, the problem, and your solution. It also pulls a startup out of “_the chasm,_” the state of affairs where you don’t know whether what you are doing is right or wrong because there is no traction. Sustained growth starts the feedback loop and shows you what actions you should scale.
### **To attract investors**
Venture capital firms and angel investors believe in Power Law. In search of the next Airbnb or Facebook, they spread their funds over a wide range of investments, knowing beforehand that most of their investments will fail: Renowned angel investor Ron Conway puts the number for the failure rate at [40 to 60 percent.](https://www.youtube.com/watch?v=bgwqM6J3WeM) The handful of investments that pan out have to be so successful that the ROI of the whole portfolio will be positive.
That’s why investors hope to discover that generational technology or the next big thing and score a few home runs that will make up for these losses and produce a healthy return on all the money invested. When you are like Peter Thiel, who invested half a million dollars in Facebook and made around [$1.1 billion](https://www.angellist.com/blog/what-angellist-data-says-about-power-law-returns-in-venture-capital) from this investment for an ROI of 2,220X, you can easily forget about your investments that fizzled out. That’s why investors value growth over everything else.
You need to document your growth to win the hearts of people like Conway and Thiel. But how much growth does your SaaS company need? Neeraj Agrawal of Battery Ventures puts a number on it: He’d like to see his portfolio companies achieve [3X-3X-2X-2X-2X growth in ARR](https://techcrunch.com/2015/02/01/the-saas-travel-adventure/) over five years. So, a startup that has achieved $2 million in ARR will have to hit $6 million, $18 million, $36 million, $72 million, and $144 million to earn Agrawal’s backing.
[Jess Bartos of Salesforce Ventures](https://chartmogul.com/blog/5-saas-metrics-that-matter-to-investors/) agrees with Agrawal:
> "_[As investors,] we usually like to see getting from zero to one. From the time you launch your product to reaching a million of ARR in around 12 months or less. And then triple, triple, double, double, double —where you triple for two more years and then double every year from that._"
Tracking your growth metrics should be the first step on your checklist if you are planning to meet investors for fundraising purposes.
## **5 key SaaS growth metrics to monitor**
There are tens of SaaS growth metrics you may track, but very few can provide you with the kind of powerful insights the five metrics below offer:
### **Churn rate**
In the SaaS world, churn refers to the number of subscribers who cancel their subscriptions in a month, quarter, or year, expressed as a percentage of subscribers at the beginning of the period.
To calculate the churn, you divide the number of customers lost in a time period by the total number of customers at the beginning of the period and multiply the result by 100.
**Monthly Churn Rate = [(Number of customers at the end of the month) - (Number of customers at the beginning of the month)] X 100 / (Number of customers at the beginning of the month)
**
One should keep in mind that the churn rate calculated will probably understate the real churn rate, as there will be people who would like to churn but can’t because they are [bound by a contract.](https://medium.com/the-saas-growth-blog/the-ultimate-guide-to-saas-growth-metrics-2a4de6f1779) Therefore, excluding these people from the initial number of customers might be a good idea.
#### **Why does churn matter?**
Churn is the opposite of growth and works in a way that offsets it. A high churn rate is a symptom of the lack of product-market fit and can signal problems with your product, onboarding, customer support, and customer success functions.
Dan Martell taps into his experience as an entrepreneur and gives some practical advice on how to reduce churn in this video:
{{ youtube(id="viG8ocpkweo") }}
The real issue with churn is how monthly compounding can turn it into a menace to be reckoned with.
**Annual Customer Churn Rate = (1 — (1 — Monthly Churn Rate)^12)
**
Thus, a seemingly innocent-looking monthly churn rate of 6 percent will amount to an annual churn rate of 52.4 percent. That’s more than half of your customers gone within a year. Think for a moment that you had 1,000,000 subscribers at the beginning of the period and lost 524,000 of them throughout the year. _Ouch!_
For a more nuanced look at the churn rate, it would be wise to keep an eye on the revenue churn, as well. Losing a small number of customers can still cripple your business if those accounts turn out to be high-value accounts. Eliminating churn altogether is impossible because people die, they forget to renew their subscriptions, or their credit cards expire. But you can always focus on your Tier 1 accounts instead of the smaller deals if deal sizes vary across your customer base.
### **Net Revenue Retention**
Net revenue retention (NRR) is [the cumulative total of your retained, contracted, and expanded revenue](https://www.forbes.com/sites/forbesbusinesscouncil/2022/04/15/why-nrr-net-revenue-retention-is-the-one-metric-to-rule-them-all-for-saas/) over a period (a month, quarter, or a year), expressed as a percentage of revenue in that period.
For monthly NRR, you add the revenue you earned from upselling and cross-selling (expansion MRR) to the base MRR figure at the beginning of the period. You then subtract the revenue you lost due to downgrades to a lower pricing tier (contraction MRR) and churned customers (churned MRR). Dividing the result by the MRR figure at the beginning of the period and multiplying it by 100 gives you the NRR figure you are looking for.
**NRR = [(Starting MRR + Expansion MRR — Contraction MRR — Churned MRR) / Starting MRR] X 100
**
#### **Why does NRR matter?**
NRR is a measure of your customer success function and speaks volumes about how well your customers were able to extract value from your product. It doesn’t let revenue from new contracts cloud your judgment, as it excludes the revenue growth provided by the newly acquired customers, which could change the picture by making up for the revenue lost from churning or downgrading customers.
The NRR gives you two important insights:
- How much growth your existing customers can generate for your SaaS business,
- How happy your existing customers, the contracts you already won, are with your product.
NRR is a critical metric for SaaS companies because it shows the way to cost-effective growth: Reduce churn and increase customer lifetime value through upselling and cross-selling. Rather than pouring money into customer acquisition to sustain a leaky bucket model, NRR encourages you to [fix your onboarding issues](https://www.thesaascfo.com/how-to-calculate-net-dollar-retention/), give your customers a better product experience, and invest in your customer success team to increase revenue.
An NRR rate of 100 percent implies that you have a stable ARR base that is neither growing nor shrinking, without taking newly acquired customers into account. An NRR rate of greater than 100 percent tells you that your company is able to grow by leaning on its existing customer base alone.
[A study of 98 SaaS companies](https://blossomstreetventures.medium.com/benchmarking-net-dollar-retention-61c297eada93) that disclosed their net revenue retention rates at the time of their IPOs reveals that the median figure for these companies was 114 percent. For instance, Gitlab’s 179 percent NRR rate means that the company would be able to grow its revenue by 79 percent without acquiring a single new customer, which is nothing short of impressive.
### **Rule of 40**
The rule of 40 is a rule of thumb stipulating that [the combined revenue growth rate and profit margin](https://www.saasacademy.com/blog/rule-of-40) of a SaaS company should be equal to or greater than 40 percent.
**Rate of revenue growth + Profit margin ≥ 40
**
Instead of the established VC view that pushed for growth, growth, and more growth, the rule of 40 brings a more balanced view. It emphasizes that if you managed to grow your revenue by just 15 percent from last year, you would still be on the right track, provided that your EBITDA (earning before interest, taxes, depreciation, and amortization) was at least 25 percent.
The macroeconomic developments of 2022 made this rule of thumb more popular than ever. With the Fed tightening monetary policy through rate hikes, it became obvious that the cost of borrowing would go up. This meant that investors would be less enthusiastic about throwing money at every SaaS project coming their way. The drop in SaaS valuations and investors suddenly getting cold feet in backing projects were the signs that a sea change was underway.
VCs began warning their portfolio companies that there might not be a next round of fundraising and advised them to focus on profitability. Sequoia [gathered founders](https://www.sequoiacap.com/adapting-to-endure-2022/) to discuss different scenarios, and YC sent founders a letter titled "[_Economic Downturn,_](https://siliconangle.com/2022/05/19/y-combinator-warns-startup-founders-wary-economic-downturn/)" urging them to prioritize profitability over growth. The message was clear:
> “_The age of free cash is over. You’re on your own until you show us some results first._”
Here is a short video explaining how the rule of 40 tries to balance growth and profitability:
{{ youtube(id="w8KXVcLENWI") }}
#### **Why does the rule of 40 matter?**
- Rule of 40 underlines the importance of balancing growth with profitability rather than chasing growth at all costs.
- There is empirical evidence that healthy SaaS companies that have validated their business models and surpassed $1 million in ARR consistently perform at around this level, which makes this figure a good target to aim for.
It’s worth keeping in mind that the rule of 40 does not apply to early-stage SaaS firms, which find it almost impossible to turn a profit, and thus push for growth at all costs. It applies to SaaS companies that have reached some level of maturity and achieved $1 million or more in ARR, according to [Brad Feld](https://feld.com/archives/2015/02/rule-40-healthy-saas-company/), who popularized the rule.
Instead of Neeraj Agrawal’s 3X-3X-2X-2X-2X runaway growth formula, the rule of 40 shifts the focus to profitability at a much earlier stage. [The data gathered by Scale](https://www.scalevp.com/blog/a-quick-primer-on-the-rule-of-40) from its portfolio companies shows that 40 percent has been a threshold that mature SaaS companies consistently hit over a decade but found it difficult to surpass by a significant margin. Therefore, it serves as a very good proxy for approximating growth and profitability for a specific type of SaaS company.
{{ resize_image(path="../static/assets/images/blog-images/growth-rule-of-40.png", width=759, height=400, op='fit_width', alt="Median rule of 40 graph") }}
Graph showing the median value for the sum of revenue growth and gross margin for 68 publicly traded SaaS companies. The image was slightly modified for aesthetic purposes.
Image credits: [Scale](https://www.scalevp.com/blog/a-quick-primer-on-the-rule-of-40).
### **Gross margin**
Gross margin is one of the more traditional metrics that does not require you to jump through hoops to calculate it, but it is still a very valuable source of information.
Gross margin is gross profits presented as a percentage of total revenue. It is the amount of revenue left after the cost of goods is subtracted, expressed as a percentage of total revenue.
**Gross margin (%) = [(Revenue - Cost of Goods Sold) / Revenue] X 100
**
The gross margin figure is different from the net profit margin, which you find by further deducting the operational expenses and taxes.
SaaS businesses typically have a low cost of goods sold as they don’t incur production costs like the more traditional industries do. The COGS in SaaS involves hosting, maintenance, licensing fees, and the money spent on customer onboarding, support, and success. Thus, SaaS companies end up with gross margins of 70-80 percent, with a KeyBanc Capital Markets Technology Group survey putting the median gross margin for SaaS companies at [73 percent.](https://www.forentrepreneurs.com/wp-content/uploads/2021/10/2021-KBCM-SaaS-Survey.pdf) This figure is significantly lower for traditional industries like [aerospace and defense (17 percent) and consumer electronics (32 percent).](https://pages.stern.nyu.edu/~adamodar/New_Home_Page/datafile/margin.html)
#### **Why does gross margin matter?**
- Gross margin is a sign of your operational efficiency, showing you how much revenue you need to generate for a certain level of gross profit.
- The higher the gross margin, the more cash you will have to pay for operational expenses and reinvest in your business.
- Gross margin also speaks volumes about the value of your business. A company with an ARR of $5 million and 75 percent gross margin can be much more valuable than one with $10 million in ARR and just 25 percent gross margin, as the former will be generating three times as much profit per every dollar of revenue compared to the latter. Shrewd investors would be valuing the first company more highly than the second one.
### **Burn multiple**
The rough couple of years SaaS companies went through at the beginning of 2020s with regard to access to funds inspired come creative metrics that prioritize efficiency. One such metric is the burn multiple, popularized by [David Sacks](https://medium.com/craft-ventures/applying-the-burn-multiple-to-marketplace-business-models-6b8e9e4f8c94) during an economic downturn in the SaaS industry. Burn multiple is a measure of capital efficiency. It measures how much money is spent to achieve the current level of growth.
To calculate the burn multiple, David Sacks took Bessemer’s "[efficiency score](https://www.slideshare.net/BessemerVP/bessemer-venture-partners-2019-state-of-the-cloud-130798518)" and flipped it on its head.
**Efficiency Score = Net New ARR / Net Burn
**
**Burn Multiple = Net Burn / Net New ARR
**
In this inverted version, the formula gives you how much cash you need to burn to generate one unit of growth.
An early-stage SaaS company usually has burn multiples as high as 3 because it is spending a lot of money to test different hypotheses and experiment with different marketing and sales techniques. Also, there is little brand value to speak of, which could have brought in new customers without any added costs. However, if the burn multiple does not improve over time, it means that the company failed to find a more efficient way of generating revenue, which is a serious problem that requires immediate attention.
{{ resize_image(path="../static/assets/images/blog-images/growth-burn-multiple.png", width=759, height=400, op='fit_width', alt="burn multiples and what they mean") }}
Burn multiples and what they mean for SaaS companies. The image was slightly modified for aesthetic purposes.
Image credits: [The Burn Multiple | David Sacks](https://sacks.substack.com/p/the-burn-multiple-51a7e43cb200).
#### **Why does burn multiple matter?**
Burn multiple is important because any serious problem the company is experiencing on the cost or revenue fronts will be reflected either in the money spent or the ARR generated. David Sacks lists [five major problem areas](https://sacks.substack.com/p/the-burn-multiple-51a7e43cb200) that will have an impact on burn multiple:
**Gross margin** — A lower growth margin means you don’t generate enough revenue for the COGS you incurred. The burn will increase in such a situation, resulting in a worse burn multiple.
**Sales efficiency** — Problems with inefficient sales processes will result in an increasing burn multiple.
**Churn** — Churn will bring the ARR down, meaning the same burn will be raking in less revenue, causing a worse burn multiple.
**Traction and growth** — The futile marketing and sales efforts that fail to generate desired levels of traction and growth will show in the increased burn rate without a corresponding increase in revenue.
**Leadership** — A consistently high burn multiple is indicative of the possibility that the decision-makers do not have the skill or the will to improve this metric.
## **How does Peaka help you with tracking growth metrics?**
Gaining full visibility into your growth metrics requires you to
- Unify the data you have scattered across multiple platforms,
- Turn your consolidated datasets into a dashboard that reveals trends.
Peaka’s unique set of capabilities ticks both boxes.
- Peaka enables you to combine data from different sources, be they CRMs, databases, or SaaS applications, with zero-copy. It eliminates the need to first copy and move the data into a data warehouse. Without any ETL pipelines to build and maintain, IT teams become instantly more productive and channel their resources to core engineering activities.
- When it comes to visualizing data, Peaka supports ready-made integrations with top-notch BI platforms such as [Looker Studio](/blog/data-visualization-with-looker-studio-integration/), [Power BI](/blog/data-visualization-with-power-bi-integration/), [Tableau](/blog/data-visualization-with-tableau-integration/), [Metabase](/blog/data-visualization-with-metabase-integration/), and [Apache Superset™](/blog/data-visualization-with-superset-integration/). This allows you to turn your tabular data into dashboards, track saas metrics that matter, and generate reports without relying on the engineering team.
Peaka brings down the technical barriers to data integration and visualization and democratizes those tasks for everyone. It empowers business teams to self-serve without waiting for support from data teams, monitor key SaaS metrics and KPIs at all times, and make informed decisions based on real-time data.
## **SaaS growth metrics content to consume**
- Video–[The SaaS Business Model & Metrics: Understand the Key Drivers for Success](https://www.youtube.com/watch?v=5RR6M_d6eKcc) | David Skok
- Podcast—[5 SaaS Metrics that Matter to Investors with Jess Bartos of Salesforce Ventures](https://chartmogul.com/blog/5-saas-metrics-that-matter-to-investors/#h-growth-needs-to-endure-at-high-rates)
- Article–[SaaS Metrics 2.0 – A Guide to Measuring and Improving What Matters](https://www.forentrepreneurs.com/saas-metrics-2/)
## **Conclusion**
Growth metrics are indispensable to decision-makers at SaaS companies. However, they offer the most value when they are put into a context that offers visibility into the efficiency of operations, showing you not only how far you have come but also at what cost.
In essence, these growth metrics serve as a compass, guiding businesses toward their goals while identifying potential pitfalls along the way. By consistently monitoring these metrics, companies can make data-informed decisions, adapt their strategies, and ultimately boost their growth. Therefore, understanding and leveraging these metrics should be a top priority for businesses seeking to thrive in today's competitive landscape.
--- START: blog/saas-ideal-customer-profile/saas-ideal-customer-profile.md ---
# **How to Create an Ideal Customer Profile for SaaS Businesses**
## **Introduction**
Rising above the marketing noise in this day and age is the number one concern for marketing teams. How do you get your message across to your audience, who have been exposed to similar messages from a plethora of different mediums? It is this particular concern that led to the emergence of account-based marketing (ABM).
Instead of churning out marketing content to saturate every communication channel and reach every kind of customer, ABM focuses on a handful of target accounts. It emphasizes undertaking research to better understand the needs of those targeted accounts and produce personalized content for them. At the center of this strategy is the "ideal customer profile" (ICP) concept.
## **What is an ideal customer profile?**
An ICP is "[the type of company that would benefit the most from your product or service.](https://about.crunchbase.com/blog/what-is-an-ideal-customer-profile-and-how-do-you-create-one/)" The term does not refer to your potential customers, though. ICP corresponds to a much more focused group of customers who are a fit for your product and aware of their pain. These customers are actively looking for a solution to a problem, thus motivated to make a purchase.
Finding and detailing customer personas is nothing new. You probably built up profiles like "[Amy the accountant](https://www.uxbooth.com/articles/whats-in-a-name-how-to-select-a-name-for-your-persona/)" or "Tony the technician" at some point in your career. Working to generate customer personas is a fun exercise that you do because you were asked to do but then put aside and never look back on later. Because customer personas are rarely actionable. That's why people have developed tools like Strategyzer's [business model canvas](https://www.strategyzer.com/canvas/business-model-canvas) to join customer personas with value propositions and specific actions to be taken.
## **Key takeaways**
+ ICP is an account-level concept that refers to the companies that will become your best-fit customers. It differs from a buyer persona, which corresponds to the individuals within an account.
+ ICP stands on four pillars: Firmographic data, demographic data, technographic data, and psychographic attributes.
+ Creating an ICP is not a one-and-done exercise. The ICP has to be updated and optimized depending on the market conditions and the macro-level changes in the economy.
+ [Peaka’s HubSpot-Stripe integration](/blog/integrations-hubspot-stripe/) is the kind of capability you need to merge your revenue and CRM data and discover which accounts you must target.
## **ICP in numbers**
+ Organizations with well-defined ICPs achieve [68 percent](https://blog.hubspot.com/marketing/account-based-marketing-stats) higher account win rates.
+ Messaging built around ICPs can work wonders. Personalized emails can drive [18 times](https://salesintel.io/blog/the-most-important-things-to-consider-when-creating-your-ideal-client-profile/) more traffic than non-personalized emails.
+ A study conducted by the Insight for Professionals community revealed that [60 percent](https://www.inboxinsight.com/advanced-abm-lookalikes-uncover-the-priorities-within-your-icp/) of senior B2B marketers use ICP to identify and prioritize market opportunities.
## **Target audience vs. Potential customers vs. ICP vs. Buyer persona**
These four terms refer to a group of people with varying degrees of potential to become your customers. They can actually be thought of as a funnel or pyramid with increasingly better-defined needs, representing a better fit for a product.
### **Target audience**
Your target audience simply refers to the market segment you are addressing. This group consists of people sharing the same pain points, but they lack the fit and motivation components, which renders them too broad a category to focus on.
### **Potential customers**
These are the members of your target audience for whose needs your product is a good fit. Your value proposition resonates with these people. You will be top of mind for these people when they get the motivation to shop to satisfy that need.
### **ICP**
ICP corresponds to a subset of your potential customers who, in addition to pain and fit, also demonstrate a motivation to buy your product. Your ICP has a pain, knows about available solutions, thinks your products can solve his problem, and shows a readiness to make a purchase.
### **Buyer persona**
This term refers to the members of the buying committee in your target account. Among this group are the everyday users who personally use a product, managers who oversee the work of everyday users, and executive decision-makers who write the check. There can be other people involved in roles like champions, influencers, or blockers.
See this short video by product-led growth guru Myk Pono for a quick look into the differences between these four concepts:
{{ youtube(id="Y1u-ngsyH60") }}
## **Why do you need an ICP for your SaaS company?**
If you are running a SaaS company, you need an ICP because "[not all customers are created equal.](https://www.linkedin.com/pulse/all-customers-created-equal-eli-weiss/)" You need an ICP because your resources are scarce, no matter how much money you have raised. You need an ICP because some segments offer higher value and much higher return on the marketing dollar you spend.
ICP is a handy tool for understanding, segmenting, and acquiring customers. [Myk Pono](https://www.mykpono.com/ideal-customer-profile-icp-how-to-create-a-comprehensive-customer-profile/) sums it up well:
> “*... [U]nderstanding your customers requires you [to] first understand the whole marketplace and then zero in on an ideal customer profile to pursue. Understand first, then segment. It's also worth noting that picking the right market and the right customer can decrease your customer acquisition cost (CAC).*”
Here is a brief look at the benefits SaaS businesses may expect from a well-defined ICP:
+ **ICP provides you with a blueprint you can use to acquire more customers similar to the ones who are the best fit for your product.** ICP reduces the time it takes to generate leads and vet them. Sales and marketing teams have more time to focus on high-value accounts without wasting time on prospects who will either not make a purchase or churn after the buy. By focusing on the ICP, you can produce personalized content that will be much more effective than generic content in converting people.
+ **Your ICP represents the people who will be your most loyal customers once you convert them.** They will buy more, upgrade more and make your product a bigger part of their lives. Nailing the ICP is a surefire way of [increasing the customer lifetime value.](https://www.linkedin.com/pulse/importance-getting-your-ideal-customer-profile-icp-right-panchagiri/)
+ **ICP provides you with a scalable template for your [account-based marketing strategy.](/blog/account-based-marketing-saas/)** ICP refers to the low-hanging fruit for your customer acquisition engine, as these are the companies with a problem that your product solves and a willingness to solve the problem. They are receptive to your value proposition and messaging, which brings down your customer acquisition cost. As the ICP is a better fit for your product, it is also more likely to be an evangelist. By creating an ICP, you are actually developing an [actionable plan](https://www.gartner.com/en/articles/the-framework-for-ideal-customer-profile-development), not just engaging in a simple thought exercise.
## **Pillars of a well-defined ICP**
There are four parameters you should work on to ensure that your ICP can inform your future marketing and sales effort.
### **Firmographics**
Firmographics are the attributes of a company that help you place that particular company in a segment. These attributes give you a reference point, enabling you to compare metrics with those of other companies with similar firmographic data. Firmographic data should include:
+ Company size
+ Vertical
+ Country
+ Annual revenue
The HubSpot-Stripe integration allows the user to pull 'country' data from HubSpot and combine it with 'pricing plan selected,' 'amount charged,' and 'invoice paid' data from Stripe. This integration gives you valuable insights into how your MRR and revenue differ from one country to another. It also reveals whether the demand for different pricing plans varies depending on the location.
### **Technographics**
Technographics refer to the tech stack a company uses. Information on the tech stack can reveal valuable insights into how a particular company works, its pain points, and how processes can be improved.
Technographics is a great tool to find the best match for your product and [make a shortlist of best-fit customers.](https://youtu.be/RqN41GVY6UQ?t=256) There are tools like [Built With](https://builtwith.com/) that can help you explore the tech stack of a company. The fact that a business is using products from your competitors can qualify that company as a good candidate for your marketing and sales efforts. Knowing in advance the kind of technologies a company employs can help you understand which one of them your product can work with and which ones it can replace. The existing tech stack is a good indicator of the fit between a customer and a product.
### **Demographics**
While firmographics involve the attributes of a target account, demographics refer to the characteristics of the buyer personas within that account. These characteristics give you a better picture of who you will personalize your content for and work with to close a deal. The demographics include information on the following parameters:
+ Age
+ Gender
+ Job title and position
+ Place in the decision-making mechanism
+ Skills and expertise
+ Needs and pain points
+ Motivations and triggers to seek a solution
### **Psychographics**
Psychographics are the sum total of the values, motives, goals, and aspirations that cumulatively make up the culture of a company. Psychographic data provides us with information on critical issues like the power structure, how authority is shared and decisions are made, risk tolerance, and what the organization aspires to become in the future.
Here's how Dan Martell goes over these four pillars and more in nine minutes:
{{ youtube(id="RqN41GVY6UQ") }}
## **4 steps to create the perfect ICP for your SaaS company**
### **Identify your highest-value customers**
+ Make a list of your current customers.
+ Identify the high-value accounts on that list. This involves determining the customers who have generated the most revenue for your business, spotting the repeat buyers, and those who upgraded to a more expensive pricing plan or bought other products from you.
### **Establish a segmentation pattern for your best-fit customers**
+ Analyze the attributes of your high-value accounts and find out [commonalities.](https://about.crunchbase.com/blog/what-is-an-ideal-customer-profile-and-how-do-you-create-one/#toc-how-do-you-create-an-ideal-customer-profile)
+ [Study the firmographics](https://youtu.be/pRuy3yp85yM?t=1065) of these customers and try to discover a [pattern.](https://www.saasceo.com/ideal-customer-profile/) Where are they located? In which industry do they operate? How many employees do they employ? Are they bootstrapped? If not, how much funding have they raised?
+ Connecting the dots between the common attributes will reveal the outlines of your ideal customer profile. However, this still is a rudimentary definition, which you will clarify in the next phase. Here, a tool like Peaka that can join and blend your revenue and CRM data can help you isolate the characteristics of your best-fit customers by allowing you to break down the data into meaningful components.
### **Hone your rudimentary ICP**
+ The silhouette of an ICP you formed in the first phase will not be enough to build an actionable plan. To create a more granular picture of your ICP, you must enrich your initial findings with demographic, technographic, and psychographic data.
+ Discover the stakeholders who make up the buying committees in your target accounts and try to understand the way decisions are made. Distinguishing between the daily users, managers, and check signers goes a long way toward understanding who can be your allies and who will likely block your efforts in the future.
+ What kind of tools do your best-fit customers have in their tech stacks? Do they use any products from your competitors? What are the friction points the daily users of these tools complain about?
+ Does the company culture in your best-fit customers allow for feedback from frontline workers? How open is the management to purchasing new tools, employing new techniques, and fine-tuning established processes? What are the growth objectives they are chasing?
+ Your research into the demographic, technographic, and psychographic data of your customers gives you visibility into a typical "[day in the life of your customer.](https://medium.com/@StartupBusinesstips/how-to-create-a-powerful-ideal-customer-profile-icp-83531bf603d9)" By walking in the shoes of your high-value accounts, you will understand the problem they had, what made your product a good fit for them, and the triggers that made them purchase your product. You can use this information to develop a customer acquisition template that can apply to companies with similar pains.
### **Adjust your value proposition**
+ There has to be a near-perfect fit between the value you propose at the beginning and what your ICP expects from. It is thanks to this fit that you will be able to gain customers without incurring high acquisition costs.
+ Your value proposition can be compelling for your initial customers, but that group will probably be too small to help you achieve your revenue goals.
+ You will have to expand into adjacent segments to secure a customer base big enough to fund your operations. This means drifting away from your initial ICP and appealing to customers who are not as motivated to purchase your product.
+ Therefore, your ICP definition will have to change a little bit. Your value proposition has to change, too, to accommodate the broader ICP you target.
## **Mistakes to avoid while searching for an ICP**
Nailing the ICP can be quite a challenge, with lots of parameters factoring in. The following are the three most common mistakes:
### **Going too broad or narrow with the ICP**
Your ICP refers to the group of customers who have a pain your product solves. Companies fitting this description will be the most receptive to your messaging, and their motivation to buy will be strong. However, there is a delicate balance to strike while defining your ICP. If you keep it too narrow, it will be easy to create hyper-personalized content for your target accounts, but their number will be too few to help you hit your revenue goals. An ICP that is too broad will [dilute your message](https://www.kalungi.com/blog/nailing-b2b-saas-icp) and make it difficult for you to focus on a subsegment that can drive your growth.
Make sure that your ICP is limited to the narrowest possible group that will allow you to realize your business objectives. ICP definition can be expanded as the need arises, which brings us to the second common mistake.
### **A stagnant ICP definition**
Your first ICP is based on [intuition.](https://www.saasceo.com/ideal-customer-profile/) You haven't launched your product yet and have no data to speak of, just a gut feeling telling you who will be your best-fit customers.
If everything goes well, your initial ICP will serve as your engine of growth, and your product will appeal to people outside this core group of customers. You will soon acquire new customer groups who adopt your product, hack, and use it in ways that you did not foresee before. If you aim to create a customer acquisition flywheel for these customers, your initial ICP definition will not offer you much help.
This is why you need [dynamic ICPs](https://www.linkedin.com/pulse/5-common-mistakes-avoid-when-defining-your-ideal-customer-profile/) that you constantly update. ICPs that do not perform up to expectations get eliminated while new ones are created. Keeping an eye on revenue from different customer segments and enriching them with customer data, you will be continuously optimizing your ICPs so that target accounts with different characteristics can get the personalized content to convert them.
### **Failing to blend qualitative and quantitative data**
While creating an ICP, historical data may fail to tell the whole story without a human touch. What looks like a decent segment right now may be a shrinking one or about to be completely replaced by something else (like the EV technology replacing the internal combustion engine today).
Field teams who directly deal with customers can provide the ABM teams with the contextual information they need to evaluate the potential of different segments and help mitigate these risks. The SDRs can spot growing trends and latent problems in a segment that will be hard to detect in revenue data, providing [feedback](https://blogs.gartner.com/greg-hessong/3-common-mistakes-in-building-an-ideal-customer-profile-icp/) that can be used to fine-tune the ICP. That's why successful ABM teams have an active SDR component that keeps the rest of the team up-to-date about the market.
## **How can Peaka help you fine-tune your ICP?**
ICP is the product of customer segmentation and represents the highest-value segment in your target audience. This segmentation needs to be based on the revenue from each customer profile. Forming an ICP requires enriching the revenue data with the customer attributes you keep in a CRM.
This is one of the strong suits of Peaka. Peaka allows users to pull in the revenue data from a payment processing platform and blend it with the CRM data. Peaka's HubSpot-Stripe integration makes things even easier, providing a one-click data integration between two popular SaaS platforms. Having consolidated their data, users can run queries and break down the data into different firmographic components, which reveals the best candidates to become the ICP.
## **ICP content to consume**
+ Video—[WEBINAR: How to Create an Ideal Customer Profile (ICP) | MYK PONO](https://www.youtube.com/watch?v=pRuy3yp85yM)
+ Video—[How to Define the Ideal Customer Profile for Your B2B SaaS Company](https://www.youtube.com/watch?v=RqN41GVY6UQ)
+ Podcast—[Your Ideal Customer Profile and How to Identify It](https://www.madkudu.com/blog/customer-profile)
+ Article—[Ideal Customer Profile (ICP): How to Create a Comprehensive Customer Profile](https://www.mykpono.com/ideal-customer-profile-icp-how-to-create-a-comprehensive-customer-profile/)
+ Article—[How to Establish a SaaS Ideal Customer Profile (ICP)](https://breyta.io/touchpoints/saas-ideal-customer-profile)
+ Article—[3 Steps to an Ideal Customer Profile](https://www.saasceo.com/ideal-customer-profile/)
## **Conclusion**
Sometimes "less is more." It's this kind of thinking that guides people to invest in creating ICPs. A well-defined ICP can create high levels of growth by concentrating resources on better prospects.
However, defining the ICP is both an art and a science. It has to be a data-driven process, for sure, but data alone will not suffice. It takes a comprehensive approach and a lot of iterations to blend data with first-hand experience from the field. It all starts with intuition, builds on research, and requires human expertise to find its final form.
--- START: blog/saastock-usa-2024/saastock-usa-2024.md ---
# **SaaStock USA 2024: Peaka Back in Austin**
The event season is in full swing, and one of the most special events is right around the corner: SaaStock USA 2024.
This year's conference will be held at Palmer Events Center in Austin from May 13 to May 15. With more than 1500 attendees, 500 companies, and 60 speakers expected in just three days, it will be jam-packed with networking and partnership opportunities for like-minded people.
## **SaaStock 2023: Lessons learned**
SaaStock USA is an event that is particularly close to our hearts at Peaka. It’s because last year’s gathering was the first major event Team Peaka had attended after our rebranding.
We had just pivoted from a B2C no-code app development platform to a B2B data integration platform in Spring 2023. When our product manager Burak and I landed in Austin in our Star Wars-themed t-shirts, we had one thing on mind: How we could make the most of SaaStock ’23. With a mission to make data integration accessible to startups, we were determined to capitalize on this event to meet as many startups as possible, test our hypotheses, and refine our ICPs.
{{ resize_image(path="../static/assets/images/blog-images/saastock_2023_peaka_t-shirt.png", width=759, height=400, op='fit_width', alt="burn multiples and what they mean") }}
Team Peaka rocking our Star Wars-themed t-shirts at SaaStock USA 2023.
During the event, I gave a keynote speech about how successful data integration initiatives could drive growth in SaaS companies. Although data integration is often seen as the domain of enterprises, startups and SMBs have data integration needs that are often overlooked. The speech laid out the rationale behind Peaka’s focus on developing solutions for these types of companies: Startups were facing data challenges earlier than anticipated, and they needed a sound plan for data integration right from the outset.
{{ resize_image(path="../static/assets/images/blog-images/saastock_2023_mustafa_growth_stage.png", width=759, height=400, op='fit_width', alt="burn multiples and what they mean") }}
Peaka CEO Mustafa Sakalsız seen during his speech at the Growth Stage during SaaStock USA 2023.
The feedback we received in Austin proved pivotal in shaping the recent trajectory of our platform. It confirmed our belief that startups and SMBs with a headcount of 20-200 people and newly-forming data silos would be our target segment. Over the past year, we have been diligently crafting solutions for startups that have reached a certain scale and started facing data-related challenges. These startups, often constrained by limited resources to invest in enterprise-grade products or maintain large data teams, have become the focal point of our platform's evolution.
## **SaaStock 2024: What’s ahead?**
This year’s SaaStock is poised to be even busier and more exciting than last year’s event. Here is a brief look at our schedule:
### **May 13**
As part of the SaaStock Startup Program, Team Peaka will meet with investors and attend a series of workshops at Inn Cahoots on May 13. The Startup Program will be a good opportunity for us to show where our platform stands a year after our launch, demonstrate its capabilities, and explore future partnerships with people and organizations who need a more streamlined data integration process.
### **May 14 & 15**
We will be at Palmer Events Center for the last two days of SaaStock ’24 (May 14 and 15). We are currently setting up meetings with other participants with the aim of having a full schedule by the time we touch down in Austin. Our team will offer one-on-one demos of Peaka at our booths at R3 & R4 and discuss individual use cases with attendants. High on our agenda are two particular topics:
**Our zero-ETL approach to data integration:** Team Peaka will demonstrate how data virtualization is the ideal data integration solution for startups with limited resources. With federated query capability, streaming ingestion, and change data capture (CDC), Peaka makes [zero-ETL](/blog/zero-etl-vs-modern-data-stack/) accessible to startups, allowing them to consume data regardless of source and without having to build and maintain ETL pipelines. Peaka’s zero-ETL enables SaaS startups to leverage their data while staying nimble and flat.
**Our serverless connector infrastructure:** We are particularly looking forward to meeting founders of AI startups who are striving to easily integrate with their customers’ tech stacks and ship more connectors faster. Building an integration, which usually takes weeks, is one thing, but maintaining those integrations is quite another. Under pressure to launch a series of integrations to convert leads, maintain connectors, and carry out daily operations, these organizations are stretched too thin.
With its [serverless connector infrastructure](/blog/startups-connector-infrastructure/) that offers connectivity to 300+ relational and NoSQL databases, APIs, and SaaS tools in minutes, Peaka can single-handedly enable AI startups to scale their operations.
On May 15, I will take to the Growth stage once again, this time for a speech titled “*The Top 5 KPIs You Should Be Tracking to Scale in 2024.*”
I think this is a good time to talk about what high-quality growth looks like. The last two years have been a rough ride for SaaS companies around the world, and the *growth-at-all-costs* mentality no longer seems to hold true. Instead of throwing money at every project with some potential, venture capital firms now prioritize profitability over growth. I will try to offer a new perspective on how to quantify various aspects of growth and the different metrics that tell us about the health of a company in my speech.
## **Final thoughts**
SaaStock USA is a great venue for a company like Peaka that offers innovative solutions to niche problems. It brings us together with many of our target users and almost feels like running a 3-day focus group. Last year’s event was a rewarding experience that helped set us on our course for a year. Here’s hope that this year’s event will be even better.
--- START: blog/self-service-data-integration/self-service-data-integration.md ---
# **What to Know About Self-service Data Integration**
One of the main themes of the fast change we are going through is the "democratization" of technology. The basic premise of this fancy expression is quite simple: It refers to ever bigger masses enjoying the benefits of technological breakthroughs, which helps level the playing field to some extent and change lives.
Our journey from mainframe computers in select few institutions to workstations at the office to personal computers in every house and smartphones in every pocket has been one of democratization. Low-code/no-code tools are democratizing software development, for example. People love ChatGPT because it made AI accessible to the masses, democratizing the field. The next frontier in this wave is data integration because data is at the core of any technological breakthrough, and without democratizing data, there will be no real democratization.
## **Difficult trade-offs**
Every effort to democratize technology has to involve some level of abstraction. This abstraction lowers the technological barriers and opens up certain technologies to more people. The improved accessibility comes at a price, though: Flexibility and certain capabilities are sacrificed for usability because of the limitations of regular users. The new abstraction level should empower people with limited knowledge to help themselves without getting lost, creating security risks, or causing trouble for others.
This rule applies to data integration as well. In an ideal world, self-service data integration brings the popular "[do-it-yourself](https://www.linkedin.com/pulse/era-self-service-data-integration-meitav-harpaz/)" attitude to the office. It allows frontline workers who consume data to solve problems by accessing, curating, and bringing together their data on their own, without the direct involvement of an IT team. By doing that, self-service data integration fulfills three objectives:
* Overcoming the bottlenecks formed by the backlog of data integration requests waiting to be handled by the IT people
* Liberating the software engineers from the day-to-day chores of attending to the requests from business units so that they can focus on more high-level tasks like improving the [performance, uptime, and the overall security of the system](https://tdwi.org/Articles/2013/01/08/Self-Service-Data-Integration.aspx?Page=2)
* Reducing the size and the payroll of the IT team as subject matter experts can become self-reliant in data integration.
## **Checks and balances**
But there is a caveat. Self-service data integration can become a disaster without well-defined user [privileges, permissions, and role-based security measures.](https://www.dataversity.net/self-service-data-integration/) Without these in place, an organization would be opening its sensitive data to people who should not see it or do not have the capabilities to handle it. This would be a disaster in many industries like health, defense, and finance. This immense security risk is among the reasons for the lack of a bigger push toward self-service data integration in the enterprise segment.
This brings up the issue of data governance. Just like the abstraction level in software causes a trade-off between usability and capability, data governance and management needs are a source of a [trade-off between usability and security](https://medium.com/datalogue/fixing-the-data-integration-problem-b0620af946d8) in data integration. Enterprises cannot afford to take risks with security, and when they impose data governance and management principles, tools [quickly become too sophisticated](https://medium.com/datalogue/fixing-the-data-integration-problem-b0620af946d8) for non-technical users to use. SMBs and startups are more fortunate as they don't have as much sensitive data.
## **'*Tell me doc, am I self-serving or self-deceiving?*'**
Considering these limitations, trade-offs , and challenges, is self-service data integration even possible? Or is it just a fantasy we are served as part of a marketing campaign?
Self-service was not a thing in the data integration space for years because we did not have [easy-to-use data integration tools](/blog/top-data-integration-tools/) at hand. Therefore, we were dependent on a handful of skilled engineers. These people had to build data pipelines for each data source, an overwhelming task that was not scalable in an enterprise environment.
Against this backdrop, it is safe to say that products that were claiming to let users self-serve without offering a data integration capability were, in fact, pseudo-self-service. Assuming that the user would somehow bring the data together, they instead focused on empowering the users in the later stages. Data would be put together by engineers, and then the data consumers would use it to build dashboards or perform business analytics.
However, there is more to self-service data integration than just [building real-time dashboards.](/blog/servicetitan-power-bi-integration/) For non-technical users to be able to self-serve, everything should start with integrating data. A seamless and preferably automated ETL process would be a good start to reduce employees' reliance on the IT department.
This is where the [data virtualization technique](/blog/data-virtualization-no-code/) comes in. Data virtualization makes self-service even more achievable as it removes ETL altogether and eliminates the need for engineers to be involved. It is empowering because frontline workers can leverage it to consolidate their data, create a single view of truth, and run any kind of business analytics without having to wait for technical people to respond. This technique truly holds the key to genuine self-service data integration.
Peaka has leveraged data virtualization to introduce [zero-ETL data integration](/blog/zero-etl-vs-modern-data-stack/). By removing the transformation phase in ETL, zero-ETL also eliminates the need to engineer data so it fits the schema of the destination. Thanks to query federation, Peaka enables users to query data at the source, eliminating the need for costly data warehouses and big data teams.
## **Conclusion**
Software has been eating the world for over a decade, and for that to continue, developers need our help. Democratization of the tech in this context is not a nice-to-have but a necessity. People need to be able to create apps on their own, leverage AI tools, and bring their data together without the involvement of developers so that technical people can keep us moving forward. By adding a data integration capability to our sophisticated no-code platform, that's exactly what we are trying to achieve at Peaka.
--- START: blog/servicetitan-dashboards-no-data-team/servicetitan-dashboards-no-data-team.md ---
# **How Trades Businesses Can Track KPIs without a Data Team**
Home service businesses would like to make data-driven decisions as much as any other business. But when it comes to turning ServiceTitan data into business intelligence, most home service companies run into the same problem: Data tools are built for companies with data engineers and analytics teams, which HVAC, plumbing, and roofing cannot afford.
Instead, they end up with a choice between outdated spreadsheets or expensive consultants. Neither is scalable. Neither gives the team the control or visibility they need to grow.
It is time for a new playbook. Business intelligence without engineers is no longer a fantasy. With the right tools, it is achievable—and practical—for growing home service companies.
## **Key takeaways**
+ **Home service teams fail to get value from BI tools:** Due to the challenges of integrating ServiceTitan with BI tools, most BI initiatives in home service companies fail to deliver value.
+ **Spreadsheets and consultants are not scalable solutions for reporting:** Manual reporting wastes time and money, while outsourced dashboards are expensive to update and lack flexibility.
+ **Peaka enables self-serve BI without a data team:** Peaka offers seamless data integration between data sources and BI tools, helping home service businesses unify their data and track key metrics without engineering overhead.
## **Why home service businesses struggle with BI tools**
As powerful as ServiceTitan is for managing jobs and operations, getting actionable, visual reporting out of it remains a pain. Its built-in reports are limited, and exporting data manually to build dashboards in Excel is time-consuming and error-prone. Most BI tools, meanwhile, are too complex to integrate with ServiceTitan directly—especially without technical help.
Business intelligence platforms like Power BI, Looker, or Tableau promise powerful insights. But for most contractors, BI projects rarely get off the ground.
Here is why:
+ Data integration remains the biggest challenge, as BI tools can be too complex to integrate directly with ServiceTitan, especially without technical assistance.
+ BI tools require some technical skill to set up and model data before building dashboards.
+ Most teams do not have SQL skills or data analysts on staff.
+ For the more capable but technical options like Tableau, the learning curve is steep, and the payoff takes too long.
+ The more user-friendly options, like Looker Studio, come up short in the customization department.
Without a simple way to integrate and prep ServiceTitan data, these tools sit unused or create more confusion than they solve
## **The risks of spreadsheets and outsourced dashboards**
To work around the BI gap, many companies fall back on Excel. However, spreadsheets require constant manual updates, are prone to human error, and quickly become outdated. Copying and pasting data from ServiceTitan each week just to calculate job costs, margins, or technician performance can become a full-time job.
Others try to escape this cycle by hiring consultants to build one-off dashboards. But these dashboards are often hard to update, rely on static data, and break as soon as the business changes.
Neither approach provides the real-time visibility into operational data that operators need to make fast, confident decisions.
## **What “BI without engineers” actually looks like**
There is now a third option—lightweight, self-serve data platforms designed for non-technical teams. These platforms remove the heavy lifting around ServiceTitan reporting and make it easy to build live dashboards using your existing BI tools.
With this option, you can
+ Connect your systems to any data source and pull in data
+ Choose the metrics that matter most to your business
+ Send your consolidated data to your BI tool of choice
+ Get real-time updates as your dashboards will refresh automatically without any need for [manual data exports](/blog/servicetitan-manual-data-export-costs/)
This gives ops, finance, and leadership teams the freedom to explore and act on their KPIs without relying on IT, analysts, or spreadsheets.
## **The new BI playbook for contractors**
If you are running a $5M or $50M home service company, here is the new playbook for getting value from your ServiceTitan data:
**Step 1: Connect your data sources**
Plug in your operational systems like ServiceTitan and your financial tools like QuickBooks or Sage Intacct.
**Step 2: Define the metrics that matter**
Focus on the KPIs that drive your business—[job cost](/blog/track-job-costs-servicetitan/), margin per job type, tech performance, and close rates.
**Step 3: Push your data to a BI tool for visualization**
Turn your tabular data into visualizations by sending it directly to [Looker Studio](/blog/how-to-connect-servicetitan-to-looker-studio/), [Power BI](/blog/servicetitan-power-bi-integration/), [Metabase](/blog/how-to-connect-servicetitan-to-metabase/), Tableau, or some other tool.
**Step 4: Share and act on insights**
Distribute dashboards across your team so everyone is aligned on what is working and what needs fixing.
## **How Peaka makes this possible**
Peaka is purpose-built for home service businesses using ServiceTitan. It enables non-technical teams to unify their operational and financial data and send it to BI tools with zero engineering effort.
+ It connects natively to [ServiceTitan, QuickBooks, and Xero](/blog/servicetitan-finance-integration/)
+ It includes a semantic layer so you can define business terms like “gross margin per job” without using code
+ It is designed for operators, not engineers, and enables you to send your data to any BI tool using a no-code interface
+ It makes data available to even the non-technical employees in an organization, empowering business units to make informed decisions
With Peaka, your team no longer has to wrestle with ServiceTitan exports or wait on custom dashboards. You get reliable, analysis-ready data where you already build reports: Your BI tool.
## **Conclusion: It's time for a purpose-built solution**
Business intelligence should not require a data team or a six-figure budget. And it should not require hours of copying and pasting from ServiceTitan every week.
Home service operators need visibility, and now Peaka gives them a faster way to unify their data, track critical KPIs, and scale reporting—all without hiring engineers or building a custom data stack.
The new playbook is simple:
Connect your data. Track the metrics that matter. Build dashboards you can actually use.
And grow with confidence.
Ready to power your dashboards without hiring a data team?
[Sign up to Peaka](https://peaka.studio/signup) for free today.
[Book a demo](https://calendly.com/peaka/demo) to see how Peaka empowers non-technical teams with real-time reporting.
--- START: blog/servicetitan-finance-integration/servicetitan-finance-integration.md ---
# **How to Unify ServiceTitan + QuickBooks in One Reporting View**
Home service businesses often find themselves running two different companies under one roof. The operations team lives inside ServiceTitan, monitoring dispatches, job status, and technician performance. The finance team, on the other hand, works with QuickBooks, Sage Intacct, or Xero, focusing on margins, revenue, and cost controls.
Both teams are looking at the same business. Yet, they often struggle to agree on what the numbers are actually saying.
This disconnect slows down decision-making, creates friction, and ultimately hurts growth. But with the right approach, it’s fixable.
## **Key takeaways**
+ **Ops and finance teams often work from disconnected systems:** ServiceTitan and accounting platforms operate in silos, making it difficult to get a unified view of performance.
+ **Manual reporting wastes time and leads to misalignment:** Exporting data into spreadsheets slows teams down and creates conflicting reports that delay decisions.
+ **Peaka bridges the gap with live, unified dashboards:** By connecting ops and finance data in one place, Peaka enables real-time insights without the need for a data team.
## **One business, two realities**
Picture this: Your operations manager claims the last two weeks were a win. Jobs were completed on time, techs were efficient, and revenue looked strong in ServiceTitan.
Then your controller runs the numbers in QuickBooks and reports that margins are down and [job costs](/blog/track-job-costs-servicetitan/) are trending in the wrong direction.
Who’s right? The answer often requires someone to manually stitch together data from multiple sources just to get a clear view. That takes time. And by the time the full picture emerges, the business has already moved on.
This is the reporting gap between ops and finance. And it’s more common than you think.
## **What the disconnect looks like in practice**
When operational and financial data are siloed, confusion becomes routine:
+ Finance flags a drop in gross margin, but has no context on the type of jobs completed.
+ Ops highlights a high-performing technician, only to find their jobs are consistently unprofitable.
+ Executives ask for a board-ready report. Each team submits a different version of the truth.
This back-and-forth creates inefficiencies. More importantly, it prevents leadership from making timely, confident decisions.
## **Why bridging the gap is so difficult**
For most growing contractors, the challenge isn’t a lack of interest. It’s a lack of infrastructure.
+ ServiceTitan focuses on scheduling, dispatch, and customer experience. It doesn’t natively track job profitability.
+ Accounting platforms like QuickBooks or Xero track financials but lack operational context.
+ There’s no internal data team to build custom integrations or reporting pipelines.
+ Buying off-the-shelf is not an option, as there are no products on the market that are purpose-built for the needs of home service businesses, but rather only enterprise-grade offerings that are expensive to purchase and costly to operate.
So teams fall back on what they know: [Manual data exports](/blog/servicetitan-manual-data-export-costs/), spreadsheet workarounds, and disconnected dashboards.
The result is a fragmented view of the business.
## **The cost of disconnected reporting**
Falling back on manual data replication can be a short-term fix, but not a long-term solution for a company looking to grow. These companies will eventually have to face the consequences of working with different data sets:
+ Job profitability is often unclear until weeks later
+ Technician performance is misinterpreted without context on revenue or cost
+ Financial forecasts are built on assumptions rather than real-time metrics
These problems don’t just slow down reporting. They undermine the organization’s ability to operate effectively in a rapidly changing competitive environment. Without accurate visibility, it’s hard to plan new hires, expand into new markets, or adjust pricing strategies.
## **What integrated reporting actually looks like**
A unified reporting system solves these problems by bringing ops and finance data into one shared dashboard. No more guesswork. No more conflicting reports.
Imagine dashboards that show:
+ Job revenue versus job cost per technician
+ Gross margin by job type or location
+ Real-time tracking of backlog and revenue targets
+ Marketing ROI alongside dispatch efficiency
Everyone works from the same data. Teams stay aligned, and leaders get the clarity they need to act fast.
## **How Peaka bridges ops and finance**
As an [official ServiceTitan partner](/blog/peaka-servicetitan-bi-integration/), Peaka makes this kind of integration possible for home service businesses—[without a data team](/blog/servicetitan-dashboards-no-data-team/) or costly custom development.
+ Peaka connects directly to ServiceTitan and your accounting platform
+ It pulls in both operational and financial data automatically
+ Once consolidated and filtered, this data is then sent to BI tools like [Looker Studio](/blog/how-to-connect-servicetitan-to-looker-studio/), [Power BI](/blog/servicetitan-power-bi-integration/), or [Metabase](/blog/how-to-connect-servicetitan-to-metabase/) for visualization
+ Everything is live, always up to date, and accessible from a single interface
With Peaka, you don’t need to choose between simplicity and sophistication. You get both.
## **Fix the gap, supercharge your growth**
When operations and finance teams aren’t aligned on the numbers, growth becomes harder. Misunderstandings multiply. Reporting takes too long. And strategic decisions are made with incomplete information.
The fix is not more spreadsheets. It’s not more meetings. It’s a single source of truth—one that connects ServiceTitan and accounting data in real time.
Peaka helps you close the gap between ops and finance so your team can focus on what matters: running a better business.
Ready to streamline reporting and scale your services?
[Sign up to Peaka](https://peaka.studio/signup) for free today.
[Book a quick demo](https://calendly.com/peaka/demo) and see how Peaka connects ServiceTitan and QuickBooks in minutes.
--- START: blog/servicetitan-integrations-trayai-zapier/servicetitan-integrations-trayai-zapier.md ---
# **Your Guide to ServiceTitan Integrations: Tray.ai vs. Zapier**
If you’re in the trades industry, you are probably familiar with ServiceTitan, the CRM for home service businesses willing to centralize their business data. The platform’s versatility is an asset to its users as it helps align field and office teams, streamlines scheduling and dispatching, and improves decision-making with detailed reports and dashboards. By lowering the technical barrier to being more data-driven, ServiceTitan makes even the modest corner shops more competitive. Hence, the popularity.
But what if these companies want to extend ServiceTitan to pull in data from other sources? That’s quite a common scenario, as businesses operating in the trades industry often need to integrate ServiceTitan with some accounting software, a human resource management platform like Bamboo, or a call-tracking tool like CallRail.
Unfortunately, connectivity is not one of ServiceTitan's strengths. You’d be well-advised to use a third-party tool to connect ServiceTitan to other data sources so you can break down data silos, incorporate data from various data sources, and form a single source of truth for better decision-making.
What are your options for building ServiceTitan integrations? In this blog post, we take a look at two popular platforms, Tray.ai and Zapier, which people use for similar tasks. After evaluating these platforms regarding ease of use, scalability, and pricing, we’ll focus on how Peaka compares with these two popular solutions.
## **Key takeaways**
+ Despite being a highly capable product, Tray. ai loses in the usability and pricing departments, which are a priority for home service businesses using ServiceTitan.
+ Zapier is an easy-to-use automation tool but struggles with ad hoc integration requests that can come up when users want to scale their ServiceTitan integrations.
+ Peaka offers the Goldilocks solution for home service businesses looking to scale ServiceTitan integrations, as it combines usability and scalability at a reasonable price point.
## **Tray.ai**
Tray.ai is a cloud-based data integration and automation platform. It enables businesses to connect different applications, gather data from different sources, and sync it across different systems. The platform caters to the automation needs of various business teams as well. Companies can use Tray.ai to automate marketing campaigns, create customer support tickets, and process invoices, to name a few.
### **Ease of use**
ServiceTitan users tend to be small businesses with limited technical resources. Due to the scarcity of engineering resources at hand, ease of use becomes one of the main criteria for these companies when choosing a data integration platform.
Tray.ai is a technical product that was developed with the data integration needs of enterprises in mind. Therefore, IT involvement is required to set it up and use it. With a sophisticated feature set that most SMBs do not need and technical complexity, it just is not a good fit for home service businesses.
Another factor that undermines the usability of Tray.ai is the small number of pre-built connectors. This results in a steeper learning curve, making it difficult for non-technical users to self-serve while accessing data.
### **Scalability**
Building integrations is an IT-only job with Tray.ai, as the platform does not lend itself to use by non-technical users. Even with IT involvement, only one integration can be built at a time with this platform.
Factoring in the maintenance required by these integrations and other tasks that demand IT attention, scaling the number of integrations becomes a formidable challenge with Tray.ai.
### **Pricing**
Tray.ai’s pricing depends on the number of workflows and integrations used. Starting at around $695 per month, the cost can quickly rise as more workflows and integrations are added, and it is easy for users to lose control of their expenses. This lack of transparent pricing undermines predictability for home service businesses, which would like to plan for the IT bill they will pay every month.
## **Zapier**
Zapier is an automation platform for connecting SaaS apps and automating repetitive tasks across these tools without any need for coding or developer involvement. It’s particularly popular among startups as it simplifies tedious tasks and makes it possible to do more with less. Teams typically use Zapier to automate email notifications that are sent upon certain events, back up data into cloud storage at predetermined intervals, or update CRM contacts regularly.
### **Ease of use**
Zapier has been the king of user-friendliness since its inception. The way Zapier simplified automation has propelled its widespread adoption and extraordinary growth. The easy setup and hundreds of pre-built integrations have made the platform very popular with startups and SMBs that typically have limited technical resources.
### **Scalability**
Zapier offers simple, linear connectivity with your favorite apps, which is probably what you are looking for if you are running a startup or an SMB. It performs well when it is asked to retrieve data from a data source upon a predetermined trigger and push it to a new platform.
However, Zapier lacks the horizontal scalability needed to handle complex integration scenarios seen in enterprise use cases. Its simplicity comes at the expense of customizability, which prevents it from adjusting to changing integration requirements.
### **Pricing**
Zapier’s pricing plans include a free tier and two more tiers with fixed monthly prices. These three cover almost every use case that startups and SMBs may have. An enterprise plan with custom pricing caters to the needs of larger organizations. All in all, Zapier offers more transparency in pricing, which makes it easier for customers to budget.
## **Peaka**
Peaka is a [zero-ETL data platform](/blog/zero-etl-vs-modern-data-stack/) developed primarily to replace the modern data stack, which is too expensive to set up, too complicated to use, and too demanding to maintain for startups and SMBs. It relies on [data virtualization](/blog/data-virtualization-no-code/) to unify data without complex and time-consuming ETL processes.
Acting as a universal middleware, Peaka turns data into virtual tables and forms a semantic layer over relational and NoSQL databases, SaaS tools, and APIs. This semantic layer allows users to query disparate data sources as a single source right away.
### **Ease of use**
In terms of user-friendliness, Peaka is placed somewhere between Tray.ai and Zapier. A technical person can set it up, and users can pick from a list of connectors to start accessing their data. Peaka allows anybody with some basic knowledge of SQL to query their data regardless of the source.
### **Scalability**
Peaka functions as a serverless connector infrastructure that allows users to build integrations easily. It leverages data virtualization to create avatars of your scattered data and join them, enabling you to view your data as a unified data layer that you can query and expose to other systems. The process involves no ETLs, data warehouses, or maintenance, which makes it perfectly scalable.
### **Pricing**
Peaka comes with a free tier that lets users get a taste of the Peaka experience and handle some meaningful data-related tasks. In the upper tier, pricing is based on a pay-as-you-go model where users are charged based on the storage space and query time they use up.
## **Final thoughts**
In terms of user-friendliness, Peaka is placed somewhere between Tray.ai and Zapier. A technical person can set it up, and users can pick from a list of connectors to connect to any data source and access data. Peaka allows anybody with some basic knowledge of SQL to query their data regardless of the source. Its embedded ChatGPT functionality, which allows the use of natural language for querying, lowers technical barriers further for people who are not proficient in SQL.
Tray.ai and Zapier both have interesting value propositions. While the former offers a highly capable product fit for technical teams, the latter’s value proposition is based on simplicity at the price of some functionality. Home service businesses do not have to settle for a compromise, though.
Peaka proves that companies do not need to sacrifice either one of usability or technical capability to have the other. By eliminating ETLs, data warehouses, and maintenance hassle, Peaka allows even a data team of one to integrate and manage data at a home service company without the hefty bills. It’s the ideal solution for home service businesses looking to connect ServiceTitan to other platforms and create a single source of truth.
Visit our documentation to see how you can [connect ServiceTitan to Peaka](/docs/integrations/service-titan#servicetitan).
Check out Peaka’s growing [library of custom connectors](/integrations/) and [book a free demo](https://calendly.com/peaka/demo) to see Peaka in action!
--- START: blog/servicetitan-manual-data-export-costs/servicetitan-manual-data-export-costs.md ---
# **Hidden Costs of Manual Data Exports for ServiceTitan Users**
Manual data exports may seem harmless, as they have become tasks we perform on autopilot with a simple CSV file here, a spreadsheet there. But for home service businesses running complex operations across multiple locations, these everyday tasks quietly eat up time, money, and opportunities.
In this post, we’ll break down why manual exports persist, what hidden costs they carry, and how automating ServiceTitan data flows can free your business to focus on growth.
## **Why manual data exports still happen in home service businesses**
Many home service companies rely on tools like ServiceTitan for scheduling, invoicing, and CRM. Yet, despite ServiceTitan’s robust features, teams still find themselves manually exporting CSV files.
Why?
+ **Data silos:** Home service businesses work with disconnected systems, which require data teams to integrate them. In the absence of such teams, data silos build up, forcing users to bring data together manually.
+ **Cost concerns:** Some businesses are intimidated by the cost of engineering teams and data integration and automation tools needed for breaking down data silos and unifying scattered data.
+ **Legacy habits:** Old habits die hard. Operations staff often default to Excel because it feels familiar, even if it’s inefficient. Due to this inertia, copying and pasting remains the dominant data integration technique in home service businesses.
## **The hidden costs that home service businesses overlook**
Although operations staff and decision-makers may have their own reasons to stick with manual data exports, home service businesses incur hidden costs from this practice.
### **Time wasted by teams**
Consider how many hours per week your admin or ops team spends pulling reports, cleaning spreadsheets, or sharing updated files. For a multi-location home service business, that time compounds:
+ 5–10 hours/week per team spent on manual reporting isn’t unusual.
+ That’s time better spent scheduling jobs, managing technicians, or improving customer service.
### **Increased risk of errors**
Every manual export introduces risks of
+ Copy-paste mistakes,
+ Overwritten files,
+ Data sprawl that results from multiple versions of the same file scattered across systems.
This practice leads to inconsistent and inaccurate data, with different departments operating on conflicting versions. Such errors can impact payroll, inventory management, and customer billing.
### **Slower decision-making**
When leadership has to wait days for up-to-date revenue, dispatch efficiency, or customer service metrics, decision-making becomes laggy:
+ Opportunities are missed.
+ Decisions are delayed.
+ Technicians may be dispatched inefficiently, costing fuel and labor.
Without a single view of truth, no decision can be made with confidence.
### **Security and compliance risks**
With increasing awareness of data security and privacy, manual data exports are becoming obsolete. Repeated CSV downloads and data replication continuously expand the attack surface for malicious actors.
With manual data exports,
+ Sensitive data like customer addresses, credit card details, or payment history is stored in unsecured files that keep getting shared and moved.
+ Ensuring compliance with privacy regulations such as GDPR and CCPA becomes increasingly difficult due to challenges in tracking who accessed what data.
## **Real-world scenarios: How manual data exports impact home service businesses**
Just like the majority of SMBs, home service companies often find themselves performing manual data exports multiple times daily, in the absence of an automated system for data extraction and report generation.
Imagine a home service company with 15 locations:
+ Each branch sends weekly performance data via spreadsheets.
+ The staff at the HQ spends hours consolidating that information before leadership meetings.
+ Errors creep in during copy-paste, rendering reports inconsistent.
+ The leaders don’t trust the numbers they see and fail to make the necessary decisions regarding resource allocation, cash flow management, and customer service.
## **The alternative: Automating ServiceTitan data flows**
ServiceTitan users are seeking automated updates for databases and dashboards. While they are exploring ways to automate CSV exports, some are leveraging tools like [Tray.io and Zapier](/blog/servicetitan-integrations-trayai-zapier/) to reduce their reliance on manual processes.
However, these experiments yield suboptimal results. Tray.io is a technically complex product that’s not a good fit for the capabilities of a home service business. Zapier, on the other hand, ticks the box for user-friendliness, but lacks the functionality needed by these companies.
Peaka solves this dilemma, proving that a data integration platform can be both user-friendly and capable. [Peaka’s ServiceTitan integration](/blog/peaka-servicetitan-bi-integration/) allows home service businesses to automatically push ServiceTitan data to BI tools such as:
+ [Looker Studio](/blog/how-to-connect-servicetitan-to-looker-studio/)
+ [Power BI](/blog/servicetitan-power-bi-integration/)
+ [Metabase](/blog/how-to-connect-servicetitan-to-metabase/)
Peaka’s partnership with ServiceTitan and its ready-made BI connectors for popular data visualization tools help users
+ Eliminate manual data exports and the associated errors,
+ Standardize reporting across all locations and departments,
+ Create [real-time KPI dashboards](/blog/consultants-servicetitan-kpi-dashboards/) that get updated automatically,
+ Reduce administrative overhead for office staff and analysts.
With Peaka, your team can focus on delivering great service and growing revenue, instead of chasing spreadsheets.
## **Key takeaways**
+ Manual data exports create hidden costs in time, accuracy, and compliance.
+ Home service businesses relying on spreadsheets risk slow, error-prone decision-making.
+ Automating ServiceTitan data flows unlocks faster, more reliable business insights.
+ Platforms like Peaka simplify BI dashboard creation and integration—no coding required.
## **Ready to eliminate manual exports?**
Manual data exports slow you down, provide you with stale and inaccurate data, and undermine decision-making, resulting in missed business opportunities.
Peaka allows you to unlock greater value from your ServiceTitan subscription without committing additional resources. By automating data exports and providing real-time data to your reports and dashboards, Peaka empowers you to make informed decisions and concentrate on value creation rather than repetitive tasks.
[Sign up to Peaka](https://peaka.studio/signup) for free today.
[Book a quick demo](https://calendly.com/peaka/demo) and see how easily you can automate your data flows and streamline reporting for your home service business.
--- START: blog/servicetitan-power-bi-integration/servicetitan-power-bi-integration.md ---
# **Simplifying ServiceTitan-Power BI Integration with Peaka**
It is a must for white-collar employees to be data-driven nowadays. Regardless of the company size, every decision-maker has metrics and KPIs to track, which puts immense pressure on these people to make better decisions and improve performance. This phenomenon is not limited to global companies, either. Just because you don’t rake in millions in ARR or know what ARR is does not mean you can’t be data-driven.
Blue-collar jobs need to be data-driven as well. Whether you are running a plumbing, lawn-mowing, cleaning, or HVAC service, gathering your business data and leveraging it to make better decisions is the only way to grow your revenue and optimize your resource utilization.
One company that recognized home service businesses’ need for data early on was ServiceTitan. Founded in 2007, this California-based company capitalized on the software needs of tradespeople, reaching more than 8,000 customers and [$685 million in ARR](https://www.saastr.com/5-interesting-learnings-from-servicetitan-at-in-arr/) this year with a year-on-year growth rate of 23 percent. The company filed for an IPO in November 2024 and reached a [valuation of $8.9 billion](https://www.cnbc.com/2024/12/12/servicetitan-starts-trading-on-nasdaq-after-ipo.html) in its Nasdaq debut on December 12.
## **Key takeaways**
+ ServiceTitan comes with a decent dashboard in addition to its CRM capability.
+ For users who find ServiceTitan’s built-in dashboard lacking, Power BI offers a good alternative with its customizability and polished UX.
+ ServiceTitan does not have a ready-made integration for Power BI, but Peaka’s zero-ETL integration between the two platforms fills the void.
## **What is ServiceTitan?**
ServiceTitan is a dedicated CRM platform designed for home service companies, commonly referred to as “the trades,” such as cleaning, plumbing, electrical, and HVAC services, to oversee their operations. The platform serves as a comprehensive software suite for these businesses, helping them manage appointments, evaluate employee performance, handle customer calls, track job progress, and monitor customer satisfaction.
ServiceTitan goes beyond the usual CRM duties and offers other functions a small business needs. It is an all-in-one platform that can handle purchasing, inventory management, and communications. Its integration with Google Ads shortens the time between insights and marketing campaigns, helping local companies run more effective campaigns.
One ServiceTitan feature that simplifies things for business teams is the dashboard. This capability enables users to turn their data into charts, graphs, and metrics so they can uncover trends in their business operations, albeit with limited personalization options.
Let’s take a closer look at this tool now.
### **The ServiceTitan dashboard: Yay or nay?**
ServiceTitan is a one-of-a-kind platform that focuses on the data needs of field service jobs. In addition to serving as a central repository for dispatch job data, it also integrates with over a hundred different tools, including accounting, tax, payment, or human resource management platforms.
ServiceTitan’s advanced reporting capability allows users to dissect and analyze their consolidated data through detailed reports. Thanks to these reports, users can track a multitude of metrics and KPIs related to business operations, call center effectiveness, Customer Service Representative performance, and field technician activity.
When it comes to turning tabular data into visualizations, users can leverage ServiceTitan’s built-in dashboard, which offers two pre-made templates:
+ Business status dashboard for tracking the lead pipeline and job progress,
+ Commercial dashboard for viewing the revenue- and sales-related metrics.
These dashboards features date filters, which help users view the data from the last 18 months and conduct trend analysis on metrics. Trend analysis can then be used to make projections and inform decision-making.
If the pre-made dashboards do not cut it for you, you can dive into the customization options to tailor the dashboard so it fits your business intelligence needs better.
For a deep dive into the capabilities of the ServiceTitan dashboard, make sure to check out this video:
{{ youtube(id="Bmjjrl3DkyQ") }}
## **What is Power BI?**
Power BI is Microsoft’s business intelligence solution. It is designed and developed to be a part of the Microsoft product range and thus complements the company’s other software products rather well. For people who are used to working with Microsoft products, Power BI offers visualizations they can use to view their centralized data.
Microsoft, like its main rival Google, has tried to be everything to its users for some time now. Whether you need an email account, a spreadsheet, a data warehouse, or an entire cloud infrastructure, Microsoft has a product that can meet your needs. This allows the company to raise the switching costs for customers while offering them a better user experience and receiving brand loyalty in return.
Serving as the go-to data visualization tool in the Microsoft ecosystem, Power BI minimizes friction for users as it allows data visualization while still staying within a product ecosystem. Despite lacking the simple UI or the wide range of pre-made visualizations some of its competitors have, it stands out from the competition with its customizability and the ability to serve different use cases.
Here are the two aspects Power BI shines in:
### **Interoperability with other Microsoft products**
Microsoft has a product offering for almost any business need, from Azure to Office 365 to Teams. Power BI is embedded in this ecosystem as the go-to data visualization solution. If you are comfortable working in this environment, making your data flow from one node to another, Power BI is the natural destination for turning your data into visualizations. This native connectivity benefits users when they want to share their reports with other Microsoft services, promoting data consistency across different teams.
### **Multi-purpose use**
Another strength of Power BI is its versatility, which saves companies from deploying different tools for different teams. A company can use Power BI to serve both its business users with limited technical skills and data teams willing to drill down into reports. This prevents duplicate expenses on tools that will do the same job and improves productivity as data is easily shared across different business units.
## **Replacing the ServiceTitan dashboard with Power BI integration**
Home services are not practiced the same way everywhere: Local practices, regulations, habits, and customs have a significant impact on the way these businesses operate. Therefore, companies tend to have different reporting needs, and customization goes a long way toward satisfying these needs.
ServiceTitan offers a decent dashboard capability, but it is bound to struggle when customization requirements become too granular. A dedicated data visualization tool comes in handy in such times and provides a tried-and-tested solution to the common data visualization problems that regular users experience.
Power BI enjoys an advantage over its competitors as most SMBs run the Windows operating system and use Microsoft products such as Office 365. Power BI seamlessly integrates with and pulls in data from such products, which simplifies things while working in this particular ecosystem. However, visualizing ServiceTitan data with Power BI is not a straightforward process because ServiceTitan does not support integration with the latter.
A determined user looking for a workaround can manually copy and export ServiceTitan data to a spreadsheet and send it to Power BI for visualization. Yet, this can’t be a one-and-done project, as the spreadsheet will have to be continuously updated. Considering the number of reports a home service business needs on a regular basis, it is safe to say that such a task won’t be popular with the employees.
## **Peaka's ServiceTitan-Power BI integration: The benefits**
If only there were a tool that could streamline data flow from ServiceTitan to Power BI… A tool that could be operated without a data team, so business units could generate reports and create dashboards without manual labor or being dependent on tech people.
The conventional data integration process usually involves a data warehouse and data pipelines. You pay for a data warehouse and copy your data from different sources, moving it to a central repository where you can query it. You build data pipelines between the source and your data warehouse to ensure that your data is modeled to fit the format your destination requires. This is where things get tricky because any change in the input or output format requires a data team to build new data pipelines and maintain them, which would be prohibitively costly for a home service business or an SMB.
Peaka eliminates this costly problem by [virtualizing your data](/blog/data-virtualization-no-code/), basically creating an avatar of your data so you don’t need to physically move it to a data warehouse. This principle applies to ServiceTitan, as well.
Being a [ServiceTitan partner](/partners/servicetitan-integration/), Peaka offers a dedicated connector for this versatile platform, allowing you to easily retrieve your ServiceTitan data and join it with data from other sources, such as CRM, SaaS tools, or internal databases.
Visit our documentation to see how you can [connect ServiceTitan to Peaka](/docs/integrations/service-titan#servicetitan).
Peaka enables you to query your fractured, siloed data as if it were in one single repository, use filters to create new datasets, and send them to BI tools such as Power BI, Looker Studio, Metabase, and Tableau for viewing. All without investing in a data warehouse or having to maintain data pipelines.
The result?
+ Reduced workload for data teams, which would otherwise have to spend significant time and effort to build and maintain data pipelines to respond to the requests of business units.
+ Saved engineering hours that can be channeled to more productive tasks.
+ Less room for human error as there is no need for manually copying and pasting data.
+ Savings from not investing in a data warehouse or a bigger data team.
## **Final thoughts**
ServiceTitan is an outstanding CRM for the trades. It centralizes all the data such a business has, helps organize daily work, and allows users to see and evaluate the results. With an advanced reporting capability that gives users visibility into every aspect of the business, ServiceTitan deserves to be complemented by a top-notch dashboard.
If you are a ServiceTitan user, Power BI is one of the best purpose-built business intelligence tools available. Connecting these platforms can be problematic, though, because ServiceTitan does not offer a connector for Power BI. Peaka solves this problem by acting as a middleware between the two, allowing you to seamlessly send your ServiceTitan data to Power BI.
Make sure to read our blog post on [how to connect ServiceTitan to Looker Studio](/blog/how-to-connect-servicetitan-to-looker-studio/) if you are looking to use [Looker Studio for data visualization](/partners/looker-studio/).
If Metabase is your BI tool of choice, then our blog post on [how to connect ServiceTitan to Metabase](/blog/how-to-connect-servicetitan-to-metabase/) is the one for you.
Check out Peaka’s growing [library of custom connectors](/integrations/) and [book a free demo](https://calendly.com/peaka/demo) to see Peaka in action!
--- START: blog/servicetitan-sage-reporting-gap/servicetitan-sage-reporting-gap.md ---
# **How to Fix the Reporting Gap Between Ops and Finance**
You have technicians in the field, trucks on the road, and dispatch working smoothly, but reporting still feels like a secondary task, often overlooked and handled with whatever tools are available. Even with systems like ServiceTitan and Sage Intacct in place, many large home service companies with multiple branches and 50-500 employees still rely on manual workflows to get answers to basic operational questions.
If your team is spending hours every week preparing reports, building dashboards, and digging through spreadsheets just to understand what happened last week, you’re not alone. But you’re also not set up for scalable growth.
Let’s break down what’s really going on here and how modern operators are escaping the reporting treadmill.
## **The weekly reporting grind**
Here’s what the typical reporting process still looks like for [contractors operating across multiple locations](/blog/multi-location-servicetitan-reporting/):
+ Export job data from ServiceTitan
+ Pull accounting numbers from Sage Intacct
+ Copy and paste into spreadsheets
+ Clean the data manually
+ Match columns, filter dates, and chase down missing entries
+ (Maybe) push it into a [Power BI](/blog/servicetitan-power-bi-integration/) or [Looker Studio dashboard](/blog/how-to-connect-servicetitan-to-looker-studio/), if someone on the team knows how to set up and use a tool like Zapier
For most ops teams, this eats up hours every week. One mid-sized HVAC company we spoke to reported spending nearly 10 hours/week on reporting across their operations and finance teams.
And what happens when leadership asks for a breakdown by technician, service line, or region? That means another round of [manual data exports](/blog/how-to-connect-servicetitan-to-looker-studio/), filters, and rework for an already busy team.
## **What this is really costing you**
The extra work needed to prepare reports is more than an inconvenience. Manual reporting workflows are actively holding your company back in several ways.
+ **Time drain:** High-value team members are stuck doing low-value data cleanup that can be automated with the right setup.
+ **Slower decisions:** You get your reports after the fact, while your teammates are already fighting problems.
+ **Higher risk of error:** The more manual steps, the more likely someone is to make a mistake.
+ **Missed opportunities:** Without visibility into your operations, you will inevitably miss out on business opportunities to maximize revenue.
This bottleneck only gets worse if you are a growth-oriented contracting business looking to add new locations, expand services, or roll up smaller shops.
## **Why the Zapier + BI Tool formula doesn’t work**
You might be thinking: “*But we already use Power BI*” or “*We built something in Looker Studio.*”
That’s great (until it breaks). Most of the time, your dashboards are only as good as your data pipeline.
Here’s the catch:
+ Outsourced BI gives you dashboards, but you’re stuck waiting days (or weeks) for a consultant to gather your data and build the dashboards you need.
+ Power BI, Looker Studio, and Tableau are capable BI tools, but ServiceTitan lacks connectors for them, and setting them up requires a data engineer on staff (which most companies in this range don’t have).
+ An [automation tool like Zapier or Tray.ai](/blog/servicetitan-integrations-trayai-zapier/) might help you move data for very specific, strictly defined use cases, but it’s fragile and prone to breaking when formats change.
In other words, standard solutions will let you down at some point. You need a solution specifically designed for teams like yours: Growth-focused, fast-moving, and resource-constrained.
## **The better way: Self-serve reporting for everyone**
That’s where a solution like Peaka comes in.
Peaka connects directly to your ServiceTitan and Sage Intacct accounts, bringing together operational and financial data in a unified data layer. In addition to removing the need to download CSVs, copy data from one spreadsheet to another, or maintain a data team, Peaka offers a text-to-SQL capability. This enables non-technical users to dig into their data using natural language prompts in case they are not confident in their SQL skills.
With Peaka, your operations staff, finance team, or even your ServiceTitan lead can consolidate their data, generate reports, and refresh [KPI dashboards](/blog/servicetitan-dashboards-no-data-team/) in real time. This helps them track the metrics that matter most, such as revenue per technician, [job costing](/blog/track-job-costs-servicetitan/) and gross margin by service line, call booking rates, or marketing ROI by channel.
## **From hours to minutes: What this looks like in practice**
Let’s say you’re running a $20M plumbing and HVAC company with five locations. Your ops team currently spends 8–10 hours each week prepping the Monday morning report deck.
Peaka allows you to
+ Connect your ServiceTitan and Sage Intacct data once,
+ Consolidate data from different accounts and filter it using natural language prompts or AI,
+ Send the consolidated data to your favorite BI tool, turning your data into visualizations that show trends.
That’s not just saving time; it's more about changing how your business operates.
## **Key takeaways**
+ Most growing home service companies still rely on manual reporting, even after adopting ServiceTitan.
+ Time spent on reporting eats into your ops team’s ability to focus on growth and performance.
+ Traditional BI stacks built around spreadsheets, Zapier, and a BI tool are too limited to cover all the data needs of a contractor and still demand a lot of manual work to operate and maintain.
+ Peaka provides a no-code, real-time reporting layer designed specifically for ServiceTitan users running operations across multiple locations.
## **Conclusion: What could your team achieve with that time back?**
Every hour your operations or finance team spends assembling reports is an hour not spent improving margins, training techs, or planning growth. Multiply that by 10 hours a week, 52 weeks a year, and the opportunity cost becomes huge.
The truth is, manual reporting is a legacy habit, not a necessity. As your business grows beyond a single shop, the same spreadsheet-based systems that once worked start to collapse under the weight of multi-location complexity.
The companies winning today aren’t necessarily bigger; they’re faster. They identify issues in real-time, make adjustments mid-week, and possess the data discipline of much larger organizations without hiring a single data engineer.
If your team still treats reporting like a chore, it’s time to change the workflow, not the people.
## **Ready to reclaim your week?**
If your team is still spending hours every week assembling reports, there’s a faster, smarter way.
With Peaka, you can stop building reports and start using them to lead, grow, and stay ahead.
[Sign up to Peaka](https://peaka.studio/signup) for free today.
[Book a demo](https://calendly.com/peaka/demo) to see how Peaka helps large contractors manage ops and finance data at scale.
--- START: blog/silicon-valley-bank-lessons/silicon-valley-bank-lessons.md ---
# **What Founders Can Learn from the Silicon Valley Bank Ordeal**
We spent 2022 with the ghost of a recession looming over our heads. Higher interest rates and rising energy prices were pointing to an economic slowdown by the year's end at the latest, and the layoffs in the tech industry seemed to confirm the worst fears. However, no one expected a bank run, and not in California, of all places. Yes, we got a bank run, people. The fact that it involved a bank that allegedly served "[nearly half of all U.S. venture-backed startups](https://www.svb.com/venture-funded)" makes it a case worthy of a deep dive.
## **What happened?**
Silicon Valley Bank (SVB), the bank of choice for many well-known tech startups, collapsed and was seized by the California Department of Financial Protection and Innovation on March 10, 2023. SVB had $209 billion in assets and was the 17th largest bank in the U.S. at the time of its collapse. Luckily, SVB was much smaller than banks like Goldman Sachs and Lehman Brothers, which were involved in the subprime mortgage crisis of 2007-2008. But SVB's central role in the tech industry still caused concern among government officials as a liquidity problem could spread through the startup ecosystem like wildfire and render startups insolvent in a short time.
Two other relatively smaller banks shared the same fate with SVB: Signature Bank, which had assets worth $110 billion and was the 32nd largest bank in the U.S., and Silvergate Bank, the 153rd largest bank in the U.S., with $11.4 billion in assets. Both of these banks were prominent lenders to crypto companies.
## **Why did it happen?**
SVB failed because it got stuck between its short-term liabilities and long-term investments. It had invested heavily in U.S. Treasury bonds to secure high gains. With the Fed raising interest rates to fight inflation, the value of those bonds dropped, shrinking SVB's asset base. Apparently, SVB was late to secure liquidity in an environment where the cost of borrowing was surging. So, it had to sell its Treasury bonds for a significant loss to meet liquidity demands from its depositors, which set off alarm bells in the industry.
SVB's liquidity problems were no secret among investment circles. What complicated the situation was the fact that depositors had become more reliant on their savings while SVB struggled to create liquidity. Startups were struggling to find funding on favorable terms throughout 2022 and were forced to withdraw more money to sustain their operations. Individuals, too, [increased their drawdowns](https://calmatters.org/economy/2023/03/silicon-valley-bank-collapse/) as a result of the tech layoffs in California. SVB found itself drifting into a perfect storm.
The bank announced on March 8 an emergency sale of its common and preferred stock to raise $2.25 billion. Coming at the heels of the sale of Treasury bonds before, this served as the last straw and triggered a bank run. The bank's stock plunged by [60 percent](https://news.yahoo.com/svb-drops-most-record-startup-211032722.html) on March 9. People rushed to withdraw deposits, moving out [$42 billion](https://dfpi.ca.gov/wp-content/uploads/sites/337/2023/03/DFPI-Orders-Silicon-Valley-Bank-03102023.pdf?emrc=bedc09) in a single day, leaving the bank with [a negative cash balance of $958 million.](https://www.cnbc.com/2023/03/10/silicon-valley-bank-collapse-how-it-happened.html)
## **To bail out, or not to bail out, that's the question**
Federal Deposit Insurance Corporation (FDIC) insures deposits in U.S. banks [up to $250,000](https://www.fdic.gov/about/what-we-do/) per depositor, per insured bank. Any amount above that figure has no state guarantee and can only be covered by other means like insurance bought from private firms.
Reuters [reported](https://www.reuters.com/business/finance/global-markets-banks-wrapup-1-2023-03-10/) that SVB had $175 billion in deposits, 89 percent of which was above the threshold and thus without insurance. The clients received access to the insured portion of their deposits on March 13. But the question of uninsured deposits was more difficult to deal with. The Biden administration found itself between a rock and a hard place: Make every client whole, and the government would be accused of performing another bailout on taxpayers' money. Leave to their own devices the depositors with uninsured deposits, and it could cripple the tech industry, setting off a domino effect. Authorities were under pressure from two camps defending two opposing views.
## **Old sins have long shadows**
Y Combinator led the effort urging authorities to make all depositors whole at SVB. Garry Tan, the CEO and President of YC, wrote [a petition](https://www.ycombinator.com/blog/urgent-sign-the-petition-now-thousands-of-startups-and-hundreds-of-thousands-of-startup-jobs-are-at-risk) addressing the U.S. Treasury Secretary Janet Yellen and was joined by 650 CEOs. The petition asked for a backstop, that is, credit support or cash injection, not a bailout. Still, the move created a significant backlash on social media, as it revealed that CEOs of multi-million dollar companies were not particularly good at managing risk, despite knowing full well how the banking industry operated.
The backlash was understandable in light of SVB CEO Greg Becker's past efforts to reduce federal oversight over SVB. The law (The Dodd-Frank Act) called for increased regulations for financial institutions controlling assets of more than $50 billion. Becker lobbied against this law, campaigning for the threshold to be raised to $250 billion because SVB had such a "[deep understanding of the markets it serves](https://www.theguardian.com/business/2023/mar/11/silicon-valley-bank-weaken-risk-regulations-svb)" that there was no need for extra regulations to kick in.
Becker got his wish on May 24, 2018, when Donald Trump finally [signed the bill](https://thehill.com/policy/finance/389212-trump-signs-dodd-frank-rollback/) that raised to $250 billion the threshold for more stringent banking regulations to be applied and exempted banks like SVB from more thorough stress tests. Becker [sold $3.6 million worth of SVB stock](https://www.cnbc.com/2023/03/14/svb-execs-sold-84-million-of-the-banks-stock-over-the-past-2-years.html) on February 27, two weeks before the bank run, and flew with his wife off to Hawaii, where he has a condo.
FDIC announced on March 13 that it would guarantee uninsured deposits as well, raising doubts about another bank bailout. However, the Biden administration denied these allegations, citing that it was not rescuing the bank management or the shareholders. Instead, the Fed chose to intervene by creating the [Bank Term Funding Program](https://en.wikipedia.org/wiki/March_2023_United_States_bank_failures#Bank_Term_Funding_Program) (BTFP), which would offer loans of up to one year in length to troubled financial institutions. The fact that the BTFD is funded through the [Deposit Insurance Fund](https://www.investopedia.com/terms/d/deposit-insurance-fund.asp), which itself is sponsored by the finance industry, seems to have put an end to the bailout allegations.
## **Key takeaways for founders**
Venture capital firm NFX [conducted a survey](https://www.nfx.com/post/founder-sentiment-survey-postsvb) among 870 founders immediately after the collapse of SVB. The survey results shed light on the problems of the startup ecosystem right before the SVB collapse, and the steps founders took to rectify mistakes in risk management right after it:
+ Most startups had a single bank account before SVB went under. The percentage of startups having just one bank account halved in a few days, going from 58 to 28.5 during the crisis. The fact that more than half of the founders were comfortable keeping in a single account the millions of dollars they raised in fundraising rounds attests to the illusion of immunity they were in. Spreading out the funds to different banks would give them an insurance of a quarter of a million dollars per bank, which is no small sum for a startup. Neglecting this point speaks to their lax management practices.
+ The almost simultaneous collapse of SVB, Signature Bank, and Silvergate Bank raised doubts about the resilience of regional banks in case of a bank run. More than a quarter of founders responded to this by choosing to open an account with a big bank, raising the percentage from 31 before the SVB collapse to 57 after. [Bank of America, Wells Fargo, and Citigroup](https://edition.cnn.com/2023/03/16/tech/silicon-valley-bank-supporters/index.html) did particularly well, enjoying a surge in deposits recently.
+ 54 percent of founders communicated with their investors for guidance and financial advice as the SVB-gate unfolded. This figure is all the more striking when you take into account that 75 percent of founders talk to their investors only once a month or even less frequently. While Hoxton Ventures advised its portfolio companies to [withdraw two months' worth of burn](https://www.cnbc.com/2023/03/10/vcs-urge-startups-to-withdraw-funds-from-silicon-valley-bank.html) from SVB, Peter Thiel's Founders Fund urged the startups on its portfolio to move their deposits to another bank.
This short episode once again demonstrated that being in frequent contact with well-connected investors can pay off for founders at critical moments. Investors tend to be steeped in the ups and downs of the business world and possess a strategic perspective that many founders lack. Tapping into their wisdom and insights to manage risk and review existing practices is the least founders can do. However, founders would be well-advised to prepare for a period where investors will get to enjoy more bargaining power at the negotiating table.
## **Final thoughts**
Despite all the funding rounds closed, the impressive year-on-year growth rate, and the incredible boost it received during the pandemic, the startup ecosystem in the tech industry remains fragile. The news of SVB going under in just 48 hours showed that most startups are only a single bad decision away from being unable to pay wages unless the government intervenes. Tech startups dodged a bullet in March 2023. Here is hoping that they will at least have the prudence to keep their money in more than one bank in the future.
--- START: blog/single-source-of-truth-contractors/single-source-of-truth-contractors.md ---
# **How Large Contractors Can Build a Single Source of Truth**
Rapid growth through local acquisitions and market expansion defines successful home service franchises. Yet, this very expansion can become a challenge when reporting workflows fail to keep pace. What once sufficed for a single office crumbles under the strain of disparate teams, incompatible software, and fragmented, inconsistent data.
For multi-location operations, establishing a single source of truth is critical. However, achieving this is more complex than simply implementing a BI tool or relying on spreadsheets. This blog post examines the challenges multi-location contractors face in reporting and offers solutions for unifying their operational, financial, and marketing data.
## **Key takeaways**
+ Multi-location home service businesses need a single source of truth to scale operations with data-driven insights.
+ Spreadsheets and manual reporting can’t keep up with growing complexity.
+ Zapier + BI tool setups are too limited for the operational complexity of a large home service franchise.
+ Peaka offers a [zero-ETL, zero-copy data integration](/blog/zero-etl-vs-modern-data-stack/) that unifies data from different sources without requiring a data warehouse or a dedicated data team.
## **The visibility challenge in multi-location businesses**
Contractors with 50–500 employees often operate across multiple regions, service categories, and technician teams. Each branch needs to adapt to the local conditions, which brings about differences in dispatch practices, sales motions, marketing campaigns, and even ServiceTitan configurations.
This creates headaches for anyone trying to understand performance at a company-wide level:
+ Which branches are profitable?
+ Where are we losing money on jobs?
+ How does marketing ROI compare across markets?
+ Which teams are exceeding expectations, and which need help?
Without centralized reporting, every department works with its own view of the truth. Finance relies on Sage Intacct or QuickBooks. Operational data lives in ServiceTitan. Only marketing has visibility into the ROI from the Google Ads campaigns being run. All this data is presented to the leadership in a weekly Excel sheet that’s already outdated by the time it hits their inbox.
## **Why a “single source of truth” changes the game**
A true single source of truth means every team (ops, finance, marketing, leadership, and even private equity stakeholders) works from the same set of live metrics. It ensures that the data is accurate and consistent across all systems. A single source of truth enables users to get real-time answers to questions like:
+ Technician revenue per hour, ranked across all locations
+ [Job costing](/blog/track-job-costs-servicetitan/) and gross margin across service categories
+ Marketing performance by region
+ Close rates by call type, location, and sales rep
+ Backlog by branch and time-to-completion
This kind of clarity results in better decisions, faster course correction, and stronger growth. It’s the kind of data that drives operational agility.
## **What’s holding these companies back?**
Despite the obvious need, most multi-location service businesses struggle to get there. Here’s why:
+ **Spreadsheets don’t scale:** They’re great for one branch, not ten. Manual data aggregation is slow, error-prone, and poses security risks.
+ **ServiceTitan’s native reporting is limited:** ServiceTitan may be the operational backbone of a home service franchise, but it is not designed for cross-location or financial visibility.
+ **Zapier + BI tools are brittle:** The Zapier + BI tool formula is good for moving data from one tool to another, but it comes up short when reporting needs become more complex in a dynamic environment.
+ **Outsourced dashboards are slow and expensive:** Waiting weeks for a consultant to update a report just doesn’t cut it in a fast-moving operation.
Most companies in this range don’t have a data team. They are stuck in a data no man’s land: They know that they need to replace spreadsheets, but neither can they afford nor do they need platforms like Snowflake and Databricks. What large contractors need is fast, flexible reporting that doesn’t rely on engineers or expensive vendors.
## **What the ideal solution looks like**
To build a real single source of truth, your reporting setup needs to check several boxes:
+ Integrate data from operational software, accounting systems (e.g., ServiceTitan + Sage Intacct or QuickBooks), and marketing tools (Google Ads)
+ Unify metrics across branches even when ServiceTitan setups vary
+ Automate dashboard updates—no more manual exports
+ Give business users control so your dispatcher, finance lead, or marketing team can explore the data themselves
+ Support both high-level overviews and deep dives for leadership, branch managers, and analysts alike
In short: You need a flexible data platform capable of forming a unified data layer from disparate data sources without requiring a Snowflake or engineering team to manage it.
## **How Peaka makes it possible**
Peaka was built for growth-focused service companies that are outgrowing spreadsheets but don’t want to hire a data team. Here’s how it solves the single source of truth problem:
+ **Zero-ETL, zero-copy integrations:** Connects directly to ServiceTitan, accounting, and marketing systems without any ETL pipelines or having to move or duplicate data.
+ **Standardized metrics and KPIs:** Translates messy, inconsistent data into [consistent metrics and KPIs](/blog/servicetitan-dashboards-no-data-team/) that make sense across all branches.
+ **BI tool flexibility:** Allows teams to send their consolidated data to any BI tool for instant visualization without any IT involvement.
+ **Real-time visibility:** Peaka enables you to integrate data from different ServiceTitan accounts. As a result, you can [list invoice data](/blog/list-invoices-multiple-servicetitan-accounts/), [monitor call data](/blog/list-calls-multiple-servicetitan-accounts/), track job profitability, close rates, and more across multiple locations.
Whether you’re a $5M regional operator or a $50M franchise scaling fast, Peaka helps you get the same reports you’d get with Snowflake and Databricks, without the massive initial investment, astronomical monthly bills, and engineering complexity.
## **A real-world example: 5 locations, one unified view**
Let’s say you run a $20M HVAC and plumbing company with five locations. Your ops team spends hours each week exporting ServiceTitan data to prep weekly reports.
With Peaka:
+ You no longer have to update your dashboards manually as Peaka supports [integration with ServiceTitan and BI tools](/blog/peaka-servicetitan-bi-integration/), simplifying how you can send your ServiceTitan data to [Power BI](/blog/servicetitan-power-bi-integration/) and [Looker Studio](/blog/how-to-connect-servicetitan-to-looker-studio/).
+ Dashboards update automatically without any CSV exports or spreadsheet wrangling
+ Your CFO can [integrate ServiceTitan and Sage Intacct data](/blog/multi-location-servicetitan-reporting/) in real-time and make better decisions
+ Your COO can [track technician data](/blog/list-technician-multiple-servicetitan-accounts/) and job profitability by region
+ Your marketing team measures ROI across locations in real-time
No more digging through disconnected reports or waiting for dashboard updates from a consultant. Everyone on your team gets the answers they need when they need them.
## **Conclusion: Centralized data for decentralized teams**
If your team is tired of [manual data exports](/blog/servicetitan-manual-data-export-costs/) to build dashboards, it might be time to modernize your data stack (preferably without having to invest in an outrageously costly “modern data stack”).
Peaka allows you to integrate ServiceTitan with your accounting software, marketing tools, and other legacy systems. It centralizes all your data with ready-made connectors without copying and moving your data into a data warehouse, eliminating the need for a data team to maintain ETL pipelines.
Purpose-built for the data needs of home service businesses, Peaka is the data stack a contractor will ever need.
[Book a demo](https://calendly.com/peaka/demo) to see how Peaka helps home service franchises build a single source of truth out of scattered data.
--- START: blog/social-media-partnership-template/social-media-partnership-template.md ---
# **The BrandBoost App Template Unleashes Marketing Synergies**
Everybody was blogging at the beginning of the 2000s, remember? Kids, housewives, sports fans, travelers… It looked like WordPress had unleashed the creative powers of millions of people who apparently had so much to tell. Then, in 2005, an obscure video sharing platform, whose possible impact probably very few people could foresee, entered our lives. With YouTube's emergence, we learned that blogging (or vlogging) could be the basis for a sound, lucrative economic model. Today top-3 highest-paid YouTubers, [Mr. Beast](https://www.youtube.com/c/MrBeast6000), [Jake Paul](https://www.youtube.com/c/jakepaul), and [Markiplier](https://www.youtube.com/c/markiplier) rake in $54 million, $45 million, and $38 million, respectively.
YouTubers, at least initially, were like TV stars: You needed to be at your desk to tune in to watch their performances. The rise of smartphones and social media changed that. These two combined to multiply the number of visual content creators and transformed the way creators engaged with their fans. A smartphone and [a social media account](https://www.broadbandsearch.net/blog/social-media-facts-statistics) were the only prerequisites for becoming a content creator.
The average number of social media accounts a person owns has grown from [4.8 in 2014 to 8.4 in 2020.](https://backlinko.com/social-media-users) The success of content creators was one of the prominent factors that drove this growth. A new economy gradually took shape around the interactions transpiring on social media. Twitter, Instagram, and later TikTok not only became the stages where content creators interacted with their fans, but they also facilitated the monetization of those interactions in this period. How many times a message was viewed, liked, and shared helped marketers gauge the potential of content creators as a marketing channel.
Individuals among content creators who could generate and guide interest came to be known as "influencers." Rachael Cihlar from the influencer marketing platform Mavrck [predicts](https://influencermarketinghub.com/influencer-marketing-predictions-2022/) that the number of people self-identifying as creators will surpass the 1 billion mark in the near future. This prediction is in tune with the projections about the growth of [the influencer market](https://influencermarketinghub.com/influencer-marketing-statistics/): Amounting to just $1.7 billion in 2017, the influencer market has grown to $13.8 billion in 2021 and is projected to surpass the $15 billion mark this year.
Of all the demographic groups, one stands out regarding how they interact with influencers: Gen Z. Influencers have an outsized impact on Gen Z's purchasing habits. That's because people in this demographic group tend to spend more time on social media, and most of them were born into a world where influencers were already household names. An Ipsos Connect study commissioned by Google discovered that [70 percent](https://www.thinkwithgoogle.com/marketing-strategies/video/youtube-stars-influence/) of adolescent YouTube subscribers found YouTubers more relatable than traditional celebrities. It turns out that [6 in 10 teenagers](https://digitalmarketinginstitute.com/blog/20-influencer-marketing-statistics-that-will-surprise-you) listen to, take advice from and relate to influencers more than traditional celebrities. Previous generations may have a low opinion of influencers, but Gen Zers see them as role models. If you want to reach out to young people, leveraging the influencers' credibility in the eyes of Gen Zers is the way to go.
Business leaders were quick to realize the value influencers offered for marketers. Thanks to social media and influencers, big companies could "act small again," as Jay Baer, entrepreneur and marketing guru, [puts it](https://twitter.com/jaybaer/status/672800288483377152?lang=en). Companies can tap into the hitherto out-of-reach customer groups by finding influencers that appeal to different customer profiles and curating campaigns that target niche segments.
Decision-makers have already found out that [influencers are more effective](https://mediakix.com/influencer-marketing-resources/influencer-marketing-statistics/#effectiveness) in generating demand than conventional forms of marketing. Influencer marketing was measured to generate [between $5.20 to $6.50](https://mediakix.com/influencer-marketing-resources/influencer-marketing-statistics/#roi) for every dollar spent. A well-chosen influencer can introduce more precision into a firm's marketing efforts, letting it focus on high-impact customer segments.
However, there is a caveat. As a business leader, you may decide to work with influencers to boost your brand's online presence, but that's easier said than done. [61 percent](https://mediakix.com/influencer-marketing-resources/influencer-marketing-industry-statistics-survey-benchmarks/) of marketers think finding suitable influencers for a company is a real challenge.
Mindful of this challenge, Peaka has recently published an app template that brings together brands and influencers: BrandBoost. The template allows businesses to search through influencer profiles to find the most suitable influencer for a particular campaign. Additionally, BrandBoost can be used to build a two-sided marketplace where brands and influencers list their requirements to find the best match.
Making the wrong choice on influencers you work with can come back to haunt your brand down the road. Similarly, an influencer can cripple her career working with brands that are not a good fit for her audience. BrandBoost lays the ground for a marketplace that can minimize these two risks. Social media partnerships do not have to be hit-or-miss affairs. BrandBoost makes sure you get your time and money's worth.
--- START: blog/standardize-servicetitan-kpis-portfolio/standardize-servicetitan-kpis-portfolio.md ---
# **How to Integrate ServiceTitan with Accounting Software**
For private equity firms rolling up home service businesses, operational data is everything. Whether it’s HVAC, plumbing, roofing, or pool cleaning your business specializes in, you can’t drive growth without knowing which branches are performing, where revenue is slipping, and how technician utilization compares across brands.
The challenge? In most roll-ups, each brand runs its own ServiceTitan instance. Pulling performance numbers means chasing multiple teams, exporting CSV files, and manually stitching together reports before every board meeting.
It’s a process that consumes hours, delays insights, and often leaves leadership making decisions based on outdated numbers. And with only a 3–5 year value creation window, that’s a problem you can’t afford.
## **The pain of manual ServiceTitan reporting**
Disconnected ServiceTitan instances create a snowballing effect that leads to inefficiency across the board:
+ **Fragmented processes:** Each brand rolled up comes with its own reporting habits and KPI definitions, making it difficult for PE leaders to evaluate the performance of comparable business units.
+ **Time drain:** Reconciling different records and manually integrating data is a time-consuming process. It requires portfolio operators to spend hours (sometimes days) downloading CSVs and replicating data to spreadsheets.
+ **Risk of human error:** Every manual merge consists of hundreds and sometimes thousands of copy & paste actions, which creates a fertile ground for data inconsistencies and mistakes.
+ **Lagging insights:** Gathering data from all portfolio companies, reconciling differences, and creating meaningful reports can take weeks, forcing decision-makers to work with outdated data most of the time.
You're reacting to the market instead of leading it, and by then, it's too late.
## **Why consistency and speed are crucial for PE timelines**
Private equity firms operate on compressed timelines. Every quarter matters, and reporting delays can directly impact value creation plans. Faster, more consistent reporting enables:
+ Standardized KPIs across brands for apples-to-apples comparisons.
+ Real-time insights to act on operational trends immediately.
+ Better board communication with consistent, credible data.
+ Operational alignment that helps spread best practices quickly across the portfolio.
In a value creation cycle, time saved on reporting is time invested in driving growth.
## **The traditional fix and why it falls short**
Some PE firms try to solve the problem with a traditional BI stack, pulling ServiceTitan data into Snowflake or BigQuery, transforming it with dbt, and visualizing it in Tableau or Power BI.
But for most home service portfolios, this approach fails to deliver on PE timelines:
+ **Months to deploy:** Every data stack becomes a project in its own right, with custom integrations and data modeling, which delays time-to-insight.
+ **High engineering overhead:** Building and maintaining a data stack requires a data team that most operators don’t have.
+ **Six-figure costs:** Tooling and talent costs add up quickly.
+ **Poor fit for lean operators:** A traditional stack is overkill for the actual reporting needs of a PE firm.
By the time the stack is live, you could already be halfway through your holding period. This is not how smart companies use their resources.
## **The ideal reporting solution for PE-led portfolios**
For private equity operators, the right solution isn’t about more tools or complex data stacks. It’s about speed, consistency, and simplicity. An ideal reporting approach should deliver:
+ Direct connections to multiple ServiceTitan accounts without custom coding.
+ Standardized KPI definitions so that revenue, close rates, and technician efficiency are measured the same way across all brands.
+ Real-time visibility into portfolio performance, eliminating reporting delays.
+ Accessibility for non-technical users, so operators and finance teams can generate insights without relying on engineers.
+ Deployment within days, not months, so value creation plans stay on track.
In other words, the best solution for PE firms is one that replaces spreadsheets with a unified, always-on reporting layer—without the heavy lift of building a full BI infrastructure.
## **How Peaka simplifies ServiceTitan reporting**
Peaka streamlines the whole reporting process, replacing slow, manual processes with real-time, automated reporting. It achieves this by
+ Connecting directly to [multiple ServiceTitan instances](/blog/unify-servicetitan-data-pe-firms/) without any code or ETL pipelines.
+ Standardizing KPI definitions so you can compare performance across brands.
+ [Integrating with accounting tools](/blog/integrate-servicetitan-with-quickbooks-xero-sage/) like QuickBooks, XeroAccounting, or Sage Intacct for reports on revenue, profitability, and job costing.
+ Lowering the technical barriers for non-technical people so they can push their data to [Power BI](/blog/servicetitan-power-bi-integration/), [Looker Studio](/blog/how-to-connect-servicetitan-to-looker-studio/), and [Metabase](/blog/how-to-connect-servicetitan-to-metabase/) without a data team.
+ Deploying in days, not months, which makes it a good fit for post-acquisition integration.
Peaka provides you with the insights you need, when you need them, reducing your reporting cycles and helping you take proactive action.
## **Key takeaways**
+ Manual ServiceTitan reporting wastes valuable time and creates inconsistency.
+ [KPI dashboards](/blog/consultants-servicetitan-kpi-dashboards/) that get updated automatically deliver faster insights and standardized benchmarks.
+ Peaka enables portfolio-wide reporting without huge investments in data warehouses and data teams, which ties in nicely with the timeline of a PE firm.
## **Conclusion: From manual reports to real-time insights**
For ServiceTitan consultants, integrating operational and financial data has always been necessary, but until now, it’s also been painful.
If you’re tired of waiting for reports that never get delivered on time, you may want to start thinking about replacing manual processes. Peaka fits the bill here as it helps you unify and automate your ServiceTitan reporting across the portfolio. No engineers, no spreadsheets—just real-time insights you can trust.
Ready to streamline reporting and scale your services?
[Sign up to Peaka](https://peaka.studio/signup) for free today.
[Book a quick demo](https://calendly.com/peaka/demo) and see how we help PE firms replace [manual data exports](/blog/servicetitan-manual-data-export-costs/) with automated dashboards in days, not months.
--- START: blog/startups-connector-infrastructure/startups-connector-infrastructure.md ---
# **Why You Must Focus on Your Connector Infrastructure in 2026**
AI-based solutions brought to light a problem that already needed answers but was pushed to later dates by businesses due to its complexity: **Having a connector infrastructure that is compatible with your customers' tech stack.**
Many organizations, regardless of their size, often build connections to major software: Big CRMs, payment platforms, or relational databases that support only a small share of their clients’ integration needs. However, with many tools disturbing big players for market share, every company’s tech stack started to look different than others. Even with NoSQL databases alone, there are at least 7 options business leaders can consider. When you scale this to more software categories like Application Tracking Systems (ATS), Marketing Automation, and AI tools, you end up with thousands of different variations for businesses to build their tech stack around.
So what happens to the remaining tools? Customers usually integrate what's available at first and give your product a go, but eventually churn as your tool cannot provide a full solution to them. With many competitors around, they’ll soon start looking for other solutions. This churn can usually be explained by two major reasons: Vendor lock-in and the inability to cross-source your products' analytics.
## **Connectors: The hidden key**
The idea of being dependent on a single tool can be concerning for customers because it limits their ability to switch to competing products, potentially leading to higher costs if the vendor (you) decides to increase prices or reduce the quality of service. Furthermore, being tied to a single vendor restricts customers’ flexibility in adapting to new technologies. By offering extensive APIs and integration options with other platforms, SaaS tools can fit into a customer's existing ecosystem. Being vendor-neutral also means you constantly have to deliver the best product in the market, but that should be your goal anyway.
Though many founders are aware of the importance of these integrations and the potential capital lost due to not offering them, they frequently misjudge the optimal timing. Many believe that it’s best to first find product-market fit (PMF) and then scale their integrations, which is very reasonable. Unfortunately, after achieving PMF and experiencing rapid scaling, numerous other developments pile up, leaving little time to build these connectors.
“*We’re building integrations as demanded.*” I’ve been hearing this phrase quite a lot from all sizes of companies. However, this approach is doomed to fail. Even if you start building integrations the second you meet the prospect, by the time they churn, you’ll have built one or two new integrations at most. {{ highlight_text(text="Having a strong connector stack in place before reaching customers improves new business close rates while reducing customer churn.", small_text="Top Highlight") }} Given these considerations, the question isn't about whether to build integrations but about the pace and quantity of these integrations.
## **Should you build your connector empire or buy it off-the-shelf?**
Despite all the benefits listed above, there are several reasons why building integrations does not appeal to companies:
* Performance & Scalability
* Customer Churn Possibility
* Integration Maintenance
* API Documentation
Each point raises bigger concerns than the last. Considering that the majority of organizations rely on small in-house engineering teams with competing priorities in their backlogs, many companies struggle to initiate this project. Tasking the engineering team would take up most of (if not all of) their time, forcing them to forgo product-related tasks. Cases where there is limited effort to get started usually fail as the integrations are not being built at the pace needed.
While it may appear simple, many companies spend months integrating just one additional connector into their product. The common issue is that building these integrations in-house is technically complicated and time-consuming. Furthermore, there's always a risk of these integrations failing to meet client expectations regarding data synchronization.
In a hypothetical scenario, a company building out its integrations before engaging with customers loses a lot of time and potential capital in the process. However, the real technical challenges surface during the development phase, as managing and maintaining these integrations proves even more painful than building them.
To give you an idea of the complexity, think of a relatively simple software system. This system often consists of multiple components, services, and technologies, where each element may have its own updates, dependencies, and configurations. Within these dependencies, there are external libraries, frameworks, and services. To complicate matters further, ensuring data consistency, security, and integrity across shared libraries requires careful execution. The list goes on, but you get the idea. Failing in any of these aspects will lead to non-functional infrastructure.
Addressing these challenges often requires a combination of skilled personnel, effective project management, and the use of tools and methodologies designed to manage complexity, such as DevOps practices, continuous integration/continuous deployment (CI/CD) pipelines, and automated testing.
In today's fast-paced tech landscape, where a new SaaS solution emerges almost daily, businesses are constantly exploring new technologies, which necessitates daily construction of new connections by engineers. Once a commitment is made to develop all connections in-house, it invariably requires dedicating an engineer solely to crafting new connections.
Unfortunately, the challenges don't stop there. Integrations that have been previously built often malfunction due to changes in third-party APIs. When this occurs, the engineering team must delve into the documentation to re-establish these connections. And, as you might guess, some of these documents are exceptionally difficult to decipher, almost as if they were deliberately written in an obtuse manner.
## **Peaka’s “white label” model**
Recently, Peaka introduced a Partner API, enabling customers to leverage Peaka’s offerings under their own branding for their connector infrastructure. For those who aren’t familiar with the product, Peaka is a serverless connector infrastructure that offers connectivity to 300+ relational and NoSQL databases, APIs, and SaaS tools in minutes ([check out this MongoDB example to see how it works](https://www.loom.com/share/eaa3027ccc1b4369b5f187e69c71baf8?sid=4f52dd09-2a35-427a-accc-f4d294d70df8)). By using Peaka, companies can not only construct their data stack in mere minutes but also seamlessly integrate with their customers' tech stacks.
Peaka's partners have the flexibility to use the Partner API, JDBC driver, ODBC driver, or Python connectors for instant connection to the solutions their customers need. Furthermore, if necessary, partners can utilize Peaka’s zero-ETL solution to access every aspect of the data pipeline. Peaka's usage-based pricing model, coupled with 24/7 engineering support, provides partners with an efficient and scalable pricing strategy, allowing them to pay as they grow.
Recently, a Peaka customer shared a success story with us that underscores the importance of connector infrastructure. During a demonstration to a B2B SaaS unicorn, the prospect's Product Manager (PM) explained how they wanted to interact with our customers’ AI agent. The process required multiple systems to be interconnected, which is a fancy way of saying our customer needed built-in connectors.
Fortunately, we had onboarded this customer just two weeks before the meeting, enabling them to showcase a brief demonstration of how the agent would function on the spot. After closing that deal in about two weeks, the prospect's PM revealed that they typically spend around six months to finalize their third-party software purchases. However, the on-spot demonstration piqued their interest and significantly expedited their decision-making process in that meeting.
## **The bottom line**
Once a business leader grasps how an accessible connector infrastructure can broaden their market reach, their go-to market strategy dramatically shifts, often leading to faster deal closure.
For those who’re interested in exploring how Peaka can differentiate their product, we’d love to [discuss potential use cases and synergies](https://calendly.com/peaka/demo?month=2024-03) and encourage everyone to [discover Peaka](/)!
--- START: blog/subscription-business-flops/subscription-business-flops.md ---
# **3 Examples of Subscription Model Flops**
Not having to chase new sales at the beginning of every month, being able to sit back instead and enjoy a passive income-like revenue stream while thinking of ways to upsell and cross-sell to your customers... One can dream, right? It is dreams like this one that have entrepreneurs adopt the subscription model as the basis of their businesses.
However, not every subscription scheme succeeds. For every Dollar Shave Club story that made a successful exit, you can find tens of failures that left behind wiser entrepreneurs, less wealthy investors, and frustrated customers. Understanding how seemingly good business ideas went bust can be instructive for all of us.
## **MoviePass**
### **What is it?**
Sometimes, an offer sounds too good to be true. That might be because it really is. That was the case for MoviePass, a subscription plan that gave people [a movie ticket a day](https://www.bloomberg.com/news/articles/2017-08-15/netflix-co-founder-s-crazy-plan-pay-10-a-month-go-to-the-movies-all-you-want) regardless of the market and theater for a monthly fee. The plan's detractors argued that it was unsustainable, which turned out to be correct.
But there was a time when the future looked bright for MoviePass for a while. After Ted Farnsworth and Mitch Love bought 51 percent of the company in 2017, they lowered the monthly subscription fee from [$50 to $9.95.](https://www.businessinsider.com/inside-story-moviepass-rise-fall-2019-8) This move created the much-needed buzz, and MoviePass was adding a quarter-million new subscribers every month by the end of the year. The company had [three million](https://en.wikipedia.org/wiki/MoviePass) paying subscribers by June 2018.
However, there was a problem: Cash burn. An average movie ticket costs somewhere between [$9 and $17](https://www.vox.com/culture/2018/8/3/17643798/moviepass-outage-subscription-blockbuster-peak-pricing), depending on the market. Since MoviePass paid the full price of a ticket to the distributor, it was losing money on every ticket. Heavy users used the service more than ten times a month, inflicting serious damage on the company’s finances.
### **How did it end?**
Bleeding money on every movie ticket, MoviePass found it extremely difficult to hold up its end of the bargain. It sought ways to lower the usage rate of its [most active users](https://www.vox.com/22526008/moviepass-ftc-complaint-password-block-scam) in an effort to control the damage. So it cheated its customers:
+ [75,000 power users](https://www.nytimes.com/2021/06/08/business/moviepass-settlement-ftc.html) had their passwords invalidated,
+ These users were allowed to see a maximum of three movies per month,
+ Screening for movies was limited to certain movie theaters and time slots.
Customers do not like being cheated. MoviePass's moves to deceive its customers triggered a [class action lawsuit](https://www.businessinsider.com/moviepass-class-action-lawsuit-alleges-bait-and-switch-scheme-2019-2), hastening the end for the already cash-strapped company. The company ceased operations in September 2019. Nowadays, the brand is [attempting a renaissance](https://www.vulture.com/2022/03/moviepass-is-back-and-its-selling-your-attention.html) with a new business model.
### **Diagnosis**
How could MoviePass executives hope to make money with such a business plan? Actually, their subscription plan was just a ploy to create a vast, devoted customer base. They thought they would be able to use that customer base to negotiate lower ticket prices with movie theaters, cut [revenue-sharing](https://www.theverge.com/2019/9/19/20872984/moviepass-shutdown-subscription-movies-helios-matheson-ted-farnsworth-explainer) agreements with them, and get a portion of the food and drink sales.
The Moviepass executives believed that the bigger the customer base, the more leverage the company would have *vis-à-vis* other stakeholders in the industry. Positioning itself as a data mining company, MoviePass banked on the idea that advertisers would fight each other for the privilege of accessing this customer base, which never happened.
It turned out that established movie theater chains like AMC did not want to be bullied around by an upstart. They refused to share revenue with MoviePass. Upon realizing how easy it was to copy the idea, those chains launched their own subscription services like AMC Stub A-List or Regal Unlimited.
MoviePass took the disruptor role to an extreme. It failed to blend into the Hollywood ecosystem, where many different players make money from the existing business model. Instead, it attempted to overthrow the established order on a wing and prayer. It was a shame that it forgot it was selling [another company's product](https://www.theverge.com/2019/9/19/20872984/moviepass-shutdown-subscription-movies-helios-matheson-ted-farnsworth-explainer) and had no extra revenue streams.
## **ScaleFactor**
### **What is it?**
ScaleFactor's rise to fame had all the elements of a feel-good story: A tech startup from Austin, Texas, leveraging a trendy technology, artificial intelligence, to solve a problem affecting a large group of people, bookkeeping for small businesses. Founded in 2014, the company claimed that its technology would allow the automation of accounting processes after a brief consultation with clients. This promise may sound too good to be true now, but it was deemed credible by investors. ScaleFactor raised [$100 million](https://news.crunchbase.com/news/scalefactor-raises-third-round-60m-in-13-months-after-700-arr-growth-in-2018/) in funding from [June 2018 to July 2019.](https://pitchbook.com/profiles/company/167820-49#overview)
### **How did it end?**
Despite its lofty promises, ScaleFactor proved to be a scam of epic proportions. As was revealed by former employees of the firm, ScaleFactor's operations had nothing to do with AI. It was just good ol' manual bookkeeping carried out in the background and obscured by financial tricks. Part of the job was even outsourced to an accounting firm in the Philippines.
Although nobody could have predicted this dark secret about how ScaleFactor conducted its business, the poor quality of the service spoke for itself. Unimpressed by the quality and suffering from costly accounting mistakes, ScaleFactor customers began to quit in droves in 2019. The churn rate was so high that the company set up a "[Churn Desk](https://www.forbes.com/sites/davidjeans/2020/07/20/scalefactor-raised-100-million-in-a-year-then-blamed-covid-19-for-its-demise-employees-say-it-had-much-bigger-problems/?sh=647425f62928)" to prioritize the cancellation requests so that the financial outlook of the company wouldn't take a big hit.
Having realized there was no hiding the truth, the company announced in January 2020 that it was adopting a marketplace model to bring together small businesses and accountants (one could argue that was what ScaleFactor had been doing all along). This decision was followed by a hike in subscription fees as customary for startups about to go under. The firm finally [ceased operations](https://www.emergingtechbrew.com/stories/2020/07/22/scalefactor-reportedly-struggled-develop-software-promised-customers) in July 2019.
### **Diagnosis**
ScaleFactor's bookkeeping product did not possess the capabilities advertised. The AI technology at the time was not mature enough to help develop an AI-powered accounting suite capable of delivering real-time updates, and it still is not.
Moreover, it turned out that accounting did not lend itself particularly well to AI-powered automation due to the high level of human judgment required and the potential cost of any mistakes. Accounting processes might seem tedious, boring, and quite straightforward to us. But it takes a good deal of professional experience and a deep understanding of legislation and [Generally Accepted Accounting Principles](https://www.investopedia.com/terms/g/gaap.asp) to decide how a transaction should be categorized. This certainly is not the kind of job you assign to AI and walk away.
## **Munchery**
### **What is it?**
Munchery was a meal delivery startup that sold meals prepared by chefs in one of its kitchens in San Francisco, Seattle, and New York. It charged its customers a monthly membership fee of $8.95, which gave them a 20 percent discount on every meal they purchased. One of the early movers in the meal delivery business, the company raised a total of [$125 million](https://www.crunchbase.com/organization/munchery) from investors.
### **How did it end?**
Right before its $85 million funding round in 2015, Munchery's weekly revenue had reached almost $600,000. That funding round took Munchery's valuation as high as [$300 million.](https://techcrunch.com/2019/01/21/munchery-shuts-down/) However, this surge resulted from extraordinarily intense marketing efforts—the number dipped below $400,000 after the funding round. Faced with increased competition from startups with similar business models and losing money on every customer, Munchery ceased operations in 2019, nine years after its foundation.
### **Diagnosis**
Munchery suffered from the usual problems that plague every food delivery startup: Having to excel in the supply and delivery side of operations at the same time. Buying, transporting, and preserving different kinds of chicken, fish, meat, vegetables, and herbs; preparing the meals and delivering them in the most efficient way possible is a [logistical nightmare](https://progressivegrocer.com/chefds-failure-reinforces-grocers-will-eventually-own-meal-kits) a startup can hardly cope with.
That's why meal delivery startups are always hungry for cash and entangled in supply chain issues. Morgan Springer, [the co-founder of Sprig](https://digiday.com/retail/prepared-food-delivery-startups-failing/), another meal delivery startup, sums it up nicely:
> *"…[It's] not necessarily the food that was difficult, but the challenge was more on both delivery and food, which are lower-margin businesses that are tricky to get right."*
For meal delivery startups, building brand loyalty among customers is an almost insurmountable obstacle. Customer loyalty is virtually non-existent beyond [six months](https://www.forbes.com/sites/brittainladd/2018/07/18/the-meal-kit-company-chefd-is-no-more-what-does-it-mean-for-the-meal-kit-industry/) as customers want to try new brands and are lured away by cheaper options. Therefore, customer acquisition cost tends to be really high for a meal delivery startup.
Because competing on price in the subscription-based food delivery (meal-kits or microwaveable meals) segment is a race to the bottom and expanding into new regions exacerbates the logistical problems, [the best case scenario](https://www.pymnts.com/news/retail/2018/meal-kits-chefd-grocery-blue-apron-hellofresh/) these startups can hope for is to be acquired by a retailer. Plated was acquired by Albertsons in 2017 and [Home Chef by Kroger](https://www.forbes.com/sites/neilstern/2018/05/23/kroger-buys-home-chef-as-the-meal-kit-industry-rapidly-consolidates/) in 2018. Others like Chef'd and Munchery weren't that fortunate and had to shutter.
## **Conclusion**
Making promises you can't deliver, lying to your customers about the capabilities of your product, and trying to execute a business model far beyond your means can support are surefire ways for a subscription business to shoot itself in the foot. Having a bright idea never suffices. Turning a good idea into a sound business plan is what differentiates a unicorn from a flop.
Instead of gauging its success by its popularity, a subscription-based startup should focus on attaining a defensible position in the market and keeping track of the number of its customers that will be there in a few months. Any short-term success is doomed to be elusive without a moat around your business. The CEOs of MoviePass, ScaleFactor, and Munchery can attest to that.
--- START: blog/subscription-business-model/subscription-business-model.md ---
# **Whatever-You-Want-as-a-Service: Subscription Business Model**
The "job-to-be-done" approach has been a revelation for the business world. The realization that people want to buy outcomes, not products or services, has transformed the way companies develop their products and market them.
People can get surprisingly creative to attain those outcomes and get the jobs done. As Clayton Christensen points out in his book [*Competing against Luck*](https://www.amazon.com/Competing-Against-Luck-Innovation-Customer/dp/0062435612/ref=sr_1_1?crid=1KB810F0KV3EM&keywords=Competing+against+Luck&qid=1649315888&sprefix=%2Caps%2C2408&sr=8-1), people driving to the nearest McDonald's to grab a milkshake before 9 a.m. were doing that to solve a specific problem: Making their morning commute more interesting while keeping the morning hunger at bay until lunch (*Competing against Luck*, pp.19-23). Milkshake beat all the other alternatives like coffee, bagels, doughnuts, or a Snickers bar at achieving the desired outcome. Moreover, the same customers could "hire" a milkshake for entirely different jobs in the afternoon. For example, it could be a consolation prize for a kid who couldn't get his mom to buy him a toy truck.
## **"Power-by-the-hour" a.k.a Product-as-a-Service**
Although business strategy gurus like Ulwick and Christensen are credited with coining the expression, it turns out that British industrialists were experimenting with the idea long before. First, the British aero-engine manufacturer Bristol Siddeley and then Rolls-Royce, which acquired Bristol Siddeley in 1966, had realized that airline companies were [looking to buy flight time, not airplane engines.](https://www.youtube.com/watch?v=Q4Li4750qwc) Airplane engines were prohibitively expensive. As airline companies had no expertise in engine maintenance, they either ran the engines into the ground or replaced them too early, thus incurring higher costs. Bristol Siddeley developed a subscription-based engine replacement and maintenance program in 1962.
Rolls-Royce inherited this program from Bristol Siddeley and honed. The result was the [power-by-the-hour](https://www.rolls-royce.com/media/press-releases-archive/yr-2012/121030-the-hour.aspx) model, which offered the Rolls-Royce customers Engine-as-a-Service. Rolls-Royce would take care of engine maintenance, maximize uptime for its customers, and provide its customers with new engines when needed. The program charged customers a fixed sum per flying hour in return for predictability in flight time and reduced overhead payments. Getting paid for the time engines remained operational, Rolls-Royce [was incentivized](https://www.linkedin.com/pulse/subscription-economy-did-start-power-by-the-hour-gene-likins/) to focus on R&D to improve the durability of its engines and develop new preventive maintenance measures.
## **Subscription services today**
The effectiveness of the power-by-the-hour model has inspired many recent adaptations. Tire manufacturer Michelin's tire subscription service [Effitires](https://business.michelin.co.uk/freight-transport/freight-transport-services/effitires) provides a case in point. It enables fleet operators such as logistics and transportation companies to outsource their tire management tasks to Michelin, which has been producing tires for more than a century. The scheme improves fleet uptime and renders a major cost item completely predictable for the customers.
What started in the capital-intensive aviation industry has become mainstream today—just think about all the subscription payments on your monthly credit card bill: Netflix, Amazon Prime, or HBO Max for home entertainment; Apple Music or Spotify for streaming music, Dollar Shave Club or Birchbox for regular supply of personal care items, to name a few. The average monthly spend on subscription services rose from [$237 in 2018 to $273 in 2021](https://www.westmonroe.com/perspectives/report/the-state-of-subscription-services-spending), an increase of $432 per year. This 15 percent increase has given subscription-based businesses a significant boost, helping them grow [five to eight times faster](https://www.forbes.com/sites/danadunne/2021/12/03/the-origin-of-the-subscription-model/?sh=3d5041d96c74) than traditional companies.
Software-as-a-Service (SaaS) companies have built their entire business model on subscriptions. This model determines not only how SaaS companies make money but also how they develop their products. By allowing SaaS companies to track usage, the subscription model provides product teams with a constant stream of customer feedback, enabling them to modify, improve and tailor the product to the customers' specific needs. Companies practicing traditional sales methods are not that lucky, though: They usually receive feedback from customers only in case of complete satisfaction or extreme dissatisfaction with the product.
## **The advantages of the subscription model**
The subscription model owes its success to its ability to offer customers and vendors a happy medium. It helps the former enjoy products and services without high upfront costs. Customers also retain flexibility because they can cancel their subscriptions anytime.
The benefits vendors derive from the subscription business model are manifold. First, they get to develop a bond with customers and maximize [Customer Lifetime Value](https://en.wikipedia.org/wiki/Customer_lifetime_value) (LTV). One of the crucial metrics a SaaS company has to monitor, LTV refers to the total revenue a customer account will generate. The subscription-based business model [lowers the barrier](https://gocardless.com/en-us/guides/posts/5-benefits-of-a-subscription-business-model/) for other offerings from the same vendor and opens up new growth opportunities through upselling and cross-selling. This maximizes the LTV by bringing in add-on revenue without incurring any marginal cost to acquire new customers. A happy subscriber is a golden goose for a SaaS company.
Secondly, the bond nurtured between the customer and the vendor introduces predictability into the vendor's future cash flows and [secures long-term revenue for the company.](https://www.profitwell.com/recur/all/recurring-revenue) This long-term revenue stream makes it easier for decision-makers to plan ahead on issues ranging from investment to hiring.
"*Lease, don't buy*" perfectly sums up the current zeitgeist. Startups that recognize that people are looking to get things done rather than owning stuff can capitalize on this and take off. By simply selling new products and services to a fraction of the existing subscribers, a company can unlock the magic of recurring revenue and achieve [compounding growth.](https://www.profitwell.com/recur/all/recurring-revenue) That's how unicorns are made.
--- START: blog/subscription-model-tips-warnings/subscription-model-tips-warnings.md ---
# **The Subscription Model: Tips & Warnings**
We [previously covered](/blog/subscription-business-model/) how subscription became a prominent business model and how SaaS businesses leveraged that model to become unicorns. The applications of the recurring revenue model are not limited to SaaS businesses, though. If you have an eye for innovation, you can adapt this model to many different industries. There are a few points to bear in mind, however.
## **Act to disrupt**
The subscription model lends itself to creativity quite well. Most successful subscription-based businesses were not built on revolutionary ideas but rather a creative take on a conventional problem. Some of these businesses create value for you by spreading a lump sum payment over 12 months; others help you deal with perishable inventory in return for a fixed monthly amount.
There are also subscription products whose value proposition is based on saving you from having to deal with a nuisance. Take buying razor blade cartridges, for example.
You don’t buy replacement cartridges frequently enough, so they are easy to forget during your supermarket trips.
Availability is another concern with razor blade cartridges. When bought so seldom, new cartridges turn out to be of a different design, which is not compatible with handles purchased in the past.
The price stability of replacement cartridges is the third problem. As commodity prices fluctuate, you can be forced to pay significantly higher prices in your future purchases.
Dollar Shave Club solves all three pain points with its subscription model. The brand’s subscribers receive razor blade refills (and other personal care products) without paying for delivery and according to a schedule of their choosing. Launched in 2012, the brand came with an [initial offering](https://www.digitalcommerce360.com/2015/05/13/how-dollar-shave-club-makes-cut/) that cost its customers just $1 a month for 60 blades a year, when Gillette sold a package of 10 cartridges for $19.99. Dollar Shave Club had [3.2 million subscribers](https://en.wikipedia.org/wiki/Dollar_Shave_Club) in 2016 and was looking at a sales revenue of $200 million for the year when it was [acquired by Unilever](https://www.nytimes.com/2016/07/20/business/dealbook/unilever-dollar-shave-club.html) for a sum of $1 billion.
This model can be adapted to any business idea that offers a solution to some sort of a nuisance people have in the back of their minds. Whether it is regular purchases of flowers, mowing the lawn, or spraying the backyard to keep mosquitos away, there are many services or products people would like to subscribe to so that they cross tasks off their to-do lists.
## **Beware of the churn**
Churn refers to the rate at which your customers quit their subscriptions. It can be expressed either in the percentage of customers leaving your brand or the revenue you lose due to that.
Some of the churn is involuntary and thus unavoidable. People die, [their credit cards expire](https://www.invitereferrals.com/blog/customer-churn-strategies/), or their needs change. The biggest reason for the avoidable portion of churn is your [failure to onboard](https://www.forentrepreneurs.com/top-two-reasons-for-churn/) the customer. Without a smooth, well-designed onboarding process, the customer cannot engage with the product and quits without getting to appreciate the value your subscription offers.
Containing churn should be a startup’s primary goal. However, amidst all the troubles a startup has to wrestle with initially, the need to minimize churn will probably not be a priority. After all, churn can seem manageable at the early stages. If you have 20 paying customers and a monthly churn rate of 5 percent, that would mean one customer quitting his subscription and leaving every month. That’s easy to make up for. All you have to do is work a little harder and sell just one more subscription the next month. However, it all adds up in the long run as you bring in more customers.
Investor and product-led growth guru David Skok [uses a model](https://www.forentrepreneurs.com/why-churn-is-critical-in-saas/) to demonstrate the long-run impact of churn. Skok starts with a hypothetical MRR of $10,000, $2,000 in additional subscriptions every month, and a monthly churn rate of 5 percent. His model generates $90,000 in lost monthly revenue at the end of the fifth year. That’s a lot of money to leave on the table.
The best move to reduce churn would be to redesign your onboarding, remove friction, and fast-track the customer’s journey to her “aha” moment. Another option could be to charge your customers upfront. After making a lump sum payment at the beginning of the subscription, your customer will be more motivated to use and engage with your product in order to get her money’s worth. This will increase her chance to derive value from the product.
## **Upsell & cross-sell**
People reconsider their subscriptions from time to time as different payments pile up on their credit card bills. They conduct a triage every now and then and quit some of their subscriptions while they try out new ones. You don’t want yours to be among the ones getting axed.
Two methods can help entrepreneurs retain customers in a subscription model:
1. **Upselling:** Selling existing customers [upgrades or new products or services at higher price points.](https://en.wikipedia.org/wiki/Upselling)
2. **Cross-selling:** Selling customers [related or complementary products or services.](https://www.investopedia.com/terms/c/cross-sell.asp)
A financial consultant serving his customers on a subscription basis can take advantage of upselling opportunities to reduce customer and revenue churn. He can charge his customer a higher price for a premium option where they can reach him 24/7. Such a move not only creates additional revenue for him but also engenders customer loyalty.
For an example of a business leveraging cross-selling to expand its revenue and boost its revenue, we can turn to Dollar Shave Club again. Having started with selling only replacement razor blade cartridges, the company later set its sights on “[owning the bathroom cabinet.](https://www.digitalcommerce360.com/2015/07/16/gillette-wants-slice-online-razor-club-business/)” Today, the brand will sell you anything you need in the bathroom, from shaving butter to shower gel, skin care products, and even wet wipes.
Upselling and cross-selling bring in additional revenue that can neutralize the customer and revenue churn your startup is suffering from. These two techniques can help you achieve [negative churn.](https://www.forentrepreneurs.com/why-churn-is-critical-in-saas/) This term refers to the amount by which your expansion revenue (revenue from new signups, upselling, and cross-selling efforts) exceeds the revenue you lose because of churn.
Net negative churn is how the subscription model works its magic. It reverses the compounding impact entrepreneurs suffer from when they have churn. Thanks to negative churn, you can grow your baseline revenue, increase customer lifetime value, and achieve a level of MRR you would not have believed was possible before starting off.
## **Conclusion**
It is no surprise that the subscription model has become so common in the last few years, regardless of the industry. It provides a win-win situation between the customer and the company. Barring any radical changes in customer requirements or product quality, the subscription model sets the stage for a long-lasting relationship, which every startup should strive for.
--- START: blog/task-management-template/task-management-template.md ---
# **The TaskAce Template Fosters Collaboration in Project Teams**
Project management is rife with challenges. Planning a roadmap, gathering the resources necessary for its execution, managing the setbacks throughout, and keeping the team aligned behind a common goal are some of the hurdles decision-makers should overcome to see projects through to completion. The digital transformation proceeding at full speed, the ever-increasing competition in the software industry resulting from the introduction of new products every day, and the pandemic-related measures still in effect further complicate things nowadays.
Project management will remain a challenge as teams take on more and bigger projects. The number of projects IT was asked to deliver in the enterprise segment [increased by 40 percent](https://www.mulesoft.com/lp/reports/connectivity-benchmark) in 2021, and 52 percent of projects weren't delivered on time. Delays in project execution puts the company's reputation on the line and can even trigger legal action by other stakeholders. To avoid such risks, companies should either dedicate more resources to projects—which would be costly at a time developers are at a premium—or find ways to become more efficient in using their human resources and time.
However, running projects more efficiently is easier said than done. Let's take a look at the common problems associated with project management:
## **1 - Getting everyone on the same page**
Project management involves bringing together diverse talents and making them work in harmony. This requires ensuring that people involved understand their roles and agree on what needs to be done. Lack of communication can lead to uncertainty about roles, deadlines, expectations and eventually cripple the project. A [PMI survey](https://www.pmi.org/-/media/pmi/documents/public/pdf/learning/thought-leadership/pulse/the-essential-role-of-communications.pdf) conducted in 2013 revealed that miscommunication accounts for 56 percent of the risk posed against projects. To make matters worse, the recently-popular remote work practices have introduced new barriers to communication, which added to the responsibilities of the leaders. Communication can make or break a project.
## **2 - Holding people accountable**
When things don't go according to plan, people start pointing fingers. Some of this results from people's unwillingness to own up to their mistakes, but a big part of it is due to a lack of clarity on roles. The only way to avoid the blame game is to promote open and continuous communication. Instead of waiting until the deadline to see how people are doing, regularly checking in to see if anyone is blocked or needs assistance helps avoid disaster down the road.
## **3 - Unclear goals**
The uncertainty about what the project aims to achieve can come in different shapes and forms, but it always brings the motivation down and makes people feel like they are drifting along. A few other problems may surface and make the situation more complicated. Scope creep may set in, with the project leadership caving in to pressure from the customers to include new features. As a result, requirements will change, moving the goalposts. Budget and team configuration may be incompatible with the goals, making the team feel stranded, unable to make any progress. At the root of all these problems lies the failure of the project leadership to communicate with the customers and the team members.
Decision-makers should set [SMART](https://lucemiconsulting.co.uk/smart-goals/) (Specific, Measurable, Achievable, Realistic, Timely) goals to avoid pitfalls and contain problems like scope creep, budgetary limitations, and incompatibility between the goals and the skillset available on the team.
What if you are working with a distributed workforce? How do you ensure that your team is in sync when team members haven't shared the same office in weeks? Employees taking leave due to Covid-19 or having to work from home and offices getting shut down as per pandemic regulations have been quite common in the last two years. Regardless, companies had to keep going as they needed the cash flow.
It was in such an environment that more and more companies came to embrace agile practices over waterfall project management. Agile methods ensure that projects are executed incrementally, enabling a company to pivot instead of committing resources to a dead-end project. But agile project management requires a new mindset from the team members and a focus on continuous communication. With so much on the line, project teams turned to task management software to get the best out of agile practices. Teams discovered that tools like Asana, Trello, Jira, or Clickup could help ensure that everyone is on the same page and understands his responsibility.
However, having so many options can be a curse, too. Picking the right task management tool for a team can be quite tricky for the uninitiated. While cost can be a concern for some teams, others may find out that their needs do not justify a suite of advanced features.
This is where our [TaskAce template](/templates/) comes in. Peaka recently published this template for teams reluctant to shell out big bucks for task management software with features they will never use. TaskAce provides its users with the basic functionality of a kanban board, allowing them to assign tasks to team members and view those tasks as *complete*, *in progress*, and *incomplete*. The template caters to the needs of teams that value simplicity and efficiency over sophistication.
Get TaskAce, customize it for your team and take teamwork to the next level!
--- START: blog/templates-know-how-transfer/templates-know-how-transfer.md ---
# **Templates as Means of Know-how Transfer**
“Ars longa, vita brevis,” the Romans would say. “Skillfulness (i.e., learning a craft) takes time, but life is short.” They were right. Life is too short to learn everything from scratch and master everything you took an interest in. Thankfully, humanity found ways to accumulate knowledge and hand it down to the next generations so that each generation did not have to start anew.
One medium of know-how storage that we use in our daily lives is recipes. Every family has a few recipes that they cherish and pass down from one generation to another. These recipes detail the steps to be followed to prepare some traditional dish for a festive day, a dessert for an anniversary, or a soup with healing powers that is cooked every time somebody in the family goes down with a cold. Recipes encapsulate a particular body of know-how that was distilled into basic instructions after much trial-and-error and turn that know-how into actionable instructions thanks to standardized measurements. *Two liters of chicken stock, one tablespoon of ginger, a pinch of parsley…* Even a teenager, once she gathers the necessary ingredients, can replicate the taste of a soup her great-grandmother would have cooked decades ago without guidance from anyone by just using a recipe.
In that regard, recipes can be regarded as templates that are based on best practices and optimized, repeatable processes. They are means for storing and transferring know-how. In this age of hectic change where we dare to venture into different domains of knowledge we have no expertise in, templates are our shortest routes to success.
Take e-commerce, for example. Despite the recent boom it has been through, this particular activity involves so many diverse aspects that it can intimidate someone willing to try his luck by setting up a website to start selling stuff. It requires technical knowledge, domain knowledge, a network of vendors, and a logistical infrastructure one can leverage, etc. It is not as straightforward as it might look. However, entrepreneurs are not disheartened by this challenge. They know that they won’t have to reinvent the wheel. There is enough know-how accumulated and crystallized in best practices that even the most technophobic entrepreneurs can find their way around in e-commerce.
One company that recognized the power of templates and used them to transform its business is Pitch. The company started off by offering templates for presentations that people like founders could use to pitch their ideas to investors. Hence, the word Pitch.
However, Pitch started to disrupt the consulting industry once it began offering the templates consulting firms used during their presentations to executives. Consulting firms keep their know-how in giant databases of actual cases, which they later leverage to develop solutions for the problem of a specific client. The eventual solution a consulting firm proposes tends to be based on a best practice, which is basically a template customized to the client's specific needs. Pitch offered the same service at a fraction of the cost, disrupting the whole industry.
Starting a business has never been easier than it is today. However, the time and resource constraints still remain. The know-how needed to create an end-to-end experience for customers takes a lot of time and money to accumulate. You need to put together a team of experts or acquire the know-how directly from a consulting firm in areas where you lack the domain knowledge. Then you have to spend time on UI, UX, and data architecture—things you can develop in-house in the long run or outsource at significant cost.
It is safe to assume that no-code platforms will fast-track this process and reduce the costs involved. These tools help entrepreneurs productize their ideas in a short time. No-code templates will serve as pre-packaged stacks of domain know-how that customers will put to use immediately.
We at [Peaka](/) think that providing our customers with flexible data models has to be a priority. Because without flexible data models, customers will inevitably run into problems that they had not foreseen at the beginning and may require the migration of data to fix. Data migration, albeit possible, is a risky process since the data migrated may not perfectly map to relevant fields on the new platform. With our no-code templates, our customers will no longer have to worry about such technicalities and instead focus on scaling their business.
--- START: blog/tips-for-freelancing-success/tips-for-freelancing-success.md ---
# **4 Tips for Sustainable Freelancing Success**
Getting started with the freelancer life can be frustrating. Been there, done that. Despite the promise of quick success (just search for the phrases “make $10,000” and “as a freelancer” on Google to get an idea about the number of clickbait articles written on the subject), it is likely that the first few months will fall short of your expectations, with lots of hiccups along the way. Landing the best freelance jobs can be a challenge for anyone—it is a matter of timing and finding the right fit for your skills. But a few steps that you can take can significantly increase your odds of success.
## **1 - Beware of the scope creep**
Freelance work online is uncharted territory for a newcomer and defining the limits of the work you will undertake will be your first wise move. When negotiating a project with a client, you might get more than what you bargained for. Clients, especially those without a tech background, tend to have higher expectations with regards to the scope of the project—they want everything but the kitchen sink. You might be expected to deliver a project that should in fact be done in phases or by different professionals. Therefore, you need to know where to draw the line and ask for more money for the extra work you will do or turn down the offer despite the pressure to score a win. Do not assume that things will work out without first coming to an agreement with regards to the [scope and duration of the project and the revision process](https://medium.com/swlh/how-to-become-a-better-freelancer-by-avoiding-these-3-mistakes-6643ee3b9a1c).
## **2 - Establish long-lasting relationships with clients**
Bear in mind that building trust and working with the same clients for long periods of time reduces the work stress, and the monetary return can be substantial, too. Loyalty to a client will lower the administrative burden you need to shoulder every time you start a new project—the time it takes for both parties to understand each other, endless negotiations on contract terms and countless emails that need to be exchanged before the project starts. You don’t get paid for the time you spend for any of these so the smaller the project, the bigger this overhead cost will be for you. The long-term relationships further pay off on platforms such as [Upwork and Peopleperhour](/blog/tips-for-freelancing-success/), where the commission rates charged decrease as the total amount of billings with a particular client increases.
## **3 - Take the road less travelled**
Give [local and specialized](https://www.forbes.com/sites/jonyounger/2020/12/16/freelancing-2021-the-trends-i-see-for-the-freelance-revolution/?sh=255a29942086) freelancing platforms a chance. [Chetu](https://www.chetu.com/) is one such platform that offers a more localized service to promote real-time interaction between the developer and the client. Another one, [Gigway](https://www.gigway.se/), narrows its scope down to a single country, Sweden, claiming to bring together the best freelancer talent in this country. Some other platforms like [Devteam](https://www.devteam.space/) and [Stackoverflow](https://stackoverflow.com/) are great places to promote your skills as a developer. These platforms support smaller communities compared to [Upwork](https://www.upwork.com/) or [Freelancer.com](https://www.freelancer.com/), and can be a better fit for people whose self-promotion skills lag behind their technical expertise. The best freelance jobs are not where the crowds are but where you will find the right fit for your skill set.
## **4 - Invest in SaaS tools**
Freelance work online means freedom, but not many people know what they can do with theirs. Without an office life that brings some structure to your day, it is entirely up to you to organize your time and increase your productivity. The SaaS world offers an amazing variety of solutions to help with that. Getting started with a tool like [Webflow](https://webflow.com/) or [Squarespace](https://www.squarespace.com/) can help you design an infinitely customizable web site, giving a boost to your self-promotion efforts. A CRM app like [Pipedrive](https://www.pipedrive.com/) lets you manage your business contacts, nurture your leads and cultivate long-term relationships with clients. [Calendly](https://calendly.com/) allows you to organize your day, schedule meetings or let your contacts pick a suitable time for a meeting with you. Tools such as [Sendgrid](https://sendgrid.com/) and [Mailchimp](https://mailchimp.com) turns sending mass emails—a real chore—into an easy task. [Stripe](https://stripe.com/) takes care of your invoicing and payment management, handling a big chunk of the accounting work for you.
## **Final thoughts**
No-code platforms like [Peaka](/) can help freelancers automate repetitive tasks and save time while enabling them to ship more apps in a shorter time. The integrations offered by these tools make it possible for a freelancer to establish workflows that can handle the tedious parts of work, letting him focus on parts where his creativity is better employed. This automatically gives a freelancer a much-needed advantage in the face of fierce competition he has to deal with, eventually improving his bottomline. Being a a full-stack platform, Peaka makes use of industry-best practices, and thus negates the effects of lack of peer review and support that are hard to come by in the absence of a regular full-time job.
Freelancing can feel like an uphill battle at times, but it doesn’t have to be a one-man crusade against everyone. Top developers are putting all of their brainpower into no-code tools, solving problems for you behind the scenes and equipping you with a capable weapon to take on challenges with. Why not leverage them to grow your freelance business?
--- START: blog/top-5-audio-editing-software-2021/top-5-audio-editing-software-2021.md ---
# **The Top Five Audio Editing Options for 2022**
If you’re ready to start recording your own podcast, or if you are into recording and editing live music, then an audio editing software package is a *must* for optimizing the quality of your content. Even if you’re just designing a short YouTube video, you will discover that a seemingly quiet recording environment is often rife with annoying “background” noise that you’ll want to strip out. Audio editing software is used to achieve this by providing tools to enhance and clean up the sounds in your video productions.
No matter what your project, it’s wise to gain an understanding of the different audio editing packages that are available because they will go miles in enhancing your content quality. However, wandering into the dark, unknown woods of audio software can be intimidating if you don’t have a guide.
We’re here to be that guide. From no-cost, open-source audio editors to supercharged software packages used by music professionals, we’ve done all the legwork for you and are pleased to present the best market options for achieving superior audio quality below.
## Audacity
[Audacity](https://www.audacityteam.org/) is an open-source, and wildly popular audio editing program with a 20-year history of remarkable success with musicians, podcaster and pretty much anyone interested in editing their own audio. Audacity can run on Windows, Mac OS, and even Linux machines and the requirements are so minimal that if you bought your computer at any point in the previous 15 years, you’ll be just fine.
Audacity offers a slick, multi-track editing timeline making it easy to quickly learn how to edit, record, and mix audio. It can generate output in a variety of audio formats that include MP3, WAV, and more. Plus, if you’re interested in editing an existing audio file, the many supported formats should make this process quite simple. All in all, this is a powerful program that you can download free of charge.
## OCENAUDIO
In terms of pure simplicity and straightforwardness, [Ocenaudio](https://www.ocenaudio.com/) is the fast, free audio editor of choice. Oftentimes compared to its rival, Audacity, Ocenaudio is considered the simplest editor to use, and that is what seems to be its competitive advantage. It’s also entirely compatible with Windows, Mac, and Free BSD operating systems.
Along with its inherent simplicity, key features of Ocenaudio include a large library of instruments along with mastering tools to accommodate all types of music needs. It also allows for the conversion of digital audio files into WAV files that can be processed by most computers and sound cards. Additional features include a huge database of sounds and instrumentation that you can integrate into your projects to make them more engaging. Where Ocenaudio also seems to edge out Audacity is with its user-friendly interface, and its ability to handle larger audio files.
## Wavosaur
A lightweight, portable audio editor recognized and appreciated by the market for doing exactly what it is intended to do – function as a free sound editor. [Wavosaur](https://www.wavosaur.com/) is capable of processing and recording sounds and it has all the required features to edit popular audio files like .wav and .mp3 files. It’s important to keep in mind that it *only runs on Windows*, but it does come with a wide array of processing options, such as conversion from stereo to mono, and advanced features that includes resampling, pitch shifts, vocal removals, or silence removals.
Wavosaur is a great pick if you primarily work with .mp3 and .wav audio files and want to do the basics, such as splicing audio clips to create music loops, and batch convert files. One big advantage of Wavosaur is that it doesn’t have an installer, so you can just download and run the app.
## Ableton Live
Originally designed to combine music production together with live performances, [Ableton Live](https://www.ableton.com/en/live/) is arguably the most preferred digital audio software by producers worldwide, and it’s as much about creativity as it is about serious audio editing. Make no mistake about it, this program is fitted primarily to DJs, electronic dance music, producers, bands, and singers that are serious about creating music and editing with a swath of editing tools and effects.
The functionality and user-friendly features make it a top-of-the-line choice not only for veteran producers, but also for those just entering the music production scene with a big appetite for robust software. Ableton Live comes absolutely loaded with a wide array of customized tools that allow musicians to create new instrument sounds and it works remarkably well for live performance recordings.
While it can run in both a Windows and Mac environment, users will find that robustness and quality come at a bit of a price. The lightweight Intro version currently runs $99, the Standard version costs $449, and the Suite version costs $749. If you’ve got the budget, the top-level suite of pro audio editing features in Ableton Live make it a very compelling option.
## Avid: Pro Tools
If you’re pegging your sound editing software with promotional language like “*power your sound with the tools that power the industry*" or "*from the comfort of your own home*”, you’re making quite a claim. But when you’re also earning PCMag’s “Editor’s Choice” awards, that’s called credibility for offering an astonishing product. Whether producing an album, mixing a film or even a video game soundtrack, [Pro Tools](https://www.avid.com/pro-tools) has a reputation for offering the very best technologies for audio editing. And it’s available for Windows or Mac.
A major advantage of Pro Tools is its ability to provide users with a useful way of seamlessly working with other musicians, including forwarding projects to producers, or sharing detailed track data with mixing engineers. In other words, Pro Tools is an audio editing software package suitable for a Hollywood movie or professional studio album.
Pro Tools offers many flexible options, including a free intro version. For the serious player, you can pay $299 up front for one year of access, plus a complimentary two months. For those who want to take it slower, the $29.99-per-month plan is offered. And, if you want to cancel at any time there is a $34.99 monthly plan.
## The Verdict
While it largely depends on your project needs and how “deep” into the technology you want to go, it’s so difficult to argue against a free trial and that’s why we feel Avid: Pro Tools offers the best deal for quality. You can start without paying anything and easily upgrade to another subscription. However, there’s always a learning curve when you try using software from the industry heavyweights. If you want to try one of the simpler interfaces that come with the cost-free audio editors, those options have been mentioned in this list as well.
In any circumstance, we encourage you to explore these packages considerably and find the right one to suit your needs before breaking your budget. You may find the cost- free options quite appealing for your project.
--- START: blog/top-data-integration-tools/top-data-integration-tools.md ---
# **Top 10 Data Integration Tools in 2026 (Reviewed & Compared)**
“*Data is the new oil,*” they say. However, data you can not use is like an untapped oil reserve under the ground. Data integration is the process that combines data from different data sources and brings it into a target system where it can be used by people after the necessary transformations are performed.
However, data integration is not about just moving data from one location to another. Depending on the situation, it may require cleaning, normalizing, or transforming the data into a new schema. Most of the time, it is a process rife with human errors and technical setbacks, which leaves decision-makers disappointed despite the commitment to build a single source of truth.
Taking into account all the environments, different data sources, and user types with varying levels of technical skills, it becomes increasingly difficult to navigate the field. In this guide, we’ve reviewed and compared the 10 best data integration tools in 2025, breaking down their key features, strengths, and limitations.
Whether you’re integrating SaaS apps, databases, or cloud services, this side-by-side comparison will help you make an informed decision and avoid costly missteps.
## **What is data integration?**
Data integration is the process of collecting data from different sources and consolidating it in a central repository. This process reconciles format differences between the source and the target and standardizes data, ensuring that it is accessible to and usable by teams and individuals who need it. The ultimate goal of data integration is to enable users to query this consolidated data to generate reports and gain a holistic view of business operations.
## **Key concepts in data integration**
Data integration tools go through a series of tasks to combine data.
**Data extraction:** Data extraction refers to how data integration tools retrieve data from various sources such as relational databases, NoSQL databases, APIs, and SaaS tools. These tools leverage connectors to streamline this operation and perform it at scale.
**Data transformation:** This is the step where raw data is converted into a new format usable by the target system. Data transformation helps fix data quality issues and ensures data will be compatible with target systems.
**Data mapping:** Data mapping is the process of matching the data fields in one database to data fields in another source. Establishing how data fields will be related to each other helps standardize data and eliminates conflicts. Modern data integration tools provide users with a visual interface to handle this rather technical process.
**Data loading:** Once data is extracted, transformed into the required format, and mapped to the target data field, it is loaded into the target system. This step can be performed in different ways, such as batch loading, stream loading, incremental loading, and full refresh loading.
**Data validation:** Data validation assures that data is accurate, consistent, and reliable. This process gives data a seal of approval, indicating that it meets the required quality standards, complies with regulations, and, therefore, is safe to use for business operations.
## **Data integration vs. Data ingestion**
These two concepts sometimes get mixed up. Data ingestion is the movement of raw data from disparate sources into a target system. It involves extracting data from sources such as databases, applications, or streams without processing it and is limited to the initial data collection and storage stages.
On the other hand, data integration is a more complicated, multi-stage process involving complex transformations and data mapping. Data integration aims to retrieve bits and pieces of data from different sources, standardize it, and create a cohesive dataset that can be used for business purposes.
Tune into this video for a deep dive into the differences between data ingestion and data integration:
{{ youtube(id="9v6NpLGIZAk") }}
## **Challenges of data integration**
Data integration is not an easy task, considering that even the tiniest startups work with tens of different applications, databases, and spreadsheets and create gigabytes of new data every day. Breaking down data silos and creating a single source of truth comes with unique challenges:
### **Poor data quality**
Data quality has a direct impact on how data is used. Low quality may render data unusable, putting all the infrastructure to collect and store data at waste. High-quality data is accurate, complete, up-to-date, and consistent across all your systems. It adheres to a valid format and has no duplicates. The more quality dimensions data lacks, the more difficult it becomes to work with it.
Data quality problems add friction to the data integration process. These problems must be addressed by someone, preferably by people who are the most familiar with the data at hand. Ensuring the data is correct, complete, and in a valid format is necessary for smooth data integration.
### **Variety of data sources**
As a company grows, new people join, and new departments are formed to serve new functions. As the functions get diversified, so do the software programs being used. Connecting a new data source to an existing system introduces new challenges for an IT team.
Data sources come in all kinds of flavors: They differ in their location (on-premise or cloud-based), structure, schemas, and formats. IT people need to reconcile these differences through extensive data modeling and mapping to transform the data so it can be loaded to the target destination. The higher the number and variety of data sources, the more complicated it becomes to integrate data.
### **Scalability**
Scalability refers to a system’s ability to handle increased workload without a drop in system performance or user experience. In the context of data integration, it corresponds to a platform's ability to handle queries in an acceptable timeframe and retrieve data in an efficient manner.
Conventional data integration is based on ETL (extract-transform-load) processes, which involve converting the data to the desired format before loading it into the target location. Each ETL process is built for a certain kind of transformation, and a new ETL pipeline is needed every time the input or output format changes. This inflexible approach hinders scalability, which data integration platforms try to overcome with data pipeline automation or ELT processes.
### **Data security**
Any data-related issue has a security dimension, even if the data is passively sitting in a hard drive in a drawer. A dynamic process like data integration, where data flows in from different data sources and gets blended, multiplies the security risks involved, making data security one of the significant challenges.
Data integration platforms gain access to data with different levels of confidentiality, such as customer, employee, operational, or financial data. Protecting this data is critical to ensuring that a company runs smoothly and preventing data breaches or leaks, which can be disastrous for a business's reputation and profitability.
Therefore, organizations must take every precaution to maximize data security. A well-planned data integration process with end-to-end security is a good first step in this direction. To uphold data security, organizations must establish guardrails, adopt industry standards and best practices, and decide who gets access to what kind of data. They should use data integration platforms that utilize techniques such as data encryption, data masking, and data recovery in case something goes wrong.
### **Cost**
Data integration can be intimidating for non-tech-savvy companies because it is a complex and expensive process. Commonly used data integration tools, known as the modern data stack, are designed to cater to the data integration needs of enterprises and priced accordingly. Operating and maintaining these tools requires investing in a team of skilled engineers and cloud infrastructure, which further drives up the costs.
Here, non-enterprise users must look for solutions that will fit their specific needs instead of going for the popular tools designed for the enterprise use case and, therefore, prohibitively costly. The needs and resources of startups and SMBs differ from those of enterprises, which can employ large data teams and invest in state-of-the-art software. Data virtualization, no-code integrators, and ready-made connectors make data integration accessible to companies with limited resources and offer great value for money compared to bloated tools these companies can neither afford nor need, to be honest.
Here is a different take on data integration challenges and how you can deal with them:
{{ youtube(id="FgL7sMij-zo") }}
## **Benefits of data integration**
Despite its seeming complexity, data integration offers a plethora of benefits that make it a must for organizations to implement. Here are the top five of them:
### **A single view of truth**
Modern organizations run different systems and applications regardless of their size. Even a small startup of under ten people starts its life with a few dozen SaaS apps and tens of spreadsheets updated regularly. For enterprises, the numbers can be staggering: [The average number of SaaS apps](https://www.spendesk.com/blog/saas-statistics/) an enterprise used in 2023 was 473, which illustrates how fractured data can be in modern organizations.
Different departments run specialized programs for their daily operations. Without a data integration process in place, each application, software, or system will become a data silo, keeping data insulated from other applications. Data integration breaks down these silos, brings together data from different repositories, and forms a consolidated view. It’s only upon this unified view, the single view of truth, that decisions can be based.
### **Data-driven decision making**
Data sitting in data silos does not mean much unless it enables data users and key decision-makers to make informed decisions. Data integration makes this possible by pulling in and prepping the data, joining it with data from other sources as per user request, and providing it to the users.
Decision-makers should rely on [accurate, consistent, relevant, and timely data](/blog/data-quality-dimensions/) for strategic success. Even for a department like marketing, access to data regarding social media, email marketing campaigns, paid ads, and content is critical to evaluating past performance, making projections about the future, and taking necessary steps to achieve goals. Data integration facilitates this by unifying the relevant data in a timely manner, which gives the leaders visibility into operations.
### **Elimination of manual processes**
Anybody who has dealt with spreadsheets before will understand how easy it is to make mistakes while copying data from one table and pasting it to another. The risk of such mistakes is significantly higher when you work with tens of different spreadsheets daily because this is the only way your company can unify its data.
As per the [1:10:100 rule](https://www.loqate.com/en-gb/blog/the-1-10-100-rule-the-real-impact-of-poor-data/), while preventing data quality issues at the source costs $1, remediating these issues later costs $10, and failure in the event of no action costs $100. Instead of employees manually entering data to reconcile various databases in different systems such as CRMs, payment processing platforms, and inventory management systems, a well-set up data integration process can unify data much more efficiently, making data flow between these systems with little room for human error.
### **Increased efficiency**
Working with data can be a tedious job as it involves repetitive tasks that need to be done daily to have a holistic view of a business. These tasks are usually time-consuming and are not a great fit for highly skilled employees whose skills can be put to better use.
Data integration platforms streamline and automate data-related tasks, allowing organizations to channel precious, scarce resources to tasks that will create more value. These tools help save time that would otherwise be spent on searching for data, manually entering it into a database, and taking corrective action in the event of a mistake.
### **Enhanced scalability**
Your typical internet user produces an immense amount of data through searches, social media use, photos taken, documents written, etc. For your typical company, the amount of data produced can quickly get out of hand as it adds new employees to its workforce and establishes new functions. Each employee and business function added means new spreadsheets, applications, and visual and audio files created.
Locating scattered data, sifting through it to spot what to keep and what to remove, turning this data into a usable format, and presenting it to data consumers in an organization becomes a significant challenge once data begins to flow in from every direction. Data integration platforms rise to the occasion in these moments, as they are designed to handle sudden increases in the volume of data being processed. Manual processes quickly get overwhelmed by sudden spikes in data volume, resulting in increased risk of errors and backlog for data users.
For a more detailed discussion of the benefits of data integration, see our article, [Top 9 Benefits of Using a Data Integration Platform](/blog/benefits-of-data-integration/), dedicated to this topic.
## **Types of data integration tools**
### **On-premise data integration tools**
“On-premise” refers to systems that are physically located on the premises of an organization. Most of the time, these systems are legacy systems an organization has been running for years or even decades, and sometimes, they are kept to store sensitive data that the organization does not want to expose to public networks.
Some companies may prefer to integrate their data using on-premise data integration tools. These tools run on a local network or private cloud, performing batch loading according to specifications. They require a data team to set up, maintain, fine-tune, and update as needed. On-premise data integration tools are less flexible than their cloud-based counterparts, as it is more difficult to scale on-premise systems.
### **Cloud-based data integration tools**
Cloud-based data integration tools have become the most popular type over the last one and a half decades thanks to the expansion of cloud infrastructure. Today, these tools form the backbone of what is commonly termed the “modern data stack.”
Cloud-based data integration tools serve as Integration-Platforms-as-a-Service (IPaaS) and use connectors to bring data into a digital warehouse where distributed data is unified. Being cloud-based allows these tools to remain flexible and scalable in the face of fluctuating demand for data integration. They are usually priced based on usage, giving users control over their data integration costs.
### **Open-source data integration tools**
Open-source data integration tools offer a cost-effective alternative to proprietary platforms, which tend to be expensive. Data integration can be a costly endeavor because buying connectors off the shelf or building them in-house costs significant sums of money. Open-source data integration tools offer connectors for free, and the code is freely available in public repositories. These tools lend themselves to customization, provided the users have the technical skills to set them up properly.
### **Proprietary data integration tools**
Cost is the main differentiator that sets proprietary data integration tools apart from open-source tools. Proprietary platforms are developed for commercial purposes and usually come with advanced features and offer a better user experience than open-source tools can. However, these platforms are costly solutions primarily built for enterprise use cases and require a skilled data team to operate, which rules them out as viable options for startups and SMBs.
## **Key factors to consider while choosing a data integration platform**
### **Problem-solution fit**
There are dozens of data integration tools in the market, each built for a specific ideal customer profile. The features they offer and the integrations they support are developed with the needs of that particular ICP in mind. Therefore, you’d be well-advised to start your search for data integration software by identifying the problem and listing the features, integrations, and functionality you’d need to overcome this problem.
### **The range of data sources to be integrated**
The number and variety of data sources a company works with usually depends on the industry and the company's size. While enterprises use hundreds of different applications, software programs, and databases, the data stacks of startups and SMBs consist of a modest number of sources. The number and types of data sources to be integrated have to be taken into consideration while choosing a data integration tool, hiring a data team, and deciding whether to build connectors in-house or use a third-party platform for integrations.
### **Connectivity**
Some organizations operate in a stable data environment where the data stack does not change. However, some organizations, such as insurance companies, need to integrate with third-party applications, government systems, and all kinds of financial software during their daily operations. For startups, connecting their data to business intelligence tools may be necessary as they want to generate reports and derive insights from their data. Companies operating in a dynamic data environment should prioritize connectivity over other capabilities while choosing a data integration platform.
### **Scalability**
Choosing a scalable platform is crucial to future-proof systems. Scalable platforms can serve even sudden hikes in the number of queries without any loss of performance. Unscalable platforms will act as a bottleneck during times of high demand and force decision-makers to look for makeshift solutions to save the day.
Data volume to be handled by data integration tools can surge over time due to the natural growth of a company or the seasonal nature of a business. Failing to handle the load at peak times can slow things down, cause a backlog, and prevent timely decision-making. It can even turn into a PR disaster if customers are directly affected by the deals in the data processing. Suppose an e-commerce business facing increased demand during the holiday season. If it takes ages for this company to match customer data with payment data, customers waiting for their purchases to be shipped will get frustrated or even cancel their orders so as not to miss other deals.
### **Process frequency**
The nature of a business informs how often data has to be brought together by data integration software. Depending on how frequently you want your data integrated, the features and capabilities you have to look for in a data integration tool will change.
“Real-time data” may have turned into a buzzword over time, but it is only a nice-to-have, not a must-have, for most companies. Some companies rely on batch ingestion that takes place in long intervals because they don’t need real-time data. For other companies that value agility, working with real-time or near-real-time data is paramount. These organizations should pick data integration platforms that use innovative approaches like [data virtualization](/blog/data-virtualization-no-code/) to reduce time-to-insights.
### **Price**
Data integration processes can become an important cost item over time, so organizations should carefully evaluate the actual price and the pricing model of solutions they are considering.
Users should base their purchasing decision on the total cost of ownership rather than one or two dimensions of it. The total cost of ownership includes setup, maintenance, and scaling costs, in addition to license fees and operational costs that change according to the usage rate.
**Open-source platforms** come with no development costs but still involve hosting, setup, and maintenance costs.
A fixed-rate **SaaS model** offers predictability but might result in overpayment if the platform is underutilized.
Data integration platforms with **usage-based pricing** take into account a lot of factors, like the amount of data handled and the compute power used. These tools tend to be more sophisticated with built-in usage monitoring, but bills can quickly rise if the company fails to estimate its usage correctly.
## **What are the top 10 data integration tools in 2026?**
### **1. Peaka**
[Peaka](/) is an innovative zero-ETL data integration platform that was built to replace expensive and difficult-to-use tools and cloud-based technologies commonly known as the “modern data stack.” It is a data integration solution purpose-built to serve the needs of startups and SMBs.
Peaka uses data virtualization to establish a semantic layer over distributed data sources, enabling users to view and query all their data sources with a single query. It leverages a library of more than 300 connectors to pull in data from relational and NoSQL databases, SaaS tools, and APIs. By eliminating ETL pipelines from data integration, Peaka allows companies without dedicated engineering resources to unify their data from any data source, form new datasets, and share them with other systems and applications.
#### **Pros**
- More than 300 ready-made connectors to retrieve data from the most popular data sources.
- Can be deployed on the cloud or on-premises.
- Supports real-time data integration, allowing business teams to access up-to-date.
#### **Cons**
- Limited technical documentation that makes it difficult for users to navigate the platform.
- Lacks an online community users can refer to for guidance, hacks, and troubleshooting.
- Requires a basic level of SQL knowledge to generate reports from the consolidated data.
#### **Pricing**
Peaka offers a freemium model that provides users with the platform’s basic functionality. The pay-as-you-go starts from as low as $1 per month and charges for the compute resources and storage used. The platform is also available with custom pricing for on-premise deployment, which is subject to change depending on the specifications.
### **2. Azure Data Factory**
Azure Data Factory (ADF) is a cloud-based, multi-purpose data integration product developed by Microsoft. In addition to data integration, ADF lends itself to data migration and data orchestration use cases, emerging as a comprehensive solution for enterprises.
#### **Pros**
- Automates data pipeline monitoring and management, allowing engineering teams to focus on value-creating tasks.
- Simplifies data ingestion with over 90 built-in connectors for the most commonly used data sources.
- Offers seamless integration with services that run on Azure infrastructure.
#### **Cons**
- Limited to Azure infrastructure and requires a significant amount of engineering resources to adapt to other environments.
- Falls behind the competition in some areas, like debugging and troubleshooting, when it comes to complex data pipelines.
- Complex pricing model that makes it difficult to predict cost and undermines budgeting.
#### **Pricing**
ADF has a pay-per-use pricing model that charges users for the resources they consume. However, the actual calculations are rather complex and depend on the use case (data pipeline orchestration, data flow execution and debugging, or data factory operations), the geographic location of the user, the frequency of activities, and whether the activities run on cloud or on-premise.
### **3. Informatica Cloud Data Integration**
Informatica is a well-known data management cloud that has recently incorporated artificial intelligence (AI) into its platform to prepare data for training AI models. One of its products, Cloud Data Integration, helps ingest, integrate, cleanse, and manage data through techniques such as ETL, ELT, data replication, and change data capture (CDC).
#### **Pros**
- Offers high scalability and uptime thanks to being a cloud-native platform.
- A highly capable platform that can integrate with a wide range of data sources, handle large volumes of data, and automate sophisticated workflows.
- Serves different use cases with its on-premise and cloud-based solutions.
#### **Cons**
- Some processes consume a lot of computing resources, which drives up the costs.
- Requires a skilled workforce to run, as complex transformations and integrations can be too difficult for regular users to set up.
- Involves a steep learning curve due to the multitude of features, workflows, and processes.
#### **Pricing**
Informatica has a consumption-based pricing model. While this gives users more control over their bills, it hinders predictability as costs can quickly rise during periods of peak demand.
### **4. Fivetran**
Fivetran is a cloud-based data movement platform that utilizes ETL/ELT processes to move data from one location to another. It copies data from a source and moves it into a data warehouse while managing various aspects of data pipeline during this process.
#### **Pros**
- Offers hundreds of connectors to fetch data from all kinds of sources.
- Comes with industry-standard security and privacy features such as end-to-end data encryption, anonymization of personal data, and column masking.
- Simplifies data governance with granular access control and permissions that can be defined at the team or connector levels.
#### **Cons**
- Despite offering economies of scale for higher usage, Fivetran can be an expensive tool for large volumes of data and in situations where data has to be resynced due to an error.
- Offers limited data transformation capability and requires other tools to handle complex transformations.
- Does not readily lend itself to on-premise deployment.
#### **Pricing**
Fivetran has a usage-based pricing model that charges users for the rows inserted, updated, or deleted over a month. This model rewards higher usage with lower unit costs, creating economies of scale for users.
### **5. Oracle Data Integrator**
Oracle Data Integrator is a flexible platform for managing large data integration projects. In addition to migrating bulk data between systems and applications, it is commonly used for business intelligence and data warehousing scenarios. Oracle Data Integrator relies on ELT processes, which makes data integration more efficient as the data is loaded directly into the target.
#### **Pros**
- Seamlessly integrates with other products in the Oracle ecosystem.
- Provides connectivity with a wide range of sources.
- Offers real-time data integration, making real-time analytics possible.
#### **Cons**
- Involves complicated setup and maintenance.
- Not easy to use for non-technical users.
- Costs too much to be an option for non-enterprise organizations.
#### **Pricing**
Oracle Data Integrator Enterprise Edition costs $30,000 for every processor license and $6,600 for the first year of software updates, licensing, and support. A “Named User Plus” license costs $900 and an additional $198 for software updates, licensing, and support in the first year.
### **6. Boomi**
Boomi is an integration-Platform-as-a-Service (iPaaS) that combines data integration with data management. It comes with a low-code interface, automates complex business processes, and helps with creating, publishing, and managing APIs.
#### **Pros**
- Offers an extensive collection of pre-made connectors.
- Supports automated data mapping powered by crowdsourced machine learning models.
- Simplified API configuration that gives centralized control over all APIs.
#### **Cons**
- Has difficulty adapting to some use cases due to limited customization options.
- Falls behind the competition when it has to deal with large volumes of data.
- May be difficult to navigate for non-technical users.
#### **Pricing**
Boomi uses a SaaS model, offering a free plan, a pay-as-you-go plan, and a custom plan that’s priced according to customer specifications. The pay-as-you-go plan costs $99 plus any amount charged for the resource usage.
### **7. AWS Glue**
AWS Glue is a serverless data integration product by Amazon Web Services. It offers a visual interface and pre-made transformations, lowering the technical barrier for users. Its data catalog functions as a central metadata repository and makes data immediately discoverable across the Amazon ecosystem once it is cataloged.
#### **Pros**
- Seamlessly integrates with the Amazon ecosystem.
- Supports connection with more than 70 data sources.
- Capable of handling complex ETL processes and large volumes of data.
#### **Cons**
- Does not suit non-enterprise use cases.
- Only runs on AWS infrastructure and involves proprietary tech and processes that may not be transferred to other platforms, resulting in vendor lock-in.
- High cost, which rules it out as an option for startups and SMBs.
#### **Pricing**
AWS Glue’s pricing model is based on data processing units (DPUs) needed to run ETL jobs. Although this allows customers to be charged for usage only, it may result in unexpectedly high costs, with customers reporting monthly bills running up to tens of thousands of dollars.
### **8. SQL Server Integration Services**
SQL Server Integration Services (SSIS) is a data integration solution developed by Microsoft. SSIS comes bundled with Microsoft SQL Server and is a good option for organizations familiar with the Microsft ecosystem.
#### **Pros**
- Readily integrates with the Microsoft ecosystem, creating synergies for users comfortable with Microsoft products.
- Provides industry-standard security features and regulatory compliance.
- Mature platform that combines an easy-to-use interface with high scalability.
#### **Cons**
- Runs on Microsoft infrastructure, which requires a long-term investment in other Microsoft products for those considering this option.
- Requires specific Microsoft know-how for debugging and troubleshooting, which some organizations do not possess.
- Platform dependency translates into high initial costs for non-Microsoft users.
#### **Pricing**
SSIS is included in SQL Server licenses, which allows companies in the Microsoft ecosystem to solve their data integration problems at no additional cost. For companies using other infrastructure, purchasing an SQL Server license can be an expensive option compared to other more cost-effective data integration solutions.
### **9. Airbyte**
Airbyte is an open-source data integration platform that leverages ELT processes to unify data from diverse sources. It is a highly flexible platform that moves data to data warehouses, data lakes, vector databases, and LLMs at a reasonable cost.
#### **Pros**
- Offers a capable, cost-effective, open-source alternative to proprietary solutions in the market.
- Supports a library of over 400 open-source connectors to retrieve data from data sources.
- Benefits from the community-driven open-source model in developing connectors, providing support, and fixing issues.
#### **Cons**
- Requires a data engineering team to set up and maintain.
- Lacks the scalability to deal with high workloads.
- Only a portion of the connectors are managed by Airbyte, with the rest being marketplace connectors it features.
#### **Pricing**
Airbyte offers a free-for-life plan where users only cover the cost of hosting. The next tier, Cloud, charges $15 per million rows synced for an API source and $10 per every GB synced from a database or data warehouse. The Team and Enterprise plans are based on custom pricing and require customers to contact the sales department for a quote.
### **10. Qlik Talend**
Qlik Talend is an all-in-one data integration solution that features data transformation, streaming, API management, and data governance. It can work with a wide array of data sources and target destinations and covers almost all use cases enterprise users can face.
#### **Pros**
- Supports real-time data integration and makes real-time data analytics possible for business teams.
- Offers advanced security features such as role-based access controls and data masking.
- Serves as a one-stop shop for an enterprise as it can fulfill data quality and governance duties in addition to data integration.
#### **Cons**
- Excludes non-enterprise use cases due to technical complexity and advanced feature set.
- Requires a skilled data engineering team to set up, operate, and maintain.
- Vague pricing model that makes it difficult to project cost.
#### **Pricing**
Qlik Talend has four pricing plans, which are seemingly usage-based. The complex matrix of features and plans lacks any specific mention of cost, and the company requires potential customers to ask for a quote for all plans.
## **Conclusion**
Data integration is not a one-and-done process. It should be constantly evaluated and optimized because organizations grow, new data sources surface, and new technologies and tools emerge. Usage patterns change, and so should data integration practices to ensure that the organization leverages its data in the most efficient way.
Choosing the right data integration software is one of the key steps in data integration as it is a long-term commitment and involves a critical asset like data. Ultimately, the choice for a data integration tool comes down to a few criteria and which tool can tick the most boxes: The specific use case, the user profile, the technical skills and resources an organization possesses, and the cost.
For non-enterprise use cases, tools relying on data virtualization and zero-ETL stand out as they get the job done with minimum overhead costs and no additional investment in hardware and data teams. Lean, efficient, and easy to use: That’s why Peaka is all the data stack a startup or an SMB needs.
--- START: blog/top-data-replication-strategies/top-data-replication-strategies.md ---
# **Top 8 Data Replication Strategies to Try in 2026**
With data streaming in from multiple departments and platforms, business leaders need a data replication plan to compile the necessary information and make timely strategic decisions. However, critical inputs can be siloed within channel-specific systems and reports, severely limiting visibility, which would be solved with an integrated platform like Peaka.
Data replication platforms solve this widespread visibility challenge by automatically transferring relevant information from separate sources into unified views for comparison, monitoring, and strategic planning.
We’ve identified the top 10 data replication strategies that companies can leverage in 2024 to more efficiently share data insights across teams.
## **Why Data Replication Matters**
A recent report found that 57 percent of businesses struggle with [slow or inaccessible data](https://insidebigdata.com/white-paper/2019-data-decisions-report-by-exasol/), but by identifying the possibilities in 2024, decision-makers can confidently utilize platforms that eliminate manual reporting burdens through a reliable, scalable data solution. You can now unlock cross-channel data by learning about consolidation, warehousing, pipeline automation, and more. You can also ensure analytics and activities align with your overarching business objectives, powered by centralized, up-to-date intelligence.
## **Key Benefits of Data Replication**
### **Increased data reliability**
Automatically copying data to secondary systems creates reliable backups, protecting companies from data loss and ensuring business continuity if issues emerge.
### **Enhanced analytics**
Combining data from separate sources provides a 360-degree view of company performance and customer behavior that exposes insights unavailable in departmental silos.
### **Improved productivity**
Teams spend less time tracking down reports, manually compiling data, or worrying about version control.
Find out how to query data [directly from its source](/integrations), in real-time with Peaka.
## **The Top 8 Data Replication Strategies of 2024**
Here are 8 replication approaches modern companies rely on to seamlessly unify data across warehouses, business intelligence tools, and other systems to create strategic alignment.
### **1. Change Data Capture (CDC)**
[Change data capture (CDC)](https://www.confluent.io/learn/change-data-capture/#:~:text=Change%20data%20capture%20(CDC)%20refers,all%20systems%20and%20deployment%20environments.) automatically tracks and replicates any database alterations as they occur in real-time, giving analysts access to the most current, up-to-the-minute information for decision-making rather than stale report snapshots. CDC replication works seamlessly across transactional databases like PostgreSQL, MySQL, SQL Server, and Oracle.
### **2. Log-based incremental replication**
Various databases provide the functionality to preserve transaction logs for several purposes, including simplifying the recovery process after an unforeseen event. Moreover, when [utilizing log-based incremental replication](https://www.stitchdata.com/docs/replication/replication-methods/log-based-incremental), replication software can examine these logs to pinpoint modifications made to the data source. Subsequently, it replicates these alterations in the target database or data store. Such modifications may include operations like INSERT, UPDATE, or DELETE within the original database.
### **3. Key-based incremental replication**
[Key-based incremental replication](https://transferwise.github.io/pipelinewise/concept/replication_methods.html) operates by utilizing a specific column within your database table, known as the replication key, to facilitate data copying. This key can take various forms, such as an integer, timestamp, float, or ID.
This method, termed key-based incremental replication, ensures that only the data alterations occurring after the previous replication process are transferred to the replica. The process involves your replication software recording the highest value found in the replication key column after each job. For subsequent replications, the tool contrasts this recorded peak value against the current highest value in the same column of the source database. If the recorded value is less than or equal to the new maximum from the source, it proceeds to replicate the updated data. After successful replication, the new maximum value from the source is saved for future reference.
### **4. Snapshot replication**
[Snapshot replication](https://www.synology.com/en-global/dsm/feature/snapshot_replication) stands out as the most frequently utilized strategy for data replication, renowned for its ease of implementation. This method captures a momentary image of the source data and duplicates this exact state across the replicas at the snapshot's timestamp.
Given its nature as a mere snapshot, this strategy does not monitor subsequent modifications within the source database. This includes deletions; data removed from the source prior to the snapshot will not appear in the replicated version. Essentially, it mirrors the source in its current state at the snapshot moment, excluding any records that have been deleted.
### **5. Full table replication**
In contrast to incremental data replication approaches that rely on log changes and updates to the maximum value of the replication key, [full table replication](https://stitch-docs.netlify.app/docs/replication/replication-methods) encompasses the complete duplication of the database. This method involves transferring all data, including new, existing, and modified rows, from the source to the target. It operates independently of any alterations in the source data, ensuring that everything is replicated regardless of whether changes have occurred.
### **6. Merge replication**
Merge replication is a method that integrates two or more databases into a single unit, ensuring that changes in a primary database are also applied to secondary databases. This characteristic sets merge replication apart from other data replication techniques. It allows a secondary database to collect updates from the primary database, apply these changes while offline, and later synchronize with the primary and other secondary databases once connectivity is restored.
Within the framework of [merge replication](https://learn.microsoft.com/en-us/sql/relational-databases/replication/merge/merge-replication?view=sql-server-ver16), both primary and secondary databases are authorized to modify the data. This feature is particularly advantageous when one database becomes unavailable, permitting the remaining databases to continue functioning and later synchronizing the offline database once it is back online.
To manage potential data inconsistencies resulting from updates in secondary databases, merge replication provides mechanisms to establish rules for conflict resolution.
Initiating merge replication similarly involves capturing a snapshot of the primary database, which forms the basis for data replication across destination databases. Thus, the process begins with the activation of the Snapshot Agent, laying the groundwork for subsequent replication activities.
### **7. Transactional replication**
[Transactional replication](https://docs.aws.amazon.com/prescriptive-guidance/latest/migration-sql-server/trans-rep.html) involves initially replicating all the data from the source, known as the publisher, to the destination, referred to as the subscriber. Following this initial replication, any alterations made to the publisher are mirrored onto the subscriber with minimal delay, preserving the sequence of changes.
Creating a snapshot of the publisher is crucial because it ensures that the subscribers start with an identical dataset and database structure as the publisher, which is essential for the consistency of subsequent updates. After establishing this baseline, the distribution agent then sets the frequency of updates that are pushed to the subscriber.
### **8. Bidirectional replication**
[Bidirectional replication](https://www.ibm.com/docs/en/idr/10.2.1?topic=multidirectional-bidirectional-replication) stands as a relatively unique approach within the realm of data replication strategies. Functioning as a specialized variant of transactional replication, this method enables two databases to exchange updates between them. Similar to merge replication, it allows for alterations to be made in both databases involved. Nonetheless, a distinctive requirement of bidirectional replication is that both databases must be operational for any transaction to be executed successfully.
## **How to Find the Best Data Replication Strategy for You**
Determining which approaches serve you best depends on use cases and stack complexity. Peaka’s analytics software combines top methods like change data capture, consolidation, transformation, and warehousing matched to your needs for unified insights.
Peaka’s dedicated service teams provide tailored guidance, identifying ideal integrations between your martech, financial data sources, support, and other mission-critical systems to un-silo insights and power data-driven planning.
## **The Bottom Line**
Say goodbye to manually assembling diluted, delayed reports that fail to connect the dots between channel activities. The future of streamlined replication is here. Evolve your analytics maturity and realize game-changing visibility through automation. Pursue platforms purpose-built to help translate enterprise-wide data into coherent intelligence that cascades company-wide into informed choices carrying bottom-line impact.
Partner with Peaka to meet your d[ata analytics](/category/saas-analytics/) needs with its state-of-the-art [zero-ETL approach](/blog/zero-etl-vs-modern-data-stack/), offering hassle-free data replication without having to copy or move your data.
See Peaka’s [growing library of custom integrations](/integrations/).
--- START: blog/top-ecommerce-api-benefits/top-ecommerce-api-benefits.md ---
# **Top 6 eCommerce API Benefits Explained**
Do you know that, like humans, computer systems can talk, too?
No, I'm not talking about a plot from a sci-fi movie where AI is trying to dominate the earth. It's a real-world undertaking that is very simple, purely logical, and, most importantly, it happens for the benefit of humans.
Yes, we are talking about the significant growth of application programming interfaces or APIs that is at the root of digital transformation. Businesses around the world are adopting API integrations to reach their goals as soon as possible. Look what Kristin R. Moyer, the VP of Gartner, has to say about it:
> *“The API economy is an enabler for turning a business or organization into a platform… Platforms multiply value creation because they enable business ecosystems inside and outside of the enterprise to consummate matches among users and facilitate the creation and/or exchange of goods, services, and social currency so that all participants can capture value.”*
With API integrations, businesses across several industry sectors are trying to innovate and reinvent themselves to cope with the trends and the competition in the market. The same is true for the e-commerce sector. The experts in this industry provide e-commerce app development services to guide businesses on how to use APIs as building blocks to pave the road to their success.
But before you start using APIs to your advantage, it is important to know what they are, how they work, and what kind of benefits you can get from using them. In this article, we will go through all of this so that when you finally employ e-commerce APIs to do your bidding, you will know what you are doing and why you are doing it so that you can get more effective results.
## **What are e-commerce APIs?**
An e-commerce APIs is a type of API that allows developers to integrate their applications [while developing an e-commerce store.](https://www.tatvasoft.com/outsourcing/2022/08/how-to-build-an-ecommerce-website.html) The API integration can be done in several ways, but the most common way is through a webhook, which is an HTTP request that triggers an action in the store's backend.
E-commerce APIs are a means of integrating different applications and services (for example, a [secure payment gateway](https://electronictransfer.com/)). For specific purposes, APIs authorize the data exchange between two or more systems. These [integrated systems work to streamline your business processes](/blog/no-code-apps-to-build/) and make them more efficient.
The collaboration of two or more systems yields more effective results, which, in the end, helps companies reach their goals faster and save money in the process.
## **How do e-commerce APIs work?**
{{ youtube(id="JoCxW5XdEpM") }}
We know that APIs are used to interact with other platforms and exchange information. E-commerce websites have to deal with tons of requests at the same moment. So, the APIs here will use the HTTP request method to request from the server the piece of information asked by the visitors.
These e-commerce APIs are based on REST architecture. They are much easier to implement using any tool and you have to just use a simple URL for it. [REST APIs are extremely helpful](https://www.ibm.com/topics/rest-apis) in accessing the data sets from the server of an e-commerce website. Therefore, developers tend to include them in their search and query tools.
When using REST architecture-based APIs for your e-commerce website, you can also strengthen your site’s security as these APIs support OAuth 2.0 authentication, which is popularly used in apps like Google and Facebook.
Moreover, REST API also supports various programming languages along with cross-platform development. Now, the e-commerce APIs integrated into your site contain the following information:
+ Resources - Objects determining the relationship with other objects and processes on how to handle them.
+ Endpoints - They are the touchpoints for APIs where other systems interact.
+ HTTP method - The process of interaction between the systems where GET is used to retrieve resources, POST is used to create resources, and PUT is used to change the resources.
+ Parameter - Criteria containing the name, value type, and description to define what kind of actions you want to take on the resources.
+ The Sample Request and Response Objects - They identify the resources’ outputs and inputs.
## **Benefits of API integration**
API integration involves integrating your e-commerce platform with other systems and applications. Here are some of the benefits this process brings about API integration:
### **1 - Integration with multiple stores**
The main benefit of using e-commerce APIs is that they allow for faster, easier, and more efficient integration with other systems and applications. By using e-commerce APIs, you can integrate your site with other ecommerce platforms and also link your store with the social media platforms like Facebook and Instagram that provide a marketplace. So, the e-commerce APIs will allow you to integrate with multiple stores and handle orders from each one separately.
### **2 - More effective data management**
The data you receive from these APIs are already organized by the store itself. This arrangement means you don't have to worry about organizing it yourself or handling errors that may arise due to data inconsistencies.
### **3 - More accessible data repository**
These APIs provide access to all kinds of data about products, inventory, pricing information, etc., so you can use them for any purpose you want. While doing that, you won’t have to create your data collection processes or manually organize them into some type of database structure or reporting tool.
### **4 - Increased sales**
With API integration, you get access to the information that your customers are willing to share with you. This interaction will not only keep them engaged with your site but also increase the number of visitors. The connectivity here will just increase the value you provide to your customers, resulting in more lead generation and more sales.
### **5 - Cost-effective extensibility**
Another benefit is that APIs help businesses save money on infrastructure costs by using existing systems instead of building new ones from scratch. This extensibility saves companies time and money, which can be used toward other business objectives such as hiring more employees or expanding their operations.
### **6 - Easy data access**
API integration gives you access to data that is not available through the web interface. You can use APIs to pull data from other web services, databases, or even hardware devices. This access allows you to [create more complex products](/blog/micro-saas-marketplaces/), improve customer experience and add new features to your site.
Also, API integration can help companies improve their customer experience by giving customers fast access to information about their products or services through a single portal. For example, if you have an e-commerce website for clothing stores, you may want to allow customers to check out on your site without leaving the site where they are currently browsing through products.
## **Final thoughts**
In today’s ever-changing digital world, businesses need to adapt and grow or risk losing to their competitors. In such times, APIs can help you build an agile marketing strategy and take advantage of channel explosion opportunities.
You can catch up on every trend and increase the functionalities of your online store easily, quickly, and efficiently with the help of e-commerce APIs. Developers don't have to stress out about coding from scratch as they only have to follow the instructions on API integration. On the other hand, the customers couldn't have asked for a better user experience.
APIs help you achieve your business goals and enable you to deliver your customers better value at far lower costs, resulting in a win-win situation for everyone involved. So, what is stopping you? The sooner you acquaint yourself with e-commerce APIs, the sooner you will start reaping the rewards of your step in the right direction.
--- START: blog/top-freelancing-sites-for-developers/top-freelancing-sites-for-developers.md ---
# **Top 5 Freelancing Sites for Developers**
The gig economy or contract-based work is booming. It is known to grow every time the economy takes a [downturn](https://medium.com/swlh/gig-economy-the-future-of-work-885354c39ad0). The 2008 global financial crisis was one such period when millions of people, having lost their jobs, turned to gig economy. The Covid-19 pandemic made a similar impact on the labor market in 2020: According to a [report](https://www.ilo.org/wcmsp5/groups/public/@dgreports/@dcomm/documents/briefingnote/wcms_767028.pdf) by the International Labor Organization (ILO), total number of jobs declined by 114 million in 2020 compared to its level in 2019. In addition to millions of people who lost their jobs during the pandemic and turned to the gig economy to somehow make a living, some more fortunate people had the chance to make this shift of their own accord, not willing to spend their lives in office buildings and choosing to try their luck in the freelance market.
In the software business, it was the demand-side rather than the supply-side dynamics that helped freelancing grow. On the demand side, digital transformation in the enterprise segment put a premium on developer skills, which drove up the salaries of talented developers and put them out of reach for startups and SMBs. Freelancing websites gave these businesses a chance to employ developers at more affordable prices and stay competitive at the same time. Hiring developers can be prohibitively expensive for startups and SMBs in high-income countries, but [a developer from Latin America](https://www.revelo.com), Ukraine, or India working remotely can get the job done for a much lower rate.
Here’s a brief look at how these online marketplaces compare:
## **1 - [UPWORK](https://www.upwork.com/)**
Easily one of the top freelancing sites, Upwork boasts a user base of [12 million registered freelancers and around 5 million clients](https://websitebuilder.org/blog/freelance-statistics/) as of 2021. Freelancers can sign up, create a profile and post on Upwork the services they can offer, or they can respond to existing job posts from potential clients. The site uses a rating system where freelancers are reviewed for their work and can distinguish themselves among the crowd by delivering top work. The median hourly rate for front-end developers on Upwork is somewhere between $15-$35, while a senior full-stack developer can expect to earn $100 per hour. The [commission fee](https://support.upwork.com/hc/en-us/articles/211062538-Freelancer-Service-Fees) Upwork charges the freelancers starts from a hefty 20 percent on the first $500 worth of billing with a client and drops to 5 percent for the portion of total billings above $10,000 for that same client. Therefore, your ROI will significantly improve in the long-run if you keep working with the same clients on Upwork.
In addition to the high commission rate at the beginning, the screening process Upwork has in place can make it difficult for freelancers to enter the job segments where the market is saturated and there is no need for newcomers. Under the leadership of the CEO Hayden Brown, Upwork [purged](https://www.businessofbusiness.com/articles/18-million-users-have-been-purged-from-gig-economy-site-upwork/) more than two-thirds of its user base in 2020, going from 2.6 million to a little over 800 thousand users in a week. This was an attempt by Brown to steer the company away from a user base chasing one-off gigs to a stable [talent pool](https://investors.upwork.com/static-files/e9603ba9-29b2-4461-b55b-1994e6e2b477) for the enterprise segment and get rid of the deadweight that did not fit in the plan. It is safe to say that Upwork will position itself in the future as a platform for senior freelancers as opposed to inexperienced freelancers.
## **2 - [FREELANCER.COM](https://www.freelancer.com/)**
The biggest of all freelancing sites, Freelancer.com has hit [50 million users and 20 million jobs](https://www.freelancer.com/about/press) posted in 2021. The lack of a vetting process on Freelancer.com gives the inexperienced freelancers a bigger chance to start their freelancing careers on this platform, but it also brings down the overall quality of candidates. Members pay Freelancer.com a commission fee of 10 percent on their earnings from fixed and hourly projects. This platform is a good option for [short-term projects](https://www.websiteplanet.com/blog/upwork-vs-freelancer-com/#hselect--3) or for those who just want to test the waters and see if freelancer life is for them.
## **3 - [FIVERR](https://www.fiverr.com/)**
Fiverr is one of the better known freelance sites with [3.42 million buyers](https://backlinko.com/fiverr-users) (clients looking to hire freelancers in Fiverr lingo) as of 2021. Although it made a name for itself by hosting freelancers who offer services for as low as $5, Fiverr has evolved into a proper marketplace where buyers (clients) and sellers (freelancers) cut deals for various price levels. Fiverr charges a flat rate of 20 percent on every contract a freelancer lands. Fiverr can be a good place to land a project or two as it draws in a lot of traffic. But it probably isn’t the right place to look for premium projects. Fiverr has been a rather controversial platform, too, since it offers the seller a 14-day grace period during which it guarantees a refund for any reason, putting the whole risk of transaction squarely on the shoulders of the freelancer. Just something to bear in mind.
## **4 - [PEOPLEPERHOUR](https://www.peopleperhour.com/)**
One of the more popular freelance sites, PeoplePerHour makes use of a screening process for the applicants before signing them in, which ensures a higher level of success rate for the later projects. Businesses post their projects on PeoplePerHour and freelancers can submit their proposals for the projects they are interested in. Although its automatic invoicing [gets praise](https://www.hostinger.com/tutorials/best-freelance-websites#12_People_Per_Hour) from people who experienced it, the fact that PeoplePerHour charges you for each proposal you submit after using up the 15 proposal credits you are awarded every month means that you might lose some money before landing your first contract. Like Upwork, PeoplePerHour charges freelancers [a sliding fee](https://support.peopleperhour.com/hc/en-us/articles/205218337-Freelancer-commission-fees) based on total lifetime earnings. The service fee is rated at 20 percent for a billing total of up to $350 per client, 7.5 percent for total billings from $350 to $7000 and 3.5 percent for the portion above $7000, incentivizing long-term business relationships with the same clients.
## **5 - [TOPTAL](https://www.toptal.com/)**
Differentiating itself from other freelancing sites by using a different business model, Toptal brings together in its talent pool the crème de la crème of freelance developers. Capitalizing on exclusivity, it prides itself on offering the [top 3 percent](https://www.toptal.com/developers) from among the developers. Toptal ensures the best-project talent fit thanks to its meticulous [five-step screening process](https://www.toptal.com/top-3-percent). The hourly rate for a developer ranges from [$60 to $250](https://www.betterteam.com/toptal), reflecting the premium market positioning of Toptal. However, it is significantly more costly for clients to hire talent on Toptal than on other top freelancing sites. It charges solely the clients at a rate nearly twice the freelancer’s predetermined rate, on top of a $500 the client has to deposit for each hire.
Freelance developers always need to be at the top of their game in order to stand out from the crowd on the highly competitive freelancing sites. They should underpromise and overdeliver until they make a name for themselves, finish projects sooner than they promised and ship apps at a pace that dazzles the clients. Premium no-code tools like Peaka come with industry-best practices out-of-the-box and by taking care of things like hosting, maintenance and security, they ensure that the quality will not suffer as workload increases and the business scales. For a freelancer, no-code tools can be the difference maker between maintaining a side hustle and building a sustainable business.
--- START: blog/top-mistakes-customer-facing-analytics/top-mistakes-customer-facing-analytics.md ---
# **Top Mistakes Made While Embedding Customer-Facing Analytics**
As SaaS companies prioritize user experience and insights to gain an edge over the competition, providing users with in-product analytics has become a crucial differentiator. Whether it’s a dashboard displaying campaign metrics, product revenue, or average ticket response times, users now anticipate having their data directly visible within the products they utilize.
However, embedding this capability into products is far more complex than it first appears. Building customer-facing analytics involves much more than just building a few data connectors.
In this post, we’ll explore the most common mistakes SaaS teams make when embedding SaaS analytics and show how a tool like [Embedded Peaka](/embedded-peaka/) helps you avoid them.
## **1. Underestimating the technical complexity**
The most common mistake in embedding customer analytics is to think that connectors and a frontend charting library can suffice. The reality is different, however. For a reliable embedded analytics experience, a data stack should include
+ Connector infrastructure for third-party systems (e.g., CRMs, payment processing platforms, SaaS tools),
+ A federated query engine,
+ A UI layer with editable queries, previews, and browser components,
+ OAuth flows, retry logic, and rate-limit management,
+ Security, governance, and multitenant data isolation.
Most of the time, teams are forced to work with a patchwork of open-source and custom tools to build a functioning embedded analytics infrastructure. But, the hassle of maintaining brittle pipelines renders this effort unsustainable over the long term, making the team look for alternatives or give up altogether.
## **2. Over-reliance on data replication**
Another common blunder in embedding customer analytics is to resort to extensive data replication. Copying and moving data into a data warehouse to make it searchable may sound sensible at first, but it comes with problems:
+ **Latency:** Copying and moving data takes time, which makes real-time analytics impossible.
+ **Data security:** Copying sensitive data creates security risks and may violate certain regulations.
+ **Cost:** Data replication creates demand for storage and compute power, which costs money.
Innovative SaaS companies overcome these problems with federated querying, which allows them to access data in real-time with [zero-copy](/blog/zero-etl-vs-modern-data-stack/).
## **3. Overlooking multitenancy and access controls**
A SaaS platform’s success can also become its bane if its infrastructure fails to scale as needed. This happens when teams try to add multitenancy to an analytics layer that was initially configured to handle a single-tenant model. As a result, it becomes a nightmare to
+ Manage access permissions,
+ Mitigate data exposure to unauthorized users,
+ Streamline the conditional logic across dashboards.
Multitenancy should not be treated as an afterthought; it must be integrated into an analytics platform to provide a personalized analytics experience for each user.
## **4. Ignoring the frontend experience**
Technical teams can become occupied by backend tasks and ignore the user experience offered by platforms. However, considering that it will be mostly business teams using the embedded customer-facing analytics, an easy-to-use, intuitive UI is just as important as a platform’s technical capabilities.
For an embedded SaaS analytics experience, teams must build
+ Connector dialogs and data browsers,
+ SQL editors with autocomplete,
+ Customizable themes.
Building all these adds weeks, if not months, to a product team’s roadmap, forcing them to make difficult decisions.
## **5. Delaying OAuth and compliance planning**
Certain tasks critical for data security, such as OAuth flows, access tokens, and audit logging, are only addressed at the end of the development cycle, which makes them blockers during that final stage. But a sloppy job in those areas will lead to
+ Possible data breaches,
+ A risk to reputation, loss of business opportunities, and potential legal responsibility,
+ Delays in roadmap targets.
SaaS companies need to either develop these security features in-house by allocating more resources or deploy embedded analytics tools that come equipped with them.
## **6. Trying to reinvent the wheel**
One of the most serious mistakes teams make while building embedded analytics capability is trying to build the whole data delivery stack in-house. Instead of incorporating what embedded platforms already offer, engineers spend months developing
+ Connector infrastructure,
+ Caching and rate-limit handling,
+ Federated SQL query engine,
+ Customizable embedded UI components.
All of these items are doable, but offering customer-facing analytics shouldn’t come at the cost of stalled product development in core areas.
## **How does Embedded Peaka help minimize these mistakes?**
Being a full-stack, white-labeled data integration and delivery platform, Embedded Peaka is purpose-built to tackle the pitfalls listed above, as it
**Simplifies technical complexity:** With no connectors to build, no data warehouse to manage, and no frontend UI to develop, Peaka significantly simplifies the complexity that product teams face.
**Eliminates data replication:** Peaka uses data virtualization to unify data without the need to copy and move data to a central repository. It leverages caching on Iceberg to offer an optimal blend of speed and cost and ensures that product teams can deliver customer-facing analytics in real-time, without incurring high costs and compromising data security.
**Provides built-in multitenant access control:** Product teams typically spend months developing multitenant access controls. These controls are already built into Embedded Peaka with its project-catalog-schema hierarchy and granular access controls. As a result, each user (tenant) can access customized analytics dashboards securely and keep their data isolated from unauthorized access.
**Fasttracks frontend development:** An intuitive UI is an integral part of the embedded analytics experience. However, developing connector dialogs, SQL editors, and customizable theming severely brings down product velocity. Peaka’s embeddable UI with full white-labeling and branding support gives SaaS product teams a head start in creating a branded analytics experience without building a frontend from scratch.
**Ensures data security and regulatory compliance:** Developing scalable OAuth flows, audit logging, and lineage tracking can slow down integrations and feature delivery, leading product teams to overlook them until they no longer can. Peaka’s audit logging and lineage tracking provide the visibility necessary for regulatory compliance while giving teams the option to choose from a bring-your-own keys or Peaka-managed OAuth model.
**Offers a complete data management solution:** In addition to serving as a data management backend, Peaka can be used as a complete data management solution that includes an embeddable UI, giving product teams exactly what they need to accelerate product development like no other product in the market can.
## **Conclusion**
Offering in-product analytics requires going beyond data integration and embracing a new approach that treats data as a product. Teams that can make this transition successfully can implement embedded SaaS product analytics and create a smooth user experience with built-in scalability and governance.
Are you tired of dealing with backend complexity? Do you lack the resources to develop frontend features from scratch? It might be time to look at a purpose-built solution like Embedded Peaka. Let Embedded Peaka simplify the technical complexity for customer-facing analytics while you focus on growing your business.
[Schedule a demo](https://calendly.com/peaka/demo) and see how easy it is to embed BI into your SaaS product.
Make sure to check out our blog post for step-by-step instructions on [how to build a churn analysis dashboard in one hour](/guides/how-to-build-churn-dashboard).
--- START: blog/top-saas-revenue-metrics/top-saas-revenue-metrics.md ---
# **Top 6 SaaS Revenue Metrics to Track in 2026**
SaaS, also known as on-demand software, is a cloud-based software delivery model wherein remotely-hosted software is distributed to users over the internet on a subscription basis. In return for a monthly or annual fee, the users receive a copy of the software, which they access after a sign-in process via a web browser or an app. Updates and bug fixes to the software are delivered to each user every time they are released.
You may have noticed that software no longer comes in boxes and CDs, and we don’t see software updates being announced with elaborate fanfare anymore. We owe this to the SaaS model. Although its origins can be traced back to the 1960s, it was Marc Benioff of Salesforce who popularized the SaaS concept with his “[_The End of Software_](https://partnertap.com/marc-benioffs-vision-cloud-based-service/)” campaign in 2000. Benioff’s one-man crusade against conventional software received a boost from the rising cloud computing and triggered a chain reaction that eventually gave us Infrastructure-as-a-Service.
Before we take a deep dive into SaaS revenue metrics, check out this video by Dan Martell for a brief introduction into the SaaS concept.
{{ youtube(id="9nMT-1kmByw") }}
## **Key takeaways**
- You need to track the right [SaaS revenue metrics](/blog/saas-business-metrics/) for your business to make sure you are on the right path.
- Nuanced metrics like expansion MRR or churned ARR offer actionable insights as opposed to blanket metrics like MRR or ARR.
- You can use NRR to judge whether you have found traction and metrics like ARPU and CLV to spot high-value customers.
- SaaS revenue data should be blended with customer data and put into a context for users to be able to make sense of it.
- A dedicated connector that integrates a CRM like HubSpot and a payment processing platform like Stripe offers users immense value.
## **SaaS revenue statistics**
- According to Gartner, [global end-user spending on SaaS tools](https://www.gartner.com/en/newsroom/press-releases/2022-10-31-gartner-forecasts-worldwide-public-cloud-end-user-spending-to-reach-nearly-600-billion-in-2023) grew from $146 billion in 2021 to $167 billion in 2022. The renowned consulting firm forecasts the industry to grow by 16.8 percent in 2023, reaching $195 billion.
- According to Statista, [the average number of SaaS applications](https://www.statista.com/statistics/1233538/average-number-saas-apps-yearly/) used by organizations worldwide rose from 8 in 2015 to 110 in 2021.
{{ resize_image(path="../static/assets/images/blog-images/saas-revenue-metrics-us-g-trends.png", width=759, height=400, op='fit_width', alt="Google searches for 'saas'") }}
Graph showing the increase in the U.S.-based Google searches for the term "saas" from the beginning of the pandemic in March 2021 to May 2023.
Image credits: [Google Trends](https://trends.google.com.tr/trends/explore?date=2020-03-01%202023-05-05&geo=US&q=saas&hl=en). The image was slightly modified for aesthetic purposes.
- A study conducted by Better Cloud revealed that organizations with more than 1,000 employees use a whopping [177 SaaS tools on average.](https://pages.bettercloud.com/rs/719-KZY-706/images/2020_StateofSaaSOpsReport.pdf)
- As of January 2023, there were [337 SaaS unicorns](https://explodingtopics.com/blog/number-of-saas-companies), that is, companies valued at over $1 billion, and 15 decacorns, companies with a valuation of over $10 billion.
## **What makes the SaaS model so attractive to users?**
- The SaaS model made enterprise-grade software accessible to the masses by spreading the cost of infrastructure over a user base that’s orders of magnitude bigger. This development allowed people to use state-of-the-art software, which they would otherwise not be able to afford.
- The model popularized usage-based pricing, letting users pick from among the options the best pricing plan for their needs.
- Firmly based on data about user practices, the SaaS model was able to develop and offer the products customers asked for. [Regular feature delivery, security updates, and customization options](https://www.techtarget.com/searchcloudcomputing/definition/Software-as-a-Service) led to an overall better user experience.
[SaaS products](/blog/why-use-saas-analytics-tools/), through brands like Salesforce, Netflix, Dropbox, or Google Workspace, have become a significant part of our daily lives. They have boosted online collaboration, helped us achieve major productivity gains, and democratized access to quality software, becoming the dominant form of software distribution today.
## **What are SaaS metrics?**
SaaS metrics are [data points](https://builtin.com/saas-metrics#) that SaaS companies use to gauge their performance and growth. Although growth metrics are the first to come to mind because SaaS businesses are mostly evaluated on how quickly they can grow, there are other kinds of SaaS metrics companies should monitor.
Think of SaaS metrics as the instrument panel a pilot uses to fly a plane. The gauges in the panel provide the pilot with vital information that would otherwise not be available to him through the senses. Much like that, SaaS metrics give decision-makers visibility into the trends and subtle changes in the performance of a SaaS company.
It is thanks to following these SaaS metrics that a company can [identify actionable KPIs](/blog/saas-growth-metrics/) and make changes to the business plan. Metrics show you the trends you should care about and highlight problem areas.
For example, keeping an eye on the usage rates of individual users may let you notice in advance the users that are about to churn. The conversion rate gives you insight into how well your marketing efforts resonate with potential customers. Some metrics allow you to discover your most valuable users so that you can devise customer loyalty plans to keep them happy. Others, like the customer engagement score or the net promoter score, can tell you a lot about how satisfied customers are with your product.
See this video by David Skok, investor and renowned SaaS guru, for a discussion of SaaS metrics and why they matter for a SaaS business:
{{ youtube(id="5RR6M_d6eKc") }}
## **6 key SaaS revenue metrics to track**
### **1 - Monthly Recurring Revenue (MRR)**
MRR is defined as a normalized metric indicating [how much a business can expect to earn](https://www.saasacademy.com/blog/what-is-mrr) in a month on a regular basis. It is an indispensable metric for companies employing a subscription-based business model.
#### **How is MRR calculated?**
MRR is the product of the Average Revenue Per User (ARPU) figure multiplied by the total number of subscribers.
**MRR = Average Revenue Per User (ARPU) X Total Number of Subscribers
**
If your customer base consists of subscribers on annual contracts in addition to customers on a monthly plan, make sure that you calculate the average monthly revenue you earn from annual subscriptions.
Let’s say you have 20 monthly subscribers on a monthly fee of $40 and 5 customers paying you an annual fee of $360 per year. Your MRR is $950.
MRR = (20 X 40) + (5 X 360/12) = 800 + 150 = $950
#### **Types of MRR**
MRR is a blanket metric that needs to be broken down into lower—level metrics used for more precise analysis.
**New MRR:** The monthly revenue you can expect to collect from new customers who subscribed to your product or service.
**Expansion MRR:** The additional monthly recurring income generated by upselling or cross-selling to existing customers.
**Churned MRR:** The fall in the monthly recurring revenue resulting from customers who canceled their subscriptions.
**Contraction MRR:** The loss of monthly recurring revenue due to customers switching to a pricing plan that is priced lower than the existing one.
**Net New MRR:** The change in your monthly revenue compared to the previous month.
**Net New MRR = New MRR + Expansion MRR - Churned MRR
**
#### **Why does MRR matter?**
MRR allows you to identify trends in your subscription revenue and churn. The monthly revenue that you can realistically expect to earn in the future has a profound impact on your [growth predictions, hiring decisions, and the funding you will need](https://blog.hubspot.com/sales/monthly-recurring-revenue) to support your operations. Investors, too, rely on MRR to assess how fast a business is growing and its future potential.
### **2 - Annual Recurring Revenue (ARR)**
[ARR](https://www.saasacademy.com/blog/arr-vs-mrr-how-to-calculate) is the total amount of recurring revenue a business earns from its subscribers normalized for a year. As opposed to MRR, which brings to light the operational efficiency of a business, ARR highlights its long-term viability.
#### **How is ARR calculated?**
In general terms, ARR is equal to MRR multiplied by 12.
**ARR = MRR X 12
**
There is a caveat, though. When you have customers on multi-year contracts, you have to normalize the value of those contracts by dividing them by the number of years.
Suppose you have 12 subscribers on one-year contracts worth $1,000, 10 subscribers on 2-year contracts worth $1,800, and 5 subscribers on 3-year contracts worth $2,400, which means you have an ARR of $25,000.
ARR = (12 X 1,000) + (10 X 1,800/2) + (5 X 2,400/3) = $25,000
#### **Types of ARR**
Just like MRR, ARR, too, is a blanket metric that needs to be broken down into lower—level metrics used for more precise analysis.
**New ARR:** The annual revenue a business can expect to collect from brand-new customers.
**Expansion ARR:** The increase in the annual recurring income generated by upselling or cross-selling to existing customers.
**Churned ARR:** The reduction in the annual recurring revenue caused by cancellations.
**Contraction ARR:** The loss of annual recurring revenue due to customers switching to a pricing plan priced lower than the existing one.
**Net New ARR:** The change in the annual revenue compared to the previous year.
**Net New ARR = New ARR + Expansion ARR - Churned ARR
**
#### **Why does the ARR matter?**
ARR is a reliable indicator of a SaaS business’ health. It’s the main metric investors take into account while gauging the potential of a startup. A consistently growing ARR in the typical “hockey stick curve” fashion tells investors that the business in question has validated its business model and found the product-market fit.
Some investors would like to see startups hit certain growth targets to justify an investment, like Neeraj Agrawal of Battery Ventures, who thinks successful SaaS startups should grow [72X growth in ARR](https://techcrunch.com/2015/02/01/the-saas-travel-adventure) in 5 years (3X-3X-2X-2X-2X).
### **3 - Average Revenue Per User (ARPU)**
ARPU refers to the earnings a business generates per user. It is a key metric used to gauge the profitability of SaaS companies.
#### **How is ARPU calculated?**
To calculate the ARPU, you should first [determine the timeframe](https://saasinsights.io/article/what-is-arpu-average-revenue-per-user) of analysis. This could be monthly, quarterly, or yearly, depending on the business model. Having calculated your total revenue in that period, you should then divide it by the total number of users to find your ARPU.
**ARPU = (Total revenue over a specific period) / (Total number of users in that period)
**
#### **Why does ARPU matter?**
ARPU is a function of the industry you are operating in and, in turn, determines [how you acquire customers and sell products.](https://www.youtube.com/watch?v=Svk_Jpqhuxc) ARPU also speaks volumes about the spending habits of your customers.
Recent studies reveal that ARPU growth accelerates as ARPU per month increases. Customers with higher ARPUs tend to be more loyal and less likely to churn. They are power users that make products a bigger part of their lives. Companies enjoying higher ARPUs can expect to have higher expansion revenue as they can talk their customers into spending more for the product through upselling and cross-selling.
### **4 - Net Revenue Retention (NRR)**
[Net Revenue (Dollar) Retention](https://www.chargebee.com/resources/glossaries/what-is-net-dollar-retention/) refers to the percentage of the recurring revenue a business can retain over a period. It is the sign of a company’s capability to keep its customer base and build upon it through expansion. The term successfully captures the compounding effect that successful SaaS companies are known for.
#### **How is NRR calculated?**
To calculate NRR, you take your starting MRR and add to it the recurring revenue you generated by upselling and cross-selling to the same customer base (expansion MRR). You then subtract from that figure the lost revenue caused by customers switching to lower-level plans and the churned MRR from the cancellations. You then divide this figure by the starting MRR number and multiply it by 100.
**NRR = [(Starting MRR + Expansion MRR — Contraction MRR — Churned MRR) / Starting MRR] X 100
**
#### **Why does NRR matter?**
Positive NRR proves that you do not have a leaky bucket and that you add to your revenue faster than your customers cancel or downgrade their subscriptions. That’s why SaaS companies with high NRRs tend to receive much higher valuations than the ones with low NRRs.
NRR can be seen as the '[north star metric](https://www.forbes.com/sites/forbesbusinesscouncil/2022/04/15/why-nrr-net-revenue-retention-is-the-one-metric-to-rule-them-all-for-saas/)' for SaaS businesses because it gives you the bottom line of all your activities. Rather than maniacally marketing your product to potential customers, this metric emphasizes the need to keep existing customers happy. NRR is probably the metric that Airbnb CEO Brian Chesky had in mind when he [said](https://www.businessinsider.com/the-best-advice-airbnb-ceo-brian-chesky-ever-received-2013-1), “_Build something 100 people love, not something 1 million people kind of like._” NRR highlights the fact that SaaS startups should take customer success seriously.
### **5 - Customer Lifetime Value (CLV or CLTV)**
CLV refers to the total revenue a business can accrue from a customer over the course of the business relationship. CLV sheds light on the customer profile that can be expected to generate the most revenue for a company.
#### **How is CLV calculated?**
Calculating CLV can be tricky as it requires forecasting future earnings from a customer, which is impossible to know for sure. However, modeling CLV as the product of the **customer value** multiplied by the **average customer lifespan** would be a good estimate. ARPU gives us the customer value we need for this formula. Dividing 1 by the customer churn rate, we can approximate the number of transactions a customer will complete before churning. So the CLV formula is:
**CLV = (Average Revenue Per User) / (Customer Churn Rate)
**
#### **Why does CLV matter?**
Calculating the CLV allows a company to identify its most valuable customers. It can guide the efforts to create more effective marketing and sales campaigns and leverage less expensive channels to reach out to customers with a higher acquisition cost than lifetime value.
One of the more sensible ways decision-makers willing to cut costs can take is to invest in the relationship with existing high-value customers. Nurturing this relationship through [customer success and loyalty programs](https://blog.hubspot.com/service/how-to-calculate-customer-lifetime-value#what-is-clv) helps boost expansion revenue. Looking at the product range through a CLV perspective can result in products or services that don’t generate enough value getting phased out. Low CLV can indicate problems with certain business operations, and remedying these can generate more revenue for a company.
### **6- Monthly Churn Rate**
The monthly churn rate is the percentage of customers a business loses in a given month. It is a metric that’s indicative of how well a product resonates with customers. A high monthly churn rate implies that the business is a long way from the product-market fit and has urgent problems it has to deal with.
#### **How is monthly churn rate calculated?**
To calculate the monthly churn rate, you should first calculate the difference between the number of customers at the beginning and end of the month. Dividing this number by the number of customers at the beginning of the month and then multiplying the quotient by 100 gives you the percentage of customers you lost in a given month.
**Monthly Churn Rate = [(Number of customers at the beginning of the month) - (Number of customers at the beginning of the month)] X 100 / (Number of customers at the beginning of the month)
**
#### **Why does monthly churn rate matter?**
A high monthly churn rate undermines your growth and signals that something is seriously wrong with your product, onboarding process, or customer support. Left unattended, the compounding effects kick in and can have a devastating impact on the business over the long haul.
However, focusing solely on customer churn in a month can be misleading as a small number of high-value accounts churning may be more destructive for your business than a large number of low-value customers canceling their plans. Therefore, **monthly revenue churn** might be a better indicator of performance compared to the plain **monthly customer churn.**
## **Why should you measure SaaS revenue metrics?**
- To get a sense of the health of your business (MRR, ARR, NRR)
- To be able to forecast your future income and plan ahead (CLV)
- To make realistic projections about the length of your runway (MRR, ARR, NRR)
- To document the growth of your business when pitching investors (NRR, ARR, ARPU)
- To plan your future strategies to engage which customers and how (LTV)
- To understand how your funnel performs and which stage needs improvement (ARPU, CLV)
- To identify and keep an eye on your high-value customers and their spending (ARPU, CLV)
- To discover the people among your customers who can become evangelists for your product (ARPU, CLV)
## **Challenges associated with SaaS revenue metrics**
- The first challenge is a technical one. It involves pulling in data from a payment processing platform and blending it with the customer data stored in a CRM platform. Without proper connectors in place, this is a job that needs to be done manually, most of the time using spreadsheets. Seamless and real-time integration between two platforms can save frontline workers a lot of time and effort while unlocking insights for decision-makers.
- Once the technical challenge is overcome through a data integration tool, then the consolidated data needs to be presented in a way that makes it easy to understand for marketing and sales teams and decision-makers. Trends might be difficult to discover when data is presented in tabular form, but seeing your monthly churn rate shooting through the roof in a graph can serve as a wake-up call for you and your team. That’s why dashboards are necessary for people dealing with B2B SaaS analytics.
- The last challenge involves what to make of metrics. A metric like MRR is just a number. It needs to be considered in relation to other data to inform decisions. This requires making the data from one source talk with data from other sources. MRR on its own may tell you whether your business is doing well or not, but it does not reveal much about the underlying reasons.
Filtering the MRR by pricing-plan changes your perspective a little, offering you a glimpse into your ideal customer profile. But to gain insights that you can act upon, you need to break down the MRR (or LTV, churn, or any other metric) into country- and company-based segments. It is only at this level that numbers can help you form hypotheses that you can test with your actions.
## **Benefits of integrating key SaaS revenue metrics with your CRM data**
Blending SaaS revenue and CRM data maximizes the potential of SaaS data, providing valuable insights for businesses to make informed decisions. Here's what you may expect to gain from this integration:
### **A chance to contextualize bare revenue metrics for better understanding**
- Raw SaaS revenue data only provides information on revenue trends without any actionable insights. MRR, ARPU, and monthly churn charts reveal trends, but they do not tell you what you should do to maintain or reverse them.
- Combining SaaS revenue and CRM data provides users with context, allowing for a breakdown of revenue metrics such as MRR, ARPU, and monthly churn into country- and company-based components.
### **Actionable insights to inform future decisions**
- Importing customer data from CRM platforms adds depth to raw SaaS revenue data, which enables users to see the impact specific customer attributes like country, industry, and company size have on revenue data.
- Armed with new insights, marketing and sales teams can form ideal customer profiles, target high-value accounts, and explore cross-selling and upselling opportunities.
## **4 tools for tracking key SaaS revenue metrics**
The rise of the SaaS business brought about an increase in the number of tools that bring together SaaS data and help users visualize that data in a dashboard. Here are four popular tools that are worth a look:
### **Peaka**
Developed with a vision to help startups and SMBs eliminate data silos, Peaka has an easy-to-use offering for people looking to bring revenue and customer data together. Of the [plethora of integrations](/integrations/) Peaka comes with, the dedicated HubSpot-Stripe connector holds great promise for startups and SMBs. Thanks to this connector, users can pull in payment data from Stripe and join it with the customer data they keep in HubSpot.
Most data integration tools can provide users with an MRR, ARPU, or LTV figure based on the pricing plan chosen-that's nothing new. Peaka goes one step further, though, and allows for further segmentation of this data according to country, company size, industry, or funding information, giving users a more granular view of their data. As a result, a Peaka user can, for example, generate reports showing the MRR from her customers based in Germany with a staff size between 10 and 100.
Our [HubSpot-Stripe](/blog/integrations-hubspot-stripe/) integration unlocks invaluable insights for both frontline workers and decision-makers. Marketing and sales professionals can use these insights to form ideal customer profiles. They can target high-value accounts and develop personalized messaging for accounts that drive most of the revenue for the company. The insights gained from HubSpot-Stripe integration enable high-level decision-makers to adjust resource allocation and achieve better ROI from marketing dollars.
### **ChartMogul**
ChartMogul offers integrations with platforms like Stripe, Securely, Chargeable, and PayPal. It allows users to consolidate their revenue data and [apply filters](https://youtu.be/Svk_Jpqhuxc?t=1760) like churn or MRR by currency, region, plan, or cohort. However, when it comes to achieving a more granular segmentation like MRR-by-region-by-pricing plan, ChartMogul comes up short.
ChartMogul offers a Pipedrive integration via Zapier, which lets users pull in customer data. But the lack of a HubSpot integration seems like a glaring problem for many users. Instead of focusing on integrations with major CRM platforms, ChartMogul seems to be charting a new course nowadays.
{{ resize_image(path="../static/assets/images/blog-images/saas-revenue-metrics-chartmogul.png", width=759, height=400, op='fit_width, alt="ChartMogul screenshot") }}
A ChartMogul screen showing the breakdown of customer lifetime value data by pricing plan.
Image credits: [Youtube Video](https://youtu.be/Svk_Jpqhuxc?t=2111).
The company recently launched the [ChartMogul CRM.](https://www.youtube.com/watch?v=wgLIeVo0MNw) Instead of enabling users to pull in data from their existing CRM platforms, ChartMogul wants to become _the_ CRM platform customers store that kind of data in. Users will keep their customer data on ChartMogul CRM and merge it with revenue data from Stripe to form detailed reports. Whether this bold move will be enough to sway people away from established CRMs like HubSpot or Salesforce remains to be seen.
### **ProfitWell**
Another popular analytics software for B2B SaaS data is ProfitWell. ProfitWell provides its users with integrations with payment processing platforms like Stripe, Chargeable, and Zuora. Users can pull in the revenue data from one of these platforms and break down the data into components like MRR, growth rate, churn rate, LTV, and ARPU and filter them by pricing plan, industry, or region. The tool also comes with one of the more capable dashboards in the market and lets users turn data into slick charts and graphs.
{{ resize_image(path="../static/assets/images/blog-images/saas-revenue-metrics-profitwell.png", width=759, height=400, op='fit_width, alt="ProfitWell screenshot") }}
| A screenshot from the ProfitWell demo dashboard showing the breakdown of customer lifetime value data by pricing plan.
Image credits: [ProfitWell](https://demo.profitwell.com/app/segmentation/comparison?comparison_category=_company_plans&comparison_segments=%5B%22basic_monthly%22%2C%22basic_yearly%22%2C%22pro_monthly%22%2C%22pro_yearly%22%5D&comparison_metrics=%5B%22lifetime_value%22%5D).|
On the customer data front, ProfitWell works with Clearbit and Fullcontact to enrich the existing data with contact information and form ideal customer profiles. It also has a dedicated HubSpot connector that combines revenue and CRM data. This connector offers automated workflows that are triggered depending on parameters such as customer engagement or plan status and seems to have received mostly positive reviews from users.
### **Baremetrics**
Baremetrics is another viable option for people looking for a B2B SaaS analytics tool. It allows users to track usual metrics like MRR, LTV, churn, or reactivations and see how these metrics change according to the pricing plan selected by customers. Similar to ProfitWell, Baremetrics offers a colorful dashboard that turns metrics into beautiful visualizations.
{{ resize_image(path="../static/assets/images/blog-images/saas-revenue-metrics-baremetrics.png", width=759, height=400, op='fit_width', alt="Baremetrics screenshot") }}
A screenshot from the Baremetrics demo dashboard showing the breakdown of customer lifetime value data by pricing plan.
Image credits: [Baremetrics](https://demo.baremetrics.com/stats/ltv).
With Baremetrics, users willing to take a more detailed look at their revenue metrics and merge them with customer data can import data from certain CRM platforms like Pipedrive. After pulling in the CRM data as attributes, they can blend it with the existing revenue information to view how revenue MRR, LTV, or churn changes in relation to region or industry. This capability helps decision-makers put things into context while evaluating the performance of sales teams or the effectiveness of marketing campaigns. However, the platform currently lacks a HubSpot connector, which undermines its appeal to a large user base used to working with it.
## **SaaS revenue metrics content to consume**
- Video – [SaaS Metrics and Benchmarks — Based on Thousands of SaaS Businesses](https://www.youtube.com/watch?v=Svk_Jpqhuxc)
- Article – [What is SaaS?](https://www.investopedia.com/terms/s/software-as-a-service-saas.asp)
- Article – [What are SaaS Metrics?](https://blog.hubspot.com/service/saas-metrics)
- Report – [ChartMogul 2023 SaaS Benchmarks](https://chartmogul.com/resources/saas-benchmarks-report.pdf)
## **Conclusion**
SaaS is a game of compounding— compounding your customer base and your revenue. To win in this game, it's essential to maintain a comprehensive understanding of your business, and that means closely monitoring your revenue metrics.
But first things first, you need to start with gathering all your data in one place. Being data-driven won't work if you have scattered information. Real-time data integration that consolidates customer and revenue data, while also allowing for country- and company-based customer segmentation, can provide a fantastic competitive edge for SaaS companies. In that regard, data integration and business analytics tools hold the key to the future for SaaS businesses.
--- START: blog/top-saas-sales-kpis/top-saas-sales-kpis.md ---
# **Top SaaS KPIs Sales Teams Should Track in 2026**
2002 was a difficult year for B2C SaaS. Things went back to normal after the boom the sector enjoyed during the pandemic as the work no longer had the appetite it had for software during the pandemic. The macroeconomic changes (interest hikes and looming recession) in the U.S. brought about a change in the VC attitude toward SaaS. The “growth at all costs” mantra of the last decade was replaced by an emphasis on profitability.
With investor funds seemingly drying up, SaaS companies were forced to turn to SMB and enterprise markets where profit margins were higher. This pivot also meant a more sales-driven business model. Instead of chasing millions of customers who would make small monthly payments, more and more SaaS companies came to rely on sales teams who knew how to make a pitch and wine-and-dine executives to win 6- and 7-figure contracts.
That’s why SaaS sales KPIs are more important today than ever before, especially for companies willing to tailor their sales efforts to the needs of select customers. This blog post will take a long hard look at SaaS sales KPIs and why they matter.
## **What are SaaS sales KPIs?**
[SaaS sales KPIs](https://www.chargebee.com/blog/saas-kpis/#Sales-KPIs-for-SaaS-Companies) are the metrics SaaS companies use to assess sales performance. They reveal how the actual sales performance of a SaaS company compares to predetermined goals, highlight problem areas, and provide insights about how the sales funnel can be optimized.
Check out this video by [David Marincic](https://www.linkedin.com/in/david-marincic/) for a quick intro into SaaS sales KPIs:
{{ youtube(id="ty_Xszi5FiU") }}
## **Key takeaways**
- Sales KPIs have become more prominent in the SaaS sector as a result of the emergence of account-based marketing practices that blend sales tactics with [advanced data analytics](/blog/b2b-saas-analytics-tools/).
- SaaS sales KPIs help align different units around measurable goals and optimize the sales funnel, bringing accountability into the sales effort.
- Sales KPIs are strategic-level, company-specific figures, whereas sales metrics are more tactical in nature and regarded as industry standards.
## **SaaS in numbers**
- The SaaS market has reached [$171.9 billion](https://thesmallbusinessblog.net/saas-companies/) by the end of 2022.
- A study by Gartner found out that the [global end-user spending on SaaS tools](https://www.gartner.com/en/newsroom/press-releases/2022-10-31-gartner-forecasts-worldwide-public-cloud-end-user-spending-to-reach-nearly-600-billion-in-2023) grew from $146 billion in 2021 to $167 billion in 2022 and forecast that it to grow by 16.8 percent in 2023, reaching $195 billion.
{{ resize_image(path="../static/assets/images/blog-images/saas-sales-kpis-sales-analytics-us-g-trends.png", width=759, height=400, op='fit_width', alt="Google searches for 'sales analytics'") }}
| Graph showing the increase in the U.S.-based Google searches for the term "sales analytics" in the last five years.
Image credits: [Google Trends](https://trends.google.com.tr/trends/explore?date=2020-03-01%202023-05-05&geo=US&q=saas&hl=en). The image was slightly modified for aesthetic purposes.|
- The average SaaS sales cycle lasts [84 days](https://blog.hubspot.com/sales/saas-sales-ultimate-guide) and can go up to 170 days for deals with an annual contract value of more than $100,000.
- While 2 percent of sales happen at the first meeting, [63 percent](https://www.lairedigital.com/blog/effective-sales-enablement-for-enterprise-saas-sales-teams) of the people inquiring about a product will not make a purchase for at least three months, and 20 percent will take more than 12 months to buy.
## **4 main methods of selling**
Before immersing ourselves in the details of SaaS sales KPIs, we should take a brief look at the four main types of sales methods and what they entail:
### **1- Transactional selling**
Transactional selling refers to the traditional sales method where a salesperson hunts for prospects, develops a relationship with them, makes a pitch, and eventually closes the deal. It is based on temporary relationships with customers where the salesperson promotes the product, emphasizes its features, and how it will benefit the customer. The traditional [4 P’s of marketing (product, pricing, placement, and promotion)](https://www.techtarget.com/searchcustomerexperience/tip/Key-differences-between-transactional-and-relationship-marketing) play a big role in transactional selling. Competing on product features and price, pursuing an omnichannel strategy, and running promotional campaigns are part and parcel of this technique.
With the product almost selling itself, this approach is predominantly used in industries like retail, automotive, and real estate, where sales cycles are relatively short and purchases are one-off. For most other industries, though, transactional selling is not particularly suitable because it is impersonal in nature. Using [mass marketing](https://www.techtarget.com/searchcustomerexperience/tip/Key-differences-between-transactional-and-relationship-marketing) may help lower the costs, but it also makes it impossible to address the needs of different customer groups. That’s why salespeople implementing this method fail to build long-term relationships with customers to maximize lifetime value.
### **2 - Solution selling**
This second technique requires more personal touch from the salesperson compared to the transactional approach. In solution selling, the salesperson invests in his relationship with the customer and nurtures it to gain a deep understanding of the [customer’s needs and pain points](https://www.salesforce.com/resources/articles/what-is-solution-selling). This understanding will help him offer a solution tailored to the customer’s needs, giving him an advantage over competitors.
Solution selling involves products that tend to be complex and heavily customized rather than off-the-shelf stuff. Like in construction projects or bespoke software development, identifying the requirements and developing a solution that will create a long-term impact takes a lot of time and effort. Due to the longer sales cycle, the costs involved are higher. Therefore, solution selling makes sense only when the account in question is valuable enough to justify the extra costs.
### **3 - Consultative selling**
Consultative selling resembles solution selling in that both require building a relationship with the customer. However, in consultative selling, the salesperson must have a lot of experience and product expertise. This expertise is the foundation of a relationship where the customer will turn to the salesperson for ideas whenever she is searching for a solution to a problem.
This strong bond with the customer enables the salesperson to ask the right questions, dive really deep into the pains she has, and offer the right solution. This technique aims to sell without making a pitch. The [four important aspects](https://blog.eonetwork.org/2022/12/the-4-main-types-of-selling-and-when-to-use-them/) of consultative selling are:
- Being a good listener
- Asking the right questions
- Being a trustworthy, objective source of knowledge
- Offering solutions, not products or features
Consultative selling envisions the salesperson as a companion to the customer and ensures that the salesperson will be top of mind when the customer is ready to make a purchase.
### **4 - Provocative selling**
This technique is for times of drastic change where creativity is needed to improve the prospects of a sale. Provocative selling involves a “[shock and awe](https://www.linkedin.com/pulse/mastering-four-major-types-selling-industry-hubinit/)” approach where you make your customers aware of problems they did not know existed. You aim to open their eyes to a critical need and create urgency so that they will start looking for a solution.
Times of great [macro-level changes](https://youtu.be/tx5__w_g2eA?t=135) like global warming, demographic change (the emergence of Gen Z), or political upheaval (Brexit) can create massive problems for prospective customers. You can use these situations to your advantage by talking to your contacts and telling them about what that change means for the industry, their organization, and their department. Provocative selling aims to instill a “why now” mentality in contacts and kickstart a search for a solution.
The Covid-19 pandemic and the way it transformed work-life provided a case in point for how provocative selling can make a difference for SaaS teams. Practitioners of this technique used lockdowns and workplace restrictions to their advantage and pitched their products as solutions to the new pains brought about by the pandemic. We might expect more salespeople to turn to provocative selling to gain prominence as global warming, the U.S.-China standoff, and mass migration disrupt existing business models and enforce change.
## **KPIs vs. Metrics**
Despite being used in similar contexts, KPIs and metrics refer to different concepts. In summary, “[_not every metric is a KPI, but every KPI is a metric._](https://databox.com/kpis-vs-metrics)”
KPIs and metrics differ on [four main points:](https://dashthis.com/blog/kpi-vs-metrics-all-you-need-to-know/)
- KPIs describe high-level strategic goals that tie different departments and teams together. Metrics, on the other hand, help break down these strategic goals into operative objectives.
- KPIs communicate the priorities of a business and determine how the lower level metrics should shape up for the attainment of a business goal. Metrics are about specific processes and they gauge the effectiveness of execution.
- Metrics reflect a benchmark or widely-acknowledged industry standard. KPIs, on the other hand, do not follow a standard form and vary according to the needs of individual organizations.
- While metrics are related to individual employees or teams, KPIs concern various units of different sizes.
## **Why do SaaS sales KPIs matter?**
The sales process in the SaaS sector is a long-winded one. It takes weeks and even months to close a deal. Where to start with a lead and how to proceed may be difficult to figure out for a sales rep at first. Any sales rep can feel disoriented and even lost without clear goals in place to inform actions.
Sales KPIs are these goals. They are not quotas or sales targets. They are figures that spell out what needs to be done for a business to perform to its full potential in terms of sales. Monitoring SaaS sales KPIs create three key benefits for an organization:
- SaaS sales KPIs chart a clear route to the end goal, which is to close a deal. Working backward from the last step in the sales funnel toward the first, sales KPIs lay out how many emails you have to send to generate enough marketing-qualified leads so that you can produce enough sales-qualified leads to close enough deals to meet your objectives. In a sense, sales KPIs help quantify the whole sales funnel from the perspective of a sales rep.
- From a management perspective, monitoring sales KPIs allow decision-makers to see how efficient the resource allocation is. Products selling better than expected can be scaled, and more sales reps can be hired to sell them. Those not meeting the expectations can be slowly phased out.
- Sales KPIs also help decision-makers evaluate the performance of individuals. People consistently hitting their KPIs should receive consideration for bigger accounts. More training might be needed for underperforming employees.
For a discussion of what SaaS companies stand to gain from tracking sales KPIs, see this podcast episode by the Stay Paid Podcast team:
{{ youtube(id="9VGVJZCJ_SQ") }}
## **8 widely-used sales KPIs you need to track**
The set of sales KPIs a company needs to track can vary depending on the industry it operates in, the business model it pursues, and the kind of challenges it needs to overcome. Here is a rundown of eight sales KPIs that are commonly tracked and what they are good for:
### **1 - Sales cycle length**
A sales cycle is the time it takes from the initial sales contact to the time a deal is closed. It is an important KPI that speaks volumes about the efficiency of your sales operations and the success of your sales reps. Longer sales cycles mean your team will be able to close fewer deals throughout the year, which will translate into less revenue.
#### **Why should you track sales cycle length?**
Sales cycle length is a fundamental figure for planning sales operations and forecasting revenue. Knowing this figure allows you to compare your sales performance with that of the competitors and your past performance.
#### **Who should track this KPI?**
Account managers and higher-level decision-makers responsible for driving growth would be wise to track the average sales cycle length.
### **2 - Number of deals in the pipeline**
The number of deals in the pipeline is a good indicator of sales rep activity and a predictor of sales revenue. This KPI can be broken down into the average number of deals in the pipeline and new deals added to the pipeline in a particular time frame
#### **Why should you track the number of deals in your pipeline?**
A low number of deals in the pipeline may be a sign of problems with lead generation. This might require a reconsideration of the marketing strategy, the targeted customer profile, the content used, and the performance of the channels leveraged.
#### **Who should track this KPI?**
The number of deals in the pipeline is a tactical KPI that sales reps should definitely monitor. A sustained drop in this figure is a serious cause for concern, and it may require the sales rep to take action by increasing the work rate or drawing attention to problems with lead generation.
### **3 - Pipeline value**
This KPI calculates the maximum amount of revenue you may expect to earn from the deals in your pipeline if everything goes according to the plan. It helps users gauge where their revenue ceiling is and guides forecasting initiatives.
#### **Why should you track pipeline value?**
Tracking this metric allows you to see how likely your sales reps are to hit their quotas. If the pipeline is full, but the overall value is low, your sales reps may be wasting their time on deals that are not worth the effort.
#### **Who should track this KPI?**
This is one of the strategic level KPIs directly concerning sales managers. But, sales reps, too, would benefit from keeping tabs on pipeline value as it shows where the sales efforts are headed and makes it possible to course-correct before it is too late.
### **4 - Number of sales opportunities created**
A [sales opportunity](https://blog.hubspot.com/sales/criteria-to-upgrade-a-lead-to-an-opportunity-and-theyre-not-what-you-think) is a qualified prospect who is highly likely to become a customer. Leads are converted into prospects, some of whom later become opportunities further down the funnel. Sales opportunities created refer to the number of these qualified prospects added to the pipeline in a given timeframe and indicate the total revenue a business can expect to generate.
#### **Why should you track the number of sales opportunities created?**
Sales opportunities created is a crucial mid-funnel KPI that tells us a whole lot about the upstream and downstream activities. A relatively low number raises questions about the target market segment and the effectiveness of the marketing tactics used. When there are plenty of sales opportunities created, but the ratio of deals won is low, then the onus is on the sales reps, who need to revisit their pitch.
#### **Who should track this KPI?**
Sales managers should keep an eye on this KPI to ensure that the sales reps are maintaining a desired level of activity and keeping the pipeline well-fed.
### **5 - Average deal size**
The average deal size tells you a lot about your product range and what resonates with your customers. Additionally, it also provides you with objective data to evaluate the performance of your sales reps.
#### **Why should you track the average deal size?**
Because channeling marketing and sales resources into more profitable products can help a company increase revenue without incurring extra costs. Everything being equal, a higher average deal size means higher profitability. Sales reps would be wise to focus on customers that can be expected to spend more.
#### **Who should track this KPI?**
Sales reps can use this KPI to make better use of their time. For higher-level decision-makers, average deal size helps identify the popular products and phase out the ones that are not generating enough returns for every sales and marketing dollar spent.
### **6- Lead-to-sale ratio**
This KPI reveals the [overall effectiveness of the pipeline](https://www.netsuite.com/portal/resource/articles/accounting/sales-kpis.shtml). It indicates how successful the company is in converting sales-qualified leads into prospects. Some of these prospects will become sales opportunities, some of whom will convert into paying customers.
#### **Why should you track the lead-to-sale ratio?**
This particular KPI helps users understand how efficient the whole sales effort is in generating desired results, that is, closing deals. A low lead-to-sale ratio can be indicative of the low quality of marketing-qualified leads handed over to the sales team or the channels used by the sales team while contacting prospects.
#### **Who should track this KPI?**
This KPI is one of the strategically important figures for sales managers. It helps them optimize the sales funnel and evaluate the performance of individual sales reps.
### **7 - Sales by contact method**
Digging into the prehistory of a deal and discovering which channel was responsible for successfully engaging the customer in the first place can provide decision-makers with powerful insights. Knowing whether it’s the phone calls, emails, or in-person visits giving you a head-start in your outreach efforts can improve your sales success.
#### **Why should you track sales by contact method?**
Monitoring this metric is important for optimizing resource allocation and keeping the customer acquisition cost in check. Prioritizing more effective channels at the expense of less successful ones maximizes the return on marketing and sales dollars.
#### **Who should track this KPI?**
Sales managers can look at this KPI and remove the low-performing channels from the funnel. Sales reps, too, can match this KPI with certain customer profiles and adjust their outreach strategy, improving their conversion rates as a result.
### **8 - Number of monthly demos booked**
The number of monthly demos booked is a good indicator of high-intent customers for SaaS companies. Usually, people who book demos are the ones that are aware of their pain points and looking for a solution.
#### **Why should you track the number of monthly demos booked?**
This KPI matters simply because people booking demos are more likely to become paying customers. Keeping an eye on this figure helps sales managers better forecast sales and plan accordingly.
#### **Who should track this KPI?**
Sales reps can use this KPI to analyze which customer profiles show more interest in demos. Focusing on these profiles can improve conversion rates and increase revenue. As stated above, sales managers also benefit from tracking this KPI for forecasting purposes.
## **How can Peaka help you with your sales campaigns?**
Salespeople are CRM addicts. The customer information they keep on CRM platforms is their biggest asset in building relationships with prospects and turning them into paying customers.
However, with the increase in the number of SaaS tools used by sales teams, bringing together the SaaS data has become a real challenge. Data locked in isolated silos is no good unless you can consolidate it to give you a holistic view of the market and the account you are focusing on. By helping you unify your SaaS data, Peaka provides you with three major benefits:
- Specifically, Peaka allows users to form highly-precise ideal customer profiles (ICPs) by joining and blending payment data with customer attributes from a CRM platform. It lets users see their MRR, ARPU, or LTV figures based on the pricing plan chosen and further breaks down this data into country-, industry-, or company-size-based components.
- Armed with a well-defined ICP, it becomes much easier to personalize the messaging and produce content that will appeal to your highest-value prospects. Peaka enables you to pursue an account-based marketing strategy and improve your return on the sales and marketing dollars spent.
- After combining your SaaS data, Peaka allows you to view the consolidated data with your favorite data visualization platform. Peaka’s dedicated connectors for popular business intelligence (BI) tools simplify this process so even non-technical employees can turn their tabular data into visualizations and draw insights.
Here are the BI tools Peaka offers ready-made connectors for:
**Metabase:** An open-source platform that connects to more than twenty different data sources, Metabase also offers different packages at different price points. Thanks to its Visual Query Builder and pre-made visualizations, the platform makes it easier for non-technical people to visualize their data.
Our blog post on [Peaka’s Metabase integration](/blog/data-visualization-with-metabase-integration/) explains how Peaka enables this user-friendly platform to retrieve and visualize data from any source.
**Apache Superset™:** Apache Superset™ is an open-source platform with technical capabilities that can satisfy the needs of enterprise customers. Supported by a large online community, the platform regularly gets updated with new features. Its customizability and scalability make it the ideal choice for technical teams with large datasets to visualize.
See this blog post on [Peaka’s Superset integration](/blog/data-visualization-with-superset-integration/) for a more detailed discussion of this platform.
**Power BI:** The go-to data visualization for users working within the Microsoft ecosystem, Power BI provides native integration with Teams, SharePoint, and Microsoft 365. Its versatility makes Power BI a versatile choice for large organizations, as both technical and non-technical teams can use the same platform to visualize data.
This blog post on [Peaka’s Power BI integration](/blog/data-visualization-with-power-bi-integration/) takes a deep dive into how Peaka allows Power BI to pull data from any source.
**Looker Studio:** As the standard BI tool of the Google ecosystem, Looker Studio supports hassle-free integration with Google Analytics, Google Ads, and BigQuery. Although it lacks the powerful features that some other BI tools offer, Looker Studio still appeals to a large user base thanks to its drag-and-drop interface and wide range of pre-made visualizations.
Check out our blog post on [Peaka’s Looker Studio integration](/blog/data-visualization-with-looker-studio-integration/), explaining how Peaka enables this tool to visualize data from any source.
**Tableau:** For users of Salesforce products, Tableau is the default BI tool for data visualization. The platform is known for the unmatched visual appeal and variety of its visualizations. Tableau natively integrates with other Salesforce apps and is a good fit for enterprise users who have access to capable technical teams that can unlock the full feature set of the platform.
As we explain in a blog post on [Peaka’s Tableau integration](/blog/data-visualization-with-tableau-integration/), Peaka ensures that this platform can connect to data sources outside the Salesforce ecosystem.
## **SaaS sales KPIs content to consume**
- Video – [5 Fundamental Sales KPIs you Need to Track| David Marincic](https://www.youtube.com/watch?v=ty_Xszi5FiU)
- Podcast – [Reach Your Goals with Sales KPIs | Stay Paid Podcast](https://www.youtube.com/watch?v=9VGVJZCJ_SQ)
- Podcast — [The State of Sales KPIs | The Modern Sales Leader Podcast](https://leveleleven.com/2016/03/the-state-of-sales-kpis-podcast/)
- Article – [Sales Performance| Mosaic](https://www.mosaic.tech/financial-metrics#sales-performance)
- Article – [21 Sales KPIs for Sales Teams to Track in 2023](https://www.netsuite.com/portal/resource/articles/accounting/sales-kpis.shtml)
- Article – [22 Sales KPIs Successful Sales Team Track in 2023](https://blog.close.com/sales-kpis-metrics/)
- Article – [32 SaaS KPIs Every Company Should Track2023](https://www.chargebee.com/blog/saas-kpis/#Sales-KPIs-for-SaaS-Companies)
## **Conclusion**
The SaaS pivot to SMBs and the enterprise segment has given a boost to account-based marketing. More and more companies are pursuing high-value accounts and trying to blend traditional sales methods with advanced data analytics. That’s why KPIs and metrics are a bigger part of the sales effort today.
Well-chosen KPIs can help align sales efforts, optimize resource allocation and improve the ROI of sales budget. They are indispensable if you are willing to introduce structure and accountability into your sales funnel.
--- START: blog/track-job-costs-servicetitan/track-job-costs-servicetitan.md ---
# **Track Job Costs in ServiceTitan without Spreadsheets**
“*How much did that job really cost us?*” If you’re running a growing HVAC, plumbing, or roofing business, this is a question you’re probably asking every week, and the reason you’re spending hours in spreadsheets trying to answer.
For many ServiceTitan users, the process of calculating job costs still involves exporting CSVs, manually cleaning data, and building custom formulas in Excel. It’s slow. It’s error-prone. And it’s holding your team back from scaling efficiently.
But there’s a better way.
## **Why job costing is a critical KPI**
Job costing is not only a financial metric but also the heartbeat of every profitable service business.
Knowing how much each job costs, in labor, materials, and overhead, helps you set profitable pricing and spot inefficiencies across technicians, services, or locations. A dependable job costing estimate is essential for calculating marketing ROI by job type or campaign and making smarter staffing and scheduling decisions.
When job costs aren’t visible in real time, you’re flying blind and lose the ability to course-correct. Access to accurate, real-time job costing data is essential for optimizing resource allocation and maximizing revenue.
## **Why ServiceTitan reporting falls short**
ServiceTitan is a powerful operational platform. But when it comes to reporting—especially job costing—it leaves a lot to be desired.
+ **Limited filters and customization:** Native reports don’t always break down costs in a way that reflects how your business actually operates.
+ **Data silos:** [Combining ServiceTitan and accounting data](/blog/integrate-servicetitan-with-quickbooks-xero-sage/) is not always straightforward, making it a challenge to join job data with cost details from QuickBooks or Sage Intacct.
+ **Manual exports:** To get the full picture of the operations, admins often download several CSVs and manually stitch the data together in an Excel table.
+ **Time sink:** Updating reports with fresh data requires hours every week, which could otherwise be used to improve processes or close new deals.
This manual reporting workflow might work for a $2 million company. But it won’t scale with a $20 million operation that manages teams distributed across [multiple locations](/blog/multi-location-servicetitan-reporting/).
## **What a better workflow looks like**
Imagine this instead:
You connect ServiceTitan (and your accounting tool) to a live data platform. Every job, every cost, every technician’s performance is tracked in real time. [No manual exports](/blog/servicetitan-manual-data-export-costs/), no formulas involved.
You connect your data to your BI tool of choice, like [Looker Studio](/blog/how-to-connect-servicetitan-to-looker-studio/), [Power BI](/blog/servicetitan-power-bi-integration/), or [Metabase](/blog/how-to-connect-servicetitan-to-metabase/). Your dashboards update automatically to show:
+ Job revenue vs job cost
+ Profit margin by service type or location
+ Technician profitability and efficiency metrics
+ Cost-per-job trends over time
The immediate benefit of such a setup is streamlined dashboard creation and report generation, which eliminates the need for Excel or a data team.
## **Real results: What contractors gain**
Companies that replace manual job costing workflows with [real-time dashboards](/blog/consultants-servicetitan-kpi-dashboards/) see measurable gains:
+ 10+ hours saved each week on reporting tasks
+ Fewer errors in financial tracking and performance reviews
+ Faster insights into what’s working (and what’s not)
+ Better strategic decisions about pricing, staffing, and growth investments
Without the need for constant manual data exports and endless spreadsheet work, ops and admin teams can focus on growing the business instead of wasting valuable time on repetitive tasks.
## **How Peaka makes it happen**
An official ServiceTitan partner, Peaka connects directly to ServiceTitan and your accounting tools, giving you a complete job costing picture without the usual engineering effort.
+ No-code connectors let you pull in job, invoice, and cost data from multiple systems.
+ The text-to-SQL capability allows even non-technical users to query and filter data without needing SQL.
+ Peaka sends consolidated data to BI tools via its ready-made connectors. This eliminates the need for manual dashboard updates, providing you with real-time figures at all times.
These capabilities make Peaka a perfect fit for the data needs of home service businesses. Peaka lowers the technical barriers for home service businesses, empowering non-technical users to build the dashboards they need without increasing headcount or the need for manual data replication.
## **Key takeaways**
+ **Manual job costing slows you down:** Exporting data from ServiceTitan into spreadsheets wastes time, introduces errors, and delays critical decisions.
+ **ServiceTitan’s native reports are limited:** Built-in reporting doesn’t offer the depth or flexibility needed to track profitability, technician efficiency, or cost breakdowns.
+ **Peaka automates job costing in real time:** With live dashboards that combine ServiceTitan and accounting data, Peaka delivers accurate, up-to-date insights without engineering help.
## **Stop copy-pasting, start scaling**
Home service businesses are caught between two extremes:
+ Complex, expensive data platforms built for enterprise teams and
+ Basic spreadsheets that are time-consuming and error-prone.
Peaka fills this gap perfectly, giving these companies a cost-effective option to manage their data. It delivers the power of real-time reporting and unified dashboards without the need for a data team or technical expertise. With native connectors for tools like ServiceTitan and QuickBooks, and an intuitive, no-code interface, Peaka gives home service operators the visibility they need to grow, minus the engineering overhead.
Tracking job costs doesn’t have to be a manual chore. Peaka unifies your data and automates reporting processes so you can focus on creating value for your organization.
Ready to ditch the spreadsheets?
[Book a demo](https://calendly.com/peaka/demo) to see how Peaka simplifies the way you track job costing and profitability.
--- START: blog/unify-servicetitan-data-pe-firms/unify-servicetitan-data-pe-firms.md ---
# **How PEs Can Unify Data from Multiple ServiceTitan Instances**
When a private equity firm rolls up multiple home service businesses operating in plumbing, HVAC, electrical, or pest control, there’s a high chance each acquired brand runs its own ServiceTitan account. While this best-in-class software helps operators manage scheduling, dispatch, and invoicing, it wasn’t built with multi-entity portfolio reporting in mind.
What begins as a tech upgrade at the individual company level quickly becomes a reporting and data integration nightmare at the platform level. KPIs don’t line up. Data sits in silos. Board decks rely on delayed, manual exports. For firms operating on a 3-5 year value creation timeline, this fragmentation acts as a bottleneck to EBITDA growth.
This guide is for private equity operating teams and finance leaders who need a practical way to unify ServiceTitan data across multiple brands or instances, normalize KPI definitions, and create a consistent reporting layer that survives the next acquisition. If you are a ServiceTitan consultant managing separate client accounts, read our blog post for [multi-account ServiceTitan consultants](/blog/manage-multiple-servicetitan-accounts/). If you are a contractor running multiple branches within one company, start with our [multi-location ServiceTitan reporting](/blog/multi-location-servicetitan-reporting/) guide.
## **The problem with disconnected ServiceTitan instances**
Most home service roll-ups result in each brand retaining its own ServiceTitan environment. While this allows for a smoother transition as teams continue working with a platform they are already familiar with, it also leads to a few problems:
+ **Inconsistent reporting:** Each entity maintains its reporting habits, with KPIs being defined and calculated slightly differently across the portfolio.
+ **Manual processes:** Data replication from one spreadsheet to another and [manual data exports](/blog/servicetitan-manual-data-export-costs/) via CSV remain the primary methods of data consolidation.
+ **No real-time insights:** Without a unified, live view of data, leadership and portfolio managers lack the data needed to draw insights from and have to rely on outdated data.
+ **Blind spots across brands**: It’s nearly impossible to benchmark technician utilization, close rates, or marketing ROI across the portfolio in the absence of integrated data and standardized metrics.
As Peter Drucker once said, “*You can’t manage what you can’t measure.*” This is especially true for PE firms that lack a single source of truth across their portfolio. It means flying blind when it comes to performance optimization and wasting precious weeks every quarter preparing investor updates.
## **What ServiceTitan PE operating teams actually need**
A central view of portfolio performance isn’t a simple reporting upgrade; it’s a source of competitive edge when you’re rolling up underperforming home service companies. Here’s why:
+ Benchmarking across brands becomes possible. Why are jobs closing faster in Dallas but not in Phoenix? Is one brand’s tech utilization lagging?
+ Revenue leaks, margin opportunities, and unusual trends are easier to spot when KPIs are normalized across entities.
+ Faster time-to-insight helps PE firms stay agile, especially when strategic decisions must be made between board meetings.
+ Board and LP reporting becomes more consistent, more reliable, and less dependent on ad hoc Excel work.
In short, centralized data unlocks the full potential of a buy-and-build strategy.
## **The traditional data stack: Why it doesn’t work for PE roll-ups**
Some firms attempt to unify their ServiceTitan data by assembling a traditional data stack. On paper, it seems the logical thing to do: use Fivetran or Airbyte to extract data, store it in Snowflake or BigQuery, model it in dbt, and visualize it in Tableau or Power BI. But the reality? It’s a bad fit for the needs of a PE firm for a variety of reasons:
+ **Cost:** Traditional data stacks require significant upfront investment in tools, data engineers, and months of setup, which easily add up to $150K+ per year.
+ **Complexity:** Most operators lack in-house data teams to run and maintain these systems, resulting in these initiatives becoming full-blown IT projects with six-figure costs and unclear ROI.
+ **Misalignment with PE timeline:** By the time a traditional data stack begins delivering ROI, a PE is halfway through its value creation window, which typically lasts 3-5 years.
All in all, the capabilities of traditional data stacks are overkill for companies that are simply trying to surface technician performance or revenue per job and fire up real-time KPI dashboards.
PE firms don’t need a data warehouse; what they need is answers. Fast. That’s why a nimble solution like Peaka, which connects directly to multiple ServiceTitan instances and delivers insights within days, is far better suited for lean operating teams and compressed timelines.
## **What the ideal solution looks like**
A solution designed for PE operators needs to go beyond point-to-point integration. It should:
+ Connect to multiple ServiceTitan accounts at once
+ Normalize data schemas across brands and define [standardized KPIs](/blog/standardize-servicetitan-kpis-portfolio/)
+ [Integrate ServiceTitan with accounting tools](/blog/integrate-servicetitan-with-quickbooks-xero-sage/) like QuickBooks, XeroAccounting, or Sage Intacct
+ Require minimal IT involvement, given most operators lack full-stack data teams
+ Work with modern BI tools, supporting dashboards in [Power BI](/blog/servicetitan-power-bi-integration/), [Looker Studio](/blog/how-to-connect-servicetitan-to-looker-studio/), [Metabase](/blog/how-to-connect-servicetitan-to-metabase/), and more
## **How Peaka solves the fragmentation problem**
Peaka was built with multi-tenant ServiceTitan environments in mind. This makes it ideal for PE-backed home service platforms.
Here’s how it works:
+ **Connects directly to each ServiceTitan instance:** No custom engineering or connector development required.
+ **Creates a unified data layer:** Peaka consolidates and models data from each brand into a single, standardized structure.
+ **Visualizes performance KPIs in real time:** Revenue trends, job close rates, technician efficiency, and more are available instantly.
+ **Reduces reliance on data teams:** With text-to-SQL capability, even non-technical users can explore, filter, and report on portfolio data.
+ **Deploys in days, not months:** Perfect for value creation plans where every quarter counts.
## **Key takeaways**
+ PE-led roll-ups using ServiceTitan often struggle with fragmented data and inconsistent reporting.
+ Unifying these ServiceTitan instances enables faster insights, better benchmarking, and higher ROI.
+ Peaka offers a fast, low-lift way to centralize multi-brand performance data—no data warehouse or BI team required.
## **Getting started with Peaka**
If you’re managing a growing portfolio of ServiceTitan-based businesses, you don’t need to keep stitching together spreadsheets or waiting on analysts. Peaka can help you unify your data, accelerate reporting, and create the visibility your value creation plan demands.
[Book a demo](https://calendly.com/peaka/demo) to see how we help PE firms simplify ServiceTitan data integration and unlock portfolio-wide insights in days, not months.
--- START: blog/venture-capital-generative-ai/venture-capital-generative-ai.md ---
# **What is Driving VC Interest in Generative AI?**
2022 was not the best year for tech startups, especially those in the software development segment. The world we woke up to after the pandemic was a different one. It no longer had the appetite for software that it had during the pandemic. The Russian invasion of Ukraine further complicated things, driving up prices and triggering an inflationary wave. The Fed was forced to hike interest rates multiple times, the ghost of a recession was looming all over us, and investors took note of all these developments.
What investors think matters because where they put their money serves as an indicator of the near future in tech. The ideas and projects investors pour money into turn into magnets, attracting attention from founders looking to hit big. The concepts no longer backed by investors lose their glamor and start to be questioned by the wider public.
## **A sea change in investment circles**
Once again, investors voted with their wallets and hit the brakes on Web3 projects. Cryptocurrencies and NFT-based ideas no longer engender the excitement they once did among investors. The low-code/no-code segment also saw funds drying up in the last quarter of the year. The segment was running on all cylinders during the pandemic, capitalizing on the rush to digital transformation. With everything going back to normal, expectations were revised in a way that would allow for a more modest level of growth for low-code/no-code companies.
There was one area that seemed immune to the lack of funding, though: Artificial intelligence (AI) and machine learning (ML).
Venture capital (VC) interest in AI is nothing new. Total global investments in AI were less than $3 billion in 2012 and reached [$75 billion in 2020](https://www.oecd-ilibrary.org/docserver/f97beae7-en.pdf). In the U.S. and China, mobility and autonomous vehicles were the top destinations for VC money during this period.
Y Combinator's (YC) first 2023 batch demonstrates that the VC interest in AI is stronger than ever. [51 of the 183 startups](https://medium.com/democratizing-finance/the-ai-goldrush-51-ai-startups-in-y-combinators-first-2023-batch-7cea092e941b) in the batch are AI startups, 32 of them focusing on [generative AI](https://www.mckinsey.com/featured-insights/mckinsey-explainers/what-is-generative-ai), that is, the algorithms that can be used to create new content like audio, code, images, text, and video.
This comes on top of the [loss of faith](https://jaredheyman.medium.com/on-y-combinator-startups-and-the-ai-revolution-fe8ee2269abe) YC experienced after its initial zeal in backing AI companies from 2013 to 2017. The first wave of AI tools failed to live up to the expectations, which were probably unrealistic to begin with. Falling short of expectations caused disillusionment and proved that a little bit of restraint was due. Things are looking up once again for AI, and VC funds are pouring in money to power projects of all kinds.
## **'*Promise me it will be different this time*'**
You probably remember seeing similar levels of unbridled enthusiasm for Web3 and metaverse just a couple of years ago. Are we going through the same things all over again? Is AI another fad that will not amount to much, just like Web3 and metaverse before it? Probably not.
Despite all the excitement it created in tech circles, Web3 failed to deliver practical use cases that can encourage mass adoption and justify more investment. The crypto winter, the FTX collapse, and the never-ending scams killed the short-term prospect that cryptocurrencies would replace fiat money any time soon. The fact that use cases for blockchain remained rather limited and ventured little beyond financial speculation eventually dampened the enthusiasm of investors. The Web3 episode is definitely not over yet, but put on hold until meaningful real-life applications appear.
AI is a more mature technology compared to Web3. Scholars and engineers have been writing and thinking about, and experimenting with different AI applications [since the mid-twentieth century](https://en.wikipedia.org/wiki/History_of_artificial_intelligence). Therefore, it is no surprise that AI proved more resilient because this is not AI's first iteration.
AI has traveled all the way along Gartner's hype cycle: It gained popularity on the back of a major innovation, produced sky-high expectations early on but failed at fulfilling them, falling into the trough of disillusionment. As people realized what AI was good at and how it could be leveraged, this new technology gained a new form in generative AI and pulled itself out of the hole, gathering steam once again with more sensible use cases.
## **A new wave of AI-powered products**
So, AI differs from Web3 in that entrepreneurs have managed to turn it into products that can be used by the masses. Different startups from various verticals like gaming, copywriting, and graphic design are leveraging a model layer like the one Open AI has and building application layers on top of it. [Taking advantage of APIs and open-source principles](https://www.forbes.com/sites/columbiabusinessschool/2023/01/17/generative-ai-the-new-frontier-for-vc-investment/), generative AI startups can quickly monetize their ideas, and investors do not hesitate to back them. Jasper, the AI-assisted copywriting app, provides a case in point. The company grabbed headlines in October with a [$125 million Series A round](https://www.businessinsider.com/generative-ai-startup-jasper-raises-seriesa-funding-insight-openai-2022-10), becoming the poster child of this new generation of AI-powered apps.
The VC interest in generative AI was almost palpable in the last few months of 2022. There were 78 successful funding rounds closed, with a total investment of [close to $1.4 billion](https://www.nytimes.com/2023/01/07/technology/generative-ai-chatgpt-investments.html). Besides Jasper, Stable Diffusion and Runway topped the list of companies raising money at incredible multiples despite having modest revenue streams as of now.
However, the niche that gets VCs drooling consists of startups working to develop new [foundation models](https://en.wikipedia.org/wiki/Foundation_models), the large AI models trained on a vast amount of data for use in a range of implementations, which can rival the ones like OpenAI's GPT. One such company is [Cohere](https://www.reuters.com/technology/ai-startup-cohere-talks-raise-funding-6-bln-plus-valuation-sources-2023-02-06/). The Toronto-based company is looking to raise money at a valuation of more than $6 billion. It stands apart from OpenAI with its focus on business-applicable use cases and its target customer base of enterprise users.
Companies like Cohere are the innovators that can broaden the horizons of AI through research and development rather than building "me-too" apps that can attract a few investors before flaming out. The hope is that these efforts will produce new models that have less bias and consume less energy.
## **Conclusion**
Angel investor Elad Gil [was quoting](https://www.youtube.com/watch?v=VThN7kpjRpM) Andy Rachleff when he said, "*the market impact, good or bad, dominates the team impact.*" The VC interest in AI is so strong and the initial reaction from the public is so positive that generative AI startups enjoy a tailwind these days.
However, this will not last forever. The laws of startup survival will still hold at the end of the day. Once the initial VC interest subsides and profitability becomes a priority, the startups with the better team, product quality, traction, and moat (defensibility) will prevail. In the words of Warren Buffett:
> "*Only when the tide goes out do you discover who's been swimming naked.*"
Startup founders in the generative AI segment had better start looking for some semblance of swimming trunks if they don't want to embarrass themselves or, worse, lose their startups.
--- START: blog/web3-better-internet/web3-better-internet.md ---
# **Web 3.0: The Better Internet?**
We are currently at an inflection point in the internet technology or standing at the edge of a drastic change. New and maturing technologies such as Virtual/Augmented Reality (VR/AR), Artificial Intelligence (AI), and blockchain are converging to revolutionize the internet. Not only that, but there is a will among people to change the way the internet has operated for more than a decade because they feel intimidated and even threatened by what has come of it.
It wasn’t always like this, though. When the internet appeared in the early 90s, it was seen as an inclusive, egalitarian breakthrough that would facilitate access to information for all of humanity. It was a one-way street back then—the internet technology was read-only, whereby you typed in the web address of the website you wanted to visit and consumed information, and that was pretty much all that there was to it. Today, this period of the internet is defined as Web 1.0.
Web 2.0, which entered our lives in the mid-2000s, transformed the way people used the internet and turned it into one of interaction. The internet was no longer read-only, but it was [read-write](https://theconversation.com/web-3-0-the-decentralised-web-promises-to-make-the-internet-free-again-113139). Search engines were the drivers of this change early on, only to be joined by social media platforms later. People became content creators, and companies that monetized the user-generated content came to dominate the internet, becoming some of the most valuable brands in all of the economy. The size of data people revealed on this network kept growing over the years, and it was this very phenomenon that created the uneasiness toward the internet lately.
The growth of platforms owned by Google, Apple, Microsoft, Facebook, Twitter, and Amazon brought about the accumulation of data in the hands of these companies. If knowledge is power, then it follows that these companies came to wield disproportionately immense power over the society, people and businesses alike. Just imagine losing access to or being locked out of an account you had on one of these platforms and how much trouble that would cause for you, and it becomes easier to understand the kind of clout these companies carry.
Privacy is one of the main concerns of internet users today. Personal information shared on such platforms can come back to haunt individuals as Big Tech companies depend on the monetization of such data for revenue generation. Google and Facebook are particularly greedy in the amount and type of personal data they store. The ostensible reason for this data hoarding is to improve the product, services, and user experience. However, it serves well to keep in mind that the business models of these two giants are based on turning this data into targeted ads. People willingly share with these platforms their [name, email address, phone number and payment information](https://www.security.org/resources/data-tech-companies-have/). These platforms can use the information you voluntarily gave them and track your interactions with other people on the platform to correctly profile you and share that data with third parties, which is where things can get a little bit unpleasant.
The opaqueness in the way Big Tech companies handle user data has always been an issue that garnered attention. But it was with the Cambridge Analytica scandal that people faced an example that illustrated the possible ramifications of harvesting of user data without user consent. An investigation carried out in 2018 revealed that the British consulting firm Cambridge Analytica had used an app to harvest data of as many as [87 million Facebook users](https://qz.com/1245049/the-cambridge-analytica-scandal-affected-87-million-people-facebook-says/) to build their psychographic profiles. This psychographic data was later used to aid the presidential campaigns of Ted Cruz and Donald Trump. Combined with the alleged Russian efforts to use influence campaigns over social media to meddle in the [U.S.](https://www.bbc.com/news/technology-46590890) and [French](https://www.wired.com/2017/05/nsa-director-confirms-russia-hacked-french-election-infrastructure/) elections, it became easier for the regular citizens to connect the dots and realize how data security and privacy were linked to the survival of democracy.
Web 2.0, as it is now, has [all the flaws of the society](https://gavofyork.medium.com/why-we-need-web-3-0-5da4f2bf95ab), only magnified by several orders of magnitude. The asymmetry of power we suffer from in our daily lives vis-à-vis the government can easily be aggravated in a scenario where Big Tech companies can collude with governments to turn life into a living hell for citizens. Combining the data collected by the former with the latter’s coercive power can be the recipe for a dystopian surveillance state. This state can then use the data provided by the Big Tech companies to curtail and push back against individual rights.
This is the main danger which Web 3.0 is expected to mitigate. Web 3.0 is a decentralized network that leverages [peer-to-peer connectivity](https://theconversation.com/web-3-0-the-decentralised-web-promises-to-make-the-internet-free-again-113139). The peer-to-peer character of Web 3.0 ensures that data is [not owned by anyone but shared](https://internationalbanker.com/technology/what-is-web-3-0-and-why-does-it-matter/), which negates the need for a user to trust anyone with his data. This means that there will be “[no middlemen, government eavesdropping or walled gardens.](https://blog.computes.com/web-3-0-decentralization-matters-to-business-57a5989dd441)” As technologies such as AI, AR, IoT, 5G data transmission, and machine learning mature, Web 3.0 will be able to synthesize data to provide its users with more relevant information, and the line between the physical and digital phenomena will get blurred.
However, nothing is set in stone at the moment. Nobody knows what kind of regulations will apply to a decentralized network like Web 3.0 and how they will be enforced. This ambiguity in regulations will undoubtedly hamper efforts to [rein in crimes](https://theconversation.com/web-3-0-the-decentralised-web-promises-to-make-the-internet-free-again-113139) such as money laundering, online harassment, or child abuse.
While there is hope that Web 3.0 will turn out to be the democratic utopia everybody hopes for, it may as well turn out to be a network of “[platform-defined, walled-garden Spatial Webs](https://www2.deloitte.com/us/en/insights/topics/digital-transformation/web-3-0-technologies-in-business.html)” owned and governed by a small group of large companies, which wouldn’t be much different than the Web 2.0 experience. We can only hold out hope that the lessons learned from the Web 2.0 saga will lead to a more egalitarian technology that will take us closer to the ideals of the World Wide Web when we first encountered it thirty years ago.
--- START: blog/web3-blockchain-internet-of-value/web3-blockchain-internet-of-value.md ---
# **Blockchain as the Key to the Internet of Value**
Web 3.0 is ushering in a new age of internet connectivity. It is a direct response to [the problems that have plagued Web 2.0](/blog/web3-better-internet/) for years, and is thus designed as a decentralized, trustless, and permissionless network from the get-go. Underpinning Web 3.0 is the [distributed ledger technology](https://www.investopedia.com/terms/d/distributed-ledger-technology-dlt.asp), which ensures that information, transactions, or contracts are cryptographically stored over a distributed network of nodes whereby each node gets to keep a copy of the data. This format minimizes the risk of data manipulation as the data on the manipulated copy would not match the data on the other copies kept on different nodes.
Blockchain keeps data in a [time-stamped string of blocks](https://www.investopedia.com/terms/b/blockchain.asp). This practice not only ensures the immutability of data, but also holds the keys to the solution of one of the biggest pains of internet users: Having just the right amount of confidentiality. People do not want to unnecessarily reveal private information unless they absolutely have to, but want to be able to produce proof of identity when needed. Transactions on blockchain can be traced back to the person who executed that transaction, but that person will not have to reveal his personal information to get the transaction done. This very feature has helped IBM and Walmart put in a system in China to [track-and-trace food products](https://www.forbes.com/sites/samantharadocchia/2018/04/26/3-innovative-ways-blockchain-will-build-trust-in-the-food-industry/#10a5ebc42afc) over the whole supply chain and get to the bottom of a problem in case something goes wrong. The system also makes it easier for the authorities to verify whether the claims of "organic" production or "fair trade" practices hold water.
This is why [finance industry](/blog/api-open-banking-defi/) is so keen on blockchain technology. Blockchain can keep an immutable proof of identity that will be universally accepted while offering the users a very high level of confidentiality. One common hurdle in banking services is the know-your-customer (KYC) procedure that is indispensable to almost everything a bank does for its customers. KYC entails the identification and verification of a person's identity. It may involve submitting a national ID card or a passport, high-quality photographs, and complete and legible documentation, [among other things](https://medium.com/evenplatform/requirements-to-kyc-documents-ee0a1cea6b36). It rarely ends with the submission of the necessary documents, though, as the process can take up to several weeks in countries like the U.S.A. and U.K. Imagine doing business in different regions of a vast country like the U.S. and having to go through this process in every city you conduct business. That would certainly be enough of a waste of time to discourage some people from doing business.
Customers are not the only party to be discouraged by the KYC procedure. KYC is one of the main barriers for local banks in the U.S to attract new customers. Not willing to go through the same ordeal in every city they conduct business in, customers are attracted to bigger national banks with branches in different states and cities.
Blockchain offers the perfect solution to mitigate the KYC problem. It allows the conversion of customer data (including your personal information and history file) into a hash code so that it can be saved on a crypto wallet. Sharing the hash code with the other banks in the system is perfectly safe as it is a one-way function: The hash code can't be used to reproduce the data stored in it.
When the customer shows up at the local branch of a bank in some other country and produces his hash code, all the bank has to do is to see if the hash code matches with the one on the system to find out if the customer is really the person he claims to be. Blockchain's solution takes care of the whole KYC process in an instant and can be implemented universally. It ensures that national borders are no longer an obstacle for you to enjoy financial services away from your home country. Your whole credit history will be with you when you visit a bank in a foreign country, and you won't have to start all over again. This is an immense benefit for the [3 billion people](https://medium.datadriveninvestor.com/the-future-will-be-decentralized-2696fc4898b0) who are "unbanked "right now. People like refugees who lack the financial records to kickstart a new life away from home stand to gain so much from this breakthrough in the KYC process.
Blockchain technology guarantees that information will be coded and distributed across a network of nodes, which removes the possibility of data editing and ensures authenticity. The immutable record stored in the hash code can be used to protect sensitive information like deeds and legal contracts in [war-torn countries](https://www.investopedia.com/terms/b/blockchain.asp) where state authority is non-existent. In that sense, blockchain transforms the internet from a [network of information](https://coinmarketcap.com/alexandria/article/what-is-decentralized-finance) into a network of value where assets can be preserved and exchanged. It removes government custody over a person's assets and facilitates the free movement of value. In more creative use cases, it can even be leveraged to set up a trustworthy voting system that cannot be rigged, and restore trust in the democratic institutions and processes.
The use cases listed above are just the tip of the iceberg—it seems blockchain will find its way into every aspect of our lives. However, the end-user won't be able to consider all these use cases and come up with solutions for his own problems since the blockchain domain comes with its particular set of challenges:
+ Scalability remains an obstacle where new data is added to the existing string of blocks and every node in the network is supposed to store that data
+ Security is a challenge, as was illustrated by the attack performed [against Ethereum](https://www.nytimes.com/2016/06/18/business/dealbook/hacker-may-have-removed-more-than-50-million-from-experimental-cybercurrency-project.html) in 2016 that forced a hard fork
+ Regulations are not in place yet
Dealing with these challenges requires a certain level of domain expertise which the end-users lack. No-code technology can definitely help here and facilitate [know-how transfer](/blog/templates-know-how-transfer/) from domain experts to the general public. Experts can employ no-code templates to define and serve the most common use cases, accelerating the revolution blockchain is expected to trigger in internet technology.
--- START: blog/web3-dao-friendly-countries/web3-dao-friendly-countries.md ---
# **Top 5 Most DAO-Friendly Countries**
The DAO (decentralized autonomous organization) economy has garnered serious interest from authorities at the state and regional levels for the last few years. However, the reactions vary. While major economies look somewhat reluctant to legalize DAOs for one reason or another, a group of relatively small countries shows enthusiasm to probably gain an early-mover advantage in the game. Let's take a look at how different jurisdictions are dealing with these structures that can one day take the ongoing blockchain craze to another level.
## **1 - Wyoming, U.S.A**
Wyoming is not the first state in the U.S. coming to mind when you think of high tech and finance industries. But the Cowboy State is determined to become the "[blockchain state](https://decrypt.co/5240/welcome-to-wyoming-the-blockchain-state)."
The authorities in Wyoming took a big step recently to introduce a regulatory framework for DAOs. The bill they passed allows DAOs to incorporate in the state and be founded as limited liability companies (LLCs). This bill cleared some of the doubts regarding the legal responsibility in DAOs by turning them into a legal entity.
The legislation brought structure to an expanding business segment. Yet, it stopped short of giving DAOs a *carte blanche*. The Secretary of the State of Wyoming retains the right [to strip a DAO of its liability protection](https://decrypt.co/68789/daos-are-now-officially-recognized-as-a-new-type-of-llc-in-wyoming) if it is involved in some kind of illegal activity.
## **2 - Malta**
The tiny Mediterranean island looks to diversify its economy, which is mainly dependent on tourism revenue. Becoming a crypto-friendly country is one of the steps to realize that goal.
In accordance with this goal, the University of Malta [has already introduced](https://timesofmalta.com/articles/view/blockchain-the-need-for-tech-law-business-and-finance.914925) a master's program on blockchain and distributed ledger technology (DLT). Malta also became [the first country to legalize DAOs](https://www.withersworldwide.com/en-gb/insight/on-the-rise-distributed-autonomous-organizations-daos). The legislation introduced some form of corporate governance into DAOs. But it ended up placing too much responsibility on the executives of these organizations, which is incompatible with the spirit of DAOs.
In 2018, Delta Summit, the first government-backed event on crypto-banking, was held in Malta. Such enthusiastic initiatives did not amount to much at the end of the day, though. There are still concerns that cryptocurrencies could [undermine anti-money laundering efforts](https://www.ellulschranz.com/crypto-friendly-banks-malta), has slowed things down a little bit. Today, any DAO [willing to conduct business in Malta](https://fintechlegal.center/best-eu-country-for-crypto-business/) should have a license, incorporate a limited liability company, and employ at least three employees.
## **3 - Switzerland**
California may have Silicon Valley, but it is the small Canton of Zug in Switzerland that's determined to become the *Crypto Valley*. Zug is a small town with a [business-friendly environment](https://www.businessinsider.com/what-its-like-in-zug-switzerlands-crypto-valley-2018-6#-10) and low corporate tax rate. Yet, it still has difficulty attracting venture capitalists. The town hopes to grow a blockchain ecosystem to compensate for the lack of investment.
The fact that Ethereum Foundation is based in Zug came to define the town in the last several years. Today Zug is [home to many crypto companies](https://cryptovalley.swiss/) like Monetas, Bitcoin Suisse, Xapo, ShapeShift, ConsenSys, and Tezos. Local authorities seem eager to get on with the times, too. As of the last quarter of 2021, Zug Department of Finance accepts tax payments in cryptocurrencies. The town also successfully ran a test of [blockchain-based municipal voting](https://www.swissinfo.ch/eng/crypto-valley-_-switzerland-s-first-municipal-blockchain-vote-hailed-a-success/44230928) in 2018.
Switzerland might be the best-positioned country to become the center of the crypto industry. It is home to some of the best financial institutions in the world. The fact that it has a population with a high disposable income per capita can be a boon for startups, too. It is no surprise that the country wants to have a say in the future of money.
However, the very success the Swiss have had in traditional finance practices may come back to haunt them when it comes to DAOs. The Swiss National Bank seems to be concerned that cryptocurrencies may increase volatility in the market. As smart contracts reduce friction in transactions, people will find it easier to complete transactions. Authorities fear that a sharp increase in the number of transactions will disrupt the finance sector.
The Swiss are playing a balancing game here. On the one hand, they are trying to attract crypto firms. On the other, they are doing their due diligence, taking as long as one year to issue crypto licenses. It will be quite an achievement if they manage to preserve their impeccable reputation for old money while leading the move toward an economy built around digital assets.
## **4 - Estonia**
Another small European country that is trying to make a name for itself as digital-friendly is Estonia. The Baltic country introduced a crypto licensing plan in 2019 to attract crypto companies and give its economy a much-needed boost.
However, it did not take long before the Estonian government hit the brakes. Similar to what happened in Malta, Estonian authorities recognized the concerns over money laundering and [shut down](https://www.bloombergquint.com/onweb/clients-of-estonia-s-e-residency-project-linked-to-crypto-scams) hundreds of crypto businesses recently. This move brought down their number from 1,234 at the end 2020 to 353 by the end of August 2021. Still, no other EU country seems as favorable to crypto businesses as Estonia today.
## **5 - Gibraltar**
There seems to be a race among tiny states, cantons, or territories to be the crypto darling. Gibraltar, a British overseas territory, is in the hunt, too.
The administration in Gibraltar has for some time sought ways to make government services more efficient and effective. It has decided recently to integrate blockchain into its legacy systems. RSK, the smart contract platform that underpins Bitcoin, has become the [platform of choice](https://www.coindesk.com/policy/2021/12/07/gibraltar-to-integrate-blockchain-into-government-systems/).
The Government of Gibraltar hopes that this change will enable its citizens to store their personal documents on a decentralized ledger. This will facilitate access to documents like IDs, driving licenses, or vehicle registration papers. The government has also given [crypto licenses](https://www.forbes.com/sites/mariaabreu/2021/12/08/hm-government-of-gibraltar-partners-with-bitso-and-iovlabs-to-issue-digital-ids-with-blockchain-technology/) to 15 firms.
## **Conclusion**
This by no means is an exhaustive list of countries showing interest in DAOs, cryptocurrencies, and blockchain technology in general. Countries like [Iran and China](https://www.euronews.com/next/2021/11/20/bitcoin-ban-these-are-the-countries-where-crypto-is-restricted-or-illegal2) had either cracked down on cryptocurrency transactions or outlawed them altogether in the past. Today, they seem to have come around to the idea. They are rumored to be mulling over plans to introduce their own state-owned cryptocurrencies.
It looks like governments and institutions like the European Union recognize the potential of blockchain technology. But they all have their reasons to remain hesitant:
+ Repressive regimes wouldn't like it if their subjects conducted business, organized or financed political activism through DAOs. DAO participants want to evade the control of a central authority. Repressive regimes will do anything to stop that.
+ The more liberal countries fear that DAOs and cryptocurrencies can spiral out of their control down the road. These technologies can be used to sidestep sanctions imposed on countries like Iran and North Korea. Worse still, they can make activities like money laundering or financing of terrorism almost impossible to detect.
Nevertheless, blockchain has become too big to ignore. Everybody is keeping an eye on attempts to legalize DAOs in different countries. As governments learn from these experiments, they will look to harness the power of blockchain for their own interests.
--- START: blog/web3-dao-novel-way/web3-dao-novel-way.md ---
# **How to Use Decentralized Autonomous Organization (DAO)**
The possible use cases for blockchain technology will proliferate, it seems. Although cryptocurrencies are all the rage nowadays, the real transformative power of blockchain is hidden in applications like the simplification of the KYC process and taking financial services to millions of unbanked people. But that’s not all that there is to it—blockchain is paving the way for a new type of organization that has the potential to change the way people do business, collect artwork, or organize for a political cause: [Decentralized Autonomous Organization](https://www.investopedia.com/tech/what-dao/) (DAO).
If blockchain is to underpin a new type of organization, it will do this through smart contracts. A [smart contract](https://ethereum.org/en/defi/) is an Ethereum account that ties transactions to certain conditions. When those conditions are met, the transaction automatically takes place without the involvement of a third party or an intermediary. So, it basically is a code that realizes the terms of an agreement between different parties.
Once smart contracts showed promise in regulating and facilitating transactions, it was evident that the concept was applicable to a broader range of situations. DAO was a product of such thinking. DAO was developed to automate decisions and ease cryptocurrency transactions. The originators of the idea aimed to leverage automation and community voting to eliminate human error and mischief and monitor transactions. In an ideal world, smart contracts would replace all the regulations in the business world, removing the need for government oversight and institutional supervision. You could bake laws, rules, and regulations into smart contracts and, in theory, execute any kind of transaction in any industry by just [stringing together](https://www.investopedia.com/news/daos-and-potential-ownerless-business/) as many “if…, then…” statements as you needed.
Despite their potential, DAOs are not technically perfect. Actually, DAOs can be technically inefficient compared to other digital processes. Any piece of data added to the blockchain is registered on every node. Due to the number of transactions that can be processed by a node being limited, scalability can be a problem with DAOs.
However, DAOs are efficient because they take care of work that would otherwise have to be done through conventional bureaucratic means, freeing up a lot of time. DAOs also bring together different parties where trust is a serious issue, and smart contracts can help get deals done. Additionally, by facilitating pooling of funds and talent, they increase the likelihood that projects will be implemented. In other words, DAOs unlock significant social and economic value for the price of a reasonable level of technical inefficiency.
The use cases for DAOs seem only limited by imagination. DAOs appeal to people who have idle funds at hand and are looking for assets to park their money. These people can join DAOs and buy shares in a communally-owned piece of art or become the sole owner of unique, inimitable artwork. DAOs also make it easier for underprivileged communities across the world to come together. Without the friction caused by national borders, people can combine their resources and form initiatives to promote causes benefitting [minorities or underrepresented people](https://blog.aragon.org/15-ways-the-world-is-being-transformed-by-daos/#community-collectives). DAOs may even have a role to play in the day-to-day running of government: The Swiss Canton of Zug has initiated the use of DAOs for voting on [municipal matters](https://www.businessinsider.com/what-its-like-in-zug-switzerlands-crypto-valley-2018-6) (more on this in [our next blog post](/blog/web3-dao-friendly-countries/)), so expect to see more political activism organized around DAOs.
The broader acceptance of DAOs still awaits a legal framework to be introduced. Some countries have already taken steps in that direction. As the issue of legal responsibility in DAOs is sorted out, these organizations will undoubtedly get to play a more prominent role in our lives.
--- START: blog/web3-dao-vc-partners-rivals/web3-dao-vc-partners-rivals.md ---
# **DAO & VC: Improbable Partners Today, Fierce Rivals Tomorrow**
On November 18, 2021, an original copy of the U.S. Constitution was [put up for sale](https://www.youtube.com/watch?v=1TBa-9Lx3vc) at Sotheby’s auction house. It looked like an ordinary auction, the likes of which the renowned auction house had held thousands of times before. However, this one turned out to be different as thousands of people mobilized over the internet to pool funds and make a bid. This crowdfunded initiative (named ConstitutionDAO) managed to raise $47 million in a week by bringing together more than 17,000 people who wanted to contribute. But the bid failed, with the item selling for [$43.2 million](https://www.sothebys.com/en/press/newsflash-newsflash%20(sothebys.com%20-%20permalink)?locale=en) ([allegedly,](https://www.cnbc.com/2021/11/18/constitutiondao-crypto-investors-lose-bid-to-buy-constitution-copy.html) had ConstitutionDAO beaten that bid, there wouldn’t be enough money left for the care, preservation, and custody of the document would). The failure raised questions about the fate of funds collected as there is no legal framework regulating the crowdfunding campaigns led by DAOs. It turns out that ConstitutionDAO had an “[act-first-think-later](https://www.fwb.help/wip/imperfect-union-how-constitutiondao-lost-its-way)” approach. Not much thought was put into what would happen after the auction—whether the bid was successful or not, the members of the ConstitutionDAO would vote on different proposals to figure out what to do.
The ConstitutionDAO case illustrates both what is exciting and scary about investment DAOs. On the one hand, the unparalleled agility and speed DAOs offer in mobilizing people, pooling funds, and investing in projects have great promise for startups. On the other hand, the lack of accountability or any form of legal recourse in case things don’t go well are significant hurdles that might prevent DAOs from becoming the mainstream instruments for investment. The p
opular crowdfunding platform Kickstarter gives you the option of [backing out of a commitment](https://help.kickstarter.com/hc/en-us/articles/115005028854-What-does-Kickstarter-do-to-protect-its-community-) to support a project during the funding period (the funds get locked in only when the project goal is met). DAOs, on the other hand, don’t have any similar regulations in place at the moment. Regulating how DAOs work, establishing strict rules as to what should be done when a project doesn’t meet its goals (or how DAO members are to be compensated in case of fraud), or turning DAOs into limited liability companies can bring accountability to this niche segment. But this would probably come at the price of the spirit that makes DAOs special in the first place. A tightly-regulated DAO will not be the fun, impulsive, and agile organization people love being a part of.
The ConstitutionDAO saga may have serious implications for Venture Capitalists (VC). VCs are indispensable to a lively startup ecosystem. They evaluate projects, spot talent, envision what may come of a particular product, and make investment decisions, some of which turn out to be real breakthroughs. However, the relationship between VCs and startups has never been egalitarian. The VCs have been in the driver’s seat while startups pitched their ideas to them and looked for funds, guidance, and a chance to make their dreams true.
The conventional fundraising process feature startup founders as mere mortals pleading their cases in front of the gods of Olympus, that is, the VC executives. This process gives VC executives more credit for spotting talent than both they deserve and the very talent in question could hope to receive. Some fund managers have even reached rock star status for investing in projects that later became hugely successful. People like Paul Graham of Y Combinator, Marc Andreessen of Andreessen Horowitz and Mark Maples of Floodgate have become celebrities, much lauded for the Midas’ touch they possess.
DAOs have the potential to change that, however. The democratization wave, which has hit everything from software to finance to content creation, is about to hit the VC firms as well. The recent crowdfunding initiatives organized under DAOs, with their agility and passion they instill in contributors, threaten to transform the whole investment landscape. Unlike VC companies that act upon financial projections, calculations, and a reputed sixth sense resulting from experience that investors use to judge the potential of a project, DAOs act like digital tribes at times, relying on a community’s belief in a supposedly righteous cause, or even pure hype in some cases. As crypto startup Multis [found out](https://www.businessinsider.com/dao-crypto-investing-trend-vc-startup-need-to-know-2021-6), the decision-making process of DAOs can be astonishingly swift. They only need a few hours to decide whether to invest in a project and if they do, the startup gets its money within the day as opposed to 15 days when pitching to a VC.
Having noticed the appeal DAOs have for startups, VCs want a piece of the action, too. However, DAOs would like to see VCs support them on DAOs’ terms, whereby VCs would see them as equals. This desire may translate into a reversal of roles regarding who is pitching and who is deciding. The controversy surrounding SushiSwap in 2021 presaged this possible future. When a group of VC firms, including [Lightspeed Venture Partners, Breyer Capital, and Polychain](https://forum.sushi.com/t/withdrawn-sushi-phantom-troupe-strategic-raise/4554) offered to buy governance tokens issued by SushiSwap at a discount, some members of SushiSwap objected. The disgruntled members questioned the value VCs would bring in and accused them of just chasing a quick buck. SushiSwap members still haven’t decided whether to take the VCs on their offer yet, but this new situation requires VC executives to pitch their proposals to the DAO community and [engage in lobbying](https://cointelegraph.com/news/andreessen-horowitz-launches-biggest-ever-crypto-venture-fund-at-2-2b) to earn the goodwill of other stakeholders. a16z committed to this change in strategy and took the plunge, recently [investing in](https://a16z.com/2021/10/27/investing-in-friends-with-benefits-a-dao/) Friends with Benefits (FWB) DAO and becoming one of the first VC firms to navigate these waters.
DAOs draw interest from VC companies because they are slated to generate a healthy return on investment. However, in the sense that DAOs are investors themselves like the ConstitutionDAO case illustrated, they are rivals with VCs. DAOs and VCs represent two different eras in investment, and their respective philosophies couldn’t be any more different. While VC companies are [top-heavy, hierarchical, and opaque in the way they operate,](https://decrypt.co/78958/how-daos-are-reshaping-investment) DAOs are made up of people who detest hierarchy and put so much value on total transparency that it may be detrimental to their cause (the owner of the winning bid in the ConstitutionDAO case definitely knew how much money the DAO had raised because it was no secret).
An advantage DAOs have over the VCs is how they simplify the bureaucratic procedures associated with an investment. Usually, whenever a VC invests in a startup, a great deal of paperwork regarding the investment, reporting, administration, and dividend payouts ensue. Companies sometimes need to hire expensive consultants who can help with these tasks. All of these costs are of the recurring type. With DAOs, smart contracts take care of them all, and the only cost involves the initial coding of the smart contract.
DAOs and VCs definitely have common scenarios they can cooperate in, where the former can bring in its agility and passion, and the latter, its networking ability and financial acumen. However, the really interesting part would be to see whether DAOs can dethrone VCs as primary investors in the startup ecosystem. Smart money says that they can. But for that to happen, they should capitalize on the lack of administrative hassle and put in place a legal framework, taking care of the legal accountability issues and instilling trust in potential contributors.
--- START: blog/web3-dao-voting-mechanisms/web3-dao-voting-mechanisms.md ---
# **The Most Common Voting Mechanisms Used by DAOs**
## **Introduction**
DAO is political. Its vision extends from reforming the current economic system to revolutionizing society. How it should be governed is one of the hottest topics in the tech world nowadays. DAO is a construct with many political implications, and governance is a political issue in and of itself as well. Voting is at the center of all this. Members of DAO communities have been trying to balance different concerns like authority, inclusivity, speed, scalability, and economic interests and come up with an optimal method of decision-making. None of the voting systems we will talk about below offer a silver bullet to solve all problems. They all come with their pros and cons, and most of the time, multiple systems will be used together for a better solution. Here's a look at the most common voting systems in DAOs:
## **Token-based quorum voting**
Quorum voting is the most basic mechanism used for decision-making in DAOs. It requires a predetermined level of voters to vote in favor of a proposal for it to pass. Determining the quorum level can be tricky, though: Too high a quorum level stifles the decision-making process, and the quality of decisions made suffers when the threshold is set too low.
Quorum voting has [serious challenges](https://medium.com/daostack/voting-options-in-daos-b86e5c69a3e3). People hoarding tokens get to enjoy more voting power in this system. Wealthy members can even bribe others for support on a particular proposal. Then, there is the issue of conflicts of interest: Some people prioritize short-term profit with an eye to selling their tokens for a profit, while others emphasize values the DAO is built around. Also, people don't look too enthusiastic about participating in voting despite all the talk about decentralization and a new form of bottom governance. The percentage of members voting on popular platforms like DAOStack and Aragon are [below 10 percent](https://jisajournal.springeropen.com/track/pdf/10.1186/s13174-021-00139-6.pdf), which allows organized groups to dominate the voting process.
The low participation rate draws attention to other voting methods such as relative quorum voting, whereby a proposal passes when 51 percent of voters participating vote in favor. This technique is not without its flaws, either. BProtocol's coup on the MakerDAO platform in October 2020 is a good case in point. [BProtocol](https://www.coindesk.com/tech/2020/10/29/flash-loans-have-made-their-way-to-manipulating-protocol-elections/) used a flash-loan to borrow $7 million worth of MKR tokens to manipulate a vote, and then returned the tokens after the vote in the same time-block, exposing how vulnerable this new experiment in democracy can be.
Wary of these shortcomings, Snapshot and Orange have joined forces to introduce a [reputation-based voting system](https://cointelegraph.com/press-releases/how-snapshot-and-orange-are-making-crypto-more-democratic-with-reputation-based-voting), which will take into account the contributions a voter made. This initiative aims to wrestle power from the hands of speculators possessing great numbers of tokens and reward voters based on their track record, giving highly-engaged voters a portable reputation they can transfer to other platforms.
## **Quadratic voting**
In quadratic voting (QV), voters are allowed to buy tokens and acquire greater voting power. The voting power increases by the square of the number of tokens a voter has. So, while the representative impact of a single vote is one, it increases to four for two votes and nine for three votes. This system comes with its pros and cons: It discourages people without a vested interest from voting on an issue and [gives a minority a more prominent voice](https://medium.com/metawoodstudios/quadratic-voting-why-we-use-it-6c1c27b4304) on issues they are passionate about. However, QV is bound to bring about a plutocracy where voting power becomes a [function of wealth](https://en.wikipedia.org/wiki/Quadratic_voting#Criticisms_of_quadratic_voting_mechanisms). This situation contradicts the principles of modern democracy and is in stark contrast to the radical democracy that fans of blockchain technology preach.
[Replacing money with tokens](https://www.forbes.com/sites/shermanlee/2018/05/30/quadratic-voting-a-new-way-to-govern-blockchains-for-enterprises/?sh=53b8dde06ef8) is an alternative to using real money for buying votes. To understand how this alternative model works, let's assume every member is assigned a credit of 100 votes for ten tokens. A voter can choose to spread her tokens across different proposals (by putting two tokens on a proposal for an impact of four votes, three tokens on another for an impact of nine, and five tokens on a third proposal for an impact of 25). She can even put all ten tokens on a single proposal and use up all her credits. This practice is akin to buying [collective attention](https://dominic-w.medium.com/using-wait-for-quiet-voting-in-the-dao-12ecd9d9ccc3) for a proposal you back and increasing its visibility.
## **Conviction voting**
Conviction voting (CV) is a mechanism based on the continuous expression of the [aggregated preference](https://medium.com/giveth/conviction-voting-a-novel-continuous-decision-making-alternative-to-governance-aa746cfb9475) of a community. In this technique, the weight of a vote increases the longer it remains unchanged. Changing votes is always possible, but it comes at the price of sacrificing the weight your preference has accumulated up to that point. CV prevents people who happen to have large stakes from overpowering the minority opinion as the system [rewards](https://medium.com/daostack/voting-options-in-daos-b86e5c69a3e3) having faith in a proposal rather than sheer wealth. It is immune to last-minute ambushes whereby a group of voters make a concerted effort to swing the outcome in their favor just before the polls close.
## **Holographic consensus**
The goal of a DAO is to realize the [global opinion](https://medium.com/daostack/holographic-consensus-part-1-116a73ba1e1c) of the DAO (the theoretical point of reference denoting the ultimate decision that would be made in ideal conditions) by committing the least amount of resources. There are two challenges at play here: The scalability of the voting process (frequency) and how much the outcome represents the global opinion of the DAO. This phenomenon is known as the [scalability-resilience dilemma](https://medium.com/daostack/holographic-consensus-part-1-116a73ba1e1c). Measures taken to ensure high levels of participation in the voting process hurt the scalability of the process. Too little participation, on the other hand, may result in bad proposals ending up passing.
In order to achieve maximum scalability, the global opinion of the DAO has to be achieved with minimum mobilization of voting power. The holographic consensus (HC) method aims to solve this conundrum through highly representative local decisions. These decisions compete in a prediction market: While the DAO downstakes on each proposal, members of the DAO put money on proposals they think will win. The backers of the winning proposals are financially rewarded while the money DAO pays them is considered as some kind of administrative expense to ensure the efficient working of the DAO. Although it optimizes scalability and resilience, HC is [quite complex and not very democratic](https://medium.com/daostack/voting-options-in-daos-b86e5c69a3e3) as the cost of participation can be steep for some people.
## **Multi-sig voting**
Is it possible to have a happy medium between a centralized authority, which can take swift action but not be trusted to make the right decision at all times, and a decentralized, collective decision-making mechanism, which takes too long and is not scalable? Multi-signature voting technique is claimed to be that happy medium. It involves a group of DAO members signing off on a transaction to take place or a proposal to pass. A predetermined rule stipulates the members who will have a private key and the minimum number of key holders needed for a transaction to be approved. So, in a group with nine private keys, if the preset rule requires six votes for a proposal to pass, six key holders agreeing on a decision will be enough to govern the DAO.
Multi-sig voting definitely comes in handy [in an emergency](https://medium.com/chorus-one/towards-multisig-administration-in-lido-for-solana-342474cac81d) where acting fast can save the day. The cause could be a security hole, a bug, or a much-needed update to the system. Looking for a quorum or running more sophisticated techniques like conviction voting or holographic consensus would be impractical in such cases and could jeopardize the existence of the DAO. Multi-sig voting ensures that necessary measures will be taken swiftly. However, there is always the risk that multi-sig key holders can collude to make decisions against the interests of the wider DAO community.
## **Conclusion**
Decision-making in DAOs take place along a spectrum and is rife with trade-offs. If you want to act fast, you have to give up some of the representative character of your decisions. If you bake new rules and sophisticated mechanisms in the system to immunize it against possible attacks, you sacrifice the amateur, bottom-up zeal that makes a DAO so unique.
The first quarter of the twenty-first century is almost over, and it feels increasingly like the last quarter of the eighteenth century in France and North America. People are full of anger towards the *ancien régime* and have the will to change it, but they are not sure what to replace it with. Back then, some of the brightest minds of the eighteenth century reflected on a new way of governance; some even lost their lives for their ideas after overthrowing the existing rule. Dreaming of a country without a king was one thing; governing such a country was another. The real challenge turned out to be building a new society without a king out of people who had never lived without a king.
People fighting over the best way to make decisions in DAOs know that more is on the line than just who gets to decide in an online community. They know they might be building the society of the future. We better educate ourselves about their ways and techniques. It's a new age, people.
--- START: blog/web3-ico-vc-capital/web3-ico-vc-capital.md ---
# **ICO vs VC: What's Best for Raising Crypto Project Capital**
## **Introduction**
Venture capitalists (VCs) and DAOs tend to have a complicated relationship. VCs may see the latter as an investment opportunity, or DAOs can mobilize to compete with VCs for other investment opportunities. VCs are not the only fundraising options for the DAOs, though. [Initial Coin Offering](https://101blockchains.com/what-is-an-ico-initial-coin-offering/) (ICO) seems to be a viable alternative to a VC. However, it is not possible to claim which one is the better way of raising funds without engaging in a detailed comparison of the two, which we will do in this post.
An ICO is an online crowdsale event carried out to finance a blockchain-based project. In an ICO, a company sells a portion of its crypto tokens to the early supporters of its project. Thanks to ICOs, companies with blockchain-based services can raise capital without [selling equity or debt financing.](https://link.springer.com/article/10.1007/s11187-020-00337-9) To do that, companies issue tokens that deliver benefits related to the project in question. These tokens do not entitle their holders to equity in the company, but rather the prevailing assumption is that their value will appreciate in time.
Raising a lot of money without giving your funders a say in the management of your company may sound like having your cake and eating it. However, ICOs are not the panacea—they come with their pros and cons, may apply to some companies but not to others, and thus are best analyzed in relation to VCs.
## **Pros of ICOs**
### **Speed and relative ease**
There are [two stages](https://101blockchains.com/ico-vs-vc-comparison/) to an ICO: The first stage involves preparation of a whitepaper and a website, which explain to the audience the details of the project. The second stage consists of issuing tokens on a blockchain platform like Ethereum. The whole process is fairly straightforward, and the result can be staggering compared to the modest effort required. That Brendan Eich, former CEO of Mozilla, [was able to raise $35 million](https://techcrunch.com/2017/06/01/brave-ico-35-million-30-seconds-brendan-eich/) for his “Brave” project in under 30 seconds is a good case in point.
On the other hand, VCs want to see a lot more from a startup before pulling the trigger on an investment decision. First of all, there has to be a sound business model in place. A working prototype or an MVP would go a long way in convincing the VCs to put money into a project. Being business people, VC executives like seeing proof of revenue and financial projections instead of mere feel-good stories or pure hype.
### **Lack of geographic limitation**
ICOs take place online. That’s the main reason behind their success in raising huge amounts of money in impossibly short periods of time. Anybody with an internet connection can buy tokens and become an investor during an ICO.
VCs are more geographically limited. Being organizations that depend on social contact and networking, VCs tend to cluster around major technology and finance centers like the Bay Area or London. Founders would be well advised to be close to such places if they want to pitch their ideas to VCs and win their backing.
### **Retaining control**
ICOs do not involve the sale of equity. In that sense, they are [non-dilutive.](https://www.financierworldwide.com/the-wild-west-of-financing-are-icos-the-end-of-venture-capital-fundraising#.YdN0jy_OmRs) The tokens sold do not give buyers any form of ownership over the company issuing them. Tokens entitle their buyers to benefits that may accrue to them if the project succeeds.
In contrast, raising capital from VCs always involves the sale of equity to the tune of 20 to 30 percent of the total company stock. This naturally gives VCs a certain level of control in the way the project is being run, which can be regarded as a loss of control. However, having VCs onboard has advantages, too, which we will delve into below.
## **Pros of VCs**
### **Prestige**
VCs are known to do their due diligence in evaluating investment opportunities. Any startup backed by a VC, in a sense, earns a seal of approval in the public eye. Thanks to this phenomenon, possible failures down the road can be attributed to risk typical of a business venture rather than fraud. This boosts the chances of founders to [make a comeback](https://medium.com/@oddup/icos-vs-venture-capital-a-detailed-comparison-of-the-two-most-popular-investment-methods-48dbecdb80f8) in case of failure.
However, raising money through an ICO involves people who may not have a deep knowledge of the subject, or are just bandwagoners seduced by the hype built around a project. Expectations in an ICO are based more on speculation than facts. We are all familiar with stories of people who considered investing a small sum in Bitcoin before 2014 but did not for some reason, and regret it to this day. These people do not want to miss out on the next big thing, so they may end up investing in projects without the necessary research.
### **Intangibles**
ICOs just bring in capital. That, for sure, is not bad, but for some startups, it may not be enough. Once you have raised the necessary amount in an ICO, you are on your own again, this time with the responsibility to deliver on the promises you made to the token holders.
If you are looking for some guidance, mentoring, or a network that you could leverage to grow your startup after the fundraising stage, VCs are the way to go. In return for selling some equity and giving up some control to the VC executives, you get to pick their brains, and they happen to be quite smart people. VC executives are generally founders of successful startups themselves, have lots of experience under their belts, and know what it takes for a startup to succeed. This sort of experience can come in handy when your startup runs into trouble and needs a course correction.
### **Legality**
VCs are highly regulated companies. A lot of bureaucratic work ensues once a VC decides to invest in a project, which slows down the process to the detriment of the cash-strapped startups. Accounting, reporting, and administrative tasks are all performed according to long-established rules and regulations when a VC gets involved in a project.
On the other hand, ICOs are in the legal grey zone. Whether issuance of tokens should be considered a security sale is debatable and contingent on whether the token is linked to the [operations of the company.](https://thebusinessprofessor.com/en_US/business-transactions/ico-vs-venture-capital-funding) The ambiguity in the legal status of ICOs also poses a serious risk with regards to legal recourse in case there is fraud.
## **Conclusion**
ICOs raised a total of [$35 billion](https://www.mdpi.com/1911-8074/14/12/599) in 2016-2019. The golden age of ICOs lasted [from mid-2017 to early 2018.](https://www.tcmb.gov.tr/wps/wcm/connect/3d4d62d0-7961-4281-8c9d-d06e95f86697/wp2116.pdf?MOD=AJPERES&CACHEID=ROOTWORKSPACE-3d4d62d0-7961-4281-8c9d-d06e95f86697-nGLC4cZ) The total amount raised in ICOs hit a peak in the first quarter of 2018 and decreased over four consecutive quarters until the second quarter of 2019. Failed projects, scams, and the fact that countries like China and South Korea banned ICOs brought an end to the ICO frenzy.
The VC interest in cryptocurrencies has been on a steady increase in the meanwhile. VCs invested around [$30 billion](https://www.forbes.com/sites/rahulrai/2022/01/02/an-overview-of-web3-venture-capital-activity-in-2021/?sh=60ddaec61f16) in crypto startups in 2021, a figure higher than the sum total of the VC investment made up to 2021. The venture capital firm Andreessen Horowitz was a pioneer in backing crypto startups. The [$25 million](https://techcrunch.com/2013/12/12/coinbase-raises-25m-from-andreessen-horowitz-to-build-its-bitcoin-wallet-and-merchant-services/) worth of investment it made in popular crypto exchange Coinbase in 2013 grew to [$11.2 billion](https://www.ft.com/content/cc50c224-0444-418b-b335-782916f8b967) in market valuation by 2021 when the company went public. In June 2021, Andreessen Horowitz announced its [$2.2 billion Crypto III fund](https://a16z.com/2021/06/24/crypto-fund-iii/) that it set up to invest in crypto startups, the biggest crypto fund at the time of the announcement, only to be replaced by [Paradigm’s $2.5 billion fund](https://techcrunch.com/2021/11/15/crypto-vc-firm-paradigm-debuts-monster-2-5-billion-fund/) announced a few months later.
It looks like VCs really took the wind out of the sails of ICOs lately. Despite all the convenience ICOs offer, the legal risks involved, illustrated by the much-publicized scams, must have outweighed the advantages in the eyes of investors. Unless the legal aspects of ICOs get sorted out, and investors are offered some form of protection, VCs are slated to remain the king of crypto investments.
--- START: blog/web3-liquid-democracy/web3-liquid-democracy.md ---
# **How Blockchain can Power Popular Rule**
We are going through an interglacial age, according to some pundits. What was solid and unchanging for a long time is changing and becoming more fluid before hardening again and taking the shape it will preserve for a long time. Looking back from now, it looks like it all started with the [subprime mortgage crisis](https://en.wikipedia.org/wiki/Subprime_mortgage_crisis) and the ensuing [global financial crisis of 2007-2008.](https://en.wikipedia.org/wiki/Financial_crisis_of_2007–2008) Irresponsible financial practices guided by excessive risk-taking burst the housing bubble, threatening the very existence of gigantic financial institutions. The fact that governments bailed out these institutions on taxpayer money brought the inequalities further under the spotlight at a time when families were losing their homes, students were unable to repay loans, and suicide rates were climbing.
What followed was an unprecedented polarization in democratic countries. Feeling once again ripped off by the elites, middle-class people increasingly turned to populist politicians who rode a tide of anger to grab power. Donald Trump in the U.S.A., Victor Orbán in Hungary, Jarosław Kaczyński in Poland, and Narendra Modi in India emerged as leaders masses followed in this tumultuous period.
Another peculiarity about the end of the first decade of the twenty-first century was the rise of social media, content creation, and tech giants that came to dominate the industry. Connecting with online friends and liking and sharing content on social media felt great initially, but we later found out that those tech giants had other motives. Their business models, at least partly, depended on the [collection and monetization of user info.](https://www.security.org/resources/data-tech-companies-have/) One scandal after another revealed that the internet we got in our hands was not what we bargained for.
Today people realize that the internet and online communication are political issues. The struggle for free internet and online privacy is political, too. One of the recent outcomes of this struggle has been Web 3.0. This blockchain-based technology is slated to redefine how data is stored and decisions are made, giving people the [transparency and decentralization](https://medium.com/aerum-technologies/liquid-democracy-and-the-politics-of-blockchain-8017f951f2ba) they dream of.
Decentralized Autonomous Organizations (DAOs) will be central to how people will mobilize in the Web 3.0 era. Nowadays, these organizations seem to be experimenting with a new, promising experiment in democracy that has the potential to give power back to people: Liquid democracy.
Liquid democracy refers to a form of direct democracy whereby participants leverage blockchain technology to express their opinions and enjoy dynamic representation. People use tokens to exercise their votes in liquid democracy. They can even delegate their voting rights to different individuals. These proxies could be trusted friends and family members or domain experts capable of making the right decision about an issue on the agenda. Another interesting aspect of liquid democracy is fractional voting, which involves dividing the voting power among different proxies.
Proxy voting and fractional voting together can take the society closer to a [meritocracy](https://medium.com/decentfund/democracy-3-0-for-the-transparent-world-5a9f1ffad1ad), where decisions will be made by experts. In theory, this could bring about a situation where voting power accumulates in the hands of a handful of [super-proxies](https://harvardtechnologyreview.com/2021/08/18/democracy-for-the-21st-century-using-blockchain-to-revitalize-our-governments/), people trusted by the larger public for their expertise or integrity. There is the risk that these super-proxies might become the new ruling elite of this new way of government, but votes delegated to proxies can always be revoked, eliminating such a possibility. Blockchain technology makes it easy for people to delegate votes to someone, track how they voted, and rescind the authorization if the results are not satisfactory, which promotes accountability.
However, liquid democracy is not without its flaws. One of the biggest concerns about liquid democracy is security. It is all too natural that many people or organizations will stand to benefit from derailing the process. Hacking into the system, manipulating the vote on a proposal about the allocation of funds, and funneling the funds into an account set up for malicious purposes would be very tempting for many actors.
Another risk factor is the transferability of the tokens. Having cast her vote, a person can transfer her tokens to somebody else, who can also vote. Tokens can be [locked](https://blog.colony.io/towards-better-ethereum-voting-protocols-7e54cb5a0119/) until the polls close and votes are tallied to prevent this, but it wouldn’t sit well with people who want to be free to do whatever they want with their tokens.
Still another hurdle limiting the prospects of liquid democracy is the level of technology literacy needed. Although the process could feel fairly straightforward for tech-savvy people, it is still somewhat complicated for most constituents.
Last but not least, the [political elite](https://markvanrijmenam.medium.com/liquid-democracy-how-blockchain-can-improve-the-democratic-process-and-enable-a-liquid-democracy-9914cb86568e) who profit from the current system would do anything to stop liquid democracy from taking hold. Replacing the current corrupt system with a true democracy would spell doom for such people.
Liquid democracy as a concept hasn’t reached the level of maturity necessary for wide-scale adoption yet. Nevertheless, we can expect to see its local implementations at the district and municipal levels. With its fractional voting, liquid democracy can offer exceptional granularity into the preferences of residents of a town, which wouldn’t be possible with a yes-or-no vote.
Liquid democracy is a testament to the fact that blockchain technology is not all about fluctuating cryptocurrency prices. Having emerged at a time when democracy, individual rights, and privacy are threatened, blockchain has the potential to solve the real pains of people. Liquid democracy, even in its relatively limited applications, illustrates how blockchain can be leveraged to transform the power relations we have grown used to in the Web 2.0 era.
--- START: blog/web3-use-cases/web3-use-cases.md ---
# **3 Use Cases for Web3 that Investors are Keeping an Eye on**
2022 was a difficult year for the crypto owners and enthusiasts who were ready to embrace a world running on cryptocurrencies. With the collapse of FTX in November 2022, which was the third largest crypto exchange by trading volume in 2021, and the questions surrounding Binance, most crypto investors seem convinced that this "crypto winter" is about to turn into a "crypto ice age." The FTX story showed that crypto exchanges were no different from the conventional financial institutions they were supposed to bring down. They proved just as [defenseless against bank runs](https://cointelegraph.com/news/what-to-expect-from-crypto-the-year-after-ftx) as banks are. These organizations turned out to be as centralized as their more traditional counterparts and relied on the trust investors put in them despite all the talk about "[zero trust.](https://www.allbrightcollective.com/edit/articles/what-does-the-ftx-collapse-mean-for-the-future-of-web3)"
That's because blockchain is still a relatively new technology that has not matured yet. The last few years have been a period of experimentation, looking for the best way of leveraging this new technology, and some people can't shake off old ways of doing business, preferring to apply this new technology to an old game. Giving up the obsession with the coin prices and [going back to the basics](https://www.cryptonewsz.com/the-future-of-web3-after-the-ftx-saga/) will be key to the future success of Web3. The days of buying a crypto asset with the hope to turn it over to someone for a fortune in a few months are over.
Despite all the scams, unkept promises, and the doom and gloom surrounding crypto and the Web3, some venture capital (VC) firms still keep backing Web3 and blockchain projects. For example, Andreessen Horowitz's crypto fund led two series B rounds last fall, helping raise [more than $90 million](https://news.crunchbase.com/fintech-ecommerce/andreessen-horowitz-blockchain-coin/) in funds. What is it that these institutional investors see but others don't? What still keeps the hope alive in the Web3 domain? It is worth taking a look at the most promising use cases in the Web3 domain.
## **Web3-native games**
Taking video games to mobile took a few years. That seems to be the case with blockchain, too, as game developers are still trying to find themselves in Web3. The first few years of Web3 gaming were dominated by play-to-earn games, in which players can make money by collecting cryptocurrencies or NFT tokens. These games have gone out of fashion, though. Chasing rewards cannot make up for the lack of a fun and immersive storyline in a game.
Today, there is a premium on gaming experience, which game developers in the Web3 domain have failed to provide so far. In the near future, Web3-native games will be expected to deliver the same quality in narrative and playability regular video games offer, and the chance to hoard crypto will not cut it.
The gaming market is a huge one with billions of potential participants. The investors are aware of the size of the total addressable market, and their hope is that the introduction of Web3-native games will win over at least part of the market. Will it be through adapting existing popular games to Web3? This is a possibility, but the real breakthrough will probably come from [decentralized storytelling.](https://www.notboring.co/p/web3-use-cases-the-future) This new concept will let fans add their own characters to a game and build out a universe around a central backbone. We are already familiar with modding and DLCs in video games. The decentralized and composable nature of Web3 will take [modding](https://a16z.com/2022/12/15/big-ideas-in-tech-2023/) to another level.
## **Regenerative finance**
Regenerative finance refers to a [rethinking of the current economic system](https://www.notboring.co/p/celo-building-a-regenerative-economy) and reallocating resources with a view to account for externalities (secondary or unintended consequences). It aims to put a price on negative externalities like CO2 emissions or water pollution. On the other hand, ReFi rewards economic activities that create positive externalities for humanity.
The good thing about ReFi is how it makes utility a core tenet of Web3 once again. ReFi platforms like Toucan already play a role in the [carbon credits trade.](https://newsletter.banklesshq.com/p/how-crypto-is-regenerating-the-world) What they do better than a Web2-based carbon credit system is the [efficiency, transparency, and composability](https://www.flowcarbon.com/knowcarbon/regenerative-finance-is-the-future-of-web3) they introduce to the carbon credits. A ReFi company turns carbon credits into tokens, eliminates intermediaries that demand a sizable chunk of the money involved as a commission fee, and replaces those intermediaries with efficient smart contracts. Removing the brokers from the process saves customers a lot of time and money. Apparently, token-based carbon credits work rather beautifully for the folks who care about their carbon footprint, as Mark Cuban states [in this short excerpt.](https://twitter.com/BanklessHQ/status/1540362738102218753)
Hard tech companies that tackle real-world problems attract more interest from investors, who seek tobacco projects that can bring together public good and profitability. ReFi seems well-positioned to take advantage of this situation. As the fight against climate change intensifies and reducing carbon footprint becomes a bigger concern, what ReFi brings to the table will only get more pronounced, making it one of the engines of Web3.
## **Going mobile**
For some technology to realize its full potential today, some form of mobile-friendliness is a must-have. If Web3 is to become mainstream one day, it won't happen without a plan to take it to mobile, considering that smartphones are much more common than computers in Africa and South Asia. Web3's future hinges on creating real user value, and smartphones have become the main channel for distributing that value. Web3's growth in the mobile market can catapult it from being a domain for tech geeks to becoming mainstream and the new version of the Internet.
Blockchain platform Polygon took a step in that direction in July 2022, [announcing a partnership](https://thedefiant.io/blockchain-phones) with tech startup Nothing to offer its NFTs on the Android-based Nothing Phone. With Polygon itself being a scalability solution for Ethereum, the project's success can help onboard millions of phone users to Web3, as the company's VP of Growth Arjun Kalsy envisions.
Polygon is not the first platform striving to bring together blockchain and smartphones. Just a few weeks before Polygon, Solana revealed its plans to develop its own [blockchain phone called Saga.](https://techcrunch.com/2022/10/19/solana-co-founder-sees-its-web3-phone-as-a-developer-play-to-target-crypto-audience/) These two initiatives have the potential to facilitate crypto payments, turn DAOs into a bigger part of our lives, and bring artists closer to their fanbase through NFTs.
We are still early in the process, and there are problems to figure out, like how [apps on different chains](https://www.coindesk.com/business/2022/07/06/polygon-joins-solana-in-bringing-web3-to-smartphones/) will be accessed. But judging by the potential, if there is one area that deserves pouring resources into, it has to be blockchain-mobile integration.
## **Final thoughts**
At the outset, blockchain owed its popularity to the promise of solving real-world problems like decentralizing the web and the ability to authenticate identity. The market diverged from those concepts and drifted toward crypto speculation, gaining a ponzi scheme-like character. For Web3 to arise from this crypto winter unscathed, utility has to regain its seat as the focal point for Web3 developers. Nail the use cases that solve real problems, and you will have no trouble finding endorsement from investors, be it winter or ice age.
--- START: blog/website-planet-interview/website-planet-interview.md ---
# **Peaka CEO Mustafa Sakalsız Featured in Website Planet**
*Website Planet contacted us for an interview with our CEO, Mustafa Sakalsız. Mustafa took this opportunity to explain Peaka's mission and vision to Website Planet readers. You can find the original version of the interview [here](https://www.websiteplanet.com/blog/codetwo-interview/).*
## **Please present Peaka to our audience.**
We are a startup focusing on no-code technology. Peaka was founded at the beginning of 2021, and after receiving seed investment from ScaleX Ventures, we launched our product in April 2021. Our product was well-received by the no-code community, and we have had thousands of users since our launch. The feedback we received from our users guided us as we adjusted our roadmap and introduced new features.
The Peaka team is a tight-knit group of developers passionate about innovation. The tech leaders among us have years of experience in the telco, banking, and defense industries. Our team has grown by 3X over the last 12 months, with additions of younger, aspiring developers.
Peaka is a no-code platform that allows users to create customer-facing, fully-functional web apps. It comes with a drag-and-drop visual interface so that even people with no technical background can build apps. If you come from a coding background and are comfortable working with code, Peaka lets you inject code or use APIs to extend your app as you like.
Peaka reduces by 10X the time it takes our users to create apps, letting them customize their apps as they see fit in the meantime. We are combining advanced customizability with workflows, which makes our offering unique in the industry.
## **Please describe the story behind the company: What sparked the idea, and how has it evolved so far?**
There were two main reasons that prompted me to seek a no-code software solution. Being a software engineer with 20 years of experience, I never liked the repetitive side of coding. I resented having to code from scratch every time I started a new project because I knew I could spend more time on tasks requiring creativity if I had the tools to take care of the tedious parts for me. Blocks of code arranged like Lego bricks that you can pick and choose from–that’s how I envisioned software technology evolving. No-code helps you do just that.
The other reason behind my interest in no-code was witnessing first-hand how many solid projects and business ideas ended up getting shelved because people didn’t have the technical skills to implement them. People have asked me to become a technical co-founder in their projects for years. I had to turn down those offers because I didn’t have enough time as I always had my own startup projects. However, it was evident that regular people from non-technical backgrounds had a huge technical barrier to overcome whenever they wanted to implement a project. It occurred to me that there was a huge market for the right kind of software that could lower that barrier.
## **What services do you offer?**
Peaka is a no-code platform that offers its customers a seamless end-to-end app development experience. Ours is a unique proposition in the market because no other no-code platform can integrate UI, Data, and Logic the way Peaka can.
In addition to enabling our users to develop customer-facing, fully-functional web apps, we offer startups and SMBs complementary software solutions they can deploy to address the out-of-scope feature requests from their customers. These out-of-scope feature requests create a predicament for startups fighting to gain traction: Turning them down can alienate customers. On the other hand, trying to accommodate them causes the startup to deviate from its roadmap. By enabling business leaders to create the forms, customer portals, internal tools, and partner portals their customers demand, we help them keep their customers happy without pulling resources away from their main line of work.
## **What is the mission of Peaka?**
Peaka's mission is to make the software more accessible to the masses. In Marc Andreessen’s words, the software has been eating the world for more than a decade now. But, the demand for developer talent far outstrips its supply, rendering developers quite expensive to hire for startups and SMBs. I believe that software should not be the sole prerogative of software developers. Regular people should be able to implement their business ideas without the need for technical assistance from developers. This is what we are striving for: Lowering the technical barriers for regular people so that everybody can unlock the power of software for themselves.
## **Who are your typical customers, and what do you think is the main challenge that your product solves for them?**
Our typical customers are solution-driven people who want to create web applications by just picking the features they’re looking for. These are freelancers, founders, and tech enthusiasts, who do not want to get deeply involved with technology to achieve scalability, a slick UI, and a secure backend. At the same time, they want a platform not barely adequate for automating a few tasks but capable of building real full-fledged production-ready applications.
Current solutions in the market are not up to the task–none of them can bring together UI, Logic, and Data on a single platform. They overpromise and underdeliver, which makes paying customers feel shortchanged. These people are disappointed by the scalability problems of the current offerings, and they get stuck using the platforms out there. Having little or no technical skills to solve their problems on their own, no-coders tend to get discouraged easily because of these problems and quit their projects.
Peaka already boasts a fantastic UI. By integrating Logic and Data capabilities into that slick UI, Peaka’s solution becomes unique and unrivaled in the market.
Being a founder myself, I empathize with other startup founders. I know that they want to quickly launch an MVP using templates, high-order blocks, and a little customization. Once they get traction and create some revenue stream, they can always hire more technical and skilled team members to scale up, but first, they need to get over the hump. Peaka will help them do just that.
## **How do you envision the future of your industry?**
I envision another breakthrough in the software industry coming up in the near future. The engine of this leap forward will be the no-code technology.
The most recent breakthrough in our industry was the rise of cloud technology. By introducing abstraction to server infrastructure, cloud technology changed the software stack forever. Today startups can serve the masses because they no longer are burdened by hardware, management, and maintenance costs. The cloud revolution took care of those issues. This abstraction level introduced by cloud technology also gave rise to a whole new ecosystem of developers, startups, and applications.
Today, we need another layer of abstraction on top of cloud services to serve less skilled developers and no-coders. This layer will practically be an a la carte menu of features. It will comprise high-level building blocks that no-coders will use to quickly build applications for their particular use cases. Developers, domain experts, and no-coders will diagnose their problems, dive into that menu of features, and mix and match them to compose an app that will achieve the desired outcome.
This breakthrough will be complemented by the seamless integration of UI, Data, and Logic, which is lacking today. Together, they will give the users the customizable, scalable, and frictionless software experience they seek.
--- START: blog/what-is-a-data-product-marketplace/what-is-a-data-product-marketplace.md ---
# **What Is a Data Product Marketplace?**
A data product marketplace is a practical way for teams to find and use trusted data without turning every request into a ticket. It provides your organization with a governance layer for publishing datasets as reusable products, so consumers can discover what they need, understand what it means, and access them safely.
This is important across all industries, but it is especially critical in financial services. Banks and insurers manage intricate data systems, follow rigorous controls, and operate under high speed expectations. Teams require self-serve analytics and AI preparedness, while risk and compliance functions demand clear evidence, traceability, and uniform definitions.
This guide starts by examining the origins of marketplaces, their connection to data products and data mesh, and what a marketplace entails in practice. It then explores why financial institutions adopt marketplaces, the problems they solve, and how to design them to enable data teams to expand access while maintaining governance.
## **Key takeaways**
+ A data product marketplace turns datasets into reusable products with ownership, shared definitions, trust signals, and controlled access.
+ In banks and and other financial institutions, the biggest wins come from reducing definition drift and replacing manual extracts with governed self-serve sharing.
+ Adoption depends on visible trust signals, such as freshness, quality, lineage, and certification tiers, that align with how teams actually use data.
+ The marketplace needs an operating model. Clear roles, lifecycle gates, and access workflows keep products reliable and audit-ready.
## **Data marketplaces in context**
Most organizations found themselves in a quickly growing data sprawl. The initial steps of giving a small number of experts direct access to databases later gave way to warehouses and lakehouses, curated marts, and dashboards. However, more data assets meant more confusion, more duplication, and more time spent figuring out which table to trust.
Data catalogs were created to record assets and enhance discoverability. While they organized information, they often only provided an inventory overview. Users could locate data, but faced challenges in using it reliably and accessing it securely. This issue became more apparent as self-serve platforms were adopted by more teams.
The marketplace idea addresses that gap. It treats internal data like an offering that must be understandable, reliable, and governable. It packages assets with ownership, definitions, trust signals, and controlled access. The goal is to publish fewer, higher-confidence data products that many teams can reuse. In highly regulated industries, this approach reduces informal sharing and makes governance easier to apply at scale.
## **Related concepts**
A marketplace rarely stands alone. It connects several concepts that often get discussed separately.
+ **Data products** are the unit of reuse. They are curated, documented, and owned offerings built for repeatable consumption.
+ **Data mesh** is an organizational approach, first proposed by technologist Zhamak Dehghani. It pushes ownership closer to domains like risk, finance, claims, and customer operations while maintaining shared standards across the enterprise.
+ A **semantic layer** and business glossary help teams agree on meaning. They reduce metric chaos by making definitions explicit and consistent across tools.
+ A **data catalog** helps teams locate assets and understand technical metadata, lineage, and stewardship. It improves discoverability and provides data users with an inventory of data assets.
+ A **data product marketplace** pulls these threads together into a system for discovery and controlled consumption. It gives teams a place to publish approved products, attach shared definitions, surface trust signals, and enforce access policies. It can work with a mesh approach or a centralized team, but it always needs product discipline. Without that discipline, the marketplace becomes another directory that teams browse once and ignore.
## **Data product marketplace: What is it for?**
A data product marketplace is a platform that simplifies the discovery, sharing, and internal distribution of data products. It offers a governed way to turn your organization’s datasets into searchable, reusable products that teams can discover, trust, and access safely.
Data marketplaces are a great fit for banks and insurers, as these organizations have more data than they can ever hope to use. However, this data is hard to find, hard to use consistently, and hard to share securely across domains, regions, and legal entities in an environment where regulations are becoming more strict. Without a reliable way to facilitate data discovery and sharing, these organizations get bogged down in duplicated pipelines, conflicting definitions, slow delivery, and a steady stream of one-off extracts that increase operational risk.
A data product marketplace addresses this by packaging data as products with what consumers need to use them responsibly: Clear ownership, shared definitions, documentation, signals to gauge quality, lineage context, and granular access controls with auditable approvals. With a data marketplace, users get to leverage approved, certified products to answer specific questions, instead of searching for individual tables or reports.
## **Why now and what changed**
The pressure on Heads of Data is coming from both directions.
On one side, the business expects faster delivery. Teams want self-serve analytics, real-time performance monitoring, and AI-ready data foundations. On the other side, regulatory and operational expectations are rising while data estates are becoming more complex with multiple clouds, multiple warehouses, more third-party sources, and more consumers across the organization.
This combination creates a familiar trap where either you move fast by copying data and loosening controls, or you stay safe by centralizing everything and slowing down delivery. Neither scales.
A data product marketplace offers a third option: Standardize what gets shared, attach governance to the product, and let teams discover and consume data through a controlled system that still feels self-serve. It’s a way to scale access while preserving consistency, privacy, and auditability when hundreds of teams are requesting data in parallel.
## **The problem a data marketplace solves in banks and insurers**
Most financial institutions do not have a data shortage problem. They have a coordination problem.
Data is spread across core systems, warehouses, lakehouses, risk platforms, claims systems, CRM, finance tools, and vendor feeds. Each domain has its own priorities, terminology, and delivery cadence.
Over time, teams build local fixes. Spreadsheets, manual exports, shadow marts, and temporary pipelines become permanent. The business gets answers, but the organization pays repeatedly through duplicated work, inconsistent reporting, and increasing operational risk.
The most visible symptom is definition drift. Terms like “customer,” “active account”, “written premium,” or “loss ratio” can mean different things depending on the team, the source system, and the filters applied. Even when teams agree on the word, they may not agree on the logic. This creates friction between finance, risk, compliance, and analytics.
The second symptom is access gridlock. Sensitive fields require protection, approvals, and evidence. When the safe path is slow, teams create unsafe paths. They export files, email extracts, widen permissions, or copy restricted datasets to places they should not be.
A data product marketplace is designed to solve these two problems together: it makes data easier to use and easier to govern without forcing every request through a ticket queue.
## **Data product marketplace vs data catalog**
A data catalog is a registry of data assets such as tables, dashboards, reports, pipelines, and their metadata. It is essential, but it often stops at listing what exists. It helps you find assets and understand their origins, but it does not always make data consumption safe and repeatable.
A data product marketplace goes a step further. It is designed to facilitate consumption and controlled sharing. In a marketplace, what gets published is not just an asset, but a data product with clear ownership, shared definitions, quality expectations, and an access model that can be approved, provisioned, and audited.
In practical terms:
+ **Data catalog:** “Here is the customer table and where it comes from.”
+ **Data marketplace:** “Here is the Certified Customer Profile product, here are the definitions it uses, here is its SLA and quality status, and here is how to request access with audit logging.”
Most financial institutions need both. The catalog organizes and documents the landscape. The marketplace operationalizes trust, standardization, and secure access at scale. If your catalog is underused, the missing piece is often productization and governance that supports real consumption.
## **What makes data a product**
Data becomes a product when it is packaged for reuse, not just exposed for access. A data product is a managed offering with a clear purpose and the supporting context consumers need to use it correctly, as opposed to a dataset, which is usually a raw or curated asset that exists in a warehouse or lakehouse.
A data product has a named owner, a defined scope, and the context consumers need to use it correctly. That includes documentation, quality expectations, freshness targets, and clear rules about what can change and how consumers will be notified. Most importantly, it includes an access model that supports safe self-serve rather than informal sharing.
In a marketplace, the goal is to publish fewer, higher-confidence products that many teams can rely on. This reduces duplicated pipelines and stops every new project from starting with a fresh round of data interpretation.
## **Shared definitions and consistency**
In financial services, inconsistency rarely looks like a broken pipeline; rather, it's two correct reports that disagree. The root cause is usually semantic. Fields and metrics carry different logic across teams, regions, and legal entities. Even small differences, such as active status logic or time window rules, can invalidate comparisons and slow decision-making.
Shared definitions solve this by making meaning explicit and reusable. A marketplace supports semantic alignment by tying business terms, metric logic, and data fields together in one place. It provides consumers with a consistent language across domains such as risk, finance, claims, underwriting, and customer operations. It also reduces the need for each team to rebuild definitions inside dashboards or spreadsheets.
Consistency is not about enforcing one definition for everything. It is about making definitions discoverable, approved, and comparable. When variations are necessary, they should be intentional and clearly labeled so teams can choose the right one with confidence.
This is a core reason marketplaces outperform ad-hoc documentation and tribal knowledge.
## **Trust signals for freshness, quality, lineage, and certification**
Discovery alone does not create adoption. Trust does. In regulated environments, trust must be earned with signals that are visible, current, and easy to interpret.
A strong marketplace surfaces operational trust signals directly on the product. Freshness tells consumers whether the data is up to date and whether delays are known. Quality signals include checks for completeness, validity, duplication, and reconciliation with source systems. Lineage explains where the data came from and which transformations shaped it, which helps teams assess suitability and troubleshoot issues faster.
A data marketplace manages governance through certification tiers. In this framework, an initial draft product allows for exploration. Once approved, a data product can be shared with specific controls. Only a certified product can be used for high-stakes reporting with stronger requirements and ownership commitments.
These signals reduce back-and-forth between producers and consumers and limit accidental use of unreliable assets.
## **Secure sharing with granular access controls, approvals, and auditability**
Financial institutions need self-serve access that still behaves like a controlled system. A marketplace enables this by combining granular access policies with workflows and logging that satisfy governance requirements.
Granular controls can restrict access by role, business unit, legal entity, region, and sensitivity level. They can also limit which columns are visible and which rows a user can see. This matters when a single product serves many teams, each with different entitlements.
Auditability completes the picture. The marketplace should record who requested access, who approved it, what was granted, and when it was used. This makes reviews and recertification practical and helps reduce over-permissioning over time.
When secure sharing is built into the marketplace, teams stop relying on manual extracts and overly broad access grants. They get speed without losing accountability.
## **Quick self-assessment to see if you need one**
You are a strong candidate for a data product marketplace if most of these are true.
+ Teams spend significant time searching for data or validating it after they find it
+ Different departments report different numbers for the same KPI and reconciliation is frequent
+ Access requests are slow, manual, or frequently bypassed through exports
+ Sensitive data is shared through manual exports or copied into uncontrolled environments.
+ The same datasets are rebuilt repeatedly for similar use cases across business units.
+ You lack a clear ownership model for shared data assets
+ Auditors ask for evidence of who accessed sensitive data and why
+ You want self-serve analytics and AI readiness without relaxing governance
If you recognized your organization in several bullets, a marketplace can turn ad hoc sharing into a governed system that still supports speed. The biggest indicator is not how much data you have but how often teams rebuild the same logic, argue about definitions, or move data through informal channels to get work done.
## **Conclusion**
A data product marketplace helps financial institutions scale data usage without sacrificing governance. It brings structure to what gets shared and how it is consumed, so teams can move faster with fewer inconsistencies and fewer risky workarounds.
The best approach to implement a data product marketplace is to start small with a handful of high-impact products, make trust and access controls obvious, and measure reuse. With the right operating model behind it, the marketplace becomes a durable foundation for analytics, reporting, and AI initiatives across the organization.
Peaka’s data marketplace is built to turn datasets into searchable data products, allowing teams use and securely share governed data with clear definitions and granular access controls.
[Book a demo](https://calendly.com/peaka/demo) to see how Peaka powers a data product marketplace for enterprises.
--- START: blog/what-is-ai-ready-data/what-is-ai-ready-data.md ---
# **What Is AI-Ready Data?**
At its core, AI-ready data is exactly what the name implies: data that’s ready for AI use. In the past, this typically meant aggregated warehouse data from a source such as Snowflake or Google BigQuery. Unfortunately, that’s proven false, as teams are wiring LLMs and agents into existing pipelines and finding that clean, warehoused data still produces incorrect answers, slow agents, and broken integrations.
The change isn't in the data; it's in who's consuming it. Agents spin up ephemerally mid-loop, and the systems they query are too static to keep up. AI-ready means data that an agent can access and reason about, rather than a meticulously tuned, human-curated pipeline upstream.
## **AI-ready vs. analytics-ready**
It’s easy to conflate AI-ready data versus analytics-ready data. While they might share similar strategies, they are fundamentally different problems.
Analytics-ready data is shaped for human analysts who can ask in #data-help what flag_v2 means. AI-ready data has to be self-describing, like a queryable data catalog, because the consumer has no institutional memory.
There are some concrete contrasts between these data classes.
+ **Latency:** Hourly ETL is fine for analysts. An agent answering 'what's my balance?' needs the answer now.
+ **Schema stability:** Analysts adapt to schema drift, whereas prompts and agents silently stop working.
+ **Access pattern:** BI tools hit a warehouse, while agents need narrow, permissioned, query-time access across many systems.
+ **Trust:** An analyst can use judgment when facing an outlier; an LLM confabulates confidently on bad inputs.
{{ resize_image(path="../static/assets/images/blog-images/mathew/ai-ready-data-vs-analytics-ready-data.png", width=759, height=400, op='fit_width', alt="a visual displaying how AI-ready data compares to analytics-ready data") }}
Context that a human analyst would hold in their head has to be encoded directly in the data.
## **The eight properties of AI-ready data**
There are a few tenets that make data AI-ready, many of which are non-negotiable and all of which are necessary at scale. They reduce to the following buckets:
1. **Accessible at query time.** AI-ready data is reachable through a stable, documented interface — SQL, REST, or MCP — that doesn't require human refresh cycles.
2. **Semantically described.** AI-ready data has table/column descriptions, metric definitions, and entity meanings encoded as metadata in a semantic layer so the AI can read them at query time.
3. **Fresh, or knowingly stale.** AI-ready data either reflects the current source state or the staleness is explicit and machine-readable.
4. **Governed at the row/column level.** AI-ready data has row- and column-level security permissions enforced when the AI queries, not assumed because "the agent runs as a service account."
5. **Joinable across sources.** AI-ready data can combine data from multiple sources in a single query, such as Salesforce + Postgres + Stripe. That’s possible at runtime, without the need for days of engineering work.
6. **Schema-stable or versioned.** AI-ready data is dynamic but also versioned through data contracts so that changes don't silently brick the agent.
7. **Auditable.** Every AI-driven read is logged with who/what/when, providing data lineage so a bad agent action can be traced.
8. **Right-shaped for the use case.** AI-ready data is not a single shape. Data shapes need to be dynamic. RAG wants chunked and embedded text, analytical agents want tables, transactional agents want APIs.
These issues often cause developers to scramble to build a data warehouse or vector database that’ll address them all. However, that is the wrong approach.
## **Where implementation goes wrong**
Most teams fail by trying to solve a nearby problem instead of the actual problem. Typically, they reach for vector databases first.
Vectors are right for certain use cases, specifically unstructured retrieval such as querying docs, transcripts, tickets, etc. They're incredibly inefficient for "*what's the MRR of customer X.*" That's a SQL question in a chatbot disguise. Most enterprise AI questions are structured-data questions in natural language. Forcing them through a vector DB produces hallucinations and worse latency.
Teams also assume the warehouse needs to go. Existing warehouses like Snowflake or BigQuery serve analytics well and don't need to be discarded. The problem is treating them as the sole layer for AI access. Copying all operational data into yet another system makes it staler, more expensive, and fragments governance. Agents additionally need live operational data (Salesforce, Stripe, Notion, prod Postgres) that a back-dated snapshot can't provide. The answer is a dynamic layer on top of your existing systems, including your warehouse, that enables query federation in real time rather than replacing any single source.
Lastly, teams almost always underestimate the semantic “cleanliness” gap. A pristine Snowflake table with a column named `attr_17` is unusable to an LLM. The bar is clean, accessible, semantically described, and governed data. Most stacks have one or two of those; few have all four.
## **Data virtualization produces AI-ready data**
One effective way to produce AI-ready data is data virtualization.
This method enables AI systems to seamlessly connect to a virtualized data layer that sits atop all your sources, including data warehouses such as Snowflake or BigQuery, and operational systems, rather than bypassing your existing infrastructure. The virtualized data layer integrates with primary data sources (Stripe, Postgres, Salesforce, your existing warehouse, etc.) and provides federated access at runtime.
This virtualized layer, meanwhile, queries the underlying sources and manages a data cache to balance speed with freshness. There is no ETL pipeline; data is synced automatically and on demand using a zero-copy approach, without delay.. The result is a single interface for every source, with the capacity to join data across sources.
Another advantage of a virtualized layer is that governance is immediate. The virtualized data layer will use the user’s credentials to access content, thereby avoiding unauthorized access through the pre-existing access control plane.
These advantages are exactly why we built Peaka. Peaka is a dynamic layer on top of your existing data sources—warehouses, operational systems, and SaaS tools alike—providing a single SQL interface with permissions and semantic context attached at query time.
## **Final thoughts: Checklist - is your data AI-ready?**
To make things easy, consider the following questions. If more than two of these questions are answered with a no, then your data is not AI-ready.
+ Can an AI agent reach this data through a stable, documented interface?
+ Does the schema include human-readable descriptions of every table and column?
+ Are business metrics defined once, somewhere that the AI can read?
+ Are permissions enforced at query time rather than assumed?
+ Can the AI join this data with other systems without a multi-month integration?
+ Is every AI-driven read logged?
+ Does freshness match the use case?
+ Is there a schema/semantic contract, enforced by a schema registry, that the AI can rely on?
If you’re looking to make your data AI-ready without a data warehouse, [book a demo](https://calendly.com/peaka/demo) with Peaka.
--- START: blog/what-is-data-integration/what-is-data-integration.md ---
# **What Is Data Integration?**
Data integration is the process of combining and harmonizing data from different sources to provide a unified view of performance. This amalgamation enables organizations to access, analyze, and derive insights from disparate datasets seamlessly. Traditionally, this process has involved extracting, transforming, and loading (ETL) data to ensure compatibility and consistency across platforms. However, novel approaches like data virtualization and zero-ETL can eliminate the transformation stage, simplifying the overall process.
## **Key Takeaways**
+ **Improved decision-making:** Data integration helps create a unified view of various data sources, enabling informed choices for business growth.
+ **Enhanced operational efficiency:** By eliminating data silos and streamlining data flow, businesses can automate workflows and reduce manual efforts, leading to increased efficiency.
+ **Better customer insights:** Combining data from multiple touchpoints provides a deeper understanding of customer behavior and preferences, making way for targeted marketing and improved customer experiences.
+ **Data quality and consistency:** Data integration ensures data quality through standardization, cleansing, and deduplication, minimizing errors and improving data reliability.
+ **Faster time-to-market:** Access to relevant data through integration accelerates product development cycles and facilitates quicker responses to market changes.
## **How Data Integration Improves Business Efficiency**
Businesses can increase efficiency, simplify operations, and make better decisions by [integrating data](/integrations/).
Data integration generates a comprehensive understanding of business processes, customers, and market trends. Data integration also empowers enterprises to leverage their multiple data sources effectively, spurring innovation and identifying opportunities to gain an advantage over their competitors. Furthermore, bad data is also a financial burden, with an average of nearly [$10 million lost every year](https://analytics-iq.com/the-high-cost-of-bad-data-and-data-quality-issues/#:~:text=According%20to%20Gartner%2C%20businesses%20lose,to%20potentially%20cripple%20a%20business.).
Leveraging data integration unlocks a unified view across disparate data sources, empowering data-driven decision-making with timely and [actionable insights](https://www.quora.com/What-are-some-great-words-to-make-a-sentence-more-authoritative). By streamlining operations and eliminating data silos, data integration fosters seamless information flow, [optimizing efficiency](https://textcortex.com/post/how-to-change-tone-in-writing-easily). This approach ensures data accuracy and consistency, mitigating the risks associated with fragmented data and [erroneous decision-making](https://textcortex.com/post/how-to-change-tone-in-writing-easily).
## **Top 7 Benefits of Data Integration**
[Data integration empowers businesses](/blog/data-integration-architecture/) to leverage data from various sources to have a unified view of their operations, customers, and markets, enabling better decision-making for business growth. By consolidating data silos, organizations can make informed choices to drive profitability.
For instance, a retail company integrating data from sales, e-commerce, and CRM systems can analyze customer behavior, sales trends, and inventory levels to optimize pricing strategies, personalize marketing campaigns, and manage inventory more effectively.
### **1. Informed decision-making**
Data integration enables organizations to aggregate and harmonize data from multiple sources, providing decision-makers with a comprehensive and unified view of their operations, customers, and markets. Consolidating disparate data sets makes it easier to make informed decisions to drive growth and profitability.
For example, if a retail chain integrates data from its point-of-sale systems, e-commerce platforms, and customer relationship management (CRM) software, the company can analyze sales trends, customer behavior, and inventory levels. The retailer can then optimize pricing strategies, tailor marketing campaigns, and manage inventory more effectively.
### **2. Improved operational efficiency**
Data integration eliminates data silos and enables seamless data flow across various systems and departments within an organization. This simplifies processes, reduces manual effort, and enhances operational efficiency. Businesses can reduce errors and delays by automating data workflows and guaranteeing data consistency.
If a healthcare provider integrates data from electronic health records (EHR), billing systems, and medical devices, clinicians can access patient information quickly and accurately, leading to faster diagnoses, better treatment outcomes, and improved patient care. Additionally, streamlined billing processes reduce administrative overhead and improve revenue cycle management.
### **3. Better client insights**
Combining data from multiple touchpoints, such as sales transactions, social media interactions, and customer service inquiries gives you a deeper understanding of your customers. Analyzing integrated customer data allows you to uncover valuable insights into customer preferences, behaviors, and sentiment, enabling personalized marketing, targeted sales efforts, and enhanced customer experiences.
For example, a telecommunications company integrates data from its customer support systems, billing platforms, and social media channels. Consolidating customer data across these sources reveals actionable insights into customer satisfaction, service issues, and product preferences. The telecom provider can then proactively address customer concerns, tailor its offerings to meet customer needs and improve overall customer satisfaction and loyalty.
### **4. Data quality and consistency**
Data integration ensures quality and consistency by standardizing formats, cleansing and deduplicating data, and enforcing governance policies. Businesses can minimize errors, reduce data redundancy, and maintain data integrity across the enterprise.
If a financial services firm integrates data from various sources, including transactional systems, customer databases, and external market data feeds, the company validates and standardizes financial data. This enables reliable financial reporting, regulatory compliance, and risk management.
### **5. Faster time-to-market**
Data integration accelerates the [development and deployment of new products](https://www.hotjar.com/product-managers/optimizations/), services, and features by providing timely access to relevant data. Integrating data from research and development, manufacturing, and marketing departments streamlines product development cycles and identifies market opportunities, resulting in a quick response to changing customer demands.
For example, a software company integrates data from customer feedback forums, beta testing platforms, and competitor analysis tools. This integrated ecosystem enables the company to gather valuable insights into customer needs, preferences, and market trends. The software developer can now prioritize product features, fine-tune user experiences, and release updates more quickly, gaining a competitive edge in the dynamic software market.
### **6. Scalability and flexibility**
[Data integration solutions](/blog/self-service-data-integration/) are scalable and flexible, allowing organizations to adapt to evolving business requirements and technological advancements. Whether expanding into new markets, integrating with third-party systems, or migrating to cloud-based platforms, businesses can easily manage their data ecosystem.
When multinational corporations integrate data from their subsidiaries, partners, and suppliers, the company consolidates financial reporting, standardizes operational processes, and achieves economies of scale. As the company grows and diversifies its operations, it can easily adapt its data integration strategy to accommodate new data sources and business needs.
### **7. Innovation and competitive advantage**
Data integration unlocks the full potential of organizational data, enabling businesses to innovate, differentiate, and gain a competitive edge in the marketplace. It enables you to uncover new insights, identify emerging trends, and capitalize on untapped opportunities for growth and expansion.
If a leading e-commerce platform integrates data from its website, mobile app, and social media channels, [advanced analytics](/blog/why-use-saas-analytics-tools/) and machine learning algorithms can personalize product recommendations, optimize pricing strategies, and predict customer behavior. This data-driven approach enhances the shopping experience, increases customer engagement, and strengthens the platform's competitive position in the fiercely competitive e-commerce market.
## **The Bottom Line**
Data integration empowers organizations to maximize the potential of their data assets, driving innovation, efficiency, and competitive advantage. In today's data-driven world, organizations can enhance customer experiences, boost operational performance, and make better decisions by utilizing data integration.
Partner with Peaka to meet your data analytics needs with its state-of-the-art zero-ETL approach, offering hassle-free data integration without having to copy or move your data.
See Peaka’s [growing library of custom integrations](/integrations/).
--- START: blog/what-is-micro-saas/what-is-micro-saas.md ---
# **What is Micro SaaS?**
If you are keeping tabs on the news from the software business, you must already know that the no-code world has been buzzing with activity lately: New products being launched every week, venture capitalists signing seven-, eight- and even nine-figure cheques to get on the bandwagon and co-founders giving interviews like victorious generals. For someone receiving daily newsletters on the technology and software industry, it is like watching the movie stars passing by on the red carpet before the Academy Awards.
## **The cold hard facts of the SaaS world**
However, there is a catch. Almost none of the [SaaS businesses](/blog/b2b-saas-analytics-tools/) are turning a profit. They manage to attract funds thanks to their exponential growth rates, but nearly all of them, including the media darlings such as Salesforce and ones with a cult following like Spotify, are [bleeding money](https://blossomstreetventures.medium.com/operating-losses-in-saas-are-huge-871eda79a5ec).
Taking a look at the income statements of most SaaS businesses would reveal that these businesses are operating with negative net incomes and negative gross margins. Being incapable of turning a gross profit and having astonishingly high levels of cash burn rate prolong their payback periods, throwing shade on their status as investments. This reminds us of the fact that having a good business idea and turning that idea into business are two different things. A business idea may be promising, but whether it can take off before the money runs out is another story.
Because of the brightness of the spotlights, it might be difficult for us to truly grasp the financial situation these giants are in. But once you understand how deep your pockets should be to survive with operating margins of -50 or -100 percent, these companies lose some of their glamor. The figures are so high that a regular person can have a hard time relating to those stars of the software business and their stories. The situation begs the question, "*Is the startup business really an all-or-nothing game where you either conquer the world or go bust?*" There must be a more human side to software entrepreneurship.
That side happens to be micro SaaS companies. They are the middle ground for regular people who do not have deep pockets to invest huge sums or charisma to attract investment right away. People of modest means pursuing modest goals. People who do not dream of a world empire but would be more than content with a small plot of land they could call theirs.
As we reconsider our priorities in life in a post-pandemic world, understanding how micro SaaS companies work can show us another way into the future. So, let's take a closer look at this more relatable breed and its endeavors.
## **What is micro SaaS?**
Micro SaaS, a term coined by the entrepreneur [Tyler Tringas](https://www.youtube.com/watch?v=i3d1asTrWUQ), refers to a small SaaS business run by a solo entrepreneur or a team of fewer than five people. These SaaS businesses focus on solving [a particular problem for a small customer base](https://tylertringas.com/1-what-is-micro-saas/), addressing a small, underserved niche in a larger market segment. The business idea central to their efforts could be as simple as a new calendar app, a local grocery service, or an app to keep track of your personal finances.
Micro SaaS companies owe their success to their razor-sharp focus and impeccable execution. The core idea is executed so effectively that customers get hooked immediately. Micro SaaS apps tend to be lean, shying away from offering a plethora of features that result in a bloated feeling. The micro SaaS business model is the embodiment of the famous maxim by [Paul Graham](https://www.techinasia.com/airbnb-co-founder-brian-chesky-make-100-people-love-product):
> *“It’s better to have 100 people [who] love you than finding a million who just sort of like you.”*
Micro SaaS startups aim to build a devoted customer base by offering them the perfect solution for their pains. They then strive to attain sustainable and predictable growth rates by capitalizing on their customers' devotion. In that regard, the almost manic interest big shot SaaS businesses show in increasing user numbers is non-existent in their little brothers.
Not prioritizing exponential monthly growth, micro SaaS startups can ignore the vast set of [SaaS metrics](/blog/saas-business-metrics/) regular SaaS startups should monitor. Customer churn rate is the primary SaaS metric they should keep an eye on. Goals like slashing churn and improving customer retention come to replace growth as the critical goals for micro SaaS companies. It is possible to achieve high retention rates in 3 simple steps:
+ **Maintaining a more personal communication with customers.** You need to know your customers well enough to offer them solutions tailored to their specific needs.
+ **Removing friction as much as possible.** This will reduce time-to-value so that your customers will get to appreciate the value you are offering before they start feeling lost within the app.
+ **Being accessible and ensuring customer success.** Owning up to your mistakes and correcting them as soon as possible go a long way toward building trust and earning customer loyalty.
A high customer retention rate is vital for the long-term health of a micro SaaS startup. The longer the bond with customers lasts, the more opportunities for cross-selling and upselling there will be. This will help maximize customer lifetime value for a micro SaaS startup.
Lacking funds and human resources to scale until they become sustainable businesses, micro SaaS startups have to leverage the SaaS ecosystem to solve their problems. Today, services like [hosting, payment processing or email marketing](https://medium.com/building-micro-saas/bootstrap-a-saas-business-with-these-services-fa40983c0586) are readily available in the market. All one has to do is pick and choose according to the needs of the business.
## **Pros of micro SaaS**
### **No need for outside funding**
Micro SaaS ideas are not as ambitious as the ones that set out to transform the way the world operates. Their goals are limited to starting a business with the means at hand and driving organic growth at a more leisurely pace. As they rely on word of mouth rather than sales and marketing, micro SaaS startups can avoid the two main sources of high operating expenses regular SaaS businesses have to budget for.
Most of the time, you won't have to spend months or years on your micro SaaS idea before it takes off and starts making money for you. The return on your modest investment will bear fruit more quickly than a big SaaS project, which will boost your motivation to reach new heights.
### **Better fit for beginners**
The pressure to succeed is not too big with micro SaaS companies because of the modest amount of money involved. Additionally, micro SaaS customers tend to be more tolerant of mistakes as long as the effort is there to make up for them. Hence, inexperienced beginners have a chance to learn and grow with their business, unlike SaaS giants, where a single mistake can cost millions of dollars.
### **Greater autonomy**
Some micro SaaS projects start as side hustles and only become full-time jobs when they prove their worth. A slowly growing micro SaaS business that generates enough income can save an entrepreneur from his office job, affording him [flexible work hours](https://thearjunajith.medium.com/the-growth-of-micro-saas-businesses-59dd6048879f) and more freedom as to wherever he wants to live and work. It may even serve as [passive income](https://tylertringas.com/1-what-is-micro-saas/) since it won’t demand frantic attention to every detail like bigger SaaS projects.
## **Cons of micro SaaS**
### **Limited customer base**
The success of micro SaaS businesses is closely linked to how well they understand their customers. The small size of their customer base makes it easier to talk to customers, understand their jobs-to-be-done, perfect the solution devised, and solve problems as soon as they arise.
However, the limited size of the customer base also works against micro SaaS companies by putting a cap on their potential. Doing away with this strategy and expanding into different segments naturally means the loss of the personal touch that makes these companies so special in the eyes of their customers.
### **Limited revenue potential**
Lack of exponential growth means that it is unlikely for a micro SaaS to reach the heights some SaaS giants have scaled. Still, there are many examples that have achieved five- or six-figure MRRs, like [SuperLemon](https://apps.shopify.com/whatsapp-chat-button) and [Storemapper](https://www.storemapper.com/), respectively.
## **Final thoughts**
After weighing the risks and opportunities, assessing the ROI, and comparing it with the effort needed to get a micro SaaS startup up and running, one cannot help but think that this business model will only get more popular among white-collar people in the future. Reevaluating their life choices since the beginning of the global pandemic, these people will find in micro SaaS the purpose they feel they lack in their lives.
And then, there is the promise of a five- or six-figure monthly income, which would be quite a raise for someone coming out of his 9-5 work schedule. Not too shabby for us regular folks, is it?
--- START: blog/what-is-the-modern-data-stack/what-is-the-modern-data-stack.md ---
# **What is the Modern Data Stack?**
## **Introduction**
In this data-rich world, being able to access, unify, and utilize data, and turn it into information can give an organization a lasting advantage over competitors.
The modern data stack has become the foundation of this data-driven revolution, from small businesses to global enterprises.
It is more than a buzzword; it represents a paradigm shift in how organizations deal with, analyze, and exploit data.
In today’s article, we will provide answers to questions such as **what is the modern data stack**, what are its benefits and why should you care.
## **What is the modern data stack?**
At the heart of our article lies a fundamental question: [What is the Modern Data Stack](/blog/zero-etl-vs-modern-data-stack/)?
A **modern data stack** is basically a collection of tools, technologies, and processes that enable companies to collect, store, process, and analyze the collected data.
The modern data stack is therefore a progression of traditional data processing approaches meant to tackle modern-day data complexities.
These are challenges that plagued a traditional data setup with data silos, making it hard to access information for real-time analysis.
***In contrast, the modern data stack unifies and simplifies all aspects of the data lifecycle.***
It is an intricate combination of many constituent parts such as data warehouses, ETL (Extract, Transform, and Load) processes, and [data visualization platforms](/blog/data-visualization-with-looker-studio-integration/).
Now that we've defined what a modern data stack is, let's delve into the myriad of benefits it offers to organizations:
### **1. Efficiency**
The modern **cloud data stack** is able to make the data integration processes more seamless and be more effective, requiring less time and effort to extract insights. Such efficiencies enable organizations to act in a more timely and data-informed manner.
### **2. Scalability**
The modern data stack can scale as quickly as you need it for your growing business. It adjusts to data volumes, allowing systems to work without any difficulty, even under more load.
### **3. Real-time insights**
The ability to process data in real-time translates into better speed for business actions where organizations can move fast and make decisions based on the current information available.
### **4. Data integration**
The modern data stack also helps break down the silos between different data sources, ensuring that all your data can be accessed and analyzed together.
### **5. Cost efficiency**
Although there might be a need for an initial investment in a modern data stack, the resultant savings in the long run are significantly high. The increase in both efficiency and scalability brings about lower operational costs.
### **6. Security**
Modern data stacks involve many security precautions for safeguarding sensitive data; thus, using them to handle data is the safer option.
### **7. Accessibility**
The easy-to-use interfaces and visualization tools make data available to even non-technical staff, thereby democratizing data access throughout an organization.
### **8. Competitive advantage**
Organizations that embrace the modern cloud data stack stand at a competitive advantage as they can respond fast to changing market dynamics and emerging opportunities.
## **What are the components of the modern data stack?**
{{ resize_image(path="../static/assets/images/blog-images/flatart/saas-written-floor-and-laptop.png", width=780, height=518, op='fit_width', alt='man working on laptop and saas written in the back') }}
Having established a clear answer to the question of what a modern data stack is and what it brings along, let’s highlight its major parts.
A modern data stack is typically a combination of a few tools and technologies that have different roles in facilitating the process of analysis.
### **1. Data sources**
Data sources form the basis of the modern data stack.
These could be internal sources such as databases within your firm, or external ones including web services, social media, and third-party data providers.
Raw data from these sources flows into your data stack.
### **2. Data integration tools**
{{ resize_image(path="../static/assets/images/blog-images/flatart/peaka-1.png", width=780, height=366, op='fit_width', alt='peaka homepage') }}
The transformation is done by [data integration tools](/blog/top-data-integration-tools/), which convert raw data into a form suitable for analysis.
These tools process the data, making it ready for use.
[Peaka, a no-code data integration tool](/), comes to your aid at this point! By checking out the features offered by Peaka, you can create the data stack that will serve your data integration needs!
### **3. Data warehouses**
Data warehouses serve as the central repository for your integrated and transformed data.
These cloud-based or on-premises storage solutions enable efficient data storage and retrieval.
Data warehouses are optimized for analytical queries, making them essential for performing complex data analysis and generating insights.
### **4. Data transformation and ETL**
ETL (Extract, Transform, Load) tools are vital components in the data processing pipeline.
They manage the transformation of raw data, carrying out various tasks such as filtering, aggregation, and data enrichment to make the data ready for analysis.
ETL tools ensure that the data fits the schema of your data warehouse and follows data quality standards.
### **5. Business intelligence tools**
Business Intelligence (BI) tools provide the interface through which users can interact with and derive insights from the data stored in the [enterprise data warehouse](/blog/best-enterprise-data-warehouse/).
These user-friendly tools allow you to create reports, build [real-time dashboards](/blog/data-visualization-with-tableau-integration/), and [visualize data](/blog/data-visualization-with-metabase-integration/), enabling non-technical users to explore data and make data-driven decisions.
### **6. Data orchestration**
Data orchestration tools are responsible for managing the flow of data within the Modern Data Stack.
They automate and schedule data movements, transformations, and other processes to ensure a streamlined and efficient data pipeline.
These tools help orchestrate complex data workflows and are pivotal in maintaining data consistency and reliability.
### **7. Data governance and security**
Data governance and security tools are paramount in ensuring the reliability and security of your data.
They help enforce data governance policies, ensure compliance with data privacy regulations, and maintain the confidentiality and integrity of your data.
These tools control user access, authentication, and authorization, making sure that sensitive information is protected from unauthorized access and breaches.
## **Final thoughts**
Modern data stack: In the era of big data, it’s finally a tool that makes sense. This changes how data is stored and accessed, making it more open and effective as well as better protected.
In conclusion, it is necessary to use and know the modern data stack. This is not just an IT improvement, but a step towards a future characterized by data dependency.
***This change can no longer be ignored as doing that can devastate an organization, and the advantages are so obvious.***
Next time you’re wondering what the modern data stack is, think of it as a bridge between today’s data and tomorrow’s success. So, embrace it and set out on the journey to make data your best friend in the future.
--- START: blog/what-is-zero-etl/what-is-zero-etl.md ---
# **How to Get Started with Zero-ETL**
Zero-ETL (extract, transform, and load) is an approach to data integration that eliminates the need for complex and time-consuming ETL processes. As organizations deal with rapidly growing data loads and need faster access to business insights, Zero-ETL provides a more streamlined way to make data readily available for analysis.
## **What Is Zero-ETL?**
Zero-ETL represents a shift in data processing strategies. Rather than moving data from source systems into a data warehouse and transforming it along the way like in traditional ETL, zero-ETL integrates data in its raw format directly from where it resides.
[Zero-ETL eliminates lengthy data transformation](https://atlan.com/zero-etl/) and movement and allows the data to be available faster for analytical and operational use cases. Technologies like data virtualization and data lakes make it possible to query data in its native format directly from source systems.
Key characteristics include:
+ There is](https://atlan.com/zero-etl/) no data movement between systems
+ No transformations during data integration
+ Ability to directly query raw data at the source
+ Leverages technologies like data virtualization and data lakes
+ Optimized for analytics and operational use cases
Implementing [zero-ETL offers faster access to business insights](/blog/zero-etl-data-integration/), flexibility, and efficiency.
## **Challenges with Traditional ETL**
Though ETL processes play an indispensable role in data processing pipelines, they come with considerable challenges:
### **1. Time-consuming**
The different steps of ETL extracting from sources, transforming, and loading into target databases are complex and take substantial time. This delays the availability of actionable insights.
### **2. Costly to Scale**
As data volumes grow, traditional ETL infrastructure has to be continually expanded to handle bigger workloads. The costs of hardware, software, maintenance, and skill sets required can spiral quickly.
### **3. Data Quality Issues**
Data that needs to move through multiple systems and undergo transformations presents more opportunities for errors to creep in and degrade accuracy and reliability.
### **4. Inflexible**
Any change to upstream data sources requires modifying and retesting ETL jobs, making adapting to evolving data landscapes challenging. By removing cumbersome ETL steps, zero-ETL makes it possible to overcome many limitations of traditional approaches.
## **The 3 Key Components of Zero-ETL**
Query federation, streaming ingestion, and change data capture (CDC) are the [three components of zero-ETL](/blog/zero-etl-vs-modern-data-stack/).
### **Query Federation**
Query federation is a collection of data structures that allow clients access to heterogeneous data stored in multiple locations. Federation makes querying data from remote systems effortless, exponentially speeding up traditional processing times.
### **Streaming Ingestion**
Streaming ingestion processes data in real time as it is generated, which is ideal for applications that demand instant actions or real-time insights. This component allows organizations to act on time-sensitive situations immediately. Streaming ingestion also minimizes latency.
### **Change Data Capture**
Change data capture (CDC) in zero-ETL tracks all changes made in a database. The CDC identifies changes and updates downstream systems and processes accordingly, ensuring that data is in sync across systems. By replacing nightly batch updates, the CDC provides users with fresh data and makes real-time data analytics possible.
## **Key Technologies for Zero-ETL Integrations**
Two pivotal technologies make zero-ETL integrations feasible:
### **Data Virtualization**
Data virtualization creates a simplified, unified view of data from disparate sources without needing physical data movement or replication. The virtualization layer maps metadata from sources and enables direct queries on source data as required. This approach avoids having to create copies of data while providing quick access.
### **Data Lakes**
Data lakes are centralized repositories that store structured, semi-structured, and unstructured data in native formats. Storing raw data eliminates lengthy preprocessing and enables on-demand transformation later. Technologies like Apache Spark allow running analytics directly against data lakes. Data virtualization and data lakes eliminate delays in moving, staging, and processing data, making analytical insights readily derivable from source data.
## **Step-by-Step Guide for Implementing Zero-ETL**
Follow these key steps to adopt a zero-ETL approach:
### **1. Identify Data Sources**
Catalog all internal and external data sources from which analytics use cases need to derive insights. These may include databases, CRM systems, cloud storage, social media feeds, and IoT data streams.
### **2. Design Data Access Architecture**
Design a solution architecture that enables direct access to source data systems using technologies like data virtualization and data lakes.
### **3. Build Data Connectivity**
Implement the designed architecture by establishing integrations with source systems, leveraging their native connectivity capabilities or platform APIs.
### **4. Create Unified Data Views**
Use metadata mapping and data modeling methodologies to create an abstracted, unified view of data sources. This provides a single access point to query data.
### **5. Make Data Discoverable**
Compile metadata in a data catalog to make the integrated data's availability, lineage, and meaning discoverable to users.
### **6. Provide Self-Service Access**
Leverage capabilities like SQL interfaces, data visualization tools, notebooks, and custom applications to empower users with self-service access to integrated data.
### **7. Govern Data Access**
To manage users' access to the data, implement role-based access, usage monitoring, and security controls aligned to governance policies. Adopting these practices can lead to a successful zero-ETL implementation, making unified data readily accessible for business insights.
## **Key Considerations for Zero-ETL**
Like any technology strategy, zero-ETL comes with some [key considerations](https://www.ascend.io/blog/zero-etl-whats-behind-the-hype/). While Zero-ETL offers faster access to analytics-ready data, its effectiveness depends on several factors:
### **Heterogeneous Data Landscape**
Zero-ETL works best when integrating varied data types like databases, files, streams, and cloud data. For homogenous sources like multiple relational databases, traditional ETL may still be preferable.
### **Data Governance Controls**
Since data transformations are minimized, strong governance practices for security, privacy, and lifecycle management are critical.
### **Analytical vs Transactional Systems**
Zero-ETL provides quick insights by directly querying source transaction systems. However, for certain heavy analytical workloads, staging a [data warehouse](/blog/logical-data-warehouse/) may still be appropriate.
### **High-Performance Data Access**
The connectivity and infrastructure powering access to source data must offer the throughput, concurrency, availability, and low latency needed for zero-ETL performance.
### **Skills Availability**
Zero-ETL relies heavily on emerging data integration technologies. Ensure teams have skills in areas like virtualization, big data, and cloud architecture. While zero-ETL streamlines access to business insights from data, traditional ETL continues to retain value in certain cases. The decision between the approaches depends on the specific data environment, integration challenges, and analytical objectives.
## **Zero-ETL in Action: Programmatic Advertising**
Consider a digital marketing platform that needs to optimize bidding on ad exchanges and targeting based on campaign performance data. Waiting days for batched ETL would result in missed opportunities. Zero-ETL integrates real-time data from ad networks, CRM, web analytics, and other systems, enabling faster optimization.
The implementation follows four key steps:
### **1. Streaming Data Ingestion**
Ingest real-time streams of ad impressions, clicks, costs, and target audience events using Apache Kafka.
### **2. Storing Raw Data**
Land streaming data in compressed, partitioned storage on cloud object stores for cost efficiency.
### **3. Providing Unified Access**
Use a metastore catalog to abstract technical metadata and give SQL access to raw data.
### **4. Powering Analytics**
Connect business intelligence tools directly to cataloged data sources to visualize and identify optimization opportunities. This zero-ETL approach delivers sub-second insights, maximizing advertising ROI through real-time monitoring and optimization.
## **The Bottom Line**
Zero-ETL bypasses complex traditional ETL processes and directly enables analytics on raw source data. Modern data architecture patterns powered by data virtualization and data lake technologies eliminate delays in making diverse data readily available for business use.
Zero-ETL presents a versatile approach as organizations aim to accelerate insight velocity across heterogeneous and rapidly growing data landscapes. Using the concepts and best practices covered here, you can assess if zero-ETL aligns with your analytics objectives and begin adopting it to tap into the value of your data.
Peaka’s data integration platform can connect to any API. See our [growing library of custom integrations](/integrations/).
--- START: blog/what-will-a-no-code-future-look-like/what-will-a-no-code-future-look-like.md ---
# **What will a No-code Future Look like?**
It was exactly ten years ago that Marc Andreessen famously [declared that](https://www.wsj.com/articles/SB10001424053111903480904576512250915629460) software was eating the world and made a list of all the industries that had already been swallowed whole by that time, adding in his predictions for the future as well. Andreessen was not so much prophesizing as connecting the dots, declaring in crystal clear fashion the logical conclusion of a two-decade-long development. He was proven right over and over again.
Today low-code/no-code technology, which has branched out from the software revolution Andreessen was drawing attention to, is pushing the limits of software use and expanding it into fields that were traditionally averse to technology. What does this tell us about the future? What role can we expect no-code technology to play in the next three to five years? Here is a short list of no-code-related changes we can expect to see in the near future:
## **1- No-code will take digital transformation to bureaucracy**
If there is one domain desperately in need of a digital transformation, it must be the government. For a regular citizen, just the idea of nudging that cumbersome behemoth into taking a particular action is enough to evoke horrors: Spending hours waiting for a single signature or approval from an official or just the go-ahead from an authority who doesn’t even know you are there. Be it an application for a building permit, a transfer of deed or a simple petition drawn out to voice a request, you are slated to waste hours and even days each time you visit a government institution. But it doesn’t have to be that way.
Bureaucratic work offers a huge area of opportunity where no-code can score quick wins and produce very high ROI. The higher the number of authorities needed for their approval, the longer the bureaucratic process. Thinking about it, even the simplest no-code platforms today are capable of tasks such as streamlining paperwork running in parallel, assigning work to different people having taken into account their workload, and triggering certain actions when a task is complete. Actually, considering the relative ease of the necessary steps and the possible savings in terms of man-hours (both from the point of view of the government and the citizens) and the compounded impact that it could have on other parts of the economy, one has a hard time understanding how the use of no-code platforms in government institutions is not already enforced by law.
## **2- ‘No-code Ops’ will become a thing**
Being born out of real needs and empowering people on the frontlines, no-code use in enterprises will be a common sight. Domain experts, having diagnosed a problem, will put on their citizen developer hats and deploy a no-code platform to solve that problem, make the necessary integrations and continue their work without skipping a beat. The writing is on the wall: IT department will have a hard time handling the demand from employees for internal tools and task automation. As a result, some other unit, closer to the field, will have to take responsibility.
No-code ops, a term coined by [David Peterson](https://blog.usejournal.com/why-no-code-operations-is-the-next-big-job-in-tech-b8bb886378ac) of Airtable, will be this very unit, bringing structure to the way no-code tools are deployed and making it possible for the IT to tend to higher level tasks. No-code ops will serve as a think-tank within the company, dedicated to finding better ways of leveraging no-code technology and dealing with unintended consequences such as technical debt and shadow IT. You may expect to see the term among job postings, too, as many companies will be in need of people who can plan, lead and supervise task automation efforts with no-code platforms.
## **3- No-code will drive the growth of Internet of Things (IoT)**
IoT [refers to](https://en.wikipedia.org/wiki/Internet_of_things) a network of physical objects, each with sensors collecting data and sharing that data with other objects via the internet to trigger certain actions. No-code will be the blood running through the veins of [IoT](https://en.wikipedia.org/wiki/Internet_of_things). No-code apps already help people control lighting, heating and appliances in smart homes. Moreover, as we have recently [covered](/blog/no-code-for-manufacturing-industry-2/ ), they increase visibility at the factory floor by collecting data and aggregating that data in the form of meaningful metrics, thus making smart manufacturing and Industry 4.0 possible. No-code apps are transforming agriculture too, by leveraging sensors to ensure utmost precision in the use of fertilizers and herbicides, reducing human involvement and cutting costs considerably. In the future, it is highly likely that we will use no-code apps to diagnose problems with our autonomous driving cars and even fix them ourselves.
Today no-code is not eating the world. Not yet. However, there are signs that it is already biting big chunks off it. Current implementations of no-code, which may seem isolated from each other at the moment, will start converging in the near future, like a confluence of tributary rivers. The resultant snowball effect will change the way we see software and technology. We envision that Peaka, offering an all-encompassing solution for a wide range of use cases, will be the no-code platform of choice for entrepreneurs with courage to navigate new waters.
--- START: blog/why-data-governance-fails-for-ai-agents/why-data-governance-fails-for-ai-agents.md ---
# AI Agents Break Data Governance: 5 Reasons Why
Role-based access, column-level classification, quarterly permission reviews, and other traditional data governance methods were built around humans being the consumer. AI agents require a different model entirely. The controls built for one don’t transfer to the other.
The most dangerous part is that despite controls not working, on the surface everything still looks governed. Logs keep filing and permissions keep getting enforced, so nothing looks broken from the outside. The original assumptions that were implicitly set by traditional data governance just no longer hold.
The clearest way to see where those assumptions break is to dive into each one directly. This piece follows five specific places where traditional governance was right for the customer it was built for and why it is now wrong.
{{ resize_image(path="../static/assets/images/blog-images/mathew/traditional-governance-ai-agents.png", width=759, height=400, op='fit_width', alt="a table depicting how AI agents break traditional data governance") }}
## What changes when the consumer is an agent
### AI agents introduce a second identity
Every traditional governance model starts from the same place. Every action has a known identity, or a role. When something goes wrong, the audit points directly to whoever broke it. AI agents don’t have a responsible party. An agent authenticates as a service account. When a query is made on behalf of a user, the database receives the service account of the AI agent.
This matters because there are now two identities in the transaction: The agent making the query and the user whose intent drove it. Traditional governance was designed around a single actor making a deliberate choice. The concept of acting on behalf of someone else didn’t exist in the old model.
With agents, an intermediary is introduced. Row-level security scoped to the real user never fires. Worse, the service account’s permissions scoped to nothing specific are what get enforced instead. [EU AI Act Article 12](https://artificialintelligenceact.eu/article/12/) now requires that AI system logs identify the responsible party behind each interaction.
### AI agents are non-deterministic
Traditional governance was built for deterministic systems. Predictability is what made control possible. The same input produces the same output so you can reason about it in advance. AI agents are more nuanced. The same prompt run twice can produce two different queries. There’s no canonical version of what an agent “does” with a given request. Its behavior is determined at runtime from the model and the context it finds along the way.
Every traditional control rests on the ability to specify acceptable behavior before it occurs, and non-determinism takes that away. Policies are written against known actions. Audits compare what happened against what was supposed to happen. Take away a knowable “what was supposed to happen,” and there’s nothing left for a policy to check against.
### AI agents create sensitive data at query time
Data classification was designed to tag sensitivity at the field level. A column with social security number is classified as PII and a schema with compensation data is restricted. The assumption is that sensitivity is a property of the data itself, knowable before any query runs.
AI agents typically don’t query one source. They pull from whatever systems are connected and synthesize a single response from all of it. The combination they produce (and the sensitivity it carries) isn’t determined until the query executes.
Field-level tags miss this entirely. A column tagged as external in Salesforce and a field tagged as internal in Workday each pass their individual checks. Neither check evaluates what those fields produce together. Deal ownership and payment history, assembled into a single response about a specific person, can be sensitive in a way neither source was on its own; the risk comes from the join, not from either field.
### AI agents read and write in the same execution
In the traditional model, reads and writes were governed separately because they were done separately. Analysts queried data. Applications modified data through defined workflows. The systems that read and the systems that wrote were different systems, so the controls governing them could be different too.
AI agents don’t have that boundary. In a single execution, an agent can read from a CRM, reason about what it finds, update a field, trigger a downstream workflow, and write a result back to the requesting system. And it doesn’t do this once per session the way a human might; it runs continuously, executing dozens of read-write cycles per task.
Traditional governance has no model for that volume or that autonomy. Write controls were calibrated for human-speed, intentional modifications. The nature of writes for AI agents has completely changed its risk profile.
### AI agents outlive permissions
Human access was self-correcting by design. Someone changes roles, their permissions change. Someone leaves, their access ends. Accordingly, traditional governance was built around the assumption that the access surface would be periodically revisited.
Service accounts have none of these triggers. There’s no role change or off-boarding. They’re created when a project needs them. They are granted whatever access seemed necessary in the moment and are left running. Permissions tend to accumulate quickly through incremental additions.
That becomes a huge problem when an incident requires revocation, because the service account is usually shared across other agents and pipelines. Revoke it outright and everything downstream stops. Scope it down instead, and you’re rebuilding the permission structure from scratch, mid-incident.
None of these failures are surprising in isolation. Together, though, they all point to the same gap.
## Closing Thoughts
The deeper issue across all five failures is timing. Traditional governance roles, queries, columns, and permissions are all configured at design time. AI agents operate entirely at runtime. They carry the user’s intent, the conversation history, the task they’re trying to complete, and all of the other context. That context is used to make decisions in real time about what to query and what data sources to combine.
Governance that was designed to be configured before execution can’t reason about context that only exists during it. A different layer is needed: One that operates at runtime alongside the agent, evaluating each query against the identity and context that produced it, across every connected source rather than one at a time. Peaka is built as that layer. It sits on top of existing infrastructure without replacing any of it.
If you’re looking to modernize your data infrastructure to keep up with the agentic era, [book a demo](https://calendly.com/peaka/demo) with Peaka.
--- START: blog/why-developers-love-no-code/why-developers-love-no-code.md ---
# **3 Reasons Why Developers Love No-Code**
The fabricated tension between developers and the no-code technology that was supposed to put them out of work seems to have subsided, finally. Click-bait headlines that question the job safety of possibly the most popular profession of our time are getting few and far between. Developers are trusting no-code platforms and apparently loving them for various reasons. Here’s a closer look at three less-cited reasons developers love no-code:
## **1 - Chance to test ideas out quickly**
The ideation phase in product development is all about throwing mud at the wall and seeing what sticks. Developers want to find out as quickly as possible whether their ideas will work without having to invest a lot of time and effort. No-code technology shortens the route from raw ideas to [Rapid Prototypes](/blog/no-code-fast-track-product-development/). This approach minimizes the business risk that would stem from committing resources to an infeasible solution to a problem. The sooner the failure takes place, the easier it is for the product development effort to pivot to something more productive. No-code provides the perfect litmus test for weeding out bad ideas and keep working with the good ones.
## **2 - Side projects**
A side project may serve various purposes for a developer: It may be an opportunity for him to learn a new skill and develop a muscle that he can use later in future projects. It can also be a tentative attempt at turning an idea into a product. If successful, this product can generate passive income in the future, something we all dream of. However, a side project should be [limited in scope](https://theobendixson.medium.com/what-does-a-good-side-project-look-like-d7ce26920967). It should be just that—a side project—and shouldn’t encroach upon a developer’s main line of work and require too much time or motivation. It should be easy to deal with. In this kind of work, the more you get rid of the mundane, tedious parts of the work, the more time you will have in your hands to focus on the nitty-gritty of the project. Deciding on things like the place of a button on the page or the amount of padding to be used should not require too much attention and brainpower after all when the developer has a lot of other things to worry about in a project. No-code tools allow developers to see the outcome of their decisions right away and expedite progress of a project. They help developers save time and effort while working on their side projects, without having to build everything from scratch for something of secondary importance.
## **3 - Separation of back end and front end**
In the past, application development was a full-stack job: Developers used to learn a programming language and build end-to-end the whole application on one technology. This was a viable approach for desktop applications which did not put much burden on servers. With the progress of the internet technology, web became capable of hosting applications, a fact that facilitated the migration of applications from desktop to web. This technological breakthrough brought about a sharp increase in user numbers and it became difficult for back end servers to cope with the sheer number of [user requests](https://medium.com/@moficodes/front-end-and-back-end-together-but-separate-6e00d90e34d3). It was obvious that back end and front end [scaled at different paces](https://www.forbes.com/sites/forbestechcouncil/2018/07/19/seven-reasons-why-a-websites-front-end-and-back-end-should-be-kept-separate/?sh=460fe6ea4fca) and the former needed to scale more quickly.
The introduction of cloud computing took things to another level, making it possible for developers to build much more capable web applications with lots of features. This gave rise to a sharp increase in the complexity of problems web developers had to face: Browser-specific problems; the differentiation between mobile and desktop; UX; SEO; security concerns. The back end-front end separation was the result of an effort to specialize in problems associated with these respective environments. With these two separated, any change made on one side no longer affects the other, putting an end to the [maintenance nightmare](https://opensenselabs.com/blog/articles/frontend-backend).
No-code platforms lend themselves to this approach, producing code for both back end and front end as the user builds his app. There are a plethora of layers between the component and the data model in a no-code platform, but they come pre-built out-of-the-box and thus, do not require developer hours to code. Modern web design and the powerful applications we use support functions such as push notification, streaming and parallel processing, which put a premium in expertise in certain back end and front end tasks. No-code is tailor-made for this new age of app development.
## **Conclusion**
Developers had no beef with no-code platforms in the first place. Articles proclaiming that the no-code revolution would spell the end of software development probably rubbed some developers the wrong way, but they were quick to see the value in no-code technology. As task automation comes to play a bigger role and time-to-market remains as one of the measures of success, developers will come to depend more on no-code tools. What was presented as a conflict of interest between developers and no-code technology has turned out to be the beginnings of a lasting alliance, it seems.
--- START: blog/why-is-no-code-becoming-in-all-of-a-sudden/why-is-no-code-becoming-in-all-of-a-sudden.md ---
   Link copied
Table of Contents
* [Why is No-code Becoming “In” All of a Sudden?](https://www.peaka.com/blog/why-is-no-code-becoming-in-all-of-a-sudden/#why-is-no-code-becoming-in-all-of-a-sudden)
* [Technology has matured](https://www.peaka.com/blog/why-is-no-code-becoming-in-all-of-a-sudden/#technology-has-matured)
* [Too much demand, not enough talent](https://www.peaka.com/blog/why-is-no-code-becoming-in-all-of-a-sudden/#too-much-demand-not-enough-talent)
* [A tech-savvy generation entering the workforce](https://www.peaka.com/blog/why-is-no-code-becoming-in-all-of-a-sudden/#a-tech-savvy-generation-entering-the-workforce)
* [The impact of the pandemic](https://www.peaka.com/blog/why-is-no-code-becoming-in-all-of-a-sudden/#the-impact-of-the-pandemic)
[Home](/) / [Blog](/blog) / Why is No-code Becoming “In” All of a Sudden?
[No-code](https://www.peaka.com/category/no-code/)
Published on May 01, 2021
6 min read
Why is No-code Becoming “In” All of a Sudden?


M. Çınar Büyükakça Peaka / Great Thinker
**Why is No-code Becoming “In” All of a Sudden?**[](#why-is-no-code-becoming-in-all-of-a-sudden)
================================================================================================
The last several years have turned “[no-code](/)” into a household term in the tech business. The initial doubts that no-code would not amount to much beyond marketing talk have turned out to be in vain. The sheer number of tasks that no-code tools can handle (breadth) and the proficiency with which they can perform them (depth) have expanded consistently over a couple of years.
Today, big corporations are deploying enterprise-grade no-code tools. Investors are racing to throw money at no-code startup projects. Regular people are joining no-code bootcamps to add new skills to their repertoires. As a result of this interest, some no-code platforms have even surpassed the billion-dollar threshold in valuation.
Let’s take a closer look at some of the factors that have combined to set the stage for the rise of no-code.
**Technology has matured**[](#technology-has-matured)
-----------------------------------------------------
The borders of the digital world have greatly expanded in the last decade. The internet infrastructure has become better across the globe. Thanks to that, significantly more people have access to the internet today compared to a decade ago.
No-code tools have come a long way in the meantime, too. In addition to tech startups developing no-code platforms, tech giants such as Google, Amazon, and Microsoft have been pouring billions of dollars into developing more capable no-code products. As technologies like cloud computing, artificial intelligence, and machine learning mature, no-code platforms look poised to take on a bigger role. Just think about it for a second: No-code app development assisted by AI... How cool would that be?
**Too much demand, not enough talent**[](#too-much-demand-not-enough-talent)
----------------------------------------------------------------------------
The rising demand for software is one of the defining characteristics of our age. However, the number of developers entering the industry each year is not enough to satisfy this demand. We are facing a developer shortage, and it is one of the reasons driving the growth of the no-code market.
The number of computer science graduates who will join the workforce by 2022 will barely amount to [one-third of the actual need](https://medium.com/chargevc/where-next-for-no-code-8f9d21354cc9) (40,000 vs. 120,000). This will add to the approximately 1 million existing tech job openings in the U.S. This dynamic is driving up the salaries of developers, making them less affordable for startups and SMBs.
Not only that, but the recruitment process seems to be getting dragged out, too. [According to a study](https://www.icims.com/blog/how-to-prepare-for-tech-hiring-in-2020/), the average time to recruit for a tech position was as long as 66 days in 2019, which is 50 percent longer than it was for other jobs. A longer recruitment process threatens innovation and prevents a company from realizing its true potential, something a startup can ill-afford.
This is where no-code comes into play. No-code technology empowers people that do not come from a coding background to carry out tasks that would otherwise have to be done by developers. In the corporate lingo, these people are called "citizen developers."
Citizen developers are domain experts who can leverage no-code tools to take on some of the application development duties. However, their app development activities focus on creating business applications suitable to carry out well-defined tasks at work. These activities complement conventional software development.
Make no mistake, though: No-code platforms will not replace the coders. No-code tools will help companies bridge skill gaps caused by the developer shortage. These tools will also support coders and take over repetitive tasks so that elite talent can focus on a strategic level where their creativity and expertise can have a much bigger impact.
**A tech-savvy generation entering the workforce**[](#a-tech-savvy-generation-entering-the-workforce)
-----------------------------------------------------------------------------------------------------
Members of the much-talked-about Gen Z are graduating from college and joining the workforce. This changes the whole ballgame because of how immersed these people have been in technology from the moment they were born—they are digital natives.
Gen Zers learn online, socialize online (they feel at home on social media), fight online, and are generally much more comfortable using technology than the generations that preceded them. While their parents might get frustrated and stressed operating different digital tools, using apps has become second nature to Gen Z. Employers are looking to leverage this capability by putting Gen Zers in a position they can make a difference using no-code tools.
**The impact of the pandemic**[](#the-impact-of-the-pandemic)
-------------------------------------------------------------
The digital transformation that was already in place before the Covid-19 pandemic has accelerated in a world of lockdowns, working from home, and video conferences. U.S. e-commerce sales saw a [32.4 percent increase](https://www.digitalcommerce360.com/article/quarterly-online-sales/) in 2020 over the previous year, and online sales have become a lifeline for even small businesses. The bakery on your street, the florist in the neighborhood, or the dairy producer in the countryside have all turned to e-commerce platforms in order to cope with the challenges of the pandemic.
[The surge of e-commerce](https://www.internetadvisor.com/online-shoppers-statistics-facts-and-trends-for-2022) has become one of the main reasons fueling the rise of no-code: E-commerce templates have become some of the most popular no-code solutions. On the other hand, remote work seems to have changed the work life forever: 83 percent of employers and 71 percent of employees think that [remote work has been a success](https://www.pwc.com/us/en/library/covid-19/us-remote-work-survey.html), so it is a trend that is here to stay in one form or another.
The capabilities no-code platforms bring to the table facilitate this trend. These platforms automate certain processes and allow people to work and collaborate online. The post-pandemic world will see widespread use of no-code tools.
Members of the Peaka team took part in code and no-code development throughout their careers. They were part of the workforce through all the changes that transpired in the software industry in the last decade. Thus, the platform evolved accordingly in response to the demands of the industry. Now, Peaka is ready to help startups and individuals fulfill their potential in the face of those challenges.
Your biweekly inspiration delivered to your inbox
Join our newsletter for news, tips, and blog posts on anything data integration!
Subscribe
 Please fill out this field
 Thank you! You have been subscribed.
Similar posts you might be interested in
[](https://www.peaka.com/blog/saas-ideal-customer-profile/)
No-code May 01, 2021
[How to Create an Ideal Customer Profile for SaaS Businesses](https://www.peaka.com/blog/saas-ideal-customer-profile/)
How do you create an ideal customer profile (ICP)? Why should a SaaS company create one? How does Peaka help you hone your ICP? Find out in this blog post.

Bruce McFadden Peaka / Seasoned Taskmaster
[](https://www.peaka.com/blog/account-based-marketing-saas/)
No-code May 01, 2021
[How to Create an Account-Based SaaS Marketing Strategy](https://www.peaka.com/blog/account-based-marketing-saas/)
Here is everything a SaaS founder needs to know about account-based marketing, how it works, its benefits, and how Peaka can help ABM teams implement it.

Eugene van Ost Peaka / IT Soothsayer
[](https://www.peaka.com/blog/top-saas-revenue-metrics/)
No-code May 01, 2021
[Top 6 SaaS Revenue Metrics to Track in 2026](https://www.peaka.com/blog/top-saas-revenue-metrics/)
A deep dive into SaaS revenue metrics, four data integration tools to track SaaS revenue, and benefits of blending your revenue data with your CRM data.

M. Çınar Büyükakça Peaka / Prolific Polemicist
 
Begin your journey today
Start your 14-day free trial to explore Peaka!
Get started for free
Enjoying this article?
Subscribe to our monthly newsletter for insights on ServiceTitan data integration and KPI reporting.


First Name
Last Name
Email
Company Name
Phone Number (optional)
Subscribe
You can unsubscribe anytime. For more details review our [Privacy Policy](https://www.peaka.com/privacy-policy/).
--- START: blog/why-use-saas-analytics-tools/why-use-saas-analytics-tools.md ---
# **Why You Need to Use SaaS Analytics Tools in 2026**
What we witnessed in the software industry in the last two decades was nothing short of a revolution. The Internet infrastructure got better and helped cloud-computing grow by more than 500 percent from 2010 to 2020. As a result, SaaS became the dominant form of software distribution in the 2010s.
SaaS not only revolutionized how software is delivered but also changed how software products are developed, marketed, sold, and continuously improved. It integrated software development, marketing, and sales functions like never before. Relying on recurring revenue rather than one-time transactions, SaaS companies felt pressed to sustain and nurture a relationship with their customers, which required understanding them first.
SaaS analytics emerged from this need to quantify how customers interact with a product, derive insights, and use them to improve the product and sell more of it.
## **What is SaaS analytics?**
[SaaS analytics](/blog/b2b-saas-analytics-tools/) refers to the way SaaS companies track, bring together, and analyze their data to make better decisions. The emergence of SaaS analytics as a discipline resulted from the business model the SaaS concept introduced.
The SaaS model might have changed the way we buy software, but it's the after-sales process where it truly differentiates itself from traditional businesses. SaaS companies [rely on recurring revenue](/blog/saas-growth-metrics/) to grow, which does not happen without retaining customers first and then adding new ones. This reliance on customer retention changes the whole game, as the SaaS analytics guru David Skok [points out](https://www.forentrepreneurs.com/saas-metrics-2/) in one of his articles:
> "_SaaS and other recurring revenue businesses are different because the revenue for the service comes over an extended period of time (the customer lifetime). If a customer is happy with the service, they will stick around for a long time, and the profit that can be made from that customer will increase considerably. On the other hand, if a customer is unhappy, they will churn quickly, and the business will likely lose money on the investment that they made to acquire that customer. This creates a fundamentally different dynamic to a traditional software business. There are now two sales that have to be accomplished:_
> _1. Acquiring the customer_
> _2. Keeping the customer (to maximize the lifetime value)._"
While customer retention concerns put pressure on SaaS companies and require frictionless customer experience, the SaaS model also presents its practitioners with opportunities to create life-changing products. Thanks to the cloud-based nature of SaaS, every user interaction with a product becomes a data point, giving a SaaS company unprecedented visibility into how its product is being used in real life. Successful SaaS companies are the ones that collect, analyze, and interpret this data and develop products that perfectly fit the needs of their customers.
Tune into this video by [David Skok](https://www.linkedin.com/in/dskok/) for a primer on the SaaS business model and why analytics is indispensable for success in SaaS:
{{ youtube(id="5RR6M_d6eKc") }}
## **Key takeaways**
- SaaS analytics encompasses how you track, unify, and analyze your SaaS data to make better decisions.
- SaaS analytics helps you see which parts of your marketing strategy work, create ideal customer profiles, and evaluate past performance.
- SaaS analytics comprises three main types: Product, marketing, and revenue analytics.
- Marketing and revenue attribution tools are becoming more popular as they enable you to identify the ads, content, and campaigns that create value for your company.
## **SaaS in numbers**
- According to a forecast by [Gartner](https://www.gartner.com/en/newsroom/press-releases/2024-11-19-gartner-forecasts-worldwide-public-cloud-end-user-spending-to-total-723-billion-dollars-in-2025), the end-user spending in the SaaS sector will reach $299.07 billion in 2025, marking a 19.2 percent growth over the 2024 figure of $250.80 billion.
- A recent study by [Precedence Research](https://www.precedenceresearch.com/software-as-a-service-market) forecasts the global SaaS market size to reach $1,251.35 billion in 2034, with a compound annual growth rate of 13.32 percent from 2025 to 2034.
- The same study projects the U.S. SaaS market to grow from $115.82 billion in 2024 to $412.14 billion in 2034.
- There are more than 16,000 [SaaS companies](https://getlatka.com/companies/countries/united-states) in the U.S. as of 2025.
- A study conducted by [BetterCloud](https://pages.bettercloud.com/rs/719-KZY-706/images/BetterCloud-State-of-SaaS-2025.pdf) among 568 IT professionals has revealed that the average number of SaaS apps used by companies with 1,500 to 4,999 employees decreased from 142 in 2023 to 101 in 2024.
## **Why do you need SaaS analytics?**
In a business environment where we are overwhelmed by data pouring in from all directions, SaaS analytics is more important than ever. Here are three main reasons you need to invest in analytics if you're running a B2B SaaS company:
### **To see what works and what doesn't**
SaaS analytics help users recognize patterns and trends in their business operations. These patterns reveal how the product resonates with customers, the friction points, the features they love, and those they don't like or understand. SaaS analytics puts an end to what you think your product is and shows you what your customers think it is.
This last point is particularly critical for startups, which have no data at the beginning and have to make decisions based on various assumptions and hypotheses. SaaS analytics exposes which of these assumptions were true and which hypotheses held. If the startup in question manages to track and unify its data, the analytics can help ensure that future decisions will be data-driven instead of throwing things against the wall and seeing what sticks.
### **To create ideal customer profiles and segment the market**
No company can serve everyone at the same time. There has to be a categorization of some kind, and we all know that "[_not all segments are created equal._](https://www.saasceo.com/ideal-customer-profile/)"
That's why companies study their potential customers and prioritize the needs of a smaller group among them. These are the customers with pains that are a better fit for a product. Companies strive to target these best-fit customers because they are more likely to make [repeat purchases, upgrade, and refer new customers](https://medium.com/@StartupBusinesstips/how-to-create-a-powerful-ideal-customer-profile-icp-83531bf603d9).
That's where SaaS analytics comes in handy. Data can speak volumes about your best-fit customers, provided that you can enrich it with [firmographic, demographic, technographic, and psychographic data](/blog/saas-ideal-customer-profile/). This data can help align marketing and sales activities and ensure that the messaging and marketing companies are personalized for the higher-value segment, which will shorten the sales cycles as a result.
### **To evaluate past performance**
SaaS analytics brings a structure to how data is to be tracked, unified, and leveraged. When done right, SaaS analytics identify high-level KPIs and low-level, more focused metrics. With metrics and KPIs at hand, it will be easier to establish ownership of goals across the company. SaaS analytics aligns a company around measurable goals and brings accountability to the day-to-day processes and quarterly operations.
Once accountability is established, individual and team performance can be more objectively evaluated and communicated to employees. SaaS analytics visualized in a dashboard reveals where employee performance needs to improve and makes one-on-one coaching of employees possible.
Measuring the success of marketing campaigns is a challenge for companies. SaaS analytics helps users correctly attribute success to marketing initiatives undertaken and measure the return on marketing dollars spent. It enables more efficient use of resources and makes it possible for marketing teams to identify the relative performance of different channels like social media, email marketing, or content marketing. More on marketing and revenue attribution later.
## **Types of SaaS analytics**
SaaS analytics is a vast and expanding field. For the sake of practicality, it is best to examine it under three headings:
### **1. Product analytics**
Product analytics is the process of [tracking and analyzing](https://productschool.com/blog/analytics/product-analytics) how users engage with your digital product and making day-to-day and strategic decisions based on insights drawn from this process. Product analytics enriches the qualitative data you receive from customer surveys and interviews with quantitative data from product usage. SaaS companies rely on Build-Measure-Learn cycles to develop their products, and product analytics tools are what make this possible. As Fatih Koca, currently the head of Global Service OPerations Data Team at Google puts it succinctly, “_What you measure grows._”
{{ youtube(id="EvigtbOs5R0") }}
A good product analytics tool helps you solve some [major problems](https://theproductmanager.com/topics/product-analytics/) by letting you
- **Understand how your users engage with your product.** Product analytics reveal valuable information about your churn and retention rates and your daily, weekly, and monthly active users.
- **Discover the friction points and wow moments your users experience.** Product analytics help you address pain points and double down on things that delight your customers.
- **Streamline your product.** Product analytics allows you to see which features create value for your product and which ones don't. Using this information, you can create a leaner user experience.
- **Conduct [cohort analysis](https://www.fullstory.com/product-analytics/).** Product analytics tools enable you to group customers according to customer attributes like the pricing plan they subscribed to, the country they are based in, and their usage habits. This help
### **2. Marketing Analytics**
Marketing analytics is the collection and evaluation of data to inform marketing efforts. Organizations use platforms like Google Analytics, HubSpot, and Salesforce to consolidate and make sense of their data.
Marketing analytics helps users to
- **Establish a goal-oriented culture.** Marketing analytics allows marketing and sales teams to set goals and align their activities around these goals.
- **Identify metrics that help quantify marketing performance.** Marketing analytics provides users with data on the email campaigns, ads, and other content like podcasts, blogs, and videos created and how well they resonated with the targeted groups. [By turning data into information](https://mailchimp.com/marketing-glossary/marketing-analytics/), marketing analytics enables users to channel resources into more productive marketing activities.
- **Segment your customers according to common attributes.** Thanks to marketing analytics, you can group your customers, form tiers depending on the account value they offer, and create personalized messaging that will appeal to them.
### **3. Revenue analytics**
Revenue analytics refers to the [collection and analysis of data](https://jennpereira.medium.com/what-is-revenue-analytics-and-why-startups-need-it-for-success-9a9fffd8403d) to evaluate revenue generation activities. SaaS companies are characterized by strong revenue growth—that's what sets them apart from SMBs. Therefore, revenue analytics is essential for SaaS companies willing to achieve exponential growth.
Thanks to revenue analytics, users can
- **Understand customers.** Diving deep into revenue data reveals the best-fit customers who have urgent pains that your product solves. Capitalizing on this group can power your revenue growth.
- **Forecast future revenue.** Past data sheds light on cyclical trends and let users brace up for a spike in demand or look to secure external funding in the face of a sharp fall in revenue.
- **Uncover new sources of [revenue growth](https://dealhub.io/glossary/revenue-analytics/#revenue-analytics-implementation-steps).** Revenue analytics helps users identify the highest-value accounts and repeat customers, who are prime candidates for upselling and cross-selling initiatives.
## **Which SaaS metrics should you track?**
### **1. Monthly churn rate**
The monthly churn rate represents the percentage of customers who canceled their subscriptions in a given month. It is one of the staple metrics to gauge the health of a business and a sign of how close it is to product-market fit.
**MRR = Average Revenue Per User (ARPU) X Total Number of Subscribers
**
A high monthly churn rate tells that something is seriously wrong with your product, which you have to look for ways to fix to retain customers and grow. Software bugs, friction in the onboarding process, or poor customer support are the usual suspects when facing a high monthly churn rate.
The monthly churn rate is a particularly critical metric for networked products. These products depend on the existence of a network for users to derive value from them. A high monthly churn rate means there are fewer and fewer people using a product, which undermines its value and may render the product useless for the remaining users at some point.
### **2. Annual recurring revenue (ARR)**
ARR refers to the recurring revenue a business earns from its subscribers normalized for a year. It's regarded as a reliable indicator of a company's long-term viability. Investors focus on this metric while assessing the potential of a startup and deciding whether to invest in it. Doubling and tripling ARR every year is how successful startups stand out from mediocre ones and SMBs.
**ARR = MRR X 12
**
However, ARR lacks the precision one expects from a metric that informs strategic decisions. That's why it needs to be broken down into its components:
- new ARR (revenue from brand-new customers)
- expansion ARR (revenue from upselling or cross-selling)
- churned ARR (lost revenue from cancellations)
- contraction ARR (lost revenue from customers downgrading to a lower-priced plan)
- net new ARR (the change in annual revenue compared to the year before)
### **3. Customer lifetime value (CLV)**
CLV is the total revenue a business can expect to earn from a customer over the course of the business relationship. It helps identify the customers that create the highest value for a company and, in a sense, separates the wheat from the chaff.
**CLV = (Average Revenue Per User) / (Customer Churn Rate)
**
CLV matters because capitalizing on existing high-value customers is the shortest route to revenue growth. Customer acquisition cost for these accounts is already incurred, and these customers tend to spend more on upselling and cross-selling offers. Low CLV may indicate inefficient operations that need to be phased out. Eliminating products that are not popular with high CLV customers can help streamline the product range and improve ROI.
### **4. Net revenue retention (NRR)**
NRR is the percentage of the recurring revenue your business can retain over a certain period. A positive NRR reflects that you are growing your revenue base, which is a sign that your business model is working. Successful B2B SaaS businesses are characterized by high NRR.
**NRR = [(Starting MRR + Expansion MRR — Contraction MRR — Churned MRR) / Starting MRR] X 100
**
The reason NRR is regarded as a north star metric is that it measures revenue and sheds light on the efficiency of your whole operation. Cancellations and downgrades are inevitable, but if you can still grow your business despite those setbacks, it means that the positives outweigh the negatives. Whether it's a certain feature of your product, the user experience you offer, or the customer success effort, you are doing something right. Identifying those strengths and doubling down on them should be the next step.
### **5. Customer Acquisition Cost (CAC)**
CAC is the total money spent on marketing and sales to acquire a new customer. This figure [includes](https://blog.hubspot.com/service/what-does-cac-stand-for) ads spend, employee salaries, production and publishing costs associated with marketing content, overhead costs regarding software and technical equipment needed to sustain marketing and sales effort, and maintenance.
**CAC = (Sum of all sales- and marketing-related expenses) / (Number of new customers added)
**
CAC is one of the fundamental metrics in unit economics. It is an indicator of the efficiency of your marketing and sales efforts and how well they are aligned. You don't want to pour money into acquiring customers who will generate less CLV than the money it costs to acquire them. Successful SaaS businesses use two benchmark figures to gauge their performance:
- One should earn from a customer [three times](https://blog.hubspot.com/service/ltv-cac-ratio) as much money as one spends acquiring them.
- It should take a company 12 months or less (payback period) to recover the money spent on customer acquisition.
### **6. Average ticket count, backlog, and resolution time**
These [three metrics](https://blog.hubspot.com/service/customer-experience-metrics) give you a well-rounded idea about the frequency of technical problems your customers are having with your product and how your customer support team is handling the requests for support.
The **average ticket count** measures the number of support tickets your team receives on a given day, week, or month. Sudden and sustained increases in the number of support tickets may point to a serious problem with your technical infrastructure or a major bug in your software.
Your **average ticket backlog** speaks volumes about your team's performance in responding to and resolving support tickets and the rate at which new tickets are created. A growing backlog of tickets can be a sign of serious issues with your product or an underperforming customer support team.
The **average ticket resolution time** is the metric that tracks the performance of your customer support team. A long resolution time means you have to invest in training and expanding your customer support team, or the issues with your product are too complex to deal with.
### **7. Customer conversion rate**
Customer conversion rate refers to the percentage of users who have completed a predefined [desired action](https://corporatefinanceinstitute.com/resources/valuation/customer-conversion-rate/). This action may differ from one part of the marketing or sales funnel to another, like visiting the website, signing up for a demo, opening an email, or entering credit card info.
Customer conversion rate is calculated by taking the number of customers who completed a particular action, like opening an email, and dividing that number by the total number of customers exposed to that particular request or trigger.
**Conversion rate = (Total number of conversions) / (Total number of users engaged)
**
Conversion rates are important to evaluate the marketing and sales decisions and actions taken along a funnel. Ads and content that generate low conversion rates can be revised for messaging and SEO or discarded altogether. Conversion rates also serve as [reference points](https://www.adjust.com/glossary/conversion-rate/) for salespeople further down the funnel. These people can use conversion rates to forecast the number of customers they will be working with when it's their turn.
For a discussion of these SaaS metrics and a few more, give a listen to this podcast by the renowned tech executive, investor, and consultant [Dave Kellogg:](https://www.linkedin.com/in/kelloggdave/)
{{ youtube(id="e0t-PSfaCe8") }}
## **4 SaaS analytics tools to keep an eye on**
B2B sales is a long-winded process with multiple touch points. As a decision-maker, you want to know which one of your decisions and experiments paid off and which ones did not. That’s why [marketing attribution](https://www.salesforce.com/blog/what-is-marketing-attribution-model/), the way marketers assess the ROI of marketing decisions and actions, is becoming increasingly popular:
{{ resize_image(path="../static/assets/images/blog-images/marketing-attribution-us-g-trends.png", width=759, height=400, op='fit_width', alt="Google searches for 'marketing attribution'") }}
Graph showing the change in the U.S.-based Google searches for the term "marketing attribution" over the last five years.
Image credits: [Google Trends](https://trends.google.com/trends/explore?date=today%205-y&geo=US&q=marketing%20attribution&hl=en). The image was slightly modified for aesthetic purposes.
Here is a look at four tools that help SaaS companies with the marketing attribution problem:
### **Dreamdata**
Dreamdata is a revenue attribution tool that lets users view the whole customer journey, understand how customers interact with a product, and glean the impact different ads, campaigns, and channels have on revenue. It gives its users visibility into conversion across all touchpoints, making them see which trigger led to a conversion.
#### **Strengths**
- Dreamdata offers one of the richest integration catalogs in the segment. Its ability to bring in data from a plethora of data sources make it easier to enrich the data and create a complete picture of the customer journey.
- Dreamdata’s reports beat those of the competitors on granularity.
#### **Weaknesses**
- Dreamdata is a complicated tool with a challenging setup process, especially for the uninitiated.
- Its data visualization capability, too, leaves much to be desired. Dreamdata offers dashboard templates for common use cases, but it may come up short when the customers develop more sophisticated needs in time. Customizable dashboards would work wonders to address the needs of diverse customer groups.
#### **Integrations**
{{ resize_image(path="../static/assets/images/blog-images/saas-analytics-1-dreamdata.png", width=759, height=400, op='fit_width', alt="CRM integrations offered by Dreamdata") }}
CRM integrations offered by Dreamdata.
Image credits: [Dreamdata](https://dreamdata.io/integrations).
In addition to CRM suites like HubSpot, Salesforce, Pipedrive, and Zoho CRM, Dreamdata integrates with Google Ads, Facebook Ads, LinkedIn Ads, and Google Search Console.
### **HockeyStack**
HockeyStack is another option if you are trying to see what part of your marketing and sales funnels are working and driving your revenue and which parts are underperforming. It links marketing data to usage and sales data, revealing how marketing initiatives contribute to a company's bottom line.
#### **Strengths**
- HockeyStack comes with an easy setup process and a no-code user interface, making it particularly suitable for small startups that can't afford large, specialized marketing teams.
- It offers a survey feature, which lets you dig into the prehistory of your relationship with your customers and learn how they heard about you.
- Another cool feature is the visualizations representing your funnels and conversions that take place along the customer journey.
The customization options in reporting and dashboards enable HockeyStack to handle different visualization needs.
#### **Weaknesses**
- HockeyStack offers a limited number of out-of-the-box integrations, although the team develops integrations with niche tools when customers demand so.
- Despite offering customized reports and dashboards, HockeyStack fails to provide the desired level of granularity with its reporting.
#### **Integrations**
{{ resize_image(path="../static/assets/images/blog-images/saas-analytics-2-hockeystack.png", width=759, height=400, op='fit_width', alt="CRM integrations offered by HockeyStack") }}
CRM integrations offered by HockeyStack.
Image credits: [HockeyStack](https://hockeystack.com/integrations).
HockeyStack integrates with major CRM platforms like HubSpot, Salesforce, Pipedrive, and Close, on the one hand, and Google Ads, Facebook Ads, and LinkedIn Ads, on the other. The tool may be expected to offer more integrations as it matures.
### **Ruler Analytics**
One of the more specialized players in the market, Ruler Analytics is a tool that unifies data from different channels and activities for the purpose of marketing and revenue attribution. It tracks leads across every touchpoint through a customer's journey and gives its users a holistic view of the impact their marketing efforts are generating.
#### **Strengths**
- Ruler Analytics' reports offer high granularity as they break down data into lower-level components. This lets users see which channels, campaigns, and keywords are responsible for the conversions.
- Its capability to track phone calls, live chats, and forms serves as an additional source of insights for users.
#### **Weaknesses**
- Reporting function covers only the last 90 days.
- Revenue analytics does not offer custom dashboards to visualize data. Instead, it scrapes the data and pushes it to other tools that can turn it into charts and dashboards.
- The setup process is intricate and requires some level of coding knowledge and support from the Revenue Analytics team.
#### **Integrations**
{{ resize_image(path="../static/assets/images/blog-images/saas-analytics-3-ruler-analytics.png", width=759, height=400, op='fit_width', alt="CRM integrations offered by Ruler Analytics") }}
Some of the CRM integrations offered by Ruler Analytics.
Image credits: [Ruler Analytics](https://www.ruleranalytics.com/integrations).
Ruler Analytics integrates with major CRM platforms like HubSpot, Salesforce, Pipedrive, and Zoho CRM. For marketing analytics, it can pull in data from Google Ads, Facebook Ads, LinkedIn Ads, and Google Analytics. Its integrations with Intercom and Drift add another dimension to the lead traction efforts.
### **Factors.ai**
Factors.ai is primarily a website analytics platform that can integrate with CRM platforms while letting its users track content performance and analyze site visitor behavior. It complements its website analytics capability with multi-touch revenue attribution, shedding light on the ROI of ads, campaigns, and channels.
#### **Strengths**
- Factors.ai offers its users an anonymous visitor identification capability. Thanks to the reverse IP-lookup technology to track high-intent accounts with the need for visitors to provide contact information.
- Factors.ai leverages AI to reveal how content, keywords, and specific actions impact conversion metrics throughout the whole funnel.
#### **Weaknesses**
- The limited number of integrations restricts Factors.ai's appeal for different use cases.
- Factors.ai's graphic representation of data looks like it could use some improvement. The lack of customization in the dashboard undermines the success of the analytics and attribution functions.
#### **Integrations**
{{ resize_image(path="../static/assets/images/blog-images/saas-analytics-4-factors.png", width=759, height=400, op='fit_width', alt="Integrations offered by Factors.ai") }}
Integrations offered by Factors.ai.
Image credits: [Factors.ai](https://www.factors.ai).
Factors.ai integrates with major platforms like HubSpot, Salesforce, and Google Ads. It is reasonable to expect the number of integrations to increase in the near future.
## **B2B SaaS analytics content to consume**
- Video–[The SaaS Business Model & Metrics: Understand the Key Drivers for Success](https://www.youtube.com/watch?v=5RR6M_d6eKcc) | David Skok
- Video–[Analytics Strategy for SaaS | Fatih Koca](https://www.youtube.com/watch?v=EvigtbOs5R0)
- Podcast–[SaaShimi Ep. II: Key SaaS Metrics | Dave Kellogg](https://www.youtube.com/watch?v=e0t-PSfaCe8)
- Article–[SaaS Metrics 2.0 – A Guide to Measuring and Improving What Matters](https://www.forentrepreneurs.com/saas-metrics-2/)
- Article–[Marketing Attribution: Creating a Growth Engine at Salesforce, Zendesk and Slack](https://www.forentrepreneurs.com/marketing-attribution/)
- Opinion–['The Next-era Metrics Playbook' | Kyle Poyar](https://www.linkedin.com/feed/update/urn:li:activity:7072166550014681088/)
## **Conclusion**
"_Scaling what works and eliminating what doesn't._" This is what all SaaS analytics boils down to. If being data-driven is the goal, SaaS analytics is the way to go.
SaaS analytics is the culmination of the efforts to make sense of data. It injects some science into the art of management and tries to make innovation and growth more predictable. Good things happen when you connect your data silos, get them to talk to each other, and actually make sense of the consolidated data. SaaS analytics takes care of the last part. For anything before that, you have Peaka.
--- START: blog/year-in-retrospect-2022/year-in-retrospect-2022.md ---
# **The Year in Retrospect: A Look Back at 2022**
Going into 2022, we had [high hopes and a cautious optimism](/blog/2022-predictions) that things would change for the better after two years of pandemic. Now, it's time for an assessment of the year to see whether our hopes materialized or unexpected developments rendered our predictions irrelevant.
## **Pivot to enterprise in the low-code/no-code**
2022 was a good year for low-code/no-code (LCNC) platforms, [just as we predicted](/blog/2022-predictions/#4-low-code-no-code-platforms). The enterprise segment was particularly enthusiastic in adopting these tools and using them to create internal tools and automate tasks. It looks like the B2C segment will take some time to mature before it offers a viable business to low-code/no-code (LCNC) companies. There are mainly two reasons for that:
Despite requiring little to no coding skills, people still benefit immensely from algorithmic thinking if they are to tap into the full potential of LCNC platforms.
Individual customers mostly see LCNC platforms as tools to realize hobby projects. Most of them lack the motivation to see a project through to completion.
The enterprise segment is not hobbled by such factors. The IT departments are full of people who can skillfully wield LCNC tools. This qualified workforce can establish guardrails and governance for non-technical LCNC users and slowly bring them into the fold. Additionally, the use cases in an enterprise environment are better defined compared to the individual segment. Employees know what they need to use an LCNC for and are motivated to invest time and effort in mastering these tools. Regular people with vague business ideas may struggle to figure out what they can do with such platforms. But these platforms become game changers in the hands of professional developers and domain experts.
Airtable was the first to make the pivot to the enterprise segment among no-code tools. Having achieved success through bottom-up adoption in big corporations, the company decided that a multi-pronged business strategy was not sustainable. As a result, management [resolved](https://www.airtable.com/newsroom/company/airtable-new-direction) to focus its efforts on the enterprise segment, where the upside looks more enticing than any other.
Another no-code platform, Bubble, also seems to be changing direction. Despite boasting a large user base and having raised large, Bubble's efforts to monetize its product weren't as successful. The company is now [repositioning](https://blog.momentumgroup.tech/bubble-ios-new-dedicated-plans-present-a-compelling-alternative-to-expensive-saas-and-enterprise-74b8e374de83) itself, targeting a piece of the ever-growing pie in the enterprise segment. This change comes as a surprise considering the popularity Bubble enjoyed among creative people and professionals with a side project.
## **Data integration becoming a core business concern**
2022 was a year during which organizations became more aware of their data integration problems. The SaaS sprawl, the explosive growth in unstructured data, and the ambition to make data-driven decisions have put data integration under the spotlight. Ensuring high [data quality](/blog/data-quality-dimensions/), breaking [data silos](/blog/data-quality-tips/), and finding the best data integration method for the needs of a business was on top of the agenda for people and organizations alike.
The challenge is to find the optimum combination of databases, data warehouses, and data lakes to satisfy specific data integration needs while balancing speed and operational costs. Terms like data fabric, [data mesh](/blog/data-warehouse-vs-data-mesh/), and [logical data warehouse](/blog/logical-data-warehouse/) made the rounds throughout 2022 as the tech community sought to overcome this challenge. Just the discussion itself was enough to show that organizations of different sizes had data integration problems seeking urgent attention.
The enterprise segment for data integration tools is not without options as long as customers are willing to pay big bucks. However, SMBs and startups are devoid of any realistic solution, despite their growing data integration needs. Aware of this pain point, the Peaka team spent most of the year working on polishing the data integration capabilities of Peaka and unveiled the new Peaka at the end of October. Leveraging data virtualization technology, the new Peaka allows users to bring their data together without having to move or sync it. With our built-to-purpose data integration tool, SMBs and startups will be able to form a single view of truth in 2023 without employing expensive data teams or paying for costly enterprise-grade products.
## **The rise of hard tech**
2022 was a culmination point, with different trends coming together to signal a lasting change in the way hard tech is perceived by governments, entrepreneurs, and investors. It all started with the Covid-19 pandemic in 2020. The rush to develop vaccines highlighted the role biotech companies could play in times of crisis. Then came the supply chain issues in 2021, which particularly hit microchips hard, creating a squeeze in the supply of electronic devices and cars. In 2022, it was the Russian invasion of Ukraine that provided our yearly dose of chaos and uncertainty. The war brought energy prices to not-seen-before levels, with Russia proving that it couldn't be counted on as a reliable supplier of natural gas and oil. Green energy was a nice cause to root for prior to the war; now, it's a matter of sovereignty and industrial policy for governments.
Real-world problems are waiting for real solutions. It looks like stars are aligning for a new era where hard tech projects will become more prominent. Today microchip manufacturing, sustainable energy generation, biotech, automotive, defense, aviation, and space technologies are rejuvenated with a [renewed interest and capital injection](/blog/investors-hard-tech-revival/) not seen in decades. It was the software industry and apps that pushed the frontier of technology in the last decade. 2022 might turn out to be an introduction to a new age of invention and innovation that will transform our lives.
## **AI: Not there yet**
AI was on a charm offensive throughout 2022. People flocked to create illustrations and artwork with OpenAI's Dall-E-2, got into conversations with the same company's AI-assisted chatbot ChatGPT at the end of the year, or whipped up avatars out of their photographs using the Lens app. Although not good for much other than having fun, the popular interest in these toys must have provided an enormous amount of data for these to train on.
However, we don't see a drastic increase in AI adoption rates in business just yet. According to an online survey McKinsey conducted among 1,492 participants, AI adoption has leveled off between [50 and 60 percent](https://www.mckinsey.com/capabilities/quantumblack/our-insights/the-state-of-ai-in-2022-and-a-half-decade-in-review#review) in 2022 despite having more than doubled since 2017. There seems to be a bottleneck here. AI is expected to decrease reliance on humans, but experienced engineering and data science talent capable of implementing AI projects are in short supply, which stops this particular technology from becoming mainstream. In the meantime, companies that have so far achieved high ROI for AI [tend to invest](https://www.mckinsey.com/capabilities/quantumblack/our-insights/the-state-of-ai-in-2022-and-a-half-decade-in-review#gap) in this technology significantly more than other companies and pull away from their competitors as a result.
Since there won't be a sudden increase in the supply of software engineers and data scientists any time soon, we will be counting on low-code/no-code platforms to pick up the slack and make AI accessible to the masses.
## **Conclusion**
2022 was a hectic year for the tech industry and may prove to be a milestone when we look back at it some time in the 2030s. It may go down as the year LCNC platforms became staples in the corporate toolbox, data integration needs of SMBs and startups were recognized, hard tech startups took a leap forward, and AI attained public favor. It could have been just the perfect year if it weren't for the war.
--- START: blog/zapier-no-code-report/zapier-no-code-report.md ---
# **Zapier No-Code Report: An Analysis of the No-code Community**
What we think of ourselves rarely matches how others see us. Russell Westbrook, the all-star guard for the Los Angeles Lakers, probably thinks he is still one of the superstars of the game (his attitude would have you think so) when actually he is having [one of the worst offensive seasons](https://www.silverscreenandroll.com/2022/3/16/22980157/russell-westbrook-lakers-lebron-james-anthony-davis-worst-offensive-season) in the history of the NBA. He could use a reality check, but it would be a challenge to convince a player on a $44 million contract to take a smaller role that could justify his performance.
Things are going extremely well in the no-code land these days. As people working in this particular segment of the software industry, we can't help but get excited about the future: Startups are gaining traction. Even non-tech-savvy people are taking note of no-code tools and slowly awakening to their potential. Capital keeps flowing in at never-seen-before rates. What's there not to like? We think the future belongs to no-code, but is that so? How do the no-coders see their experience with the no-code technology? What can we learn from them?
## **Riding the pandemic wave**
No-code automation platform Zapier has recently published [a report](https://zapier.com/blog/no-code-report/) about the impact no-code has had on individuals and businesses. The findings in the report give us valuable insights into how no-code tools have been received by the community.
The first figure from the report tells us that 82 percent of the no-code users started using no-code tools in the last two years. This piece of information speaks to the transformative effect of the global pandemic, confirming a point we [repeatedly emphasized](/blog/after-deluge-post-pandemic-business-world/) in [our blog posts](/blog/great-resignation-no-code/). The pandemic dealt a powerful and unexpected blow to the business world. Overwhelmed by the lockdowns and labor shortages, companies turned to no-code technologies to automate as many processes as possible and tried to rethink them in a way that incorporates no-code. As a result, no-code tools covered more ground in two years than they would be expected to do in a decade.
## **Developers love no-code**
Another striking point mentioned in the report is the level of technical knowledge the users of no-code platforms have. 88 percent of the respondents in the study possessed some level of coding knowledge, and 35 percent of the respondents are indeed professional developers.
This last figure is in line with the experience we had with our customers, one-third of whom are developers. Although this should make us rethink why people without a coding background struggle to adopt no-code technology, it also demonstrates that developers are open to what no-code can do for them. We can finally put to sleep once and for all the worries about no-code technology and developers becoming [mortal enemies](https://www.forbes.com/sites/forbestechcouncil/2022/03/14/are-no-code-platforms-making-developers-redundant/) and developers not taking no-code tools seriously.
## **A little bit of homework for us**
The biggest hurdles for people working with no-code technology involve troubleshooting moments. People seem to get stuck in case of a problem as they don't know their way around this new domain. Lack of examples is among the cited complaints as well. These struggles come as no surprise, as only 31 percent of the respondents received formal training from their companies about the no-code tools they used. The majority of the respondents seem to be self-taught thanks to watching videos and attending online classes.
The no-code community has come a long way in educating the public, but it looks like our job is not done yet. We must make an organized effort to further lower the barriers for no-coders. Seeking government backing in reskilling employees and students as no-coders would be a step in the right direction for the industry.
At [Peaka](/), we have been expanding our documentation and adding videos to our Youtube channel in order to mitigate such difficulties. The fact that people have trouble solving the problems they run into indicates that no-coders can benefit from a more structured start to app building so that they won't get lost. Templates are great for getting your feet wet in app building if you have no prior experience, and that's why we have been relentlessly growing our collection of ready-made templates.
## **Conclusion**
The bright spot is that 65 percent of people use no-code tools at least once a week. This usage rate implies that these tools have become part of the job for two-thirds of the respondents. Unlike the plethora of other software tools we download and forget about, no-code platforms deliver real business value and keep people engaged.
Zapier's recent study sheds light on the friction points no-coders face. If not dealt with properly, these issues may keep the capabilities of platforms from fully translating into value for the customers. Perfecting the onboarding process and empowering the no-coders to unlock the existing capabilities could help no-code platforms pick the low-hanging fruit. For a no-code platform looking for a high-impact move to improve its bottom line, greasing the wheels for the already-converted no-coders should be the top priority.
--- START: blog/zero-etl-data-integration/zero-etl-data-integration.md ---
# **The Pros and Cons of Zero ETL Explained**
Not a day goes by without a new data-related term coming up. Why? Because harnessing the power of data is the most pressing issue on the agenda nowadays. We keep accumulating data through various tools just because we can. Then, management gurus tell us to use that data to become more data-driven.
But how? How are we supposed to bring together data scattered over numerous data warehouses, data lakes, SaaS tools, and repositories in the first place so that data scientists and analysts can work their magic? As if that were not challenging enough, we must do it with a handful of experts or find a way to democratize the whole process.
If you are done studying terms like data mesh, data fabric, and data virtualization, meet your new homework: Zero-ETL. In this blog post, we find out what it is and whether it can live up to the promise of its name.
## **Why would we need zero-ETL?**
Because the extract-transform-load (ETL) process is like calories, sugar, or fat: You want less of it. But can you get away with no ETL at all?
To understand what zero-ETL is trying to achieve, we should start by analyzing the ETL process that it is trying to replace. ETL involves [moving data to a staging layer](https://www.youtube.com/watch?v=_Nk0v9qUWk4), converting it into the desired format, and then loading it to the desired storage location for it to be consumed by data users. This particular process is the main reason data integration poses such a challenge.
There must be something ETL is doing really well, though, considering how widely it is used in the industry. It is a fast and effective data integration method that works well with legacy systems. Additionally, it introduces security checks and addresses privacy concerns while bringing the data together.
However, ETL has its downsides, too. First of all, it is a labor-intensive and inflexible method by design. Each ETL pipeline is [built for a specific type of transformation.](https://www.youtube.com/watch?v=voC0ewDeltA) Therefore, it has to be reconfigured every time data formats change. It is also high-maintenance as you need to supervise the existing pipelines and ensure that they are working properly. These factors put a strain on IT people and hurt scalability.
## **"*Why don't we drop the T, huh?*"**
Zero-ETL is the outcome of the efforts to create a reliable data integration method without the shortcomings of ETL. It is for those who want to have their cake and eat it, too. Zero-ETL indeed gets rid of the pesky transformation phase, speeding up data integration. However, while doing that, it also sacrifices the standardization and cleansing of the data that comes with the [transformation function](https://en.wikipedia.org/wiki/Extract,_transform,_load#Transform).
Transformation is not a needless chore you should look to dump at all costs, though. It prepares the data so that it can be consumed by the data user. You can eliminate the transformation as a task, but the need to cleanse and standardize the data remains. It just has to be dealt with differently.
The zero-ETL approach tries to get around this problem by keeping the data in a single ecosystem and automating its movement. Amazon's implementation of this method between its [Aurora relational database system and Redshift data warehouse](https://aws.amazon.com/tr/about-aws/whats-new/2022/11/amazon-aurora-zero-etl-integration-redshift/) is a good case in point. By letting its users move their data without performing an ETL, Amazon claims to offer near real-time analytics and machine learning (ML) capability. However, zero-ETL gives up the flexibility of being able to work with different [data sources, cloud environments, and platforms](https://www.matillion.com/resources/blog/mythbuster-would-life-be-better-without-etl) in the meantime.
Now, let's take a tally and summarize the pros and cons of zero-ETL:
## **The pros of zero-ETL**
+ **Speed:** The zero-ETL approach is [faster than the conventional ETL](https://medium.com/starschema-blog/so-whats-all-this-talk-about-zero-etl-integration-aa3b0ca9612b) as the former does not involve the time-consuming data transformation phase.
+ **Efficiency:** The zero-ETL approach requires [less custom programming](https://medium.com/codex/is-the-zero-etl-approach-the-end-of-the-data-engineer-32f34fd434cd), hence less manpower and less duplicate storage, which combine to bring down costs.
+ **Ease of use:** The speed and the elimination of data pipelines make the technology accessible to a broader range of users.
## **The cons of zero-ETL**
+ **Lack of flexibility:** Despite aiming to replace the inflexible ETL method, zero-ETL comes up short on that front. Its flexibility, speed, and ease of use apply only to a small number of use cases where data moves within the same ecosystem.
+ **Not enterprise-friendly:** Due to the vendor lock-in and inability to work with different systems, zero-ETL does not lend itself to use by enterprises that tend to employ different data sources and, among them, legacy systems. It is more suitable for organizations like startups and SMBs where data integration needs are well-defined and predictable.
+ **Limited scope:** Unfortunately, it is not possible to abstract away all the possible transformations, which undermines zero-ETL's capability to address different needs. This method is not suitable for building, managing, and maintaining sophisticated data pipelines. Zero-ETL trades versatility for efficiency and speed in a limited number of situations.
## **What are the most common use cases for zero-ETL?**
Zero-ETL lends itself to a particular brand of products and services that require real-time data:
### **Personalized product recommendations**
Zero-ETL facilitates the delivery of personalized product recommendations to users based on their previous searches. With no data transformation phase required, e-commerce platforms can use zero-ETL to tailor their suggestions to better accommodate user interest.
### **Live business intelligence**
A data management infrastructure leveraging zero-ETL pulls in data from data warehouses, data lakes, and databases and powers dashboards in real-time. This allows business teams to work with real-time metrics instead of the stale data that batch-oriented data integration infrastructure usually generates.
### **Fraud detection**
Real-time ingestion and change data capture (CDC) enables zero-ETL to detect abnormal transactions and identify threats before they materialize. Financial institutions can use zero-ETL-based data management to monitor credit card activity or money transfers and take timely measures to prevent security issues.
### **Internet of Things (IoT) applications**
Real-time data ingestion is the power behind the Internet of Things (IoT) projects. Ingesting sensor data live and comparing it to the previous data stored helps uncover problems with IoT applications before they surface. Zero-ETL data integration also reduces the maintenance hassle as it gives visibility into these systems and prevents failures before they occur.
### **Training artificial intelligence (AI) models**
The success of artificial intelligence (AI) models hinges on the quality of the data they are fed. Up-to-date data helps minimize AI hallucinations and improve the policy suggestions these systems provide. Zero-ETL data integration ensures that LLMs train on fresh data and generate high-quality output without the need for a large data team.
## **Final thoughts**
The merits of a genuine zero-ETL data integration are obvious. The question is whether the technology is there yet and how much the claim of zero-ETL corresponds to reality. It is the issue of a process living up to the name given again, like the ["self-service" data integration](/blog/self-service-data-integration/) we touched upon in our previous blog post.
As is usually the case, there is no one-size-fits-all solution in data integration. Currently, zero-ETL is a quick and easy-to-implement data integration method that only covers select use cases in narrowly-defined ecosystems. It functions like a very specialized form of the data virtualization technique. For use cases where data virtualization is not ideal, it makes more sense to work to improve the good ol' ETL. Reconciling data inconsistencies, standardizing names and type conventions, and building systems that are integrated at the application layer would go a long way toward making the process more efficient.
--- START: blog/zero-etl-vs-modern-data-stack/zero-etl-vs-modern-data-stack.md ---
# **Why Zero-ETL is the Modern Data Stack for Startups**
A startup’s tech stack begins to shape up when it sets up its CRM, payment platform, and various tools to monitor product usage. This setup serves its purpose well with minor adjustments and additions until the startup reaches a headcount of around 20-25 people.
At this point, the ‘flat organization’ principles, which discourage middle management levels and promote collaboration between individuals with overlapping responsibilities, become more difficult to implement. A more hierarchical structure begins to appear, along with departments and new chains of command.
This increase in headcount is usually good news—possibly a consequence of nailing the product-market fit, which brings about an explosion in data. The tech stack at hand fails to handle this new tide of data, so data silos start to form, making it challenging to build a single view of truth. It is around this time that startups get acquainted with the “modern data stack.”
## **Key takeaways**
- The modern data stack is a buzz phrase describing a set of tools and processes centered around data warehouses and ETLs and widely used as data infrastructure by organizations today.
- Despite the hype, the modern data stack is not a good fit for startups due to the high costs and complexity involved.
- Zero-ETL is a viable solution for startups striving to unify and query their data, handle high-velocity event data to track product usage, and [conduct real-time analytics](/blog/data-visualization-with-looker-studio-integration/).
- The three components of zero-ETL—query federation, streaming ingestion, and change data capture—give a startup everything they need from a data stack.
## **The modern data stack: How modern is it, really?**
The term “modern data stack” refers to the one-size-fits-all solution we have had in the data integration realm for quite some time. It consists of
+ a [data warehouse](https://medium.com/@diogo22santos/the-problems-in-the-modern-data-stack-e163faf90fa0) to store your data,
+ ETL pipelines to extract, transform, and load data from different sources into the data warehouse,
+ a data transformation tool,
+ a BI tool for drawing insights from the data you brought together and
+ various other tools for data orchestration, monitoring, and governance.
However, not much is modern about the modern data stack, especially the data warehouse and the ETL pipelines that make up its backbone. These concepts have been around for thirty years. Justin Borgman, [Starburst co-founder and CEO](https://www.starburst.io/blog/lie-2-the-modern-data-stack-is-modern/), is right when he says the modern data stack is ”*just the data stack of decades ago moved to the cloud.*” In fact, there has been so little innovation in the segment in the last few decades that even the introduction of ELT was touted as a breakthrough.
Another sign of the obsolescence of the modern data stack is its lack of solutions for new problems. The modern data stack has specialized in handling enterprise data. It has become so good at this job that it has upgraded the problem many times over, creating fancy terms for every incremental improvement it unlocked.
However, the modern data stack failed spectacularly in providing purpose-built solutions for the data needs of non-enterprise users. The selection of choices available to startups looking to integrate their data is fundamentally the same as an enterprise with tens of thousands of data consumers. They are basically miniaturized or souped-up versions of enterprise solutions that sell startups on features they neither need nor can use. Therefore, money these organizations spend on the modern data stack represents low ROI because it is
+ prohibitively expensive to set up unless you are running an enterprise,
+ costly to maintain, and
+ difficult to use for organizations without sizable data teams.
These challenges are the direct results of the ETL processes involved in the modern data stack.
The “T” in ETL refers to transformation, which involves changing the data format in a way that maps to the target schema used by the destination platform. However, each type of transformation requires a new ETL pipeline, and these pipelines need to be updated as data formats change. This constant need for monitoring and maintaining pipelines renders ETL a labor-intensive process, which organizations without data teams can ill-afford.
So, [the ideal data integration solution](/blog/top-data-integration-tools/) for a startup is one without the ETL processes. What it should include is whole another story.
## **Picking the right tool for your job-to-be-done**
As a startup founder, what’s the “job” you want to get done when you “hire” a modern data stack? You want to consolidate your scattered data, create a single view of truth for everyone on your team, in real time, if possible, and leverage that data to draw insights that can inform your decisions. To cut it short, you want to query your data wherever it resides.
Do you care if you can do this with a sophisticated stack also used by some Fortune 500 company? Probably not. Does it make any difference to you that the cloud data platform you are using raised X gazillions of dollars last month? Not really. You want to bring your data together and query it in the most efficient way possible. Period.
This is a bit like the Internal Combustion Engine (ICE) car vs. Electric Vehicle (EV) debate we have been witnessing for the last few years. You may like the design of an ICE car, the heritage of the brand, and the so-called character it oozes when you rev up its V8 engine. But, purely on the basis of daily utility, your bespoke Bentley cannot hold a candle to a run-of-the-mill Tesla. With its plethora of moving parts, hoses, and fluids, your Bentley is a breakdown waiting to happen. Even keeping it on the road can be a challenge, with those parts getting replaced one by one and at a significant cost.
Tesla, on the other hand, represents a different paradigm: Lean, easy to build (hence, affordable), cheap to run and maintain, and almost failproof. If you are buying a car for your daily commute or want to get from A to B in the most efficient way possible, Tesla is hands down the better option than a gas-guzzling Bentley with hand-crafted wood trim in its dashboard.
The same applies to a startup’s data integration needs: You want to transition from a state of scattered data to one of unified data in the quickest and most efficient way possible. In the meantime, your “non-modern” data stack should allow you to
- connect and query every data source,
- track product usage data so you can understand how your customers are interacting with your product,
- [conduct real-time data visualization](/blog/data-visualization-with-tableau-integration/) while offloading reporting duties of the source database so it does not get overwhelmed.
Thankfully, we finally have an alternative that can provide all three. It is called zero-ETL, but we might as well call it the *real* modern data stack.
## **What's zero-ETL?**
Zero-ETL is defined as “a set of integrations that eliminates or minimizes the need to build ETL pipelines” by [AWS](https://aws.amazon.com/what-is/zero-etl/). This technique offers an innovative and practical way of integrating your data.
The fact that [zero-ETL data integration](/zero-etl-data-integration/) does away with data transformation makes it instantly more suitable for handling a wider range of data sources, as there is no need to engineer the data to fit the schema of the destination. Omitting this intermediary stage translates into cost savings since it reduces the need for data storage and frees up engineering hours that can be used for other value-creating activities.
How you build your data stack with zero-etl (top) vs. conventional data integration (bottom).
## **A closer look at the components of zero-ETL**
Zero-ETL consists of three main components:
### **Query federation**
Having all the data you will ever need in a single location would make your life easier. However, it is neither doable nor necessary. Your data needs are not set in stone, and they will vary over time. What you need is a flexible, easy-to-use, and low-maintenance system that lets you pull in the data you need at any time.
One way of doing that is through query federation. Query federation (or federated query) is a method for fetching data from multiple disparate data sources. It creates temporary virtual tables from the data it pulled in from other systems and allows users to query data stored in remote systems without using any physical ETL process.
The temporary virtual databases created by query federation do not contain the actual remote data but rather the metadata about the remote data. The [metadata serves as a digital catalog](https://www.firebolt.io/glossary-items/query-federation) of where remote data is stored so that it can be pulled in when needed, eliminating the need to copy and move the data from one location to another at predetermined intervals.
- Query federation offers some significant advantages over the conventional data integration methods centered around data warehouses.
- Query federation does away with the prohibitive setup costs of data warehouses as it acts like middleware while bringing data in from remote systems without requiring investment in new hardware.
- Query federation enables users to work with virtual databases without actually moving the data. This helps with data management bills that can quickly get out of hand while using data warehouses.
- The absence of ETL processes in query federation translates into cost savings as maintenance costs tend to be much lower compared to ETL-based data integration methods.
- While data warehouses use batch ingestion and update the data in long intervals, query federation offers real-time or near-real-time data, facilitating decision-making in dynamic environments.
### **Streaming ingestion**
One of the core tenets of data analytics today is the ability to handle and make use of event data. [Events](https://www.tibco.com/reference-center/what-is-event-streaming) are changes in state, such as a transaction or any action a user takes on a website or application. An ordered sequence of these events forms an event stream that can reveal a trove of information for a business.
Being able to ingest event data gives decision-makers visibility into how users use a product or interact with a system. Therefore, it is central to value-creating activities like product development, UX design, and growth frameworks such as product-led growth.
However, ingesting event data poses a serious challenge for organizations. It requires the capability to deal with a continuous stream of high-volume, high-velocity data and simultaneously join it with data from other sources if need be. This stream can easily overwhelm a conventional database, and you can’t keep up with it by manually entering data if you prefer to use a big data table format.
This is where streaming ingestion comes into play. [Streaming ingestion](https://www.dremio.com/wiki/streaming-ingestion/) is a low-latency process for continuously ingesting high-velocity data from streaming sources such as IoT sensors, various apps, networked devices, or online transactions. While batch processing involves large amounts of data being processed at regular, predetermined intervals, streaming ingestion allows for real-time or near-real-time data processing.
Streaming ingestion is what enables digital marketing teams to listen to social media platforms for mentions, reviews, and feedback and continuously gauge how public opinion views a brand and a product. This technique also allows a product team to track usage data so they can remove the friction points from the SaaS app they are building.
Actioner, one of the first customers of Peaka, was tested by the challenges of handling event data early on. Its stack consisted of HubSpot (for customer info and emails), Segment (for event data), and DynamoDB (for the app IDs and flow IDs that tie events to the customer emails). There were a few options for handling the high-volume event data Segment pumped into Actioner’s databases, but none of them were ideal:
- PostgreSQL did not work after a certain threshold as storage and querying became problematic.
- Keeping the Segment data on the file system could be an option but that would render querying the data difficult.
- Storing that data in one of the big data table formats would require manual data entry, which would not be practical.
Actioner needed to invest in a whole new data stack to deal with this challenge. Instead, they chose to go with Peaka and were able to set up a stack in minutes and handle the Segment data. Peaka made a difference here by buffering that data and loading a big portion of it via bulk-insert.
The Actioner team can now identify individual customers in the huge pile of data being sent by Segment and spot where they are in their respective journeys. This gives them deeper insights into how their customers convert and upgrade, helping them adjust messaging accordingly.
### **Change data capture (CDC)**
[Change data capture](https://www.striim.com/blog/change-data-capture-cdc-what-it-is-and-how-it-works/) (CDC) is the process of spotting and capturing changes made in a database. By [targeting and capturing only the incremental changes](https://www.pingcap.com/blog/change-data-capture-cdc-first-steps-getting-started-tidb) made to data, the CDC reduces your workload as you no longer have to scan whole databases for changes. Having spotted the changes in a database, the CDC then transfers them to downstream processes and systems in real time as new database events occur. This process helps keep data in sync and is perfect for data environments where high-volume data is changed frequently.
The CDC lends itself to use in a cloud-based infrastructure because continuous real-time updates to data keep it fresh, minimizing the possible downtime needed for [data migration](https://www.qlik.com/us/change-data-capture/cdc-change-data-capture).
The CDC also helps with optimizing resource allocation and upholding system performance. The data replication carried out by the CDC creates an analytics database that can be used for resource-intensive querying. This helps offload main database systems, shielding them from excess load.
Another use case that the CDC fits perfectly is [real-time data analytics](/blog/data-visualization-with-metabase-integration/). Nightly updates to data render it stale, and yesterday’s data does not hold much value for the decisions you need to make today if you are operating in a dynamic environment. The CDC enables data consumers to access the most up-to-date data at all times, making data-driven decision-making possible. The [log-based version of the CDC](https://www.confluent.io/learn/change-data-capture/), particularly, achieves this without creating any extra computational stress on source databases. Data consumers enjoy [real-time data replication](https://dzone.com/articles/leveraging-change-data-capture-for-fraud-detection) in this method while accessing only the changes in transaction logs rather than the source databases themselves.
## **6 reasons why zero-ETL is the modern data stack for the generative AI era**
The emergence of generative artificial intelligence (AI) has transformed the data landscape. Before this era, data management was predominantly a batch-oriented process serving predictable and mostly scheduled requests for reporting purposes. It was reliant on data warehouses, ETL pipelines, and continuous data replication and movement. This traditional data integration and management method needed large data teams for implementation, which rendered it prohibitively expensive for non-enterprise organizations.
With the widespread adoption of AI applications, data integration and management processes need to become more dynamic. [Real-time data](/blog/data-visualization-with-superset-integration/) is no longer a nice-to-have for these systems but a must for use cases such as fraud detection, product recommendation, autonomous driving, or humanoid robotics. However, traditional ETL pipelines cannot provide real-time or near-real-time data flows for these scenarios.
This is where zero-ETL comes into play:
1. Zero-ETL minimizes the latency of the traditional data integration process, providing AI systems with the live data they need.
2. By eliminating ETL pipelines and enabling systems to query data at its source, zero-ETL reduces complexity and allows engineering teams to do more with less.
3. Zero-ETL also allows for more scalable data architectures as it does not involve brittle data pipelines that require constant maintenance.
4. Zero-ETL removes the need for a data warehouse as it accesses the data at its source instead of copying and moving it to a data warehouse. This results in significant cost savings for an organization.
5. By not replicating data, zero-ETL puts an end to data sprawl and facilitates compliance with regulations such as GDPR and HIPAA.
6. Training AI on stale data results in misleading output from the system. Zero-ETL ensures that the AI systems have access to fresh data, improving the insights they will provide.
The generative AI applications we turn to for every little question that pops up in our minds run on data. Zero-ETL solves the data aggregation problem enterprises face and accelerates AI adoption in these organizations.
## **Conclusion**
The modern data stack is based on a three-decades-old method of data integration. It is an invasive method that meddles with how companies are organized. Its gravitational pull forces other processes to change so they can fit with the modern data stack.
With zero-ETL, startups get a lightweight approach to data integration that won’t pull resources away from other functions—something they can plug-and-play at will without a thorough reorganization of the way they operate. Zero-ETL allows startups to be startups, without having to operate like enterprises when they lack the means to.
--- START: docs/api-reference/api-reference.md ---
# Peaka Partner API
The Peaka Partner API is a powerful gateway that lets you seamlessly integrate Peaka's features into your own applications and services. With secure access provided through a unique API key, you can leverage the full potential of Peaka's capabilities to enhance your user experience and streamline operations.
- [OpenAPI specification](https://www.peaka.com/api/peaka-openapi.json) — View or download the raw OpenAPI document.
- [Postman Collection](https://www.postman.com/peaka-api/peaka-api/collection/znssuf9/partner-api) — Explore and run the Peaka Postman Collection.
## Key Features
- **Secure Authentication**: Access the API with confidence using the apiKey provided by Peaka, ensuring secure and authorized interactions.
- **Robust Functionality**: Utilize a wide range of functions, from data retrieval to executing complex operations, all tailored to meet diverse integration needs.
- **Real-Time Data Access**: Retrieve up-to-the-minute information to keep your services synchronized with the latest developments within Peaka.
- **Customizable Integration**: Tailor the API's extensive features to fit your platform's specific requirements, providing a personalized experience for your users.
- **Scalability**: Designed to handle requests at scale, the Peaka Partner API can accommodate growing traffic as your business expands.
- **Dedicated Support**: Benefit from Peaka's dedicated support for API integration and usage.
## Getting Started
- **API Key Activation**: Create your unique apiKey from the Developer section in Peaka Studio. This key is essential for all API requests.
- **Pick your zone**: The API is served from US and EU zones — see [Servers](https://www.peaka.com/docs/api-reference/?page=servers) for base URLs and guidance.
- **Authenticate**: Send the key as a Bearer token — see [Authentication](https://www.peaka.com/docs/api-reference/?page=authentication).
- [Manage your Partner API Key](https://www.peaka.com/docs/cookbook/how-to-manage-partner-api-key/) — Step-by-step guide in the Cookbook.
- [Generate Project API Keys](https://www.peaka.com/docs/cookbook/how-to-generate-api-keys/) — Create project-scoped keys in Peaka Studio.
## Support and Assistance
Our dedicated team is available to assist you throughout the integration process and beyond. Should you have any questions or require technical support, please reach out through the [Peaka Community](https://www.peaka.com/community) or email [support@peaka.com](mailto:support@peaka.com).
---
# Servers
The Peaka API is hosted in two geographic zones to ensure optimal performance, compliance, and data residency for users worldwide. Each zone has its own server endpoint, allowing you to choose the one that best suits your location, regulatory requirements, and latency needs.
- **US Zone**: `https://partner.peaka.studio/api/v1`
- **EU Zone**: `https://eu.partner.peaka.studio/api/v1`
## Choosing the Right Zone
### Geographic Proximity
- Use the **US Zone** if your operations or users are primarily based in North America. This reduces latency and improves performance for users in that region.
- Use the **EU Zone** if your operations or users are primarily based in Europe or if you need to comply with EU data protection regulations, such as GDPR.
### Compliance and Data Residency
- The EU zone is designed to meet strict data residency and privacy requirements, making it ideal for organizations operating under European regulations.
- The US zone is optimized for users in North America but may also be suitable for global operations outside the EU, depending on your compliance needs.
### API Functionality
Both zones offer identical API functionality, endpoints, and features. The only difference is the geographic location of the servers and the domain used to access them.
## Making API Requests
Include the appropriate base URL (depending on your chosen zone) in your API requests. For example:
```bash
# US-based request
GET https://partner.peaka.studio/api/v1/supportedDrivers
# EU-based request
GET https://eu.partner.peaka.studio/api/v1/supportedDrivers
```
Ensure that your API key is included in the request headers as described in the Authentication section.
---
# Authentication
The Peaka Partner API uses API keys for authentication. There are two types of API keys:
- **Partner API Key**: Grants access to all resources for partner-level access.
- **Project API Key**: Grants access to resources specific to the project for which the key was created.
- [Manage a Partner API Key](https://www.peaka.com/docs/cookbook/how-to-manage-partner-api-key/) — Create and rotate partner-level keys.
- [Generate API Keys](https://www.peaka.com/docs/cookbook/how-to-generate-api-keys/) — Create project-scoped keys in Peaka Studio.
While **Project API Keys** are restricted to project-specific resources, **Partner API Keys** provide broader access across all available resources. Badges next to endpoint descriptions indicate which type of API key can be used.
## Using your key
Include the API key in the `Authorization` header as a Bearer token:
```http
Authorization: Bearer
```
**Example: Using a Partner API Key**
A **Partner API Key** can perform all actions a **Project API Key** can, plus partner-level operations. For example, to list all organizations accessible by the partner:
```http
GET api/v1/organizations
Authorization: Bearer
```
You can also use a Partner API Key on project-scoped endpoints:
```http
GET api/v1/data/projects/{projectId}/catalogs
Authorization: Bearer
```
**Example: Using a Project API Key**
Project keys work on endpoints scoped to their project — whenever you see `projects/{projectId}` in a path, it is project-scoped:
```http
GET api/v1/data/projects/{projectId}/catalogs
Authorization: Bearer
```
Replace `{projectId}` with the ID of your project.
---
# Structure
Peaka provides a structured environment for managing data integrations and analytics. Understanding the hierarchy and relationships between its core components is essential for effective utilization.

## 🔹 Organization
- **Definition**: The top-level entity representing a business or team within Peaka.
- **Role**: Serves as the container for all workspaces, projects, and associated resources.
- **API Endpoint**: `GET /organizations` to list all organizations.
## 🔹 Workspace
- **Definition**: A collaborative environment within an organization where teams can manage projects.
- **Role**: Facilitates team collaboration and resource management within an organization.
- **API Endpoint**: `GET /organizations/{organizationId}/workspaces` to list workspaces within an organization.
## 🔹 Project
- **Definition**: A unit within a workspace where data connections are established and workflows are executed. This is the core component of Peaka. Projects are isolated from other projects within the same workspace. You can create **Project API Key**s to enable access to only this project.
- **Role**: Central unit for data operations, including queries, tables, and integrations.
- **API Endpoint**: `POST /organizations/{organizationId}/workspaces/{workspaceId}/projects` to create a new project.
## 🔹 Connection
- **Definition**: A configuration that links a project to external data sources, such as databases or APIs, including necessary credentials.
- **Role**: Holds the necessary details for connecting to external data sources.
- **API Endpoint**: `POST /projects/{projectId}/connections` to establish a new connection.
- **Note**: A single connection can be used to create multiple catalogs, allowing credential reuse across catalogs of the same external data source.
## 🔹 Catalog
- **Definition**: A structured representation of data schemas and tables associated with a connection.
- **Role**: Provides metadata and structure for querying and analyzing data.
- **API Endpoint**: `POST /projects/{projectId}/catalogs` to create a catalog using a connection.
- **Note**: Multiple catalogs can be created from a single connection, each representing different naming of the same external source.
## Machine-readable specification
Every endpoint, with request and response schemas, is defined in the OpenAPI document at https://www.peaka.com/api/peaka-openapi.json. The interactive reference at https://www.peaka.com/docs/api-reference/ renders that same file and can send live requests.
--- START: guides/build-health-dashboard-zendesk-hubspot-stripe/build-health-dashboard-zendesk-hubspot-stripe.md ---
## Project Overview
Before customer dissatisfaction snowballs into churn, what if you could spot the early signs from support tickets, health scores, and revenue trends, all in one dashboard?
In this tutorial, you will build a **customer health dashboard** that integrates data from **Zendesk**, **Hubspot**, and **Stripe** to track key metrics like **support tickets**, **average MRR (Monthly Recurring Revenue)**, **health scores**, and **churn risk**, all in one unified view. The goal is to help **customer success teams**, **product managers**, and **sales leaders** spot early warning signs, improve retention, and reduce churn.
This dashboard delivers real value for:
- **Customer success teams** focused on proactive churn prevention
- **Product managers** looking for deeper insights into account health
- **Growth and revenue teams** aiming to maximize customer lifetime value and reduce churn costs
Best of all, instead of spending weeks on complex **data integration** and dashboard development, you will build this entire solution in just a few hours using **Peaka** for seamless data unification and **v0.dev** for fast frontend generation.
This dashboard serves as a starting point, a foundational solution that you can build upon and customize further as your needs grow. While it covers key customer health metrics, you can easily extend it with more data sources, advanced analytics, or deeper integrations over time.
## The Tools We Need
To build this customer health dashboard, we'll rely on a streamlined set of tools that simplify data integration and frontend development without the complexity of traditional data engineering.
### Peaka
Peaka acts as the central platform that connects to your existing data sources and lets you join, transform, and model your data in one place using SQL queries. This approach eliminates the need for setting up complex ETL pipelines or managing separate data warehouses, making it faster and easier to create unified views of your customer data while keeping full control over the data logic.
### v0.dev
Once your data models are ready in Peaka, v0.dev enables you to generate a polished, functional dashboard interface using prompt-based UI creation. This allows you to build and iterate on your frontend quickly without writing boilerplate code.
### Data Sources
We'll connect Peaka to familiar platforms like Zendesk, Hubspot, and Stripe to pull support ticket data, customer health scores, and subscription revenue information. These integrations provide the raw data needed to power the dashboard's key metrics.
## What is Peaka?
Peaka is a cloud-native data platform that enables teams to connect, transform, and query data from multiple sources in real-time using standard SQL. Unlike traditional data warehouses that require complex ETL pipelines and data duplication, Peaka provides **virtualized data models** that join and aggregate live data without moving it.
In this project, Peaka acts as the **central data layer**, unifying disparate datasets from Zendesk, Hubspot, and Stripe into clean, queryable virtual tables. This approach allows you to maintain data freshness and consistency while avoiding the overhead of managing separate infrastructure.
Peaka's SQL-first design empowers data engineers and analysts to define business logic directly in the platform, accelerating development cycles and improving data governance. Its seamless integration with downstream tools like v0.dev enables rapid frontend development based on these robust data models.
By using Peaka, you get the best of both worlds: the flexibility and control of SQL with the efficiency and scalability of a modern data platform.
## Let's Dive In
### Step 1: Setting Up Your Peaka Project
Before connecting data sources or writing queries, you'll need to create a Peaka project and generate an API key for authentication.
Follow these steps:
1. Go to [peaka. studio](https://peaka.studio/) and log in.
> If you don't have an account yet, sign up. It only takes a couple of minutes.
2. From your dashboard, click **Create New Project** and give it a name.
3. Open your newly created project and click the gear icon (⚙️) in the bottom-left sidebar to open **Settings**.
4. In the **Settings** panel, go to the **API Keys** tab and click **Create API Key**.
5. Copy your **Project ID** from the URL in your browser's address bar. It should look like this:
```text
https://peaka.studio/studio/{project_id}/...
```
> Make sure to save both your API key and Project ID somewhere safe, you'll need them in the next step when connecting Peaka to your app.
### Step 2: Connect Your Data Sources
Let's start by connecting your first data source, **Zendesk**.
1. Go to your Peaka workspace and click the **+ Data Source** button at the top left.
2. In the search bar, type **Zendesk**, then select it from the list.
3. Click **Add New Connection**.
4. Enter a **Connection Name** and your **Zendesk subdomain**.
5. Click **Sign In**, and authorize Peaka to access your Zendesk account.
Once this process is complete, your Zendesk data will be ready to use inside Peaka.
Next, follow a similar process to connect **HubSpot,** search, select, and authorize via the OAuth screen. For **Stripe**, you'll instead use your Stripe API key when creating the connection.
Need help? You can find step-by-step instructions for each connector in the Peaka documentation:
- [Zendesk Integration Guide](/docs/integrations/zendesk)
- [HubSpot Integration Guide](/docs/integrations/hubspot)
- [Stripe Integration Guide](/docs/integrations/stripe)
### Step 3: Creating Your Queries
To build a dashboard, you'll first need to define the queries that power your metrics. Here’s how you can create a query on Peaka:
1. Navigate to the **Queries** section in the left sidebar.
2. Click **➕ New Query** to start creating a new SQL query.
3. Choose **Start from Scratch** instead of using a template. (You can explore templates later for common use cases.)
4. Write your SQL and click **Run** to preview the results.
For a more detailed guide on how to create queries in Peaka, check out [this documentation page](/docs/connecting-your-data/creating-query).
Let’s go through the core queries you'll need:
### 1. Active Tickets
This query shows how many active support tickets (with statuses "open" or "pending") each user has created in the past 30 days. It helps identify users who may need more urgent support.
```sql
SELECT
u.email AS requester_email, -- Requester's email address
COUNT(*) AS active_ticket_count -- Count of active tickets per user
FROM "zendesk"."public"."tickets" t
JOIN "zendesk"."public"."users" u ON t.requester_id = u.id
WHERE t.status IN ('open', 'pending') -- Only tickets that are still open or pending
AND t.created_at >= CURRENT_DATE - INTERVAL '30' DAY -- Tickets created in the last 30 days
GROUP BY u.email; -- Group results by user email
```
### 2. Monthly Recurring Revenue (MRR)
This query calculates the monthly recurring revenue (MRR) per customer by summing up the unit amounts of active or recently incomplete subscriptions. Useful for understanding current revenue flow.
```sql
SELECT
c.email AS customer_email, -- Customer's email address
SUM(p.unit_amount / 100) AS mrr_usd -- Sum of subscription amounts (converted from cents to dollars)
FROM "stripe"."payment"."subscriptions" s
JOIN "stripe"."payment"."customers" c ON s.customer_id = c.id
JOIN "stripe"."payment"."prices" p ON s.plan_id = p.id
WHERE s.status IN ('active', 'incomplete_expired', 'incomplete') -- Active or recently incomplete subscriptions
GROUP BY c.email; -- Group results by customer email
```
### 3. Churn Risk
This query identifies customers who have recently submitted a high number of support tickets and cross-references them with their subscription activity to assess churn risk levels.
```sql
WITH active_tickets AS (
SELECT
u.email AS customer_email, -- Email of the customer who submitted tickets
COUNT(*) AS ticket_count -- Number of tickets created in the last 30 days
FROM "zendesk"."public"."tickets" t
JOIN "zendesk"."public"."users" u ON t.requester_id = u.id
WHERE t.created_at >= CURRENT_DATE - INTERVAL '30' DAY
GROUP BY u.email
),
active_subscriptions AS (
SELECT
c.email AS customer_email, -- Customer email from Stripe
MAX(s.ended_at) AS last_payment_date -- Last subscription end date
FROM "stripe"."payment"."subscriptions" s
JOIN "stripe"."payment"."customers" c ON s.customer_id = c.id
WHERE s.status = 'active'
GROUP BY c.email
)
SELECT
at.customer_email, -- Email from active tickets
at.ticket_count, -- Number of tickets submitted
CASE
WHEN at.ticket_count > 5 AND (asub.last_payment_date IS NULL OR asub.last_payment_date < CURRENT_DATE - INTERVAL '30' DAY) THEN 'High' -- High risk if many tickets and no recent payment
WHEN at.ticket_count > 3 THEN 'Medium' -- Medium risk if moderate ticket count
ELSE 'Low' -- Otherwise low risk
END AS churn_risk
FROM active_tickets at
LEFT JOIN active_subscriptions asub ON at.customer_email = asub.customer_email;
```
### 4. Account Health Score
This query calculates a composite health score for each customer by combining their active subscription status, recent open tickets, and churn risk level. The score helps prioritize accounts needing attention.
```sql
WITH ticket_stats AS (
SELECT
u.email AS customer_email, -- Customer email from Zendesk users
COUNT(*) FILTER (WHERE t.status IN ('open', 'pending') AND t.created_at >= CURRENT_DATE - INTERVAL '30' DAY) AS open_tickets_last_30d, -- Number of open tickets in last 30 days
COUNT(*) AS total_tickets -- Total number of tickets
FROM "zendesk"."public"."tickets" t
JOIN "zendesk"."public"."users" u ON t.requester_id = u.id
GROUP BY u.email
),
active_subscriptions AS (
SELECT
c.email AS customer_email, -- Customer email from Stripe
COUNT(*) > 0 AS has_active_subscription -- Boolean flag for active subscription
FROM "stripe"."payment"."subscriptions" s
JOIN "stripe"."payment"."customers" c ON s.customer_id = c.id
WHERE s.status = 'active'
GROUP BY c.email
),
churn_risk_calc AS (
SELECT
ts.customer_email,
CASE
WHEN ts.open_tickets_last_30d > 5 AND (asub.has_active_subscription = false OR asub.has_active_subscription IS NULL) THEN 'High' -- High churn risk if many open tickets and no active subscription
WHEN ts.open_tickets_last_30d > 3 THEN 'Medium' -- Medium churn risk for moderate open tickets
ELSE 'Low' -- Otherwise low risk
END AS churn_risk
FROM ticket_stats ts
LEFT JOIN active_subscriptions asub ON ts.customer_email = asub.customer_email
)
SELECT
ts.customer_email,
COALESCE(asub.has_active_subscription, false) AS active_subscription, -- Whether customer has active subscription
ts.open_tickets_last_30d, -- Number of open tickets in last 30 days
crc.churn_risk, -- Churn risk level
(
CASE WHEN COALESCE(asub.has_active_subscription, false) THEN 50 ELSE 0 END + -- Add 50 points if active subscription
CASE WHEN ts.open_tickets_last_30d = 0 THEN 20 ELSE 0 END + -- Add 20 points if no open tickets
CASE WHEN ts.open_tickets_last_30d > 5 THEN -20 ELSE 0 END + -- Subtract 20 points if more than 5 open tickets
CASE WHEN crc.churn_risk = 'High' THEN -30 ELSE 0 END -- Subtract 30 points if high churn risk
) AS account_health_score -- Final calculated health score
FROM ticket_stats ts
LEFT JOIN active_subscriptions asub ON ts.customer_email = asub.customer_email
LEFT JOIN churn_risk_calc crc ON ts.customer_email = crc.customer_email;
```
### Step 4: How to Build the Dashboard on v0.dev
Once your queries are ready on Peaka, the next step is turning them into a full-stack dashboard UI. This section explains how to use [v0.dev](https://v0.dev/), an AI tool that generates production-grade UIs from prompts, to build a fully responsive dashboard with zero boilerplate.
Here's how to go from saved queries to a fully functional customer health dashboard:
---
### Write the Prompt for v0.dev
Begin by preparing a detailed prompt that describes your goal. Here's an example prompt you can adapt:
```markdown
I have a Peaka account and a Peaka project that contains four saved queries:
- active_tickets: Returns number of active support tickets per customer
- mrr: Returns monthly recurring revenue (MRR) per customer
- account_health_score: Returns a numeric health score between 0 and 100 for each customer
- churn_risk: Returns churn risk category ("Low", "Medium", or "High")
I want to build a full-stack customer health dashboard in Next.js, using React and Tailwind CSS.
The dashboard layout should include:
Top section (4 metric cards):
- Total active tickets
- Average MRR
- Average account health score
- High churn risk percentage
Bottom section (charts):
- Bar chart showing MRR by customer
- Pie chart showing churn risk distribution
- Histogram (bar chart) of health score distribution in buckets
- Scatter plot of active tickets vs MRR, with churn risk as point color
All data should be fetched directly from Peaka's data API using fetch.
To get data from a Peaka query, I will use the following API pattern:
POST https://partner.peaka.studio/api/v1/data/projects/{projectId}/queries/execute
Authorization: Bearer
Content-Type: application/json
Body:
{
"from": [
{
"catalogName": "peaka",
"schemaName": "query",
"tableName": "mrr" // or "active_tickets", etc.
}
]
}
Each query will be executed this way from the frontend. You can assume the token is stored in an .env file or injected via a helper function.
Please generate the full dashboard code as a single `dashboard.tsx` page, using `fetch` to call these APIs from the browser. Use Tailwind CSS for layout. For charts, you can use Recharts or another modern charting library.
You can check Peaka's API reference here: https://docs.peaka.com/api-reference/introduction
Make the code developer-friendly and easy to customize.
```
This prompt provides enough context for v0 to generate a complete dashboard layout with proper data bindings and visualizations.
---
### Set Up Environment Variables
After generating the UI, v0 will request environment variables for secure access to your Peaka project. Add the following to your `.env` file:
```dotEnv
PEAKA_API_KEY=your_api_key_here
PEAKA_PROJECT_ID=your_project_id_here
```

These values are injected into your app and used when making authenticated `fetch` calls to Peaka's Data API.
---
### Verify API Calls and Response Handling
v0 generates initial API logic based on your prompt. To ensure accuracy:
- Review how `fetch` requests are constructed (especially the body structure)
- Compare it with [Peaka's API documentation](https://docs.peaka.com/api-reference/data--queries/execute-query)
- Add sample request and response objects from the docs directly into your prompt (if needed) to improve alignment
Pay close attention to fields like `catalogName`, `schemaName`, and `tableName`, these need to be exactly as defined in your Peaka query setup.
---
### Make Final Adjustments
Once the initial dashboard is generated:
- Refine how response data is parsed into metrics and chart series
- Tweak chart components (tooltips, colors, legends, bucket logic)
- Adjust layout and spacing using Tailwind utility classes
- Simplify or restructure component logic for maintainability
These small improvements will help polish the UI and make the dashboard easier to customize for future use cases.
---
Within minutes, you'll have a live, responsive, developer-friendly customer health dashboard, powered by real-time data from Peaka and built entirely through prompt-driven development.

## Real-World Use Cases
Different roles across a company can benefit from these metrics in meaningful ways. For instance, a **Customer Success Manager** might regularly track Account Health Scores and Active Tickets to prioritize accounts that need immediate attention or proactive engagement. If an account shows a declining health score and an increasing number of unresolved tickets, it's a clear signal to intervene before churn becomes inevitable.
On the other hand, a **Revenue Manager** could use MRR data to analyze revenue growth trends and identify which customer segments are driving the most value. By tying this insight with churn risk data, he/she can spot weak points in the customer journey and collaborate with other teams to improve retention.
Meanwhile, **Product Teams** can look at churn-prone accounts to understand usage patterns, or the lack thereof. If many of the accounts with high churn risk share a common behavior (e.g., not using a key feature), it becomes a product insight that could inform roadmap priorities or onboarding improvements.
And of course, **Executives** benefit from seeing the bigger picture, how health scores, support loads, and revenue trends correlate across the business. Having these metrics aggregated and visualized in one place enables faster, more informed strategic decisions.
## Before Peaka and v0.dev: The Legacy Approach
Before tools like Peaka, tracking customer metrics across Stripe and other platforms meant stitching together multiple data sources manually.
To calculate metrics like MRR or active support tickets, teams often relied on:
- Exporting CSVs from Stripe, Intercom, and Jira
- Writing custom SQL scripts in local notebooks or BI tools
- Setting up and maintaining pipelines to sync these exports into a central database
- Using spreadsheet formulas to aggregate or visualize key numbers
This approach was:
- **Time-consuming**: Writing and maintaining queries required technical expertise.
- **Error-prone**: Each manual export introduced chances for mismatched data or outdated snapshots.
- **Hard to scale**: As the number of metrics or tools increased, keeping everything in sync became a full-time job.
- **Poorly democratized**: Business and support teams had to wait for engineers or analysts to fetch the numbers they needed.
Even with all this effort, the insights often remained fragmented and delayed.
## Key takeaways
- With v0 and Peaka, you can build customer dashboards from natural language prompts, no coding or manual setup required.
- Peaka brings data from multiple platforms into one place, eliminating the need for custom pipelines or integrations.
- Teams like Customer Success, Product, and Account Management can monitor churn risk, MRR, and ticket activity in real time.
- By replacing spreadsheets and scattered tools, Peaka creates a single source of truth for customer health metrics.
## Conclusion
In this example, we combined data from different sources using Peaka's robust integration layer and SQL-based interface. Then, with just a few steps, we plugged that data into v0 and built a working dashboard UI in no time. The seamless integration between Peaka and v0 made it incredibly easy to go from raw data to visual output, without setting up a backend or writing complex code. It's a simple yet powerful way to prototype data-driven apps fast.
--- START: guides/how-to-build-churn-dashboard/how-to-build-churn-dashboard.md ---
# Project Overview
What if your high-paying customers try to tell you something before they churn, and you don’t catch it?
In this tutorial, you will build a dashboard that identifies **Pro- and Enterprise-tier subscribers who contacted support shortly before canceling** their subscriptions. The goal is to help support and product teams understand churn patterns and take action before it’s too late.
This dashboard provides real value for:
- **Customer support teams** looking to spot at-risk users,
- **Product managers** needing context around cancellations,
- **Growth and revenue teams** focused on reducing churn.
Best of all, instead of spending days coding, you will build this entire system in **just 1 hour** using **Peaka** for data integration and **v0.dev** to generate the frontend.
## The Tools You’ll Need / The Stack
Here’s what you’ll use to bring everything together:
- **Peaka** – A no-code data integration platform that connects and joins data from Stripe and Zendesk, then turns those queries into APIs you can consume.
- **v0.dev** – An AI-powered tool that generates a full-stack dashboard UI based on a simple natural language prompt.
- **Stripe + Zendesk** – The core data sources providing subscription details and customer support tickets, respectively.
---
### Why Peaka?
Peaka is a no-code data operations platform that enables you to:
- Connect to external data sources like APIs, databases, and SaaS applications,
- Model your data as **virtual tables** without moving or duplicating it,
- Create APIs on top of those virtual tables to serve your applications.
For this dashboard, Peaka provides:
- A seamless way to **connect Zendesk and Stripe data** by matching customer emails,
- A flexible query builder that lets you **join support tickets with subscription data** using SQL,
- Ready to use API endpoints that you can call directly from your app.
By using Peaka, you avoid building and maintaining a custom backend, saving significant development time and complexity.
---
### Why v0.dev?
With v0.dev, you can:
- Skip writing any frontend code. Just describe your app in a prompt,
- Get a fully functional, developer-friendly UI generated for you,
- Automatically generate backend integration logic that connects to Peaka’s APIs,
- Easily adapt your app by updating prompts or API specs and regenerating the code.
## Let's Start
### Step 1: Setting Up Your Peaka Project
Before you start building, you need to set up your Peaka workspace and generate an API key for authentication.
Follow these steps:
1. Go to [peaka.studio](https://peaka.studio/) and log in.
> If you don’t have an account yet, sign up. It only takes a minute.
2. Create a **new project** from your dashboard.
3. Open your new project, then click the gear icon (⚙️) in the bottom left sidebar to open **Settings**.
4. In **Settings**, navigate to the **API Keys** tab and create a new API key.
5. Copy your **Project ID** from the URL in your browser’s address bar. It should look like this: `https://peaka.studio/studio/{project_id}/..`
Save both the API key and Project ID safely, you’ll need these when connecting Peaka to v0.dev.
### Step 2: Connecting Data Sources in Peaka
With your project set up, it’s time to bring in your external data.
In this example, you’ll connect **Stripe** and **Zendesk** to Peaka. These will serve as the foundation for your churn and support analysis.
---
#### Connecting Stripe
- In your Peaka project, click the **➕ Add** button on the left sidebar to open the **Connector List**.
- Use the search bar to find **Stripe** among the available connectors.
- Select it, give the connection a name (e.g., `stripe_main`), and enter your **Stripe API Key**.
- Click **Connect,** and you’re done!
Your Stripe data will now appear under your connected data sources.


#### Connecting Zendesk
- Back in the **Connector List**, search for **Zendesk** and select it.
- Since Zendesk supports **OAuth authentication**, setup is quick and easy.
- Provide a **connection name** and your **Zendesk subdomain** (e.g., `yourcompany.zendesk.com`).
- Peaka will redirect you to Zendesk for login and authorization. Once approved, the connector will be activated.
- You’ll now have access to **Zendesk tickets and user data** within Peaka, no API handling required.

---
By the end of this step, both **Stripe** and **Zendesk** will be live in your Peaka project fully authenticated and ready to query.
### Step 3: Writing Queries in Peaka
With Stripe and Zendesk connected, it’s time to extract insights by writing queries across both data sources.
---
#### Creating a New Query in Peaka
- From the left sidebar, go to the **Queries** section.
- Click **➕ New Query** to create a new SQL query.
- Choose **Start from Scratch** instead of using a template.
> (You can explore Peaka’s templates later for common use cases.)
- Write the following SQL queries and click **Run** to preview the results.


---
#### Query 1: Support Tickets Submitted Shortly Before Churn
This query finds **Pro or Enterprise users** who submitted a support ticket **within 14 days before canceling** their subscription.
Use it to identify customers who might have been unhappy or struggling and possibly prevent future churn.
```sql
SELECT
u.name,
prod.name AS plan_name,
z.subject,
z.description,
u.email AS customer_email
FROM
"zd"."public"."tickets" z
JOIN
"zd"."public"."users" u ON z.requester_id = u.id
JOIN
"stripe"."payment"."customers" c ON u.email = c.email
JOIN
"stripe"."payment"."subscriptions" sub ON c.id = sub.customer_id
JOIN
"stripe"."payment"."plans" p ON sub.plan_id = p.id
JOIN
"stripe"."payment"."products" prod ON p.product_id = prod.id
WHERE
prod.name IN ('Pro Plan', 'Enterprise Plan')
AND sub.canceled_at IS NOT NULL
AND z.created_at BETWEEN (sub.canceled_at - INTERVAL '14' DAY) AND sub.canceled_at
ORDER BY z.created_at DESC
LIMIT 100;
```
---
#### Query 2: All Tickets from Premium Users
This query retrieves **all support tickets** submitted by **Pro and Enterprise plan** users, whether they churned or not.
It’s useful for exploring the overall support volume, issue trends, and satisfaction signals from your premium customer base.
```sql
SELECT
u.name AS customer_name,
prod.name AS plan_name,
z.subject AS ticket_subject,
z.description AS ticket_description,
u.email AS customer_email,
z.priority,
z.status,
z.updated_at
FROM
"zd"."public"."tickets" z
JOIN
"zd"."public"."users" u ON z.requester_id = u.id
JOIN
"stripe"."payment"."customers" c ON u.email = c.email
JOIN
"stripe"."payment"."subscriptions" sub ON c.id = sub.customer_id
JOIN
"stripe"."payment"."plans" p ON sub.plan_id = p.id
JOIN
"stripe"."payment"."products" prod ON p.product_id = prod.id
WHERE
prod.name IN ('Pro Plan', 'Enterprise Plan')
ORDER BY z.created_at DESC
LIMIT 100;
```
### Step 4: Integrating Peaka Queries into the Frontend with v0.dev
With your Peaka queries ready, you can now build a complete frontend dashboard using [v0.dev](https://v0.dev/). This step shows how to integrate live query results into your UI, entirely through prompt-based generation.
#### Start with a Prompt
Begin by opening [v0.dev](https://v0.dev/) and entering a prompt like this:
```markdown
I have a Peaka account and a Peaka project that contains two queries.
I want to create a dashboard with the following charts:
- A table listing users who contacted support shortly before canceling. (You can execute the tickets_by_pro_enterprise_customers query from Peaka)
- A list of recent feedback entries from premium subscribers. (You can execute the zendesk_tickets_with_stripe_customer_and_plan_info query from Peaka)
It should be a full-stack system. The design should be developer-friendly and backend should be integrated with Peaka.
You can check the API reference here: https://docs.peaka.com/api-reference/introduction
```

---
#### Set Environment Variables
v0.dev will likely ask you to define the following environment variables to authenticate with Peaka:
- `PEAKA_API_KEY`
- `PEAKA_PROJECT_ID`
Use the values you obtained earlier from your Peaka project’s settings and paste them into v0.dev’s environment configuration.

---
#### Fix the API Base URL
By default, v0.dev may try to connect to `https://api.peaka.com/v1`, which is not the correct base URL for query execution.
You can fix this by prompting v0.dev with:
```markdown
API Endpoint base is different than api.peaka.com/v1.
It should be https://partner.peaka.studio/api/v1
```
If you're using the **EU zone**, use:
```markdown
https://partner.eu.peaka.studio/api/v1
```

---
#### Use the Correct Request Format
After correcting the base URL, you’ll also need to make sure the request payload matches Peaka’s `execute-query` API format.
You can provide v0.dev with this sample request and response structure, based on the [official documentation](https://docs.peaka.com/api-reference/data-queries/execute-query):
**Sample request:**
```js
const options = {
method: "POST",
headers: {
Authorization: "Bearer ",
"Content-Type": "application/json",
},
body: '{"from":[{"catalogName":"peaka","schemaName":"query","tableName":"samplequery"}]}',
};
fetch(
"https://partner.eu.peaka.studio/api/v1/data/projects/{projectId}/queries/execute",
options,
)
.then((response) => response.json())
.then((response) => console.log(response))
.catch((err) => console.error(err));
```
**Sample response:**
```json
{
"columns": [
{
"catalogId": "2",
"catalogName": "peaka",
"schemaName": "query",
"tableName": "samplequery",
"columnName": "amount"
}
],
"data": [
[
{
"name": "amount",
"displayName": "amount",
"dataType": "bigint",
"value": "75",
"order": 0
}
],
[
{
"name": "amount",
"displayName": "amount",
"dataType": "bigint",
"value": "75",
"order": 0
}
],
[
{
"name": "amount",
"displayName": "amount",
"dataType": "bigint",
"value": "75",
"order": 0
}
]
]
}
```

---
#### Final Touches via Prompt Iteration
Once your frontend is connected to Peaka and fetching live data, you can polish the UI using plain prompts.
For example:
```
Map the "date" field to the "updated_at" column in the recent feedback table, and remove the "rate" field.
```
v0.dev will apply your changes automatically, no need to manually edit code.
---
> ✅ At the end of this step, you’ll have a dynamic frontend powered by Peaka’s live query data fully operational in under an hour.
### Step 5: The Final Dashboard
After hooking up Peaka as the data layer in a [v0.dev](https://v0.dev/) dashboard, you’ll have a clean, fully functional, and developer-friendly interface, powered entirely by live data from Stripe and Zendesk.
The dashboard consists of two key components:
---
#### 1. Users Who Contacted Support Shortly Before Churning
This table lists:
- Customer name
- Email address
- Plan type (Pro or Enterprise)
- Ticket subject & description
- Ticket creation date (within 14 days before cancellation)
This component highlights **last-minute support activity** from users who churned, providing early-warning signals of dissatisfaction or friction. It’s an invaluable tool for customer support and product teams to spot trends behind cancellations.

---
#### 2. Recent Feedback from Premium Subscribers
This section displays all tickets submitted by **current** Pro and Enterprise users, regardless of churn status. It includes:
- Customer name
- Plan name
- Ticket subject & description
- Ticket priority, status, and last updated date
This real-time view helps teams **monitor ongoing support needs** and stay ahead of potential churn risks before they escalate.

---
#### Why This Dashboard Delivers Value
This dashboard isn’t just a data visualization, it enables action. Here's how different teams benefit:
- **Product teams** can identify recurring friction points.
- **Support teams** can evaluate whether unresolved tickets correlate with churn.
- **Revenue & growth teams** can track churn trends across plan tiers.
- **CSMs** can proactively reach out to users showing warning signs.
---
#### Time and Effort Saved
Traditionally, building this system would require:
- Manual API integrations
- Authentication handling
- SQL joins and data modeling
- Backend service development
- Frontend component coding
…resulting in **days or even a week** of effort.
By using **Peaka + v0.dev**, the same outcome can be achieved in **under an hour**, with:
- No custom backend development
- No manual UI coding
- Just clear prompts and a few API keys
---
> 💡 This is a fast, scalable way to ship internal tools or MVPs using live SaaS data without compromising on developer experience.
## Real-World Use Cases
This exact approach can be adapted for various needs:
- **Support teams**: Proactively identify at-risk customers.
- **Product teams**: Spot recurring feedback from premium users.
- **Growth teams**: Understand why high-value customers churn.
All without hiring a data team or building internal tools from scratch.
## The Conventional Way
The traditional approach would have looked like this:
- ETL pipeline to pull data from Stripe and Zendesk,
- A data warehouse to store and query the results,
- A backend service to expose APIs,
- A frontend team to build a dashboard.
Estimated time: **2–3 days, at minimum**.
Peaka + v0? **1 hour.**
## Key Takeaways
- **Churn signals often hide in support data:** Users who reach out to support shortly before canceling are waving red flags. Surfacing these interactions helps teams take proactive action before it's too late.
- **Peaka makes integrations painless:** Connect to platforms like Stripe and Zendesk without writing any code, model the data with SQL, and instantly turn queries into APIs.
- **v0.dev eliminates frontend overhead:** With natural language prompts, you can generate fully functional dashboards that connect to live data, no UI or backend coding required.
- **1 hour = days of saved effort:** What would normally take days, building data pipelines, backend services, and frontend components, can now be achieved in under an hour.
- **Accessible for non-technical teams:** PMs, support leads, and growth managers can gain insights without needing to write a single line of code.
- **Flexible and reusable:** The same structure can be repurposed for different queries, data sources, or dashboard layouts with minimal changes.
> 🎯 Bottom line: Skip the complexity, accelerate insight.
>
> Peaka + v0.dev is a turbocharged way to build MVPs and internal tools.
## Conclusion
By simply:
- Connecting Zendesk and Stripe to Peaka,
- Writing two SQL queries,
- Prompting v0.dev to generate the frontend,
I built a fully functional, data-powered churn insight dashboard in just **1 hour**.
If you’re a developer, or even a PM who wants results without the overhead of building everything from scratch, give this combo a try.
--- START: guides/how-to-build-rag-with-peaka/how-to-build-rag-with-peaka.md ---
Retrieval-Augmented Generation (RAG) is a cutting-edge technique in artificial intelligence (AI) that enhances the capabilities of generative models by integrating retrieval mechanisms. In the context of AI data platforms, RAG is particularly significant. These platforms often need to process and generate insights from extensive and diverse datasets.
By leveraging RAG, AI systems can retrieve pertinent information from their vast data repositories and generate responses or insights that are not only contextually appropriate but also grounded in the most relevant and up-to-date data available. This enhances the accuracy, reliability, and utility of the AI's outputs, making RAG an invaluable component in the development and deployment of advanced AI applications on data platforms.
In this blog post we will build a RAG pipeline for chatbot which gives info about SpaceX launches by using Peaka, a zero-ETL data platform which integrates all your data sources and allows you to query them as single data source immediately. We will add Pinecone and SpaceX API as connections to Peaka and leverage Peaka’s [Node Client](https://www.npmjs.com/package/@peaka/client) to query data for the RAG pipeline.
## **TL;DR**
If you want to skip the implementation details, check out the finished code on [Github](https://github.com/peakacom/rag-example-with-api). Follow the instructions on Readme to run the project on your local machine.
If you want to try the demo for yourself, visit Vercel to [try the demo](https://rag-with-spacex-api.vercel.app/)
## **Prerequisites**
You will need the following accounts for this project:
- [Peaka](/) Account
- [OpenAI](https://openai.com/) Account
- [Pinecone](https://www.pinecone.io/) Account
## Tech Stack
| Technology | Description |
| ------------------------------- | ------------------------------------------------------------------------------------------------------------- |
| https://www.peaka.com/ | A zero-ETL data integration platform with single-step context generation capability |
| https://www.pinecone.io/ | The serverless vector database which will be used for storing vector embeddings. |
| https://openai.com/ | An artificial intelligence research lab focused on developing advanced AI technologies. |
| https://vercel.com/templates/ai | Library for building AI-powered streaming text and chat UIs. |
| https://docs.nlkit.com/nlux/ | NLUX is an open-source JavaScript library for creating elegant and performant conversational user interfaces. |
| https://nextjs.org/ | The React Framework for the Web. Nextjs will be used for building the chatbot app. |
## Create Peaka Project and API Key
Once you login to Peaka, you need to create your project and connect sample data sets.
Check out Peaka Documentation on [how to create a project](/docs/project-operations/how-to-create-a-project) for detailed instructions.
Enter your created project and click `Connect sample data sets` button on the screen as shown in the image below:

In the sample data set both Peaka Rest Table for SpaceX API and Pinecone data sources are already added. We will use these data sources for our demo app.
After you create your project, setup connections, and create your catalogs in Peaka, you need to generate a Peaka API Key to use it with our project.
Check out Peaka Documentation on [how to create API Keys](/docs/cookbook/how-to-generate-api-keys) for detailed instructions. Copy and save your Peaka API Key.
## **Create a Next.js Application**
To create a new project, first navigate to the directory that you want to create your project in using your terminal. Then, run the following commands:
```bash
npm install -g create-next-app
npx create-next-app@latest
```
- Use Tailwind CSS (for UI design)
- Use "App Router"
After this step, go to your project's folder with the `cd` command and install the necessary libraries
```bash
npm i @ai-sdk/openai @ai-sdk/react @nlux/react @nlux/themes @peaka/client @upstash/vector ai langchain lodash zod
```
From now on, when you are at the directory of your project the command
`npm run dev`
is going to be sufficient to run the project on [**localhost:3000**](http://localhost:3000/).
If you need further clarification, you can refer to the [**Readme**](https://github.com/kaanguneyli/semantic_search_for_docs) or the [**Next.js documentation**](https://nextjs.org/learn-pages-router/basics/create-nextjs-app)
## Create .env file
Now create a file called `.env` in your project and add it to the `.gitignore` file if you are considering to add this project to your Github account. In this file, we will store our API keys. You need to create a Pinecone project and API Key. After creating your Pinecone project then create an index with `dimension` **_1536_** and `metric` **_cosine_**. Then use the name of the index in the environment variable. Finally, you need to create an OpenAI API Key. After completing necessary actions copy these values to environment variables accordingly.
```dotenv
PEAKA_API_KEY=
OPENAI_API_KEY=
PINECONE_API_KEY=
PINECONE_INDEX=
```
## Create Peaka Service
Create a `service` folder under the root folder in your project and create a `peaka.service.ts` file inside this folder. We will need to implement two methods in this service class. The first method is `getAllSpacexLaunches`, which will fetch all the launches from SpaceX API. The SQL query is trivial like below:
```sql
SELECT id, name, links_article FROM "spacex"."public"."launches"
```
Then we need to implement `vectorSearch` method, which will query both Pinecone index and will join the results with SpaceX API results to get all of the metadata of the launches. The query will be like this:
```sql
WITH vector_query AS (
SELECT CAST(JSON_EXTRACT(metadata, '$.id') AS VARCHAR) AS launch_id, CAST(JSON_EXTRACT(metadata, '$.text') AS VARCHAR) AS article_content FROM "pinecone"."main"."spacex-launches"
WHERE _q_search= 'query_vector(vector=[<%= vectors %>]; topK=<%= topK %>;)'
)
SELECT * FROM "vector_query" AS vq, "spacex"."public"."launches" AS l WHERE l.id = vq.launch_id
```
Finally, `peaka.service.ts` will look like this:
```typescript
export class PeakaService {
private connection: Peaka;
private constructor() {
this.connection = connectToPeaka(process.env.PEAKA_API_KEY ?? "");
}
static #instance: PeakaService;
public static get instance(): PeakaService {
if (!PeakaService.#instance) {
PeakaService.#instance = new PeakaService();
}
return PeakaService.#instance;
}
public async getAllSpacexLaunches(): Promise {
const iter = await this.connection.query(
'SELECT id, name, links_article FROM "spacex"."public"."launches"',
);
const launches: SpacexLaunchInfo[] = [];
const data: QueryData[] = await iter
.map((r) => r.data ?? [])
.fold([], (row, acc) => [...acc, ...row]);
for (const queryData of data) {
const launch: SpacexLaunchInfo = {
id: queryData[0],
name: queryData[1],
links_article: queryData[2],
};
launches.push(launch);
}
return launches;
}
public async vectorSearch(
vectors: number[],
topK: number,
): Promise {
const iter = await this.connection.query(
VECTOR_LAUNCHES_VECTOR_SEARCH_SQL_TEMPLATE({ vectors, topK }),
);
const data: QueryData[] = await iter
.map((r) => r.data ?? [])
.fold([], (row, acc) => [...acc, ...row]);
return data;
}
}
```
## Create populate data endpoint
We will implement a get endpoint which will populate vector database when called. First, we will create `route.ts` under `app/api/populate-data` folder. We will follow below steps:
1. Delete all the data in the index
2. Fetch all SpaceX launches from Peaka Rest which will have article urls about SpaceX launches
3. For all article urls fetch all the content with `RecursiveUrlLoader` of the langhchain library
4. Split all of the articles into chunks
5. Write all the chunks to Pinecone index with the metada
The final code will be like this:
```typescript
export const dynamic = "force-dynamic";
import { PeakaService } from "@/service/peaka.service";
import { Pinecone } from "@pinecone-database/pinecone";
import { NextResponse } from "next/server";
import { RecursiveUrlLoader } from "@langchain/community/document_loaders/web/recursive_url";
import { compile } from "html-to-text";
import { PineconeStore } from "@langchain/pinecone";
import { Document } from "@langchain/core/documents";
import { OpenAIEmbeddings } from "@langchain/openai";
import { RecursiveCharacterTextSplitter } from "langchain/text_splitter";
export async function GET() {
const pc = new Pinecone({
apiKey: process.env.PINECONE_API_KEY!,
});
const pineconeIndex = pc.index(process.env.PINECONE_INDEX!);
try {
await pineconeIndex.deleteAll();
} catch (e) {
console.log("Could not delete index");
}
const peakaService = PeakaService.instance;
const launches = await peakaService.getAllSpacexLaunches();
const compiledConvert = compile({ wordwrap: 130 }); // returns (text: string) => string;
const splitter = new RecursiveCharacterTextSplitter({});
const docs: Document[] = [];
for (const launch of launches) {
const url = launch.links_article;
if (url) {
const loader = new RecursiveUrlLoader(url, {
extractor: compiledConvert,
maxDepth: 0,
});
const urlDocs = await loader.load();
if (urlDocs.length === 0) continue;
const output = await splitter.createDocuments([urlDocs[0].pageContent]);
for (const text of output) {
docs.push(
new Document({
metadata: {
id: launch.id,
name: launch.name,
link: launch.links_article,
},
pageContent: text.pageContent,
}),
);
}
}
}
await PineconeStore.fromDocuments(docs, new OpenAIEmbeddings(), {
pineconeIndex,
maxConcurrency: 5,
});
return NextResponse.json({ success: true });
}
```
## Create Chat Prompts
Create a folder `config` in the root directory of the project and create a `config.ts` under this folder. We will define our system prompt and OpenAI parameters for our chatbot in here with lodash templates and export them like below:
```ts
export const SPACEX_CHATBOT_INSTRUCTION =
_.template(` You are a helpful chatbot which answers questions about given context. Context information is below.
---------------------
<%= context %>
---------------------
Given the context information and not prior knowledge, answer the query.
Query: <%= query %>
Answer:
`);
export const SPACEX_CHATBOT_PARAMS = {
temperature: 0,
modelName: "gpt-4o",
max_tokens: 2000,
};
```
Notice that in `SPACEX_CHATBOT_INSTRUCTION` template we will feed the LLM with Pinecone results as context and user query and we will expect the LLM to answer with the given contex.
## **Implement Chatbot API**
In the chatbot, we should first create a POST endpoint. The input of this endpoint should be the message of the user and output should be the message generated by LLM running on OpenAI.
First, we will create `route.ts` under `app/api/chat`. This file will have the POST endpoint with `/api/chat` extension in the url.
We will use ai-sdk of Vercel for response streaming and use langchain open library to interact with LLM.
The code is straight forward with an algorithm is like this:
- Get the prompt from request body
- Get the OpenAI Embeddings of the user query with langchain
- Query Pinecone Store with Peaka Client
- Finally, feed the result to the LLM and stream the response of LLM to frontend
Implementation of `api/chat` route should like this:
```ts
export const dynamic = "force-dynamic";
import { SPACEX_CHATBOT_INSTRUCTION } from "@/config/config";
import { PeakaService } from "@/service/peaka.service";
import { openai } from "@ai-sdk/openai";
import { OpenAIEmbeddings } from "@langchain/openai";
import { streamText } from "ai";
export async function POST(req: Request) {
const request = await req.json();
if (!request.prompt) return new Response("Missing query", { status: 400 });
const prompt = request.prompt;
const peakaService = PeakaService.instance;
const embeddings = new OpenAIEmbeddings();
const vectors = await embeddings.embedQuery(request.prompt);
const launches = await peakaService.vectorSearch(vectors, 10);
const result = await streamText({
model: openai("gpt-4o"),
messages: [
{
role: "system",
content: SPACEX_CHATBOT_INSTRUCTION({
context: JSON.stringify(launches),
query: prompt,
}),
},
],
});
return result.toTextStreamResponse();
}
```
## **Implement Chatbot UI**
We have the POST endpoint ready. Now we need the UI for our chatbot. For the UI, we will use `NLUX`. We choose `NLUX` because it provides easy integration with Vercel AI SDK.
Let's open `pages.tsx` file to build our chat window. The following code will implement a very basic chatbot UI for this demo. We will use `AiChat` component from `NLUX` and need to implement `ChatAdapter` interface in order to communicate with the backend. Then, we provide `conversationOptions` to our `AiChat` component which will built-in chat prompt for demo purposes.
```tsx
"use client";
import "@nlux/themes/nova.css";
import {
AiChat,
AiChatUI,
ChatAdapter,
StreamingAdapterObserver,
} from "@nlux/react";
export default function Chat() {
const chatAdapter: ChatAdapter = {
streamText: async (prompt: string, observer: StreamingAdapterObserver) => {
const response = await fetch("/api/chat", {
method: "POST",
body: JSON.stringify({ prompt: prompt }),
headers: { "Content-Type": "application/json" },
});
if (response.status !== 200) {
observer.error(new Error("Failed to connect to the server"));
return;
}
if (!response.body) {
return;
}
// Read a stream of server-sent events
// and feed them to the observer as they are being generated
const reader = response.body.getReader();
const textDecoder = new TextDecoder();
while (true) {
const { value, done } = await reader.read();
if (done) {
break;
}
const content = textDecoder.decode(value);
if (content) {
observer.next(content);
}
}
observer.complete();
},
};
return (
Hello! 👋
This is a rag pipeline is implemented with Peaka. The data is
fetched from SpaceX public API's by using Peaka's
Rest Table and uses Peaka's Pinecone connector to search
for information in vector database using sql. Then the results
are sent to OpenAI to generate the response.
Try by clicking sample prompts or get to the full code from{" "}
Github
);
}
```
After we finish our implementation, the UI should look like this:

Let’s try one of our sample prompts and see what our bot will tell us about Turksat 5A launch:

As you can see, our chatbot gave detailed information about Turksat 5A launch by combining SpaceX API data from Peaka Rest Connector and Pinecone vector index with Peaka’s query engine. By the help of Peaka, we were able to query both data sources with single API call.
## Conclusion
In this tutorial, we’ve demonstrated how you can build a RAG pipeline using Peaka and Pinecone.
Using Peaka's advanced query engine, our chatbot seamlessly combined SpaceX API data from Peaka Rest Connector and Pinecone vector index, delivering detailed information about the Turksat 5A launch—all with a single API call.
If you have any questions or comments, feel free to reach out to me on [**GitHub**](https://github.com/kobalski).
--- START: guides/how-to-use-peaka-api-mcp-server/how-to-use-peaka-api-mcp-server.md ---
## Introduction
Ever wanted to give your AI assistant the power to manage entire data platforms, create connections to databases, and execute complex queries across multiple data sources?
With Peaka's API MCP Server, you can transform any MCP-compatible AI assistant into a powerful data management tool that understands your infrastructure, connects to various data sources, and helps you build comprehensive data solutions without writing a single line of integration code.
In this blog, I'll show you how to set up and use Peaka's API MCP Server to unlock the full potential of AI-powered data management.
## What is an MCP Server?
While AI assistants are great at understanding and generating text, they often need external tools to interact with real systems like databases, APIs, or data platforms. That's where MCP servers shine.
MCP stands for Model Context Protocol. An MCP server is a standardized interface that exposes tools or data sources to AI assistants. The assistant doesn't need to know the intricacies of how a specific API works or where services are hosted.
For example, Peaka's API MCP server provides comprehensive access to Peaka's most of API endpoints, including:
- **Complete API Documentation**: URLs, endpoints, HTTP methods, and parameters
- **Authentication Details**: Headers, authorization rules, and API key management
- **Request/Response Examples**: Sample payloads and expected returns
- **Error Handling**: Status codes and troubleshooting guidance
## Prerequisites
To get started with Peaka's API MCP Server, you'll need:
- **Peaka Partner API Key**: Access to Peaka's comprehensive API endpoints. Get yours from the [Partner API Key Management Guide](/docs/cookbook/how-to-manage-partner-api-key).
- **MCP-Compatible AI Assistant**: Such as [Claude Desktop](https://www.anthropic.com/products/claude-desktop) or [Cursor IDE](https://www.cursor.com/)
## Tech Stack
| **Technology** | **Description** |
| ------------------------------------------------------------------- | -------------------------------------------------------------------------------------------- |
| [Peaka](/) | A zero-ETL data integration platform with comprehensive API for programmatic data management |
| [Model Context Protocol](https://modelcontextprotocol.io/) | A standardized protocol for connecting AI assistants with external systems and APIs |
| [Claude Desktop](https://www.anthropic.com/products/claude-desktop) | Anthropic's desktop AI assistant with MCP support |
| [Cursor IDE](https://www.cursor.com/) | AI-powered code editor with integrated MCP capabilities |
### Why Peaka's API MCP Server?
Peaka's API MCP Server is a comprehensive solution that provides **complete access to Peaka's most of API endpoints**. Unlike traditional API documentation, this MCP server acts as an intelligent API companion that:
#### **Exposes the Full Peaka API Suite**
- **Organization Management APIs**: Create, read, update, delete organizations and workspaces
- **Connection APIs**: Set up and manage data source connections
- **Data Catalog APIs**: Discover, create, and manage data catalogs and schemas
- **Query Execution APIs**: Run SQL queries and retrieve results programmatically
- **Caching APIs**: Configure and manage data caching strategies
- **AI Agent APIs**: Interact with Peaka's conversational AI capabilities
- **Internal Table APIs**: Create and manage Peaka's internal data structures
- **More**: And more...
#### **Enables Seamless Code Integration**
Your AI assistant can help you:
- **Generate API Calls**: Create ready-to-use code in Python, JavaScript, cURL, and more
- **Handle Authentication**: Set up proper headers and API key management
- **Parse Responses**: Extract and process API return data efficiently
- **Implement Error Handling**: Add robust error checking and retry logic
- **Build Complete Applications**: From simple scripts to full data applications
### Why MCP?
The Model Context Protocol represents a paradigm shift in how AI assistants interact with external systems. Instead of custom integrations for each service, MCP provides:
- **Standardized Communication**: One protocol for all external tools
- **Security**: Controlled access to external resources
- **Extensibility**: Easy to add new capabilities without changing the AI assistant
- **Reliability**: Structured error handling and consistent responses
## Quick Start Guide
### Setting up Claude Desktop
1. **Locate your Claude Desktop configuration file**:
- **macOS**: `~/Library/Application Support/Claude/claude_desktop_config.json`
- **Windows**: `%APPDATA%\Claude\claude_desktop_config.json`
2. **Add the Peaka API MCP server**:
```json
{
"mcpServers": {
"peaka-api": {
"command": "npx",
"args": ["-y", "@peaka/mcp-server-peaka-api@latest"]
}
}
}
```
3. **Restart Claude Desktop** to load the new server.
### Setting up Cursor IDE
1. **Locate your Cursor MCP configuration**:
- **macOS**: `~/.cursor/mcp.json`
- **Windows**: `%USERPROFILE%\.cursor\mcp.json`
2. **Add the server configuration**:
```json
{
"mcpServers": {
"peaka-api": {
"command": "npx",
"args": ["-y", "@peaka/mcp-server-peaka-api@latest"]
}
}
}
```
3. **Enable MCP in Cursor settings**.
## What You Can Do with Peaka's API MCP Server
Once connected, your AI assistant becomes a comprehensive API development companion. Here's what becomes possible:
### 1. API Discovery and Documentation
```
"Show me all available Peaka APIs for managing database connections"
```
Your assistant will provide:
- Complete list of connection-related endpoints
- Required parameters and headers for each API
- Authentication requirements and formats
- Sample request/response payloads
- Error codes and troubleshooting tips
### 2. Code Generation for Any Language
```
"Generate JavaScript code to create a new Peaka project using the API with given organization ID and workspace ID"
```
The assistant will create:
- Complete JavaScript script with proper imports and headers
- Correct API endpoint URLs and headers
- Authentication setup with your API key
- Error handling and response parsing
**Example output:**
```javascript
const PEAKA_API_URL = "https://partner.peaka.studio/api/v1";
const API_KEY = "your-api-key";
// Create a new Peaka project
async function createPeakaProject(organizationId, workspaceId, projectName) {
const response = await fetch(
`${PEAKA_API_URL}/organizations/${organizationId}/workspaces/${workspaceId}/projects`,
{
method: "POST",
headers: {
Authorization: `Bearer ${API_KEY}`,
"Content-Type": "application/json",
},
body: JSON.stringify({ name: projectName }),
}
);
if (!response.ok) {
throw new Error(`Failed to create project: ${response.statusText}`);
}
return await response.json();
}
// Usage example
async function main() {
try {
const project = await createPeakaProject(
"your-organization-id",
"your-workspace-id",
"My New Project"
);
console.log("Project created:", project.name);
console.log("Project ID:", project.id);
} catch (error) {
console.error("Error:", error.message);
}
}
// Run the example
main();
```
## Real-World Development Scenarios
### 1. Building a Data Integration Script
**Developer Request**: _"I need to create a new connection to a PostgreSQL database using the API with given organization ID and workspace ID" with given details: name: "My DB", driver: "postgresql", host: "localhost"_
**AI Assistant Response**:
```javascript
const PEAKA_API_URL = "https://partner.peaka.studio/api/v1";
async function createPostgreSQLConnection(config) {
const {
apiKey,
projectId,
connectionName,
host,
port,
user,
password,
database,
} = config;
// Connection payload for PostgreSQL
const payload = {
name: connectionName || "My PostgreSQL DB",
type: "POSTGRES",
credential: {
url: host || "localhost",
port: port || 5432,
user: user || "postgres",
password: password,
databaseName: database,
useSsl: false,
},
};
// Create connection via Peaka API
const response = await fetch(`${PEAKA_API_URL}/connections/${projectId}`, {
method: "POST",
headers: {
Authorization: `Bearer ${API_KEY}`,
"Content-Type": "application/json",
},
body: JSON.stringify(payload),
});
if (!response.ok) {
throw new Error(`Failed to create connection: ${response.statusText}`);
}
return await response.json();
}
// Example usage
async function run() {
try {
const connection = await createPostgreSQLConnection({
apiKey: "your-peaka-api-key",
projectId: "your-project-id",
connectionName: "My DB",
host: "localhost",
port: 5432,
user: "postgres",
password: "your-password",
database: "your-database",
});
console.log("✅ Connection created:", connection.id);
} catch (error) {
console.error("❌ Error:", error.message);
}
}
run();
```
### 2. API Error Handling and Debugging
**Developer Request**: _"My API call is failing with a 422 error. Help me understand what's wrong."_
**AI Assistant Analysis**:
- Reviews the 422 status code (Unprocessable Entity)
- Analyzes your request payload against Peaka's API schema
- Identifies missing required fields or invalid data types
- Provides corrected request with proper validation
- Suggests preventive measures for future calls
## Key Takeaways
- **Complete API Access**: Peaka's MCP server exposes the entire Peaka API suite with full documentation, authentication details, and code examples
- **Intelligent Code Generation**: Your AI assistant can generate production-ready code in any language with proper error handling and best practices
- **Comprehensive Integration Support**: From simple scripts to complex data pipelines, get complete implementation guidance
- **Developer-Friendly Documentation**: Access live API documentation, examples, and troubleshooting through natural language queries
## Conclusion
Peaka's API MCP Server transforms how developers interact with data platform APIs. Instead of switching between documentation, testing tools, and code editors, you get everything in one conversational interface.
Your AI assistant becomes an expert API companion that knows:
- Every endpoint, parameter, and response format
- Authentication requirements and security best practices
- How to generate clean, production-ready code
- How to debug issues and optimize performance
- How to build complete integration workflows
This isn't just about making API calls easier—it's about fundamentally changing how we build data-driven applications. With Peaka's comprehensive API access through MCP, you can focus on solving business problems rather than wrestling with integration complexity.
Whether you're building a simple data sync script or a comprehensive analytics platform, the combination of Peaka's powerful APIs and MCP's intelligent interface puts enterprise-grade data capabilities at your fingertips.
Ready to supercharge your development workflow? Get your [Peaka Partner API key](/docs/cookbook/how-to-manage-partner-api-key) and start building with AI-powered API assistance.
That's it! You can now use Peaka API MCP Server in your AI assistant.
--- START: guides/mastra-agent-with-peaka-mcp/mastra-agent-with-peaka-mcp.md ---
## Introduction
Ever wondered how to turn a simple natural language question into a valid SQL query and get an answer from a live database?
During my internship, I worked on a project using Mastra framework and the Peaka MCP server to build a conversational agent that understands user questions, writes SQL, and retrieves answers from Peaka’s sample data.
In this blog, I’ll walk you through what I built, and how it works.
## What is an MCP Server?
While Mastra lets you build agents, those agents often need external tools like querying a database, fetching files, or calling APIs. That’s where the MCP server comes in.
MCP stands for Model Context Protocol. An MCP server is a standardized interface that exposes tools or data sources to agents. The agent doesn’t need to know how a database works or where an API is hosted. For example, in my project, the Peaka MCP server exposed the following tools:
- `peaka_schema_retriever`: Retrieves metadata and schema info
- `peaka_query_golden_sqls`: Queries question/SQL pairs from Peaka’s store
- `peaka_execute_sql_query`: Executes SQL queries on Peaka
## Prerequisites
To build and run this project, you will need:
- Node.js installed
- LLM provider or API key: To power the agents, you need an LLM provider API Key. For example, get one from [OpenAI](https://platform.openai.com/account/api-keys).
- Peaka Project API Key: To use Peaka tools via the MCP server, you need to create a Project API Key from your Peaka workspace. You can follow the steps in the [Peaka documentation](/docs/cookbook/how-to-generate-api-keys) to generate it.
- _Packages_: Install the following packages:
```bash
npm install @mastra/core @mastra/mcp @ai-sdk/openai
```
## Tech Stack
| **Technology** | **Description** |
| --------------------------------------------- | ------------------------------------------------------------------------------------------------------------------------------------ |
| [Peaka](/) | A zero-ETL data integration platform with single-step context generation capability |
| [OpenAI](https://openai.com/) | An artificial intelligence research lab focused on developing advanced AI technologies. |
| [Mastra](https://mastra.ai/) | A modular framework for building AI agents with composable tools, natural language interfaces, and multi-channel deployment support. |
| [Vercel](https://vercel.com/templates/ai) | A cloud platform for frontend frameworks and serverless functions, enabling fast and scalable web app deployments. |
| [Next.js](https://nextjs.org/) | The React Framework for the Web. Next.js was used for building the chatbot app. |
| [assistant-ui](https://www.assistant-ui.com/) | An open-source chat interface designed to connect easily with Mastra agents. |
### Why Peaka?
Peaka is a no-code data platform that allows you to:
- Connect to APIs, databases, and SaaS tools without integration code,
- Model external data as virtual tables without moving or duplicating it,
- Query data using SQL and expose it through ready-to-use API endpoints.
For this project, Peaka powered the backend intelligence of the Mastra agent by:
- Providing sample datasets that could be queried instantly,
- Understanding the data schema to support structured, SQL-based querying,
- Returning reliable results through a single API call, without building a custom backend.
### Why Mastra?
Mastra is a developer-friendly, open-source framework for building AI applications, especially ones that rely on large language models (LLMs). It’s written in TypeScript and provides everything you need to build intelligent agents.
## TL;DR
If you want to skip the implementation details, check out the finished code on [GitHub](https://github.com/peakacom/peaka-mastra-ai-agent). Follow the instructions in the README to run the project locally.
You can also [try the live demo](https://peaka-mastra-agent-ui.vercel.app).
## How to Use Peaka with Mastra via its MCP Server Tools
### Building the Peaka Agent
First, set the environment for Peaka API and OpenAI API keys in a `.env` file:
```bash
PEAKA_API_KEY=
OPENAI_API_KEY=
```
Next, import the following packages and instantiate the Mastra MCP client in **mcp.ts** file:
```javascript
import { createTool } from "@mastra/core";
import { MCPClient } from "@mastra/mcp";
process.env.HOME = "/tmp";
console.log("PEAKA_API_KEY: " + process.env.PEAKA_API_KEY);
export const mcp = new MCPClient({
servers: {
peaka: {
command: "npx",
args: ["-y", "@peaka/mcp-server-peaka@latest"],
env: {
PEAKA_API_KEY: process.env.PEAKA_API_KEY || "",
},
},
},
});
```
To build the assistant, I created a Mastra agent called `peakaAgent`. It uses OpenAI’s gpt-4o-mini model, connects to the tools exposed by the Peaka MCP server, and stores memory in a local SQLite database.
Here’s how the agent is instantiated:
Import required packages in **agent.ts** file:
```javascript
import { openai } from "@ai-sdk/openai";
import { Agent } from "@mastra/core/agent";
import { mcp } from "../agents/mcp";
export const peakaAgent = new Agent({
name: "Peaka Data Assistant",
instructions: `You are a helpful assistant for querying Peaka's sample launch data.
- Always write valid SQL queries based on available tables and columns.
- If a query fails or returns an error, suggest rephrasing or an alternative.
- Be concise, but provide enough detail for the user to understand.
- You can ask follow-up questions or offer related queries if relevant.
- When uncertain, prefer safety and clarity over guessing.`,
model: openai("gpt-4o-mini"),
tools: await mcp.getTools(),
});
```
### Why Customize the Instructions?
By default, Mastra agents work well with basic prompting. But I found that explicit instructions help guide the LLM more reliably and make a big difference in consistency. To improve the assistants's performance, I manually tested different user questions and tweaked instructions to fix edge cases.
#### Injecting SQL Rules Resources from the MCP Server
Peaka's MCP server doesn't just expose tools like SQL execution and data retrieval. It also provides resources, including a rule set that guidelines how to write valid SQL using Trino, which is the SQL engine Peaka relies on.
To make the assistant more accurate, I pulled in these rules dynamically and added them to the agent's instructions. By including the following function in mcp.ts file:
```javascript
export const getSQLRuleSet = async () => {
const resources = await mcp.resources.list();
if (resources.peaka) {
const resource = resources.peaka.find(
(r) => r.uri === "file:///peaka_sql_query_rule_set.txt",
);
if (!resource) {
throw new Error("Resource not found");
}
console.log(resource);
const result = await mcp.resources.read("peaka", resource.uri);
return result.contents[0].text;
}
};
```
In addition to updating agent.ts file to combine SQL rules with the base instructions:
```javascript
import { getSQLRuleSet, mcp } from "../agents/mcp";
export const peakaAgent = new Agent({
name: "Peaka Data Assistant",
instructions:
`You are a helpful assistant for querying Peaka's sample launch data.
- Always write valid SQL queries based on available tables and columns.
- If a query fails or returns an error, suggest rephrasing or an alternative.
- Be concise, but provide enough detail for the user to understand.
- You can ask follow-up questions or offer related queries if relevant.
- When uncertain, prefer safety and clarity over guessing.\n` +
(await getSQLRuleSet()),
model: openai("gpt-4o-mini"),
tools: await mcp.getTools(),
});
```
### Running the Chatbot
Open that link in your browser to access the Mastra Playground, where you can click on “Peaka Data Assistant” and interact with your agent by testing queries from Peaka sample data.

In the following example, I asked the assistant to list 5 Airbnb listings with exactly 3 bedrooms and a price under $600.
The assistant parsed the natural language request, generated the appropriate SQL query, and returned relevant results, filtering out any listings that didn’t match. This shows how easily users can interact with the system using plain language while still getting precise, data-driven results.

When exact matches aren’t found, the assistant prompts the user for clarification, helping refine the query for more accurate results.


### Deploying to Vercel
Vercel is a cloud platform that makes it easy to deploy frontend and backend applications. For this project, we can use Vercel to host and serve our Mastra agent API, making it accessible online with just a few configuration steps.
#### Step 1: Add the Vercel Deployer to your Mastra Project:
in **index.ts**, import the Vercel Deployer which handles the API routing and deployement structure Vercel expects:
```javascript
import { VercelDeployer } from “@mastra/deployer-vercel”;
```
Then modify your Mastra setup to include the deployer:
```javascript
export const mastra = new Mastra({
deployer: new VercelDeployer(),
agents: { peakaAgent },
storage: new LibSQLStore({
url: ":memory:",
}),
logger: new PinoLogger({
name: "Mastra",
level: "info",
}),
});
```
#### Step 2: Patch The MCP Client for Vercel
In your **mcp.ts** file, before creating the MPCLient, add the following lines:
```javascript
process.env.HOME = "/tmp";
console.log("PEAKA_API_KEY: " + process.env.PEAKA_API_KEY);
```
Then proceed with the MCP client as usual:
```javascript
export const mcp = new MCPClient({
// ...
});
```
After deploying the Mastra agent project to your Vercel account, you can confirm that the deployment is working correctly and have access to Peaka tools by visiting the endpoint:
```
https://.vercel.app/api/agents
```

This validated that the **Vercel deployment was not only live but also correctly integrated with the Peaka toolset**.
#### Step 3: Building the Chat Interface with Assistant-UI
To provide a user friendly interface for interacting with my Mastra agent, I used assistant-ui , which is an open source frontend built specifically for Mastra deployments. I connected it to my Vercel-hosted Mastra Backend, allowing real time responses from deployed agent. This setup made it simple to test and showcase the Peaka agent’s capabilities without building a custom frontend from scratch since Vercel doesn't offer it.
You can access The Peaka assistant-UI finished code on [Github](https://github.com/kobalski/peaka-mastra-agent-ui.git). Follow the Readme instructions to run the project.

## Key Takeaways
- **Peaka simplifies data access:** Query real data without setting up ETL, modeling it as virtual tables to the agents access and let it do its work. Peaka MCP server is backed by tools that enables agents to query structured data using natural language.
- **Mastra provides a smart interface:** With Mastra powering the logic and assistant-ui providing the frontend, you can build and deploy conversational agents in minutes.
- **Vercel makes it production-ready:** Deploy your agent as a server-less API with zero config and instantly share it online.
## Conclusion
In this blog, we walked through how to deploy Peaka AI agent to Vercel using Mastra framework and connect to a user friendly frontend using assistant-ui. The result is a fully functional chatbot that doesn't just guess but understands the data schema, follows the right SQL syntax, and gives useful feedback even when something goes wrong.
If you are a developer, or just curious about AI powered interfaces that can retrieve your data, this setup is worth exploring. Try it, adapt it and build on it without starting from scratch.
Feel free to reach out to me on [Github](https://github.com/ramamatar) for any questions or comments.
If you are interested to see more, check out other Peaka blog posts for real world use cases, tutorials and data-powered project ideas like [Peaka’s RAG Capabilities](/guides/how-to-build-rag-with-peaka) and [building a churn analysis dashboard](/guides/how-to-build-churn-dashboard).
--- START: guides/why-semantics-matters/why-semantics-matters.md ---
# Project Overview
Querying databases using natural language has become increasingly accessible thanks to advancements in AI-powered SQL generation. However, the accuracy of these systems often depends on how well the model understands the structure and semantics of the database schema.
In this project, we evaluate the performance of Peaka AI Agent, a no-code tool that converts natural language questions into executable SQL queries, by using the Spider dataset as the testbed.
## TL;DR
If you’d like to skip the implementation details, you can review the finished code on [Peaka's GitHub account](https://github.com/peakacom/PeakaSemantics). Follow the instructions in the README to run the project locally.
You can also [try the live demo](https://peakasemantics-gboxymwyv55rvleuxckhwv.streamlit.app/).
## What is Peaka?
Peaka is a no-code data management platform that connects and transforms data from multiple sources, making it easier to access, manage, and utilize across various applications. Peaka provides a unique semantics generation tool that completes table columns with human-readable descriptions. These semantics help the AI Agent better understand schema context, leading to more accurate SQL generation. We’ll be showing you how applying Peaka’s semantics tool can narrow the gap between AI-generated queries and ground-truth Spider SQL results, especially when raw schema names are vague or ambiguous.
## What is Spider?
Spider is a large-scale, cross-domain text-to-SQL benchmark designed to evaluate the performance of natural language interfaces for complex database queries. Unlike simpler datasets, Spider challenges systems to understand diverse schemas and generate accurate SQL queries from natural language questions without access to query templates or hard-coded logic.
It contains 10,000 natural language questions across 200 databases covering a wide range of real-world scenarios. Each question is paired with a ground truth SQL query and is designed to test a model’s ability to generalize.
Spider is used to assess the effectiveness of semantic parsers and AI agents that attempt to bridge the gap between users and relational databases using plain languages.
## What is Snowflake?
Snowflake is a modern cloud-based data warehouse platform known for its scalability, speed, and SQL-native environment. In the context of Spider benchmark, Snowflake serves as the execution environment for evaluating generated SQL queries. Since Spider provides natural language questions and corresponding SQL queries, these can be executed against databases hosted in Snowflake to validate whether the SQL returns correct results.
## What is a Semantic Layer?
A semantic layer is a method for making data easier to understand and utilize. It connects technical database terms to more familiar business language. By defining key terms, establishing relationships between tables, and implementing standard filters, a semantic layer helps tools like AI agents generate more accurate and meaningful queries.
### Schema Clarity and RAG
- **Use clear schema definitions**: The schema should be well-documented by listing all tables, columns, data types, and their relationships to each other.
- **Add context to column names:** When column names are unclear (like cust_id), include descriptions such as “customer identifier” so the model can have a better understanding of meaning.
- **Use RAG for real-time schema access:** Retrieval-Augmented Generation allows your system to pull in up-to-date schema information when generating queries, thereby reducing errors caused by outdated or missing context.
- **Leverage query templates:** Keep a library of tried and true query patterns. Instead of generating queries from scratch, the model can modify these blueprints to fit new questions more accurately.
## Prerequisites
Before running this project, make sure you have the following:
- Python 3.8+ installed
- Spider Text-to-SQL Dataset for generating natural language questions. You can find it [here](https://github.com/xlang-ai/Spider2).
- Peaka Studio account with API key and [project setup](/docs/project-operations/how-to-create-a-project). You can follow the steps in the [Peaka documentation](/docs/cookbook/how-to-generate-api-keys) to generate a key.
- [Snowflake](https://signup.snowflake.com/?utm_cta=trial-en-www-homepage-top-right-nav-ss-evg&_ga=2.22504568.2102680694.1752750423-1660293532.1752241628&_fsi=xN7WEhTe) account or access(for Spider execution in Snowflake syntax)
- The following Python packages installed:
```bash
pip install requests streamlit python-dotenv
```
## Tech Stack
| Tool/Library | **Purpose** |
| --------------------------------------------------------------------------------------------------------------------------------------------------------------------------- | ----------------------------------------------------------------------------------- |
| [Peaka](/) | A zero-ETL data integration platform with single step context generation capability |
| [Spider Dataset](https://signup.snowflake.com/?utm_cta=trial-en-www-homepage-top-right-nav-ss-evg&_ga=2.22504568.2102680694.1752750423-1660293532.1752241628&_fsi=xN7WEhTe) | Source of natural language questions and structured DB schemas |
| [Snowflake SQL](https://signup.snowflake.com/?utm_cta=trial-en-www-homepage-top-right-nav-ss-evg&_ga=2.22504568.2102680694.1752750423-1660293532.1752241628&_fsi=xN7WEhTe) | Backend execution engine used by Spider for SQL result generation |
| Requests | Used to make authenticated API calls to Peaka AI Agent |
| [Streamlit](https://streamlit.io) | To build an interactive web UI for comparing question results |
## Let’s Start
### Combining Natural Language Questions with SQL Queries
In this step, we prepare a dataset that combines:
- Natural languages questions
- Their corresponding Snowflake SQL queries
- The associated database context
- The result file name
Our goal is to create a JSON file **output.json** that will later be used to test the Peaka AI agent’s ability to answer the same questions accurately.
#### Step 1: Load Natural Language Questions
Import the required libraries:
```python
import os
import json
```
Each line in [spider2-snow.jsonl](https://github.com/ramamatar/PeakaSemantics/blob/main/spider2-snow.jsonl) contains:
- instance_id: used to match with SQL file
- instruction: the NL question
- db_id: the name of database
Map this info using a dictionary:
```python
INSTRUCTION_FILE = "spider2-snow.jsonl"
instruction_map = {}
```
```python
with open(INSTRUCTION_FILE, 'r', encoding="utf-8") as f:
for line in f:
entry = json.loads(line)
instruction_id = entry.get("instance_id")
instruction = entry.get("instruction")
database = entry.get("db_id")
if instruction_id and instruction:
instruction_map[instruction_id] = (instruction, database)
```
#### Step 2: Matching SQL Files to Questions
Each SQL file in sql/ is named using instance_id (e.g. q_1001.sql). We read the file and try to transpile it to Trino dialect that Peaka recognize using sqlglot.
First import the necessary libraries for SQL transpilation from sqlglot:
```python
from sqlglot import transpile
import sqlglot.errors
from sqlglot import exp
from sqlglot.helper import logger as helper_logger
```
Spider SQL queries sometimes include Snowflake-specfic syntax. We define a custom transformer to convert:
- `TO_NUMBER` → `CAST AS DECIMAL`
- `REGEXP_EXTRACT` → compatible Trino equivalent
```python
def custom_transformer(node):
if isinstance(node, exp.ToNumber):
return exp.Cast(this=node.this, to=exp.DataType(this=exp.DataType.Type.DECIMAL))
if isinstance(node, exp.RegexpExtract):
return exp.RegexpExtract(
this=node.this,
expression=node.expression,
position=None,
occurrence=None,
parameters=None
)
return node
```
Now let us match the parameters, skipping files with missing file pairs and transpiling snowflake to trino by:
```python
output_data = []
SQL_DIR = "sql"
for filename in os.listdir(SQL_DIR):
if not filename.endswith(".sql"):
continue
```
```python
instance_id = os.path.splitext(filename)[0]
if instance_id not in instruction_map:
continue
sql_path = os.path.join(SQL_DIR, filename)
try:
with open(sql_path, "r", encoding="utf-8") as sql_file:
original_sql = sql_file.read().strip()
except Exception:
continue
try:
transpiled_sql_list = transpile(
sql=original_sql,
read="snowflake",
write="trino",
identity=True,
error_level=sqlglot.errors.ErrorLevel.WARN,
transforms=[custom_transformer]
)
transpiled_sql = transpiled_sql_list[0] if transpiled_sql_list else original_sql
except Exception:
transpiled_sql = original_sql
```
#### Step 3: Assemble the Output Dataset
Combine everything — instruction, database, transpiled SQL, and the result file name — into a structured list.
```python
instruction, database = instruction_map[instance_id]
output_data.append({
"sql_query": transpiled_sql,
"instruction": instruction,
"database": database,
"result-file": instance_id
})
```
Finally, write collected data to a JSON file that will be used in the next step.
```python
OUTPUT_FILE = "output.json"
with open(OUTPUT_FILE, "w", encoding="utf-8") as out_file:
json.dump(output_data, out_file, indent=2, ensure_ascii=False)
```
### Sending Instructions to Peaka AI Agent
Peaka serves a powerful data management backend, enabling seamless integration between your front-end apps and structured data sources. It provides a unified layer to manage, query, and expose data securely. With features like API generation, data federation, and access controls, Peaka is designed to support use cases such as AI agents, dashboards, and automation tools. You can visit our documentation section to learn more about [how Peaka handles data management](/docs/embedded-peaka/data-management-backend).
**Prerequisites**
For this step, you must create Peaka project and have its ID and an API key. The Peaka project must contain one or more databases already integrated from snowflake and ready to be queried.
Now, use the outputs.json file from the previous step, and for each instruction:
1. Send a GET request to retrieve schema info.
2. Send a POST request to the Peaka AI agent with user question and schema
3. Collect the AI’s SQL response.
4. Measure response time.
5. Save all results in a structured file.
#### Step 1: Loading Needed Dependencies
Start by importing requests, time, json, and os for API calls and file handling.
```python
import os
import json
import requests
import time
from dotenv import load_dotenv
import os
load_dotenv()
```
Then define API, URLS and Headers :
```python
API_TOKEN = os.getenv("PEAKA_API_KEY")
GET_URL= "[https://partner.peaka.studio/api/v1/info](https://partner.peaka.studio/api/v1/info)"
POST_URL = "[https://partner.peaka.studio/api/v1/ai-agent/{project_id}/chat](https://partner.peaka.studio/api/v1/ai-agent/%7Bproject_id%7D/chat)"
INPUT_FILE= "output.json"
OUTPUT_FILE= "results.json"
```
> **GET_URL:** Fetches info about your Peaka project (including projectId).
> **POST_URL:** Sends questions to the AI agent in that project.
Headers include your token for authorization:
```python
headers = {
"Authorization": f"Bearer {API_TOKEN}",
"Content-Type": "application/json"
}
```
#### Step 2: Get Peaka Project ID
```python
with open(INPUT_FILE, 'r') as f:
data = json.load(f)
response= requests.get(GET_URL, headers=headers)
project_info= response.json()
project_id = project_info.get("projectId")
```
#### Step 3: Loop through Instructions and Send to the AI Agent
```python
results = []
target_databases = {"AIRLINES"}
if database not in target_databases:
continue
```
Send POST request:
```python
body = {"message": question}
start_time = time.time()
response = requests.post(
POST_URL.format(project_id=project_id),
headers=headers,
json=body
)
end_time = time.time()
elapsed_time = round(end_time - start_time)
```
#### Step 4: Process Response and Collect Results
```python
reply = response.json()
content_raw = reply["result"]["messages"][1]["kwargs"]["content"]
results.append({
"database": item.get("database"),
"question": question,
"result": content_raw,
"response_time": elapsed_time})
```
Finally, dump the full array of results to disk:
```python
with open("results.json", "w", encoding="utf-8") as f:
json.dump(results, f, indent=2, ensure_ascii=False)
```
### Visualizing Results with Streamlit
To explore and compare the AI-generated SQL outputs visually, I built a simple Streamlit Dashboard. It lets you browse through databases and its instructions, view Peaka’s results alongside the original Spider queries, and evaluate differences if any. You can find the full Streamlit implementation in the [Github repository.](https://github.com/ramamatar/PeakaSemantics/blob/main/streamlit.py) To launch the app locally, just run:
```bash
streamlit run streamlit.py
```
It will appear on your browser like the following, where you can select the specific database and the question related to get the desired answer.

### Enhancing Accuracy with Peaka’s Semantic Tool
Peaka comes with a tool that analyzes the database schema and automatically generates rich semantic metadata (such as column descriptions, table purposes, and relationships), which are then used by the AI agent during query generation. By providing deeper context about the data, the agent is able to produce significantly more accurate SQL outputs, enhancing the performance of the agent.
I will walk you through how you can simply generate semantics of the tables you are working on. As an example, we’ll generate semantics for a Snowflake Table named “aircrafts_data” that contains information about different aircrafts items, including their code, model, and ranges.

Follow these steps along:
1. **Open the Edit Metadata Modal:** Click the “Edit Metadata” button above the table. This action opens a modal where you can define more detailed description of the table and columns.

As you can see the descriptions are initially empty before generating semantics.
1. **Open Generating Semantics Modal:** To add more context to the table click the “Generate Semantics” button on the right side above the table.

To ensure accurate semantic generation, an **initial prompt** is included upfront to frame how the assistant should interpret incoming queries. For this example, you can add something like “code, models and ranges of aircrafts”.
1. **Generate Semantics:** after adding initial prompt, click “Generate Semantics” and wait until you see the previous table description columns has been filled with explanations about the data.

Columns descriptions and sample values has been added automatically by Peaka.
1. **Update Metadata**: to save the data semantics click “Update Metadata” button.

That’s it! Now the metadata of our table has been updated successfully and will be used effectively by the AI agent while retrieving the data and generating more accurate SQL queries.
Let’s look at a specific example that demonstrates the difference before and after applying Peaka’s semantic tool. The same NL instruction is processed by the AI agent in both cases. The resulting answer shows how semantics lead to more accurate interpretation and alignment with the expected logic from the Spider benchmark.

Peaka’s initial results significantly lag behind Spider’s performance before table semantics are generated for the query.

After generating the Semantics of data, we retrieve an accurate answer more quickly.
## Key Takeaways
- Spider is a widely used benchmark for evaluating the performance of natural language to SQL systems, offering complex, multi-domain instructions and queries.
- Transpiring SQL syntax makes Snowflake compatible with Spider queries.
- Peaka AI Agent was tested using real Spider instructions, with responses retrieved via API.
- Response accuracy improves significantly when adding semantic to the data with the help of Peaka, as it adds meaning and structure to database columns.
## Conclusion
This project demonstrates how combining the Spider benchmark with Peaka AI Agent reveals the power of semantics in natural language to SQL generation. While raw AI responses can approximate correct queries, enabling semantics bridges the gap between vague column names and their true intent, leading to more accurate, reliable SQL output. Tools like Peaka’s semantic enhancer not only improve model understanding but also make AI-powered data access far more effective in real-world applications.
Feel free to reach out to me on [my Github account](https://github.com/ramamatar) for any questions or comments.
--- START: integrations/hubspot-stripe/hubspot-stripe.md ---
INTEGRATIONS
------------
One-click Hubspot-Stripe integration.
=====================================
Real-time reports. Actionable insights.
---------------------------------------

What can you do with Peaka's HubSpot-Stripe connector?
------------------------------------------------------
Enrich revenue data from Stripe with the customer data from HubSpot.
Edit and query your consolidated data and see how your revenue changes in relation to customer attributes.
Understand who your best-fit customers are and adjust your messaging accordingly.

How does Peaka’s HubSpot-Stripe integration compare to ProfitWell RevConnect?
-----------------------------------------------------------------------------
ProfitWell RevConnect is a popular HubSpot-Stripe connector, albeit one with a few shortcomings. Peaka offers a marked improvement over ProfitWell in three different areas:

 Custom filters to pull in just what is needed
 Flexible querying independent of data structure
 Dynamic reports, charts, and dashboards
 
 ProfitWell RevConnect
 No filters for keeping unwanted data out
 Requires data structure to match the structure in HubSpot
 Limited to the HubSpot infrastructure for displaying data
Explore Peaka and try how you can bring your SaaS data together
Sign Up for Free
###  Unified data, powerful insights
Reports you can generate with Peaka
-----------------------------------
### Country-based MRR by the pricing plan
Find out how your MRR changes across different countries and pricing plans. Learn where your best-fit customers are located and create marketing campaigns targeting specific demographics.


### Industry-based MRR by the pricing plan
Subscriptions in some industries are subject to seasonality. Understanding how demand for specific pricing plans changes throughout the year helps you better schedule your outreach and maximize conversion rates.


### Company-size-based MRR by the pricing plan
Company size is an indispensable element of your customer segmentation efforts. Pull in your revenue and pricing plan data from Stripe, blend it with the company size data from HubSpot, and you can now identify the type of companies your product is popular with.


And many more..
---------------
### Country-based churned MRR by the pricing plan
Take a better look at the fall in your MRR resulting from canceled subscriptions and how it changes in relation to the pricing plan and country.
### Industry-based ARR by the pricing plan
Find out how your annual revenue from a pricing plan deal varies across different industries.
### Funding-based MRR by the pricing plan
This report reveals how your product and messaging resonate with customers in different funding stages.
### IPO-based MRR by the pricing plan
Discover how much of your revenue comes from public companies and the pricing plans they have subscribed to.
### Country-based customer lifetime value by the pricing plan
Where are your most valuable customers located? Which pricing plans do they prefer? Find out with this report.
### Industry-based average revenue per user (ARPU) by the pricing plan
Break down your ARPU data into components and see how it varies across pricing plans and industries.
Explore Peaka and see how you can bring your SaaS data together
Sign Up for Free
### Let’s talk!
Let us walk you through Peaka. Contact us for more information.
Submit
--- START: partners/looker-studio/looker-studio.md ---

Peaka Connector for Looker Studio
---------------------------------
Use Peaka’s wide array of connectors to pull in and join data from various data sources such as PostgreSQL, Google Analytics, Stripe, Mongo DB, HubSpot, Google Ads, Salesforce, and Snowflake.
Turn your consolidated data into fully customizable dashboards and reports on Looker Studio with a single query.
Enhance your reports with charts, links, images, and color-coding to reveal the insights hidden in your data.
Harness your data’s potential with Peaka
----------------------------------------
Peaka is a zero-ETL data integration platform that allows users to connect and query all data sources, including databases, NoSQL, SaaS tools, and APIs, as a single source.
With Peaka, you can
* Convert APIs into relational databases in real time,
* Use SQL to query APIs and NoSQL databases,
* Filter your unified data to form new data sets and expose them with APIs to serve BI tools, APIs, and DB drivers,
* Ingest event and streaming data using webhooks.

How to get started with Peaka
-----------------------------
Peaka is a SaaS platform with a usage-based pricing model.
Its freemium and free-trial options let users experience the platform’s capabilities before upgrading.
In order to use Peaka’s Looker Studio connector and other features, you need to sign up by setting up an account.
Try for free  [Pick your place ](https://peaka.studio/home/billing)
### Step 1 - Connect & cross-query any data source immediately
Use Peaka’s powerful connector capability to retrieve your data from different data sources and join them in our Query Engine.
### Step 2 - Connect your Peaka project to Looker Studio with an API Key
Decide which fields you want to include in your report. First, select a Catalog, then a Schema, and finally, a table. Check your columns and data type mapping to ensure that everything is set properly.
### Step 3 - Visualize your data
Ta-da! You can now share your Peaka data with Looker Studio and create custom reports from your data sets using Looker Studio’s advanced dashboard capabilities.
Use Peaka’s powerful connector capability to retrieve your data from different data sources and join them in our Query Engine.
Decide which fields you want to include in your report. First, select a Catalog, then a Schema, and finally, a table. Check your columns and data type mapping to ensure that everything is set properly.
Ta-da! You can now share your Peaka data with Looker Studio and create custom reports from your data sets using Looker Studio’s advanced dashboard capabilities.
### Connect Peaka to Looker Studio
Read our how-to guide for step-by-step instructions on how you can set up your Peaka Connector for Looker Studio.
[Read the how-to guide ](/docs/bi-tools/looker-studio/)
--- START: partners/servicetitan-integration/servicetitan-integration.md ---
Make the most of your ServiceTitan data
=======================================

Connect ServiceTitan with any data source, from accounting platforms to CRMs and spreadsheets.

Send your unified data to any BI tool for visualization.
Try for Free  Talk to Sales
Peaka’s partnership with ServiceTitan allows home and field service businesses to maximize the potential of their ServiceTitan subscription.

Unified data
Combine ServiceTitan and any business data
------------------------------------------

Join your ServiceTitan data with your QuickBooks, Excel, Google Sheets, and HubSpot data without a single line of code.

Skip the data warehouse and query your data across systems without moving or duplicating it.

Effortless dashboards
View your ServiceTitan data
in Looker Studio, Power BI, or Tableau
--------------------------------------------------------------------
Turn your ServiceTitan data into dashboards in your BI tool of choice.
Track metrics and KPIs, and gain visibility into the overall performance of your business.

Empowered teams
ServiceTitan reporting
made easy
--------------------------------
Stop exporting data manually. Make sure that your dashboards are continuously updated with fresh data.
Let your business teams generate reports and build custom dashboards without having to rely on IT.


Enhanced productivity
Improve every single process with
data-driven insights
--------------------------------------------------------
Combine job costing, scheduling, and billing data.
Monitor job progress, technician performance, and customer sentiment.
Create custom dashboards with real-time insights.
Enable field operations and finance teams to self-serve reports.
Pricing
-------
Monthly Yearly 16.7% savings
Basic Package
$299 \-16.7%
Choose Plan
Save 2 months with yearly billing
Typical Usage Pattern
* 
Up to 4 daily syncs
* 
Suitable for small businesses with 5-15 employees, 1-2 locations
Includes
* 
5,000 compute minutes/month
* 
Up to 50GB of data storage
* 
Minimum 6-hour intervals
* 
Unlimited data connectors
(including ServiceTitan)
* 
5 seats
Add-on Support Services
* 
Available on demand
Standard Package
$499 \-16.7%
Choose Plan
Save 2 months with yearly billing
Typical Usage Pattern
* 
8 daily syncs for operational tables
* 
Suitable for mid-sized businesses with 15-40 employees, 2-5 locations
Includes
* 
10,000 compute minutes/month
* 
Up to 200GB of data storage
* 
Minimum 2-hour intervals
* 
Unlimited data connectors
(including ServiceTitan)
* 
15 seats
Add-on Support Services
* 
Available on demand
Premium Package
$999 \-16.7%
Choose Plan
Save 2 months with yearly billing
Typical Usage Pattern
* 
Hourly syncs for most other tables
* 
Complex queries across multiple data sources
* 
Suitable for larger operations with 40+ employees, multiple locations
Includes
* 
20,000 compute minutes/month
* 
Up to 500GB of data storage
* 
Minimum 15-minute intervals
* 
Unlimited data connectors
(including ServiceTitan)
* 
Unlimited number of seats
Add-on Support Services
* 
Available on demand
Custom Enterprise
Package
Talk to Sales
Save 2 months with yearly billing
Typical Usage Pattern
* 
Suitable for large organizations and PEs
Includes
* 
Custom package configurations and integrations
* 
Special SLA levels and onboarding scenarios
Add-on Support Services
* 
Available on demand
Get started now
Unlock the benefits of
the ServiceTitan-Peaka partnership  
----------------------------------------------------------------------------------------------------------------------------------------------------------------------
Transform your ServiceTitan experience, from data integration to querying and visualization
Try for Free  Talk to Sales
### Add-on Customer Support Services
Maximize the value of your ServiceTitan subscription with our professional support services.
White-glove Onboarding Service
$1,500 (One-Time Fee)
* 
Initial ServiceTitan connection setup
* 
Configuration of additional data sources
(Up to 5 additional data sources)
* 
Creation of 2 basic dashboards in your preferred BI tool
* 
3 hours of team training
Professional Ongoing Support Service
$1,500 /month
* 
Best for growing businesses with evolving needs
* 
5 hours of dedicated support per month
* 
Monthly system health checks and performance optimization assessment
* 
Quarterly business review with recommendations
* 
Co-development of 1 new dashboard per quarter
* 
Priority email and Slack/Teams channel support with predefined SLA times
Close Continue
Trusted by leading ServiceTitan consultants
-------------------------------------------
Top ServiceTitan consultants trust Peaka to unify data, manage multiple accounts, and deliver dashboards at scale.
Interested in becoming a partner? Get in touch.
[Book a demo ](https://calendly.com/peaka/demo)


### Let’s fix your ServiceTitan reporting workflow
Tell us a bit about your setup, and we’ll show you how teams scale reporting.
First Name
Last Name
Company Name
Company Email
Phone Number (optional)
Submit
--- START: release-notes/action-buttons/action-buttons.md ---
[ Back to What's New](/release-notes) January 12, 2024
Action buttons
==============
Peaka now offers “action buttons” that can be used to initiate row-based actions in data tables.
With action buttons, users can edit or delete a specific row or trigger predefined flows that will take place at the click of a button. By just setting up flows and clicking on an action button, users can send the records in rows meeting predetermined criteria via an email or a Slack message.
Action buttons enable Peaka users to add new capabilites to their data tables and make them even more functional.

Tags: [New Feature](/release-notes?tag=New Feature)
--- START: release-notes/ads-integration/ads-integration.md ---
[ Back to What's New](/release-notes) April 30, 2024
Google Ads integration
======================
By far the most popular online advertising platform, Google Ads is an integral part of daily operations for e-commerce companies, digital marketing teams, and local services businesses. With its ability to target certain locations, industries, and demographics, Google Ads gives businesses of all sizes a much-needed capability to create tailored marketing campaigns and track metrics.
Peaka’s Google Ads integration enables users to access and query their Google Ads data in real time. Users can then join this data with data from popular BI tools and CRMs, gaining a more comprehensive view of their digital marketing activities.
Tags: [New Feature](/release-notes?tag=New Feature)
--- START: release-notes/amazon-dynamodb-integration/amazon-dynamodb-integration.md ---
[ Back to What's New](/release-notes) September 01, 2023
Amazon Dynamodb integration
===========================
Peaka now supports integration with Amazon Dynamodb, empowering its users to query NoSQL databases with SQL.
You can now apply your SQL skills to NoSQL databases and leverage their versatility and flexibility with your existing skill set.
Tags: [New Feature](/release-notes?tag=New Feature)
--- START: release-notes/asana-connector/asana-connector.md ---
[ Back to What's New](/release-notes) May 30, 2025
Asana connector
===============
Asana is a work management platform that helps teams plan, organize, track, and complete work. It’s especially popular with marketing teams, project managers, product teams, and cross-functional teams looking to manage everything from a single interface.
Teams use Asana to align around common goals, meet deadlines, and become more productive. The platform gives managers visibility into the tasks, resources, and progress being made while instilling a sense of accountability across teams.
Peaka helps join Asana data with data from other sources, such as
* Jira, to track progress in software development,
* Zendesk, to link customer support tickets to specific internal tasks,
* Slack and Microsoft Teams, to auto-create tasks from messages and minimize manual task creation.
Peaka’s Asana connector enables users to enrich and extract more value from their Asana data.
Tags: [New Feature](/release-notes?tag=New Feature)
--- START: release-notes/bulk-selected-rows-delete/bulk-selected-rows-delete.md ---
[ Back to What's New](/release-notes) December 15, 2023
Bulk deletion & selected-rows deletion
======================================
Bulk deletion and selected-rows deletion options are now available for Peaka Tables and Peaka BI Tables. Users can now easily delete multiple rows of data at once, as well as pick and delete specific rows, eliminating the need to delete them one by one.
These features allow users to delete data that is no longer up-to-date or relevant to the business, helping them uphold data quality. Bulk deletion & selected-rows deletion also simplify getting rid of test data one no longer needs or data mistakenly pulled in from other systems.
_That’s one small step for mankind, but one giant leap for the junior employee who has thousands of rows to delete in various data tables._

Tags: [New Feature](/release-notes?tag=New Feature)
--- START: release-notes/bullhorn-crm-integration/bullhorn-crm-integration.md ---
[ Back to What's New](/release-notes) March 14, 2024
Bullhorn CRM integration
========================
Peaka now readily integrates with Bullhorn CRM, one of the go-to platforms for companies operating in the staffing industry. Helping its users achieve higher job placement rates through streamlined hiring processes, Bullhorn CRM is widely popular among recruitment professionals, account managers, HR departments, and C-level decision-makers.
Peaka’s seamless integration with Bullhorn CRM allows users to pull in data from this capable platform and combine it with data from various sources. This gives users better visibility into recruitment processes, reduces paperwork, and enhances applicant tracking and evaluation.
Tags: [New Feature](/release-notes?tag=New Feature)
--- START: release-notes/caching-option/caching-option.md ---
[ Back to What's New](/release-notes) October 16, 2023
Caching option
==============
You can now enable the caching option and set a caching frequency for your Peaka projects.
This feature makes it possible for you to work with a cached version of your data and minimize the query execution times when real-time data is not a priority.
Tags: [New Feature](/release-notes?tag=New Feature)
--- START: release-notes/chartmogul-connector/chartmogul-connector.md ---
[ Back to What's New](/release-notes) December 06, 2024
ChartMogul connector
====================
ChartMogul is a subscription analytics platform that pulls in data from different payment tools, turning that data into metrics such as churn rate, MRR, ARR, LTV, and so on. Adding a CRM to its product range in 2023, the company now unifies customer and financial data in one platform.
ChartMogul’s strength lies in its “cohort analysis” capability, which allows users to monitor the metrics of a group of users that signed up in a specific timeframe. Coupled with ChartMogul’s integrations with various payment gateways, this capability enables users to generate granular revenue reports at the MRR-by-cohort level, providing insights for business teams.
ChartMogul users working with different CRMs and data sources have so far relied on data warehouses to import data from other data sources and combine that data with their ChartMogul data. Peaka’s ChartMogul connector is a game changer in this regard, as it enhances the connectivity of this platform without any need for data warehouses and pipelines.
This connector enables users to pull in subscription analytics, customer, and billing data from ChartMogul and join it with data from other sources, such as CRMs, databases, and SaaS tools, to form new data sets. Users can then send this consolidated data to dedicated BI tools to create reports and dashboards that tell a story.
Tags: [New Feature](/release-notes?tag=New Feature)
--- START: release-notes/codat-connector/codat-connector.md ---
[ Back to What's New](/release-notes) December 25, 2024
Codat connector
===============
Codat is a universal API infrastructure for banks, finance institutions like banks, fintech companies, and insurance firms. Its integrations enable users to pull in data from ERPs, bank accounts, point-of-sale devices, and a wide range of accounting software and form a 360-degree view of their customers.
The customer financial data unified by Codat helps lenders evaluate credit risk better and allows insurance companies to streamline their underwriting process. With Codat, organizations can build integrations at scale without creating extra workload for the engineering teams.
Peaka’s dedicated connector for Codat further extends this powerful platform, allowing Codat users to join the financial data they consolidated with customer data from a CRM or SaaS data from any popular app. Peaka then sends this new dataset to a BI tool for visualization, if you wish to do so.
The good thing is, there are no data warehouses or pipelines involved in this process.
Tags: [New Feature](/release-notes?tag=New Feature)
--- START: release-notes/column-based-filtering/column-based-filtering.md ---
[ Back to What's New](/release-notes) December 15, 2023
Column-based filtering
======================
Peaka users can apply column-based filtering in their data tables. This feature allows them to filter a range of data based on the criteria they provide.
Users can set the filter condition by clicking on the filter icon in the top cell in a column and then entering the filter value.

Tags: [New Feature](/release-notes?tag=New Feature)
--- START: release-notes/databricks-crm-integration/databricks-crm-integration.md ---
[ Back to What's New](/release-notes) April 15, 2024
Databricks integration
======================
Databricks is a lakehouse platform that lends itself to machine learning, artificial intelligence, and streaming use cases. It's optimized for handling big data, intense computing, and data science initiatives.
Databricks users train their machine learning models on the data stored on the platform. Peaka allows them to unify this data with data from other sources and create a single view of truth.
Tags: [New Feature](/release-notes?tag=New Feature)
--- START: release-notes/embedded-chatgpt/embedded-chatgpt.md ---
[ Back to What's New](/release-notes) August 11, 2023
Embedded ChatGPT
================
Peaka launches its embedded ChatGPT feature, allowing you to query your data or modify and update an existing query using natural language.
Thanks to Peaka’s embedded ChatGPT, you can chat with your data and build up reports in an iterative manner even if you are not proficient in SQL or simply do not want to write queries.
Tags: [AI](/release-notes?tag=AI)
--- START: release-notes/excel-365-integration/excel-365-integration.md ---
[ Back to What's New](/release-notes) May 30, 2024
Microsoft 365 Excel integration
===============================
For decades, Microsoft Excel has consistently been among the most popular software in the business world. With hundreds of built-in functions, it has become the go-to software for millions of organizations worldwide and powered operations seemingly beyond the capabilities of a simple spreadsheet program.
Always in tune with the times, this iconic software was rebranded as Microsoft 365 Excel as part of the cloud-powered Microsoft 365 suite of software, making online collaboration across different platforms a breeze.
With Peaka’s new connector, you can now tap into your Microsoft 365 Excel data and query it using SQL or natural language. Our connector also enables you to join your Excel data with data from other SaaS tools, giving you a more complete view of your operations.
Tags: [New Feature](/release-notes?tag=New Feature)
--- START: release-notes/export-to-csv/export-to-csv.md ---
[ Back to What's New](/release-notes) December 15, 2023
Data export into a CSV file
===========================
Users now have the ability to export their data into a CSV file, which enables them to easily utilize and manipulate the filtered or transferred data with their preferred tool, such as Excel.
CSV files allow you to transfer your data between different applications in a simple and standardized format that other software applications can easily process. They also make it easier for users to upload lists of contacts into CRM platforms or marketing automation tools, simplifying day-to-day operations for business teams.
This feature enhances data utilization across different systems in an organization, making data accessible to a wider user base.

Tags: [New Feature](/release-notes?tag=New Feature)
--- START: release-notes/firebase-integration/firebase-integration.md ---
[ Back to What's New](/release-notes) April 15, 2024
Firebase integration
====================
Firebase is an app development platform that mobile app developers utilize as backend infrastructure. It offers users a secure, scalable environment for developing, testing, and previewing their apps.
Peaka’s Firebase integration allows users to remain on top of their apps all the time. With Peaka, they can monitor events and track user journeys in each of their various apps and aggregate data in a single platform.
Tags: [New Feature](/release-notes?tag=New Feature)
--- START: release-notes/freshdesk-connector/freshdesk-connector.md ---
[ Back to What's New](/release-notes) January 09, 2025
Freshdesk connector
===================
Freshdesk is an all-in-one help desk solution developed by Freshworks. Alongside acting as a ticketing tool that allows customers to report issues they encountered with a product, Freshdesk also assists customer support teams in aligning their efforts to address these issues.
Users can leverage Freshdesk to open tickets and sub-tickets that delegate tasks to individuals and form meaningful workflows. Additionally, the platform excels in creating FAQ material and AI chatbots so customers can self-serve in more than forty languages. Its reporting capability gives users visibility into help desk performance, ticket lifecycle, recurring problem points, and customer satisfaction.
Peaka’s Freshdesk connector extends this powerful tool, allowing it to pull in data from other platforms. By joining ticketing data with their CRM or payment data, Freshdesk users can gain new insights to perfect their customer support strategy and improve customer segmentation.
Tags: [New Feature](/release-notes?tag=New Feature)
--- START: release-notes/github-connector/github-connector.md ---
[ Back to What's New](/release-notes) September 13, 2024
Github connector
================
GitHub is a web-based repository running on Git software. With version control, bug tracking, task management, and continuous integration, it has become an integral part of how code is written, stored, and shared since 2007.
Peaka’s dedicated connector simplifies pulling in data from GitHub and making sense of GitHub activity. It gives users visibility into every repository they have access to, allowing them to monitor pull requests, issues, and commits and see their contents.
Users can apply filters to GitHub data and create custom reports on the number of pull requests received from public repositories, open issues, and their status, practically turning raw statistics into metrics. These reports cast light on the efficiency of development processes, helping project leaders make better decisions.
Tags: [New Feature](/release-notes?tag=New Feature)
--- START: release-notes/google-bigquery-integration/google-bigquery-integration.md ---
[ Back to What's New](/release-notes) September 01, 2023
Google BigQuery integration
===========================
Peaka now supports integration with BigQuery, which is particularly suitable for business analytics and working with big data.
If you need to run super-fast queries on millions of records buried in petabytes of data, this connector allows you to do just that.
Tags: [New Feature](/release-notes?tag=New Feature)
--- START: release-notes/gorgias-connector/gorgias-connector.md ---
[ Back to What's New](/release-notes) April 29, 2025
Gorgias connector
=================
Gorgias is an AI-powered helpdesk and customer service platform for e-commerce businesses. More than a basic ticketing tool, it centralizes disparate support efforts across disparate channels, helping customer support teams align around common goals.
Gorgias offers three products that address different needs:
* **Gorgias Automate,** which uses AI agents to track orders, make refunds, or resolve issues through personalized interactions,
* **Gorgias Helpdesk,** which offers AI assistance for managing support tickets, building a knowledge base, and streamlining performance reporting,
* **Gorgias Convert,** which provides campaign management aimed at increasing revenue through customization and cross-selling initiatives.
Peaka allows customer support teams to join their Gorgias data with customer data from other sources such as HubSpot, Stripe, and Salesforce. Our Gorgias integration helps users better understand their customers and perfect their customer segmentation.
Tags: [New Feature](/release-notes?tag=New Feature)
--- START: release-notes/heatmap-chart/heatmap-chart.md ---
[ Back to What's New](/release-notes) December 15, 2023
Heatmap chart
=============
Peaka users now have the option to view their data in a ‘heatmap chart’ format, which provides color-coded way for presenting data.
Heatmap charts add a third dimension (color coding) to the X- and Y- axes and demonstrate the strength of the relationship between two variables. In addition to increasing the amount of information a chart can convey, this format also helps reveal underlying patterns and trends, which may be difficult to discern in a regular table.
Heatmap charts are excellent tools for displaying large amounts of data like cohort retention data for SaaS companies, employee performance data for sales teams, census data for government agencies, or meteorological data for climate scientists.

Tags: [New Feature](/release-notes?tag=New Feature)
--- START: release-notes/hubspot-stripe-integration/hubspot-stripe-integration.md ---
[ Back to What's New](/release-notes) June 19, 2023
Hubspot-Stripe integration
==========================
Peaka launches its HubSpot-Stripe connector, which allows users to pull in customer data from HubSpot and join it with the payment data pulled in from Stripe.
With this connector, users can now generate highly granular revenue reports, which helps with customer segmentation and identifying best-fit customers.
Tags: [New Feature](/release-notes?tag=New Feature)
--- START: release-notes/jira-cloud-integration/jira-cloud-integration.md ---
[ Back to What's New](/release-notes) December 08, 2023
Jira Cloud integration
======================
With this connector, you can pull in data from Jira Cloud and track the rate at which your teammates close issues, monitor their workloads, and keep an eye on the bugs reported.
Peaka’s Jira Cloud connector enables you to join your Jira data with the data from CRM platforms, HR suites, or Google Sheets, boosting your ability to track and evaluate employee performance.
Tags: [New Feature](/release-notes?tag=New Feature)
--- START: release-notes/jira-service-management-connector/jira-service-management-connector.md ---
[ Back to What's New](/release-notes) January 23, 2025
Jira Service Management connector
=================================
Jira Service Management (JSM) is a versatile service desk solution for managing service requests IT departments routinely receive. Built by Atlassian, JSM simplifies the management of both external and internal support requests, harmonizing IT workflows and optimizing resource allocation.
JSM comes with pre-made templates for common service requests and workflows, which simplify onboarding and allow users to launch a helpdesk right away. In addition to enabling engineering teams to manage customer requests and triage issues, the platform also helps create a knowledge base so internal users can self-serve.
JSM’s interaction with various systems turns it into a valuable source of data. Peaka’s JSM connector lets users integrate this data source with other sources like CRMs and payment platforms. By joining their JSM data with customer and payment data, users gain deeper insights into the service requests IT people face so they can improve their service desk strategy.
Tags: [New Feature](/release-notes?tag=New Feature)
--- START: release-notes/klaviyo-connector/klaviyo-connector.md ---
[ Back to What's New](/release-notes) April 29, 2025
Klaviyo connector
=================
Klaviyo is a marketing automation platform used by e-commerce businesses to collect customer data, improve customer segmentation, run targeted marketing campaigns, and automate future interactions. Its capabilities make Klaviyo an integral part of customer acquisition and retention strategies.
Klaviyo offers four different solutions to its customers:
* **Klaviyo Marketing,** which automates how B2C companies engage with their customers through emails, SMS, mobile push, and reviews.
* **Klaviyo Service,** which uses AI agents to tailor order management and product recommendations to the exact needs of customers,
* **Klaviyo Analytics,** which gives users more visibility into the customer journey of every shopper, allowing them to identify churn risks and cross-sell opportunities,
* **Klaviyo Data Platform,** which centralizes customer data for further analysis and segmentation.
Peaka enables users to pull their Klaviyo data and join it with data from other sources, such as CRMs, SaaS tools, and relational databases. Peaka’s ready-made connector lets this versatile platform maximize its potential without any data warehouse or data pipeline involved.
Tags: [New Feature](/release-notes?tag=New Feature)
--- START: release-notes/looker-studio-integration/looker-studio-integration.md ---
[ Back to What's New](/release-notes) August 15, 2024
Looker Studio integration
=========================
Easily one of the most capable and enterprise-ready business intelligence (BI) platforms on the market, Looker Studio is designed to cater to the most sophisticated data visualization needs of complex organizations. Its advanced data modeling capability makes this platform a good fit for a wide range of use cases.
In addition to providing its users with more than twenty connectors and over forty ready-made visualizations built in-house, Looker Studio also offers a collection of more than 1,000 connectors built and supported by its partners. This allows users to pull in data from almost any data source and generate highly customizable reports, charts, and dashboards from their consolidated data.
As one of Looker Studio's partners, Peaka readily integrates with this platform, giving Peaka users another option for visualizing their data. This integration enables users to unify their data from different sources, run join queries, form new datasets, and view them with Looker Studio.
Limited only by its users’ needs and technical expertise, Looker Studio is a valuable addition to the BI integrations supported by Peaka.
Tags: [New Feature](/release-notes?tag=New Feature)
--- START: release-notes/make-integration/make-integration.md ---
[ Back to What's New](/release-notes) February 08, 2024
Make integration
================
Peaka now seamlessly integrates with Make, the popular workflow automation platform formerly known as Integromat. This integration brings together Make’s ‘scenarios’ (workflows) with Peaka’s data integration and querying capability.
Make users can leverage Peaka to connect to various data sources and unify and query their data. They can then choose from Make’s wide array of workflows to perform different actions with their consolidated data.
Tags: [New Feature](/release-notes?tag=New Feature)
--- START: release-notes/metabase-integration/metabase-integration.md ---
[ Back to What's New](/release-notes) June 14, 2024
Metabase integration
====================
Metabase is an open-source business intelligence (BI) platform that integrates with more than twenty databases and data warehouses. It allows users to query their data and turn it into charts and graphs to reveal hidden trends and patterns, making business analytics accessible to everyone in an organization.
With Peaka’s Metabase integration, users can now leverage Peaka’s ready-made connectors to retrieve data from a wide array of SaaS tools in addition to the databases and data warehouses Metabase integrates with. After joining data from two data sources, our new integration enables users to treat the resulting dataset as a new data source and visualize it with Metabase.
Peaka’s Metabase integration makes data visualization a seamless process across a wide range of platforms, helping unlock deeper insights and data-driven decisions.
Tags: [New Feature](/release-notes?tag=New Feature)
--- START: release-notes/new-connectors/new-connectors.md ---
[ Back to What's New](/release-notes) July 19, 2023
New connectors launched (OpenAI, Google Analytics, and more)
============================================================
Peaka introduces a new set of connectors, making it possible for you to access your Intercom, OpenAI, Mailchimp, Jira, and Google Analytics data.
This adds to an already impressive suite of database connectors Peaka has launched for Amazon Redshift, Google Sheets, MariaDB, MongoDB, and Oracle, creating a lightweight, easy-to-use data integration platform that you can operate without the need for a data team.
Tags: [New Feature](/release-notes?tag=New Feature)
--- START: release-notes/organization-workspace-hierarchy/organization-workspace-hierarchy.md ---
[ Back to What's New](/release-notes) March 27, 2025
New project structure with organizations & workspaces
=====================================================
Peaka now features a new hierarchy that supports more scalable and secure access controls for projects.
Projects are no longer grouped solely under accounts. Instead, they are now placed within Workspaces, which are, in turn, grouped under a new top-level entity called an Organization.
Organization
└── Workspace
└── Project
Users can now assign roles and permissions at the Workspace and Organization levels, instead of configuring access on a project-by-project basis. Teams can be granted access to entire Workspaces, streamlining onboarding and cross-project collaboration. This new structure makes settings and permissions more manageable for admins and sets the stage for even more advanced features in the future.
Tags: [New Feature](/release-notes?tag=New Feature)
--- START: release-notes/pipedrive-crm-integration/pipedrive-crm-integration.md ---
[ Back to What's New](/release-notes) March 14, 2024
Pipedrive CRM integration
=========================
Peaka adds another popular CRM platform to its growing list of integrations: Pipedrive. But make no mistake—Pipedrive is not your run-of-the-mill CRM. Despite offering the usual CRM capabilities such as customizable reports, dashboards, emailing, and workflow automation, this platform specializes in catering to the needs of sales teams.
Pipedrive enables its users to monitor sales pipelines, manage various aspects of sales funnels, and help sales teams close more deals. Thanks to Peaka’s hassle-free integration, users can now extract their sales data from Pipedrive and join it with data from other sources, such as Stripe and Google Sheets, gaining deeper insight into their sales cycles.
Peaka’s Pipedrive integration ensures that sales teams better align with other business functions.
Tags: [New Feature](/release-notes?tag=New Feature)
--- START: release-notes/posthog-connector/posthog-connector.md ---
[ Back to What's New](/release-notes) April 29, 2025
PostHog connector
=================
PostHog is an open-source, multi-purpose product analytics platform primarily used by product teams. It serves as a one-stop shop for tracking event-based analytics, creating conversion funnels, running in-app surveys, and analyzing web analytics.
PostHog’s versatility makes it an essential tool in the SaaS startup toolbox, as it offers no-code A/B testing, session replays, and heatmaps. These capabilities allow SaaS product teams to analyze, test, and deploy new features with confidence.
Peaka’s dedicated PostHog connector multiplies the number of data sources this capable tool integrates with. It enables product teams to join PostHog data with any other data to make better decisions during the product development cycle.
Tags: [New Feature](/release-notes?tag=New Feature)
--- START: release-notes/power-bi-integration/power-bi-integration.md ---
[ Back to What's New](/release-notes) July 26, 2024
Power BI integration
====================
Power BI is Microsoft’s data visualization platform, catering to a wide range of use cases for individuals, teams, departments, and enterprises. Like all other Microsoft products, such as Teams, PowerPoint, Excel, and Power Platform, Power BI is optimized for various user personas, from business analysts to data scientists to developers.
While Power BI readily connects to Excel, Azure, and Microsoft 365 apps, Peaka’s integration allows this powerful platform to incorporate SaaS data as well, giving users a single view of truth from their scattered data. Thanks to this integration, users can also leverage Peaka to consolidate their data from different sources, run join queries, and visualize the results of those queries with Power BI.
This new integration extends Power BI beyond the limits of the Microsoft ecosystem, turning it into a do-it-all type of data visualization platform for all types of data sources and users.
Tags: [New Feature](/release-notes?tag=New Feature)
--- START: release-notes/preset-integration/preset-integration.md ---
[ Back to What's New](/release-notes) June 26, 2024
Preset integration
==================
Preset is a business intelligence (BI) platform built on the open-source Apache Superset. Being able to connect to a host of SQL databases and data warehouses, Preset offers an easy-to-use drag-and-drop interface and fully interactive dashboards with more than forty pre-built visualizations to view data.
Peaka’s Preset integration adds to these already impressive capabilities and enables Preset users to pull in data from a wide range of SaaS platforms. Thanks to this integration, users can join data from different sources, form new data sets, and visualize them with Preset.
Reducing the time from data to insights, Peaka’s Preset integration helps boost productivity and empower non-technical users to self-serve while working with data.
Tags: [New Feature](/release-notes?tag=New Feature)
--- START: release-notes/profitwell-connector/profitwell-connector.md ---
[ Back to What's New](/release-notes) December 20, 2024
ProfitWell connector
====================
ProfitWell has been one of the forerunners in subscription analytics for years. Its software has provided SaaS companies with all the metrics, KPIs, and actionable insights they need for smooth operation.
ProfitWell offers hassle-free integration with the most popular payment gateways. The financial data it gathers from these platforms sheds light on which accounts are ready to convert or upgrade and which ones are about to churn. These insights inform various critical decisions in budgeting, marketing, and hiring.
Peaka’s ready-made connector for ProfitWell multiplies the number of data sources and destinations this platform can connect with. It enriches the ProfitWell reports with data from other sources and feeds this consolidated data into dedicated data visualization tools—all without any data warehouse or a data pipeline involved.
As a result, users get to improve customer segmentation, hone their messaging, and make better marketing decisions without costly and time-consuming data engineering tasks.
Tags: [New Feature](/release-notes?tag=New Feature)
--- START: release-notes/sample-data-sets/sample-data-sets.md ---
[ Back to What's New](/release-notes) September 01, 2023
Sample data sets
================
You can now explore Peaka’s capabilities without connecting your own data.
This feature enables you to work with sample PostgreSQL, Stripe, HubSpot, and Internal Peaka tables data and see the reports and insights Peaka can generate for you _before you even start your project._
Tags: [New Feature](/release-notes?tag=New Feature)
--- START: release-notes/scheduled-triggers/scheduled-triggers.md ---
[ Back to What's New](/release-notes) September 15, 2023
Scheduled triggers
==================
Peaka introduces scheduled triggers, allowing you to set in advance when you want your backend flows to run to complete certain tasks.
This feature helps you automate some of the repetitive tasks so that you can focus on creating actual value for your organization.
Tags: [New Feature](/release-notes?tag=New Feature)
--- START: release-notes/segment-integration/segment-integration.md ---
[ Back to What's New](/release-notes) March 01, 2024
Segment integration
===================
Peaka is officially a Segment destination now. Destinations are platforms, apps, or business tools that you can connect to the data flowing through Segment. Becoming a Segment destination means that Peaka can seamlessly integrate with this popular platform.
This integration allows users to view and query the product event data in Segment from Peaka Studio. Users can even cross-join this data with data from other platforms, such as HubSpot, to gain a more holistic view of their products and how customers interact with them.

Tags: [New Feature](/release-notes?tag=New Feature)
--- START: release-notes/snowflake-integration/snowflake-integration.md ---
[ Back to What's New](/release-notes) April 15, 2024
Snowflake integration
=====================
One of the most popular cloud-based data warehouses, Snowflake is optimized for business intelligence and data analysis use cases, where data is structured and users are proficient in SQL.
Peaka’s Snowflake integration adds another dimension to Snowflake’s data warehouse capability, enabling it to pull in API-based data from SaaS tools. This integration enhances Snowflake's connectivity and allows users to make better use of their scattered data.
Tags: [New Feature](/release-notes?tag=New Feature)
--- START: release-notes/superset-integration/superset-integration.md ---
[ Back to What's New](/release-notes) July 11, 2024
Apache Superset™ integration
============================
Apache Superset™ is an enterprise-grade open-source business intelligence (BI) tool for data exploration, visualization, and analytics. Supporting drag-and-drop functionality and SQL querying, this highly customizable platform is a good data visualization option for organizations with technical teams and resources.
Peaka’s Superset integration further extends this platform by enabling it to pull in data from SaaS tools in addition to the databases and data warehouses it already integrates with. With this integration, users can consolidate their data from different sources, create new data sets, and feed them into Superset for visualization.
Allowing tech-savvy users to make the most of Apache Superset™, Peaka’s new integration makes this impressive platform a bigger part of enterprise tech stacks.
Tags: [New Feature](/release-notes?tag=New Feature)
--- START: release-notes/tableau-integration/tableau-integration.md ---
[ Back to What's New](/release-notes) August 28, 2024
Tableau integration
===================
Considered a gold standard in business intelligence, Tableau is a powerful data visualization tool that fits different use cases and user personas. It is owned by Salesforce, which gives it native connectivity with the plethora of apps within the Salesforce ecosystem.
Tableau comes with a drag-and-drop interface and a wide array of ready-made visualizations, which promote ease of use. However, it also offers high degrees of customizability for users with technical skills. Its data exploration, preparation, and modeling capabilities turn it into an end-to-end solution for data professionals. With its advanced AI features, Tableau enables even users without technical skills to self-serve and draw insights from data.
Peaka’s Tableau integration allows Peaka users to leverage this top-notch tool to view their data. Users can now pull in data from different sources, including various SaaS tools, run join queries on their consolidated data to create new datasets, and then push the results to Tableau to view and share them across their organization.
Tags: [New Feature](/release-notes?tag=New Feature)
--- START: release-notes/turning-rest-api-into-sql-tables/turning-rest-api-into-sql-tables.md ---
[ Back to What's New](/release-notes) October 31, 2023
Turning Rest API into SQL tables
================================
With this feature, you can now pull in data via a specific API, join it with data from other sources, and query any data source with the power and convenience of SQL.
This also works wonders when there is no ready-made Peaka connector for the API you want to use. You can still bring in, query, and filter your data without hassle by utilizing Peaka REST in that case.
Tags: [New Feature](/release-notes?tag=New Feature)
--- START: release-notes/visual-queries/visual-queries.md ---
[ Back to What's New](/release-notes) April 17, 2023
Visual queries without SQL
==========================
Peaka introduces its visual query capability, which eliminates the need for users to know SQL to run queries.
Users can now pick a query from the list, set the type of table they want to use, apply filters, and even choose from popular chart options to visualize their data. All without the need for SQL expertise.
Tags: [New Feature](/release-notes?tag=New Feature)
--- START: release-notes/xero-accounting-connector/xero-accounting-connector.md ---
[ Back to What's New](/release-notes) June 02, 2025
Xero Accounting connector
=========================
Xero Accounting is a cloud-based accounting software platform primarily for small businesses. It is a nimble and capable tool for retailers, home and field service businesses, and self-employed people, without the technical complexity of enterprise-grade products.
In addition to basic bookkeeping, Xero Accounting automates invoicing and bank reconciliation, simplifies payroll management, and streamlines tax compliance, while offering detailed financial reporting.
Peaka’s Xero Accounting connector lends more connectivity to this platform, ensuring that users can join their Xero Accounting data with other data they keep in other sources.
With this connector, users can leverage Peaka to retrieve data from Xero Accounting and join it with data from
* a CRM for customer profitability analysis,
* a payment processing platform to create revenue reports,
* an HRMS for payroll analysis.
Users can then push their consolidated data to a BI tool for real-time financial dashboards.
Tags: [New Feature](/release-notes?tag=New Feature)
--- START: release-notes/zapier-integration/zapier-integration.md ---
[ Back to What's New](/release-notes) February 08, 2024
Zapier integration
==================
This integration combines Zapier’s powerful ‘zaps’ (Zapier’s workflows) with Peaka’s data integration and querying capabilities.
Zapier users can now access and query their data in Peaka. After using Peaka to pull data in from various tools and databases, they can leverage zaps to take predefined actions on their unified data.
Peaka’s Zapier integration offers the best of both worlds, enabling users to run the familiar Zapier workflows on the data they consolidated in Peaka.
Check out the video below for a peek into what this integration makes possible for you:
Tags: [New Feature](/release-notes?tag=New Feature)
--- START: release-notes/zoho-crm-integration/zoho-crm-integration.md ---
[ Back to What's New](/release-notes) November 16, 2023
Zoho CRM integration
====================
If you are among the tens of millions of Zoho CRM customers, you should rejoice: Peaka’s new connector makes accessing and querying your Zoho CRM data a breeze.
With this connector, you can bring in your data from Zoho CRM and then join it with data from other sources to create new data sets. Peaka enables you to use APIs to expose these data sets so that they can be used by other applications and systems.
Tags: [New Feature](/release-notes?tag=New Feature)
--- START: release-notes/zoom-connector/zoom-connector.md ---
[ Back to What's New](/release-notes) September 26, 2024
Zoom connector
==============
Zoom is the leading videoconferencing application in the market, with close to 200,000 enterprise customers as of 2024. The company became a household brand during the coronavirus pandemic as it facilitated online collaboration and remote work for millions of users.
Zoom is used for all kinds of online events, from daily business meetings to webinars, online education, and even doctor consultations. All this activity makes it a significant source of data organizations would like to tap into. Peaka’s Zoom connector lets you access this data and turn it into metrics.
Peaka’s dedicated connector gives users visibility into statistics from all the Zoom meetings held. By aggregating data on the topics of meetings, who attended them, and which meetings specific employees attended and for how long, the Zoom connector enhances performance evaluation for critical functions such as sales, customer support, and customer success.
Tags: [New Feature](/release-notes?tag=New Feature)
--- START: docs/ai-setup/bring-your-own-ai-model/bring-your-own-ai-model.md ---
Documentation menu
[Home](/) / [Docs](/docs/) / Bring your own AI model
 Copy as Markdown
Bring your own AI model
=======================
How to use custom AI models with Peaka
Prerequisites
-------------
Before adding a custom LLM model, make sure you have the following ready:
* **API Key**: The authentication key issued by your LLM provider.
* **Base URL** (if applicable): The endpoint through which requests to the model will be made.
We currently support the following providers:
* **OpenAI** and **Azure OpenAI**
* **Google Gemini**
* **Alibaba Cloud Qwen**
👉 If you’re using another provider, let us know — we can add support for additional LLMs.
Model Roles
-----------
In Peaka, each model you add is assigned a role based on how it will be used. Currently, we support two types of roles:
Role
Purpose
Example Usages
Agent / Chat
Text-to-SQL generation
`Show me the top 10 customers by revenue` → model generates the SQL query.
Embedding / RAG
Retrieval-Augmented Generation (RAG)
Store embeddings of table names & metadata → system retrieves context before SQL.
### How they work together
* **Agent / Chat models** handle natural language to SQL conversion.
* **Embedding / RAG models** enhance accuracy by retrieving the most relevant tables and metadata before query generation.
By combining these roles, Peaka ensures your text-to-SQL agent is both accurate and context-aware.
Adding a Custom Model
---------------------
Follow these steps to add a custom LLM model to Peaka:
1. Navigate to AI Settings
* Go to Organization Settings → AI Settings.
2. Click “Add AI Model”
* Locate and click the Add AI Model button to open the form.
 3. Fill out the Add AI Model Form The form contains the following fields:
* **Gen AI System** – Select the provider (e.g., Google Gemini, OpenAI, Alibaba Cloud Qwen).
* **Model Role** – Choose the role of the model: Agent/Chat or Embedding/RAG.
* **Gen AI Model** – Specify the model name/version to use.
* **Gen AI API Key** – Enter the API key issued by your provider.
* **Gen AI Base URL** – Enter the base URL/endpoint if required by the provider.
 4. Save and Validate
* Click Save.
* Peaka will automatically test your credentials.
* If the credentials are valid, the model will be added and ready to use.
* If invalid, an error message will guide you to correct the information.
After successfully adding the model, it will appear in your list of AI models, ready for use in your projects.
 Configuring Model Usage
-----------------------
Once you’ve added your custom AI models, you can configure Peaka to use them instead of the default models.
1. Configure the Settings Form The form contains the following fields:
**Setting**
**Description**
**Agent/Chat Model**
Select the model to use for chat and text-to-SQL agent features.
**Embedding / RAG Model**
Select the model to use for retrieval-augmented generation and metadata retrieval. **⚠️ Changing this model will trigger reindexing of semantic metadata, which may take some time.**
**AI Response Language**
Set the global language for AI responses across the system.
**Generate Semantics on Each Query Update with AI**
Toggle **On/Off**. When enabled, Peaka will automatically generate semantic metadata whenever a new query is executed.
 2. Save Settings
* Click Save to apply your configuration.
* Peaka will start using your selected AI models according to the roles you’ve assigned.
Monitoring Token Usage of Models
--------------------------------
Peaka allows you to monitor the usage of your AI models, including tokens consumed during operations. Follow these steps to access the monitoring page:
1. Navigate to the AI Page
* Go to Peaka AI in the main navigation.
2. Open the Token Usage Table
* Click the Token Usage button.
 * The LLM Monitoring Table will open, displaying detailed usage information.
3. Understanding the Table Fields
 **Field**
**Description**
**Gen AI System**
The AI system used (e.g., OpenAI, Google Gemini).
**Gen AI Model**
The specific model used for the operation.
**Workflow Name**
The main AI workflow associated with the operation.
**Workflow Path**
The path of the subtask within the AI workflow.
**Token**
Total number of tokens consumed by Peaka for the operation.
**Start Time**
Timestamp when the operation started.
**End Time**
Timestamp when the operation ended.
**Model Used**
Indicates whether the **User Model** or **Peaka Model** was used.
This table helps you track usage, analyze costs, and ensure that your custom models are being utilized as expected.
On this page
* [Prerequisites](https://www.peaka.com/docs/ai-setup/bring-your-own-ai-model/#prerequisites)
* [Model Roles](https://www.peaka.com/docs/ai-setup/bring-your-own-ai-model/#model-roles)
* [How they work together](https://www.peaka.com/docs/ai-setup/bring-your-own-ai-model/#how-they-work-together)
* [Adding a Custom Model](https://www.peaka.com/docs/ai-setup/bring-your-own-ai-model/#adding-a-custom-model)
* [Configuring Model Usage](https://www.peaka.com/docs/ai-setup/bring-your-own-ai-model/#configuring-model-usage)
* [Monitoring Token Usage of Models](https://www.peaka.com/docs/ai-setup/bring-your-own-ai-model/#monitoring-token-usage-of-models)
--- START: docs/bi-tools/looker-studio/looker-studio.md ---
Documentation menu
[Home](/) / [Docs](/docs/) / Looker Studio
 Copy as Markdown
Looker Studio
=============
Learn how you can use Peaka in Looker Studio
### Prerequisites:
* **A Google account**: To access **Looker Studio**, you will need a Google account. If you already have one, you can directly log into Looker Studio. If not, you can create an account in the [Looker Studio](https://lookerstudio.google.com/) page.
* A Peaka account and a Peaka Project.
* An API Key you created in your Peaka Project.
Using Peaka as a Data Source in Looker Studio
---------------------------------------------
1. Prepare your data in [Peaka](https://peaka.studio).
2. Click on the following link to navigate Looker Studio: [https://lookerstudio.google.com](https://lookerstudio.google.com)
3. Click "Create" button on the left side of the page and then click "Data Source"
 4. Search "Peaka" in searchbar and select the "Peaka" connector in "Partner Connectors" list or simply click [this link](https://lookerstudio.google.com/datasources/create?connectorId=AKfycbzAkhGsKvv3xV6qO10BPjS4DCBuCwF6-6cHnOVEONufpGh6LH6mAnTSocuiYV6cpv3j) to add Peaka to Looker Studio as a data source.
 5. To confirm the action, click on the AUTHORIZE button.
 6. Sign in to Looker Studio using your Google account credentials and grant Google access rights by clicking on the ALLOW button.
7. Paste your Peaka Project API Key to the "Key" field in Looker Studio.
 Peaka's Looker Studio connector does not support Partner API Keys. Please make sure you enter an API Key that is created from a specific Peaka Project.
8. Select Data Refresh Rate to define how often Looker Studio fetches fresh data from Peaka.
 9. Select a Catalog.
 10. Select a Schema (if you are working with a Peaka Table, a Peaka Query, or a BI Table, you will proceed to select a Table without being asked to select a Schema).
 11. Select a Table and click on the "Connect" button.
 12. Browse the fields and rename the Data Source if needed.
 13. Add the data source to your report.
You are all set now! You have successfully added Peaka to Looker Studio as a Data Source.
You can now use your queries or tables to create insightful reports in Looker Studio.
On this page
* [Prerequisites:](https://www.peaka.com/docs/bi-tools/looker-studio/#prerequisites)
* [Using Peaka as a Data Source in Looker Studio](https://www.peaka.com/docs/bi-tools/looker-studio/#using-peaka-as-a-data-source-in-looker-studio)
--- START: docs/bi-tools/metabase/metabase.md ---
Documentation menu
[Home](/) / [Docs](/docs/) / Metabase
 Copy as Markdown
Metabase
========
Peaka and Metabase integration brings together the power of Peaka's data platform with the visualization capabilities of Metabase's business intelligence platform. With this integration, customers can leverage Peaka's robust data processing and management capabilities to feed into Metabase’s intuitive and interactive dashboards. This allows users to create compelling analytics dashboards that provide meaningful insights into their data.
Metabase has both hosted service and on-premise offerings. We will walkthrough setup process for the both version.
Metabase Cloud Setup
--------------------
You need 2 steps to complete Metabase Cloud setup:
* Generate Peaka API Key
* Setup Peaka Integration with Starburst Connector
### Generate Peaka API Key
After you create your project, setup connections and create your catalogs in Peaka, you need to generate a Peaka API Key to use it with Metabase Connector. Check out Peaka Documentation on [how to create API Keys](/docs/cookbook/how-to-generate-api-keys) for detailed instructions.
### Setup Peaka Integration with Startburst Connector
The Peaka Metabase integration uses the Starburst Connector right now. Startburst Connector is offical partner driver which is provided in Metabase Cloud offering.
* In order to add Peaka as data source, go to your Metabase Home page. Click settings icon on the top right corner of the screen and click _Admin Settings_ button as shown in the screenshot below.
 * On the next screen click Databases from the top toolbar.
 * On the next screen click Add database button.
 * Add database form will open and you need to add your connection details on this screen. Select Starbust for Database Type. Then give a name to your database connection. For the host name enter `dbc.peaka.studio`. For the port enter `4567`. As for the Catalog Name and Schema Name enter the catalog name and schema name of your Peaka Catalog. Then enter trino to the User name field and select Use Secure Connection checkbox. Your form should look like the screenshot below after you enter correct values:
**Note:** If you are using Peaka in EU, you need to use `dbc.eu.peaka.studio` instead of `dbc.peaka.studio` for the host name.
 * Scroll down to bottom and click Show advanced options button. Check Optimize prepared statements checkbox. Enter your Peaka API Key to Additional JDBC connection string options in the following format extraCredentials=peakaKey:``. After that check Rerun queries for simple explorations and Periodically refingerprint tables check boxes. Your form should look like the screenshot below after you enter correct values:
 * If everything is entered correctly you should be able to see Peaka under databases list like the screenshot below.
 * Go to Metabase Home page and click Browse Data button from the toolbar from the left and select your Peaka connection. You should be able to see your tables here. In our case we are seeing tables under catalog stripe and schema name payment.
 Click the table you want to see data and if you can see the data successfully like the screenshot below, you have successfully completed Peaka connection to your Metabase cloud account.
 Metabase On-Premise Setup
-------------------------
If you are using Metabase On-Prem or Open Source Edition, follow these steps to install the Starburst driver:
1. Download the latest release of the [Peaka Driver .jar file.](https://github.com/peakacom/metabase-driver/releases)
2. Copy the JAR file into the `/plugins/` directory of your Metabase installation. If you aren’t sure where to find the plugins directory, review the [Metabase driver installation guide](https://www.metabase.com/docs/latest/developers-guide-drivers.html#how-to-use-a-third-party-driver)
3. Restart Metabase.
4. After here follow the same steps as explained in the Metabase Cloud Setup part of this documentation. Only change is Peaka Connector requires different connection parameters than the Startburst. When you enter the Add Database form you will need to. Select Peaka for Database Type. Then give a name to your database connection. For the host name enter `_dbc.peaka.studio._` For the port enter `_4567._` As for the Catalog Name and Schema Name enter the catalog name and schema name of your Peaka Catalog. Your form should look like the screenshot below after you enter correct values:
**Note:** If you are using Peaka in EU, you need to use `_dbc.eu.peaka.studio._` instead of `_dbc.peaka.studio._` for the host name.
 Then click Save button and follow the same steps as explained in Metabase Cloud Setup Documentation.
Testing Metabase Integration Locally Using Docker Compose
---------------------------------------------------------
If you wish to test our Metabase integration from your local environment, we've created a Docker compose file for your convenience.
Follow these steps:
1. Download the latest zip file from the provided link:
* [Metabase Docker Compose File](https://drive.google.com/drive/folders/1SXKT3hzgScO0SW9AH_MmWhSAYQsGtG3G?usp=drive_link)
2. Unzip the file.
3. Run the 'docker compose up' command.
After running the command, two folders named 'database' and 'metabase-data' will be created. As long as these folders are not deleted, the data will not be lost. This allows you to easily manage and test the integration on your local machine.
On this page
* [Metabase Cloud Setup](https://www.peaka.com/docs/bi-tools/metabase/#metabase-cloud-setup)
* [Generate Peaka API Key](https://www.peaka.com/docs/bi-tools/metabase/#generate-peaka-api-key)
* [Setup Peaka Integration with Startburst Connector](https://www.peaka.com/docs/bi-tools/metabase/#setup-peaka-integration-with-startburst-connector)
* [Metabase On-Premise Setup](https://www.peaka.com/docs/bi-tools/metabase/#metabase-on-premise-setup)
* [Testing Metabase Integration Locally Using Docker Compose](https://www.peaka.com/docs/bi-tools/metabase/#testing-metabase-integration-locally-using-docker-compose)
--- START: docs/bi-tools/superset/superset.md ---
Documentation menu
[Home](/) / [Docs](/docs/) / Superset
 Copy as Markdown
Superset
========
Welcome to the installation guide for integrating Apache Superset with Peaka. As a leading data platform, Peaka provides seamless integration with various business intelligence and data visualization platforms, including Apache Superset. This document will guide you through the step-by-step process to set up this integration, enabling you to unlock the full potential of your data. Please follow each step carefully to ensure a successful setup.
You need 2 steps to complete setup:
* Generate Peaka API Key
* Add Peaka as Database Connection
Generate API Key
----------------
After you create your project, setup connections and create your catalogs in Peaka, you need to generate a Peaka API Key to use it with Superset. Check out Peaka Documentation on [how to create API Keys](/docs/cookbook/how-to-generate-api-keys) for detailed instructions.
Add Peaka as Database Connection
--------------------------------
* Adding Peaka as Database Connection to Superset is so easy. In your main dashboard in Superset, click Setting and then click Database Connections. Then in the next screen click Database button on the top right corner of your screen.
 * Connect a database window will open. In supported databases select Trino.
 * In the next screen you need to enter Display Name and SQL Alchemy URI. You can enter anything you like for the Display Name.The SQL Alchemy URI format is like below:
**Note:** If you are using Peaka in EU, you need to use `trino://dbc.eu.peaka.studio:4567` instead of `trino://dbc.peaka.studio:4567`.
`trino://dbc.peaka.studio:4567//?http_scheme=https&extra_credential=[["peakaKey",""]]&access_token=true`
You need to fill ``, `` and ``. For example if I want to see work on the tables under stripe catalog and payment schema created in Peaka with API Key `abc` , then my SQL Alchemy URI would look like below:
`trino://dbc.peaka.studio:4567/stripe/payment?http_scheme=https&extra_credential=[["peakaKey","abc"]]&access_token=true`
Then click `Test Connection` button to test the connection and if the connection is ok, then click `Connect` button.
 Installation is complete you should be able to see Peaka in Database Connections List. You can start using Peaka with Superset.
 On this page
* [Generate API Key](https://www.peaka.com/docs/bi-tools/superset/#generate-api-key)
* [Add Peaka as Database Connection](https://www.peaka.com/docs/bi-tools/superset/#add-peaka-as-database-connection)
--- START: docs/bi-tools/tableau/tableau.md ---
Documentation menu
[Home](/) / [Docs](/docs/) / Tableau
 Copy as Markdown
Tableau
=======
Welcome to the installation guide for integrating Tableau with Peaka. As a leading data platform, Peaka provides seamless integration with various business intelligence and data visualization platforms, including Tableau. This document will guide you through the step-by-step process to set up this integration, enabling you to unlock the full potential of your data. Please follow each step carefully to ensure a successful setup.
Peaka Tableau Connector allows you integrate Peaka with Tableu for seamless data connection. It's an essential tool for data analysts and scientists to enhance their data visualization capabilities using Tableau. The installation process is straightforward, but this guide will walk you through each step to ensure a successful setup.
You need 4 steps to complete setup:
- Generate Peaka API Key
- Install Peaka Tableau Taco File
- Install Trino JDBC Driver
- Configure Tableau Start Script
Generate API Key
----------------
After you create your project, setup connections and create your catalogs in Peaka, you need to generate a Peaka API Key to use it with Tableu Connector. Check out Peaka Documentation on [how to create API Keys](/docs/cookbook/how-to-generate-api-keys) for detailed instructions.
Install Peaka Tableau Taco File
-------------------------------
A TACO file (.taco) is a packaged Tableau connector file that can be placed in your “My Tableau Repository/Connectors” folder. From there, Tableau automatically loads all connectors it finds.
You need to do following steps to install Peaka Taco File:
* Download the Peaka Taco file by clicking the link below:
* [PeakaStudioJDBC-v1.0.0.tacov](https://cdn.peaka.com/files/PeakaStudioJDBC-v1.0.0.taco)
Place the .taco file in the following directory (default location):
For 2021.2 and newer:
For Tableau Desktop
**For Tableau Prep Builder**
For Tableau Server, Tableau Prep Conductor, Tableau Prep Flow Authoring
• Windows - C:\\Users\[Windows User\]\\Documents\\My Tableau Repository\\Connectors
• Windows: C:\\Users\[Windows User\]\\Documents\\My Tableau Prep Repository\\Connectors
• Windows: C:\\Program Files\\Tableau\\Connectors
• macOS - /Users/\[user\]/Documents/My Tableau Repository/Connectors
• MacOS: /Users//Documents/My Tableau Prep Repository/Connectors
• Linux: /opt/tableau/connectors
For 2021.1 and older:
For Tableau Desktop
**For Tableau Prep Builder**
For Tableau Server, Tableau Prep Conductor, Tableau Prep Flow Authoring
• Windows - C:\\Users\[Windows User\]\\Documents\\My Tableau Repository\\Connectors
• Windows: C:\\Users\[Windows User\]\\Documents\\My Tableau Prep Repository\\Connectors
• Tableau Server: \[Tableau\_Server\_Installation\_Directory\]/data/tabsvc/vizqlserver/Connectors
• macOS - /Users/\[user\]/Documents/My Tableau Repository/Connectors
• MacOS: /Users//Documents/My Tableau Prep Repository/ConnectorsFor Tableau
• To enable your connector for Prep, you also need to add your taco to the following locations:
Tableau Prep Conductor: \[Tableau\_Server\_Installation\_Directory\]/data/tabsvc/flowprocessor/Connectors
Tableau Prep Flow Authoring: \[Tableau\_Server\_Installation\_Directory\]/data/tabsvc/flowqueryservice/Connectors
## Install Trino JDBC Driver
Peaka connector requires Trino JDBC driver to be installed. You can install Trino JDBC Driver by clicking [here](https://trino.io/docs/current/client/jdbc.html).
In the Trino page, you can download the the driver by clicking link highlighted in the image below:

JDBC drivers are self-contained .jar files. Place the Trino JDBC Driver in the folder for your operating system. (You need to create the folder if it doesn't already exist.)
* Windows: C:\\Program Files\\Tableau\\Drivers
* Mac: ~/Library/Tableau/Drivers
* Linux: /opt/tableau/tableau\_driver/jdbc
💡 You must have read permissions on the .jar file.
Configure Tableau Start Script
------------------------------
Tableau requires taco file to be signed. Currently, Peaka Connector taco file is not signed by a certificate authority. We are working on it. However you can still use Peaka Connector by passing a parameter to Tableau executable. Follow these steps to run Peaka Connector:
### For Mac:
Open terminal and create a **tableau.sh** file with this command:
mkdir tableau.sh
Open **tableau.sh** file with a text editor and copy the code below:
#!/bin/bash
"/Applications/Tableau Desktop .app/Contents/MacOS/Tableau" -DDisableVerifyConnectorPluginSignature=true
Change < Tableau Version > with the version of the Tableau you are using. Save and close the file. Make the **tableu.sh** executable by running this command:
chmod +x
Now you should be able to run [tableau.sh](http://tableau.sh) script and start Tableau Desktop by running the command below:
sh tableau.sh
### For Windows:
Open command line and run the command below change < ableau Version > with your tableau version:
C:\Program Files\Tableau\Tableau \bin\tableau.exe -DDisableVerifyConnectorPluginSignature=true
How to use Peaka Connector
--------------------------
After completing all the steps, you should be able to see Peaka Connector listed in Tableau Desktop. Click to Peaka Studio by Peaka connector from the connector list.

Enter your Peaka API Key to the opened window.

In the next screen you can see your tables by selecting catalog and schema.

On this page
* [Generate API Key](https://www.peaka.com/docs/bi-tools/tableau/#generate-api-key)
* [Install Peaka Tableau Taco File](https://www.peaka.com/docs/bi-tools/tableau/#install-peaka-tableau-taco-file)
* [Configure Tableau Start Script](https://www.peaka.com/docs/bi-tools/tableau/#configure-tableau-start-script)
* [For Mac:](https://www.peaka.com/docs/bi-tools/tableau/#for-mac)
* [How to use Peaka Connector](https://www.peaka.com/docs/bi-tools/tableau/#how-to-use-peaka-connector)
--- START: docs/bi-tools/tableau-web-data/tableau-web-data.md ---
Documentation menu
[Home](/) / [Docs](/docs/) / Tableau Web Data Connector
 Copy as Markdown
Tableau Web Data Connector
==========================
Welcome to the installation guide for integrating Tableau Web Data Connector with Peaka. As a leading data platform, Peaka provides seamless integration with various business intelligence and data visualization platforms, including Tableau Web Data Connector. This document will guide you through the step-by-step process to set up this integration, enabling you to unlock the full potential of your data. Please follow each step carefully to ensure a successful setup.
Peaka Tableau Web Data Connector allows you integrate Peaka with Tableu for seamless data connection. It's an essential tool for data analysts and scientists to enhance their data visualization capabilities using Tableau. The installation process is straightforward, but this guide will walk you through each step to ensure a successful setup.
You need 3 steps to complete setup:
- Generate Peaka API Key
- Install Peaka Tableau Taco File
- Configure Tableau Start Script
Generate API Key
----------------
After you create your project, setup connections and create your catalogs in Peaka, you need to generate a Peaka API Key to use it with Tableu Connector. Check out Peaka Documentation on [how to create API Keys](/docs/cookbook/how-to-generate-api-keys) for detailed instructions.
Install Peaka Tableau Taco File
-------------------------------
A TACO file (.taco) is a packaged Tableau connector file that can be placed in your “My Tableau Repository/Connectors” folder. From there, Tableau automatically loads all connectors it finds.
You need to do following steps to install Peaka Taco File:
Download the Peaka Taco file by clicking the link below:
* [PeakaWebDataConnector-1.0.0.taco](https://cdn.peaka.com/files/PeakaWebDataConnector-1.0.0.taco)
For 2021.2 and newer:
For Tableau Desktop
**For Tableau Prep Builder**
For Tableau Server, Tableau Prep Conductor, Tableau Prep Flow Authoring
• Windows - C:\\Users\[Windows User\]\\Documents\\My Tableau Repository\\Connectors
• Windows: C:\\Users\[Windows User\]\\Documents\\My Tableau Prep Repository\\Connectors
• Windows: C:\\Program Files\\Tableau\\Connectors
• macOS - /Users/\[user\]/Documents/My Tableau Repository/Connectors
• MacOS: /Users//Documents/My Tableau Prep Repository/Connectors
• Linux: /opt/tableau/connectors
For 2021.1 and older:
For Tableau Desktop
**For Tableau Prep Builder**
For Tableau Server, Tableau Prep Conductor, Tableau Prep Flow Authoring
• Windows - C:\\Users\[Windows User\]\\Documents\\My Tableau Repository\\Connectors
• Windows: C:\\Users\[Windows User\]\\Documents\\My Tableau Prep Repository\\Connectors
• Tableau Server: \[Tableau\_Server\_Installation\_Directory\]/data/tabsvc/vizqlserver/Connectors
• macOS - /Users/\[user\]/Documents/My Tableau Repository/Connectors
• MacOS: /Users//Documents/My Tableau Prep Repository/ConnectorsFor Tableau
To enable your connector for Prep, you also need to add your taco to the following locations:
Tableau Prep Conductor: \[Tableau\_Server\_Installation\_Directory\]/data/tabsvc/flowprocessor/Connectors
Tableau Prep Flow Authoring: \[Tableau\_Server\_Installation\_Directory\]/data/tabsvc/flowqueryservice/Connectors
Configure Tableau Start Script
------------------------------
Tableau requires taco file to be signed. Currently, Peaka Connector taco file is not signed by a certificate authority. We are working on it. However you can still use Peaka Connector by passing a parameter to Tableau executable. Follow these steps to run Peaka Connector:
### For Mac:
Open terminal and create a **tableau.sh** file with this command:
mkdir tableau.sh
Open **tableau.sh** file with a text editor and copy the code below:
#!/bin/bash
"/Applications/Tableau Desktop < Tableau Version >.app/Contents/MacOS/Tableau" -DDisableVerifyConnectorPluginSignature=true
Change < Tableau Version > with the version of the Tableau you are using. Save and close the file. Make the **tableau.sh** executable by running this command:
chmod +x
Now you should be able to run [tableau.sh](http://tableau.sh) script and start Tableau Desktop by running the command below:
sh tableau.sh
### For Windows:
Open command line and run the command below change < Tableau Version > with your tableau version:
C:\Program Files\Tableau\Tableau < Tableau Version >\bin\tableau.exe -DDisableVerifyConnectorPluginSignature=true
How to use Peaka Connector
--------------------------
After completing all the steps, you should be able to see Peaka Web Data Connector listed in Tableau Desktop. Click to Peaka Web Data Connector by Peaka connector from the connector list.
Enter your Peaka API Key to the opened window and click Authorize.
In the next screen you need to select tables to be exported from the list on the left side. Selected tables are on the right side of the screen. Once you select all the tables click Next to continue.
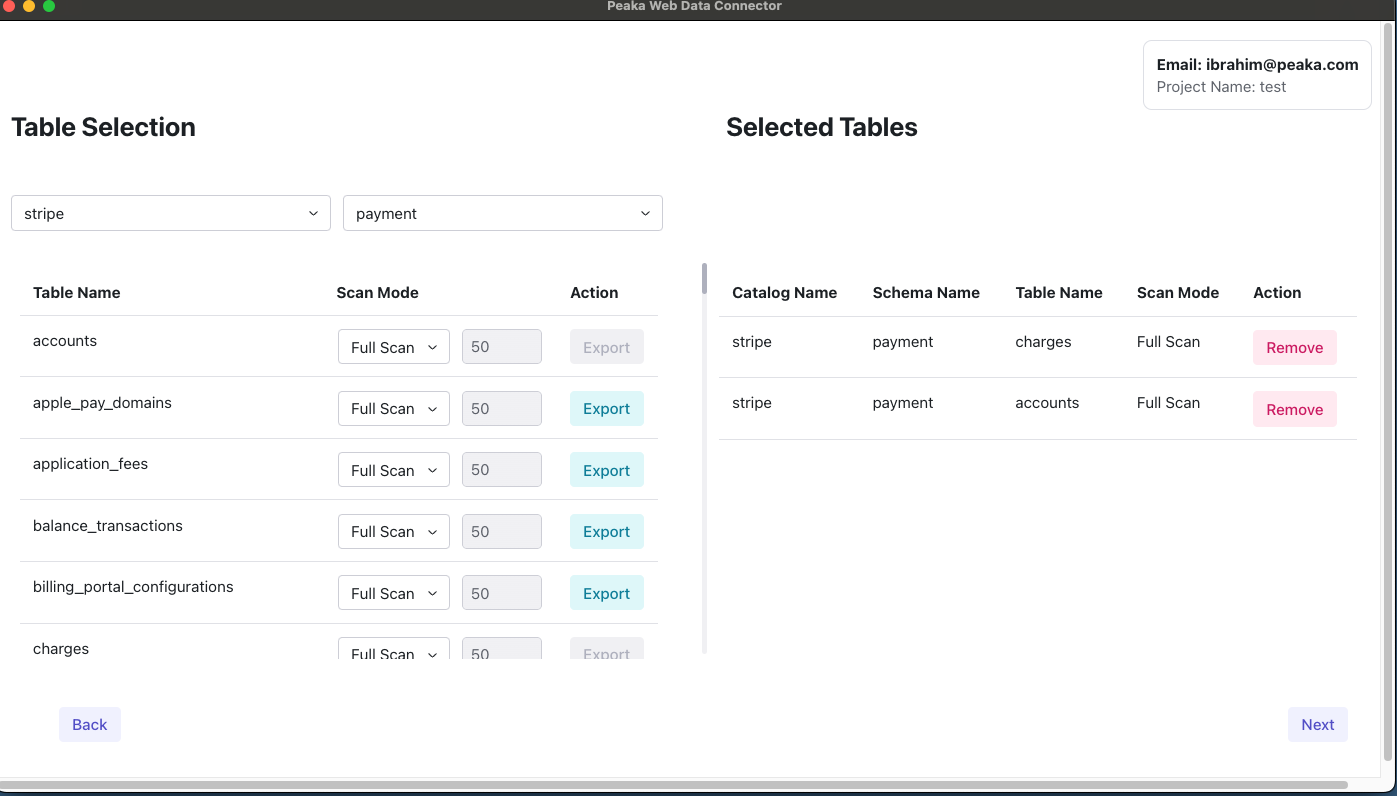
In the last screen you will see the summary of the tables you want to export. If you are ok with the results click Finish and complete the setup.
After the export process is finished, you should be able to see your tables inside Tableau.
On this page
* [Generate API Key](https://www.peaka.com/docs/bi-tools/tableau-web-data/#generate-api-key)
* [Install Peaka Tableau Taco File](https://www.peaka.com/docs/bi-tools/tableau-web-data/#install-peaka-tableau-taco-file)
* [Configure Tableau Start Script](https://www.peaka.com/docs/bi-tools/tableau-web-data/#configure-tableau-start-script)
* [For Mac:](https://www.peaka.com/docs/bi-tools/tableau-web-data/#for-mac)
* [For Windows:](https://www.peaka.com/docs/bi-tools/tableau-web-data/#for-windows)
* [How to use Peaka Connector](https://www.peaka.com/docs/bi-tools/tableau-web-data/#how-to-use-peaka-connector)
--- START: docs/bi-tools/preset/preset.md ---
Documentation menu
[Home](/) / [Docs](/docs/) / Preset
 Copy as Markdown
Preset
======
Welcome to the installation guide for integrating Apache Preset with Peaka. As a leading data platform, Peaka provides seamless integration with various business intelligence and data visualization platforms, including Apache Preset. This document will guide you through the step-by-step process to set up this integration, enabling you to unlock the full potential of your data. Please follow each step carefully to ensure a successful setup.
You need 2 steps to complete setup:
* Generate Peaka API Key
* Add Peaka as Database Connection
Generate API Key
----------------
After you create your project, setup connections and create your catalogs in Peaka, you need to generate a Peaka API Key to use it with Preset. Check out Peaka Documentation on [how to create API Keys](/docs/cookbook/how-to-generate-api-keys) for detailed instructions.
Add Peaka as Database Connection
--------------------------------
* Adding Peaka as Database Connection to Preset is so easy. In your main dashboard in Preset, click Setting and then click Database Connections. Then in the next screen click Database button on the top right corner of your screen.

 * Connect a database window will open. In supported databases select Trino.
 * In the next screen you need to enter Display Name and SQL Alchemy URI. You can enter anything you like for the Display Name.The SQL Alchemy URI format is like below:
**Note:** If you are using Peaka in EU, you need to use `trino://dbc.eu.peaka.studio:4567` instead of `trino://dbc.peaka.studio:4567`.
`trino://dbc.peaka.studio:4567//?http_scheme=https&extra_credential=[["peakaKey",""]]&access_token=true`
You need to fill ``, `` and ``. For example if I want to see work on the tables under stripe catalog and payment schema created in Peaka with API Key `abc` , then my SQL Alchemy URI would look like below:
`trino://dbc.peaka.studio:4567/stripe/payment?http_scheme=https&extra_credential=[["peakaKey","abc"]]&access_token=true`
Then click `Test Connection` button to test the connection and if the connection is ok, then click `Connect` button.
 * Installation is complete you should be able to see Peaka in Database Connections List. You can start using Peaka with Preset.
 On this page
* [Generate API Key](https://www.peaka.com/docs/bi-tools/preset/#generate-api-key)
* [Add Peaka as Database Connection](https://www.peaka.com/docs/bi-tools/preset/#add-peaka-as-database-connection)
--- START: docs/connecting-your-data/add-connection/add-connection.md ---
Documentation menu
[Home](/) / [Docs](/docs/) / Connecting data using a SaaS connector
 Copy as Markdown
Connecting data using a SaaS connector
======================================
Learn how you can connect your data using a SaaS connector
This guide will demonstrate how to add a SaaS Connector in Peaka, using the Peaka HubSpot Connector as an example. SaaS Connectors enable you to seamlessly integrate and access data from various external sources within your Peaka project.
Step-by-Step Guide
------------------
1. **Switch to the 'Data Model' mode**: Ensure that you are in the '**Data Model**' mode. If you're not already in this mode, use the switch button located at the top of the page to select it.
2. **Access the SaaS Connector Setup**: In the '**Data Model**' screen, you will see a set of buttons, as shown in the image below. Click on one of these buttons to access the SaaS Connector Setup.
3. **Choose the connector**: Choose the connector you want to connect.
There is technical documentation in Peaka Docs for each integration. You can find the documentation of the integration which you want to connect
* [Integrations](/docs/integrations).
On this page
* [Step-by-Step Guide](https://www.peaka.com/docs/connecting-your-data/add-connection/#step-by-step-guide)
--- START: docs/connecting-your-data/creating-peaka-table/creating-peaka-table.md ---
Documentation menu
[Home](/) / [Docs](/docs/) / Creating a Peaka Table
 Copy as Markdown
Creating a Peaka Table
======================
Learn how you can create your first internal table in Peaka
This guide will walk you through the process of creating your first internal table in Peaka. Internal tables are a fundamental way of storing and managing data within your Peaka project.
Step-by-Step Guide
------------------
Follow these steps to create a Peaka Table:
1. **Switch to the 'Data Model' mode**: Start by ensuring that you are in the '**Data Model**' mode. If you're not already in this mode, use the switch button located at the top of the page to select it.

2. **Access the 'Create Table' menu**: Once in '**Data Model**' mode, you'll see a set of buttons, as shown in the image below. Click on one of these buttons to access the '**Create Table**' menu.
3. **Define the table details**: A popup will appear with options for defining your internal table. Provide a name for your table in the provided field. This name should clearly indicate the purpose or content of the table.
Congratulations!
----------------
You have successfully created your first internal table in Peaka. This table serves as a vital component for storing and managing data within your project.
You can now proceed to populate the table with data, define its structure, and perform various data operations to meet your project's needs.
On this page
* [Step-by-Step Guide](https://www.peaka.com/docs/connecting-your-data/creating-peaka-table/#step-by-step-guide)
* [Congratulations!](https://www.peaka.com/docs/connecting-your-data/creating-peaka-table/#congratulations)
--- START: docs/connecting-your-data/creating-query/creating-query.md ---
Documentation menu
[Home](/) / [Docs](/docs/) / Creating a Peaka Query
 Copy as Markdown
Creating a Peaka Query
======================
Learn how you can create your first query in Peaka
This guide will walk you through the process of creating your first query in Peaka. Peaka Queries are a powerful way to filter, manipulate, and analyze data within your Peaka project.
Step-by-Step Guide
------------------
Follow these steps to create a Peaka Query:
1. **Switch to the 'Data Model' mode**: Begin by ensuring that you are in the '**Data Model**' mode. If you're not already in this mode, use the switch button located at the top of the page to select it.

2. **Access the 'Write your Query' menu**: Once you are in the '**Data Model**' mode, you will see a set of buttons, as shown in the image below. Click on one of these buttons to access the '**Create Query**' menu.

3. **Create Your Peaka Query**: Choose whether to create a query from scratch or start with a template.

* **Create Your Query From Scratch**
a. **Create a query**: Click on the '**Create Your Query from Scratch**' button.
b. **Define the query details**: A popup will appear with options for defining your query. Provide a meaningful name for your query in the provided field. This name should clearly indicate the purpose or content of the query.

* **Import a Query Template**
a. **Create a query**: Click on the '**Import a Query Template**' button.
b. **Select a template**: A popup will appear, presenting you with a variety of predefined templates to choose from. Select the one that best fits your needs to streamline your query creation process.

c. **Customize the template**: After selecting a template, you can adjust it to meet your specific requirements. Modify the fields and parameters as needed to align with your data needs and objectives.

d. **View the query**: Click the '**View Query**' button to see the created query.

Congratulations!
----------------
You have successfully created your first query in Peaka.

Peaka Queries are a versatile tool that allows you to filter, manipulate, and analyze data from various sources within your project.
You can now proceed to define the query criteria, apply data transformations, and use it in your project components to access the data you need.
On this page
* [Step-by-Step Guide](https://www.peaka.com/docs/connecting-your-data/creating-query/#step-by-step-guide)
* [Congratulations!](https://www.peaka.com/docs/connecting-your-data/creating-query/#congratulations)
--- START: docs/connecting-your-data/differences-of-peaka-table-and-peaka-bi-table/differences-of-peaka-table-and-peaka-bi-table.md ---
Documentation menu
[Home](/) / [Docs](/docs/) / Differences of Peaka Table and Peaka BI Table
 Copy as Markdown
Differences of Peaka Table and Peaka BI Table
=============================================
Learn about the differences between Peaka Table and Peaka BI Table
Peaka Table and Peaka BI Table serve different purposes, tailored to distinct data management needs. In this article, we will delve into the key differences between these two offerings, helping you choose the right one for your specific requirements.
Peaka BI Table: Handling Large Datasets
---------------------------------------
Peaka BI Table is primarily designed for efficiently managing vast datasets, with a focus on high-speed data filtering. It is particularly well-suited for situations where rapid data retrieval is essential. However, it is not the ideal choice for extensive data editing, as editing operations can be relatively slow within Peaka BI Table.
**Common Uses of Peaka BI Table:**
* Uploading and filtering substantial datasets.
Peaka Table: Suited for Small Data Management
---------------------------------------------
Peaka Table, on the other hand, excels in tasks involving smaller datasets. It offers capabilities for inserting, editing, deleting, and filtering data, making it ideal for precise data manipulation. If you have a substantial dataset and intend to use Peaka Table, be prepared for potentially longer processing times.
**Common Uses of Peaka Table:**
* Managing and editing smaller datasets, such as customer information and financial data.
**Data Type Considerations:**
* It's worth noting that Peaka BI Table does not support certain data types, such as JSON. In contrast, Peaka Table is more versatile in this regard, accommodating a wider range of data types.
Conclusion
----------
Peaka Table and Peaka BI Table cater to distinct data management needs. To make the right choice, consider the size of your dataset and your specific data type requirements. Peaka BI Table excels in handling large datasets swiftly, while Peaka Table is best suited for managing, editing, and manipulating smaller datasets with diverse data types.
You can observe variations in query times as the dataset size increases, as depicted in the chart below (note that the values shown are for illustration purposes and not actual data). The blue line in the graphic represents Peaka Table, while the green line corresponds to Peaka BI Table.

On this page
* [Peaka BI Table: Handling Large Datasets](https://www.peaka.com/docs/connecting-your-data/differences-of-peaka-table-and-peaka-bi-table/#peaka-bi-table-handling-large-datasets)
* [Peaka Table: Suited for Small Data Management](https://www.peaka.com/docs/connecting-your-data/differences-of-peaka-table-and-peaka-bi-table/#peaka-table-suited-for-small-data-management)
* [Conclusion](https://www.peaka.com/docs/connecting-your-data/differences-of-peaka-table-and-peaka-bi-table/#conclusion)
--- START: docs/connecting-your-data/peaka-bi-table/peaka-bi-table.md ---
Documentation menu
[Home](/) / [Docs](/docs/) / What is a Peaka BI Table?
 Copy as Markdown
What is a Peaka BI Table?
=========================
Learn about Peaka BI Table and how you can use it to manage your data
Peaka BI Table is a robust solution for managing large datasets, designed to handle data-intensive tasks with ease. In this guide, we will delve into what Peaka BI Table is and how it can empower you to effectively manage your big data.
Peaka BI Table employs a column-oriented data storage approach, resulting in exceptionally fast filtering and grouping performance for large datasets. Notably, this approach eliminates the need for additional indexing, further enhancing its efficiency.
When to Use Peaka BI Table
--------------------------
It's important to choose the right tool for the job. Peaka BI Table excels in handling vast datasets, typically comprising over one million records. If your dataset is small or moderate in size, there may be more suitable alternatives like [Peaka Table](/docs/connecting-your-data/peaka-table/), as Peaka BI Table's performance advantages become most apparent when managing substantial amounts of data.
Understanding Peaka Tables
--------------------------
* **Structured data storage** : Peaka BI Tables empower you to store data in a structured tabular format, though it's important to note that certain data types, such as JSON, are not supported. Should you require compatibility with these data types, Peaka Table is the recommended choice. This structured approach streamlines data management and organization, enhancing your information's accessibility and structure.
* **Data manipulation**: One of the features of Peaka BI Table is its in data management, allowing you to execute operations like row-by-row updates, deletions, and insertions, thereby affording you level of control. However, if your needs involve frequent and extensive data manipulation, we recommend considering Peaka Table for an optimized experience. It is ideal for the storage of event data, particularly excelling when handling bulk data insertion from various sources. Furthermore, its column-oriented data storage structure enhances the efficiency of data querying, making it exceptionally fast for filtering and aggregation operations on large datasets
* **Integration and connectivity**: Peaka BI Tables seamlessly integrate with other components of your project. You can connect to the data stored in Peaka BI Tables, use table components to display it on your project pages, and employ flow actions to make data changes.
When dealing with substantial datasets, Peaka BI Table emerges as a reliable and efficient choice for your data management needs. Its capacity to handle vast amounts of data and offer granular control over operations makes it a valuable tool for businesses and organizations with substantial data requirements.
On this page
* [When to Use Peaka BI Table](https://www.peaka.com/docs/connecting-your-data/peaka-bi-table/#when-to-use-peaka-bi-table)
* [Understanding Peaka Tables](https://www.peaka.com/docs/connecting-your-data/peaka-bi-table/#understanding-peaka-tables)
--- START: docs/connecting-your-data/peaka-query/peaka-query.md ---
Documentation menu
[Home](/) / [Docs](/docs/) / What is a Peaka Query?
 Copy as Markdown
What is a Peaka Query?
======================
Learn about Peaka Queries and how you can harness their power
Peaka Queries are a versatile tool that allows users to filter and manipulate data in Peaka Tables. They enable you to combine data from your internal tables with other queries and connected data sources, unlocking powerful data management and analysis capabilities.
Key Features of Peaka Queries
-----------------------------
Peaka Queries offer the following key features:
### 1\. Data Filtering and Combinations
* **Data Filtering**: Peaka Queries provide an SQL-like interface that enables you to filter data within your Peaka Tables. You can specify conditions to extract only the data that meets specific criteria.
* **Data Combinations**: These queries allow you to combine data from different Peaka Tables and other connected data sources. This capability enhances your ability to correlate and analyze information from various parts of your project.
### 2\. Query Modes
Peaka Queries offer multiple query modes, catering to different user preferences and expertise levels:
### Visual Mode

### AI | GPT Mode

### SQL Mode

### Modifying the SQL Mode

Getting Started with Peaka Queries
----------------------------------
To harness the power of Peaka Queries, you can follow these steps:
1. **Creating a Peaka Query**: Begin by creating a Peaka Query within your project. Depending on your familiarity with SQL and your preferences, choose the query mode that suits you best.
* **Visual Mode**: This mode offers a user-friendly visual interface for creating queries.
* **AI | GPT Mode**: Leveraging AI, this mode assists in generating queries based on natural language input.
* **SQL Mode**: Experienced users can directly write SQL queries in this mode for fine-grained control over data manipulation.
* **Modifying the SQL Mode**: In this mode, you can customize SQL queries generated by AI | GPT Mode to meet specific requirements.
2. **Executing Queries**: Execute your Peaka Queries to filter and combine data as needed. You can use these queries in various project components to access the data you require.
Peaka Queries offer a powerful way to interact with your data, making it easier to extract meaningful insights and drive informed decisions within your Peaka projects.
For more details on creating a Peaka Query, please check out the [Creating a Peaka Query](/docs/connecting-your-data/creating-query) link.
On this page
* [Key Features of Peaka Queries](https://www.peaka.com/docs/connecting-your-data/peaka-query/#key-features-of-peaka-queries)
* [1\. Data Filtering and Combinations](https://www.peaka.com/docs/connecting-your-data/peaka-query/#1-data-filtering-and-combinations)
* [2\. Query Modes](https://www.peaka.com/docs/connecting-your-data/peaka-query/#2-query-modes)
* [Visual Mode](https://www.peaka.com/docs/connecting-your-data/peaka-query/#visual-mode)
* [AI | GPT Mode](https://www.peaka.com/docs/connecting-your-data/peaka-query/#ai-gpt-mode)
* [SQL Mode](https://www.peaka.com/docs/connecting-your-data/peaka-query/#sql-mode)
* [Modifying the SQL Mode](https://www.peaka.com/docs/connecting-your-data/peaka-query/#modifying-the-sql-mode)
* [Getting Started with Peaka Queries](https://www.peaka.com/docs/connecting-your-data/peaka-query/#getting-started-with-peaka-queries)
--- START: docs/connecting-your-data/peaka-table/peaka-table.md ---
Documentation menu
[Home](/) / [Docs](/docs/) / What is a Peaka Table?
 Copy as Markdown
What is a Peaka Table?
======================
Learn about Peaka Tables and how you can use them to manage your data
Peaka Tables are a fundamental feature within Peaka, serving as internal relational databases designed to help you efficiently organize and manage your data.
In this guide, we'll explore the key aspects of Peaka Tables and how they allow you to store, access, and manipulate your data effectively.
Understanding Peaka Tables
--------------------------
* **Structured data storage**: Peaka Tables enable you to store your data in a structured tabular format. This structured approach makes it easy to manage and organize your information.
* **Data manipulation**: You can easily add, delete, filter, and edit your data within Peaka Tables. This flexibility ensures that you have full control over the information you store.
* **Integration and connectivity**: Peaka Tables seamlessly integrate with other components of your project. You can connect to the data stored in Peaka Tables, use table components to display it on your project pages, and employ flow actions to make data changes.
Peaka Tables play a pivotal role in facilitating efficient data management within your Peaka projects. They ensure that your data remains organized, accessible, and easily adaptable to meet your project's evolving needs.

On this page
* [Understanding Peaka Tables](https://www.peaka.com/docs/connecting-your-data/peaka-table/#understanding-peaka-tables)
--- START: docs/connecting-your-data/what-is-catalog-schema-virtual-table/what-is-catalog-schema-virtual-table.md ---
Documentation menu
[Home](/) / [Docs](/docs/) / What are catalogs, schemas, and virtual tables?
 Copy as Markdown
What are catalogs, schemas, and virtual tables?
===============================================
Learn about 3 basic concepts for organizing your data in Peaka
**Peaka** users organize their data using catalogs, schemas, and virtual tables. These concepts help users manage and access data from various data sources. Here's a brief introduction into these fundamental concepts:
Catalogs
--------
Catalogs in Peaka represent a collection of data sources or connectors, such as
* a SaaS Platform (HubSpot, Stripe, etc.),
* relational databases (PostgreSQL, MariaDB, etc.),
* spreadsheets (Airtable, Google Sheets, etc.),
* a REST API returning a collection of objects (coming soon...).
Each catalog is configured with a specific connector, which enables Peaka to read from and write to the underlying data source. Catalogs are the top-level organizational data units in Peaka and serve as a way to group related schemas.
Schemas
-------
Schemas are a level below catalogs and can be thought of as namespaces that contain a collection of tables. A schema is used to group related tables and views within a catalog, providing a way to organize data in a hierarchical manner. Schemas are inherited from the underlying connector.
Schemas have different meanings for relational databases and SaaS connectors in Peaka:
* In relational databases, schemas often correspond to a database or a specific user's workspace. For a PostgreSQL connector, schemas correspond to exact schemas with the connected database.
* In SaaS connectors, schemas refer to the groups of APIs according to the API organization of the SaaS providers. For example, HubSpot organizes its APIs under CRM, Marketing, etc.
If there is no organization in the underlying connector, the default schema is usually referred to as **public**, a keyword borrowed from PostgreSQL as the default schema.
Tables / Virtual Tables
-----------------------
Tables form the lowest level in this organizational hierarchy and represent structured data sets.
A table is composed of rows and columns, where each row represents a single record, and each column represents a specific attribute or field of that record.
Tables store the actual data that users query and manipulate using SQL statements in Peaka.
At Peaka, we sometimes call it a virtual table instead of a table because not all are real database tables. Instead, Peaka just shows them as tables in the system. Almost all of the tables of a SaaS connector are virtual tables. You can still use these tables in your data operations and treat them like real tables. You can query them using SQL and join their data with other tables and virtual tables. Virtual tables are bound to an API of the connected data source or SaaS Provider.
Summary
-------
In summary, Peaka organizes data using catalogs, schemas, and tables, where catalogs represent data sources, schemas group related tables within a catalog, and tables store structured data. This hierarchical organization enables users to manage, query, and manipulate data from multiple data sources in a unified and efficient manner.
On this page
* [Catalogs](https://www.peaka.com/docs/connecting-your-data/what-is-catalog-schema-virtual-table/#catalogs)
* [Schemas](https://www.peaka.com/docs/connecting-your-data/what-is-catalog-schema-virtual-table/#schemas)
* [Tables / Virtual Tables](https://www.peaka.com/docs/connecting-your-data/what-is-catalog-schema-virtual-table/#tables-virtual-tables)
* [Summary](https://www.peaka.com/docs/connecting-your-data/what-is-catalog-schema-virtual-table/#summary)
--- START: docs/connecting-your-data/what-is-materialized-query/what-is-materialized-query.md ---
Documentation menu
[Home](/) / [Docs](/docs/) / What is a Materialized Query?
 Copy as Markdown
What is a Materialized Query?
=============================
Learn about Peaka Materialized Queries and how you can harness their power
What is a Materialized Query?
-----------------------------
A Materialized Query is a powerful performance optimization technique that stores the results of complex queries physically in your database. Instead of executing expensive computations repeatedly, materialized queries cache precomputed data, dramatically reducing query execution time and system load.
### Key Benefits
* **Performance Boost**: Queries that once took minutes can now execute in seconds by accessing pre-calculated results
* **Resource Efficiency**: Reduces computational overhead by eliminating redundant processing
* **Real-time Analytics**: Enables faster dashboards and reporting by serving data from materialized views
* **Cost Optimization**: Lower database resource consumption translates to reduced operational costs
### Common Use Cases
* **Data Warehousing**: Pre-aggregate large datasets for faster reporting
* **Dashboard Queries**: Cache complex analytical queries that power business intelligence tools
* **Cross-database Joins**: Materialize results from queries spanning multiple data sources
* **Heavy Computations**: Store results of resource-intensive calculations like statistical analyses
Materialized queries are essential for applications requiring both complex data processing and fast response times.
### What is the difference between a Materialized Query and a Semantic Catalog?
**Materialized Query**
**Semantic Catalog**
**Storage**
Stores query results physically (precomputed cache)
Virtual—no stored data; runs the underlying query when accessed
**Data freshness**
Refreshed on a schedule or manually; data can be slightly stale between refreshes
Always reflects current source data—each access hits the live query
**Primary goal**
**Performance**: avoid re-running expensive queries; faster dashboards and reporting
**Organization & access**: semantic layer, sharing across projects, controlled access, no data duplication
**Use when**
The query is heavy and you can tolerate periodic refresh (e.g. aggregations, cross-db joins, BI)
You need live data, reusable “data products,” sharing with partners, or a single business-friendly view without copying data
In short: use a **Materialized Query** when you want speed and can accept scheduled updates; use a **Semantic Catalog** when you want a virtual, always-current view with sharing and governance and no physical copy of the data.
How to create a Materialized Query?
-----------------------------------
To create a Materialized Query, you can follow these steps:
1. Navigate to the Query Editor located in the right side panel and then select your query which you want to materialize.
2. Click on the Advanced button to open the configuration modal. Select the Materialize option and click on the Next button.
3. Configure your Materialized Query settings:
* **Name**: Enter a descriptive name for your Materialized Query
* **Auto Update**: Toggle this option to enable automatic refresh of your materialized data
When Auto Update is enabled, you can choose from two update strategies:
* **At regular intervals**: Updates the materialized query at specified minute intervals (e.g., every 15, 30, or 60 minutes)
* **Based on a schedule**: Provides flexible scheduling options where you can define:
* Timezone
* Frequency options (daily, weekly, monthly, or specific dates)
Configure these settings based on how frequently your underlying data changes and your performance requirements.
You can also fine-tune how the results are physically stored for better performance. Both fields are optional:
* **Partitioning**: Physically groups rows by one or more columns or transforms so that filtered reads scan less data. Use the format `ARRAY['column1', 'column2']` — for example `ARRAY['country', 'day(order_date)']`. See [How to Update Materialized Query Settings](https://www.peaka.com/docs/connecting-your-data/what-is-materialized-query/#how-to-update-materialized-query-settings) for the full list of supported transforms.
* **Sorted By**: Sorts rows within each file to speed up selective filters on high-cardinality columns. Use the format `ARRAY['column1', 'column2']` — for example `ARRAY['order_date DESC']`.
Then click on the Create Query button to create the Materialized Query.
That's it, your Materialized Query will be created. You can see the Materialized Query in the right side panel under the "Tables" section.
How to Update Your Materialized Query
-------------------------------------
You can update your materialized query in two ways: by editing the existing query or by replacing it with a different query entirely.
### Edit the Existing Query
1. Navigate your materialized query in the right side panel under the "Tables" section and click on the Show MT Query button.
2. A modal will open displaying the materialized query details. Click on the Edit button to modify the query.
3. You will be redirected to the Query Editor where your materialized query will open. Make your desired modifications to the query and run it to see the updated results.
### Replace with a Different Query
1. Navigate your materialized query in the right side panel under the "Tables" section and click on the Show MT Query button.

2. A modal will open displaying the materialized query details. Click on the dropdown button next to the Edit option and select "Select from List" from the dropdown menu.
3. A modal will open displaying the list of queries. Select the query you want to replace your materialized query with and click on the Update button.
4. Your materialized query will be replaced with the new query.
How to Update Materialized Query Settings
-----------------------------------------
You can modify various settings for your materialized queries to optimize performance and control refresh behavior.
1. Navigate your materialized query in the right side panel under the "Tables" section and click on the Show MT Query button.

2. A modal will open displaying the materialized query details. Click on the **Setup** tab to access configuration options.
3. You can modify the following settings:
* **Name**: Enter a descriptive name for your Materialized Query
* **Auto Update**: Toggle this option to enable automatic refresh of your materialized data
When Auto Update is enabled, you can choose from two update strategies:
* **At regular intervals**: Updates the materialized query at specified minute intervals (e.g., every 15, 30, or 60 minutes)
* **Based on a schedule**: Provides flexible scheduling options where you can define:
* Timezone
* Frequency options (daily, weekly, monthly, or specific dates)
* **Partitioning**: Optionally configure table partitioning to improve query performance. Materialized queries support partitioning by specifying transforms over the table columns. A partition is created for each unique tuple value produced by the transforms. Identity transforms are simply the column name. Other transforms include:
* `year(order_date)` - Creates a partition for each year. The partition value is the integer difference in years between order\_date and January 1 1970.
* `month(order_date)` - Creates a partition for each month of each year. The partition value is the integer difference in months between order\_date and January 1 1970.
* `day(order_date)` - Creates a partition for each day of each year. The partition value is the integer difference in days between order\_date and January 1 1970.
* `hour(created_at)` - Creates a partition for each hour of each day. The partition value is a timestamp with the minutes and seconds set to zero.
* `bucket(account_number, 10)` - Hashes data into 10 buckets. The partition value is an integer hash of account\_number, with a value between 0 and 9 inclusive.
* `truncate(country, 2)` - The partition value is the first 2 characters of the country field.
When enabled, you can specify partition columns using the format `partitioning = ARRAY['column1', 'column2']` or with transforms like `partitioning = ARRAY['year(order_date)', 'country']`.
* **Sort by**: Configure sorted files as a performance improvement. Data is sorted during writes within each file based on the specified array of one or more columns. Sorting is particularly beneficial when the sorted columns show high cardinality and are used as filters for selective reads. You can specify sort columns using the format `sorted_by = ARRAY['column1', 'column2']`. For example, to sort by order\_date, use `sorted_by = ARRAY['order_date']`. You can also explicitly configure sort directions and null ordering like `sorted_by = ARRAY['order_date DESC NULLS FIRST', 'order_id ASC NULLS LAST']`. Sorting can be combined with partitioning on the same column for optimal performance.
4. Then click on the **Update Materialized Query** button to update the materialized query settings.
That's it, your materialized query settings will be updated.
How to Update Materialized Query Manually
-----------------------------------------
You can manually refresh your materialized query to get the latest data without waiting for the scheduled update.
1. Navigate to your materialized query in the right side panel under the "Tables" section and click on the **Show MT Query** button.

2. A modal will open displaying the materialized query details. Click on the **Setup** tab to access configuration options.

3. Click on the **Manuel Update** button to update the materialized query manually.
That's it, your materialized query will be updated manually.
On this page
* [What is a Materialized Query?](https://www.peaka.com/docs/connecting-your-data/what-is-materialized-query/#what-is-a-materialized-query)
* [Key Benefits](https://www.peaka.com/docs/connecting-your-data/what-is-materialized-query/#key-benefits)
* [Common Use Cases](https://www.peaka.com/docs/connecting-your-data/what-is-materialized-query/#common-use-cases)
* [What is the difference between a Materialized Query and a Semantic Catalog?](https://www.peaka.com/docs/connecting-your-data/what-is-materialized-query/#what-is-the-difference-between-a-materialized-query-and-a-semantic-catalog)
* [How to create a Materialized Query?](https://www.peaka.com/docs/connecting-your-data/what-is-materialized-query/#how-to-create-a-materialized-query)
* [How to Update Your Materialized Query](https://www.peaka.com/docs/connecting-your-data/what-is-materialized-query/#how-to-update-your-materialized-query)
* [Edit the Existing Query](https://www.peaka.com/docs/connecting-your-data/what-is-materialized-query/#edit-the-existing-query)
* [Replace with a Different Query](https://www.peaka.com/docs/connecting-your-data/what-is-materialized-query/#replace-with-a-different-query)
* [How to Update Materialized Query Settings](https://www.peaka.com/docs/connecting-your-data/what-is-materialized-query/#how-to-update-materialized-query-settings)
* [How to Update Materialized Query Manually](https://www.peaka.com/docs/connecting-your-data/what-is-materialized-query/#how-to-update-materialized-query-manually)
--- START: docs/connecting-your-data/what-is-semantic-catalogs/what-is-semantic-catalogs.md ---
Documentation menu
[Home](/) / [Docs](/docs/) / What are semantic catalogs?
 Copy as Markdown
What are semantic catalogs?
===========================
Learn how to create, share, and use semantic catalogs to simplify data models and enable AI-ready datasets in Peaka
What are semantic catalogs?
---------------------------
A semantic catalog is a powerful semantic layer that organizes and provides controlled access to curated data subsets from your integrated sources such as Snowflake, MongoDB, and HubSpot—all without the need for data duplication.
Semantic catalogs act as a bridge between your raw data sources and end users, providing a clean, consistent, and business-friendly view of your data. They transform complex, technical data structures into simplified, meaningful datasets that can be easily understood and consumed by different teams, tools, and applications.
### How semantic catalogs work
Semantic catalogs are created from SQL queries that you've already saved in Peaka. When you convert a query into a semantic catalog, it becomes a virtual table that appears in your **Tables** section. This table can be queried just like any other table in your catalog, but it's powered by the underlying SQL query you defined.
The key advantage is that semantic catalogs automatically reflect changes in your source data—when the underlying data updates, queries against your semantic catalog will return the latest information without requiring manual updates or data copying.
Why semantic catalogs are useful
--------------------------------
Semantic catalogs offer several key benefits:
* **No data duplication**: Access curated data views without copying or moving data, reducing storage costs and ensuring data consistency
* **Centralized data modeling**: Create a single source of truth for business logic and data transformations using SQL
* **Controlled access**: Share specific data subsets with different teams, partners, or projects while maintaining security and governance
* **Simplified consumption**: Present complex data in a format that's easy to understand and use, whether through APIs, BI tools, or dashboards
* **Reusability**: Share semantic catalogs across multiple projects and use cases, reducing redundant work
* **AI-ready**: Structure your data in a way that's optimized for AI and machine learning applications
Use cases
---------
### Simplifying data models
Semantic catalogs help you transform complex, multi-table data structures into simplified, single-table views. Instead of requiring users to understand complex joins, relationships, and technical schemas, semantic catalogs present data in a flat, intuitive format. This makes it easier for business users, analysts, and developers to work with your data without deep technical knowledge of the underlying database structure.
For example, you can combine customer data from multiple tables (customers, orders, products) into a single semantic catalog that shows customer purchase history in one clean view.
### AI-ready data models
Semantic catalogs are ideal for preparing data for AI and machine learning applications. They allow you to:
* Structure data in formats optimized for AI consumption
* Ensure consistent data quality and formatting
* Create feature-rich datasets with pre-computed aggregations and transformations
* Provide clean, labeled data that AI models can easily process
By creating semantic catalogs specifically designed for AI use cases, you can accelerate your AI initiatives and ensure your models are working with high-quality, well-structured data.
### Data products and cross-project sharing
Semantic catalogs function as reusable data products that can be shared across multiple projects within your organization. Instead of recreating the same data transformations in each project, you can:
* Create a semantic catalog once and share it with multiple projects
* Maintain consistency across different projects and teams
* Reduce development time and effort
* Ensure all projects use the same business logic and data definitions
This approach promotes data reuse and standardization across your organization, making your data infrastructure more efficient and maintainable.
### Sharing datasets with third-party partners and vendors
Semantic catalogs enable secure data sharing with external partners, vendors, or clients. You can:
* Create curated datasets that expose only the necessary data to external parties
* Control access through API keys and project-level permissions
* Share data without exposing your entire database or raw data sources
* Provide partners with clean, well-documented datasets that are easy to integrate
This is particularly useful for B2B data sharing scenarios, vendor integrations, or when providing data to clients as part of your service offering.
How to create a semantic catalog
--------------------------------
Before creating a semantic catalog, ensure you have:
* An existing catalog set up
* A query created and saved
For detailed information about catalogs and queries, refer to our [catalog documentation](/docs/connecting-your-data/add-connection) and [query documentation](/docs/connecting-your-data/creating-query).
Follow these steps to create a semantic catalog:
1. Navigate to the **Queries** page in Peaka and select the query you want to use as the basis for your semantic catalog.
2. Click the **Advanced** button to open the configuration modal. Select the **Semantic Catalog** option and click **Next**.
3. Choose your catalog:
* If you have an existing semantic catalog, select **Existing Catalogs** and choose the catalog from the dropdown
* If you want to create a new catalog, fill in the required fields:
* **Catalog name**: A descriptive name for your semantic catalog
* **Schema name**: The schema where your semantic table will be created
* **Table name**: The name for your semantic table
Click **Add** to proceed.
4. Your semantic catalog is now created! You can view it in the **Tables** section of the left sidebar.
How to share a semantic catalog
-------------------------------
Before sharing a semantic catalog, ensure you have:
* A semantic catalog created
Follow these steps to share a semantic catalog:
1. Navigate to the **Tables** page in Peaka. Find your semantic catalog name in the list, click the three-dot menu (...), next to it, and select **Share Options**.
2. A modal will open allowing you to share the semantic catalog with other projects. Select the project(s) you want to share the semantic catalog with and click **Share**.
That's it, the semantic catalog is now shared with the project. You can view the shared semantic catalog in the **Tables** section of the left sidebar in the project you shared the semantic catalog with.
On this page
* [What are semantic catalogs?](https://www.peaka.com/docs/connecting-your-data/what-is-semantic-catalogs/#what-are-semantic-catalogs)
* [How semantic catalogs work](https://www.peaka.com/docs/connecting-your-data/what-is-semantic-catalogs/#how-semantic-catalogs-work)
* [Why semantic catalogs are useful](https://www.peaka.com/docs/connecting-your-data/what-is-semantic-catalogs/#why-semantic-catalogs-are-useful)
* [Use cases](https://www.peaka.com/docs/connecting-your-data/what-is-semantic-catalogs/#use-cases)
* [Simplifying data models](https://www.peaka.com/docs/connecting-your-data/what-is-semantic-catalogs/#simplifying-data-models)
* [AI-ready data models](https://www.peaka.com/docs/connecting-your-data/what-is-semantic-catalogs/#ai-ready-data-models)
* [Data products and cross-project sharing](https://www.peaka.com/docs/connecting-your-data/what-is-semantic-catalogs/#data-products-and-cross-project-sharing)
* [Sharing datasets with third-party partners and vendors](https://www.peaka.com/docs/connecting-your-data/what-is-semantic-catalogs/#sharing-datasets-with-third-party-partners-and-vendors)
* [How to create a semantic catalog](https://www.peaka.com/docs/connecting-your-data/what-is-semantic-catalogs/#how-to-create-a-semantic-catalog)
* [How to share a semantic catalog](https://www.peaka.com/docs/connecting-your-data/what-is-semantic-catalogs/#how-to-share-a-semantic-catalog)
--- START: docs/cookbook/how-to-change-flow-name/how-to-change-flow-name.md ---
Documentation menu
[Home](/) / [Docs](/docs/) / How to change the name of a flow
 Copy as Markdown
How to change the name of a flow
================================
Learn how you can easily change the name of your flow in Peaka
This article explains how you change the name of your flow in three steps in Peaka.
Changing the Flow Name
----------------------
Follow these simple steps to change the name of your flow:
1. **Show your flow:** First, ensure that you have a flow to work with. If you haven't created a flow yet, you can refer to the article on [How to create a flow](/docs/flows/how-to-create-a-flow/) for guidance.
2. **Mouse over the flow name:** Navigate to the flow you want to rename and hover your mouse cursor over its name. When you do this, an edit button will appear next to the flow name.
3. **Edit the flow name:** Click on the edit button to initiate the renaming process. This action will allow you to enter a new name for your flow, as shown in the image below.
4. **Confirm the new name:** After typing the desired new name for your flow, simply press the "Enter" key to confirm the change.
That's it! You have successfully updated the name of your flow to better suit your needs. Renaming flows can help you keep your workspace organized and ensure clarity when working on your projects.
On this page
* [Changing the Flow Name](https://www.peaka.com/docs/cookbook/how-to-change-flow-name/#changing-the-flow-name)
--- START: docs/cookbook/how-to-combine-connector-and-peaka-table-data/how-to-combine-connector-and-peaka-table-data.md ---
Documentation menu
[Home](/) / [Docs](/docs/) / How to join connector data with Peaka Table data
 Copy as Markdown
How to join connector data with Peaka Table data
================================================
Learn how you can combine connector data with Peaka Table data and utilize the result in your Peaka application
This article provides a step-by-step guide on how to join the data from a connector with the data from a Peaka Table and use the result in your Peaka application.
Prerequisites
-------------
Before joining data from a connector and a Peaka Table, ensure that you have the necessary data sources available. You will need:
1. **Peaka Table:** If you don't have a Peaka Table yet, see the documentation on [how to create a Peaka Table](/docs/connecting-your-data/creating-peaka-table) for detailed instructions.
2. **Connector data:** You should have data from a connector source. If you don't have any connector data, refer to the documentation on [how to connect your data](/docs/connecting-your-data/add-connection) using a SaaS connector.
Step-by-step Guide
------------------
Follow these steps to join and use the data from your connector and Peaka Table:
1. **Create an SQL query:** You'll need to create a SQL query that combines data from your connector and Peaka Table. See the documentation on [how to create a SQL query](/docs/connecting-your-data/creating-query) for further details.
2. **Execute the query:** Execute the SQL query you've created while clicking on the "Run" button. This query will merge the data from your connector and Peaka Table.
3. **View the merged data:** Once the query has been executed, you can review the merged data. The results will be displayed as shown in the image below. Additionally, you can access the data in the "Data Model" page under the "Query" tables.
By following these steps, you can seamlessly join and utilize the data from your connector and Peaka Table in your Peaka application. This allows you to harness the power of both data sources to enhance your application's functionality and capabilities.
On this page
* [Prerequisites](https://www.peaka.com/docs/cookbook/how-to-combine-connector-and-peaka-table-data/#prerequisites)
* [Step-by-step Guide](https://www.peaka.com/docs/cookbook/how-to-combine-connector-and-peaka-table-data/#step-by-step-guide)
--- START: docs/cookbook/how-to-connect-databases-in-aws-using-iam-credentials/how-to-connect-databases-in-aws-using-iam-credentials.md ---
Documentation menu
[Home](/) / [Docs](/docs/) / How to connect databases in AWS using IAM credentials
 Copy as Markdown
How to connect databases in AWS using IAM credentials
=====================================================
Learn how you can connect databases in AWS using IAM credentials
This guide walks you through the process of connecting a connector with IAM (Identity and Access Management) credentials to Peaka.
Prerequisites
-------------
Before you begin, ensure that you have the necessary information by following these steps:
Follow the steps below to obtain it:
1. **Enable IAM Database Authentication:** Ensure that IAM database authentication is enabled for your database. Refer to the [official AWS documentation](https://docs.aws.amazon.com/AmazonRDS/latest/UserGuide/UsingWithRDS.IAMDBAuth.Enabling.html) for detailed instructions.
2. **Create a Database User:** Create a database user following the guidelines outlined in the [AWS documentation](https://docs.aws.amazon.com/AmazonRDS/latest/UserGuide/UsingWithRDS.IAMDBAuth.DBAccounts.html). Be cautious to grant the appropriate privileges to the user.
**Warning:** Ensure that you grant the necessary privileges to the user created in this step.
3. **Create an IAM Policy:** Set up an IAM policy for your IAM user by following the steps outlined in the [AWS documentation](https://docs.aws.amazon.com/AmazonRDS/latest/UserGuide/UsingWithRDS.IAMDBAuth.IAMPolicy.html).
4. **Create an IAM User:** Create an IAM user and attach the IAM policy created in the previous step. Ensure that the IAM username matches the database username created in step 2. Refer to the [AWS documentation](https://docs.aws.amazon.com/IAM/latest/UserGuide/id_users_create.html) for detailed instructions.
**Warning:** Keep in mind that the IAM username and database username (from step 2) must be identical.
5. **Obtain AWS Access Key and Secret Key:** After creating the IAM user, navigate to the AWS console: IAM -> Users -> < IAM user you've just created > -> Security credentials. Create an access key to obtain your AWS Access Key and AWS Secret Key. Utilize these keys and your IAM username in Peaka's Amazon RDS connection screen to authenticate Peaka with your RDS.
**Note:** Use caution with access keys; ensure they are handled securely and kept confidential.
On this page
* [Prerequisites](https://www.peaka.com/docs/cookbook/how-to-connect-databases-in-aws-using-iam-credentials/#prerequisites)
--- START: docs/cookbook/how-to-create-oauth2-based-connections-via-peaka/how-to-create-oauth2-based-connections-via-peaka.md ---
Documentation menu
[Home](/) / [Docs](/docs/) / How to create OAuth2 based connections via Peaka API?
 Copy as Markdown
How to create OAuth2 based connections via Peaka API?
=====================================================
Learn how to create OAuth2 based connections via Peaka API.
You can easily create connection via the Peaka API. For example, here’s how to create a connection to Stripe, a very popular payment platform:
curl --request POST \
--url https://partner.peaka.studio/api/v1/connections/{projectId} \
--header 'Authorization: Bearer ' \
--header 'Content-Type: application/json' \
--data '{
"name": "",
"type": "stripe",
"credential": {
"token": ""
}
}'
Passing the Stripe token to the Peaka platform is sufficient.
Not all 3rd party platforms support a simple token (or user:password) based authentication. For example, HubSpot - a very popular CRM platform - or Google Sheets use OAuth2 based authentication (see: [https://en.wikipedia.org/wiki/OAuth](https://en.wikipedia.org/wiki/OAuth) or [https://auth0.com/intro-to-iam/what-is-oauth-2](https://auth0.com/intro-to-iam/what-is-oauth-2)). The most common OAuth2 grant type is Authorization Code. Authorization Code flow requires some user interaction. After various steps, the platform you are using gives you a pair of token: an Access Token and a Refresh Token. Peaka should know these tokens in order to query data of the platform.
Peaka has already implemented various 3rd party platforms using OAuth2. If you are using Peaka
* directly ([https://peaka.studio/](https://peaka.studio/)),
* in an Embedded UI ([/docs/cookbook/how-to-embed-peaka-to-my-app](/docs/cookbook/how-to-embed-peaka-to-my-app)),
you will get connected to those platforms.
For those who want to create connection based on OAuth2 via Peaka Rest Api, there are two options:
1. Use your OAuth implementation, provide tokens to Peaka
2. Use Peaka OAuth mechanism
1\. Use Your OAuth Implementation
=================================
Partners may have an already implemented OAuth process and OAuth apps.
In order to use these apps, Peaka needs clientId, clientSecret, refreshToken and accessToken.
Since partner makes all OAuth flows, it is sufficient to pass these info to Peaka. This is the simplest integration way of OAuth.
Upon getting refresh token and access token from the OAuth Provider (e.g. Google), the Partner will make “create connection” request.
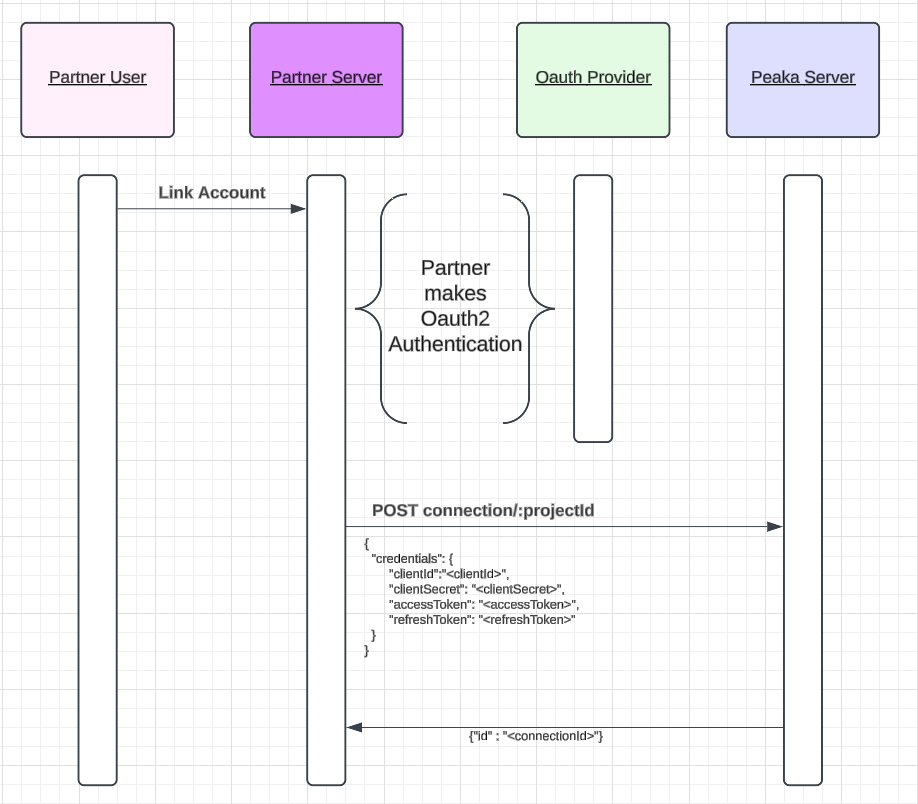
A typical request example will be
curl --request POST \
--url https://partner.peaka.studio/api/v1/connections/{projectId} \
--header 'Authorization: Bearer ' \
--header 'Content-Type: application/json' \
--data '{
"name": "",
"type": "hubspot",
"credential": {
"clientId": "",
"clientSecret": "",
"accessToken": "",
"refreshToken": ""
}
}'
And sample response returning connection id will be:
200
{
"id": "6243f42a-42d0-4821-a90f-763cda6cda50",
"name": "",
"type": "hubspot"
}
Partners choose this way integration because they have already have Oauth processes or they want to do OAuth processes by themselves.
2\. Use Peaka OAuth Mechanism
=============================
OAuth flows are a bit complex to implement for some partners. Defining and registering appropriate OAuth apps can also be complex and time consuming (e.g. Some platforms may have longer review process).
Peaka does the complex part and informs you when an OAuth flow has completed.
Since everything happens in the user browser, such integration is more complex than the previous.
Whether you will be using Peaka OAuth App or your own OAuth app, this mechanism can be implemented in two ways:
2.a. Use Peaka OAuth App
------------------------
When you choose to use Peaka OAuth app for some Platform (e.g. Google Analytics), OAuth flow will end at Peaka site and Peaka will inform you after that.
Using Peaka OAuth app has some advantages and disadvantages. Also in some cases, you should use your own OAuth app.
Advantages:
* Some platforms enable public creation of an OAuth app, some requires developer accounts, and some requires a partnership program. Also they may have review process. Peaka has completed review process of the Platform you are using. So you don’t need to wait for your own.
Disadvantages:
* In OAuth flow, a consent screen will be shown to your user. In that screen, Peaka’s branding and logo will be shown. If you need to show your logo and branding, you should choose to create your own OAuth app and implement the next option.
* Platforms may have strict rate limits. To avoid rate limits, you may consider creating your own oauth app.
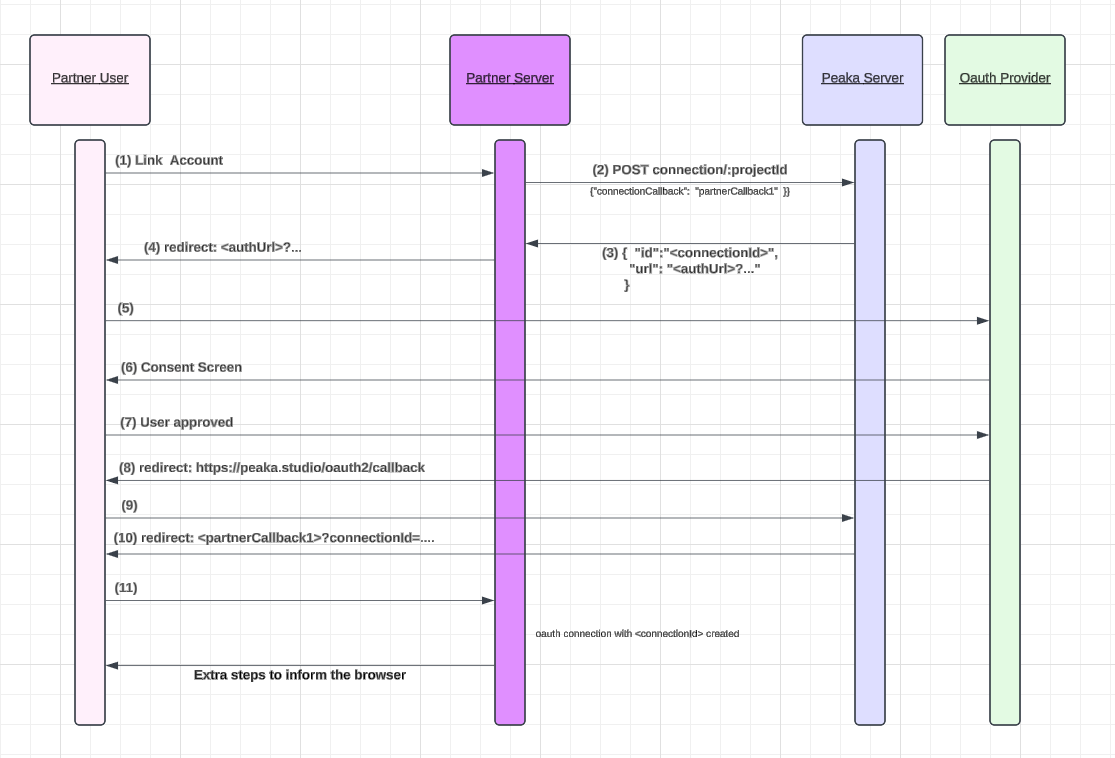
1. Your user clicks a button in your application in order to create connection. e.g. Google Analytics connection. The response of this http request will be done in Step 4.
2. Your server should make a create connection request
curl --request POST \
--url https://partner.peaka.studio/api/v1/connections/{projectId} \
--header 'Authorization: Bearer ' \
--header 'Content-Type: application/json' \
--data '{
"name": "exampleOauthConnection",
"type": "google_analytics",
"connectionCallback": ""
}'
Here `partner_callback_url` is the full url of your server endpoint responsible to complete creation process. We will use `partner_callback_url` at Step 10 and 11.
3. As a response to the request in Step 2
200
{
"id" : "",
"name": "",
"type": "google_analytics"
"url": ""
}
Peaka will return the url of the consent screen of the Platform.
4. Your server should return redirect: to the browser as response to the request initiated at Step 1. Also it is a good practice to store `connection_id`and the location where the user has started the connection.
An example for Step 1-4 can be given in Node.js as follows:
(Note that it is not a complete working example)
const express = require("express");
const axios = require("axios");
const app = express();
app.use(express.json());
// Replace with your actual Peaka API key and project ID
const PEAKA_API_KEY = "";
const PROJECT_ID = "";
// Your server endpoint responsible for completing the connection process
const partnerCallbackUrl = ""; // e.g., "https://yourserver.com/complete-connection"
app.post("/create-connection", async (req, res) => {
try {
// Step 2: Make the create connection request
const response = await axios.post(
`https://partner.peaka.studio/api/v1/connections/${PROJECT_ID}`,
{
name: "exampleOauthConnection",
type: "google_analytics",
connectionCallback: partnerCallbackUrl,
},
{
headers: {
Authorization: `Bearer ${PEAKA_API_KEY}`,
"Content-Type": "application/json",
},
}
);
// Step 3: Extract connection data from the response
const { id, name, type, url } = response.data;
// Store connection ID and where the user started the connection (Optional, e.g., in a database)
// For example: storeConnection(id, name, type, req.originalUrl);
// Step 4: Redirect the user to the consent URL
res.redirect(url); // Redirect the user to the consent screen
} catch (error) {
console.error("Error creating connection:", error);
res.status(500).send("Error creating connection");
}
});
// Endpoint to complete the connection process (Step 10 and 11)
app.get("/complete-connection", async (req, res) => {
try {
// Handle the final steps of completing the OAuth connection
// This would typically involve processing the authorization code, fetching data, etc.
console.log("Connection completed successfully!");
res.send("Connection completed successfully!");
} catch (error) {
console.error("Error completing connection:", error);
res.status(500).send("Error completing connection");
}
});
// Start the Express server
const PORT = process.env.PORT || 3000;
app.listen(PORT, () => {
console.log(`Server running on port ${PORT}`);
});
5. Browser will automatically redirect to Platform Consent Screen.
6. Browser shows the Consent Screen.
7. User will approve the consents.
8. Platform will return the Peaka OAuth app’s redirect (oauth2 callback of Peaka) redirect:https://peaka.studio/oauth2/callback
9. Browser will be redirected to Peaka Callback.
10. Peaka will return a redirection to your `partner_callback_url`:
?connectionId=?status=< success or fail >
11. The browser will be redirected to your `` with query parameters `connectionId` and `status`. If `status` is `success`, the connection has been created successfully. Otherwise, if `status` is `fail`, it indicates a problem, such as a platform error or a timeout in the flow.
A typical implementation of Step 10 and Step 11 in Node.js:
(Note that it is not a complete working example)
const express = require("express");
const axios = require("axios");
const app = express();
const PORT = 3000;
app.get("/oauth2/mycallback", async (req, res) => {
try {
const { connectionId, status } = req.query;
if (!connectionId) {
return res.redirect("/error?message=Connection could not be created");
}
// Find the URL using the connectionId (this could involve querying your session, in-memory map or database)
const redirectUrl = getRedirectUrlByConnectionId(connectionId);
if (!redirectUrl) {
return res.redirect("/error?message=Redirect URL not found");
}
// Redirect to the found URL
res.redirect(redirectUrl);
} catch (error) {
console.error("Error handling callback:", error);
// Redirect to an error page with a message
res.redirect("/error?message=Failed to process callback");
}
});
// Dummy function to simulate finding a URL by connectionId
function getRedirectUrlByConnectionId(connectionId) {
// Replace with actual logic to find the URL by connectionId
if (connectionId === "someConnectionId") {
return "https://yourdomain.com/this_is_where_you_begin";
}
return null;
}
app.listen(PORT, () => {
console.log(`OAuth2 callback endpoint running on http://localhost:${PORT}`);
});
2\. b. Use Your Own OAuth App
-----------------------------
You should create your own app,
* if you need to use your own branding and logo
* if you need better rate limits for the Platform API
* if Peaka supports connection for the Platform but does not have a global app.
* Here, global app means that the Platform allows Peaka use data of other users. Sometimes the platforms allow only non-global apps or there are long review processes for the global apps.
There are a couple things to consider while your are creating your OAuth app.
The OAuth app will ask for redirect url (or callback url). Redirect Url is the endpoint where the browser is redirected at the end of OAuth flow. According to the given url, the integration process will differentiate.
1. **You can use Peaka’s own callback url.**
https://peaka.studio/oauth2/callback
In that case, it is necessary and sufficient to implement steps described in **2.a. Use Peaka Oauth App** with a minor diff. You should give the client id and client secret parameters in the request.
Step 2 will be:
curl --request POST \
--url https://partner.peaka.studio/api/v1/connections/{projectId} \
--header 'Authorization: Bearer ' \
--header 'Content-Type: application/json' \
--data '{
"name": "exampleOauthConnection",
"type": "google_analytics",
"connectionCallback": "",
"credential": {
"clientId": "",
"clientSecret": ""
}
}'
2. **You can use your own redirect url and then redirect it to the Peaka’s callback.**
If you do the appropriate redirection, the implementation steps will be same as the above case.
In that case, the user browser will momentarily redirected to Peaka’s callback and then it will be redirected to `partner_callback_url`
e.g. You give the OAuth app `redirect_url` as `https://yourdomain.com/oauth2/mycallback`
Then you should redirect the request coming to your `redirect_url` to `https://peaka.studio/oauth2/callback`
You can do this redirection in your reverse proxy server (Apache, Nginx, Traefik, etc.) or in your application server (Express in Node.js, Spring in Java, etc.).
Apache (HTTPD)
ServerName yourdomain.com
RewriteEngine On
RewriteCond %{QUERY_STRING} (.*)
RewriteRule ^/oauth2/mycallback$ https://peaka.studio/oauth2/callback?%1 [R=307,L]
Nginx
server {
listen 80;
server_name yourdomain.com;
location /oauth2/mycallback {
# Redirect to Peaka callback with all query parameters
return 307 https://peaka.studio/oauth2/callback?$query_string;
}
}
Traefik
http:
routers:
redirectRouter:
rule: "Path(`/oauth2/mycallback`)"
service: dummyService
middlewares:
- redirectToPeaka
middlewares:
redirectToPeaka:
redirectRegex:
regex: "^.*"
replacement: "https://peaka.studio/oauth2/callback?${query}"
permanent: false
Node.js
const express = require("express");
const app = express();
app.get("/oauth2/mycallback", (req, res) => {
// Peaka callback URL
const peakaCallbackUrl = "https://peaka.studio/oauth2/callback";
const queryParams = req.url.split("?")[1];
const redirectUrl = queryParams
? `${peakaCallbackUrl}?${queryParams}`
: peakaCallbackUrl;
res.redirect(307, redirectUrl);
});
app.listen(3000, () => {
console.log("Server running at http://localhost:3000");
});
3. **You can use your own callback url and the user’s browser will never redirected to Peaka’s domain.**
This approach requires a different implementation compared to the previous cases when integrating your OAuth app.

1. Your user clicks a button in your application in order to create connection. e.g. Google Analytics connection. The response of this http request will be done in Step 4.
2. Your server should make a create connection request
curl --request POST \
--url https://partner.peaka.studio/api/v1/connections/{projectId} \
--header 'Authorization: Bearer ' \
--header 'Content-Type: application/json' \
--data '{
"name": "exampleOauthConnection",
"type": "google_analytics",
"credential": {
"clientId": "",
"clientSecret": "",
"redirectUrl": ""
}
}'
Here `redirect_url` under “credential” object should be the callback (or redirect) url you give to the Platform OAuth app.
3. As a response to the request in (2)
200
{
"id" : "",
"name": "",
"type": "google_analytics"
"url": ""
}
Peaka will return the url of the consent screen of the Platform.
4. Your server should return redirect: to the browser as response to the request initiated at Step 1. Also it is a good practice to store `connection_id`and the location where the user has started the connection.
An example for Step 1-4 can be given in Node.js as follows: (Note that it is not a complete working example)
const express = require("express");
const axios = require("axios");
const app = express();
// Replace with your actual Peaka API key and project ID
const PEAKA_API_KEY = "";
const PROJECT_ID = "";
app.use(express.json());
// Endpoint to initiate the connection creation process
app.post("/create-connection", async (req, res) => {
try {
// Step 2: Make the create connection request
const response = await axios.post(
`https://partner.peaka.studio/api/v1/connections/${PROJECT_ID}`,
{
name: "exampleOauthConnection",
type: "google_analytics",
credential: {
clientId: "",
clientSecret: "",
redirectUrl: "",
},
},
{
headers: {
Authorization: `Bearer ${PEAKA_API_KEY}`,
"Content-Type": "application/json",
},
}
);
// Step 3: Handle the response and extract the consent URL
const { id, url } = response.data;
// Optionally, you can store the connection ID and other relevant data in a database
// Step 4: Return the redirect response with the consent URL
res.redirect(url); // This will redirect the user to the consent screen
} catch (error) {
console.error("Error creating connection:", error);
res.status(500).send("Error creating connection");
}
});
// Start the Express server
const PORT = process.env.PORT || 3000;
app.listen(PORT, () => {
console.log(`Server running on port ${PORT}`);
});
5. Browser will automatically redirect to Platform Consent Screen
6. Browser shows the Consent Screen.
7. User will approve the consents.
8. Platform will return the your OAuth app’s redirect url - you give in Step 2 - with some query parameters.
9. Browser will be redirected to your callback with some query parameters.
10. A typical `redirect_url` will be
https://yourdomain.com/oauth2/mycallback?state=2def...&code=2asd...&...
You should pass all the query parameters to Peaka as follows:
curl --request POST \
--url https://partner.peaka.studio/api/v1/connections/{projectId}/oauth2 \
--header 'Authorization: Bearer ' \
--header 'Content-Type: application/json' \
--data '{
"queryParameters": "state=2ad...&code=2asd...&other_query_params=...."
}'
11. Response of Step 10 will be
200
{
"id" : ""
}
A typical implementation of Step 10 and Step 11 in Node.js:
(Note that it is not a complete working example)
const express = require("express");
const axios = require("axios");
const app = express();
const PORT = 3000;
// Replace with your Peaka API details
const PEAKE_API_URL =
"https://partner.peaka.studio/api/v1/connections/{projectId}/oauth2";
const PEAKE_API_KEY = "";
app.get("/oauth2/mycallback", async (req, res) => {
try {
// Extract all query parameters from the request
const queryParams = new URLSearchParams(req.query).toString();
if (!queryParams) {
return res.redirect("/error?message=Missing authorization code");
}
// Post query parameters to Peaka
const peakaResponse = await axios.post(
PEAKE_API_URL,
{ queryParameters: queryParams },
{
headers: {
Authorization: `Bearer ${PEAKE_API_KEY}`,
"Content-Type": "application/json",
},
}
);
// Extract the connectionId from Peaka's response
const connectionId = peakaResponse.data.id;
if (!connectionId) {
return res.redirect("/error?message=Connection could not be created");
}
// Find the URL using the connectionId (this could involve querying your in memory map or database)
const redirectUrl = getRedirectUrlByConnectionId(connectionId);
if (!redirectUrl) {
return res.redirect("/error?message=Redirect URL not found");
}
// Redirect to the found URL
res.redirect(redirectUrl);
} catch (error) {
console.error("Error posting to Peaka:", error);
// Redirect to an error page with a message
res.redirect("/error?message=Failed to process callback");
}
});
// Dummy function to simulate finding a URL by connectionId
function getRedirectUrlByConnectionId(connectionId) {
// Replace with actual logic to find the URL by connectionId
if (connectionId === "someConnectionId") {
return "https://yourdomain.com/this_is_where_you_begin";
}
return null;
}
app.listen(PORT, () => {
console.log(`OAuth2 callback endpoint running on http://localhost:${PORT}`);
});
On this page
* [1\. Use Your OAuth Implementation](https://www.peaka.com/docs/cookbook/how-to-create-oauth2-based-connections-via-peaka/#1-use-your-oauth-implementation)
* [2\. Use Peaka OAuth Mechanism](https://www.peaka.com/docs/cookbook/how-to-create-oauth2-based-connections-via-peaka/#2-use-peaka-oauth-mechanism)
* [2.a. Use Peaka OAuth App](https://www.peaka.com/docs/cookbook/how-to-create-oauth2-based-connections-via-peaka/#2-a-use-peaka-oauth-app)
* [2\. b. Use Your Own OAuth App](https://www.peaka.com/docs/cookbook/how-to-create-oauth2-based-connections-via-peaka/#2-b-use-your-own-oauth-app)
--- START: docs/cookbook/how-to-create-peaka-rest-api-catalog-with-authentication/how-to-create-peaka-rest-api-catalog-with-authentication.md ---
Documentation menu
[Home](/) / [Docs](/docs/) / How to create Peaka REST API catalog with authentication
 Copy as Markdown
How to create Peaka REST API catalog with authentication
========================================================
Learn how you can create Peaka REST API catalog with authentication
This article explains how you can create Peaka REST API catalog with authentication.
Creating Peaka REST API catalog with authentication
---------------------------------------------------
Follow these simple steps to create Peaka REST API catalog with authentication:
1. **Open New Data Source Modal:** Click on the "New Data Source" button in the left sidebar and click on "Connect Rest API" button. It will open a modal to create a new Peaka REST API catalog.
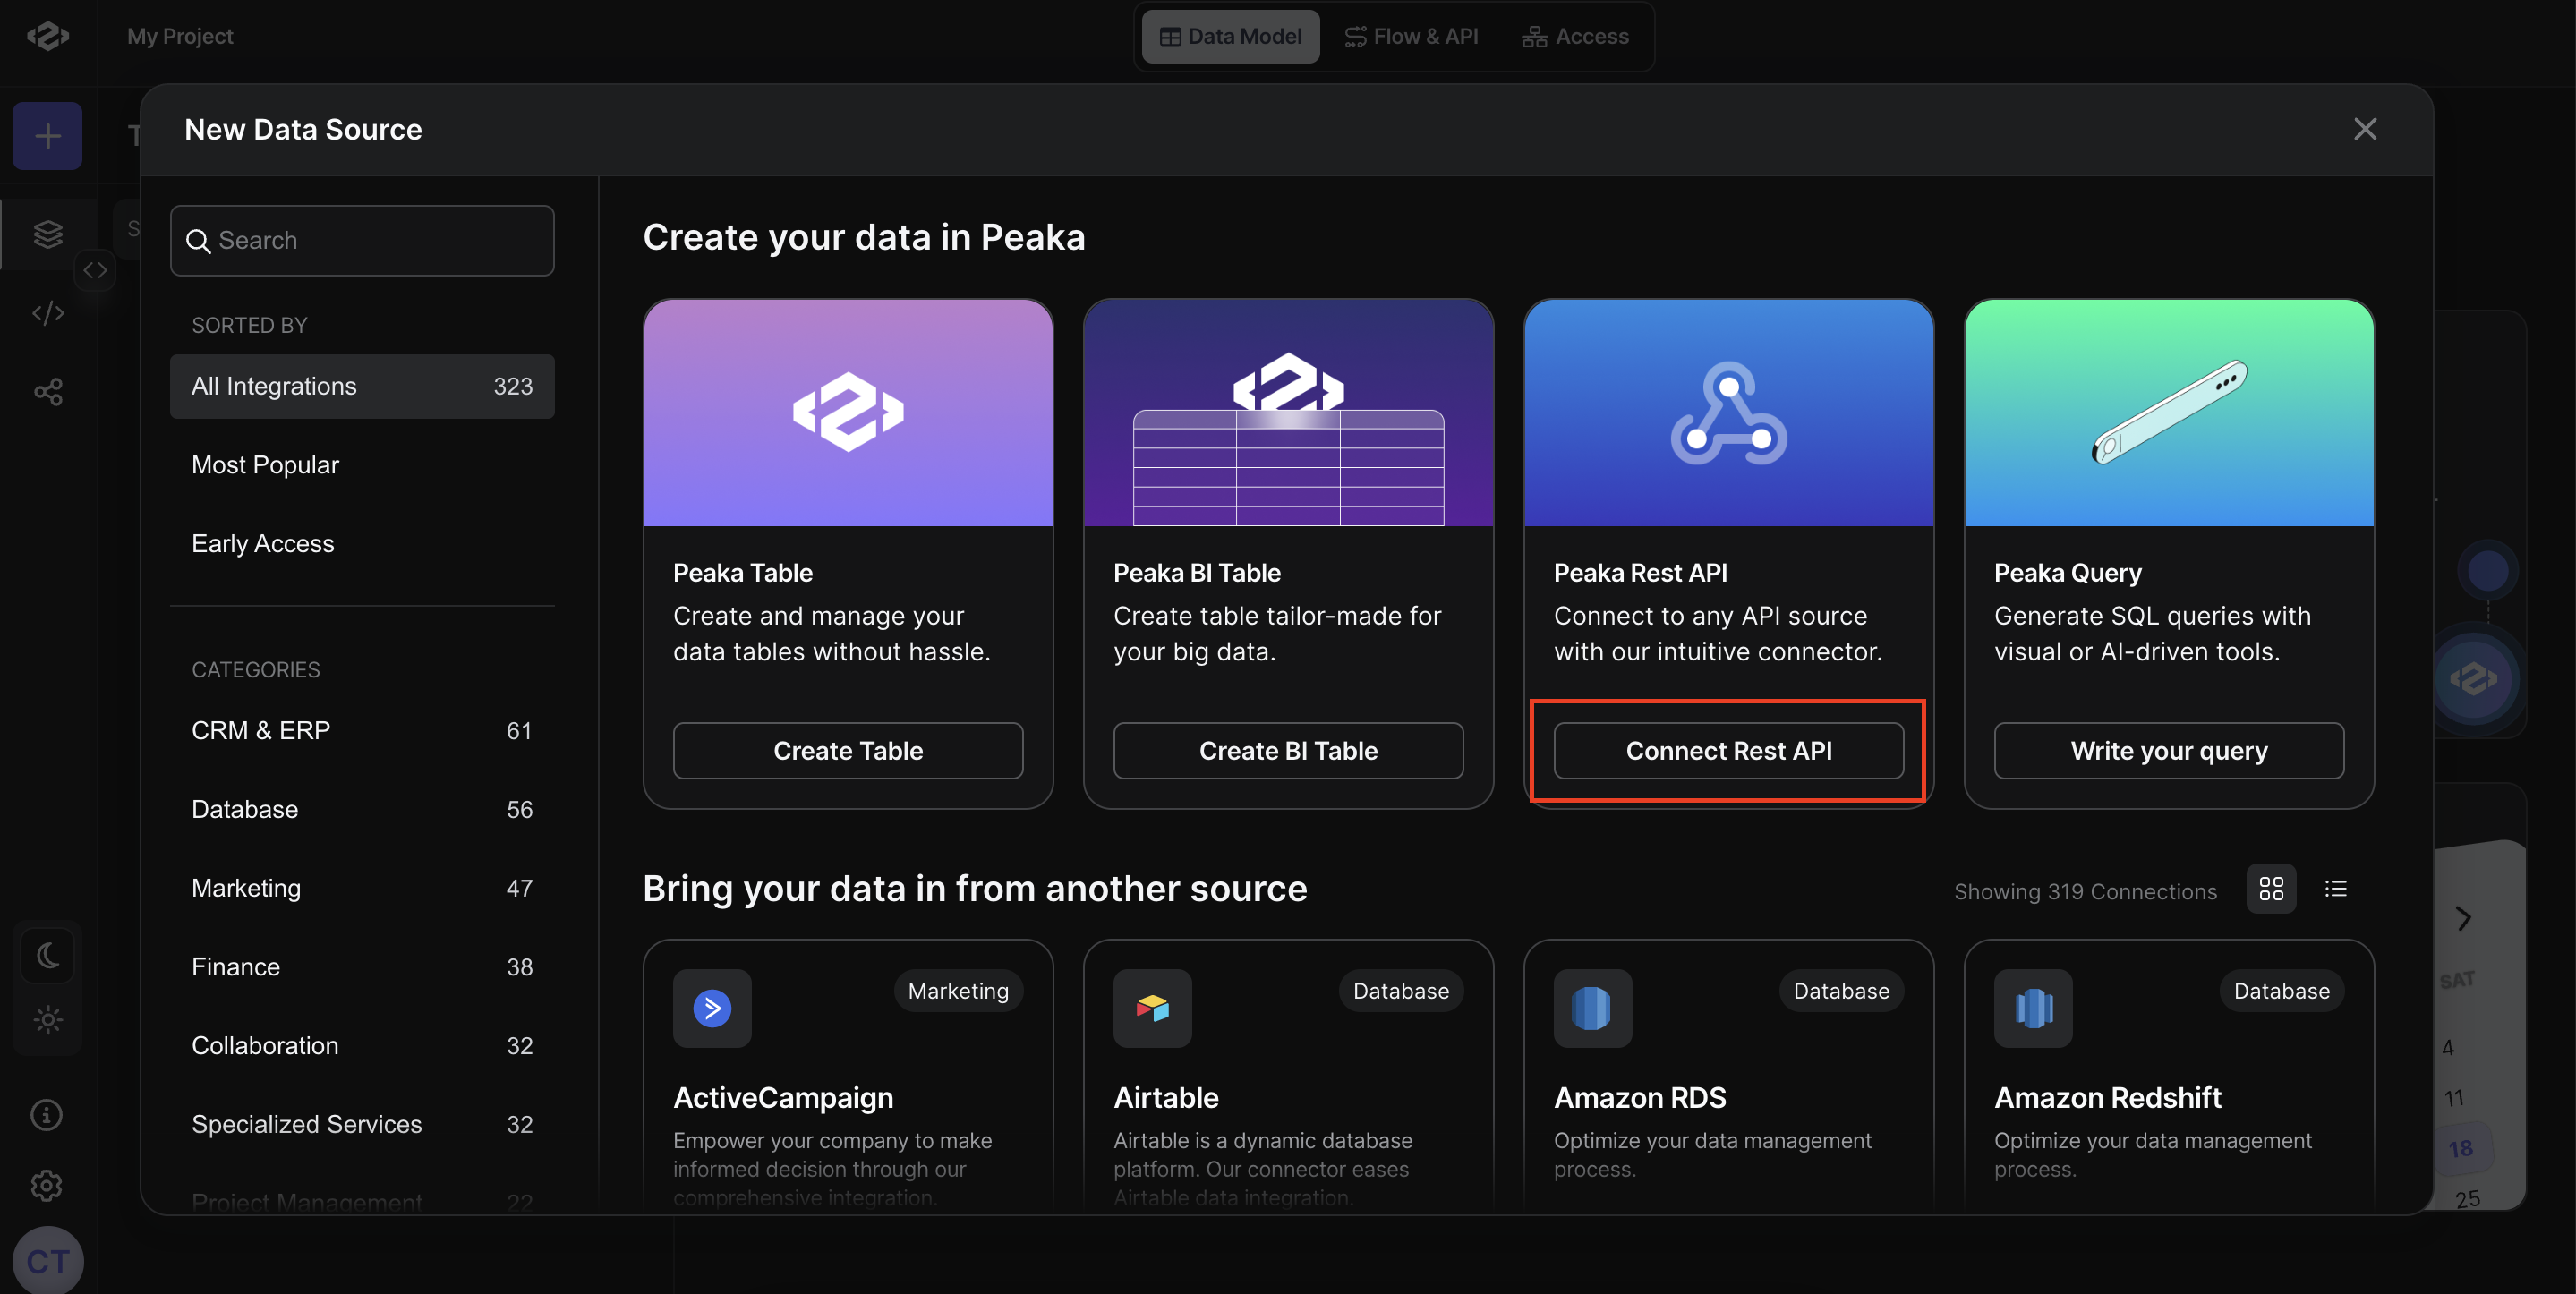
2. **Enter the API Details:** Enter the API details such as URL, parameters, headers, body, etc.
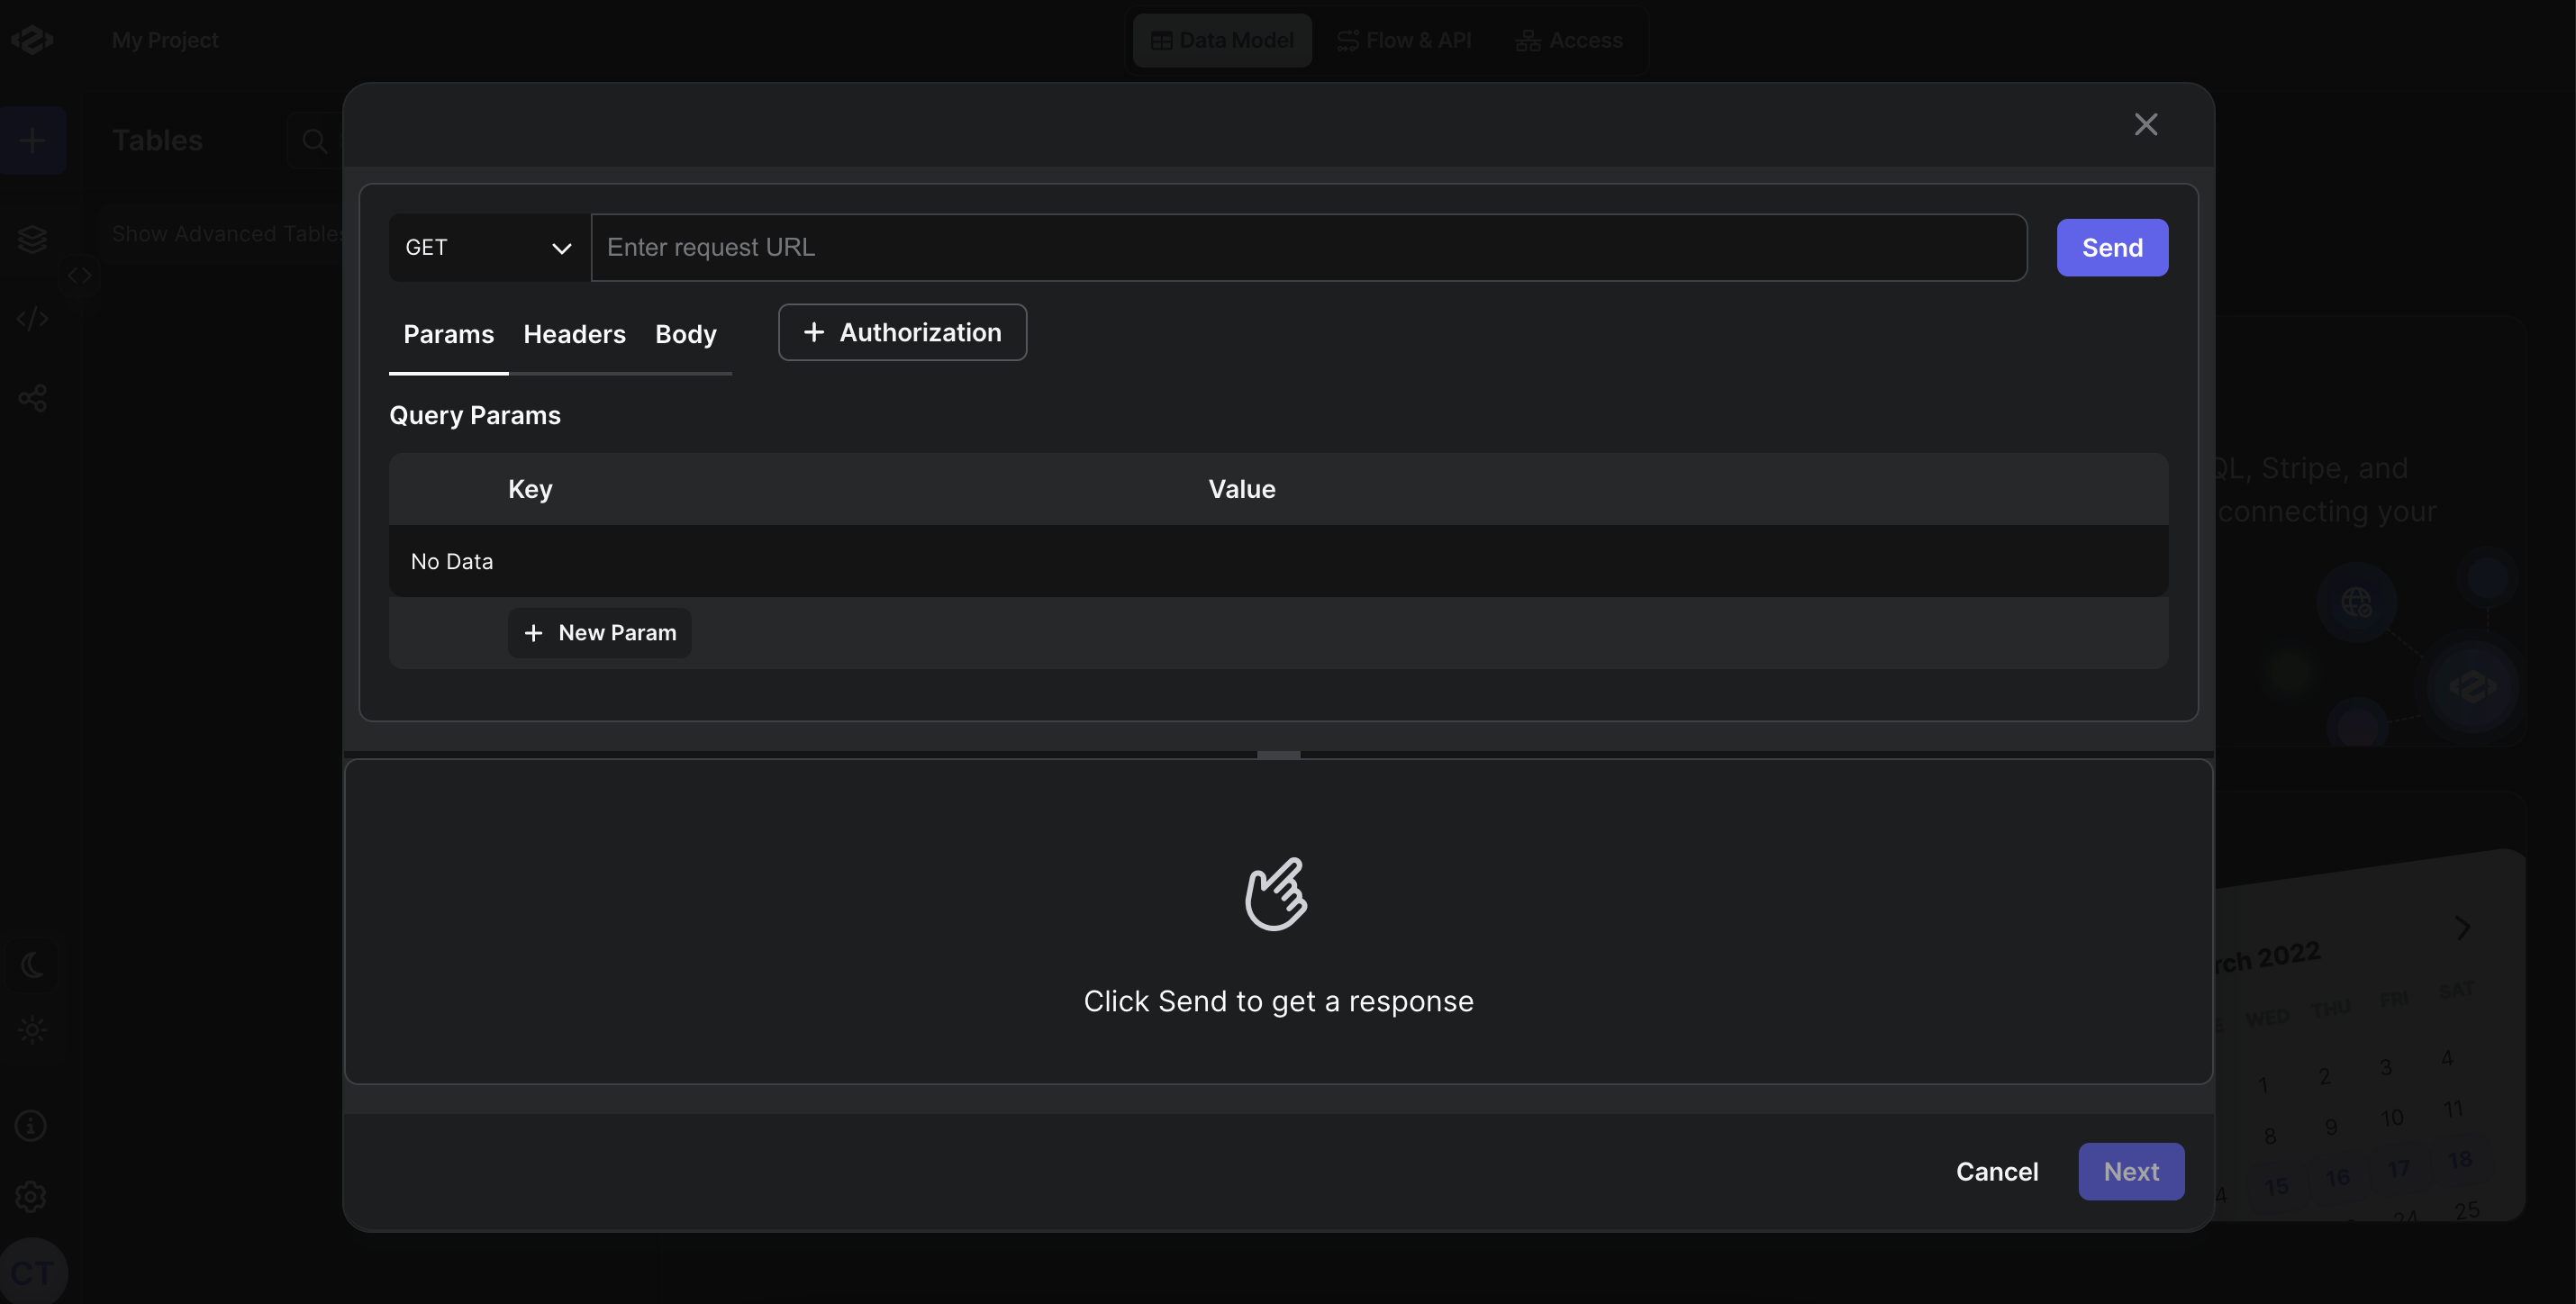
3. **Add Authentication:**
* To add authentication, click on the "Authentication" and it will open a modal to add authentication.
* Select the authentication type from the dropdown.
* Enter the authentication details such as username, password, token, etc.
* Click on the "Create" button to create the authentication.
4. **Run your API:** Click on the "Send" button to run your API.
5. **View the API Response:** Check your API response under the "Output" tab.
6. **Update Data Profile:**
* Click on the "Next" button, it will show the data profile of the API response.
* You can update your column names, types, comments, etc.
7. **Update Pagination Strategy:**
* Click on the "Next" button, it will show the pagination strategy of the API response.
* Select your pagination strategy from the dropdown by your API design.
8. **Update Parameters for Query:**
* Click on the "Next" button, it will show the parameters for query of the API response.
* You can add new parameters by clicking on the "New Parameter" button.
* You can update the parameter key, parameter type, data type, default value etc.
9. **Create Catalog:**
* Click on the "Create" button to create the catalog.
* Enter the fields such as catalog name, schema name, table name, etc.
* Click on the "Create" button to create the catalog.
That's it! You have created a Peaka REST API catalog with authentication.
On this page
* [Creating Peaka REST API catalog with authentication](https://www.peaka.com/docs/cookbook/how-to-create-peaka-rest-api-catalog-with-authentication/#creating-peaka-rest-api-catalog-with-authentication)
--- START: docs/cookbook/how-to-customize-embedded-ui-style/how-to-customize-embedded-ui-style.md ---
Documentation menu
[Home](/) / [Docs](/docs/) / How to customize Embedded Peaka UI
 Copy as Markdown
How to customize Embedded Peaka UI
==================================
Learn how you can update the Peaka's UI according to your application
Peaka has built-in design system that makes the application adoptable with different themes and views. This design system helps you to create different themes with using different colors and sizes. With this flexibility you can customize the embedded Peaka's view and make its look and feel as same as your application.
Peaka design system is built to offer flexibility through CSS variables, allowing you to adjust and personalize the appearance of your application easily.
Here is the reference of the customizable variables.
CSS Reference
=============
General Colors
--------------
There are two generic color codes in Peaka's Design System. Most of the UI components use these color options.
General colors have 5 different variants per class as `base`, `hover`, `dark`, `light`, `lighter`
### Primary Colors
You can change the primary colors of the Peaka with overriding following css variables
--primary-base: #5f62f0;
--primary-hover: #5457cd;
--primary-dark: #363885;
--primary-light: #bcbdf9;
--primary-lighter: #dadafc;
### Secondary Colors
You can override the secondary colors of the Peaka with following css variables.
--secondary-base: #9aa4be;
--secondary-hover: #444d66;
--secondary-dark: #2d354c;
--secondary-light: #e3e6eb;
--secondary-lighter: #eef0f3;
Severity Colors
---------------
There are 6 severity option in Peaka's Design System. These are `Success`, `Error`, `Warning`, `Informative`, `Neutral` and `Updating`.
Each severity option has 5 different variants like general colors.
### Success Colors
Success colors are used for express result for successful activities or harmless actions.
--success-base: #22c55e;
--success-hover: #16a34a;
--success-dark: #15803d;
--success-light: #bbf7d0;
--success-lighter: #dcfce7;
### Warning Colors
Warning colors are used in components that the user should be warn.
--warning-base: #f97316;
--warning-hover: #ea580c;
--warning-dark: #c2410c;
--warning-light: #fed7aa;
--warning-lighter: #ffedd5;
### Error Colors
Error colors are used for errors and actions that user should reconsider the action.
--error-base: #ef4444;
--error-hover: #dc2626;
--error-dark: #b91c1c;
--error-light: #fecaca;
--error-lighter: #fee2e2;
### Informative Colors
These colors are used for informations
--information-base: #3b82f6;
--information-hover: #326fd1;
--information-dark: #295bac;
--information-light: #abc9fb;
--information-lighter: #d0e1fd;
### Neutral Colors
These are also used for informations. These can be thought as secondary for iformative colors
--neutral-base: #9aa4be;
--neutral-hover: #444d66;
--neutral-dark: #2d354c;
--neutral-light: #e3e6eb;
--neutral-lighter: #eef0f3;
### Updating Colors
These colors are used in ongoing processes in Peaka. Such as caching process.
--updating-base: #14b8a6;
--updating-hover: #0e8174;
--updating-dark: #0b655b;
--updating-light: #9ae0d9;
--updating-lighter: #c7eeea;
Text Colors
-----------
These are the colors that used in text fields in Peaka.
--link-text-color: #f3f4f6;
--link-text-hover-color: #ffffff;
--header-color: #f9fafb;
--text-primary-color: #cfd1d7;
--text-secondary-color: #e5e7eb;
--text-label-color: #cfd1d7;
--text-disabled-color: #555659;
--text-placeholder-color: #75777a;
Border Colors
-------------
These are the border colors that used in form components, containers, cards etc.
--border-active-color: #f3f4f6;
--border-primary-strong-color: #555659;
--border-primary-color: #3f4043;
--border-strong-color: #f9fafb;
--border-soft-color: #141415;
--border-secondary-color: #27282a;
--border-soft-secondary-color: #27282a;
--border-error-color: #ef4444;
--border-success-color: #22c55e;
--border-warning-color: #f97316;
--border-information-color: #3b82f6;
--border-neutral-color: #9aa4be;
Background Colors
-----------------
Peaka uses 5 different background token in its Design System. You can override these tokens to implement your own look and feel
--background-default: #0d0d0d;
--background-primary: #141415;
--background-secondary: #1d1e1f;
--background-tertiary: #27282a;
--background-offline: #3f4043;
Fonts
-----
### Font Family
You can use your own font families via overrride this variable.
Note: It should be imported the font families that you mentioned in the font family variable.
--font-family: Inter, -apple-system, BlinkMacSystemFont, Segoe UI, Roboto, Helvetica, Arial, sans-serif, Apple Color Emoji, Segoe UI Emoji, Segoe UI Symbol;
### Heading Font Sizes
Peaka Design System allows you to override heading font sizes. These variables are used for heading components.
--heading-xxs-size: 0.75rem;
--heading-xs-size: 0.875rem;
--heading-sm-size: 1rem;
--heading-md-size: 1.25rem;
--heading-lg-size: 1.5rem;
--heading-xl-size: 1.75rem;
--heading-xxl-size: 2.25rem;
--heading-xxs-line-height: 1rem;
--heading-xs-line-height: 1.125rem;
--heading-sm-line-height: 1.25rem;
--heading-md-line-height: 1.5rem;
--heading-lg-line-height: 1.75rem;
--heading-xl-line-height: 2rem;
--heading-xxl-line-height: 2.5rem;
### Label Font Sizes
These font size variables are used for labels, descriptions, component's labels (such as button) etc.
--label-xs-size: 0.625rem;
--label-sm-size: 0.75rem;
--label-md-size: 0.875rem;
--label-lg-size: 1rem;
--label-xl-size: 1.25rem;
--label-xs-line-height: 0.75rem;
--label-sm-line-height: 0.875rem;
--label-md-line-height: 1rem;
--label-lg-line-height: 1.125rem;
--label-xl-line-height: 1.375rem;
### Body Font Sizes
These font sizes are used for general informations and explanations in the Peaka UI.
--body-xs-size: 0.625rem;
--body-sm-size: 0.75rem;
--body-md-size: 0.875rem;
--body-lg-size: 1rem;
--body-xl-size: 1.25rem;
--body-xs-line-height: 0.875rem;
--body-sm-line-height: 1rem;
--body-md-line-height: 1.25rem;
--body-lg-line-height: 1.5rem;
--body-xl-line-height: 1.875rem;
### Font Weight
These variables set the font weight in all system. It can affect all components in the system.
--font-thin: 100;
--font-extralight: 200;
--font-light: 300;
--font-normal: 400;
--font-medium: 500;
--font-semibold: 600;
--font-bold: 700;
--font-extrabold: 800;
--font-black: 900;
Sizes
-----
### Padding
These are system wide padding sizes. You can override the padding values in order to apply your design system's your whitespace rules.
--padding-none: 0;
--padding-3xs: 0.125rem;
--padding-2xs: 0.25rem;
--padding-xs: 0.375rem;
--padding-sm: 0.5rem;
--padding-md: 0.625rem;
--padding-lg: 0.75rem;
--padding-xl: 1rem;
--padding-2xl: 1.5rem;
--padding-3xl: 2rem;
--padding-4xl: 2.5rem;
--padding-5xl: 3rem;
### Radius
These are the default radius values of Peaka Design System. You can override them to apply your radius rules.
--radius-xs: 0.25rem;
--radius-sm: 0.375rem;
--radius-md: 0.5rem;
--radius-lg: 0.75rem;
--radius-xl: 1rem;
--radius-2xl: 1.25rem;
--radius-3xl: 1.5rem;
Shadows
-------
These are the basic shadow rules in Cards, Form components, Tooltip's etc.
--shadow-sm: 0 8px 16px 0 rgba(71, 74, 79, 0.12);
--shadow-md: 0 8px 12px 0 rgba(26, 27, 28, 0.16);
--shadow-lg: 0 4px 16px 0 rgba(69, 72, 74, 0.24);
--shadow-xl: 0 8px 12px 0 rgba(42, 44, 49, 0.36);
--tooltip-shadow: 0 2px 2px 0 rgba(59, 59, 59, 0.22);
--input-shadow: 0 0 0 3px #27282a;
--avatar-shadow: inset 0 -4px 8px 0 rgba(31, 34, 38, 0.2);
--border-shadow: 0 0 1px 0 rgba(90, 90, 107, 0.64);
Gradients
---------
These gradients are used in system wide. You can override gradient rule(s) with these variables
--gradient-01: linear-gradient(180deg, #2c3271 0%, #5a1f9d 100%);
--gradient-02: linear-gradient(180deg, #e265de 0%, #33cbb2 100%);
--gradient-03: linear-gradient(180deg, #208be2 0%, #3838bd 100%);
--gradient-04: linear-gradient(180deg, #111111 0%, #333333 100%);
--gradient-05: linear-gradient(180deg, #000b58 0%, #9b7ebd 100%);
--gradient-06: linear-gradient(360deg, #0d92f4 0%, #00ff9c 100%);
--gradient-07: linear-gradient(180deg, #ff6500 0%, #6256ca 96%);
--gradient-08: linear-gradient(360deg, #00712d 0%, #86ab89 100%);
--gradient-09: linear-gradient(180deg, #ffa62f 0%, #f97300 100%);
--gradient-10: linear-gradient(360deg, #8576ff 0%, #bc7fcd 100%);
On this page
* [CSS Reference](https://www.peaka.com/docs/cookbook/how-to-customize-embedded-ui-style/#css-reference)
* [General Colors](https://www.peaka.com/docs/cookbook/how-to-customize-embedded-ui-style/#general-colors)
* [Severity Colors](https://www.peaka.com/docs/cookbook/how-to-customize-embedded-ui-style/#severity-colors)
* [Text Colors](https://www.peaka.com/docs/cookbook/how-to-customize-embedded-ui-style/#text-colors)
* [Border Colors](https://www.peaka.com/docs/cookbook/how-to-customize-embedded-ui-style/#border-colors)
* [Background Colors](https://www.peaka.com/docs/cookbook/how-to-customize-embedded-ui-style/#background-colors)
* [Fonts](https://www.peaka.com/docs/cookbook/how-to-customize-embedded-ui-style/#fonts)
* [Sizes](https://www.peaka.com/docs/cookbook/how-to-customize-embedded-ui-style/#sizes)
* [Shadows](https://www.peaka.com/docs/cookbook/how-to-customize-embedded-ui-style/#shadows)
* [Gradients](https://www.peaka.com/docs/cookbook/how-to-customize-embedded-ui-style/#gradients)
--- START: docs/cookbook/how-to-filter-your-data-with-visual-filter/how-to-filter-your-data-with-visual-filter.md ---
Documentation menu
[Home](/) / [Docs](/docs/) / How to filter your data with a visual filter
 Copy as Markdown
How to filter your data with a visual filter
============================================
Learn how you can effectively filter your data using visual filters in Peaka
This article explains how you can filter your data using visual filters in Peaka. We'll use an example of filtering a Peaka Table to illustrate the process.
Filtering Data with Visual Filters
----------------------------------
As an example, we'll filter a Peaka Table named "Food" that contains information about different food items, including their name, quantity, and company ID.
Follow these steps to filter your data using visual filters:
1. **Open the filter modal:** Click the "Filter" button above the table. This action opens a modal where you can define your filter criteria.
2. **Define the filter criteria:** In the modal, locate the "WHERE" input field. Here, you can define your filtering criteria to narrow down the data as per your requirements. Additionally, you can use the "ORDER BY" option to sort the data.
3. **Apply the filter:** Once you've configured your filter criteria, click the "Filter" button at the bottom of the modal. This action applies the filter and sorts your data based on your specified criteria.
By following these steps, you can effectively filter your data using the visual filters in Peaka. This feature allows you to quickly and intuitively refine your data to access the specific information you need.
On this page
* [Filtering Data with Visual Filters](https://www.peaka.com/docs/cookbook/how-to-filter-your-data-with-visual-filter/#filtering-data-with-visual-filters)
--- START: docs/cookbook/how-to-generate-api-keys/how-to-generate-api-keys.md ---
Documentation menu
[Home](/) / [Docs](/docs/) / How to generate API Key for your project
 Copy as Markdown
How to generate API Key for your project
========================================
Learn how you can generate API Keys in your projects.
1\. Navigate to the Settings Page
---------------------------------
Users can generate API Keys on the settings page. Follow these steps:
* Click on the icon as shown in the image below:
2\. Select API Keys Tab
-----------------------
Once on the settings page:
* Navigate to the API Keys tab from the sidebar.
3\. Generate Your API Key
-------------------------
To generate your first API Key:
* Click either the "Add First API Key" button or the "API Key" button. This will open a modal.
* Enter your API Key name.
* Click on the "Generate" button.
4\. Copy and Use Your API Key
-----------------------------
Your API Key is now created. Simply:
* Copy the generated API Key.
* Use it wherever you need.
That's it. You can see your API Keys and edit them.
On this page
* [1\. Navigate to the Settings Page](https://www.peaka.com/docs/cookbook/how-to-generate-api-keys/#1-navigate-to-the-settings-page)
* [2\. Select API Keys Tab](https://www.peaka.com/docs/cookbook/how-to-generate-api-keys/#2-select-api-keys-tab)
* [3\. Generate Your API Key](https://www.peaka.com/docs/cookbook/how-to-generate-api-keys/#3-generate-your-api-key)
* [4\. Copy and Use Your API Key](https://www.peaka.com/docs/cookbook/how-to-generate-api-keys/#4-copy-and-use-your-api-key)
--- START: docs/cookbook/how-to-implement-row-level-security/how-to-implement-row-level-security.md ---
Documentation menu
[Home](/) / [Docs](/docs/) / How to implement row-level security
 Copy as Markdown
How to implement row-level security
===================================
Learn how to restrict which rows each user can see in Peaka using the current\_user\_props() SQL function.
Row-level security means different users see different rows of the same table — a sales rep sees only their own deals, a regional manager sees only their region. In Peaka you implement this with the `current_user_props()` SQL function: it returns properties of the user running the query, so a single saved query can filter itself for whoever executes it.
How it works
------------
Every query in Peaka runs with the identity of the user who executes it — whether it comes from the Studio, the Query API, a BI tool, or an embedded app. The `current_user_props(key)` function exposes that identity inside SQL:
Key
Returns
`'id'` or `'user'`
The user's unique ID
`'email'`
The user's email address
`'username'`
The user's username
`'firstname'` / `'first_name'`
The user's first name
`'lastname'` / `'last_name'`
The user's last name
`'project'`
The current project ID
All keys return a `varchar`. If the property is not available — or the query runs without a user identity — the function returns an empty string, so identity-based filters simply match no rows rather than exposing data.
1\. Test the function
---------------------
Run this in the SQL editor to see your own identity:
SELECT current_user_props('email') AS email,
current_user_props('firstname') AS first_name,
current_user_props('id') AS user_id
email
first\_name
user\_id
jane.doe@acme.com
Jane
a72a80ed-7c1c-4847-8a36-8a07d506afcf
2\. Write a self-filtering query
--------------------------------
Add a `WHERE` clause that compares a column against the current user. For a CRM table where every deal has an `owner_email` column:
SELECT deal_id, deal_name, amount, stage
FROM crm.public.deals
WHERE owner_email = current_user_props('email')
When Jane runs this query she gets only her deals; when another rep runs the _same_ query, they get theirs. No per-user copies, no application-side filtering.
3\. Save and share the query
----------------------------
Save the statement as a Peaka query and share _the query_ with your users instead of the underlying table. The filter travels with the query, and each consumer — in the Studio, over the Query API, or in an embedded app — is automatically limited to their own rows.
Row-level security lives in the query, not on the table. A user who can query the base table directly can bypass the filter — so grant your consumers access to the saved query, not to the raw catalog table.
4\. Use a mapping table for indirect relationships
--------------------------------------------------
Often your data doesn't contain user emails directly — deals belong to _regions_, and users are assigned to regions elsewhere. Model that with a small mapping table (a Peaka Table works well):
**user\_regions**
user\_email
region
jane.doe@acme.com
EMEA
john.smith@acme.com
AMER
Then join through it in your shared query:
SELECT d.deal_id, d.deal_name, d.amount, d.region
FROM crm.public.deals d
WHERE d.region IN (
SELECT r.region
FROM "peaka"."table"."user_regions" r
WHERE r.user_email = current_user_props('email')
)
Access management now becomes data management: to change what someone sees, edit a row in `user_regions` — no query changes needed. A user with no row in the mapping table sees nothing.
Things to keep in mind
----------------------
* `current_user_props()` always returns `varchar`. Cast when comparing against numeric columns: `CAST(current_user_props('id') AS ...)` or cast the column instead.
* An unknown key returns an empty string rather than an error — double-check key spelling, since a typo silently filters out all rows.
* User properties such as email and name are cached for a few minutes, so profile changes may take up to five minutes to be reflected in query results.
* Row-level security controls _which rows_ a user sees. To control _what's inside_ sensitive columns, combine it with [tag-based column masking](/docs/cookbook/how-to-mask-sensitive-columns-with-tags).
On this page
* [How it works](https://www.peaka.com/docs/cookbook/how-to-implement-row-level-security/#how-it-works)
* [1\. Test the function](https://www.peaka.com/docs/cookbook/how-to-implement-row-level-security/#1-test-the-function)
* [2\. Write a self-filtering query](https://www.peaka.com/docs/cookbook/how-to-implement-row-level-security/#2-write-a-self-filtering-query)
* [3\. Save and share the query](https://www.peaka.com/docs/cookbook/how-to-implement-row-level-security/#3-save-and-share-the-query)
* [4\. Use a mapping table for indirect relationships](https://www.peaka.com/docs/cookbook/how-to-implement-row-level-security/#4-use-a-mapping-table-for-indirect-relationships)
* [Things to keep in mind](https://www.peaka.com/docs/cookbook/how-to-implement-row-level-security/#things-to-keep-in-mind)
--- START: docs/cookbook/how-to-manage-partner-api-key/how-to-manage-partner-api-key.md ---
Documentation menu
[Home](/) / [Docs](/docs/) / How to Manage Your Partner API Key
 Copy as Markdown
How to Manage Your Partner API Key
==================================
This guide explains how to create, manage, and update Partner API Keys in Peaka.
This guide will show you how to create, manage, and update your Partner API Key within the Peaka platform.
The Developer section is available to all Peaka users. You can find it in the sidebar on the homepage.
### Creating a Partner API Key
1. Navigate to the [Developer](https://peaka.studio/home/advanced-settings) section.
2. Click on the Partner API Key button to open a dialog box.
3. Fill in the form by entering your desired API Key Name.
4. Click on the Create button.
Your Partner API Key will be displayed in the dialog box, where you can copy and use it.
### Updating Status
By default, when a Partner API Key is created, its status is set to active. If you wish to deactivate the key, toggle the switch to the off position.
### Editing a Partner API Key
1. Click on the three dots icon of Partner API Key which you want to edit.
2. Select the Edit Name button, which will open a dialog box.
3. Enter the new API Key Name and click on the Update button.
Your API Key name will be updated accordingly.
### Deleting a Partner API Key
1. Click on the three dots icon of Partner API Key which you want to delete.

2. Click the Delete button.
Your Partner API Key will be deleted.
On this page
* [Creating a Partner API Key](https://www.peaka.com/docs/cookbook/how-to-manage-partner-api-key/#creating-a-partner-api-key)
* [Updating Status](https://www.peaka.com/docs/cookbook/how-to-manage-partner-api-key/#updating-status)
* [Editing a Partner API Key](https://www.peaka.com/docs/cookbook/how-to-manage-partner-api-key/#editing-a-partner-api-key)
* [Deleting a Partner API Key](https://www.peaka.com/docs/cookbook/how-to-manage-partner-api-key/#deleting-a-partner-api-key)
--- START: docs/cookbook/how-to-mask-sensitive-columns-with-tags/how-to-mask-sensitive-columns-with-tags.md ---
Documentation menu
[Home](/) / [Docs](/docs/) / How to mask sensitive columns with tags
 Copy as Markdown
How to mask sensitive columns with tags
=======================================
Learn how to protect PII and other sensitive data in Peaka by tagging columns and applying masking rules per user group.
Column masking lets you hide or transform sensitive values — emails, phone numbers, national IDs, salaries — without changing the underlying data or writing a separate query for every audience. You classify columns with **tags**, and each tag carries **mask rules** that decide what each user group sees. Masking is enforced at query time by Peaka's query engine, so it applies everywhere the data is consumed: the Peaka Studio, the Query API, BI tools, and embedded apps.
How it works
------------
Three building blocks work together:
* **Tags** classify your data (for example `PII`, `Financial`, `Confidential`). Tags are defined once at the organization level and can be attached to any number of columns across your projects and catalogs.
* **Masks** define _how_ a value is transformed. You can use Peaka's predefined masks or create your own with a SQL expression.
* **Mask rules** connect the two: for a given tag, a rule says which **group** of users sees the data through _which_ mask.
When a query touches a tagged column, Peaka checks the querying user's groups. If one of the tag's rules targets a group the user belongs to, the column is rewritten through that mask on the fly. If no rule matches — or the tag is inactive — the column is returned **unmasked**.
There is no implicit "everyone" rule: a user who is in none of the tag's rule groups sees raw values. To mask data by default, create a group that contains all regular members and give it a rule. Avoid putting the same user in multiple rule groups of one tag — only a single rule is applied.
1\. Open the Tags page
----------------------
Tags are managed at the organization level. In Peaka Studio's home screen, find the **ORGANIZATION** section in the left sidebar and open **Tags**. This brings you to the _Tag List_ page.
Mask rules target user groups, which are managed on the same organization sidebar under **General → Groups** (Organization Settings). Create your groups — for example `support-team` — and add members before setting up rules.
2\. Pick a mask (or create a custom one)
----------------------------------------
Peaka ships with predefined masks that cover the most common cases:
Mask
What it does
Example (`jane.doe99@acme.com`)
Redact
Replaces letters with `X`/`x` and digits with `0`
`xxxx.xxx00@xxxx.xxx`
Partial Mask Show Last Four
Masks everything except the last four characters
`XXXXXXXXXXXXXXX.com`
Partial Mask Show First Four
Masks everything except the first four characters
`janeXXXXXXXXXXXXXXX`
Nullify
Replaces the value with `NULL`
`NULL`
Unmasked
No masking — useful for exempting a group from a tag's rules
`jane.doe99@acme.com`
Date Show Only Year
Truncates a date to its year
`2024-01-01` (from `2024-08-15`)
If none of these fit, create a **custom mask** with a SQL expression — either from the **Manage Custom Masks** button on the Tag List page, or directly from the _Mask Type_ dropdown's **\+ Custom Mask** option while editing a rule. A custom mask has a _Name_, _Description_, and _Expression_. Use the `{col}` placeholder for the column and `{type}` for its data type — Peaka substitutes them at query time. For example, a mask that keeps only the email domain:
cast(concat('***@', split_part({col}, '@', 2)) as {type})
3\. Create a tag with mask rules
--------------------------------
On the Tag List page click **New Tag**, give it a _Name_ (for example `PII`) and optionally a _Description_, and add rules with **\+ New Rule**. Each rule pairs a **Mask Type** with a **Group**. A typical setup:
* **Group: support-team** → _Redact_ — support agents work with masked values.
* **Group: contractors** → _Nullify_ — external contractors see nothing.
* Users in neither group — say, your data team — keep seeing raw values, since no rule targets them.
Keep the tag's **Status** toggle on — deactivating a tag switches off all of its masking at once, which is useful for testing.
4\. Assign the tag to columns
-----------------------------
Tags are attached to columns inside your project. Open the table in the **Data Model** view and click **Manage Column Tags** in the table toolbar. Add a mapping with **\+ New Column Rule**, pick the _Column_ and the _Tag_, and **Save** — for example the `email` and `phone` columns of your CRM catalog. A column can carry one tag; the same tag can be reused across any number of tables and catalogs.
5\. Verify the masking
----------------------
Run a query on the tagged table as different users:
SELECT id, full_name, email, phone FROM crm.public.customers LIMIT 5
A member of the _support-team_ group sees the masked version, while users outside the rule groups see raw values:
id
full\_name
email
phone
1
Xxxx Xxx
xxxx.xxx00@xxxx.xxx
000-000-0000
The change takes effect immediately — the next query against the tagged column is masked, with no refresh or restart needed.
Things to keep in mind
----------------------
* Masking is applied by the query engine, so it also covers downstream access paths — the Query API, BI tool connections, and embedded Peaka.
* Rules are group-based. If none of the querying user's groups has a rule for the tag, the column comes back unmasked — design your groups so that everyone who should see masked data is covered by a rule.
* Custom mask expressions run inside the query, so any Peaka SQL function is available in them.
* Masks transform values but do not remove rows. To control _which rows_ a user can see, combine masking with [row-level security](/docs/cookbook/how-to-implement-row-level-security).
On this page
* [How it works](https://www.peaka.com/docs/cookbook/how-to-mask-sensitive-columns-with-tags/#how-it-works)
* [1\. Open the Tags page](https://www.peaka.com/docs/cookbook/how-to-mask-sensitive-columns-with-tags/#1-open-the-tags-page)
* [2\. Pick a mask (or create a custom one)](https://www.peaka.com/docs/cookbook/how-to-mask-sensitive-columns-with-tags/#2-pick-a-mask-or-create-a-custom-one)
* [3\. Create a tag with mask rules](https://www.peaka.com/docs/cookbook/how-to-mask-sensitive-columns-with-tags/#3-create-a-tag-with-mask-rules)
* [4\. Assign the tag to columns](https://www.peaka.com/docs/cookbook/how-to-mask-sensitive-columns-with-tags/#4-assign-the-tag-to-columns)
* [5\. Verify the masking](https://www.peaka.com/docs/cookbook/how-to-mask-sensitive-columns-with-tags/#5-verify-the-masking)
* [Things to keep in mind](https://www.peaka.com/docs/cookbook/how-to-mask-sensitive-columns-with-tags/#things-to-keep-in-mind)
--- START: docs/cookbook/how-to-materialize-a-query-with-the-peaka-api/how-to-materialize-a-query-with-the-peaka-api.md ---
Documentation menu
[Home](/) / [Docs](/docs/) / How to Materialize a Query with the Peaka API
 Copy as Markdown
How to Materialize a Query with the Peaka API
=============================================
Materialize an existing query, schedule automatic refreshes, and query the materialized data using the Peaka Partner API.
Materializing a query stores its result as a physical table that is refreshed on demand or on a schedule. Reads against the materialized table are fast and predictable, because they no longer hit the underlying connectors — which makes materialization the right tool for dashboards, reports, and pipelines built on heavy federated queries.
This guide walks through the full workflow: materializing an existing query, scheduling refreshes, querying the result, keeping it in sync with its source, and monitoring refresh runs.
### Prerequisites
* An API key — either a [Partner API Key](/docs/cookbook/how-to-manage-partner-api-key) or a [Project API Key](/docs/cookbook/how-to-generate-api-keys) created for the project. See [Authentication](/docs/api-reference/authentication) for the difference.
* Your Project ID.
The examples below use the US zone base URL `https://partner.peaka.studio/api/v1`. If your organization is in the EU zone, use `https://eu.partner.peaka.studio/api/v1` instead. See [Servers](/docs/api-reference/servers) for details.
### How materialization works
Before calling the API, it helps to know five things:
1. **A materialized query is a separate query object** with `queryType: "MATERIALIZED"`. When you materialize an existing query, the original query is left untouched — you get a new query alongside it.
2. **The first materialization runs immediately.** Creating a materialized query executes it right away and stores the result; you do not need to trigger the first run yourself.
3. **The result lives in the `mtquery` schema.** A materialized query named `samplequery` is queryable as `"peaka"."mtquery"."samplequery"`.
4. **A schedule keeps it fresh.** Attach a `schedule` object to refresh at regular intervals or on a cron expression. Without a schedule, the data stays as of the last (manual) refresh.
5. **Materializing by reference takes a snapshot.** When you pass `inputQueryRefId`, Peaka resolves the referenced query's SQL at that moment and stores it as the new query's own `inputQuery`. Later edits to the source query do not propagate automatically — see [Keep it in sync with the source](https://www.peaka.com/docs/cookbook/how-to-materialize-a-query-with-the-peaka-api/#keep-it-in-sync-with-the-source).
### Materialize an existing query
This is the API equivalent of the **Advanced → Materialize** flow in Peaka Studio. Call [Create Query](/docs/api-reference/) with `queryType: "MATERIALIZED"` and the id of the source query in `inputQueryRefId`. You do not need to send `inputQuery` — the SQL is taken from the source query.
The example below materializes an existing query and refreshes it twice a day:
curl --request POST \
--url https://partner.peaka.studio/api/v1/data/projects/{projectId}/queries \
--header 'Authorization: Bearer ' \
--header 'Content-Type: application/json' \
--data '{
"displayName": "dailyRevenueMaterialized",
"queryType": "MATERIALIZED",
"inputQueryRefId": "709922802836177297",
"schedule": {
"type": "interval",
"repeatDuration": "PT12H"
}
}'
const options = {
method: "POST",
headers: {
Authorization: "Bearer ",
"Content-Type": "application/json",
},
body: JSON.stringify({
displayName: "dailyRevenueMaterialized",
queryType: "MATERIALIZED",
inputQueryRefId: "709922802836177297",
schedule: { type: "interval", repeatDuration: "PT12H" },
}),
};
fetch(
"https://partner.peaka.studio/api/v1/data/projects/{projectId}/queries",
options,
)
.then((response) => response.json())
.then((response) => console.log(response))
.catch((err) => console.error(err));
import requests
url = "https://partner.peaka.studio/api/v1/data/projects/{projectId}/queries"
headers = {
"Authorization": "Bearer ",
"Content-Type": "application/json",
}
payload = {
"displayName": "dailyRevenueMaterialized",
"queryType": "MATERIALIZED",
"inputQueryRefId": "709922802836177297",
"schedule": {"type": "interval", "repeatDuration": "PT12H"},
}
response = requests.post(url, headers=headers, json=payload)
print(response.text)
The response contains the new query. Note that `inputQuery` holds the snapshot of the source query's SQL that was resolved at create time, and that `inputQueryRefId` is not part of the response — the reference is consumed, not stored:
{
"id": "709922802836177298",
"displayName": "dailyRevenueMaterialized",
"name": "dailyrevenuematerialized",
"inputQuery": "SELECT * FROM \"mycatalog\".\"payment\".\"charges\"",
"queryType": "MATERIALIZED",
"schedule": {
"type": "interval",
"repeatDuration": "PT12H",
"expression": "PT12H"
}
}
The first materialization has already run by the time this response returns, so the data is immediately queryable.
You can also create a materialized query from scratch — send `inputQuery` with the SQL instead of `inputQueryRefId`:
{
"displayName": "dailyRevenueMaterialized",
"inputQuery": "SELECT * FROM \"mycatalog\".\"payment\".\"charges\"",
"queryType": "MATERIALIZED",
"schedule": {
"type": "interval",
"repeatDuration": "PT12H"
}
}
### Convert a query in place
If you want to turn an existing `PLAIN` query into a materialized one — rather than creating a new query next to it — call [Update Query](/docs/api-reference/) on the query itself with `queryType: "MATERIALIZED"`:
curl --request PUT \
--url https://partner.peaka.studio/api/v1/data/projects/{projectId}/queries/{queryId} \
--header 'Authorization: Bearer ' \
--header 'Content-Type: application/json' \
--data '{
"queryType": "MATERIALIZED",
"schedule": {
"type": "interval",
"repeatDuration": "P1D"
}
}'
Fields omitted from an update keep their current values, so this request only changes the query type and attaches a schedule. After the conversion the query is materialized in place — there is no separate `PLAIN` query anymore.
### Schedule refreshes
The `schedule` object supports three types:
`type`
Fields
Behavior
`interval`
`repeatDuration` (ISO-8601 duration)
Refreshes at a fixed interval, e.g. every 6 hours.
`cron`
`cronExpression`, optional `timezone`
Refreshes on a cron schedule, evaluated in the given timezone.
`none`
—
No automatic refresh. Equivalent to omitting `schedule`.
`repeatDuration` is an ISO-8601 duration. Common values:
Value
Meaning
`PT1H`
Every hour
`PT6H`
Every 6 hours
`PT12H`
Twice a day
`P1D`
Once a day
`cronExpression` is a UNIX cron expression (`minute hour day-of-month month day-of-week`), and `timezone` is an IANA timezone name (defaults to UTC):
{
"schedule": {
"type": "cron",
"cronExpression": "0 6 * * *",
"timezone": "Europe/Istanbul"
}
}
You can change or remove the schedule at any time with [Update Query](/docs/api-reference/) — send a new `schedule` object (or `{ "type": "none" }` to stop automatic refreshes).
### Query the materialized data
The materialized result is exposed in the `mtquery` schema of the `peaka` catalog, under the query's `name` (the normalized form of `displayName` returned in the response):
SELECT * FROM "peaka"."mtquery"."dailyrevenuematerialized"
This reads the stored table directly — it is fast and does not touch the underlying connectors. You can run it anywhere you run SQL against your project, for example with the [Execute Query](/docs/api-reference/) endpoint, a [JDBC driver](/docs/db-drivers/java), or from other Peaka queries.
`"peaka"."query".""` addresses a query's logical definition, while `"peaka"."mtquery".""` addresses the stored, materialized result.
### Keep it in sync with the source
Materializing by reference takes a **snapshot** of the source query's SQL. Scheduled and manual refreshes re-run that snapshot against live data — so the _data_ stays fresh — but if you later edit the _SQL_ of the source query, the materialized query keeps computing the old SQL.
To re-sync the materialized query with its source, send the reference again with [Update Query](/docs/api-reference/):
curl --request PUT \
--url https://partner.peaka.studio/api/v1/data/projects/{projectId}/queries/{materializedQueryId} \
--header 'Authorization: Bearer ' \
--header 'Content-Type: application/json' \
--data '{
"queryType": "MATERIALIZED",
"inputQueryRefId": "709922802836177297"
}'
This resolves the source query's SQL again, stores the fresh snapshot, and rebuilds the materialized table.
### Monitor, refresh, and cancel
Materialized queries have dedicated endpoints for operating on refreshes:
* [List Materialized Query Statuses](/docs/api-reference/) — refresh status, schedule, and next execution time for all materialized queries in a project.
* [Read Materialized Query Status](/docs/api-reference/) — the same information for a single query.
* [Refresh Materialized Query](/docs/api-reference/) — trigger an immediate refresh, regardless of the schedule.
* [Cancel Materialized Query Refresh](/docs/api-reference/) — cancel an in-progress refresh.
For example, to check when a materialized query last refreshed and when the next run is due:
curl --request GET \
--url https://partner.peaka.studio/api/v1/data/projects/{projectId}/materialized-queries/{queryId}/status \
--header 'Authorization: Bearer '
{
"queryId": "709922802836177298",
"queryName": "dailyrevenuematerialized",
"scheduleSettings": {
"type": "interval",
"repeatDuration": "PT12H",
"expression": "PT12H"
},
"nextExecutionStartTime": "2026-07-07T06:00:00Z",
"status": "COMPLETED",
"lastExecutionStartTime": "2026-07-06T18:00:00Z",
"lastUpdateTime": "2026-07-06T18:00:41Z"
}
### Clean up
A materialized query is deleted like any other query, with [Delete Query](/docs/api-reference/). Deleting it removes the materialized table and its refresh schedule.
If the materialized query was created from an existing query with `inputQueryRefId`, deleting it does **not** affect the source query.
On this page
* [Prerequisites](https://www.peaka.com/docs/cookbook/how-to-materialize-a-query-with-the-peaka-api/#prerequisites)
* [How materialization works](https://www.peaka.com/docs/cookbook/how-to-materialize-a-query-with-the-peaka-api/#how-materialization-works)
* [Materialize an existing query](https://www.peaka.com/docs/cookbook/how-to-materialize-a-query-with-the-peaka-api/#materialize-an-existing-query)
* [Convert a query in place](https://www.peaka.com/docs/cookbook/how-to-materialize-a-query-with-the-peaka-api/#convert-a-query-in-place)
* [Schedule refreshes](https://www.peaka.com/docs/cookbook/how-to-materialize-a-query-with-the-peaka-api/#schedule-refreshes)
* [Query the materialized data](https://www.peaka.com/docs/cookbook/how-to-materialize-a-query-with-the-peaka-api/#query-the-materialized-data)
* [Keep it in sync with the source](https://www.peaka.com/docs/cookbook/how-to-materialize-a-query-with-the-peaka-api/#keep-it-in-sync-with-the-source)
* [Monitor, refresh, and cancel](https://www.peaka.com/docs/cookbook/how-to-materialize-a-query-with-the-peaka-api/#monitor-refresh-and-cancel)
* [Clean up](https://www.peaka.com/docs/cookbook/how-to-materialize-a-query-with-the-peaka-api/#clean-up)
--- START: docs/cookbook/how-to-use-new-ai-api-api/how-to-use-new-ai-api-api.md ---
Documentation menu
[Home](/) / [Docs](/docs/) / How to use new AI API
 Copy as Markdown
How to use new AI API
=====================
This guide explains on how to use new ai agent API of Peaka
### Architecture
Peaka text2SQL agent has a new version which is written with popular agent library [LangGraph](https://www.langchain.com/langgraph).
Previous implementation was using tool based implementation new version uses workflow based approach to get more predictable results.
Below you can see workflow of the agent. Peaka AI agent is a workflow implemented in LangGraph.
### Internal state of agent
Below you can see internal state of the agent and its description. When agent completes a given task it updates the internal state. If agent provides answer to the user it is added to `messages` state.
{
"projectId": "Peaka Project id",
"messages": "Array containing all the chat messages between user and AI Agent",
"noExecute": "State whether agent should execute generated sql on Peaka takes true of false",
"userIntentReasoning": "State for classifying user intent. Values are: WAITING_FOR_INPUT, TEXT_TO_SQL,DB_SCHEMA_DISCOVERY,USER_INTENT_NOT_CLEAR ",
"tableNames": "Array containing table names extracted from user question by the agent",
"metadata": "Metadata for the tables used by the agent.",
"currentGeneratedQuery": "Generated sql query during generate-query node execution",
"currentQueryError": "Error when generated sql is executed on Peaka",
"invalidQuery": "Flag to current executed query is valid or not",
"currentQueryResult": "Data returned after generated sql is run on Peaka",
"goldSQLs": "Gold sql used in query generation",
"currentQueryReasoning": "Reasoning of the agent during query generation",
"catalogs": "Catalogs of Peaka Project",
"sampleQuestions": "Sample questions generated to guide the user in data exploration."
}
### Stream Modes
You can stream agent internal state via stream modes.
Currently we have these stream modes: When using the stream and methods with LangGraph, you can one or more streaming mode which allow you to control the type of output that is streamed. The available streaming modes are:
* `values`: Emit all values of the state for each step.
* `updates`: Emit only the node name(s) and updates that were returned by the node(s) after each step.
* `debug`: Emit debug events for each step.
* `messages`: Emit LLM messages token-by-token.
Default stream mode is `messages`.
On this page
* [Architecture](https://www.peaka.com/docs/cookbook/how-to-use-new-ai-api-api/#architecture)
* [Internal state of agent](https://www.peaka.com/docs/cookbook/how-to-use-new-ai-api-api/#internal-state-of-agent)
* [Stream Modes](https://www.peaka.com/docs/cookbook/how-to-use-new-ai-api-api/#stream-modes)
--- START: docs/db-drivers/java/java.md ---
Documentation menu
[Home](/) / [Docs](/docs/) / JDBC Driver
 Copy as Markdown
JDBC Driver
===========
"Welcome to the documentation for the Peaka JDBC Driver – your gateway to seamless integration with the powerful Peaka data platform.
Requirements
------------
* Java version 8 or higher.
Installation
------------
Peaka JDBC Driver is distributed via the [Maven central repository](https://central.sonatype.com/artifact/com.peaka/peaka-jdbc/). Simply configure your build tool to pull the latest version of the SDK into your projects. We recommend using the latest version of the JDBC driver.
* Group ID: `com.peaka`
* Artifact ID: `peaka-jdbc`
Usage
-----
First you need to register the driver with `Class.forName("com.peaka.jdbc.PeakaDriver");`. Host name for the Peaka JDBC Driver is `dbc.peaka.studio` and port is `4567`. You need to provide your API Key with `extraCredentials` property. You can find a sample code below:
private static final String QUERY = "SELECT SUM(\"amount\") AS total_amount\n" +
"FROM \"stripe\".\"payment\".\"charges\"";
//Follow instructions on how to create your api key: https://www.peaka.com/docs/cookbook/how-to-generate-api-keys
//Connect sample data sets to Peaka then run the query above with sample data by running testQueryWithSampleData.
private static final String PEAKA_API_KEY = "";
//Register the driver with the classname
try {
Class.forName("com.peaka.jdbc.PeakaDriver");
} catch (Throwable t) {
throw new RuntimeException(t);
}
String url = "jdbc:peaka://dbc.peaka.studio:4567";
Properties properties = new Properties();
properties.setProperty("extraCredentials", "peakaKey:" + PEAKA_API_KEY);
properties.setProperty("SSL", "true");
try {
Connection connection = DriverManager.getConnection(url, properties);
Statement stmt = connection.createStatement();
ResultSet rs = stmt.executeQuery(QUERY);
while (rs.next()) {
System.out.print("total_amount: " + rs.getInt("total_amount"));
}
stmt.close();
connection.close();
} catch (SQLException e) {
throw new RuntimeException(e);
}
Contact
-------
For feature requests and bugs, please create an issue in [this](https://github.com/peakacom/peaka-jdbc-driver) repo. For further support, see the following resources:
* [Peaka Community Discord](https://discord.com/invite/peaka)
On this page
* [Requirements](https://www.peaka.com/docs/db-drivers/java/#requirements)
* [Installation](https://www.peaka.com/docs/db-drivers/java/#installation)
* [Usage](https://www.peaka.com/docs/db-drivers/java/#usage)
* [Contact](https://www.peaka.com/docs/db-drivers/java/#contact)
--- START: docs/db-drivers/nodejs/nodejs.md ---
Documentation menu
[Home](/) / [Docs](/docs/) / NodeJS Driver
 Copy as Markdown
NodeJS Driver
=============
Discover the [Peaka](/) NodeJS driver
Requirements
------------
* Node 12 or newer.
Install
-------
or
```yarn
## Usage
### Create a Peaka connection
```typescript
import { Peaka, connectToPeaka } from "@peaka/client";
const connection: Peaka = connectToPeaka("")
### Submit a query
import type { QueryResult } from "@peaka/client";
try{
const iter: Iterator = await connection.query(
'select * from .. limit 100'
);
}catch(err){
console.error(err.response.data);
})
### Iterate through the query results
for await (const queryResult of iter) {
console.log(queryResult.data);
}
### Alternative: map and aggregate the data
import type { QueryData } from "@peaka/client";
const data: QueryData[] = await iter
.map(r => r.data ?? [])
.fold([], (row, acc) => [...acc, ...row]);
Handle the Errors
-----------------
Query errors are returned in two different ways.
* The `connection.query()` method throws an error object, and the `error.response.data` object contains the following properties:
Error Property
Description
errorCode
Code of error
message
Description of the error
traceId
The identifier that you can give Peaka Team to learn more about the error
* The `connection.query()` method returns successfully, but the response may include an `error` object with the following structure:
type QueryError = {
message: string;
errorCode: number;
errorName: string;
errorType: string;
failureInfo: QueryFailureInfo;
};
In order to handle all possible errors, please make sure to check both objects, as demonstrated in the example below:
try{
const iter = await connection.query(
'SELECT * FROM "peaka"."table"."lookup table"'
);
for await (const queryResult of iter) {
if(queryResult.error){
console.log("error", queryResult.error);
}
}
}catch(e){
console.log("e", e.response.data);
}
On this page
* [Requirements](https://www.peaka.com/docs/db-drivers/nodejs/#requirements)
* [Install](https://www.peaka.com/docs/db-drivers/nodejs/#install)
* [Submit a query](https://www.peaka.com/docs/db-drivers/nodejs/#submit-a-query)
* [Iterate through the query results](https://www.peaka.com/docs/db-drivers/nodejs/#iterate-through-the-query-results)
* [Alternative: map and aggregate the data](https://www.peaka.com/docs/db-drivers/nodejs/#alternative-map-and-aggregate-the-data)
* [Handle the Errors](https://www.peaka.com/docs/db-drivers/nodejs/#handle-the-errors)
--- START: docs/db-drivers/python/python.md ---
Documentation menu
[Home](/) / [Docs](/docs/) / Python Driver
 Copy as Markdown
Python Driver
=============
Discover the [Peaka](/) python driver
Provides a low-level client and a DBAPI 2.0 implementation and a SQLAlchemy adapter. It supports Python>=3.8 and PyPy.
Usage
-----
### The Python Database API (DBAPI)
**Installation**
$ pip install peaka
**Quick Start**
Use the DBAPI interface to query Peaka:
You can call the `connect_to_peaka` method with your Peaka `api_key`.
`catalog`, `schema` and `timezone` are the optional parameters.
from peaka.dbapi import connect_to_peaka
conn = connect_to_peaka(api_key="", catalog="", schema="", timezone="")
cur = conn.cursor()
cur.execute("SELECT * FROM ")
rows = cur.fetchall()
You can query your `table` directly, if you enter the `catalog` and `schema` information when you connect.
### SQLAlchemy
**Installation**
$ pip install peaka[sqlalchemy]
**Usage**
To connect to Peaka using SQLAlchemy, use a connection string (URL) following this pattern:
peaka://dbc.peaka.studio:4567//?http_scheme=https&extra_credential=[["peakaKey",]]&access_token=true
NOTE: `schema` is optional
**Examples**:
from sqlalchemy import create_engine
from sqlalchemy.schema import Table, MetaData
from sqlalchemy.sql.expression import select, text
engine = create_engine('peaka://dbc.peaka.studio:4567//?http_scheme=https&extra_credential=[["peakaKey",]]&access_token=true')
connection = engine.connect()
rows = connection.execute(text("SELECT * FROM ")).fetchall()
# or using SQLAlchemy schema
nodes = Table(
'',
MetaData(schema=''),
peaka_autoload=True,
autoload_with=engine
)
rows = connection.execute(select(nodes)).fetchall()
In order to pass additional connection attributes use [connect\_args](https://docs.sqlalchemy.org/en/14/core/engines.html#sqlalchemy.create_engine.params.connect_args) method. Attributes can also be passed in the connection string.
On this page
* [Usage](https://www.peaka.com/docs/db-drivers/python/#usage)
* [The Python Database API (DBAPI)](https://www.peaka.com/docs/db-drivers/python/#the-python-database-api-dbapi)
* [SQLAlchemy](https://www.peaka.com/docs/db-drivers/python/#sqlalchemy)
--- START: docs/embedded-peaka/data-management-backend/data-management-backend.md ---
Documentation menu
[Home](/) / [Docs](/docs/) / Peaka as a Data Management Backend
 Copy as Markdown
Peaka as a Data Management Backend
==================================
Peaka is a powerful data management backend that enables seamless integration and efficient data operations. Users can create projects to organize their data and establish catalogs for easier access.
Users can run queries to retrieve specific information or perform operations. Peaka's caching capabilities enhance performance by storing frequently accessed data, reducing retrieval times. This ensures efficient data operations, allowing users to focus on insights rather than waiting for processes to complete. Overall, Peaka empowers users to manage their data effectively in backend.
Key Features
------------
* **Seamless Integration**: Easily connect with various third-party services to enhance your data management capabilities.
* **Efficient Data Operations**: Utilize APIs for creating projects, catalogs, and executing queries to streamline your data workflows.
* **Advanced Caching**: Optimize performance with a versatile caching API that supports creating, updating, and managing cache states.
* **Query Execution**: Execute queries to retrieve specific information or perform operations.
Step-by-Step Implementation
---------------------------
### 1\. Creating Partner API Key
* Prior to initiating the creation of a project, it is essential to generate a Partner API key. This key serves as a crucial authentication mechanism for your project creation requests to the Peaka API, ensuring secure and authorized access.
* Navigate to the [Developer](https://peaka.studio/home/advanced-settings) section.
* Click on the Partner API Key button to open a dialog box.
* Fill in the form by entering your desired API Key Name.
* Click on the Create button.
* You can copy the API key from the dialog box.
For detailed guidance, please refer to the documentation on [how to create a partner API key](/docs/cookbook/how-to-manage-partner-api-key#creating-a-partner-api-key).

### 2\. Creating a Project
* Now you have your partner API key, and you need to create a project that will act as a centralized repository for effectively storing and caching your data.
* Create your project by using below API.
For detailed guidance, please refer to the documentation on [how to create a project](/docs/api-reference/).
curl --request POST \
--url https://partner.peaka.studio/api/v1/organizations/{organizationId}/workspaces/{workspaceId}/projects \
--header 'Authorization: Bearer ' \
--header 'Content-Type: application/json' \
--data '{
"name": "Sample Project Name"
}'
const url = 'https://partner.peaka.studio/api/v1/organizations/{organizationId}/workspaces/{workspaceId}/projects';
const options = {
method: 'POST',
headers: {Authorization: 'Bearer ', 'Content-Type': 'application/json'},
body: '{"name":"Sample Project Name"}'
};
try {
const response = await fetch(url, options);
const data = await response.json();
console.log(data);
} catch (error) {
console.error(error);
}
import requests
url = "https://partner.peaka.studio/api/v1/organizations/{organizationId}/workspaces/{workspaceId}/projects"
payload = { "name": "Sample Project Name" }
headers = {
"Authorization": "Bearer ",
"Content-Type": "application/json"
}
response = requests.post(url, json=payload, headers=headers)
print(response.json())
$curl = curl_init();
curl_setopt_array($curl, [
CURLOPT_URL => "https://partner.peaka.studio/api/v1/organizations/{organizationId}/workspaces/{workspaceId}/projects",
CURLOPT_RETURNTRANSFER => true,
CURLOPT_ENCODING => "",
CURLOPT_MAXREDIRS => 10,
CURLOPT_TIMEOUT => 30,
CURLOPT_HTTP_VERSION => CURL_HTTP_VERSION_1_1,
CURLOPT_CUSTOMREQUEST => "POST",
CURLOPT_POSTFIELDS => json_encode([
'name' => 'Sample Project Name'
]),
CURLOPT_HTTPHEADER => [
"Authorization: Bearer ",
"Content-Type: application/json"
],
]);
$response = curl_exec($curl);
$err = curl_error($curl);
curl_close($curl);
if ($err) {
echo "cURL Error #:" . $err;
} else {
echo $response;
}
package main
import (
"fmt"
"strings"
"net/http"
"io"
)
func main() {
url := "https://partner.peaka.studio/api/v1/organizations/{organizationId}/workspaces/{workspaceId}/projects"
payload := strings.NewReader("{\n \"name\": \"Sample Project Name\"\n}")
req, _ := http.NewRequest("POST", url, payload)
req.Header.Add("Authorization", "Bearer ")
req.Header.Add("Content-Type", "application/json")
res, _ := http.DefaultClient.Do(req)
defer res.Body.Close()
body, _ := io.ReadAll(res.Body)
fmt.Println(res)
fmt.Println(string(body))
}
HttpResponse response = Unirest.post("https://partner.peaka.studio/api/v1/organizations/{organizationId}/workspaces/{workspaceId}/projects")
.header("Authorization", "Bearer ")
.header("Content-Type", "application/json")
.body("{\n \"name\": \"Sample Project Name\"\n}")
.asString();
{
"id": "URNg0GIj",
"name": "Sample Project Name",
"description": "Non accusantium ducimus accusantium. Laborum eum accusamus sit sit hic eaque doloremque. Occaecati blanditiis facere consequuntur consectetur culpa reiciendis hic tempore dolorem. Saepe impedit nam necessitatibus maxime numquam voluptatum cum. Adipisci mollitia blanditiis sint inventore ex commodi occaecati ipsam quas.",
"domain": "sampleprojectname-cdcn",
"webhookBaseUrl": "https://sampleprojectname-cdcn--test.api.peaka.host",
"createdAt": "2024-09-10T10:11:02.385253956Z"
}
### 3\. Create a API Key
* Now that you have created your project, you need to create a API key for your project.
* You will use the API key to authenticate your requests to the Peaka API.
For detailed guidance, please refer to the documentation on [how to create a project API key](/docs/api-reference/).
curl --request POST \
--url https://partner.peaka.studio/api/v1/projects/{projectId}/apiKeys \
--header 'Content-Type: application/json' \
--data '{
"name": "test"
}'
const options = {
method: 'POST',
headers: {'Content-Type': 'application/json'},
body: '{"name":"test"}'
};
fetch('https://partner.peaka.studio/api/v1/projects/{projectId}/apiKeys', options)
.then(response => response.json())
.then(response => console.log(response))
.catch(err => console.error(err));
import requests
url = "https://partner.peaka.studio/api/v1/projects/{projectId}/apiKeys"
payload = {"name": "test"}
headers = {"Content-Type": "application/json"}
response = requests.request("POST", url, json=payload, headers=headers)
print(response.text)
"https://partner.peaka.studio/api/v1/projects/{projectId}/apiKeys",
CURLOPT_RETURNTRANSFER => true,
CURLOPT_ENCODING => "",
CURLOPT_MAXREDIRS => 10,
CURLOPT_TIMEOUT => 30,
CURLOPT_HTTP_VERSION => CURL_HTTP_VERSION_1_1,
CURLOPT_CUSTOMREQUEST => "POST",
CURLOPT_POSTFIELDS => "{\n \"name\": \"test\"\n}",
CURLOPT_HTTPHEADER => [
"Content-Type: application/json"
],
]);
$response = curl_exec($curl);
$err = curl_error($curl);
curl_close($curl);
if ($err) {
echo "cURL Error #:" . $err;
} else {
echo $response;
}
package main
import (
"fmt"
"strings"
"net/http"
"io/ioutil"
)
func main() {
url := "https://partner.peaka.studio/api/v1/projects/{projectId}/apiKeys"
payload := strings.NewReader("{\n \"name\": \"test\"\n}")
req, _ := http.NewRequest("POST", url, payload)
req.Header.Add("Content-Type", "application/json")
res, _ := http.DefaultClient.Do(req)
defer res.Body.Close()
body, _ := ioutil.ReadAll(res.Body)
fmt.Println(res)
fmt.Println(string(body))
}
HttpResponse response = Unirest.post("https://partner.peaka.studio/api/v1/projects/{projectId}/apiKeys")
.header("Content-Type", "application/json")
.body("{\n \"name\": \"test\"\n}")
.asString();
{
"name": "test",
"apiKey": "TtgGcQFq.s3fzROFoop8uHG4pS2LYhoqn1rLb6oW6",
"apiKeyId": "21fd1a8d-88d5-4295-b792-5b2113138057"
}
### 4\. Creating a Catalog
* You have successfully created your project and obtained your API key.
* The next step is to create a catalog, which will serve as a structured collection of data sourced from a specific origin.
* To view all available catalogs, you can utilize the API. See the documentation on [how to get a catalog list](/docs/api-reference/) for further instructions.
For detailed guidance, please refer to the documentation on [how to create a catalog](/docs/api-reference/) .
curl --request POST \
--url https://partner.peaka.studio/api/v1/data/projects/{projectId}/catalogs \
--header 'Content-Type: application/json' \
--data '{
"name": "exampleAirtableCatalog",
"catalogType": "airtable",
"connectionId": "8db17e23-29de-4dab-8886-af9717e0e742"
}'
const options = {
method: 'POST',
headers: {'Content-Type': 'application/json'},
body: '{"name":"exampleAirtableCatalog","catalogType":"airtable","connectionId":"8db17e23-29de-4dab-8886-af9717e0e742"}'
};
fetch('https://partner.peaka.studio/api/v1/data/projects/{projectId}/catalogs', options)
.then(response => response.json())
.then(response => console.log(response))
.catch(err => console.error(err));
import requests
url = "https://partner.peaka.studio/api/v1/data/projects/{projectId}/catalogs"
payload = {
"name": "exampleAirtableCatalog",
"catalogType": "airtable",
"connectionId": "8db17e23-29de-4dab-8886-af9717e0e742"
}
headers = {"Content-Type": "application/json"}
response = requests.request("POST", url, json=payload, headers=headers)
"https://partner.peaka.studio/api/v1/data/projects/{projectId}/catalogs",
CURLOPT_RETURNTRANSFER => true,
CURLOPT_ENCODING => "",
CURLOPT_MAXREDIRS => 10,
CURLOPT_TIMEOUT => 30,
CURLOPT_HTTP_VERSION => CURL_HTTP_VERSION_1_1,
CURLOPT_CUSTOMREQUEST => "POST",
CURLOPT_POSTFIELDS => "{\n \"name\": \"exampleAirtableCatalog\",\n \"catalogType\": \"airtable\",\n \"connectionId\": \"8db17e23-29de-4dab-8886-af9717e0e742\"\n}",
CURLOPT_HTTPHEADER => [
"Content-Type: application/json"
],
]);
$response = curl_exec($curl);
$err = curl_error($curl);
curl_close($curl);
if ($err) {
echo "cURL Error #:" . $err;
} else {
echo $response;
}
package main
import (
"fmt"
"strings"
"net/http"
"io/ioutil"
)
func main() {
url := "https://partner.peaka.studio/api/v1/data/projects/{projectId}/catalogs"
payload := strings.NewReader("{\n \"name\": \"exampleAirtableCatalog\",\n \"catalogType\": \"airtable\",\n \"connectionId\": \"8db17e23-29de-4dab-8886-af9717e0e742\"\n}")
req, _ := http.NewRequest("POST", url, payload)
req.Header.Add("Content-Type", "application/json")
res, _ := http.DefaultClient.Do(req)
defer res.Body.Close()
body, _ := ioutil.ReadAll(res.Body)
fmt.Println(res)
fmt.Println(string(body))
}
HttpResponse response = Unirest.post("https://partner.peaka.studio/api/v1/data/projects/{projectId}/catalogs")
.header("Content-Type", "application/json")
.body("{\n \"name\": \"exampleAirtableCatalog\",\n \"catalogType\": \"airtable\",\n \"connectionId\": \"8db17e23-29de-4dab-8886-af9717e0e742\"\n}")
.asString();
{
"id": "626654862255325504",
"name": "exampleairtablecatalog",
"displayName": "exampleAirtableCatalog",
"catalogType": "airtable",
"connectionId": "8db17e23-29de-4dab-8886-af9717e0e742"
}
### 5\. Cache Your Catalog
* In this step, we will cache your catalog. This allows you to store frequently accessed data in a temporary storage area, which significantly enhances data retrieval speeds.
For detailed guidance, please refer to the documentation on [how to cache a catalog](/docs/api-reference/).
curl --request POST \
--url https://partner.peaka.studio/api/v1/data/projects/{projectId}/cache \
--header 'Content-Type: application/json' \
--data '{
"catalogId": "627249916703408649",
"schemaName": "payment",
"tableName": "customers"
}'
const options = {
method: 'POST',
headers: {'Content-Type': 'application/json'},
body: '{"catalogId":"627249916703408649","schemaName":"payment","tableName":"customers"}'
};
fetch('https://partner.peaka.studio/api/v1/data/projects/{projectId}/cache', options)
.then(response => response.json())
.then(response => console.log(response))
.catch(err => console.error(err));
import requests
url = "https://partner.peaka.studio/api/v1/data/projects/{projectId}/cache"
payload = {
"catalogId": "627249916703408649",
"schemaName": "payment",
"tableName": "customers"
}
headers = {"Content-Type": "application/json"}
response = requests.request("POST", url, json=payload, headers=headers)
print(response.text)
"https://partner.peaka.studio/api/v1/data/projects/{projectId}/cache",
CURLOPT_RETURNTRANSFER => true,
CURLOPT_ENCODING => "",
CURLOPT_MAXREDIRS => 10,
CURLOPT_TIMEOUT => 30,
CURLOPT_HTTP_VERSION => CURL_HTTP_VERSION_1_1,
CURLOPT_CUSTOMREQUEST => "POST",
CURLOPT_POSTFIELDS => "{\n \"catalogId\": \"627249916703408649\",\n \"schemaName\": \"payment\",\n \"tableName\": \"customers\"\n}",
CURLOPT_HTTPHEADER => [
"Content-Type: application/json"
],
]);
$response = curl_exec($curl);
$err = curl_error($curl);
curl_close($curl);
if ($err) {
echo "cURL Error #:" . $err;
} else {
echo $response;
}
package main
import (
"fmt"
"strings"
"net/http"
"io/ioutil"
)
func main() {
url := "https://partner.peaka.studio/api/v1/data/projects/{projectId}/cache"
payload := strings.NewReader("{\n \"catalogId\": \"627249916703408649\",\n \"schemaName\": \"payment\",\n \"tableName\": \"customers\"\n}")
req, _ := http.NewRequest("POST", url, payload)
req.Header.Add("Content-Type", "application/json")
res, _ := http.DefaultClient.Do(req)
defer res.Body.Close()
body, _ := ioutil.ReadAll(res.Body)
fmt.Println(res)
fmt.Println(string(body))
}
HttpResponse response = Unirest.post("https://partner.peaka.studio/api/v1/data/projects/{projectId}/cache")
.header("Content-Type", "application/json")
.body("{\n \"catalogId\": \"627249916703408649\",\n \"schemaName\": \"payment\",\n \"tableName\": \"customers\"\n}")
.asString();
{
"id": "",
"appId": "",
"catalogId": "",
"schemaName": "",
"tableName": "",
"incrementalCacheSchedule": {
"type": "",
"expression": ""
},
"fullRefreshCacheSchedule": {
"type": "",
"expression": ""
}
}
#### Enabling Auto Update (Scheduling Refreshes)
The request above creates a cache **without** auto update — the cache is populated once and never refreshed automatically. To keep the cache in sync with the source, enable auto update by including a schedule in your request.
A cache has two independent schedules, both defined by the same `Schedule` object:
* **`incrementalCacheSchedule`**: How often Peaka pulls only the new or changed rows since the last run. Faster and cheaper — use this for frequent updates.
* **`fullRefreshCacheSchedule`**: How often Peaka rebuilds the entire cache from scratch. Heavier — use this less frequently to guarantee the cache fully matches the source.
Each schedule is an object with two fields:
Field
Description
`type`
`BASIC` to enable the schedule, or `NONE` to disable it. When `NONE`, `expression` is ignored.
`expression`
The refresh interval as an **ISO-8601 duration** (only used when `type` is `BASIC`).
The `expression` is an **ISO-8601 duration**, not a cron expression or a plain string like `"15 minutes"`. A malformed expression is the most common cause of a schedule that silently never runs.
The following table maps each UI **Update Frequency** option to its equivalent ISO-8601 `expression`:
Update Frequency
`expression`
Every 15 minutes
`PT15M`
Every 30 minutes
`PT30M`
Every 1 hour
`PT1H`
Every 2 hours
`PT2H`
Every 6 hours
`PT6H`
Every day
`P1D`
Every week
`P7D`
The example below creates a cache that runs an **incremental update every hour** and a **full refresh every week**:
curl --request POST \
--url https://partner.peaka.studio/api/v1/data/projects/{projectId}/cache \
--header 'Content-Type: application/json' \
--data '{
"catalogId": "627249916703408649",
"schemaName": "payment",
"tableName": "customers",
"incrementalCacheSchedule": {
"type": "BASIC",
"expression": "PT1H"
},
"fullRefreshCacheSchedule": {
"type": "BASIC",
"expression": "P7D"
}
}'
const options = {
method: 'POST',
headers: {'Content-Type': 'application/json'},
body: JSON.stringify({
catalogId: "627249916703408649",
schemaName: "payment",
tableName: "customers",
incrementalCacheSchedule: { type: "BASIC", expression: "PT1H" },
fullRefreshCacheSchedule: { type: "BASIC", expression: "P7D" }
})
};
fetch('https://partner.peaka.studio/api/v1/data/projects/{projectId}/cache', options)
.then(response => response.json())
.then(response => console.log(response))
.catch(err => console.error(err));
import requests
url = "https://partner.peaka.studio/api/v1/data/projects/{projectId}/cache"
payload = {
"catalogId": "627249916703408649",
"schemaName": "payment",
"tableName": "customers",
"incrementalCacheSchedule": {"type": "BASIC", "expression": "PT1H"},
"fullRefreshCacheSchedule": {"type": "BASIC", "expression": "P7D"}
}
headers = {"Content-Type": "application/json"}
response = requests.request("POST", url, json=payload, headers=headers)
print(response.text)
To turn auto update **off**, either omit the schedule fields entirely or set their `type` to `NONE`:
{
"catalogId": "627249916703408649",
"schemaName": "payment",
"tableName": "customers",
"incrementalCacheSchedule": { "type": "NONE" },
"fullRefreshCacheSchedule": { "type": "NONE" }
}
**Note**: You can update the schedules of an existing cache at any time with the [update cache settings](/docs/api-reference/) endpoint, or trigger a one-off refresh with the [incremental](/docs/api-reference/) or [full refresh](/docs/api-reference/) endpoints.
### 6\. Write Your Query
* Now you have created your project, API key, and catalog. Also cached your catalog.
* You are now ready to create queries that allow you to extract and refine data from your catalog based on your requirements.
For detailed guidance, please refer to the documentation on [how to create a query](/docs/api-reference/).
curl --request POST \
--url https://partner.peaka.studio/api/v1/data/projects/{projectId}/queries \
--header 'Content-Type: application/json' \
--data '{
"displayName": "sampleQuery",
"inputQuery": "SELECT * from \"mycatalog\".payment.customers"
}'
const options = {
method: 'POST',
headers: {'Content-Type': 'application/json'},
body: '{"displayName":"sampleQuery","inputQuery":"SELECT * from \"mycatalog\".payment.customers"}'
};
fetch('https://partner.peaka.studio/api/v1/data/projects/{projectId}/queries', options)
.then(response => response.json())
.then(response => console.log(response))
.catch(err => console.error(err));
import requests
url = "https://partner.peaka.studio/api/v1/data/projects/{projectId}/queries"
payload = {
"displayName": "sampleQuery",
"inputQuery": "SELECT * from \"mycatalog\".payment.customers"
}
headers = {"Content-Type": "application/json"}
response = requests.request("POST", url, json=payload, headers=headers)
print(response.text)
"https://partner.peaka.studio/api/v1/data/projects/{projectId}/queries",
CURLOPT_RETURNTRANSFER => true,
CURLOPT_ENCODING => "",
CURLOPT_MAXREDIRS => 10,
CURLOPT_TIMEOUT => 30,
CURLOPT_HTTP_VERSION => CURL_HTTP_VERSION_1_1,
CURLOPT_CUSTOMREQUEST => "POST",
CURLOPT_POSTFIELDS => "{\n \"displayName\": \"sampleQuery\",\n \"inputQuery\": \"SELECT * from \\\"mycatalog\\\".payment.customers\"\n}",
CURLOPT_HTTPHEADER => [
"Content-Type: application/json"
],
]);
$response = curl_exec($curl);
$err = curl_error($curl);
curl_close($curl);
if ($err) {
echo "cURL Error #:" . $err;
} else {
echo $response;
}
package main
import (
"fmt"
"strings"
"net/http"
"io/ioutil"
)
func main() {
url := "https://partner.peaka.studio/api/v1/data/projects/{projectId}/queries"
payload := strings.NewReader("{\n \"displayName\": \"sampleQuery\",\n \"inputQuery\": \"SELECT * from \\\"mycatalog\\\".payment.customers\"\n}")
req, _ := http.NewRequest("POST", url, payload)
req.Header.Add("Content-Type", "application/json")
res, _ := http.DefaultClient.Do(req)
defer res.Body.Close()
body, _ := ioutil.ReadAll(res.Body)
fmt.Println(res)
fmt.Println(string(body))
}
HttpResponse response = Unirest.post("https://partner.peaka.studio/api/v1/data/projects/{projectId}/queries")
.header("Content-Type", "application/json")
.body("{\n \"displayName\": \"sampleQuery\",\n \"inputQuery\": \"SELECT * from \\\"mycatalog\\\".payment.customers\"\n}")
.asString();
{
"id": "",
"displayName": "",
"name": "",
"inputQuery": "",
"inputQueryRefId": "",
"queryType": "",
"schedule": {
"expression": ""
}
}
### 7\. Run Your Query
* Last step is to run your query.
* After running query is completed, you will get the data in response. You can use this data for further processing or analysis as needed.
For detailed guidance, please refer to the documentation on [how to run a query](/docs/api-reference/).
curl --request POST \
--url https://partner.peaka.studio/api/v1/data/projects/{projectId}/queries/execute \
--header 'Content-Type: application/json' \
--data '{
"from": [
{
"catalogName": "peaka",
"schemaName": "query",
"tableName": "samplequery"
}
]
}'
const options = {
method: 'POST',
headers: {'Content-Type': 'application/json'},
body: '{"from":[{"catalogName":"peaka","schemaName":"query","tableName":"samplequery"}]}'
};
fetch('https://partner.peaka.studio/api/v1/data/projects/{projectId}/queries/execute', options)
.then(response => response.json())
.then(response => console.log(response))
.catch(err => console.error(err));
import requests
url = "https://partner.peaka.studio/api/v1/data/projects/{projectId}/queries/execute"
payload = {"from": [
{
"catalogName": "peaka",
"schemaName": "query",
"tableName": "samplequery"
}
]}
headers = {"Content-Type": "application/json"}
response = requests.request("POST", url, json=payload, headers=headers)
print(response.text)
"https://partner.peaka.studio/api/v1/data/projects/{projectId}/queries/execute",
CURLOPT_RETURNTRANSFER => true,
CURLOPT_ENCODING => "",
CURLOPT_MAXREDIRS => 10,
CURLOPT_TIMEOUT => 30,
CURLOPT_HTTP_VERSION => CURL_HTTP_VERSION_1_1,
CURLOPT_CUSTOMREQUEST => "POST",
CURLOPT_POSTFIELDS => "{\n \"from\": [\n {\n \"catalogName\": \"peaka\",\n \"schemaName\": \"query\",\n \"tableName\": \"samplequery\"\n }\n ]\n}",
CURLOPT_HTTPHEADER => [
"Content-Type: application/json"
],
]);
$response = curl_exec($curl);
$err = curl_error($curl);
curl_close($curl);
if ($err) {
echo "cURL Error #:" . $err;
} else {
echo $response;
}
package main
import (
"fmt"
"strings"
"net/http"
"io/ioutil"
)
func main() {
url := "https://partner.peaka.studio/api/v1/data/projects/{projectId}/queries/execute"
payload := strings.NewReader("{\n \"from\": [\n {\n \"catalogName\": \"peaka\",\n \"schemaName\": \"query\",\n \"tableName\": \"samplequery\"\n }\n ]\n}")
req, _ := http.NewRequest("POST", url, payload)
req.Header.Add("Content-Type", "application/json")
res, _ := http.DefaultClient.Do(req)
defer res.Body.Close()
body, _ := ioutil.ReadAll(res.Body)
fmt.Println(res)
fmt.Println(string(body))
}
HttpResponse response = Unirest.post("https://partner.peaka.studio/api/v1/data/projects/{projectId}/queries/execute")
.header("Content-Type", "application/json")
.body("{\n \"from\": [\n {\n \"catalogName\": \"peaka\",\n \"schemaName\": \"query\",\n \"tableName\": \"samplequery\"\n }\n ]\n}")
.asString();
{
"columns": [
{
"catalogId": "2",
"catalogName": "peaka",
"schemaName": "query",
"tableName": "samplequery",
"columnName": "amount"
}
],
"data": [
[
{
"name": "amount",
"displayName": "amount",
"dataType": "bigint",
"value": "75",
"order": 0
}
],
[
{
"name": "amount",
"displayName": "amount",
"dataType": "bigint",
"value": "75",
"order": 0
}
],
[
{
"name": "amount",
"displayName": "amount",
"dataType": "bigint",
"value": "75",
"order": 0
}
]
]
}
### 8\. Success
* You have successfully created your project, generated your API key, established your catalog, cached the catalog, and executed your query.
* This data is now ready for advanced processing and insightful analysis.
* You have effectively integrated Peaka as your robust data management backend.
On this page
* [Key Features](https://www.peaka.com/docs/embedded-peaka/data-management-backend/#key-features)
* [Step-by-Step Implementation](https://www.peaka.com/docs/embedded-peaka/data-management-backend/#step-by-step-implementation)
* [1\. Creating Partner API Key](https://www.peaka.com/docs/embedded-peaka/data-management-backend/#1-creating-partner-api-key)
* [2\. Creating a Project](https://www.peaka.com/docs/embedded-peaka/data-management-backend/#2-creating-a-project)
* [3\. Create a API Key](https://www.peaka.com/docs/embedded-peaka/data-management-backend/#3-create-a-api-key)
* [4\. Creating a Catalog](https://www.peaka.com/docs/embedded-peaka/data-management-backend/#4-creating-a-catalog)
* [5\. Cache Your Catalog](https://www.peaka.com/docs/embedded-peaka/data-management-backend/#5-cache-your-catalog)
* [6\. Write Your Query](https://www.peaka.com/docs/embedded-peaka/data-management-backend/#6-write-your-query)
* [7\. Run Your Query](https://www.peaka.com/docs/embedded-peaka/data-management-backend/#7-run-your-query)
* [8\. Success](https://www.peaka.com/docs/embedded-peaka/data-management-backend/#8-success)
--- START: docs/embedded-peaka/data-management-tool-with-ui/data-management-tool-with-ui.md ---
Documentation menu
[Home](/) / [Docs](/docs/) / Peaka as a Data Management Tool with UI
 Copy as Markdown
Peaka as a Data Management Tool with UI
=======================================
With **Peaka as a Data Management Tool with UI**, you can access all of its **premium features** through either its **powerful API** or/and its **intuitive user interface (UI)**. Whether you prefer seamless automation via the API or a more visual approach using the UI, Peaka offers the flexibility to suit your needs. If you prefer to use Peaka exclusively as a connector solution, we provide a dedicated approach for that use case. To learn more about this focused implementation, please refer to the [Peaka as a Connector-Only Solution](https://www.peaka.com/docs/embedded-peaka/data-management-tool-with-ui/#peaka-as-a-connector-only-solution) section.
Embed Peaka's UI in Your Web Application
----------------------------------------
You can easily integrate **Peaka's UI** into your own web application. This allows your users to enjoy the full range of Peaka's advanced features without ever leaving your platform. By embedding Peaka, you provide a **seamless and cohesive experience**, empowering your users with the tools they need to maximize productivity and efficiency.
* * *
### Key Benefits:
* Access all premium features via API or UI.
* Embed Peaka's UI directly into your web application.
* Deliver a unified experience for your users.
* Enhance productivity with Peaka's advanced tools.
* * *
### TLDR;
If you want to see it in action you can check our example applications that created in NextJs with Python/NodeJS backend.
[Go to Python App](https://github.com/peakacom/embedded-peaka-python-example)
[Go to Node App](https://github.com/peakacom/embedded-peaka-node-example)
[Go to Running Example](https://embedded-peaka-node-example-bate-six.vercel.app/)
* * *
### Prerequisites
* Partner API Key: To create a Partner API Key, please refer to our guide on [managing partner API keys](/docs/cookbook/how-to-manage-partner-api-key#how-to-manage-your-partner-api-key).
Initiate the Session
--------------------
* To begin, you need to initiate a session with Peaka using your Partner API Key as the token.
curl --request POST \
--url https://partner.peaka.studio/api/v1/ui/initSession \
--header 'Content-Type: application/json' 'Authorization: Bearer '\
--data '{
"projectId":
}'
const options = {
method: 'POST',
headers: {'Content-Type': 'application/json'},
body: '{"projectId":"projectId"}'
};
fetch('https://partner.peaka.studio/api/v1/ui/initSession', options)
.then(response => response.json())
.then(response => console.log(response))
.catch(err => console.error(err));
import requests
url = "https://partner.peaka.studio/api/v1/ui/initSession"
payload = {
"projectId": "projectId",
}
headers = {"Content-Type": "application/json"}
response = requests.request("POST", url, json=payload, headers=headers)
print(response.text)
"https://partner.peaka.studio/api/v1/ui/initSession",
CURLOPT_RETURNTRANSFER => true,
CURLOPT_ENCODING => "",
CURLOPT_MAXREDIRS => 10,
CURLOPT_TIMEOUT => 30,
CURLOPT_HTTP_VERSION => CURL_HTTP_VERSION_1_1,
CURLOPT_CUSTOMREQUEST => "POST",
CURLOPT_POSTFIELDS => "{\n \"projectId\": \"projectId\" \n}",
CURLOPT_HTTPHEADER => [
"Content-Type: application/json"
],
]);
$response = curl_exec($curl);
$err = curl_error($curl);
curl_close($curl);
if ($err) {
echo "cURL Error #:" . $err;
} else {
echo $response;
}
package main
import (
"fmt"
"strings"
"net/http"
"io/ioutil"
)
func main() {
url := "https://partner.peaka.studio/api/v1/ui/initSession"
payload := strings.NewReader("{\n \"projectId\": \"projectId\" \n}")
req, _ := http.NewRequest("POST", url, payload)
req.Header.Add("Content-Type", "application/json")
res, _ := http.DefaultClient.Do(req)
defer res.Body.Close()
body, _ := ioutil.ReadAll(res.Body)
fmt.Println(res)
fmt.Println(string(body))
}
HttpResponse response = Unirest.post("https://partner.peaka.studio/api/v1/ui/initSession")
.header("Content-Type", "application/json")
.body("{\"projectId\": \"projectId\"}")
.asString();
* The endpoint will provide a URL to initiate your session.
{
"sessionUrl": "https://partner.peaka.studio/api/v1/ui/session?code="
"partnerOrigin": "https://.peaka.studio/"
}
You can access the user interface using the provided URL.
Enabling Embedded UI for Peaka Integration Using an iframe
----------------------------------------------------------
For security reasons, you cannot use the session URL directly in an iframe. To embed Peaka within an iframe, you need to enable the embedded UI for your partner API key.
In order to do that you should;
* Go to `Developer Settings` in your peaka account.
 * Find your api key in the table then click `...` button.
 * Select `Enable Embedded UI` option
 * Enable Embedded UI for this API Key
 * Enter your domain that you want to embed the Peaka app.
 URL is needed for security reasons. Please be aware that your application should be served over HTTPS for use in an iframe.
* Enter a Company Name for white labeling in Embedded UI.
 * If you want to customize the UI, click "Customize UI Theme" button then give a theme name and upload your custom css file. You can also download the valid example of the customization file (Check out the related documentation [to learn more about customization](/docs/cookbook/how-to-customize-embedded-ui-style)). You can add custom css files more than one and change themes in runtime.
 After you set the css file, you should start the session with following parameters to enable custom theme.
{
projectId:
theme: ,
themeOverride: true
}
Now you are ready to embed Peaka's UI into your web application using an iframe.
Note: The application requires clipboard access to perform copy actions. Please ensure your iframe code includes allow="clipboard-write \*" to prevent browser blocking.
Note: If you want to switch between different themes in runtime you can do it with iframe's post message method.
iframeElement.contentWindow.postMessage(
{
theme:
themeOverride: true,
},
partnerOrigin:
);
Congratulations! You have successfully embedded Peaka's UI into your web application. Your users can now seamlessly interact with Peaka's interface to manage their data efficiently and effectively.
Hiding Parts of the Embedded UI
-------------------------------
In **Embedded Mode**, you can customize the Peaka UI by hiding specific components or features. To do this, use the `featureFlags` key when initiating the UI session. This allows you to tailor the interface to your application’s needs, ensuring a seamless and focused user experience.
### Example:
When initializing the UI session, specify the features you want to hide or disable using the `featureFlags` configuration. This ensures that only the relevant parts of the UI are displayed to your users. For example you can hide **queries** sections in Peaka's UI with following configuration.
curl --request POST \
--url https://partner.peaka.studio/api/v1/ui/initSession \
--header 'Content-Type: application/json' 'Authorization: Bearer '\
--data '{
"projectId":
"theme": ,
"themeOverride": true,
"featureFlags": {
"queries": false,
}
}'
For more details, refer to the [Embedded API Reference](/docs/api-reference/).
Peaka as a Connector-Only Solution
----------------------------------
When you need to use Peaka exclusively as a connector solution, you can configure the UI session to display only the connector functionality. This streamlined approach is perfect for applications that focus on data source connections without requiring the full Peaka studio experience.
First, initialize the session with following payload options:
curl --request POST \
--url https://partner.peaka.studio/api/v1/ui/initSession \
--header 'Content-Type: application/json' 'Authorization: Bearer '\
--data '{
"projectId":
"theme": ,
"themeOverride": true,
"sessionMode": <"CONNECTOR_MODAL_ONLY" | "FULL_STUDIO">,
"connectorType": ,
"catalogCreateEnabled": true,
}'
### Configuration Options:
**SessionMode**: Specifies the mode of the session. Available options are:
**ConnectorType**: Specifies the type of connector interface to display. Available options can be found in the [API Reference](/docs/api-reference/).
**CatalogCreateEnabled**: Boolean flag that controls whether catalogs are automatically created when establishing connections. The default value is `true`. Set this to `false` only when using `CONNECTOR_MODAL_ONLY` mode to prevent automatic catalog creation.
* `CONNECTOR_MODAL_ONLY`
* `FULL_STUDIO`
Note: **ConnectorType** and **CatalogCreateEnabled** are only available in the `CONNECTOR_MODAL_ONLY` mode.
### Example:
The API response includes `sessionUrl` and `partnerOrigin` properties, allowing you to open the Peaka interface in a popup window for seamless integration.
In this example, we're using the `CONNECTOR_MODAL_ONLY` mode to display only the connector modal interface. We get the session URL and partner origin from the API response and open the Peaka interface in a popup window.
fetch(`https://partner.peaka.studio/api/v1/ui/initSession`, {
method: "POST",
headers: {
"Content-Type": "application/json",
"Authorization": "Bearer "
},
body: JSON.stringify({
projectId: ,
theme: ,
themeOverride: true,
sessionMode: "CONNECTOR_MODAL_ONLY",
connectorType: ,
catalogCreateEnabled: true,
}),
}).then(async (response) => {
const res = await response.json();
// Open the Peaka connector interface in a popup window
window.open(
res.sessionUrl,
"authPopup",
`width=500,height=600,left=${window.screen.width / 2 - 500 / 2},top=${
window.screen.height / 2 - 600 / 2
},resizable=yes,scrollbars=yes,noopener=no,noreferrer=no`
);
// Handle the message from the Peaka connector popup
const handleMessage = (event) => {
// Use event.data to get the message from the Peaka connector popup when popup is closed
if (event.data.status) {
// Status might be "CANCELLED" or "FINISHED"
// If popup is closed without selection a catalog, status will be "CANCELLED"
// If popup is closed with selection a catalog, status will be "FINISHED"
console.log("Status from the Peaka connector popup:", event.data.status);
window.removeEventListener("message", handleMessage);
} else {
console.log("Data from the Peaka connector popup:", event.data);
}
};
// Listen to the message from the Peaka connector popup when popup is closed
window.addEventListener("message", handleMessage);
});
### Troubleshooting
If you are having trouble with having status from the connector popup, follow these steps to troubleshoot the issue:
* Check if you have enabled Embedded UI Settings for your API Key.
* Add your domain that you want to embed the Peaka app to the Embedded UI Settings in the Developer Settings.
On this page
* [Embed Peaka's UI in Your Web Application](https://www.peaka.com/docs/embedded-peaka/data-management-tool-with-ui/#embed-peaka-s-ui-in-your-web-application)
* [Key Benefits:](https://www.peaka.com/docs/embedded-peaka/data-management-tool-with-ui/#key-benefits)
* [TLDR;](https://www.peaka.com/docs/embedded-peaka/data-management-tool-with-ui/#tldr)
* [Prerequisites](https://www.peaka.com/docs/embedded-peaka/data-management-tool-with-ui/#prerequisites)
* [Initiate the Session](https://www.peaka.com/docs/embedded-peaka/data-management-tool-with-ui/#initiate-the-session)
* [Enabling Embedded UI for Peaka Integration Using an iframe](https://www.peaka.com/docs/embedded-peaka/data-management-tool-with-ui/#enabling-embedded-ui-for-peaka-integration-using-an-iframe)
* [Hiding Parts of the Embedded UI](https://www.peaka.com/docs/embedded-peaka/data-management-tool-with-ui/#hiding-parts-of-the-embedded-ui)
* [Example:](https://www.peaka.com/docs/embedded-peaka/data-management-tool-with-ui/#example)
* [Peaka as a Connector-Only Solution](https://www.peaka.com/docs/embedded-peaka/data-management-tool-with-ui/#peaka-as-a-connector-only-solution)
* [Configuration Options:](https://www.peaka.com/docs/embedded-peaka/data-management-tool-with-ui/#configuration-options)
* [Example:](https://www.peaka.com/docs/embedded-peaka/data-management-tool-with-ui/#example-1)
* [Troubleshooting](https://www.peaka.com/docs/embedded-peaka/data-management-tool-with-ui/#troubleshooting)
--- START: docs/embedded-peaka/data-source/data-source.md ---
Documentation menu
[Home](/) / [Docs](/docs/) / Peaka as a Data Source
 Copy as Markdown
Peaka as a Data Source
======================
Peaka serves as a powerful data source for your data warehouse, enabling you to effortlessly create and manage projects, catalogs, and caching mechanisms. Additionally, it offers a comprehensive API that allows you to execute queries and retrieve data simultaneously, enhancing your data management capabilities.
Key Features
------------
* **Project Management**: Effortlessly create and manage projects, catalogs, and caching through the intuitive Peaka UI
* **Query Execution**: Execute queries and retrieve data seamlessly using the powerful Peaka API
* **Advanced Caching**: Implement advanced caching strategies for optimized performance
* **Complex Query Handling**: Execute complex queries with ease
* **Seamless Integration**: Achieve seamless integration with existing systems
* **Efficient Data Operations**: Perform efficient data operations to enhance productivity
Step-by-Step Implementation
---------------------------
### 1\. Create a Peaka Project
* Before you start, you need to login to your Peaka account. If you don't have an account, you can sign up for a free trial [here](https://peaka.studio/signup).
* After you login, click on the "Create New Project" button.
* Enter the project name and click on the "Create Project" button.
* Your project will be created and you will be redirected to the project page.
For detailed guidance, please refer to the documentation on [how to create a project](/docs/project-operations/how-to-create-a-project).
### 2\. Create a Catalog
Once you are redirected to the project page, locate and click the plus button on the right side panel to initiate the catalog creation process.

* From the list of available options, select the catalog you wish to connect to.

* Fill in the catalog name along with any other required fields to ensure proper configuration.
* After entering the necessary information, click on the "Create" or "Sign In" button to finalize the process.
* Your catalog will be successfully created, and you can start managing your data within it.
For detailed guidance, please refer to the documentation on [how to create a catalog](/docs/connecting-your-data/add-connection).
### 3\. Caching
Once you have created the catalog, you will find the catalog table displayed in the right side panel under the "Tables" section.
* Hover over the catalog item and click on the three dots icon to reveal a dropdown menu. From this menu, select the "Start Cache" option.
* A modal will appear prompting you to confirm the caching action. Click on the "Start Initial Cache" button within this modal.
**Note**: This action may either initiate a cache job for the catalog directly or open a new modal where you can input the required fields. If prompted, fill in the necessary information and then click on the "Start Cache" button to proceed.
#### Cache Settings
When configuring the cache, you can control how and when your cached data is refreshed using the following settings:
* **Auto Update**: A toggle that enables or disables automatic cache refreshes. When turned **on**, Peaka periodically refreshes the cache based on the update frequency you select. When turned **off**, the cache is not refreshed automatically, and both the **Update Frequency** and **Cache Type** options are disabled.
* **Update Frequency**: Determines how often the cache is automatically refreshed. This option is only available when **Auto Update** is on. The available intervals are:
* Every 15 minutes
* Every 30 minutes
* Every 1 hour
* Every 2 hours
* Every 6 hours
* Every day
* Every week
* **Cache Type**: Determines how the cache is refreshed on each update. This option is only available when **Auto Update** is on. The available types are:
* **Incremental**: Updates the cache with only the new or changed data since the last refresh, resulting in faster and more efficient updates.
* **Full Refresh**: Rebuilds the entire cache from scratch on each refresh, ensuring the cached data fully matches the source.
* This will initiate the caching process for your catalog.
#### Choosing the Right Autoupdate Settings
Autoupdate keeps your cached data in sync with the source. Picking the wrong combination is the most common setup mistake, so use the scenarios below as a starting point:
* **Frequently changing data that needs to stay fresh** (e.g. orders, events): enable **Auto Update**, choose a short **Update Frequency** (Every 15 or 30 minutes), and set **Cache Type** to **Incremental**. Incremental updates only pull new or changed rows, so short intervals stay inexpensive.
* **Large tables where you mainly need recent data**: enable **Auto Update** with an **Incremental** refresh at a moderate frequency (Every 1–6 hours). Avoid frequent **Full Refresh** on large tables — rebuilding the whole cache repeatedly is slow and resource-heavy.
* **Data that must exactly match the source, including deletes and updates to old rows**: use a **Full Refresh**. Because incremental updates only add new or changed rows, schedule a less frequent Full Refresh (Every day or Every week) to guarantee the cache fully matches the source.
* **Reference or rarely changing data** (e.g. lookup tables): a low frequency such as **Every day** or **Every week** is usually enough.
* **Static data that never changes**: turn **Auto Update off**. The cache is populated once and never refreshed automatically. You can still trigger a manual refresh later if needed.
If **Auto Update** is off, your cache will **not** refresh on its own and will gradually become stale as the source changes. Only turn it off for data you know is static, or when you intend to refresh manually.
Incremental and Full Refresh can run on independent schedules. A common pattern is a frequent **Incremental** update (e.g. hourly) combined with a periodic **Full Refresh** (e.g. weekly) to catch deletes and corrections. To configure these schedules via the API, see [Cache Your Catalog](/docs/embedded-peaka/data-management-backend).
### 4\. Creating Partner API Key
* Before starting execution of query, you need to create a Partner API key. You will use this API key to authenticate your requests to the Peaka API.
* Navigate to the [Developer](https://peaka.studio/home/advanced-settings) section.
* Click on the Partner API Key button to open a dialog box.
* Fill in the form by entering your desired API Key Name.
* Click on the Create button.
* You can copy the API key from the dialog box.
For detailed guidance, please refer to the documentation on [how to create a partner API key](/docs/cookbook/how-to-manage-partner-api-key#creating-a-partner-api-key).

### 5\. Create Your Query
* Now you have created your project, API key, and catalog. Also cached your catalog.
* You are now ready to create queries that allow you to extract and refine data from your catalog based on your requirements.
For detailed guidance, please refer to the documentation on [how to create a query](/docs/api-reference/).
curl --request POST \
--url https://partner.peaka.studio/api/v1/data/projects/{projectId}/queries \
--header 'Content-Type: application/json' \
--data '{
"displayName": "sampleQuery",
"inputQuery": "SELECT * from \"mycatalog\".payment.customers"
}'
const options = {
method: 'POST',
headers: {'Content-Type': 'application/json'},
body: '{"displayName":"sampleQuery","inputQuery":"SELECT * from \"mycatalog\".payment.customers"}'
};
fetch('https://partner.peaka.studio/api/v1/data/projects/{projectId}/queries', options)
.then(response => response.json())
.then(response => console.log(response))
.catch(err => console.error(err));
import requests
url = "https://partner.peaka.studio/api/v1/data/projects/{projectId}/queries"
payload = {
"displayName": "sampleQuery",
"inputQuery": "SELECT * from \"mycatalog\".payment.customers"
}
headers = {"Content-Type": "application/json"}
response = requests.request("POST", url, json=payload, headers=headers)
print(response.text)
"https://partner.peaka.studio/api/v1/data/projects/{projectId}/queries",
CURLOPT_RETURNTRANSFER => true,
CURLOPT_ENCODING => "",
CURLOPT_MAXREDIRS => 10,
CURLOPT_TIMEOUT => 30,
CURLOPT_HTTP_VERSION => CURL_HTTP_VERSION_1_1,
CURLOPT_CUSTOMREQUEST => "POST",
CURLOPT_POSTFIELDS => "{\n \"displayName\": \"sampleQuery\",\n \"inputQuery\": \"SELECT * from \\\"mycatalog\\\".payment.customers\"\n}",
CURLOPT_HTTPHEADER => [
"Content-Type: application/json"
],
]);
$response = curl_exec($curl);
$err = curl_error($curl);
curl_close($curl);
if ($err) {
echo "cURL Error #:" . $err;
} else {
echo $response;
}
package main
import (
"fmt"
"strings"
"net/http"
"io/ioutil"
)
func main() {
url := "https://partner.peaka.studio/api/v1/data/projects/{projectId}/queries"
payload := strings.NewReader("{\n \"displayName\": \"sampleQuery\",\n \"inputQuery\": \"SELECT * from \\\"mycatalog\\\".payment.customers\"\n}")
req, _ := http.NewRequest("POST", url, payload)
req.Header.Add("Content-Type", "application/json")
res, _ := http.DefaultClient.Do(req)
defer res.Body.Close()
body, _ := ioutil.ReadAll(res.Body)
fmt.Println(res)
fmt.Println(string(body))
}
HttpResponse response = Unirest.post("https://partner.peaka.studio/api/v1/data/projects/{projectId}/queries")
.header("Content-Type", "application/json")
.body("{\n \"displayName\": \"sampleQuery\",\n \"inputQuery\": \"SELECT * from \\\"mycatalog\\\".payment.customers\"\n}")
.asString();
{
"id": "",
"displayName": "",
"name": "",
"inputQuery": "",
"inputQueryRefId": "",
"queryType": "",
"schedule": {
"expression": ""
}
}
### 6\. Run Your Query
* After creating query, you can run your query.
* After running query is completed, you will get the data in response. You can use this data for further processing or analysis as needed.
For detailed guidance, please refer to the documentation on [how to run a query](/docs/api-reference/).
curl --request POST \
--url https://partner.peaka.studio/api/v1/data/projects/{projectId}/queries/execute \
--header 'Content-Type: application/json' \
--data '{
"from": [
{
"catalogName": "peaka",
"schemaName": "query",
"tableName": "samplequery"
}
]
}'
const options = {
method: 'POST',
headers: {'Content-Type': 'application/json'},
body: '{"from":[{"catalogName":"peaka","schemaName":"query","tableName":"samplequery"}]}'
};
fetch('https://partner.peaka.studio/api/v1/data/projects/{projectId}/queries/execute', options)
.then(response => response.json())
.then(response => console.log(response))
.catch(err => console.error(err));
import requests
url = "https://partner.peaka.studio/api/v1/data/projects/{projectId}/queries/execute"
payload = {"from": [
{
"catalogName": "peaka",
"schemaName": "query",
"tableName": "samplequery"
}
]}
headers = {"Content-Type": "application/json"}
response = requests.request("POST", url, json=payload, headers=headers)
print(response.text)
"https://partner.peaka.studio/api/v1/data/projects/{projectId}/queries/execute",
CURLOPT_RETURNTRANSFER => true,
CURLOPT_ENCODING => "",
CURLOPT_MAXREDIRS => 10,
CURLOPT_TIMEOUT => 30,
CURLOPT_HTTP_VERSION => CURL_HTTP_VERSION_1_1,
CURLOPT_CUSTOMREQUEST => "POST",
CURLOPT_POSTFIELDS => "{\n \"from\": [\n {\n \"catalogName\": \"peaka\",\n \"schemaName\": \"query\",\n \"tableName\": \"samplequery\"\n }\n ]\n}",
CURLOPT_HTTPHEADER => [
"Content-Type: application/json"
],
]);
$response = curl_exec($curl);
$err = curl_error($curl);
curl_close($curl);
if ($err) {
echo "cURL Error #:" . $err;
} else {
echo $response;
}
package main
import (
"fmt"
"strings"
"net/http"
"io/ioutil"
)
func main() {
url := "https://partner.peaka.studio/api/v1/data/projects/{projectId}/queries/execute"
payload := strings.NewReader("{\n \"from\": [\n {\n \"catalogName\": \"peaka\",\n \"schemaName\": \"query\",\n \"tableName\": \"samplequery\"\n }\n ]\n}")
req, _ := http.NewRequest("POST", url, payload)
req.Header.Add("Content-Type", "application/json")
res, _ := http.DefaultClient.Do(req)
defer res.Body.Close()
body, _ := ioutil.ReadAll(res.Body)
fmt.Println(res)
fmt.Println(string(body))
}
HttpResponse response = Unirest.post("https://partner.peaka.studio/api/v1/data/projects/{projectId}/queries/execute")
.header("Content-Type", "application/json")
.body("{\n \"from\": [\n {\n \"catalogName\": \"peaka\",\n \"schemaName\": \"query\",\n \"tableName\": \"samplequery\"\n }\n ]\n}")
.asString();
{
"columns": [
{
"catalogId": "2",
"catalogName": "peaka",
"schemaName": "query",
"tableName": "samplequery",
"columnName": "amount"
}
],
"data": [
[
{
"name": "amount",
"displayName": "amount",
"dataType": "bigint",
"value": "75",
"order": 0
}
],
[
{
"name": "amount",
"displayName": "amount",
"dataType": "bigint",
"value": "75",
"order": 0
}
],
[
{
"name": "amount",
"displayName": "amount",
"dataType": "bigint",
"value": "75",
"order": 0
}
]
]
}
### 7\. Success
* You have successfully created your project, generated your API key, established your catalog, cached the catalog, and executed your query.
* This data is now ready for advanced processing and insightful analysis.
* You have effectively integrated Peaka as your robust data management backend.
On this page
* [Key Features](https://www.peaka.com/docs/embedded-peaka/data-source/#key-features)
* [Step-by-Step Implementation](https://www.peaka.com/docs/embedded-peaka/data-source/#step-by-step-implementation)
* [1\. Create a Peaka Project](https://www.peaka.com/docs/embedded-peaka/data-source/#1-create-a-peaka-project)
* [2\. Create a Catalog](https://www.peaka.com/docs/embedded-peaka/data-source/#2-create-a-catalog)
* [3\. Caching](https://www.peaka.com/docs/embedded-peaka/data-source/#3-caching)
* [4\. Creating Partner API Key](https://www.peaka.com/docs/embedded-peaka/data-source/#4-creating-partner-api-key)
* [5\. Create Your Query](https://www.peaka.com/docs/embedded-peaka/data-source/#5-create-your-query)
* [6\. Run Your Query](https://www.peaka.com/docs/embedded-peaka/data-source/#6-run-your-query)
* [7\. Success](https://www.peaka.com/docs/embedded-peaka/data-source/#7-success)
--- START: docs/embedded-peaka/introduction/introduction.md ---
Documentation menu
[Home](/) / [Docs](/docs/) / What is Embedded Peaka?
 Copy as Markdown
What is Embedded Peaka?
=======================
Embedded Peaka enables you to integrate Peaka seamlessly into your system, unlocking robust features such as **caching, semantic catalogs, query materialization,** and more. Depending on your needs, there are three distinct ways to embed Peaka:
* **As a Data Source**: Use Peaka to connect and access data directly within your system.
* **As a Data Management Backend**: Leverage Peaka’s backend capabilities to manage and optimize your data workflows.
* **As a Complete Data Management Solution**: Implement Peaka along with its user interface for comprehensive data management.
Let’s explore the different use cases and how Peaka provides tailored solutions to address these challenges.
Peaka as a Data Source
======================
Peaka can serve as a **single data source** that consolidates data from multiple sources. By integrating with Peaka’s endpoints, you can query all your data directly through Peaka. This allows you to:
* Access and query multiple data sources seamlessly.
* Simplify your integration process with a single, straightforward connection.
For more information, see the [Data Source](/docs/embedded-peaka/data-source) section.
Peaka as a Data Management Backend
==================================
Peaka can function as a **data management backend**, enabling you to:
* Manage your data sources and data catalogs.
* Create projects and catalogs.
* Connect third-party services.
* Cache data for improved performance.
For more details, refer to the [Data Management Backend](/docs/embedded-peaka/data-management-backend) section.
Peaka as a Complete Data Management Solution
============================================
Embedded Peaka allows you to integrate Peaka’s features into your own application through flexible integration options. You can use Peaka’s UI components and tools to enhance your application’s data management capabilities.
For more information, refer to the [Complete Data Management Solution](/docs/embedded-peaka/data-management-tool-with-ui) section.
On this page
* [Peaka as a Data Source](https://www.peaka.com/docs/embedded-peaka/introduction/#peaka-as-a-data-source)
* [Peaka as a Data Management Backend](https://www.peaka.com/docs/embedded-peaka/introduction/#peaka-as-a-data-management-backend)
* [Peaka as a Complete Data Management Solution](https://www.peaka.com/docs/embedded-peaka/introduction/#peaka-as-a-complete-data-management-solution)
--- START: docs/flows/connections/connections.md ---
Documentation menu
[Home](/) / [Docs](/docs/) / How to make use of Connections in Peaka
 Copy as Markdown
How to make use of Connections in Peaka
=======================================
Learn about 'Connections' in Peaka and how they allow you to work with various actions and data in your workflows
This article provides an introduction to 'Connections' in Peaka, explaining their significance in working with actions and data within your workflows.
What are 'Connections'?
-----------------------
'Connections' in Peaka are essential components that enable you to interact with various external services, data sources, and actions within your workflows. They serve as bridges between your Peaka application and external systems.
The actions you can perform with 'Connections' depend on the type of connection you create, and they can vary widely. 'Connections' are versatile and can include actions like sending emails, updating databases, triggering external events, and more.
To create a connection and configure its actions, you can refer to [this article](/docs/connecting-your-data/add-connection/).
It's important to note that each connection node may have specific parameters that you must set to ensure they function correctly. These parameters are crucial for establishing the connection and enabling seamless communication between your Peaka application and external systems.
Conclusion
----------
'Connections' play a vital role in extending the functionality of your Peaka applications and enable you to integrate with a wide range of external services and actions, enhancing the capabilities of your workflows.
On this page
* [What are 'Connections'?](https://www.peaka.com/docs/flows/connections/#what-are-connections)
* [Conclusion](https://www.peaka.com/docs/flows/connections/#conclusion)
--- START: docs/flows/how-to-create-a-flow/how-to-create-a-flow.md ---
Documentation menu
[Home](/) / [Docs](/docs/) / How to create a flow in Peaka
 Copy as Markdown
How to create a flow in Peaka
=============================
Learn how you can create different types of flows in Peaka
This article explains you can create different types of flows in Peaka.
Peaka flows have three types flows which are:
1. API & Webhooks Flows
2. Backend Flows
3. Scheduled Flows
### API & Webhooks Flows
API & Webhooks Flows are designed to handle API endpoints, enabling your front-end to interact seamlessly with your backend database.
To create an API & Webhooks Flow, you can follow the steps below:
1. Click on the "Flow & API" button in the top center of the screen.
2. From the sidebar, choose the specific type of flow you wish to create.
3. Click on the "Add Endpoint" button.
4. It will open a modal where you can enter the endpoint details.
* Path: The path of the endpoint.
* Method: The HTTP method of the endpoint.
* Description: The description of the endpoint.
5. Click on the "Create" button.
### Reusable Flows
Reusable flows are a powerful feature that allows you to define a set of actions and logic once and then call them from other flows, promoting modularity and reusability in your workflows.
To create a reusable flow, you can follow the steps below:
1. Click on the "Flow & API" button in the top center of the screen.
2. From the sidebar, choose the specific type of flow you wish to create.
3. Click on the "Flow" button.
4. It will open a modal where you can enter the flow details.
* Name: The name of the flow.
* Description: The description of the flow.
5. Click on the "Add Flow" button.
### Scheduled Flows
Scheduled flows are designed to automate tasks that need to run at specific intervals.
To create a scheduled flow, you can follow the steps below:
1. Click on the "Flow & API" button in the top center of the screen.
2. From the sidebar, choose the specific type of flow you wish to create.
3. Click on the "Flow" button.
4. It will open a modal where you can enter the flow details.
* Name: The name of the flow.
* Description: The description of the flow.
5. Click on the "Add Flow" button.
On this page
* [API & Webhooks Flows](https://www.peaka.com/docs/flows/how-to-create-a-flow/#api-webhooks-flows)
* [Reusable Flows](https://www.peaka.com/docs/flows/how-to-create-a-flow/#reusable-flows)
* [Scheduled Flows](https://www.peaka.com/docs/flows/how-to-create-a-flow/#scheduled-flows)
--- START: docs/flows/http-request/http-request.md ---
Documentation menu
[Home](/) / [Docs](/docs/) / How to make use of the HTTP Request node in Peaka
 Copy as Markdown
How to make use of the HTTP Request node in Peaka
=================================================
Learn about the HTTP Request node in Peaka and how you can use it to make HTTP requests and handle response
This article provides an introduction to the HTTP Request node in Peaka, explaining its role in making HTTP requests and managing responses.

What is the HTTP Request Node?
------------------------------
The HTTP Request node is a powerful feature in Peaka that allows you to send HTTP requests to external APIs or services and retrieve data. It supports various HTTP methods such as GET, POST, PUT, PATCH, and DELETE, and provides options for configuring request parameters, headers, request body, and authorization.
Using the HTTP Request Node
---------------------------
To use the HTTP Request node effectively, follow these steps:
1. Insert an "HTTP Request" node into your workflow.
2. Configure the details of the HTTP request by specifying the HTTP method, URL, request parameters, headers, request body, and authorization settings.
3. After configuring the request, you can click on the "Send" button to initiate the request. The result of the request will be displayed, showing the response data.


4. If you want to extract specific data from the response, you can use the "Select Data" tab in the modal. This allows you to choose which data elements to capture. Variables will be created for the selected data, which you can view on the right side of the "Select Data" tab.

5. You can access the results of the HTTP request by using the variables created for the response data in your project.

Conclusion
----------
The HTTP Request node empowers you to interact with external APIs and services seamlessly, making it a versatile tool for integrating data and functionality into your Peaka applications.
On this page
* [What is the HTTP Request Node?](https://www.peaka.com/docs/flows/http-request/#what-is-the-http-request-node)
* [Using the HTTP Request Node](https://www.peaka.com/docs/flows/http-request/#using-the-http-request-node)
* [Conclusion](https://www.peaka.com/docs/flows/http-request/#conclusion)
--- START: docs/flows/loops/loops.md ---
Documentation menu
[Home](/) / [Docs](/docs/) / How to make use of loops in Peaka
 Copy as Markdown
How to make use of loops in Peaka
=================================
Learn about different types of loops in Peaka and how they can enhance your workflows
This article provides an introduction to loops in Peaka and explains the three types of loops available: Loop List, Loop Forever, and Break.

Types of Loops
--------------
In Peaka, you can utilize three types of loops to control the flow of your workflow:
### Loop List
The **Loop List** allows you to iterate over each item in an array and execute a series of nodes for each item. Here's how it works:

1. Provide an array of items that you want to loop through in the "Items" field.
2. Specify a variable name in the "Variable Name" field. This variable will represent each item in the array during each iteration.
3. You can access the value of each array item using the variable name you defined.

### Loop Forever
The **Loop Forever** node allows a sequence of nodes to run continuously until a **Break** node is triggered to stop the loop. This type of loop is useful for creating continuous or repeated actions.

### Break
The **Break** node is used to stop the execution of a loop, specifically the **Loop Forever** loop. When a **Break** node is encountered within the loop, the loop stops executing.

Conclusion
----------
Loops are a powerful tool in Peaka workflows, enabling you to perform repetitive tasks, iterate through data, and control the flow of your application. Understanding how to use these loop types effectively can enhance your workflow automation capabilities.
On this page
* [Types of Loops](https://www.peaka.com/docs/flows/loops/#types-of-loops)
* [Loop List](https://www.peaka.com/docs/flows/loops/#loop-list)
* [Loop Forever](https://www.peaka.com/docs/flows/loops/#loop-forever)
* [Break](https://www.peaka.com/docs/flows/loops/#break)
* [Conclusion](https://www.peaka.com/docs/flows/loops/#conclusion)
--- START: docs/flows/reusable-flows/reusable-flows.md ---
Documentation menu
[Home](/) / [Docs](/docs/) / How to implement reusable flows in Peaka
 Copy as Markdown
How to implement reusable flows in Peaka
========================================
Learn what reusable flows are and how to implement them in your Peaka workflows
This article provides insights into reusable flows and explains how to utilize them effectively within your Peaka workflows.
What Are Reusable Flows?
------------------------
Reusable flows are a versatile feature in Peaka that allows you to create and reuse a specific set of actions and logic across different parts of your application. These flows can be employed within component flows, backend flows, or even other reusable flows, enhancing the modularity and reusability of your workflows.
Creating a Reusable Flow
------------------------
To create a reusable flow, follow these steps:
1. If you're not familiar with the process, refer to our guide on [How to Create a Flow](/docs/flows/how-to-create-a-flow/) for detailed instructions on creating flows.
2. Once you have your reusable flow ready, navigate to the flow where you want to implement it.
3. Click the plus icon in your flow editor to add a new node.
4. Select the 'Reusable Flow' button from the available node options.
5. From the configuration options, choose the specific reusable flow that you wish to implement.
Congratulations! You have successfully implemented a reusable flow within your workflow.
Conclusion
----------
Utilizing reusable flows streamlines your development process, encourages code reusability, and simplifies maintenance, making it an essential tool for efficient application development in Peaka.
On this page
* [What Are Reusable Flows?](https://www.peaka.com/docs/flows/reusable-flows/#what-are-reusable-flows)
* [Creating a Reusable Flow](https://www.peaka.com/docs/flows/reusable-flows/#creating-a-reusable-flow)
* [Conclusion](https://www.peaka.com/docs/flows/reusable-flows/#conclusion)
--- START: docs/flows/set-flow-variable/set-flow-variable.md ---
Documentation menu
[Home](/) / [Docs](/docs/) / How to make use of the 'Set Flow Variable' node in Peaka
 Copy as Markdown
How to make use of the 'Set Flow Variable' node in Peaka
========================================================
Learn about the 'Set Flow Variable' node in Peaka and how to use it to create variables within a specific flow
This article provides an overview of the 'Set Flow Variable' node in Peaka and explains its role in creating variables that are specific to a particular flow.
What is the 'Set Flow Variable' Node?
-------------------------------------
The 'Set Flow Variable' node is a vital element in Peaka that allows you to create variables within the context of a specific flow. These variables are isolated and can only be accessed within the flow where they are created.
Creating Flow-Specific Variables
--------------------------------
To create a flow-specific variable using the 'Set Flow Variable' node, follow these steps:
1. Start by selecting the 'Set Flow Variable' node within your flow.
2. Define the variable you want to create and assign it a value.
That's it! You've now created a variable that is accessible only within the scope of the current flow.
Conclusion
----------
The 'Set Flow Variable' node enhances the modularity and control of your workflows by enabling you to create and utilize flow-specific variables for various purposes.
On this page
* [What is the 'Set Flow Variable' Node?](https://www.peaka.com/docs/flows/set-flow-variable/#what-is-the-set-flow-variable-node)
* [Creating Flow-Specific Variables](https://www.peaka.com/docs/flows/set-flow-variable/#creating-flow-specific-variables)
* [Conclusion](https://www.peaka.com/docs/flows/set-flow-variable/#conclusion)
--- START: docs/flows/success-fail/success-fail.md ---
Documentation menu
[Home](/) / [Docs](/docs/) / How to make use of the 'Success' and 'Fail' nodes in Peaka
 Copy as Markdown
How to make use of the 'Success' and 'Fail' nodes in Peaka
==========================================================
Learn about the 'Success' and 'Fail' nodes in Peaka, which are used to manage the flow and handle success or failure scenarios
This article provides an introduction to the 'Success' and 'Fail' nodes in Peaka, explaining their roles in managing the flow and handling success or failure scenarios.
What are 'Success' and 'Fail' Nodes?
------------------------------------
The 'Success' and 'Fail' nodes are critical components in Peaka workflows that allow you to manage the flow of your application based on success or failure outcomes.
When the 'Success' node is executed, it signifies that a particular operation or task has been successfully completed, and it typically marks the end of a successful branch in your workflow.

The 'Fail' node, on the other hand, indicates that an operation has failed or encountered an error. When the 'Fail' node is triggered, it will stop the faulty flow.
You can customize the error message or response by specifying parameters in the 'Fail' node.
Conclusion
----------
These nodes are essential for handling success and failure scenarios within your Peaka applications, allowing you to build robust and error-tolerant workflows.
On this page
* [What are 'Success' and 'Fail' Nodes?](https://www.peaka.com/docs/flows/success-fail/#what-are-success-and-fail-nodes)
* [Conclusion](https://www.peaka.com/docs/flows/success-fail/#conclusion)
--- START: docs/flows/switch-case/switch-case.md ---
Documentation menu
[Home](/) / [Docs](/docs/) / How to make use of the 'Switch / Case' node in Peaka
 Copy as Markdown
How to make use of the 'Switch / Case' node in Peaka
====================================================
Learn about the 'Switch / Case' node in Peaka, which allows you to create conditional logic in your workflows
This article provides an introduction to the 'Switch / Case' node in Peaka, explaining its role in creating conditional logic within your workflows.
What is the 'Switch / Case' Node?
---------------------------------
The 'Switch / Case' node is a fundamental component in Peaka that enables you to create conditional logic. It allows you to define cases and associate specific actions or nodes with each case. The node evaluates conditions and executes the corresponding case based on the condition that matches.
Conclusion
----------
'Switch / Case' is a versatile feature for adding decision-making capabilities to your workflows. You can use it to create branching logic, handle different scenarios, and control the flow of your Peaka applications effectively.
On this page
* [What is the 'Switch / Case' Node?](https://www.peaka.com/docs/flows/switch-case/#what-is-the-switch-case-node)
* [Conclusion](https://www.peaka.com/docs/flows/switch-case/#conclusion)
--- START: docs/flows/what-is-output-and-how-to-use-it/what-is-output-and-how-to-use-it.md ---
Documentation menu
[Home](/) / [Docs](/docs/) / The concept of 'Output' and how to make use of it in Peaka
 Copy as Markdown
The concept of 'Output' and how to make use of it in Peaka
==========================================================
Learn about the concept of output and how to make use of flow components in Peaka
This article explains the concept of outputs in Peaka and provides guidance on how to make the most of them in your workflows.
Understanding Outputs
---------------------
In Peaka, outputs are automatically generated variables that capture data returned by a node within your workflow. These variables store the results of node execution, allowing you to access and manipulate the data for further actions or processing.

Creating Custom Output Variables
--------------------------------
Besides automatically generated output variables, you can also create custom output variables to store specific data or results from your workflow. This feature provides flexibility and control over the data you want to capture.

Utilizing Output Variables
--------------------------
To use output variables in your workflow, simply refer to them by their assigned names. You can access the data they contain and incorporate it into subsequent nodes or actions, as illustrated in the image below.

Conclusion
----------
Outputs in Peaka enhance the flexibility and versatility of your workflows. They enable you to capture and manipulate data efficiently, facilitating seamless integration and automation of your projects.
On this page
* [Understanding Outputs](https://www.peaka.com/docs/flows/what-is-output-and-how-to-use-it/#understanding-outputs)
* [Creating Custom Output Variables](https://www.peaka.com/docs/flows/what-is-output-and-how-to-use-it/#creating-custom-output-variables)
* [Utilizing Output Variables](https://www.peaka.com/docs/flows/what-is-output-and-how-to-use-it/#utilizing-output-variables)
* [Conclusion](https://www.peaka.com/docs/flows/what-is-output-and-how-to-use-it/#conclusion)
--- START: docs/integrations/activecampaign/activecampaign.md ---
Documentation menu
[Home](/) / [Docs](/docs/) / ActiveCampaign
 Copy as Markdown
ActiveCampaign
==============
Discover a seamless integration process! Learn how to connect ActiveCampaign to Peaka effortlessly for streamlined transactions.
This article guides you through the process of connecting ActiveCampaign to Peaka, allowing you to seamlessly access your ActiveCampaign data within the Peaka platform.
Prerequisites
-------------
Before you start, you will need an API Key and an API URL from ActiveCampaign.
Follow the steps below to obtain it:
1. Visit the [ActiveCampaign website](https://www.activecampaign.com/) and log in.
2. Click on the "Settings" button and click on the "Developer" button on the side bar, as shown in the image below:
3. Copy the API key and the API URL.
Connecting ActiveCampaign to Peaka
----------------------------------
Now that you have your ActiveCampaign API URL and API Key, you can connect it to Peaka using the following steps:
1. Navigate to the data model page in Peaka.
2. In the side menu bar, click the "New Data Source" button to initiate the connection process.
3. In the modal that appears, select "ActiveCampaign" as your data source.
4. Enter a name for your data source name and paste the ActiveCampaign API URL and API Key into the input fields.
5. Click "Authorize" to create your ActiveCampaign data source.
Congratulations! You've successfully connected ActiveCampaign to Peaka. You can now access and manage your ActiveCampaign data seamlessly within the Peaka platform.
On this page
* [Prerequisites](https://www.peaka.com/docs/integrations/activecampaign/#prerequisites)
* [Connecting ActiveCampaign to Peaka](https://www.peaka.com/docs/integrations/activecampaign/#connecting-activecampaign-to-peaka)
--- START: docs/integrations/acumatica/acumatica.md ---
Documentation menu
[Home](/) / [Docs](/docs/) / Acumatica
 Copy as Markdown
Acumatica
=========
This guide explains how to connect your Acumatica ERP instance to Peaka in order to access and analyze your Acumatica data within the Peaka platform.
This article guides you through the process of connecting Acumatica to Peaka, allowing you to seamlessly access your Acumatica data within the Peaka platform.
Prerequisites
-------------
Acumatica has no central sign-in service: every instance is its own authorization server, so the application Peaka signs in as has to be registered inside your own instance. Before you start, you will need the following:
* Instance URL
* Client ID
* Client Secret
To register the application you need access to the Connected Applications (SM303010) form, which usually means an administrator account. Sign in to the tenant whose data you want to query before you begin — the client ID Acumatica generates is bound to that tenant, and the application will only ever see that tenant's data.
Registering Peaka in Acumatica
------------------------------
1. On the System tab, click "Integration". In the navigation pane, navigate to Configure > Connected Applications.
2. In the "Client Name" box, type a name for the application, for example `Peaka`.
3. In the "OAuth 2.0 Flow" box, select "Authorization Code".
4. On the "Secrets" tab, click "Add Shared Secret" on the tab toolbar. Type a description, then copy the value shown in the "Value" box and keep it somewhere safe — this is your Client Secret, and Acumatica does not display it again.
Leave "Expires On (UTC)" empty unless you plan to rotate the secret. If you enter a date, the connection stops working on that date and has to be reconnected with a new secret.
5. On the "Redirect URIs" tab, click "Add Row" and enter the Peaka callback URL:
https://peaka.studio/oauth2/callback
The redirect URI has to match exactly, has to be absolute, and must not contain a fragment (the part after `#`).
6. On the form toolbar, click "Save". The generated client ID now appears in the "Client ID" box.
You do not need to configure any scopes: Peaka requests the permissions it needs when you authorize the connection.
For the full reference, see Acumatica's [Connected Applications](https://help.acumatica.com/Wiki/ShowWiki.aspx?pageid=6ca02ea1-884d-4981-9d72-0fa83b40028c) documentation.
Connecting Acumatica to Peaka
-----------------------------
Now that you have obtained the necessary integration data and credentials, you can connect Acumatica to Peaka using the following steps:
1. Navigate to the data model page in Peaka.
2. In the side menu bar, click the "New Data Source" button to initiate the connection process.
3. In the modal that appears, select "Acumatica" as your data source.
4. Enter a name for your data source, then enter the Instance URL of your Acumatica instance — for example `https://acme.acumatica.com` — along with the Client ID and Client Secret you obtained in the previous steps.
5. Click "Authorize". You are taken to your Acumatica instance to sign in and approve access, and returned to Peaka once you do.
Congratulations! You've successfully connected Acumatica to Peaka. You can now access and manage your Acumatica data seamlessly within the Peaka platform.
On this page
* [Prerequisites](https://www.peaka.com/docs/integrations/acumatica/#prerequisites)
* [Registering Peaka in Acumatica](https://www.peaka.com/docs/integrations/acumatica/#registering-peaka-in-acumatica)
* [Connecting Acumatica to Peaka](https://www.peaka.com/docs/integrations/acumatica/#connecting-acumatica-to-peaka)
--- START: docs/integrations/airtable/airtable.md ---
Documentation menu
[Home](/) / [Docs](/docs/) / Airtable
 Copy as Markdown
Airtable
========
Discover a seamless integration process! Learn how to connect Airtable to Peaka effortlessly for streamlined transactions.
This article guides you through the process of connecting Airtable to Peaka, allowing you to seamlessly access your Airtable data within the Peaka platform.
Prerequisites
-------------
Before you start, you will need an Personal Access Token from Airtable.
Follow the steps below to obtain it:
1. Visit the [Airtable website](https://airtable.com).
2. Click on the "Developer Hub" button, as shown in the image below:
3. Create an API Token by clicking the "Create Token" button. You can select the necessary scopes and workspaces for your integration:
4. Once the token is created, it will be displayed in a modal. Copy the API Token for later use:
Connecting Airtable to Peaka
----------------------------
Now that you have your Airtable API Token, you can connect it to Peaka using the following steps:
1. Navigate to the data model page in Peaka.
2. In the side menu bar, click the "New Data Source" button to initiate the connection process.
3. In the modal that appears, select "Airtable" as your data source.
4. Enter a name for your data source name and paste the Airtable API Token into the "Personal Access Token" input field.
5. Click "Authorize" to create your Airtable data source.
Congratulations! You've successfully connected Airtable to Peaka. You can now access and manage your Airtable data seamlessly within the Peaka platform.
On this page
* [Prerequisites](https://www.peaka.com/docs/integrations/airtable/#prerequisites)
* [Connecting Airtable to Peaka](https://www.peaka.com/docs/integrations/airtable/#connecting-airtable-to-peaka)
--- START: docs/integrations/amazon-athena/amazon-athena.md ---
Documentation menu
[Home](/) / [Docs](/docs/) / Amazon Athena
 Copy as Markdown
Amazon Athena
=============
Discover a seamless integration process! Learn how to connect Amazon Athena to Peaka effortlessly for streamlined transactions.
This article guides you through the process of connecting Amazon Athena to Peaka, allowing you to seamlessly access your Amazon Athena data within the Peaka platform.
Prerequisites
-------------
Before you start, you will need the following information from your AWS account:
* **Region** (The AWS region where your Athena resources are located)
* **Catalog** (The data source catalog name, typically `AwsDataCatalog` for AWS Glue)
* **Access Key ID** (The access key ID for your AWS account or IAM user)
* **Secret Access Key** (The secret access key for your AWS account or IAM user)
Follow the steps below to obtain these values:
1. **Region:** Identify the AWS region where your Athena workgroup and data reside. You can find your current region in the top-right corner of the [AWS Management Console](https://console.aws.amazon.com/). For more details, refer to the [AWS region selection guide](https://docs.aws.amazon.com/awsconsolehelpdocs/latest/gsg/select-region-procedure.html).
2. **Catalog:** The catalog name refers to the data source catalog registered in Athena. If you are using AWS Glue Data Catalog, the default catalog name is `AwsDataCatalog`. For more details, see the [Athena data sources documentation](https://docs.aws.amazon.com/athena/latest/ug/data-sources-glue.html).
3. **Access Key ID and Secret Access Key:** Generate an access key pair from the AWS IAM console.
* For IAM users, follow the [IAM user access key guide](https://docs.aws.amazon.com/IAM/latest/UserGuide/access-keys-admin-managed.html#admin-create-access-key).
* For root users, follow the [root user access key guide](https://docs.aws.amazon.com/IAM/latest/UserGuide/id_root-user_manage_add-key.html).
Connecting Amazon Athena to Peaka
---------------------------------
Now that you have obtained the necessary credentials, you can connect Amazon Athena to Peaka using the following steps:
1. Navigate to the data model page in Peaka.
2. In the side menu bar, click the "Data Source" button to initiate the connection process.
3. In the modal that appears, select "Amazon Athena" as your data source.
4. Fill out the connection details form as shown in the image below.
5. Click "Connect" to create your Amazon Athena data source.
Congratulations! You've successfully connected Amazon Athena to Peaka. You can now access and manage your Amazon Athena data seamlessly within the Peaka platform.
On this page
* [Prerequisites](https://www.peaka.com/docs/integrations/amazon-athena/#prerequisites)
* [Connecting Amazon Athena to Peaka](https://www.peaka.com/docs/integrations/amazon-athena/#connecting-amazon-athena-to-peaka)
--- START: docs/integrations/amazon-rds/amazon-rds.md ---
Documentation menu
[Home](/) / [Docs](/docs/) / Amazon RDS
 Copy as Markdown
Amazon RDS
==========
Discover a seamless integration process! Learn how to connect Amazon RDS to Peaka effortlessly for streamlined transactions.
This article guides you through the process of connecting Amazon RDS to Peaka, allowing you to seamlessly access your Amazon RDS data within the Peaka platform.
Prerequisites
-------------
Before you start, you will need to obtain certain values, which you can get from Amazon RDS.
Peaka now supports three different databases: MySQL, PostgreSQL, and MariaDB. You can select any of these options. If you switch to "Aurora," your database will remain on Amazon instances. This option is only available for MySQL and PostgreSQL databases.

You need to select your AWS region and enter the URL and port. For a PostgreSQL database, you also need to enter the database name. You can obtain these values from your Amazon account.
You can authenticate using one of three methods: IAM, Secret Manager, or Password. The requirements are as follows:
**IAM**: User Name, AWS Access Key, and AWS Secret Key. Check this [article](https://docs.aws.amazon.com/AmazonRDS/latest/UserGuide/database-authentication.html) to get credentials.
**Secret Manager**: Secret Manager ARN, AWS Access Key, and AWS Secret Key. Check this [article](https://docs.aws.amazon.com/AmazonRDS/latest/UserGuide/rds-secrets-manager.html) to get credentials.
**Password**: User Name and Password. Check this [article](https://docs.aws.amazon.com/AmazonRDS/latest/UserGuide/database-authentication.html) to get credentials.
Connecting Amazon RDS to Peaka
------------------------------
Now that you have Amazon RDS, you can connect it to Peaka using the following steps:
1. Navigate to the data model page in Peaka.
2. In the side menu bar, click the "New Data Source" button to initiate the connection process.
3. In the modal that appears, select "Amazon RDS" as your data source.
4. Enter the values you obtained earlier.

5. Click "Connect" to create your Amazon RDS data source.
Congratulations! You've successfully connected Amazon RDS to Peaka. You can now access and manage your Amazon RDS data seamlessly within the Peaka platform.
On this page
* [Prerequisites](https://www.peaka.com/docs/integrations/amazon-rds/#prerequisites)
* [Connecting Amazon RDS to Peaka](https://www.peaka.com/docs/integrations/amazon-rds/#connecting-amazon-rds-to-peaka)
--- START: docs/integrations/bigquery/bigquery.md ---
Documentation menu
[Home](/) / [Docs](/docs/) / BigQuery
 Copy as Markdown
BigQuery
========
Discover a seamless integration process! Learn how to connect BigQuery to Peaka effortlessly for streamlined transactions.
This article guides you through the process of connecting BigQuery to Peaka, allowing you to seamlessly access your BigQuery data within the Peaka platform.
Prerequisites
-------------
Before you start, you will need the following information from BigQuery.
* Project ID
* Parent Project ID (optional)
* Credentials in JSON format
Follow the steps below to obtain it:
1. Go to the BigQuery dashboard. You can find your Project ID in the blue squared area.

2. Visit the [Credentials page](https://console.cloud.google.com/apis/credentials).
3. Select "+Create credentials" and then choose "Service account."

4. Enter a name for the service account (e.g., "Peaka BigQuery Read Account") and select "Create and Continue."

5. Ensure the service account has the following permissions:
* BigQuery Data Editor
* BigQuery User

6. You can skip the optional user access step and select "Done."
7. Your servise account will be created and click on the service account email.

8. Click the "Add Key" button and select "Create New Key."

9. Choose the "JSON" file format and click the "Create" button. This will download a JSON key file that you'll need for the integration.

Connecting BigQuery to Peaka
----------------------------
Now that you have obtained the necessary integration data and credentials, you can connect BigQuery to Peaka using the following steps:
1. Navigate to the data model page in Peaka.
2. In the side menu bar, click the "New Data Source" button to initiate the connection process.
3. In the modal that appears, select "BigQuery" as your data source.
4. Enter a name for your data source and upload the credentials JSON file you downloaded in step 9.

5. Click "Next" to create your BigQuery data source.
Congratulations! You've successfully connected BigQuery to Peaka. You can now access and manage your BigQuery data seamlessly within the Peaka platform.
On this page
* [Prerequisites](https://www.peaka.com/docs/integrations/bigquery/#prerequisites)
* [Connecting BigQuery to Peaka](https://www.peaka.com/docs/integrations/bigquery/#connecting-bigquery-to-peaka)
--- START: docs/integrations/clickhouse/clickhouse.md ---
Documentation menu
[Home](/) / [Docs](/docs/) / Clickhouse
 Copy as Markdown
Clickhouse
==========
Discover a seamless integration process! Learn how to connect Clickhouse to Peaka effortlessly for streamlined transactions.
This article guides you through the process of connecting Clickhouse to Peaka, allowing you to seamlessly access your Clickhouse data within the Peaka platform.
Prerequisites
-------------
Before you start, you will need the following information from Clickhouse.
* URL
* PORT
* User Name
* Password
* SSL (Toggle "Connect Through TLS" switch)
Follow the steps below to obtain it:
1. Open the Clickhouse dashboard.
2. Click on the "Connect" button as shown in the image below.
3. It will open a modal and show the data source detail such as URL, PORT, User Name, and Password.
Connecting Clickhouse to Peaka
------------------------------
Now that you have obtained the necessary integration data and credentials, you can connect Clickhouse to Peaka using the following steps:
1. Navigate to the data model page in Peaka.
2. In the side menu bar, click the "New Data Source" button to initiate the connection process.
3. In the modal that appears, select "Clickhouse" as your data source.
4. Enter a name for your data source, input the credentials you obtained in the previous steps, and toggle the "Connect Through TLS" switch if SSL is required.
5. Click "Next" to create your Clickhouse data source.
Congratulations! You've successfully connected Clickhouse to Peaka. You can now access and manage your Clickhouse data seamlessly within the Peaka platform.
On this page
* [Prerequisites](https://www.peaka.com/docs/integrations/clickhouse/#prerequisites)
* [Connecting Clickhouse to Peaka](https://www.peaka.com/docs/integrations/clickhouse/#connecting-clickhouse-to-peaka)
--- START: docs/integrations/databricks/databricks.md ---
Documentation menu
[Home](/) / [Docs](/docs/) / Databricks
 Copy as Markdown
Databricks
==========
Discover a seamless integration process! Learn how to connect Databricks to Peaka effortlessly for streamlined transactions.
This article guides you through the process of connecting Databricks to Peaka, allowing you to seamlessly access your Databricks data within the Peaka platform.
Prerequisites
-------------
Before you start, you will need the following information from Databricks.
* URL
* PORT
* HTTP Path
* User Email Address
* Personal Access Token
Follow the steps below to obtain it:
1. To obtain get URL, PORT and HTTP path, check this [article](https://docs.databricks.com/en/integrations/compute-details.html#:~:text=do%20the%20following%3A-,Log%20in%20to%20your%20Databricks%20workspace.,%2C%20Port%2C%20and%20HTTP%20path.).
2. To obtain get User Email Address, check this [article](https://docs.databricks.com/api/account/accountusers/get).
3. To obtain get Personal Access Token, check this [article](https://docs.databricks.com/aws/en/dev-tools/auth/pat#databricks-personal-access-tokens-for-workspace-users).
Connecting Databricks to Peaka
------------------------------
Now that you have obtained the necessary integration data and credentials, you can connect Databricks to Peaka using the following steps:
1. Navigate to the data model page in Peaka.
2. In the side menu bar, click the "New Data Source" button to initiate the connection process.
3. In the modal that appears, select "Databricks" as your data source.
4. Enter a name for your data source, input the credentials you obtained in the previous steps.

5. Click "Next" to create your Databricks data source.
Congratulations! You've successfully connected Databricks to Peaka. You can now access and manage your Databricks data seamlessly within the Peaka platform.
On this page
* [Prerequisites](https://www.peaka.com/docs/integrations/databricks/#prerequisites)
* [Connecting Databricks to Peaka](https://www.peaka.com/docs/integrations/databricks/#connecting-databricks-to-peaka)
--- START: docs/integrations/dynamics-365/dynamics-365.md ---
Documentation menu
[Home](/) / [Docs](/docs/) / Dynamics 365
 Copy as Markdown
Dynamics 365
============
Discover a seamless integration process! Learn how to connect Dynamics 365 to Peaka effortlessly for streamlined transactions.
This article guides you through the process of connecting Dynamics 365 to Peaka, allowing you to seamlessly access your Dynamics 365 data within the Peaka platform.
Prerequisites
-------------
Before you start, you will need the following information from Dynamics 365.
* Dynamics 365 URL
* Client ID (required for advanced authentication)
* Client Secret (required for advanced authentication)
Follow the steps below to obtain it:
1. To obtain the Dynamics 365 URL, refer to this [article](https://community.dynamics.com/blogs/post/?postid=d1ebf5d8-0a0c-41af-91ff-cd25f1cb37f7).
2. To obtain the Client ID and Client Secret, refer to this [article](https://learn.microsoft.com/en-us/dynamics365/finance/localizations/global/universal-tax-rate-api-how-to-setup-clientid-and-clientsecret).
Connecting Dynamics 365 to Peaka
--------------------------------
Now that you have obtained the necessary integration data and credentials, you can connect Dynamics 365 to Peaka using the following steps:
1. Navigate to the data model page in Peaka.
2. In the side menu bar, click the "New Data Source" button to initiate the connection process.
3. In the modal that appears, select "Dynamics 365" as your data source.
4. Enter a name for your data source, input the credentials you obtained in the previous steps.

5. Click "Sign in" to create your Dynamics 365 data source.
Congratulations! You've successfully connected Dynamics 365 to Peaka. You can now access and manage your Dynamics 365 data seamlessly within the Peaka platform.
On this page
* [Prerequisites](https://www.peaka.com/docs/integrations/dynamics-365/#prerequisites)
* [Connecting Dynamics 365 to Peaka](https://www.peaka.com/docs/integrations/dynamics-365/#connecting-dynamics-365-to-peaka)
--- START: docs/integrations/elastic-search/elastic-search.md ---
Documentation menu
[Home](/) / [Docs](/docs/) / ElasticSearch
 Copy as Markdown
ElasticSearch
=============
Discover a seamless integration process! Learn how to connect ElasticSearch to Peaka effortlessly for streamlined transactions.
This article guides you through the process of connecting ElasticSearch to Peaka, allowing you to seamlessly access your ElasticSearch data within the Peaka platform.
Prerequisites
-------------
Before you start, you will need the following information from ElasticSearch.
* Host
* Port
* User name
* SSL (Enable this option if you want to use SSL)
Follow the steps below to obtain it:
1. To obtain the Host and Port, navigate to the developer page and copy the ElasticSearch cluster URL. You can extract the Host and Port from the URL.

2. Navigate to the developer page and click on the "Reset Password" button as shown in the image.

3. To obtain User name and Password, cLick on the Reset Password button as in the image, and your default user name is "elastic".

Connecting ElasticSearch to Peaka
---------------------------------
Now that you have obtained the necessary integration data and credentials, you can connect ElasticSearch to Peaka using the following steps:
1. Navigate to the data model page in Peaka.
2. In the side menu bar, click the "New Data Source" button to initiate the connection process.
3. In the modal that appears, select "ElasticSearch" as your data source.
4. Enter a name for your data source, input the credentials you obtained in the previous steps.

5. Click "Authorize" to create your ElasticSearch data source.
Congratulations! You've successfully connected ElasticSearch to Peaka. You can now access and manage your ElasticSearch data seamlessly within the Peaka platform.
On this page
* [Prerequisites](https://www.peaka.com/docs/integrations/elastic-search/#prerequisites)
* [Connecting ElasticSearch to Peaka](https://www.peaka.com/docs/integrations/elastic-search/#connecting-elasticsearch-to-peaka)
--- START: docs/integrations/excel-365/excel-365.md ---
Documentation menu
[Home](/) / [Docs](/docs/) / Excel 365
 Copy as Markdown
Excel 365
=========
Discover a seamless integration process! Learn how to connect Excel 365 to Peaka effortlessly for streamlined transactions.
This article guides you through the process of connecting Excel 365 to Peaka, allowing you to seamlessly access your Excel 365 data within the Peaka platform.
Connecting Excel 365 to Peaka
-----------------------------
1. Navigate to the data model page in Peaka.
2. In the side menu bar, click the "New Data Source" button to initiate the connection process.
3. In the modal that appears, select "Excel 365" as your data source.
4. Enter a name for your data source.
5. Click the "Sign in" button to log in with your Excel 365 account. A pop-up window will appear, redirecting you to the Excel 365 login page.
6. Click the "Accept" button which will create your Excel 365 data source.
Congratulations! You've successfully connected Excel 365 to Peaka. You can now access and manage your Excel 365 data seamlessly within the Peaka platform.
On this page
* [Connecting Excel 365 to Peaka](https://www.peaka.com/docs/integrations/excel-365/#connecting-excel-365-to-peaka)
--- START: docs/integrations/facebook-ads/facebook-ads.md ---
Documentation menu
[Home](/) / [Docs](/docs/) / Facebook Ads
 Copy as Markdown
Facebook Ads
============
Discover a seamless integration process! Learn how to connect Facebook Ads to Peaka effortlessly for streamlined transactions.
This article guides you through the process of connecting Facebook Ads to Peaka, allowing you to seamlessly access your Facebook Ads data within the Peaka platform.
Prerequisites
-------------
Before you start, you will need the following information from Facebook Ads.
* Default Ad Account ID
* Client ID (required for advanced authentication)
* Client Secret (required for advanced authentication)
Follow the steps below to obtain it:
1. To obtain the Default Ad Account ID, refer to this [article](https://www.facebook.com/business/help/1492627900875762).
2. To obtain the Client ID and Client Secret, refer to this [article](https://developers.facebook.com/docs/facebook-login/guides/advanced/manual-flow/#confirm).
Connecting Facebook Ads to Peaka
--------------------------------
Now that you have obtained the necessary integration data and credentials, you can connect Facebook Ads to Peaka using the following steps:
1. Navigate to the data model page in Peaka.
2. In the side menu bar, click the "New Data Source" button to initiate the connection process.
3. In the modal that appears, select "Facebook Ads" as your data source.
4. Enter a name for your data source, input the credentials you obtained in the previous steps.
5. Click "Sign in" to create your Facebook Ads data source.
Congratulations! You've successfully connected Facebook Ads to Peaka. You can now access and manage your Facebook Ads data seamlessly within the Peaka platform.
On this page
* [Prerequisites](https://www.peaka.com/docs/integrations/facebook-ads/#prerequisites)
* [Connecting Facebook Ads to Peaka](https://www.peaka.com/docs/integrations/facebook-ads/#connecting-facebook-ads-to-peaka)
--- START: docs/integrations/firebase/firebase.md ---
Documentation menu
[Home](/) / [Docs](/docs/) / Firebase
 Copy as Markdown
Firebase
========
Discover a seamless integration process! Learn how to connect Firebase to Peaka effortlessly for streamlined transactions.
This article guides you through the process of connecting Firebase to Peaka, allowing you to seamlessly access your Firebase data within the Peaka platform.
Prerequisites
-------------
Before you start, you will need the following information from Firebase.
* Service Account JSON
Follow the steps below to obtain it:
1. To obtain the Service Account JSON, navigate to the Firebase Console, go to the "Project Settings" page, select the "Service Accounts" tab, and click on "Generate New Private Key." This will download a JSON file containing your service account credentials.
Connecting Firebase to Peaka
----------------------------
1. Navigate to the data model page in Peaka.
2. In the side menu bar, click the "New Data Source" button to initiate the connection process.
3. In the modal that appears, select "Firebase" as your data source.
4. Enter a name for your data source.
5. Upload the Service Account JSON file you downloaded in the previous step.
5. Click "Next" to create your Firebase data source.
Congratulations! You've successfully connected Firebase to Peaka. You can now access and manage your Firebase data seamlessly within the Peaka platform.
On this page
* [Prerequisites](https://www.peaka.com/docs/integrations/firebase/#prerequisites)
* [Connecting Firebase to Peaka](https://www.peaka.com/docs/integrations/firebase/#connecting-firebase-to-peaka)
--- START: docs/integrations/freshdesk/freshdesk.md ---
Documentation menu
[Home](/) / [Docs](/docs/) / Freshdesk
 Copy as Markdown
Freshdesk
=========
Discover a seamless integration process! Learn how to connect Freshdesk to Peaka effortlessly for streamlined transactions.
This article guides you through the process of connecting Freshdesk to Peaka, allowing you to seamlessly access your Freshdesk data within the Peaka platform.
Prerequisites
-------------
Before you start, you will need the following information from Freshdesk.
* API Key
* Domain
Follow the steps below to obtain it:
1. To create your API key in Freshdesk, please refer to this helpful [guide](https://support.freshdesk.com/support/solutions/articles/215517-how-to-find-your-api-key) that provides step-by-step instructions.
2. To create your Domain in Freshdesk, please refer to this helpful [guide](https://support.freshdesk.com/support/solutions/articles/37590-set-up-a-custom-portal-url-and-verify-dns) that provides step-by-step instructions.
Connecting Freshdesk to Peaka
-----------------------------
Now that you have obtained the necessary integration data and credentials, you can connect Freshdesk to Peaka using the following steps:
1. Navigate to the data model page in Peaka.
2. In the side menu bar, click the "New Data Source" button to initiate the connection process.
3. In the modal that appears, select "Freshdesk" as your data source.
4. Enter a name for your data source and enter your API key and domain.

5. Click "Connect" to create your Freshdesk data source.
Congratulations! You've successfully connected Freshdesk to Peaka. You can now access and manage your Freshdesk data seamlessly within the Peaka platform.
On this page
* [Prerequisites](https://www.peaka.com/docs/integrations/freshdesk/#prerequisites)
* [Connecting Freshdesk to Peaka](https://www.peaka.com/docs/integrations/freshdesk/#connecting-freshdesk-to-peaka)
--- START: docs/integrations/github/github.md ---
Documentation menu
[Home](/) / [Docs](/docs/) / Github
 Copy as Markdown
Github
======
Discover a seamless integration process! Learn how to connect Github to Peaka effortlessly for streamlined transactions.
This article guides you through the process of connecting Github to Peaka, allowing you to seamlessly access your Github data within the Peaka platform.
Prerequisites
-------------
Before you start, you will need the following information from Github.
* Personal Access Token
* Organization Name
Follow the steps below to obtain it:
1. To obtain get Personal Access Token, check this [article](https://docs.github.com/en/authentication/keeping-your-account-and-data-secure/managing-your-personal-access-tokens#creating-a-personal-access-token-classic).
2. To obtain get Organization Name, check this [article](https://docs.github.com/en/account-and-profile/setting-up-and-managing-your-personal-account-on-github/managing-your-membership-in-organizations/accessing-an-organization).
Connecting Github to Peaka
--------------------------
Now that you have obtained the necessary integration data and credentials, you can connect Github to Peaka using the following steps:
1. Navigate to the data model page in Peaka.
2. In the side menu bar, click the "New Data Source" button to initiate the connection process.
3. In the modal that appears, select "Github" as your data source.
4. Enter a name for your data source, input the credentials you obtained in the previous steps.
5. Click "Authorize" to create your Github data source.
Congratulations! You've successfully connected Github to Peaka. You can now access and manage your Github data seamlessly within the Peaka platform.
On this page
* [Prerequisites](https://www.peaka.com/docs/integrations/github/#prerequisites)
* [Connecting Github to Peaka](https://www.peaka.com/docs/integrations/github/#connecting-github-to-peaka)
--- START: docs/integrations/google-ads/google-ads.md ---
Documentation menu
[Home](/) / [Docs](/docs/) / Google Ads
 Copy as Markdown
Google Ads
==========
Discover a seamless integration process! Learn how to connect Google Ads to Peaka effortlessly for streamlined transactions.
This article guides you through the process of connecting Google Ads to Peaka, allowing you to seamlessly access your Google Ads data within the Peaka platform.
Prerequisites
-------------
Before you start, you will need the following information from Google Ads.
* Client ID (required for advanced authentication)
* Client Secret (required for advanced authentication)
* Developer Token (required for advanced authentication)
* Customer ID
Follow the steps below to obtain it:
1. To obtain get Client ID and Client Secret, go to the [Goole Developers Console](https://console.cloud.google.com/apis/dashboard).
2. Click Select a project ➝ New Project ➝ the Create button.

3. Enter your Project name ➝ click the Create button.

4. Click OAuth consent screen in the left side menu ➝ choose User Type ➝ click the Create button.

5. Add Application name ➝ Support email ➝ Authorized domain ➝ Developer content information ➝ click the Save and Continue button.
6. Complete all 4 steps in OAuth consent screen ➝ click the Back to Dashboard button.

7. Go to Credentials ➝ click Create Credentials ➝ select OAuth client ID from the dropdown list.

8. Open the dropdown list Application type ➝ select Web application ➝ enter the name of your OAuth 2.0 client.
9. Enter your site URL in Authorized JavaScript origins ➝ in Authorized redirect URIs, enter the page URL where you wanted your users redirected back after they have authenticated with Google ➝ click the Create button.

10. Copy your Client ID and Client Secret.

11. To obtain the Developer Token, refer to this [article](https://developers.google.com/google-ads/api/docs/get-started/dev-token).
12. To obtain the Customer ID, refer to this [article](https://support.google.com/google-ads/answer/1704344?hl=en).
Connecting Google Ads to Peaka
------------------------------
Now that you have obtained the necessary integration data and credentials, you can connect Google Ads to Peaka using the following steps:
1. Navigate to the data model page in Peaka.
2. In the side menu bar, click the "New Data Source" button to initiate the connection process.
3. In the modal that appears, select "Google Ads" as your data source.
4. Enter a name for your data source, input the credentials you obtained in the previous steps.

5. Click "Sign in with Google" to create your Google Ads data source.
Congratulations! You've successfully connected Google Ads to Peaka. You can now access and manage your Google Ads data seamlessly within the Peaka platform.
On this page
* [Prerequisites](https://www.peaka.com/docs/integrations/google-ads/#prerequisites)
* [Connecting Google Ads to Peaka](https://www.peaka.com/docs/integrations/google-ads/#connecting-google-ads-to-peaka)
--- START: docs/integrations/google-analytics/google-analytics.md ---
Documentation menu
[Home](/) / [Docs](/docs/) / Google Analytics
 Copy as Markdown
Google Analytics
================
Discover a seamless integration process! Learn how to connect Google Analytics to Peaka effortlessly for streamlined transactions.
This article guides you through the process of connecting Google Analytics to Peaka, allowing you to seamlessly access your Google Analytics data within the Peaka platform.
Follow these steps to connect Google Analytics to Peaka:
1. Navigate to the data model page in Peaka.
2. In the side menu bar, click the "New Data Source" button to initiate the connection process.
3. In the modal, select "Google Analytics" as your data source.
4. Enter a name for your data source.
5. Click the "Signing in to Google Analytics" button. This will open a modal to allow Peaka access to your Google Analytics account.
6. In the modal, click the "Allow" button to grant Peaka access to your Google Analytics data.
Congratulations! You've successfully connected Google Analytics to Peaka. You can now access and manage your Google Analytics data seamlessly within the Peaka platform.
--- START: docs/integrations/google-sheets/google-sheets.md ---
Documentation menu
[Home](/) / [Docs](/docs/) / Google Sheets
 Copy as Markdown
Google Sheets
=============
Discover a seamless integration process! Learn how to connect Google Sheets to Peaka effortlessly for streamlined transactions.
This article guides you through the process of connecting Google Sheets to Peaka, allowing you to seamlessly access your Google Sheets data within the Peaka platform.
Follow these detailed steps to establish a data source between Google Sheets and Peaka:
1. Navigate to the data model page in Peaka.
2. In the side menu bar, click the "New Data Source" button to initiate the connection process.
3. In the modal, select "Google Sheets" as your data source.
4. Enter a name for your data source.
5. Click the "Signing in to Google Sheets" button. This will open a modal to allow Peaka access to your Google Sheets account.
6. In the modal, click the "Allow" button to grant Peaka access to your Google Sheets data.
Congratulations! You've successfully connected Google Sheets to Peaka. You can now access and manage your Google Sheets data seamlessly within the Peaka platform.
--- START: docs/integrations/google-spanner/google-spanner.md ---
Documentation menu
[Home](/) / [Docs](/docs/) / Google Spanner
 Copy as Markdown
Google Spanner
==============
Discover a seamless integration process! Learn how to connect Google Spanner to Peaka effortlessly for streamlined transactions.
This article guides you through the process of connecting Google Spanner to Peaka, allowing you to seamlessly access your Google Spanner data within the Peaka platform.
Prerequisites
-------------
Before you start, you will need the following information from Google Spanner.
* **Dialect**
* **Project ID**
* **Instance ID**
* **Database Name**
* **Credentials** in JSON format
Follow the steps below to obtain it:
1. Check this [article](https://support.google.com/googleapi/answer/7014113?hl=en) to get your **Project ID**.
2. To get your **Dialect**, follow these steps:
* Open your Google Cloud Console.
* Go to your Spanner Database Overview page.
* Look at the **Database info** section on the screen.
* Check the **Database dialect** label and note the value.
3. To get your **Instance ID**, check this [article](https://cloud.google.com/spanner/docs/create-manage-instances).
4. To get your **Database Name**, follow these steps:
* Navigate to your Google Cloud Spanner Instances page.
* Click on the name of the Instance ID you found in the previous step.
* On the instance details page, look at the **Databases** table at the bottom of the screen.
* Your database name is listed under the **Database ID** column (e.g., `example-db`, `banking-db`, `production`).
5. To create your **Credentials JSON** file, follow these steps:
* Visit the [APIs & Services](https://console.cloud.google.com/apis/dashboard) page in the Google Cloud Platform Console and click **Credentials**.
* Click **Create credentials** and choose **Service account key**.
* Under **Service account**, choose **Compute Engine default service account** and leave **JSON** selected under **Key type**. Click **Create**. Your browser will download a JSON file.
Connecting Google Spanner to Peaka
----------------------------------
Now that you have obtained the necessary integration data and credentials, you can connect Google Spanner to Peaka using the following steps:
1. Navigate to the data model page in Peaka.
2. In the side menu bar, click the **"New Data Source"** button to initiate the connection process.
3. In the modal that appears, select **"Google Spanner"** as your data source.
4. Enter a name for your data source, fill in the **Project ID**, **Instance ID**, **Database Name**, and **Dialect** fields, then upload the credentials JSON file you downloaded in step 5.
5. Click **"Next"** to create your Google Spanner data source.
Congratulations! You've successfully connected Google Spanner to Peaka. You can now access and manage your Google Spanner data seamlessly within the Peaka platform.
On this page
* [Prerequisites](https://www.peaka.com/docs/integrations/google-spanner/#prerequisites)
* [Connecting Google Spanner to Peaka](https://www.peaka.com/docs/integrations/google-spanner/#connecting-google-spanner-to-peaka)
--- START: docs/integrations/gorgias/gorgias.md ---
Documentation menu
[Home](/) / [Docs](/docs/) / Gorgias
 Copy as Markdown
Gorgias
=======
Discover a seamless integration process! Learn how to connect Gorgias to Peaka effortlessly for streamlined transactions.
This article guides you through the process of connecting Gorgias to Peaka, allowing you to seamlessly access your Gorgias data within the Peaka platform.
Prerequisites
-------------
Before you start, you will need the following information from Gorgias.
* Domain name
* Email
* API Key
Follow the steps below to obtain it:
1. To obtain the domain name, refer to this [article](https://docs.gorgias.com/en-US/customize-the-help-center-domain-81975).
2. You can obtain your email under Setting > Channels as in the screenshot below.

3. To obtain the API Key, refer to this [article](https://developers.gorgias.com/docs/access-tokens-api-keys).
Connecting Gorgias to Peaka
---------------------------
Now that you have obtained the necessary integration data and credentials, you can connect Gorgias to Peaka using the following steps:
1. Navigate to the data model page in Peaka.
2. In the side menu bar, click the "New Data Source" button to initiate the connection process.
3. In the modal that appears, select "Gorgias" as your data source.
4. Enter a name for your data source, input the credentials you obtained in the previous steps.

5. Click "Sign in" to create your Gorgias data source.
Congratulations! You've successfully connected Gorgias to Peaka. You can now access and manage your Gorgias data seamlessly within the Peaka platform.
On this page
* [Prerequisites](https://www.peaka.com/docs/integrations/gorgias/#prerequisites)
* [Connecting Gorgias to Peaka](https://www.peaka.com/docs/integrations/gorgias/#connecting-gorgias-to-peaka)
--- START: docs/integrations/hubspot/hubspot.md ---
Documentation menu
[Home](/) / [Docs](/docs/) / HubSpot
 Copy as Markdown
HubSpot
=======
Discover a seamless integration process! Learn how to connect HubSpot to Peaka effortlessly for streamlined transactions.
This article guides you through the process of connecting HubSpot to Peaka, allowing you to seamlessly access your HubSpot data within the Peaka platform.
Connecting HubSpot to Peaka
---------------------------
1. Navigate to the data model page in Peaka.
2. In the side menu bar, click the "New Data Source" button to initiate the connection process.
3. In the modal, select "HubSpot" as your data source.
4. Enter a name for your data source name, click the Sign In button. This will open a modal to allow Peaka access to your HubSpot account.
5. Allow Peaka access to your HubSpot account.

Congratulations! You've successfully connected HubSpot to Peaka. You can now access and manage your HubSpot data seamlessly within the Peaka platform.
On this page
* [Connecting HubSpot to Peaka](https://www.peaka.com/docs/integrations/hubspot/#connecting-hubspot-to-peaka)
--- START: docs/integrations/instagram/instagram.md ---
Documentation menu
[Home](/) / [Docs](/docs/) / Instagram
 Copy as Markdown
Instagram
=========
Discover a seamless integration process! Learn how to connect Instagram to Peaka effortlessly for streamlined transactions.
This article guides you through the process of connecting Instagram to Peaka, allowing you to seamlessly access your Instagram data within the Peaka platform.
Prerequisites
-------------
Before you start, you will need the following information from Instagram.
* Client ID (required for advanced setup)
* Client Secret (required for advanced setup)
* Business Account ID
Follow the steps below to obtain it:
1. To obtain Client ID and Client Secret, check this [article](https://developers.facebook.com/docs/facebook-login/guides/access-tokens/#clienttokens).
2. To obtain Business Account ID, check this [article](https://www.facebook.com/business/help/1181250022022158?id=180505742745347).
Connecting Instagram to Peaka
-----------------------------
Now that you have obtained the necessary integration data and credentials, you can connect Instagram to Peaka using the following steps:
1. Navigate to the data model page in Peaka.
2. In the side menu bar, click the "New Data Source" button to initiate the connection process.
3. In the modal that appears, select "Instagram" as your data source.
4. Enter a name for your data source, input the credentials you obtained in the previous steps.
5. Click "Sign in" to authenticate and grant Peaka access to your Instagram account.
Congratulations! You've successfully connected Instagram to Peaka. You can now access and manage your Instagram data seamlessly within the Peaka platform.
On this page
* [Prerequisites](https://www.peaka.com/docs/integrations/instagram/#prerequisites)
* [Connecting Instagram to Peaka](https://www.peaka.com/docs/integrations/instagram/#connecting-instagram-to-peaka)
--- START: docs/integrations/intercom/intercom.md ---
Documentation menu
[Home](/) / [Docs](/docs/) / Intercom
 Copy as Markdown
Intercom
========
Discover a seamless integration process! Learn how to connect Intercom to Peaka effortlessly for streamlined transactions.
This article guides you through the process of connecting Intercom to Peaka, allowing you to seamlessly access your Intercom data within the Peaka platform.
Prerequisites
-------------
Before you start, you will need the following information from Intercom.
* Client ID (required for advanced authentication)
* Client Secret (required for advanced authentication)
Follow the steps below to obtain it:
1. To obtain the Client ID and Client Secret, refer to this [article](https://developers.intercom.com/docs/build-an-integration/learn-more/authentication/setting-up-oauth#get-the-authorization-code).
Connecting Intercom to Peaka
----------------------------
1. Navigate to the data model page in Peaka.
2. In the side menu bar, click the "New Data Source" button to initiate the connection process.
3. In the modal that appears, select "Intercom" as your data source.
4. Enter a name for your data source and input the Client ID and Client Secret you obtained in the previous step.
5. Click "Sign in" to create your Intercom data source and allow Peaka access to your Intercom account.
Congratulations! You've successfully connected Intercom to Peaka. You can now access and manage your Intercom data seamlessly within the Peaka platform.
On this page
* [Prerequisites](https://www.peaka.com/docs/integrations/intercom/#prerequisites)
* [Connecting Intercom to Peaka](https://www.peaka.com/docs/integrations/intercom/#connecting-intercom-to-peaka)
--- START: docs/integrations/jira/jira.md ---
Documentation menu
[Home](/) / [Docs](/docs/) / JIRA Cloud
 Copy as Markdown
JIRA Cloud
==========
Discover a seamless integration process! Learn how to connect Jira to Peaka effortlessly for streamlined transactions.
Experience a smooth integration process with our JIRA Cloud integration. This guide will walk you through the steps to connect JIRA Cloud with Peaka, enabling you to effortlessly manage your JIRA data within the Peaka platform.
Prerequisites
-------------
Before you begin, you'll need to obtain an API Key from JIRA Cloud. Here's how to do it:
Follow the steps below to obtain it:
1. To generate your API Key, navigate to [Atlassian API Key Generation](https://id.atlassian.com/manage-profile/security/api-tokens) and follow the instructions to create your API Key.

2. To include your service URL, visit this [link](https://id.atlassian.com/manage-profile/products) and get your service URL it will be in the format of `https://<>.atlassian.net/`.

Connecting JIRA Cloud to Peaka
------------------------------
With your API Key and service URL at hand, you're ready to connect JIRA Cloud to Peaka. Follow these steps:
1. Go to the settings page in Peaka.
2. In the side menu bar, click the "New Data Source" button to initiate the connection process.
3. In the pop-up that appears, choose "JIRA Cloud" as your data source.
4. Input your data source name, API Key, and service URL. The username is your email address which you entered your account with.

5. Click on "Authorize" to establish your JIRA Cloud data source.
And that's it! You have successfully integrated JIRA Cloud with Peaka. You can now access and manage your JIRA data directly within the Peaka platform. Enjoy the seamless experience!
On this page
* [Prerequisites](https://www.peaka.com/docs/integrations/jira/#prerequisites)
* [Connecting JIRA Cloud to Peaka](https://www.peaka.com/docs/integrations/jira/#connecting-jira-cloud-to-peaka)
--- START: docs/integrations/jira-service-management/jira-service-management.md ---
Documentation menu
[Home](/) / [Docs](/docs/) / JIRA Service Management
 Copy as Markdown
JIRA Service Management
=======================
Discover a seamless integration process! Learn how to connect JIRA Service Management to Peaka effortlessly for streamlined transactions.
This article guides you through the process of connecting JIRA Service Management to Peaka, allowing you to seamlessly access your JIRA Service Management data within the Peaka platform.
Connecting JIRA Service Management to Peaka
-------------------------------------------
1. Navigate to the data model page in Peaka.
2. In the side menu bar, click the "New Data Source" button to initiate the connection process.
3. In the modal that appears, select "JIRA Service Management" as your data source.
4. Enter a name for your data source and click the "Sign in" button.

5. It will open a pop up to allow Peaka access to your JIRA Service Management account, click the "Allow" button.

6. Select your Cloud ID and Service Desk ID, then click the Next button.

Congratulations! You've successfully connected JIRA Service Management to Peaka. You can now access and manage your JIRA Service Management data seamlessly within the Peaka platform.
On this page
* [Connecting JIRA Service Management to Peaka](https://www.peaka.com/docs/integrations/jira-service-management/#connecting-jira-service-management-to-peaka)
--- START: docs/integrations/klaviyo/klaviyo.md ---
Documentation menu
[Home](/) / [Docs](/docs/) / Klaviyo
 Copy as Markdown
Klaviyo
=======
Discover a seamless integration process! Learn how to connect Klaviyo to Peaka effortlessly for streamlined transactions.
This article guides you through the process of connecting Klaviyo to Peaka, allowing you to seamlessly access your Klaviyo data within the Peaka platform.
Prerequisites
-------------
Before you start, you will need the following information from Klaviyo.
* API Key
Follow the steps below to obtain it:
1. To obtain the API Key, refer to this [article](https://help.klaviyo.com/hc/en-us/articles/7423954176283).
Connecting Klaviyo to Peaka
---------------------------
Now that you have obtained the necessary integration data and credentials, you can connect Klaviyo to Peaka using the following steps:
1. Navigate to the data model page in Peaka.
2. In the side menu bar, click the "New Data Source" button to initiate the connection process.
3. In the modal that appears, select "Klaviyo" as your data source.
4. Enter a name for your data source, input the credentials you obtained in the previous steps.
5. Click "Sign in" to create your Klaviyo data source.
Congratulations! You've successfully connected Klaviyo to Peaka. You can now access and manage your Klaviyo data seamlessly within the Peaka platform.
On this page
* [Prerequisites](https://www.peaka.com/docs/integrations/klaviyo/#prerequisites)
* [Connecting Klaviyo to Peaka](https://www.peaka.com/docs/integrations/klaviyo/#connecting-klaviyo-to-peaka)
--- START: docs/integrations/linkedin-ads/linkedin-ads.md ---
Documentation menu
[Home](/) / [Docs](/docs/) / LinkedIn Ads
 Copy as Markdown
LinkedIn Ads
============
Discover a seamless integration process! Learn how to connect LinkedIn Ads to Peaka effortlessly for streamlined transactions.
This article guides you through the process of connecting LinkedIn Ads to Peaka, allowing you to seamlessly access your LinkedIn Ads data within the Peaka platform.
Prerequisites
-------------
Before you start, you will need the following information from LinkedIn Ads.
* Client ID (required for advanced authentication)
* Client Secret (required for advanced authentication)
* Default Account ID
Follow the steps below to obtain it:
1. To obtain the Client ID and Client Secret, go to the [LinkedIn developers site](https://www.linkedin.com/developer/apps).
2. Click Create App and complete the entire information. Specify your company name or create a new company page.
3. Click Create App. The App Settings is displayed.
4. Select the Auth tab.
5. Copy the Client ID and Client Secret.
6. To obtain the Default Account ID, [sign in to Campaign Manager.](https://www.linkedin.com/campaignmanager/).
7. The ads account name is in the upper-left corner of the page. The account ID number is below the account name.
8. To see your other ad accounts, click the account name in the upper-left corner of the page. The account ID number appears below each name.
9. For a detailed list of all your ad accounts, click the ads account name in the upper-left corner of the page, then click View all accounts at the bottom of the left menu. The account ID will appear below each account name.
10. Copy the Default Account ID.
Connecting LinkedIn Ads to Peaka
--------------------------------
1. Navigate to the data model page in Peaka.
2. In the side menu bar, click the "New Data Source" button to initiate the connection process.
3. In the modal that appears, select "LinkedIn Ads" as your data source.
4. Enter a name for your data source and input credentials you obtained in the previous step.
5. Click "Sign in" to create your LinkedIn Ads data source and allow Peaka access to your LinkedIn Ads account.
Congratulations! You've successfully connected LinkedIn Ads to Peaka. You can now access and manage your LinkedIn Ads data seamlessly within the Peaka platform.
On this page
* [Prerequisites](https://www.peaka.com/docs/integrations/linkedin-ads/#prerequisites)
* [Connecting LinkedIn Ads to Peaka](https://www.peaka.com/docs/integrations/linkedin-ads/#connecting-linkedin-ads-to-peaka)
--- START: docs/integrations/mailchimp-marketing/mailchimp-marketing.md ---
Documentation menu
[Home](/) / [Docs](/docs/) / Mailchimp Marketing
 Copy as Markdown
Mailchimp Marketing
===================
Discover a seamless integration process! Learn how to connect Mailchimp Marketing to Peaka effortlessly for streamlined transactions.
This article guides you through the process of connecting Mailchimp Marketing to Peaka, allowing you to seamlessly access your Mailchimp Marketing data within the Peaka platform.
Prerequisites
-------------
Follow the steps below to connect it.
1. Navigate to the data model page in Peaka.
2. In the side menu bar, click the "New Data Source" button to initiate the connection process.
3. In the modal, select "Mailchimp Marketing" as your data source.
4. Enter a name for your data source and click the "Signing in to Mailchimp Marketing" button.
5. Once clicking, it will open a modal for logging in to your Mailchimp account.
6. In the Mailchimp login modal, enter your Mailchimp credentials
7. After logging in, you will be asked to allow Peaka access to your Mailchimp Marketing account. Click the "Allow" button to proceed.
Congratulations! You've successfully connected Mailchimp Marketing to Peaka. You can now access and manage your Jira data seamlessly within the Peaka platform.
On this page
* [Prerequisites](https://www.peaka.com/docs/integrations/mailchimp-marketing/#prerequisites)
--- START: docs/integrations/mailchimp-transactional/mailchimp-transactional.md ---
Documentation menu
[Home](/) / [Docs](/docs/) / Mailchimp Transactional
 Copy as Markdown
Mailchimp Transactional
=======================
Discover a seamless integration process! Learn how to connect Mailchimp Transactional to Peaka effortlessly for streamlined transactions.
This article guides you through the process of connecting Mailchimp Transactional to Peaka, allowing you to seamlessly access your Mailchimp Transactional data within the Peaka platform.
Prerequisites
-------------
Before you start, you will need an API Key from Mailchimp Transactional.
Follow the steps below to obtain it:
1. Go to this [link](https://us21.admin.mailchimp.com/account/api/) to create or obtain your Mailchimp Transactional API Key.
2. Click the "Create a Key" button to generate your API Key.
Connecting Mailchimp Transactional to Peaka
-------------------------------------------
Now that you have your requirements, you can connect it to Peaka using the following steps:
1. Navigate to the data model page in Peaka.
2. In the side menu bar, click the "New Data Source" button to initiate the connection process.
3. In the modal that appears, select "Mailchimp Transactional" as your data source.
4. Enter your data source name and API Key.
5. Click "Authorize" to create your Mailchimp Transactional data source.
Congratulations! You've successfully created a new data source between Mailchimp Transactional and Peaka. You can now access and manage your Mailchimp Transactional data seamlessly within the Peaka platform.
On this page
* [Prerequisites](https://www.peaka.com/docs/integrations/mailchimp-transactional/#prerequisites)
* [Connecting Mailchimp Transactional to Peaka](https://www.peaka.com/docs/integrations/mailchimp-transactional/#connecting-mailchimp-transactional-to-peaka)
--- START: docs/integrations/mariadb/mariadb.md ---
Documentation menu
[Home](/) / [Docs](/docs/) / MariaDB
 Copy as Markdown
MariaDB
=======
Discover a seamless integration process! Learn how to connect MariaDB to Peaka effortlessly for streamlined transactions.
This article guides you through the process of connecting MariaDB to Peaka, allowing you to seamlessly access your MariaDB data within the Peaka platform.
Prerequisites
-------------
Before you start, you will need the following information from MariaDB.
* Host (Endpoint without the port or database name)
* Port (The port used to connect to your database)
* User (The username of the service account)
* Password (The password for the service account user)
* SSL, if active (Toggle "Connect Through TLS" switch)
Connecting MariaDB to Peaka
---------------------------
1. Navigate to the data model page in Peaka.
2. In the side menu bar, click the "New Data Source" button to initiate the connection process.
3. In the modal that appears, select "MariaDB" as your data source.
4. Fill out the data source details form as shown in the image below, including:
* Host (Endpoint without the port or database name)
* Port (The port used to connect to your database)
* User (The username of the service account)
* Password (The password for the service account user)
* Connect Through TLS (Toggle switch if SSL is active)
5. Click "Next" to establish the data source.

Congratulations! You've successfully created a new data source between MariaDB and Peaka. You can now access and manage your MariaDB data seamlessly within the Peaka platform.
On this page
* [Prerequisites](https://www.peaka.com/docs/integrations/mariadb/#prerequisites)
* [Connecting MariaDB to Peaka](https://www.peaka.com/docs/integrations/mariadb/#connecting-mariadb-to-peaka)
--- START: docs/integrations/mixpanel/mixpanel.md ---
Documentation menu
[Home](/) / [Docs](/docs/) / Mixpanel
 Copy as Markdown
Mixpanel
========
Discover a seamless integration process! Learn how to connect Mixpanel to Peaka effortlessly for streamlined transactions.
This article guides you through the process of connecting Mixpanel to Peaka, allowing you to seamlessly access your Mixpanel data within the Peaka platform.
Prerequisites
-------------
Before you start, you will need the following information from Mixpanel.
* Username
* Secret
* Project ID
* Region (Optional)
Follow the steps below to obtain it:
1. Enter your Mixpanel username for username field.
2. Navigate to your Mixpanel project settings page to locate your Secret, Region, and Project ID credentials as illustrated in the screenshots below.
 
Connecting Mixpanel to Peaka
----------------------------
1. Navigate to the data model page in Peaka.
2. In the side menu bar, click the "New Data Source" button to initiate the connection process.
3. In the modal that appears, select "Mixpanel" as your data source.
4. Enter a name for your data source and input the information you obtained in the previous step.

5. Click "Connect" to create your Mixpanel data source.
Congratulations! You've successfully connected Mixpanel to Peaka. You can now access and manage your Mixpanel data seamlessly within the Peaka platform.
On this page
* [Prerequisites](https://www.peaka.com/docs/integrations/mixpanel/#prerequisites)
* [Connecting Mixpanel to Peaka](https://www.peaka.com/docs/integrations/mixpanel/#connecting-mixpanel-to-peaka)
--- START: docs/integrations/mongodb/mongodb.md ---
Documentation menu
[Home](/) / [Docs](/docs/) / MongoDB
 Copy as Markdown
MongoDB
=======
Discover a seamless integration process! Learn how to connect MongoDB to Peaka effortlessly for streamlined transactions.
This article guides you through the process of connecting MongoDB to Peaka, allowing you to seamlessly access your MongoDB data within the Peaka platform.
**Note**: Before you begin, ensure that Peaka has been granted the necessary read permissions as shown in the image below.
Prerequisites
-------------
**Important**: Ensure that the Peaka IP address 34.42.188.247 is added to your firewall's safelist to enable access to your MongoDB data.
Before you start, you will need the following information from MongoDB.
MongoDB data source has two type connection way;
* MongoDB Atlas
* Password (The password for the MongoDB Atlas user)
* Atlas Connection String (The connection string for MongoDB Atlas)
* You can get it on MongoDB Atlas page as in the below image. 
* MongoDB Manual (Self-Hosted)
* Host (Endpoint without the port or database name)
* Port (The port used to connect to your database)
* User (The username of the service account)
* Password (The password for the service account user)
* Database Name (The database name of your service)
* Multiple Replica Seed (Indicate whether MongoDB Atlas is being utilized)
Connecting MongoDB to Peaka
---------------------------
To connect MongoDB to Peaka, follow these steps based on your MongoDB setup:
1. Navigate to the data model page in Peaka.
2. In the side menu bar, click the "New Data Source" button to initiate the connection process.
3. In the modal that appears, select "MongoDB" as your data source.
4. Select the connection type based on your MongoDB setup.
* If you select **Atlas**;
1. Enter the connection string and password you have gathered.
* If you select **Manual**;
1. Enter the host, port, user, password, database name, and any other required details.
5. Click **Authorize** to complete the data source connection.
Congratulations! You have successfully connected MongoDB to Peaka. You can now effortlessly access and manage your MongoDB data within the Peaka platform.
On this page
* [Prerequisites](https://www.peaka.com/docs/integrations/mongodb/#prerequisites)
* [Connecting MongoDB to Peaka](https://www.peaka.com/docs/integrations/mongodb/#connecting-mongodb-to-peaka)
--- START: docs/integrations/mssql/mssql.md ---
Documentation menu
[Home](/) / [Docs](/docs/) / MSSQL
 Copy as Markdown
MSSQL
=====
Discover a seamless integration process! Learn how to connect MSSQL to Peaka effortlessly for streamlined transactions.
This article guides you through the process of connecting MSSQL to Peaka, allowing you to seamlessly access your MSSQL data within the Peaka platform.
Prerequisites
-------------
Before you start, you will need the following information from MSSQL.
* Host (Endpoint without the port or database name)
* Port (The port used to connect to your database)
* User (The username of the service account)
* Password (The password for the service account user)
* Database Name (The database name of your service)
* SSL, if active (Toggle "Connect Through TLS" switch)
Connecting MSSQL to Peaka
-------------------------
1. Navigate to the data model page in Peaka.
2. In the side menu bar, click the "New Data Source" button to initiate the connection process.
3. In the modal that appears, select "MSSQL" as your data source.
4. Fill out the data source details form as shown in the image below, including:
* Host (Endpoint without the port or database name)
* Port (The port used to connect to your database)
* User (The username of the service account)
* Password (The password for the service account user)
* Database Name (The database name of your service)
* Connect Through TLS (Toggle switch if SSL is active)
5. Click "Next" to establish the data source.

Congratulations! You've successfully created a new data source between MSSQL and Peaka. You can now access and manage your MSSQL data seamlessly within the Peaka platform.
On this page
* [Prerequisites](https://www.peaka.com/docs/integrations/mssql/#prerequisites)
* [Connecting MSSQL to Peaka](https://www.peaka.com/docs/integrations/mssql/#connecting-mssql-to-peaka)
--- START: docs/integrations/mysql/mysql.md ---
Documentation menu
[Home](/) / [Docs](/docs/) / MySQL
 Copy as Markdown
MySQL
=====
Discover a seamless integration process! Learn how to connect MySQL to Peaka effortlessly for streamlined transactions.
This article guides you through the process of connecting MySQL to Peaka, allowing you to seamlessly access your MySQL data within the Peaka platform.
Note: Users can establish a data source to their MySQL database on AWS by leveraging IAM credentials. For more details, refer to the [article in Peaka's documentation](/docs/cookbook/how-to-connect-databases-in-aws-using-iam-credentials/).
Prerequisites
-------------
Before you start, you will need the following information from MySQL.
* Host (Endpoint without the port or database name)
* Port (The port used to connect to your database)
* User (The username of the service account)
* Password (The password for the service account user)
* SSL, if active (Toggle "Connect Through TLS" switch)
Connecting MySQL to Peaka
-------------------------
1. Navigate to the data model page in Peaka.
2. In the side menu bar, click the "New Data Source" button to initiate the connection process.
3. In the modal that appears, select "MySQL" as your data source.
4. Fill out the data source details form as shown in the image below, including:
* Host (Endpoint without the port or database name)
* Port (The port used to connect to your database)
* User (The username of the service account)
* Password (The password for the service account user)
* Connect Through TLS (Toggle switch if SSL is active)
5. Click "Next" to establish the data source.
Congratulations! You've successfully created a new data source between MySQL and Peaka. You can now access and manage your MySQL data seamlessly within the Peaka platform.
On this page
* [Prerequisites](https://www.peaka.com/docs/integrations/mysql/#prerequisites)
* [Connecting MySQL to Peaka](https://www.peaka.com/docs/integrations/mysql/#connecting-mysql-to-peaka)
--- START: docs/integrations/neo4j/neo4j.md ---
Documentation menu
[Home](/) / [Docs](/docs/) / Neo4J
 Copy as Markdown
Neo4J
=====
Discover a seamless integration process! Learn how to connect Neo4J to Peaka effortlessly for streamlined transactions.
This article guides you through the process of connecting Neo4J to Peaka, allowing you to seamlessly access your Neo4J data within the Peaka platform.
Prerequisites
-------------
Before you start, you will need the following information from Neo4J.
* Host (Endpoint without the port or database name)
* Port (The port used to connect to your database)
* User Name (The username of the service account)
* Password (The password for the service account user)
* SSL, if active (Optional)
* Bolt Schema, if active (Optional)
Follow the steps below to obtain it:
1. To obtain the User Name and Password, go to the [article](https://support.neo4j.com/s/article/6787460237843-Neo4j-Aura-Database-Authentication-Neo4j-Database-Username-Password#:~:text=When%20you%20create%20an%20instance,note%20of%20the%20username%2C%20neo4j).
2. To obtain the Host and Port, go to the [article](https://neo4j.com/docs/operations-manual/current/configuration/ports/#_ports_used_by_neo4j).
Connecting Neo4J to Peaka
-------------------------
1. Navigate to the data model page in Peaka.
2. In the side menu bar, click the "New Data Source" button to initiate the connection process.
3. In the modal that appears, select "Neo4J" as your data source.
4. Enter a name for your data source and input credentials you obtained in the previous step.
5. Click "Next" to establish the data source.

Congratulations! You've successfully connected Neo4J to Peaka. You can now access and manage your Neo4J data seamlessly within the Peaka platform.
On this page
* [Prerequisites](https://www.peaka.com/docs/integrations/neo4j/#prerequisites)
* [Connecting Neo4J to Peaka](https://www.peaka.com/docs/integrations/neo4j/#connecting-neo4j-to-peaka)
--- START: docs/integrations/odoo/odoo.md ---
Documentation menu
[Home](/) / [Docs](/docs/) / Odoo
 Copy as Markdown
Odoo
====
Discover a seamless integration process! Learn how to connect Odoo to Peaka effortlessly for streamlined transactions.
This article guides you through the process of connecting Odoo to Peaka, allowing you to seamlessly access your Odoo data within the Peaka platform.
Prerequisites
-------------
Before you start, you will need the following information from Odoo.
* Odoo URL
* Database Name
* User Name
* Password
Follow the steps below to obtain it:
1. Odoo URL is your project URL like https://example-app.odoo.com/
2. The Database Name is the specific name of the database you wish to connect. It can be found in the URL subdomain, such as `example-app` in the URL https://example-app.odoo.com/.
3. User Name is the username of the service account.
4. Password is the password for the service account user.
Connecting Odoo to Peaka
------------------------
1. Navigate to the data model page in Peaka.
2. In the side menu bar, click the "New Data Source" button to initiate the connection process.
3. In the modal that appears, select "Odoo" as your data source.
4. Enter a name for your data source and input credentials you obtained in the previous step.
5. Click "Next" to establish the data source.
Congratulations! You've successfully connected Odoo to Peaka. You can now access and manage your Odoo data seamlessly within the Peaka platform.
On this page
* [Prerequisites](https://www.peaka.com/docs/integrations/odoo/#prerequisites)
* [Connecting Odoo to Peaka](https://www.peaka.com/docs/integrations/odoo/#connecting-odoo-to-peaka)
--- START: docs/integrations/openai/openai.md ---
Documentation menu
[Home](/) / [Docs](/docs/) / OpenAI
 Copy as Markdown
OpenAI
======
Discover a seamless integration process! Learn how to connect OpenAI to Peaka effortlessly for streamlined transactions.
This article guides you through the process of connecting OpenAI to Peaka, allowing you to seamlessly access your OpenAI data within the Peaka platform.
Prerequisites
-------------
Before you start, you will need an API Key from OpenAI.
Follow the steps below to obtain it:
1. Go to this [link](https://platform.openai.com/account/api-keys) to create or obtain your OpenAI API Key.
2. Click the "Create new secret key" button to generate your API Key.
Connecting OpenAI to Peaka
--------------------------
Now that you have your requirements, you can connect it to Peaka using the following steps:
1. Navigate to the data model page in Peaka.
2. In the side menu bar, click the "New Data Source" button to initiate the connection process.
3. In the modal that appears, select "OpenAI" as your data source.
4. Enter your data source name and API Key.
5. Click "Authorize" to create your OpenAI data source.
Congratulations! You've successfully created a new data source between OpenAI and Peaka. You can now access and manage your OpenAI data seamlessly within the Peaka platform.
On this page
* [Prerequisites](https://www.peaka.com/docs/integrations/openai/#prerequisites)
* [Connecting OpenAI to Peaka](https://www.peaka.com/docs/integrations/openai/#connecting-openai-to-peaka)
--- START: docs/integrations/oracle/oracle.md ---
Documentation menu
[Home](/) / [Docs](/docs/) / Oracle
 Copy as Markdown
Oracle
======
Discover a seamless integration process! Learn how to connect Oracle to Peaka effortlessly for streamlined transactions.
This article guides you through the process of connecting Oracle to Peaka, allowing you to seamlessly access your Oracle data within the Peaka platform.
Prerequisites
-------------
Before you start, you will need the following information from Oracle.
* Host (Endpoint without the port or database name)
* Port (The port used to connect to your database)
* User (The username of the service account)
* Password (The password for the service account user)
* Database Name (The database name of your service)
* SSL, if active (Toggle "Connect Through TLS" switch)
Connecting Oracle to Peaka
--------------------------
1. Navigate to the data model page in Peaka.
2. In the side menu bar, click the "New Data Source" button to initiate the connection process.
3. In the modal that appears, select "Oracle" as your data source.
4. Fill out the data source details form as shown in the image below, including:
* Host (Endpoint without the port or database name)
* Port (The port used to connect to your database)
* User (The username of the service account)
* Password (The password for the service account user)
* Database Name (The database name of your service)
* Connect Through TLS (Toggle switch if SSL is active)
5. Click "Next" to establish the data source.
Congratulations! You've successfully created a data source between Oracle and Peaka. You can now access and manage your Oracle data seamlessly within the Peaka platform.
On this page
* [Prerequisites](https://www.peaka.com/docs/integrations/oracle/#prerequisites)
* [Connecting Oracle to Peaka](https://www.peaka.com/docs/integrations/oracle/#connecting-oracle-to-peaka)
--- START: docs/integrations/paychex/paychex.md ---
Documentation menu
[Home](/) / [Docs](/docs/) / Paychex
 Copy as Markdown
Paychex
=======
Discover a seamless integration process! Learn how to connect Paychex to Peaka effortlessly for streamlined transactions.
This article guides you through the process of connecting Paychex to Peaka, allowing you to seamlessly access your Paychex data within the Peaka platform.
Prerequisites
-------------
Before you start, you will need the following information from Paychex.
* **Client ID**
* **Client Secret**
Follow the steps below to obtain it:
Note: For getting your Client Secret, you must obtain it while creating app,
1. Log in to your Paychex account and go into Company Settings.
2. Select Integrated apps.
3. Click Create App.
4. Enter an Application Name and Description.
5. Select Read only for the Company and worker APIs
* If you also need to sync payroll information, select Read only for the Payroll and check APIs.
* If you need access to Payroll data and do not see it as a toggle, contact your account manager for help.
6. Accept the Legal Notice and Paychex Inc, API License Agreement, and Save.
7. You'll then see the API key and Client Secret, which you'll paste into the linking flow
Connecting Paychex to Peaka
---------------------------
Now that you have obtained the necessary integration data and credentials, you can connect Paychex to Peaka using the following steps:
1. Navigate to the data model page in Peaka.
2. In the side menu bar, click the "New Data Source" button to initiate the connection process.
3. In the modal that appears, select "Paychex" as your data source.
4. Enter a name for your data source, fill in the **Client ID** and **Client Secret** fields.
5. Click "Next" to create your Paychex data source.
Congratulations! You've successfully connected Paychex to Peaka. You can now access and manage your Paychex data seamlessly within the Peaka platform.
On this page
* [Prerequisites](https://www.peaka.com/docs/integrations/paychex/#prerequisites)
* [Connecting Paychex to Peaka](https://www.peaka.com/docs/integrations/paychex/#connecting-paychex-to-peaka)
--- START: docs/integrations/pinecone/pinecone.md ---
Documentation menu
[Home](/) / [Docs](/docs/) / Pinecone
 Copy as Markdown
Pinecone
========
Discover a seamless integration process! Learn how to connect Pinecone to Peaka effortlessly for streamlined transactions.
This article guides you through the process of connecting Pinecone to Peaka, allowing you to seamlessly access your Pinecone data within the Peaka platform.
Prerequisites
-------------
Pinecone offers two distinct connection methods:
* Pinecone Connect
* API Key
Before you start, you will need the following information from Pinecone.
* API Key (if required for the connection method)
Follow the steps below to obtain it:
1. To obtain API Key, check this [article](https://docs.pinecone.io/guides/get-started/authentication).
Connecting Pinecone to Peaka
----------------------------
Now that you have obtained the necessary integration data and credentials, you can connect Pinecone to Peaka using the following steps:
1. Navigate to the data model page in Peaka.
2. In the side menu bar, click the "New Data Source" button to initiate the connection process.
3. In the modal that appears, select "ActiveCampaign" as your data source.
4. Choose the authentication method that best suits your needs.
5. If you're using the API Key connection method, simply enter your API Key and click the Authorize button.
6. If you're using the Pinecone Connect method, click the Connect to Pinecone button and allow Peaka to access your Pinecone data.

Congratulations! You've successfully connected Pinecone to Peaka. You can now access and manage your Pinecone data seamlessly within the Peaka platform.
On this page
* [Prerequisites](https://www.peaka.com/docs/integrations/pinecone/#prerequisites)
* [Connecting Pinecone to Peaka](https://www.peaka.com/docs/integrations/pinecone/#connecting-pinecone-to-peaka)
--- START: docs/integrations/pipedrive/pipedrive.md ---
Documentation menu
[Home](/) / [Docs](/docs/) / Pipedrive
 Copy as Markdown
Pipedrive
=========
Discover a seamless integration process! Learn how to connect Pipedrive to Peaka effortlessly for streamlined transactions.
This article guides you through the process of connecting Pipedrive to Peaka, allowing you to seamlessly access your Pipedrive data within the Peaka platform.
Prerequisites
-------------
Before you start, you will need an API Key from Pipedrive.
Follow the steps below to obtain it:
1. Visit the [Pipedrive website](https://app.pipedrive.com/).
2. It can be found under **Settings > Personal preferences > API**.
If you cannot find your API token here, it may be that the permission set you are in does not have that permission enabled.
Connecting Pipedrive to Peaka
-----------------------------
Now that you have your Pipedrive API Key, you can connect it to Peaka using the following steps:
1. Navigate to the data model page in Peaka.
2. In the side menu bar, click the "New Data Source" button to initiate the connection process.
3. In the modal that appears, select "Pipedrive" as your data source.
4. Enter a name for your data source name and paste the Pipedrive API Key into the "API Key" input field.
5. Click "Authorize" to create your Pipedrive data source.
Congratulations! You've successfully connected Pipedrive to Peaka. You can now access and manage your Pipedrive data seamlessly within the Peaka platform.
On this page
* [Prerequisites](https://www.peaka.com/docs/integrations/pipedrive/#prerequisites)
* [Connecting Pipedrive to Peaka](https://www.peaka.com/docs/integrations/pipedrive/#connecting-pipedrive-to-peaka)
--- START: docs/integrations/postgresql/postgresql.md ---
Documentation menu
[Home](/) / [Docs](/docs/) / PostgreSQL
 Copy as Markdown
PostgreSQL
==========
Discover a seamless integration process! Learn how to connect PostgreSQL to Peaka effortlessly for streamlined transactions.
This article guides you through the process of connecting PostgreSQL to Peaka, allowing you to seamlessly access your PostgreSQL data within the Peaka platform.
Note: Users can establish a data source to their PostgreSQL database on AWS by leveraging IAM credentials. For more details, refer to the [article in Peaka's documentation](/docs/cookbook/how-to-connect-databases-in-aws-using-iam-credentials/).
Prerequisites
-------------
Before you start, you will need the following information from PostgreSQL.
* Host (Endpoint without the port or database name)
* Port (The port used to connect to your database)
* User (The username of the service account)
* Password (The password for the service account user)
* Database Name (The database name of your service)
* Schema (The name of your schema)
* SSL, if active (Toggle "Connect Through TLS" switch)
Connecting PostgreSQL to Peaka
------------------------------
1. Navigate to the data model page in Peaka.
2. In the side menu bar, click the "New Data Source" button to initiate the connection process.
3. In the modal that appears, select "PostgreSQL" as your data source.
4. Fill out the data source details form as shown in the image below, including:
* Host (Endpoint without the port or database name)
* Port (The port used to connect to your database)
* User (The username of the service account)
* Password (The password for the service account user)
* Database Name (The database name of your service)
* Schema (The name of your schema)
* Connect Through TLS (Toggle switch if SSL is active)
5. Click "Next" to establish the data source.
Congratulations! You've successfully created a new data source between PostgreSQL and Peaka. You can now access and manage your PostgreSQL data seamlessly within the Peaka platform.
On this page
* [Prerequisites](https://www.peaka.com/docs/integrations/postgresql/#prerequisites)
* [Connecting PostgreSQL to Peaka](https://www.peaka.com/docs/integrations/postgresql/#connecting-postgresql-to-peaka)
--- START: docs/integrations/posthog/posthog.md ---
Documentation menu
[Home](/) / [Docs](/docs/) / PostHog
 Copy as Markdown
PostHog
=======
Discover a seamless integration process! Learn how to connect PostHog to Peaka effortlessly for streamlined transactions.
This article guides you through the process of connecting PostHog to Peaka, allowing you to seamlessly access your PostHog data within the Peaka platform.
Prerequisites
-------------
Before you start, you will need the following information from PostHog.
* Personal API Key
* Domain
Follow the steps below to obtain it:
1. To obtain the Personal API Key:
* Navigate to the [Personal API keys](https://us.posthog.com/settings/user-api-keys) section in your PostHog account.
* Click the "Create Personal API key" button.
* In the modal that appears, select either your Organization, Project, or both.
* Under scopes, select at least "Read" permissions to view your PostHog data in Peaka.
* Give your API key a label and click "Create key".
* Copy the generated API key (note: it will only be shown once).

2. You can select your domain from the dropdown menu by this information. You can find it under Settings > Project > General as in the screenshot below.

Connecting PostHog to Peaka
---------------------------
1. Navigate to the data model page in Peaka.
2. In the side menu bar, click the "New Data Source" button to initiate the connection process.
3. In the modal that appears, select "PostHog" as your data source.
4. Enter a name for your data source and click the "Next" button.

5. You'll proceed to the second step where you need to select your Organization and Organization Project from the dropdown menus. After making your selections, click the "Next" button to continue.

Congratulations! You've successfully connected PostHog to Peaka. You can now access and manage your PostHog data seamlessly within the Peaka platform.
On this page
* [Prerequisites](https://www.peaka.com/docs/integrations/posthog/#prerequisites)
* [Connecting PostHog to Peaka](https://www.peaka.com/docs/integrations/posthog/#connecting-posthog-to-peaka)
--- START: docs/integrations/profitwell/profitwell.md ---
Documentation menu
[Home](/) / [Docs](/docs/) / ProfitWell
 Copy as Markdown
ProfitWell
==========
Discover a seamless integration process! Learn how to connect ProfitWell to Peaka effortlessly for streamlined transactions.
This article guides you through the process of connecting ProfitWell to Peaka, allowing you to seamlessly access your ProfitWell data within the Peaka platform.
Prerequisites
-------------
Before you start, you will need an API Key from ProfitWell.
Follow the steps below to obtain it:
1. Go to this [link](https://www2.profitwell.com/app/account/integrations) to create or obtain your ProfitWell API Key or private token.
2. Copy your private token for use in the integration.
Connecting ProfitWell to Peaka
------------------------------
Now that you have your requirements, you can connect it to Peaka using the following steps:
1. Navigate to the data model page in Peaka.
2. In the side menu bar, click the "New Data Source" button to initiate the connection process.
3. In the modal that appears, select "ProfitWell" as your data source.
4. Enter your data source name and API Key.
5. Click "Authorize" to create your ProfitWell data source.
Congratulations! You've successfully created a new data source between ProfitWell and Peaka. You can now access and manage your ProfitWell data seamlessly within the Peaka platform.
On this page
* [Prerequisites](https://www.peaka.com/docs/integrations/profitwell/#prerequisites)
* [Connecting ProfitWell to Peaka](https://www.peaka.com/docs/integrations/profitwell/#connecting-profitwell-to-peaka)
--- START: docs/integrations/provet-cloud/provet-cloud.md ---
Documentation menu
[Home](/) / [Docs](/docs/) / Provet Cloud
 Copy as Markdown
Provet Cloud
============
Discover a seamless integration process! Learn how to connect Provet Cloud to Peaka effortlessly for streamlined transactions.
This article guides you through the process of connecting Provet Cloud to Peaka, allowing you to seamlessly access your Provet Cloud data within the Peaka platform.
Prerequisites
-------------
Before you start, you will need the following information from Provet Cloud.
* Client ID
* Client Secret
* Provet ID
* Environment
Follow the steps below to obtain it:
1. To obtain Client ID and Client Secret, check this [article](https://developers.provetcloud.com/restapi/authentication_oauth2.html#client-credentials-example-get-access-token).
2. To obtain Provet ID, check this [article](https://support.provet.cloud/hc/en-gb/articles/360009783098-Logging-In-to-Provet-Cloud).
3. To obtain Environment, check this [article](https://support.provet.cloud/hc/en-gb/articles/360010249038-Integrating-Third-party-Applications-with-Provet-Cloud).
Connecting Provet Cloud to Peaka
--------------------------------
Now that you have obtained the necessary integration data and credentials, you can connect Provet Cloud to Peaka using the following steps:
1. Navigate to the data model page in Peaka.
2. In the side menu bar, click the "New Data Source" button to initiate the connection process.
3. In the modal that appears, select "Provet Cloud" as your data source.
4. Enter a name for your data source, input the credentials you obtained in the previous steps.
5. Click "Authorize" to create your Provet Cloud data source.
Congratulations! You've successfully connected Provet Cloud to Peaka. You can now access and manage your Provet Cloud data seamlessly within the Peaka platform.
On this page
* [Prerequisites](https://www.peaka.com/docs/integrations/provet-cloud/#prerequisites)
* [Connecting Provet Cloud to Peaka](https://www.peaka.com/docs/integrations/provet-cloud/#connecting-provet-cloud-to-peaka)
--- START: docs/integrations/qdrant/qdrant.md ---
Documentation menu
[Home](/) / [Docs](/docs/) / Qdrant
 Copy as Markdown
Qdrant
======
Discover a seamless integration process! Learn how to connect Qdrant to Peaka effortlessly for streamlined transactions.
This article guides you through the process of connecting Qdrant to Peaka, allowing you to seamlessly access your Qdrant data within the Peaka platform.
Prerequisites
-------------
Before you start, you will need the following information from Qdrant.
* URL
* API Key
Follow the steps below to obtain it:
1. To obtain URL and API Key, check this [article](https://qdrant.tech/documentation/cloud/authentication/#).
Connecting Qdrant to Peaka
--------------------------
Now that you have obtained the necessary integration data and credentials, you can connect Qdrant to Peaka using the following steps:
1. Navigate to the data model page in Peaka.
2. In the side menu bar, click the "New Data Source" button to initiate the connection process.
3. In the modal that appears, select "Qdrant" as your data source.
4. Enter a name for your data source, input the credentials you obtained in the previous steps.

5. Click "Authorize" to create your Qdrant data source.
Congratulations! You've successfully connected Qdrant to Peaka. You can now access and manage your Qdrant data seamlessly within the Peaka platform.
On this page
* [Prerequisites](https://www.peaka.com/docs/integrations/qdrant/#prerequisites)
* [Connecting Qdrant to Peaka](https://www.peaka.com/docs/integrations/qdrant/#connecting-qdrant-to-peaka)
--- START: docs/integrations/quickbooks-online/quickbooks-online.md ---
Documentation menu
[Home](/) / [Docs](/docs/) / Quickbooks Online
 Copy as Markdown
Quickbooks Online
=================
Discover a seamless integration process! Learn how to connect Quickbooks Online to Peaka effortlessly for streamlined transactions.
This article guides you through the process of connecting Quickbooks Online to Peaka, allowing you to seamlessly access your Quickbooks Online data within the Peaka platform.
Prerequisites
-------------
Before you start, you will need the following information from Quickbooks Online.
* Client ID (required for advanced authentication)
* Client Secret (required for advanced authentication)
Follow the steps below to obtain it:
1. To obtain the Client ID and Client Secret, go to the [article](https://quickbooks.intuit.com/learn-support/en-us/account-management/how-to-get-client-id-and-client-secret-from-my-qb-online-account/00/928730).
Connecting Quickbooks Online to Peaka
-------------------------------------
1. Navigate to the data model page in Peaka.
2. In the side menu bar, click the "New Data Source" button to initiate the connection process.
3. In the modal that appears, select "Quickbooks Online" as your data source.
4. Enter a name for your data source and input credentials you obtained in the previous step.
5. Click "Sign in" to create your Quickbooks Online data source and allow Peaka access to your Quickbooks Online account.
Congratulations! You've successfully connected Quickbooks Online to Peaka. You can now access and manage your Quickbooks Online data seamlessly within the Peaka platform.
On this page
* [Prerequisites](https://www.peaka.com/docs/integrations/quickbooks-online/#prerequisites)
* [Connecting Quickbooks Online to Peaka](https://www.peaka.com/docs/integrations/quickbooks-online/#connecting-quickbooks-online-to-peaka)
--- START: docs/integrations/redshift/redshift.md ---
Documentation menu
[Home](/) / [Docs](/docs/) / Amazon Redshift
 Copy as Markdown
Amazon Redshift
===============
Discover a seamless integration process! Learn how to connect Amazon Redshift to Peaka effortlessly for streamlined transactions.
This article guides you through the process of connecting Amazon Redshift to Peaka, allowing you to seamlessly access your Amazon Redshift data within the Peaka platform.
Prerequisites
-------------
Before you start, you will need the following information from Amazon Redshift.
* Port
* Host
* User name
* Password
* Database name
Follow the steps below to obtain it:
1. Go to Amazon Redshift.
2. After accessing Amazon Redshift, create your cluster.
3. After clicking the "Create Cluster" button, you will be redirected to provide some information. Your password and username should match the details shown in the image below.
4. If you choose to customize the Additional Configurations settings, you have the flexibility to modify your database name. However, if you prefer to stick with the default settings, your database name will be set to "dev" and the port will remain at the default value of 5439. Once you've finished inputting your desired configurations, simply click the "Create Cluster" button located at the bottom of the page. Please be patient as the creation process may take a few minutes to complete.
5. Accessing your host's knowledge can be done through the "Properties" tab.
Connecting Amazon Redshift to Peaka
-----------------------------------
Now that you have your requirements, you can connect it to Peaka using the following steps:
1. Navigate to the data model page in Peaka.
2. In the side menu bar, click the "New Data Source" button to initiate the connection process.
3. In the modal that appears, select "Amazon Redshift" as your data source type.
4. Enter a name for your data source name and data source details below:
* User name
* Password
* Port
* Host
* You can enable the "Connect through TLS" option if SSL is active.
5. Click "Connect" to create your Amazon Redshift data source.
Congratulations! You've successfully created a new data source between Amazon Redshift and Peaka. You can now access and manage your Amazon Redshift data seamlessly within the Peaka platform.
The specific steps for connecting Amazon Redshift may vary based on your unique setup. If you encounter any difficulties or have questions, please don't hesitate to contact our Support Team for assistance.
On this page
* [Prerequisites](https://www.peaka.com/docs/integrations/redshift/#prerequisites)
* [Connecting Amazon Redshift to Peaka](https://www.peaka.com/docs/integrations/redshift/#connecting-amazon-redshift-to-peaka)
--- START: docs/integrations/salesforce/salesforce.md ---
Documentation menu
[Home](/) / [Docs](/docs/) / Salesforce
 Copy as Markdown
Salesforce
==========
Discover a seamless integration process! Learn how to connect Salesforce to Peaka effortlessly for streamlined transactions.
This article guides you through the process of connecting Salesforce to Peaka, allowing you to seamlessly access your Salesforce data within the Peaka platform.
Prerequisites
-------------
Before you start, you will need the following information from Salesforce.
* User Name
* Password
* Security Token
Follow the steps below to obtain it:
1. To obtain the User Name and Password, go to the [article](https://support.omaticsoftware.com/s/article/Locating-your-Salesforce-Username-and-Password).
2. To obtain the Security Token, log in to your Salesforce account.
3. Click the profile avatar and choose Settings.
4. Select My Personal Information → Reset My Security Token.
5. Check your email for the security token.
Connecting Salesforce to Peaka
------------------------------
1. Navigate to the data model page in Peaka.
2. In the side menu bar, click the "New Data Source" button to initiate the connection process.
3. In the modal that appears, select "Salesforce" as your data source.
4. Enter a name for your data source and input credentials you obtained in the previous step.
5. Click "Next" to create your Salesforce data source.
Congratulations! You've successfully connected Salesforce to Peaka. You can now access and manage your Salesforce data seamlessly within the Peaka platform.
On this page
* [Prerequisites](https://www.peaka.com/docs/integrations/salesforce/#prerequisites)
* [Connecting Salesforce to Peaka](https://www.peaka.com/docs/integrations/salesforce/#connecting-salesforce-to-peaka)
--- START: docs/integrations/sap-hana/sap-hana.md ---
Documentation menu
[Home](/) / [Docs](/docs/) / SAP HANA
 Copy as Markdown
SAP HANA
========
Discover a seamless integration process! Learn how to connect SAP HANA to Peaka effortlessly for streamlined transactions.
This article guides you through the process of connecting SAP HANA to Peaka, allowing you to seamlessly access your SAP HANA data within the Peaka platform.
Prerequisites
-------------
Before you start, you will need the following information from SAP HANA.
* Host (endpoint without the port or database name)
* Port (the port used to connect to your database)
* User (the username of the service account)
* Password (the password for the service account user)
* Database Name (the database name of your service)
* SSL, if active (toggle "Connect through TLS" switch)
* Show System Schemas (enable the switch to display style schemas)
Connecting SAP HANA to Peaka
----------------------------
1. Navigate to the data model page in Peaka.
2. In the side menu bar, click the "New Data Source" button to initiate the connection process.
3. In the modal that appears, select "SAP Hana" as your data source.
4. Fill out the data source details form as shown in the image below, including:
* Host (endpoint without the port or database name)
* Port (the port used to connect to your database)
* User (the username of the service account)
* Password (the password for the service account user)
* Database Name (the database name of your service)
* Connect Through TLS (toggle switch if SSL is active)
* Show System Schemas (enable its switch to display style schemas)
5. Click "Next" to establish the data source.

Congratulations! You've successfully created a new data source between SAP HANA and Peaka. You can now access and manage your SAP HANA data seamlessly within the Peaka platform.
On this page
* [Prerequisites](https://www.peaka.com/docs/integrations/sap-hana/#prerequisites)
* [Connecting SAP HANA to Peaka](https://www.peaka.com/docs/integrations/sap-hana/#connecting-sap-hana-to-peaka)
--- START: docs/integrations/segment/segment.md ---
Documentation menu
[Home](/) / [Docs](/docs/) / Segment
 Copy as Markdown
Segment
=======
Discover a seamless integration process! Learn how to connect Segment to Peaka effortlessly for streamlined transactions.
This article guides you through the process of connecting Segment to Peaka, allowing you to seamlessly access your Segment data within the Peaka platform.
Prerequisites
-------------
Before you start, you will need an API Key from Segment.
Follow the steps below to obtain it:
1. Navigate to the data model page in Peaka.
2. In the side menu bar, click the "New Data Source" button to initiate the connection process.
3. In the modal that appears, select "Segment" as your data source.
4. Input the necessary information, including the Segment Catalog Name, and proceed by clicking the "Next" button.

5. Upon clicking the "Next" button, your unique API Key will be automatically generated. Please note that the API Key will only be displayed once.

6. Copy the generated API Key from Peaka and paste it into the designated field within your Segment account settings.
Adding Peaka Destination in Segment
-----------------------------------
To integrate Peaka with Segment, follow these steps to paste your API Key:
1. Navigate to the Peaka Destination page on Segment by clicking on the following link:
https://app.segment.com/{your-workspace-name}/destinations/catalog/peaka
2. On the Peaka Destination page, locate and click on the "Add Destination" button.

3. In the dialogue box that appears, provide a name for your destination and proceed by clicking on the "Create Destination" button.

4. Once the destination is created, locate the designated field for API Key entry. Paste the API Key obtained from Peaka into this field.

5. After pasting the API Key, make sure to save your changes to finalize the integration.
On this page
* [Prerequisites](https://www.peaka.com/docs/integrations/segment/#prerequisites)
* [Adding Peaka Destination in Segment](https://www.peaka.com/docs/integrations/segment/#adding-peaka-destination-in-segment)
--- START: docs/integrations/sendgrid/sendgrid.md ---
Documentation menu
[Home](/) / [Docs](/docs/) / SendGrid
 Copy as Markdown
SendGrid
========
Discover a seamless integration process! Learn how to connect SendGrid to Peaka effortlessly for streamlined transactions.
This article guides you through the process of connecting SendGrid to Peaka, allowing you to seamlessly access your SendGrid data within the Peaka platform.
Prerequisites
-------------
Before you start, you will need an API Key from Open AI.
Follow the steps below to obtain it:
1. Go to this [link](https://www2.Sendgrid.com/app/account/integrations) to create or obtain your SendGrid API Key.
2. Click the "Create API Key" button to generate your API Key.

Connecting SendGrid to Peaka
----------------------------
Now that you have your requirements, you can connect it to Peaka using the following steps:
1. Navigate to the data model page in Peaka.
2. In the side menu bar, click the "New Data Source" button to initiate the connection process.
3. In the modal that appears, select "Sendgrid" as your data source.
4. Enter your data source name and API Key.

5. Click "Authorize" to create your SendGrid data source
Congratulations! You've successfully created a data source between SendGrid and Peaka. You can now access and manage your SendGrid data seamlessly within the Peaka platform.
On this page
* [Prerequisites](https://www.peaka.com/docs/integrations/sendgrid/#prerequisites)
* [Connecting SendGrid to Peaka](https://www.peaka.com/docs/integrations/sendgrid/#connecting-sendgrid-to-peaka)
--- START: docs/integrations/service-titan/service-titan.md ---
Documentation menu
[Home](/) / [Docs](/docs/) / ServiceTitan
 Copy as Markdown
ServiceTitan
============
This guide explains how to connect your ServiceTitan account to Peaka in order to access and analyze your ServiceTitan data within the Peaka platform.
Prerequisites
-------------
Before you begin, ensure you have the following credentials from ServiceTitan:
* **Tenant** (Tenant ID)
* **Application Key**
* **Client ID**
* **Client Secret**
_You can obtain the Application Key, Client ID, and Client Secret by registering your app on [developer.servicetitan.io](https://developer.servicetitan.io/). The Tenant ID identifies your ServiceTitan account and can be found in the API Applications section of your ServiceTitan account. It often matches your ServiceTitan subdomain (for example, yourcompany.servicetitan.io)._
> **Important:** When registering your app, make sure to mark the **read** permissions under each of the scopes shown below. These read permissions are required for Peaka to access and analyze your ServiceTitan data.
Follow these steps to obtain them:
Follow the steps below to obtain it:
1. To obtain URL and API Key, check this [article](https://help.servicetitan.com/docs/get-started-with-api-dev-portal-v2).
> **Important:** Remember which environment you use here. You must select the matching environment when connecting the data source in Peaka (see the Integration Environment toggle below). Credentials generated in one environment will not work in the other.
Connecting ServiceTitan to Peaka
--------------------------------
Now that you have your ServiceTitan Client ID, Client Secret, Tenant and Application Key, you can connect it to Peaka using the following steps:
1. Navigate to the data model page in Peaka.
2. In the side menu bar, click the "New Data Source" button to initiate the connection process.
3. In the modal that appears, select "ServiceTitan" as your data source.
4. Enter a name for your data source and provide the following credentials:
* Tenant ID
* Application Key
* Client ID
* Client Secret
5. Set the **Integration Environment** toggle to match the environment in which your credentials were created:
* If your credentials were generated in the **Integration Environment**, turn the toggle **on**.
* If your credentials were generated in the **Production Environment**, leave the toggle **off**.
> **Important:** If this toggle does not match the environment used to generate your credentials, the connection will fail even if all credentials are correct.
6. Click the "Authorize" button to finalize the creation of your ServiceTitan data source.
Your ServiceTitan data source is now successfully connected to Peaka and ready to be used.
On this page
* [Prerequisites](https://www.peaka.com/docs/integrations/service-titan/#prerequisites)
* [Connecting ServiceTitan to Peaka](https://www.peaka.com/docs/integrations/service-titan/#connecting-servicetitan-to-peaka)
--- START: docs/integrations/shopify/shopify.md ---
Documentation menu
[Home](/) / [Docs](/docs/) / Shopify
 Copy as Markdown
Shopify
=======
Discover a seamless integration process! Learn how to connect Shopify to Peaka effortlessly for streamlined transactions.
This article guides you through the process of connecting Shopify to Peaka, allowing you to seamlessly access your Shopify data within the Peaka platform.
Prerequisites
-------------
Before you start, you will need Admin API Access Token and Subdomain from Shopify.
Follow the steps below to obtain it:
1. Go to this [link](https://www.shopify.com/) and log in to your Shopify account.
2. Click the settings icon located in the lower-left corner of the website.
3. If you already have a Shopify app, select it. If not, create a new app.
4. Click the "Develop apps" button, as shown in the image below.

5. Configure your Admin API scopes and Storefront API scopes as needed for your integration.
6. After configuring your API scopes, click "Install app" button to generate Admin API Access Token.
7. Copy the Access Token generated for your app.
8. Go to the "Domains" section on the side panel of the website to obtain or connect your Shopify subdomain.
Connecting Shopify to Peaka
---------------------------
Now that you have your requirements, you can connect it to Peaka using the following steps:
1. Navigate to the data model page in Peaka.
2. In the side menu bar, click the "New Data Source" button to initiate the connection process.
3. In the modal that appears, select "Shopify" as your data source
4. Enter your data source name, Admin API Access Token and Subdomain.

5. Click "Authorize" to create your Shopify data source.
Congratulations! You've successfully created a data source between Shopify and Peaka. You can now access and manage your Shopify data seamlessly within the Peaka platform.
On this page
* [Prerequisites](https://www.peaka.com/docs/integrations/shopify/#prerequisites)
* [Connecting Shopify to Peaka](https://www.peaka.com/docs/integrations/shopify/#connecting-shopify-to-peaka)
--- START: docs/integrations/single-store/single-store.md ---
Documentation menu
[Home](/) / [Docs](/docs/) / SingleStore
 Copy as Markdown
SingleStore
===========
Discover a seamless integration process! Learn how to connect SingleStore to Peaka effortlessly for streamlined transactions.
This article guides you through the process of connecting SingleStore to Peaka, allowing you to seamlessly access your SingleStore data within the Peaka platform.
Prerequisites
-------------
Before you start, you will need the following information from SingleStore.
* User
* Password
* Host
* Port
* Database Name
Follow the steps below to obtain it:
1. Go to the SingleStore website and log in to your account if you're not already logged in.
2. Create a new workspace on SingleStore. Please note that this step may take some time.
3. Click the "Connect" button and select "Connect Directly." This will take you to the SingleStore dashboard.
4. Click on the "SQL IDE" tab. Here, you will find your user name, port, and host.
5. Select the "Access" tab. Here, you will find your password. You can reset your password if needed.
6. Select the "Database" tab and copy your database name.
Connecting SingleStore to Peaka
-------------------------------
Now that you have your requirements, you can connect it to Peaka using the following steps:
1. Navigate to the data model page in Peaka.
2. In the side menu bar, click the "New Data Source" button to initiate the connection process.
3. In the modal that appears, select "SingleStore" as your data source
4. Enter your data source name, user, password, host, port, and database name. Optionally, enable the "Connect through TLS" switch if SSL is active.
5. Click "Authorize" to create your SingleStore data source.
Congratulations! You've successfully created a data source between SingleStore and Peaka. You can now access and manage your SingleStore data seamlessly within the Peaka platform.
On this page
* [Prerequisites](https://www.peaka.com/docs/integrations/single-store/#prerequisites)
* [Connecting SingleStore to Peaka](https://www.peaka.com/docs/integrations/single-store/#connecting-singlestore-to-peaka)
--- START: docs/integrations/slack/slack.md ---
Documentation menu
[Home](/) / [Docs](/docs/) / Slack
 Copy as Markdown
Slack
=====
Discover a seamless integration process! Learn how to connect Slack to Peaka effortlessly for streamlined transactions.
This article guides you through the process of connecting Slack to Peaka, allowing you to seamlessly access your Slack data within the Peaka platform.
Follow these detailed steps to establish a connection between Slack and Peaka:
1. Navigate to the data model page in Peaka.
2. In the side menu bar, click the "New Data Source" button to initiate the connection process.
3. In the modal that appears, select "Slack" as your data source.
4. Enter a name for your data source.
5. Click the "Signing in to Slack" button. This will open a modal to allow Peaka access to your Slack account.
6. It will open a modal to grant permission to Peaka.
Congratulations! You've successfully created a new data source between Slack and Peaka. You can now access and manage your Slack data seamlessly within the Peaka platform.
--- START: docs/integrations/snowflake/snowflake.md ---
Documentation menu
[Home](/) / [Docs](/docs/) / Snowflake
 Copy as Markdown
Snowflake
=========
Discover a seamless integration process! Learn how to connect Snowflake to Peaka effortlessly for streamlined transactions.
This article guides you through the process of connecting Snowflake to Peaka, allowing you to seamlessly access your Snowflake data within the Peaka platform.
Prerequisites
-------------
Peaka provides two ways to connect to Snowflake:
* Using Snowflake Password
* Using Snowflake Private Key
Before you begin, ensure you have the following credentials from Snowflake:
* **Account**
* **User**
* **Password** (for using Snowflake Password)
* **Private Key** (for using Snowflake Private Key)
* **Private Key Passphrase** (for using Snowflake Private Key)
* **Database Name**
* **Role**
* **Warehouse**
* **Http Proxy**
Follow the steps below to obtain it:
1. To get the Account information, follow these steps:
* Log in to your Snowflake account. If you are logging in for the first time, use the email you have received from Snowflake.
* At the bottom left, click on your generated account name next to the Snowflake icon.
* Copy the **Account** name shown and store them in a safe place.
2. To get the User, follow these steps:
* User fields are your Snowflake account's login credentials.
3. To get the Database Name information, follow these steps:
* This is the name of your database before creation. If you haven't created a database yet, you will need to do so.
4. To get the Role information, follow these steps:
* Navigate to **Admin > Users & Roles** in the left-hand menu.
* Select the **Roles** tab, and your roles will be displayed. Copy the necessary role.
5. To get the Warehouse information, follow these steps:
* Navigate to **Admin > Warehouses** in the left-hand menu.
* Your warehouses will be shown. Copy the required warehouse.
6. To get the Http Proxy information, follow these steps:
* If you need to set up an HTTP Proxy, refer to the following articles:
* [AWS](https://docs.snowflake.com/en/sql-reference/external-functions-creating-aws-ui-proxy-service)
* [Google Cloud](https://docs.snowflake.com/en/sql-reference/external-functions-creating-gcp-ui-proxy-service)
### Authentication Methods
Choose one of the following authentication methods based on your security requirements:
#### Method 1: Private Key Authentication
7. **Private Key & Passphrase Setup:**
* Generate your private key pair by following the [official Snowflake key-pair authentication guide](https://docs.snowflake.com/en/user-guide/key-pair-auth#generate-the-private-keys)
* Store the private key securely and note the passphrase you created during generation
#### Method 2: Password Authentication
8. **Password Setup:**
* Use your standard Snowflake account login password
Connecting Snowflake to Peaka
-----------------------------
Now that you have your Snowflake Account, User,Password, Database Name, Role, Warehouse and Http Proxy, you can connect it to Peaka using the following steps:
1. Navigate to the data model page in Peaka.
2. In the side menu bar, click the "New Data Source" button to initiate the connection process.
3. In the modal that appears, select "Snowflake" as your data source.
4. Enter a name for your data source name and paste values that you before.
5. Click "Connect" to create your Snowflake data source.
Congratulations! You've successfully connected Snowflake to Peaka. You can now access and manage your Snowflake data seamlessly within the Peaka platform.
On this page
* [Prerequisites](https://www.peaka.com/docs/integrations/snowflake/#prerequisites)
* [Authentication Methods](https://www.peaka.com/docs/integrations/snowflake/#authentication-methods)
* [Connecting Snowflake to Peaka](https://www.peaka.com/docs/integrations/snowflake/#connecting-snowflake-to-peaka)
--- START: docs/integrations/stripe/stripe.md ---
Documentation menu
[Home](/) / [Docs](/docs/) / Stripe
 Copy as Markdown
Stripe
======
Discover a seamless integration process! Learn how to connect Stripe to Peaka effortlessly for streamlined transactions.
This article guides you through the process of connecting Stripe to Peaka, allowing you to seamlessly access your Stripe data within the Peaka platform.
Prerequisites
-------------
Before you start, you will need an API Key from Stripe.
Follow the steps below to obtain it:
1. Go to this [link](https://stripe.com/) and log in to your Stripe account. This will take you to your Stripe dashboard.
2. Click the "Developers" button, as shown in the image below.
3. In the Developers section, click the "API Keys" button.Then click the "Reveal test key" button to display your API Key.
Connecting Stripe to Peaka
--------------------------
Now that you have your requirements, you can connect it to Peaka using the following steps:
1. Navigate to the data model page in Peaka.
2. In the side menu bar, click the "New Data Source" button to initiate the connection process.
3. In the modal that appears, select "Stripe" as your data source.
4. Enter your data source name and API Key.
5. Click "Authorize" to create your Stripe data source.
Congratulations! You've successfully created a data source between Stripe and Peaka. You can now access and manage your Stripe data seamlessly within the Peaka platform.
On this page
* [Prerequisites](https://www.peaka.com/docs/integrations/stripe/#prerequisites)
* [Connecting Stripe to Peaka](https://www.peaka.com/docs/integrations/stripe/#connecting-stripe-to-peaka)
--- START: docs/integrations/twilio/twilio.md ---
Documentation menu
[Home](/) / [Docs](/docs/) / Twilio
 Copy as Markdown
Twilio
======
Discover a seamless integration process! Learn how to connect Twilio to Peaka effortlessly for streamlined transactions.
This article guides you through the process of connecting Twilio to Peaka, allowing you to seamlessly access your Twilio data within the Peaka platform.
Prerequisites
-------------
Before you start, you will need SID and Auth Token from Twilio.
Follow the steps below to obtain it:
1. Go to this [link](https://console.twilio.com/).
2. Scroll down on the page, and you will find your Twilio SID and Auth Token, as shown in the image below.

Connecting Twilio to Peaka
--------------------------
Now that you have your requirements, you can connect it to Peaka using the following steps:
1. Navigate to the data model page in Peaka.
2. In the side menu bar, click the "New Data Source" button to initiate the connection process.
3. In the modal that appears, select "Twilio" as your connection.
4. Enter a name for your data source name and paste values that you got before.

5. Click "Authorize" to create your Twilio data source.
Congratulations! You've successfully created a data source between Twilio and Peaka. You can now access and manage your Twilio data seamlessly within the Peaka platform.
On this page
* [Prerequisites](https://www.peaka.com/docs/integrations/twilio/#prerequisites)
* [Connecting Twilio to Peaka](https://www.peaka.com/docs/integrations/twilio/#connecting-twilio-to-peaka)
--- START: docs/integrations/upstash-vector/upstash-vector.md ---
Documentation menu
[Home](/) / [Docs](/docs/) / Upstash Vector
 Copy as Markdown
Upstash Vector
==============
Discover a seamless integration process! Learn how to connect Upstash Vector to Peaka effortlessly for streamlined transactions.
This article guides you through the process of connecting Upstash Vector to Peaka, allowing you to seamlessly access your Upstash Vector data within the Peaka platform.
Prerequisites
-------------
Before you start, you will need the following information from Upstash Vector.
* Index Endpoint
* Token
Follow the steps below to obtain it:
1. To obtain your Index Endpoint and Token, navigate to the project dashboard. If you don't have an existing Upstash Vector project, create a new one to access these credentials.
Connecting Upstash Vector to Peaka
----------------------------------
Now that you have obtained the necessary integration data and credentials, you can connect Upstash Vector to Peaka using the following steps:
1. Navigate to the data model page in Peaka.
2. In the side menu bar, click the "New Data Source" button to initiate the connection process.
3. In the modal that appears, select "Upstash Vector" as your data source.
4. Enter a name for your data source and paste values that you got before.
5. Click "Authorize" to create your Upstash Vector data source.
Congratulations! You've successfully connected Upstash Vector to Peaka. You can now access and manage your Upstash Vector data seamlessly within the Peaka platform.
On this page
* [Prerequisites](https://www.peaka.com/docs/integrations/upstash-vector/#prerequisites)
* [Connecting Upstash Vector to Peaka](https://www.peaka.com/docs/integrations/upstash-vector/#connecting-upstash-vector-to-peaka)
--- START: docs/integrations/weaviate/weaviate.md ---
Documentation menu
[Home](/) / [Docs](/docs/) / Weaviate
 Copy as Markdown
Weaviate
========
Discover a seamless integration process! Learn how to connect Weaviate to Peaka effortlessly for streamlined transactions.
This article guides you through the process of connecting Weaviate to Peaka, allowing you to seamlessly access your Weaviate data within the Peaka platform.
Prerequisites
-------------
Before you start, you will need the following information from Weaviate.
* Weaviate Server URL
* API Key
Follow the steps below to obtain it:
1. To obtain Weaviate Server URL and API Key, check this [article](https://weaviate.io/developers/weaviate/quickstart#:~:text=You%20need%20a%20Weaviate%20instance,the%20Details%20tab%20in%20WCD.).
Connecting Weaviate to Peaka
----------------------------
Now that you have obtained the necessary integration data and credentials, you can connect Weaviate to Peaka using the following steps:
1. Navigate to the data model page in Peaka.
2. In the side menu bar, click the "New Data Source" button to initiate the connection process.
3. In the modal that appears, select "Weaviate" as your data source.
4. Enter a name for your data source and paste values that you got before.
5. Click "Authorize" to create your Weaviate data source.
Congratulations! You've successfully connected Weaviate to Peaka. You can now access and manage your Weaviate data seamlessly within the Peaka platform.
On this page
* [Prerequisites](https://www.peaka.com/docs/integrations/weaviate/#prerequisites)
* [Connecting Weaviate to Peaka](https://www.peaka.com/docs/integrations/weaviate/#connecting-weaviate-to-peaka)
--- START: docs/integrations/xero-accounting/xero-accounting.md ---
Documentation menu
[Home](/) / [Docs](/docs/) / Xero Accounting
 Copy as Markdown
Xero Accounting
===============
Discover a seamless integration process! Learn how to connect Xero Accounting to Peaka effortlessly for streamlined transactions.
This article guides you through the process of connecting Xero Accounting to Peaka, allowing you to seamlessly access your Xero Accounting data within the Peaka platform.
Prerequisites
-------------
Before you start, you will need the following information from Xero Accounting.
* Client ID (required for advanced setup)
* Client Secret (required for advanced setup)
Follow the steps below to obtain it:
1. To obtain the Client ID, visit the [Xero Developer Portal](https://developer.xero.com/app/manage/app), select your app, and find the Client ID in the "Configuration" tab on the right side of the page.
2. To obtain the Client Secret, click on the "Generate a secret" button and it will be displayed client secret.
Connecting Xero Accounting to Peaka
-----------------------------------
1. Navigate to the data model page in Peaka.
2. In the side menu bar, click the "New Data Source" button to initiate the connection process.
3. In the modal that appears, select "Xero Accounting" as your data source.
4. Enter a name for your data source and input the information you obtained in the previous step.
5. Click "Sign in" to create your Xero Accounting data source and allow Peaka access to your Xero Accounting account.
Congratulations! You've successfully connected Xero Accounting to Peaka. You can now access and manage your Xero Accounting data seamlessly within the Peaka platform.
On this page
* [Prerequisites](https://www.peaka.com/docs/integrations/xero-accounting/#prerequisites)
* [Connecting Xero Accounting to Peaka](https://www.peaka.com/docs/integrations/xero-accounting/#connecting-xero-accounting-to-peaka)
--- START: docs/integrations/youtube-analytics/youtube-analytics.md ---
Documentation menu
[Home](/) / [Docs](/docs/) / Youtube Analytics
 Copy as Markdown
Youtube Analytics
=================
Discover a seamless integration process! Learn how to connect Youtube Analytics to Peaka effortlessly for streamlined transactions.
This article guides you through the process of connecting Youtube Analytics to Peaka, allowing you to seamlessly access your Youtube Analytics data within the Peaka platform.
Prerequisites
-------------
Before you start, you will need the following information from Youtube Analytics.
* Client ID (required for advanced authentication)
* Client Secret (required for advanced authentication)
Follow the steps below to obtain it:
1. To obtain the Client ID and Client Secret, refer to this [article](https://developers.google.com/identity/protocols/oauth2#1.-obtain-oauth-2.0-credentials-from-the-dynamic_data.setvar.console_name-.).
Connecting Youtube Analytics to Peaka
-------------------------------------
Now that you have obtained the necessary integration data and credentials, you can connect Youtube Analytics to Peaka using the following steps:
1. Navigate to the data model page in Peaka.
2. In the side menu bar, click the "New Data Source" button to initiate the connection process.
3. In the modal that appears, select "Youtube Analytics" as your data source.
4. Enter a name for your data source and paste values that you got before.
5. Click "Sign in" to create your Youtube Analytics data source and allow the connection to access your Youtube Analytics data.
Congratulations! You've successfully connected Youtube Analytics to Peaka. You can now access and manage your Youtube Analytics data seamlessly within the Peaka platform.
On this page
* [Prerequisites](https://www.peaka.com/docs/integrations/youtube-analytics/#prerequisites)
* [Connecting Youtube Analytics to Peaka](https://www.peaka.com/docs/integrations/youtube-analytics/#connecting-youtube-analytics-to-peaka)
--- START: docs/integrations/zendesk/zendesk.md ---
Documentation menu
[Home](/) / [Docs](/docs/) / Zendesk
 Copy as Markdown
Zendesk
=======
Discover a seamless integration process! Learn how to connect Zendesk to Peaka effortlessly for streamlined transactions.
This article guides you through the process of connecting Zendesk to Peaka, allowing you to seamlessly access your Zendesk data within the Peaka platform.
Prerequisites
-------------
Before you start, you will need the following information from Zendesk.
* Domain
* Unique Identifier
* Secret
Follow the steps below to obtain it:
1. Go to [Zendesk website](https://www.zendesk.com) and sign in to your Zendesk account.
2. Click on the settings icon, as shown in the image below, to access your account settings.
3. On the Settings page, you will find your Zendesk domain. Make a note of it.
4. Navigate to the Admin Center by clicking on it, as shown in the image below.
5. Inside the Admin Center, go to the "Zendesk API" tab from the left menu and click the "Add OAuth Client" button.
6. Begin by entering a distinct name and identifier for your integration. Following that, choose "Confidential" as the Client type. Proceed by inserting the following URL for the Redirect URLs parameter:
[https://peaka.studio/oauth2/callback](https://peaka.studio/oauth2/callback) 
7. Next, click the save button to establish your OAuth client. Upon creation, Zendesk will produce a Secret token for you. It's crucial to record this for future reference.
Connecting Zendesk to Peaka
---------------------------
Now that you have your requirements, you can connect it to Peaka using the following steps:
1. Navigate to the data model page in Peaka.
2. In the side menu bar, click the "New Data Source" button to initiate the connection process.
3. In the modal that appears, select "Zendesk" as your data source.
4. Enter a name for your data source and paste values that you got before.
5. Click "Authorize" to create your Zendesk data source.
Congratulations! You've successfully created a new data source between Zendesk and Peaka. You can now access and manage your Zendesk data seamlessly within the Peaka platform.
On this page
* [Prerequisites](https://www.peaka.com/docs/integrations/zendesk/#prerequisites)
* [Connecting Zendesk to Peaka](https://www.peaka.com/docs/integrations/zendesk/#connecting-zendesk-to-peaka)
--- START: docs/integrations/zoho-crm/zoho-crm.md ---
Documentation menu
[Home](/) / [Docs](/docs/) / Zoho CRM
 Copy as Markdown
Zoho CRM
========
Discover a seamless integration process! Learn how to connect Zoho CRM to Peaka effortlessly for streamlined transactions.
This article guides you through the process of connecting Zoho CRM to Peaka, allowing you to seamlessly access your Zoho CRM data within the Peaka platform.
Follow these steps to connect Zoho CRM to Peaka:
1. Navigate to the data model page in Peaka.
2. In the side menu bar, click the "New Data Source" button to initiate the connection process.
3. In the modal that appears, select "Zoho CRM" as your data source.
4. Enter a name for your data source and select a domain.
5. Click the "Signing in to Zoho CRM" button. This will open a modal to allow Peaka access to your Zoho CRM account.
6. In the modal, click the "Allow" button to grant Peaka access to your Zoho CRM data.
Congratulations! You've successfully connected Zoho CRM to Peaka. You can now access and manage your Zoho CRM data seamlessly within the Peaka platform.
--- START: docs/integrations/zoom/zoom.md ---
Documentation menu
[Home](/) / [Docs](/docs/) / Zoom
 Copy as Markdown
Zoom
====
Discover a seamless integration process! Learn how to connect Zoom to Peaka effortlessly for streamlined transactions.
This article guides you through the process of connecting Zoom to Peaka, allowing you to seamlessly access your Zoom data within the Peaka platform.
Prerequisites
-------------
Before you start, you will need the following information from Zoom.
* Client ID (required for advanced authentication)
* Client Secret (required for advanced authentication)
Follow the steps below to obtain it:
1. Navigate to the [Zoom Marketplace](https://marketplace.zoom.us/) and select 'Build App' from the dropdown menu to begin the app creation process.
2. Choose the type of app you want to create from the available options.
3. In the left-side menu, locate the section highlighted in a red rectangle and copy your Client ID and Client Secret from there.
4. Scroll down to the "Select how the app is managed" section and select "Admin-managed" to specify the management type for your app.
5. Scroll down to the "OAuth Information" section, where you will find the field for the OAuth Redirect URL. Enter `https://peaka.studio/oauth2/callback` in this field, as it is crucial for redirecting users after they complete the authentication process.
6. In the left-side menu, click on the "Scopes" option, then click the "Add Scopes" button to proceed with defining the permissions your app will require.
7. In the modal that appears, choose the following mandatory scopes to ensure your app has the necessary permissions for optimal functionality:
* View users
* View a user's meetings
* View a past meeting's instances
* View a past meeting's participants
* View a meeting's registrants
* View a user's upcoming meetings
* View a meeting
* View a meeting's participant
* View a past meeting
* View a meeting's registrant
8. After reviewing your selected scopes, click the "Continue" button.
Connecting Zoom to Peaka
------------------------
Now that you have obtained the necessary integration data and credentials, you can connect Zoom to Peaka using the following steps:
1. Navigate to the data model page in Peaka.
2. In the side menu bar, click the "New Data Source" button to initiate the connection process.
3. In the modal that appears, select "Zoom" as your data source.
4. Enter a name for your data source and paste values that you got before.
5. Click "Sign In" to connect Zoom and allow access to your data.
Congratulations! You've successfully connected Zoom to Peaka. You can now access and manage your Zoom data seamlessly within the Peaka platform.
On this page
* [Prerequisites](https://www.peaka.com/docs/integrations/zoom/#prerequisites)
* [Connecting Zoom to Peaka](https://www.peaka.com/docs/integrations/zoom/#connecting-zoom-to-peaka)
--- START: docs/jexl/advanced-jexl/advanced-jexl.md ---
Documentation menu
[Home](/) / [Docs](/docs/) / How to implement advanced JEXL functions in Peaka
 Copy as Markdown
How to implement advanced JEXL functions in Peaka
=================================================
Click here for an overview of the advanced functions in JEXL
### Unary Operators
Operation
Symbol
Negate
!
**Example**
The exclamation mark negates the boolean that appears next to it.
{{!true}}
### Binary Operators
Operation
Symbol
Add, Concat
+
Subtract
\-
Multiply
\*
Divide
/
Divide and floor
//
Modulus
%
Power of
^
Logical AND
&&
Logical OR
||
### Comparisons
Comparison
Symbol
Equal
`==`
Not equal
`!=`
Greater than
`>`
Greater than or equal
`>=`
Less than
`<`
Less than or equal
`<=`
Element in array or string
`in`
**A note about `in`**
The `in` operator can be used to check for a substring: `"Cad" in "Ron Cadillac"`, and it can be used to check for an array element: `"coarse" in ['fine', 'medium', 'coarse']`. However, the `==` operator is used behind-the-scenes to search arrays, so it should not be used with arrays of objects. The following expression returns false: `{a: 'b'} in [{a: 'b'}]`.
### Ternary operator
Conditional expressions are used to check if the first segment returns a correct value. If that’s the case, the value in the next segment is applied. Otherwise, the other value is applied. If the next segmeent is missing, the test result itself will be used instead.
Expression
Result
"" ? "Full" : "Empty"
Empty
"foo" in "foobar" ? "Yes" : "No"
Yes
`{agent: "Archer"}.agent ?: "Kane"`
Archer
### Native Types
Type
Examples
Booleans
`true`, `false`
Strings
"Hello "user"", 'Hey there!'
Numerics
6, -7.2, 5, -3.14159
Objects
`{hello: "world!"}`
Arrays
\['hello', 'world!'\]
### Groups
Parentheses work just how you'd expect them to:
Expression
Result
(83 + 1) / 2
42
1 < 3 && (4 > 2 || 2 > 4)
true
### Identifiers
Access variables in the context object by just typing their name. Objects can be accessed with dot notation, or by using brackets to access a dynamic property name.
Example context:
{
name: {
first: "Malory",
last: "Archer"
},
exes: [
"Nikolai Jakov",
"Len Trexler",
"Burt Reynolds"
],
lastEx: 2
}
Expression
Result
name.first
Malory
name\['la' + 'st'\]
Archer
exes\[2\]
Burt Reynolds
exes\[lastEx - 1\]
Len Trexler
### Functions
In JEXL, common built-in functions are readily available, but also functions library is extended with lodash functions.
You can use lodash functions from this [link](https://lodash.com/docs/4.17.15).
Additionally, you can read [our documentation on JEXL](/docs/jexl/built-in-functions/) to learn more about these functions.
**Example**
Check out the JEXL codes below:
_Find Min_
{{ min([65, 42, 87, 88]) }}
// => 42
_Reverse Array_
{{ reverse([1, 2, 3, 4]) }}
// => [4, 3, 2, 1]
_Check Equal_
{{ eq({ a:1 }, { a:1 }) }}
// => true
{{ eq(3, 4) }}
// => false
_Add Elements To Array_
{{ concat([1], 2, 3, 4) }}
// => [1, 2, 3, 4]
_Get Last Element of Array_
{{ reverse([1, 2, 3]) }}
// => 3
On this page
* [Unary Operators](https://www.peaka.com/docs/jexl/advanced-jexl/#unary-operators)
* [Binary Operators](https://www.peaka.com/docs/jexl/advanced-jexl/#binary-operators)
* [Comparisons](https://www.peaka.com/docs/jexl/advanced-jexl/#comparisons)
* [Ternary operator](https://www.peaka.com/docs/jexl/advanced-jexl/#ternary-operator)
* [Native Types](https://www.peaka.com/docs/jexl/advanced-jexl/#native-types)
* [Groups](https://www.peaka.com/docs/jexl/advanced-jexl/#groups)
* [Identifiers](https://www.peaka.com/docs/jexl/advanced-jexl/#identifiers)
* [Functions](https://www.peaka.com/docs/jexl/advanced-jexl/#functions)
--- START: docs/jexl/built-in-functions/built-in-functions.md ---
Documentation menu
[Home](/) / [Docs](/docs/) / How to implement Peaka functions in JEXL
 Copy as Markdown
How to implement Peaka functions in JEXL
========================================
Click here for an introduction to using Peaka functions in JEXL
### **stringConcat(value)**
This function converts the provided value into a string representation.
stringConcat(123456);
// => '123456'
### **convertLocaleString(value, locale, options)**
Converts a value to a string with a specified locale.
* `value` can be a number or date type and is required.
* `locale` is your desired locale language (e.g., 'fr' for French, 'tr' for Turkish) and is required.
* `options` is an optional object for customization, as shown below:
{
weekday: "long",
year: "numeric",
month: "long",
day: "numeric",
};
convertLocaleString(123456.789, "de", {
style: "currency",
currency: "EUR",
});
// => 123.456,79 €
### **convertLocaleDateString(value, locale, options)**
Converts a value to a string with a specified locale.
* `value` can be a string or date type and is required.
* `locale` is your desired locale language (e.g., 'fr' for French, 'tr' for Turkish) and must be a string, and it's required.
* `options` is an optional object for customization, as shown below:
{
weekday: "long",
year: "numeric",
month: "long",
day: "numeric",
};
convertLocaleDateString("Tue Aug 15 2023 10:23:41", "de", {
weekday: "long",
year: "numeric",
month: "long",
day: "numeric",
});
// => Dienstag, 15. August 2023
### **push(arr, value)**
Appends a new value to an array.
* `arr` must be of type array and is a required parameter.
* `value` can be of any data type and is also required.
push([1, 2, 3, 4, 5], 6);
// => [1, 2, 3, 4, 5, 6]
### **addKey(object, key, value)**
Adds a new key and value to an object.
* `object` must be an object type and is required.
* `key` must be a string type and is required.
* The type of `value` may be a string, number, date, object, array, and is required.
addKey(
{
weekday: "long",
year: "numeric",
month: "long",
},
"day",
"numberic"
);
/* =>
{
weekday: "long",
year: "numeric",
month: "long",
day: "numeric",
}
*/
### **removeKey(object, key)**
Deletes a key from an object.
* `object` must be an object type and is required.
* `key` must be a string type and is required.
removeKey(
{
weekday: "long",
year: "numeric",
month: "long",
},
"month"
);
/* =>
{
weekday: "long",
year: "numeric",
}
*/
### **mapToKey(objects, key)**
Retrieves values of a specified key.
* `objects` is an array that includes objects and is required.
* `key` must be a string type and is required.
mapToKey([{ value: 11 }, { value: 22 }], "value");
// => [11,22]
### **filterByKeys(objects, keys)**
Filters objects by specified keys.
* `objects` is an array that includes objects and is required.
* `keys` is an array of strings and is required
filterByKeys(
[
{ name: "Joe", surname: "Doe" },
{ name: "Can", surname: "Tuna" },
],
["surname"]
);
// => [{surname:'Doe'},{surname: 'Tuna'}]
### **fromEntries(object)**
Returns an array of keys and values from an object.
* `object` must be an object type and is required.
fromEntries({
a: "somestring",
b: 42,
});
// => [['a', 'something'], ['b', 42]]
### **fromKeysAndValues(keys, values)**
It creates an object with your keys and values. You need to enter them by your order.
* `keys` must be an array and is required.
* `values` must be an array and is required.
fromKeysAndValues(["one", "two", "three"], [1, 2, 3]);
// => { one: 1, two: 2, three: 3}
### **uuid()**
Generates a unique ID.
uuid();
// => 4d85bbb9-f602-40f9-bd07-48eda130a1b5
### **len(arr)**
Returns the length of an array.
* `arr` is an array and is required.
len([1, 2, 3, 4, 5, 6]);
// => 6
### **updateKey(object, oldKey, newKey)**
Updates a specified key. It finds the old key and replaces it with the new key.
* `object` must be an object type and is required.
* `oldKey` must be a string type and is required.
* `newKey` must be a string type and is required.
updateKey(
{
a: "somestring",
b: 42,
},
"b",
"newKeyC"
);
/* =>
{
a: "somestring",
newKeyC: 42
}
*/
### **findDeep(arr,recursiveKey, searchKey, value)**
Finds a value based on a search key and returns its value. If the value is not found or the search key's value does not match, it returns 'undefined'.
* `arr` may be an object or array type and is required.
* `recursiveKey` is the key for recursive array searching. If not applicable, use an empty string ('').
* `searchKey` is the key you are searching for.
* `value` is the value to compare against the search key.
findDeep(
{
item: "string",
children: [
{
item: "string2",
children: [{ valueKey: "myValue" }],
},
],
},
"children",
"valueKey",
"myValue"
);
// => {valueKey: "myValue"}
### **removeIndex(array, index)**
Removes an element at a specified index.
* `array` must be an array and is required.
* `index`must be number of string and is required.
removeIndex(["one", "two", "three"], 0);
// => ['two'. 'three']
### **jsonStringify(value)**
This function converts the given value into a string representation.
* `value` can be of any data type and is a required parameter.
jsonStringify({ name: "John", age: 30, city: "New York" });
// => "{ name: "John", age: 30, city: "New York" }"
### **jsonParse(value)**
This function parses the provided value, converting it from a string back into its original data structure.
* `value` can be of any data type and is a required parameter.
jsonStringify("{ name: 'John', age: 30, city: 'New York' }");
// => { name: "John", age: 30, city: "New York" }
### **withQuotes(value)**
The withQuotes function encloses a given string with quotation marks, both at the start and end.
* `value` must be of string type and is a required parameter.
withQuotes("can tuna");
// => "can tuna"
### **trimQuotes(value)**
This function removes leading and trailing quotation marks from a string.
* `value` must be of string type and is a required parameter.
trimQuotes("\"How to add doublequotes\"");
// => can tuna
### **fetch(url,options)**
This function initiates an HTTP request.
* `url` is the URL for your request and is a required parameter.
* `options` represent request configuration and is also required.
fetch("https://jsonplaceholder.typicode.com/posts", {
method: "POST",
headers: {
"Content-Type": "application/json",
},
});
### **getQueryParameter(url, key)**
The getQueryParameter function extracts a specific query parameter from a URL.
* `url` must be of string type and is required.
* `key` is the parameter key to retrieve and is also required.
getQueryParameter("https://example.com?foo=1&bar=2", "foo");
// => 1
### **getQueryParameters()**
This function returns all query parameters from a URL.
* `url` is your URL and is a required parameter.
* `key` is the parameter key to retrieve, and it's also required.
getQueryParameter("https://example.com?foo=1&foo=2", "foo");
// => [1, 2]
### **now()**
The now function returns the current date and time.
now();
// => 2023-08-15T12:53:50.862Z
On this page
* [stringConcat(value)](https://www.peaka.com/docs/jexl/built-in-functions/#stringconcat-value)
* [convertLocaleString(value, locale, options)](https://www.peaka.com/docs/jexl/built-in-functions/#convertlocalestring-value-locale-options)
* [convertLocaleDateString(value, locale, options)](https://www.peaka.com/docs/jexl/built-in-functions/#convertlocaledatestring-value-locale-options)
* [push(arr, value)](https://www.peaka.com/docs/jexl/built-in-functions/#push-arr-value)
* [addKey(object, key, value)](https://www.peaka.com/docs/jexl/built-in-functions/#addkey-object-key-value)
* [removeKey(object, key)](https://www.peaka.com/docs/jexl/built-in-functions/#removekey-object-key)
* [mapToKey(objects, key)](https://www.peaka.com/docs/jexl/built-in-functions/#maptokey-objects-key)
* [filterByKeys(objects, keys)](https://www.peaka.com/docs/jexl/built-in-functions/#filterbykeys-objects-keys)
* [fromEntries(object)](https://www.peaka.com/docs/jexl/built-in-functions/#fromentries-object)
* [fromKeysAndValues(keys, values)](https://www.peaka.com/docs/jexl/built-in-functions/#fromkeysandvalues-keys-values)
* [uuid()](https://www.peaka.com/docs/jexl/built-in-functions/#uuid)
* [len(arr)](https://www.peaka.com/docs/jexl/built-in-functions/#len-arr)
* [updateKey(object, oldKey, newKey)](https://www.peaka.com/docs/jexl/built-in-functions/#updatekey-object-oldkey-newkey)
* [findDeep(arr,recursiveKey, searchKey, value)](https://www.peaka.com/docs/jexl/built-in-functions/#finddeep-arr-recursivekey-searchkey-value)
* [removeIndex(array, index)](https://www.peaka.com/docs/jexl/built-in-functions/#removeindex-array-index)
* [jsonStringify(value)](https://www.peaka.com/docs/jexl/built-in-functions/#jsonstringify-value)
* [jsonParse(value)](https://www.peaka.com/docs/jexl/built-in-functions/#jsonparse-value)
* [withQuotes(value)](https://www.peaka.com/docs/jexl/built-in-functions/#withquotes-value)
* [trimQuotes(value)](https://www.peaka.com/docs/jexl/built-in-functions/#trimquotes-value)
* [fetch(url,options)](https://www.peaka.com/docs/jexl/built-in-functions/#fetch-url-options)
* [getQueryParameter(url, key)](https://www.peaka.com/docs/jexl/built-in-functions/#getqueryparameter-url-key)
* [getQueryParameters()](https://www.peaka.com/docs/jexl/built-in-functions/#getqueryparameters)
* [now()](https://www.peaka.com/docs/jexl/built-in-functions/#now)
--- START: docs/jexl/lodash-functions/lodash-functions.md ---
Documentation menu
[Home](/) / [Docs](/docs/) / Most-used Lodash functions in Peaka
 Copy as Markdown
Most-used Lodash functions in Peaka
===================================
Learn more about the most-used lodash functions in Peaka
In JEXL, we can use all lodash functions. This article provides a list of the most frequently used among them.
If you want to see more lodash functions, check out [this article](https://lodash.com/docs).
### isArray(value)
Checks if value is classified as an Array object.
* value is required.
{{ isArray([1, 2, 3]) }}
// => true
{{ isArray('text') }}
// => false
### concat(array, \[values\])
Creates a new array concatenating array with any additional arrays and/or values.
* values and array are required.
{{ concat([1], 2, [3], [[4]]) }}
// => [1, 2, 3, [4]]
### indexOf(array, value, \[fromIndex=0\])
Gets the index where the first occurrence of value is found in array. If fromIndex is negative, it's used as the offset from the end of array.
* array and value is required.
* array (Array): The array to inspect.
* value (\*): The value to search for.
* \[fromIndex=0\] (number): The index to search from.
{{ _.indexOf([1, 2, 1, 2], 2) }}
// => 1
// Search from the `fromIndex`.
{{ indexOf([1, 2, 1, 2], 2, 2) }}
// => 3
### reverse(array)
Reverses array so that the first element becomes the last, the second element becomes the second to last, and so on.
* array is required.
{{ reverse([1, 2, 3]) }}
// => [3, 2, 1]
### slice(array, \[start=0\], \[end=array.length\])
Creates a slice of array from start up to, but not including, the end.
* array (Array): The array to slice.
* \[start=0\] (number): The start position.
* \[end=array.length\] (number): The end position.
{{ slice([1,2,3,4,5],2,4)}}
// [3,4]
### without(array, \[values\])
Creates an array excluding all given values.
* array (Array): The array to inspect.
* \[values\]: The values to exclude.
{{ without([2, 1, 2, 3], 1, 2) }}
// => [3]
### filter(collection, filterItems)
Iterates over elements of collection, returning an array of all elements predicate returns truthy for. The predicate is invoked with three arguments: (value, index|key, collection).
* collection (Array|Object): The collection to iterate over.
* filterItems: The items you want to filter by them.
{{
filter(
[
{ user: "barney", age: 36, active: true },
{ user: "fred", age: 40, active: false },
],
{ age: 36, active: true }
);
}}
// => ['barney']
{{
filter(
[
{ user: "barney", age: 36, active: true },
{ user: "fred", age: 40, active: false },
],
["active", false]
);
}}
// => ['fred']
### eq(value, other)
Compares `value` and `other`, return true or false according to they equals each other or not.
* value and other are required and can be any type.
{{ eq( 1, 1 ) }}
// => true
{{ eq( 1, 'some text' ) }}
// => false
### sum(array)
Computes the sum of the values in array.
* array is required and includes items which are number tpye.
{{ sum([4, 2, 8, 6]) }}
// => 20
### max(array)
Computes the maximum value of array. If array is empty or falsey, undefined is returned.
* array is required.
{{ max([4, 2, 8, 6]) }}
// => 8
{{ max([]) }}
// => undefined
### get(object, path, \[defaultValue\])
Gets the value at path of object. If the resolved value is undefined, the defaultValue is returned in its place.
* object (Object): The object to query.
* path (Array|string): The path of the property to get.
* \[defaultValue\] (\*): The value returned for undefined resolved values.
{{
get({ a: [{ b: { c: 3 } }] }), "a[0].b.c";
}}
// => 3
{{
get({ a: [{ b: { c: 3 } }] }),['a', '0', 'b', 'c'];
}}
// => 3
### hasIn(object, path)
Checks if path is a direct or inherited property of object.
* object and path are required.
{{ hasIn({ a: { b:2 }}, 'a') }}
// => true
{{ hasIn({ a: { b:2 }}, 'a.b') }}
// => true
{{ hasIn({ a: { b:2 }}, ['a', 'b']) }}
// => true
{{ hasIn({ a: { b:2 }}, 'b') }}
// => false
On this page
* [isArray(value)](https://www.peaka.com/docs/jexl/lodash-functions/#isarray-value)
* [concat(array, \[values\])](https://www.peaka.com/docs/jexl/lodash-functions/#concat-array-values)
* [indexOf(array, value, \[fromIndex=0\])](https://www.peaka.com/docs/jexl/lodash-functions/#indexof-array-value-fromindex-0)
* [reverse(array)](https://www.peaka.com/docs/jexl/lodash-functions/#reverse-array)
* [slice(array, \[start=0\], \[end=array.length\])](https://www.peaka.com/docs/jexl/lodash-functions/#slice-array-start-0-end-array-length)
* [without(array, \[values\])](https://www.peaka.com/docs/jexl/lodash-functions/#without-array-values)
* [filter(collection, filterItems)](https://www.peaka.com/docs/jexl/lodash-functions/#filter-collection-filteritems)
* [eq(value, other)](https://www.peaka.com/docs/jexl/lodash-functions/#eq-value-other)
* [sum(array)](https://www.peaka.com/docs/jexl/lodash-functions/#sum-array)
* [get(object, path, \[defaultValue\])](https://www.peaka.com/docs/jexl/lodash-functions/#get-object-path-defaultvalue)
* [hasIn(object, path)](https://www.peaka.com/docs/jexl/lodash-functions/#hasin-object-path)
--- START: docs/jexl/using-jexl/using-jexl.md ---
Documentation menu
[Home](/) / [Docs](/docs/) / How to use JEXL in Peaka
 Copy as Markdown
How to use JEXL in Peaka
========================
Click here to see a detailed description of how to use JEXL in Peaka
**Javascript Expression Language: Powerful context-based expression parser and evaluator.**
In Peaka, JEXL empowers you to assign dynamic values to flows while seamlessly integrating with variables. This versatile feature extends to all property values, and for added convenience, you can access an expanded editing interface by simply clicking the arrow icon located on the right side of the property field.
Even properties typically represented as simple checkboxes can be transformed into JEXL editors with a single click of the expand icon button. Below, we present a selection of common examples demonstrating the practical application of JEXL:
**Examples**
// addition
{{sum(45, 99)}}
// => 144
// show name
{{ "Hello " + my_name_variable}}
// => 'Hello Can'
// alternatively
Hello {{ my_name_variable }}
// => 'Hello Can'
// convert the date
{{convertLocaleDateString("Tue Aug 15 2023 10:23:41", "de",{
weekday: "long",
year: "numeric",
month: "long",
day: "numeric",
})
}}
// => Dienstag, 15. August 2023
Using Variable in Webhook Response Flow Node
--------------------------------------------
The webhook response flow node is designed to return a JSON object when you send a request to an external API. This functionality allows you to dynamically retrieve and integrate data into your workflows.
To include a variable in the body of the webhook response flow node, simply enclose the variable name within double curly braces, as demonstrated in the example below:
{{ getRecord_1 }}
In addition, we can easily access the value associated with the key 'name' in the object.
{{ getRecord_1.name }}
Please refer to the documentation on [Flows](/docs/flows/) for detailed instructions.

On this page
* [Using Variable in Webhook Response Flow Node](https://www.peaka.com/docs/jexl/using-jexl/#using-variable-in-webhook-response-flow-node)
--- START: docs/mcp/authentication/authentication.md ---
Documentation menu
[Home](/) / [Docs](/docs/) / Authentication
 Copy as Markdown
Authentication
==============
How the Peaka MCP server authenticates — OAuth on the remote server, API keys for local installs.
The Peaka MCP server uses two different auth mechanisms depending on how you run it.
Install mode
Auth mechanism
Acts as
[Remote](/docs/mcp/install/remote) — `mcp.peaka.studio/mcp`
OAuth
The signed-in Peaka user
[NPM](/docs/mcp/install/npm)
`PEAKA_API_KEY` env var
The owner of the API key
[From source](/docs/mcp/install/local)
`PEAKA_API_KEY` env var
The owner of the API key
Remote — OAuth
--------------
When a client connects to `https://mcp.peaka.studio/mcp`, the server returns `401 Unauthorized` with OAuth metadata in the `WWW-Authenticate` header. Your MCP client opens a browser to `mcp.peaka.studio`, you sign in to Peaka, approve the consent screen, and the client receives an access token.
From that point on, every tool call is authorized as **you**. The assistant can do anything you can do in Peaka — and nothing else.
There is no API key to copy, rotate, or store. Tokens are scoped to your session and refresh automatically.
See [Remote install](/docs/mcp/install/remote) for the step-by-step screenshots.
Local — API keys
----------------
The NPM and from-source installs read a Peaka API key from the `PEAKA_API_KEY` environment variable. Two key types are supported.
### Project API key
A Project API key is bound to a single Peaka project. It's the simplest option and the right default if you only work with one project at a time.
* **Scope:** the one project the key was issued for.
* **`peaka_list_projects` returns:** that single project.
* **How to create one:** [How to generate API keys](/docs/cookbook/how-to-generate-api-keys).
### Partner API key
A Partner API key is bound to your Peaka account and can act across all organizations and workspaces that account owns.
* **Scope:** every project your account can access.
* **`peaka_list_projects` returns:** all projects across all organizations and workspaces — useful when you want the assistant to discover and switch between projects.
* **How to create one:** [How to manage Partner API keys](/docs/cookbook/how-to-manage-partner-api-key).
### Which should I use?
Use a Project key when… You're working with one project, you want strict scope, or you're embedding the server in a per-project workflow (CI for one project, a script that operates on a known project, etc.).
Use a Partner key when… You want the assistant to enumerate projects across your organization, or you regularly switch between projects in the same session.
### Setting the key
Pass the key via the `env` block in your MCP client config:
{
"mcpServers": {
"peaka": {
"command": "npx",
"args": ["-y", "@peaka/mcp-server-peaka@latest"],
"env": {
"PEAKA_API_KEY": ""
}
}
}
}
Treat API keys like passwords. Don't commit MCP client configs that contain raw keys to source control. Most clients also support reading from your shell environment if you'd rather not put the key in a JSON file.
What permissions does the agent have?
-------------------------------------
The MCP server is a thin protocol layer over the Peaka API — it has no special privileges. Whatever the authenticated identity (OAuth user or API key owner) is allowed to do in Peaka, the server is allowed to do. Nothing more.
If a tool call returns a permission error, the underlying identity doesn't have access; granting access in Peaka resolves it.
On this page
* [Remote — OAuth](https://www.peaka.com/docs/mcp/authentication/#remote-oauth)
* [Local — API keys](https://www.peaka.com/docs/mcp/authentication/#local-api-keys)
* [Project API key](https://www.peaka.com/docs/mcp/authentication/#project-api-key)
* [Partner API key](https://www.peaka.com/docs/mcp/authentication/#partner-api-key)
* [Which should I use?](https://www.peaka.com/docs/mcp/authentication/#which-should-i-use)
* [Setting the key](https://www.peaka.com/docs/mcp/authentication/#setting-the-key)
* [What permissions does the agent have?](https://www.peaka.com/docs/mcp/authentication/#what-permissions-does-the-agent-have)
--- START: docs/mcp/clients/clients.md ---
Documentation menu
[Home](/) / [Docs](/docs/) / Supported clients
 Copy as Markdown
Supported clients
=================
Add the Peaka MCP server to Claude Desktop, Claude Code, Cursor, Windsurf, VS Code, and any other MCP-compatible client.
The Peaka MCP server works with any client that supports the Model Context Protocol. Pick your client below for the right config snippet and a link to its "add an MCP server" instructions.
Two configuration patterns appear throughout this page:
* **Remote (recommended).** Point the client at `https://mcp.peaka.studio/mcp` and authenticate via OAuth. Some clients accept a remote URL natively; others use the [`mcp-remote`](https://www.npmjs.com/package/mcp-remote) bridge to expose it as a stdio server.
* **Local (NPM).** Run [`@peaka/mcp-server-peaka`](https://www.npmjs.com/package/@peaka/mcp-server-peaka) via `npx` and authenticate with `PEAKA_API_KEY`.
For everything else (auth modes, env vars), see [Authentication](/docs/mcp/authentication).
Claude Desktop
--------------
[Add an MCP server in Claude Desktop ↗](https://support.anthropic.com/en/articles/11175166-getting-started-with-custom-connectors-using-remote-mcp)
**Remote** — Claude Desktop adds remote MCP servers through the UI, not the JSON config file.
1
Open Settings → Connectors
Click your name in the bottom-left, then **Settings** → **Connectors**.
2
Add custom connector
Click **Add custom connector** and paste `https://mcp.peaka.studio/mcp` as the MCP Server URL.
3
Authenticate
Claude Desktop opens the OAuth flow in your browser. Sign in to Peaka and approve.
**NPM** — for the local, API-key path, edit `claude_desktop_config.json`:
* **macOS:** `~/Library/Application Support/Claude/claude_desktop_config.json`
* **Windows:** `%APPDATA%\Claude\claude_desktop_config.json`
{
"mcpServers": {
"peaka": {
"command": "npx",
"args": ["-y", "@peaka/mcp-server-peaka@latest"],
"env": { "PEAKA_API_KEY": "" }
}
}
}
Restart Claude Desktop after editing.
Claude Code
-----------
[Add an MCP server in Claude Code ↗](https://docs.claude.com/en/docs/claude-code/mcp)
# Remote
claude mcp add --transport http peaka https://mcp.peaka.studio/mcp
# NPM
claude mcp add peaka -- npx -y @peaka/mcp-server-peaka@latest -e PEAKA_API_KEY=
Cursor
------
[Add an MCP server in Cursor ↗](https://docs.cursor.com/context/model-context-protocol)
Edit `~/.cursor/mcp.json` (macOS/Linux) or `%USERPROFILE%\.cursor\mcp.json` (Windows):
{
"mcpServers": {
"peaka": {
"url": "https://mcp.peaka.studio/mcp"
}
}
}
{
"mcpServers": {
"peaka": {
"command": "npx",
"args": ["-y", "@peaka/mcp-server-peaka@latest"],
"env": { "PEAKA_API_KEY": "" }
}
}
}
Windsurf
--------
[Add an MCP server in Windsurf ↗](https://docs.windsurf.com/windsurf/cascade/mcp)
Edit `~/.codeium/windsurf/mcp_config.json`:
{
"mcpServers": {
"peaka": {
"serverUrl": "https://mcp.peaka.studio/mcp"
}
}
}
{
"mcpServers": {
"peaka": {
"command": "npx",
"args": ["-y", "@peaka/mcp-server-peaka@latest"],
"env": { "PEAKA_API_KEY": "" }
}
}
}
VS Code (GitHub Copilot)
------------------------
[Add an MCP server in VS Code ↗](https://code.visualstudio.com/docs/copilot/customization/mcp-servers)
Edit `.vscode/mcp.json` in your workspace, or your user-level `mcp.json`:
{
"servers": {
"peaka": {
"type": "http",
"url": "https://mcp.peaka.studio/mcp"
}
}
}
{
"servers": {
"peaka": {
"type": "stdio",
"command": "npx",
"args": ["-y", "@peaka/mcp-server-peaka@latest"],
"env": { "PEAKA_API_KEY": "" }
}
}
}
Zed
---
[Add an MCP server in Zed ↗](https://zed.dev/docs/ai/mcp)
Open the command palette → `agent: add context server`, or edit `settings.json`:
{
"context_servers": {
"peaka": {
"command": {
"path": "npx",
"args": ["-y", "mcp-remote", "https://mcp.peaka.studio/mcp"]
}
}
}
}
Cline
-----
[Add an MCP server in Cline ↗](https://docs.cline.bot/mcp/configuring-mcp-servers)
Open Cline → `MCP Servers` → `Configure MCP Servers`:
{
"mcpServers": {
"peaka": {
"command": "npx",
"args": ["-y", "mcp-remote", "https://mcp.peaka.studio/mcp"]
}
}
}
ChatGPT (Custom Connectors)
---------------------------
[Add a custom connector in ChatGPT ↗](https://help.openai.com/en/articles/11487775-connectors-in-chatgpt)
In ChatGPT settings → **Connectors** → **Add custom connector**, enter:
* **MCP Server URL:** `https://mcp.peaka.studio/mcp`
* **Authentication:** OAuth
ChatGPT walks you through the OAuth flow.
Any other client
----------------
Any MCP-compliant client can connect. Use one of the patterns above as a template:
* If the client supports remote MCP natively, give it `https://mcp.peaka.studio/mcp`.
* If it only supports stdio, wrap the URL with `npx -y mcp-remote https://mcp.peaka.studio/mcp`.
* If you'd rather use an API key, run `npx -y @peaka/mcp-server-peaka@latest` with `PEAKA_API_KEY` in the environment.
See [Quickstart](/docs/mcp/quickstart) for the minimal setup, [Tools reference](/docs/mcp/tools) for what the assistant can do once connected, and [Troubleshooting](/docs/mcp/troubleshooting) if something doesn't light up.
On this page
* [Claude Desktop](https://www.peaka.com/docs/mcp/clients/#claude-desktop)
* [Claude Code](https://www.peaka.com/docs/mcp/clients/#claude-code)
* [Cursor](https://www.peaka.com/docs/mcp/clients/#cursor)
* [Windsurf](https://www.peaka.com/docs/mcp/clients/#windsurf)
* [VS Code (GitHub Copilot)](https://www.peaka.com/docs/mcp/clients/#vs-code-github-copilot)
* [Zed](https://www.peaka.com/docs/mcp/clients/#zed)
* [Cline](https://www.peaka.com/docs/mcp/clients/#cline)
* [ChatGPT (Custom Connectors)](https://www.peaka.com/docs/mcp/clients/#chatgpt-custom-connectors)
* [Any other client](https://www.peaka.com/docs/mcp/clients/#any-other-client)
--- START: docs/mcp/overview/overview.md ---
Documentation menu
[Home](/) / [Docs](/docs/) / Peaka MCP Server
 Copy as Markdown
Peaka MCP Server
================
Give your AI assistant first-class access to Peaka — query data, manage caches, inspect schemas, and orchestrate semantic catalogs through the Model Context Protocol.
The Peaka MCP server exposes Peaka's data platform to any [Model Context Protocol](https://modelcontextprotocol.io/)–compatible client. Once connected, your AI assistant can list catalogs, inspect schemas, run SQL, manage caches, save queries, and build semantic catalogs on your behalf — using natural language.
Under the hood it's the same Peaka you use in Studio. The MCP server is a thin protocol adapter that lets agents call Peaka the way humans do.
What you can do with it
-----------------------
* **Talk to your data.** Ask questions in natural language; the assistant inspects your project's metadata, writes SQL, and runs it on Peaka.
* **Manage caches.** Create caches, schedule refreshes, and check status without leaving your editor.
* **Curate a semantic layer.** Save queries, group them under semantic catalogs, and surface them as queryable tables.
* **Inspect connections.** List data source connections in a project and pull connection-specific configuration.
* **Reuse golden SQL.** The server queries Peaka's golden-SQL store so the assistant can lean on vetted, hand-written queries before generating new ones.
See [Tools reference](/docs/mcp/tools) for the full list of exposed tools.
Three ways to connect
---------------------
[Remote Point any client that supports remote MCP. Recommended.](/docs/mcp/install/remote) [NPM Run the server locally. Authenticates with a Peaka API key.](/docs/mcp/install/npm) [From source Clone the repository and run it from a local checkout. For contributors and air-gapped setups.](/docs/mcp/install/local)
Authentication at a glance
--------------------------
Install mode
Auth
Acts as
Remote (`mcp.peaka.studio/mcp`)
OAuth
The signed-in Peaka user — limited to what they're authorized to do
NPM
Project or Partner API key in `PEAKA_API_KEY`
The owner of the key
From source
Project or Partner API key in `PEAKA_API_KEY`
The owner of the key
Full details in [Authentication](/docs/mcp/authentication).
Next steps
----------
[Quickstart Connect your first client in under five minutes.](/docs/mcp/quickstart) [Supported clients Claude Desktop, Claude Code, Cursor, Windsurf, VS Code, and more.](/docs/mcp/clients) [Tools reference Every tool the server exposes, grouped by area.](/docs/mcp/tools) [Troubleshooting Common errors, environment variables, and how to read server logs.](/docs/mcp/troubleshooting)
On this page
* [What you can do with it](https://www.peaka.com/docs/mcp/overview/#what-you-can-do-with-it)
* [Three ways to connect](https://www.peaka.com/docs/mcp/overview/#three-ways-to-connect)
* [Authentication at a glance](https://www.peaka.com/docs/mcp/overview/#authentication-at-a-glance)
* [Next steps](https://www.peaka.com/docs/mcp/overview/#next-steps)
--- START: docs/mcp/quickstart/quickstart.md ---
Documentation menu
[Home](/) / [Docs](/docs/) / Quickstart
 Copy as Markdown
Quickstart
==========
Connect Peaka MCP to your AI assistant in under five minutes.
The fastest way to get started is the **remote** server.
Remote (recommended)
--------------------
Point your client at:
https://mcp.peaka.studio/mcp
The first request triggers OAuth. Approve the consent screen and the assistant can act as you in Peaka.
{
"mcpServers": {
"peaka": {
"url": "https://mcp.peaka.studio/mcp"
}
}
}
Not sure which form your client wants? See [Supported clients](/docs/mcp/clients) — each row shows the right config snippet and a link to the client's "add an MCP server" docs.
Restart the client after editing its config.
NPM (local)
-----------
If you'd rather run the server yourself with a Peaka API key:
{
"mcpServers": {
"peaka": {
"command": "npx",
"args": ["-y", "@peaka/mcp-server-peaka@latest"],
"env": {
"PEAKA_API_KEY": ""
}
}
}
}
Get an API key from [How to generate API keys](/docs/cookbook/how-to-generate-api-keys). Either a Project or Partner key works — see [Authentication](/docs/mcp/authentication) for the trade-offs.
First prompts to try
--------------------
Once the server is connected, give your assistant a try:
* _"List my Peaka projects."_
* _"What catalogs and schemas are in project ``?"_
* _"Find me the top 10 customers by revenue last quarter."_
* _"Cache the `orders` table and schedule an incremental refresh every hour."_
* _"Save this query as `monthly_active_users` and surface it in a semantic catalog."_
On the remote server, the assistant is instructed to ask which project you want to work with once per session — unless you mention a specific project up front.
Next steps
----------
[Remote install details OAuth flow, scopes, and screenshots.](/docs/mcp/install/remote) [Tools reference Everything the assistant can do via the server.](/docs/mcp/tools)
On this page
* [Remote (recommended)](https://www.peaka.com/docs/mcp/quickstart/#remote-recommended)
* [NPM (local)](https://www.peaka.com/docs/mcp/quickstart/#npm-local)
* [First prompts to try](https://www.peaka.com/docs/mcp/quickstart/#first-prompts-to-try)
* [Next steps](https://www.peaka.com/docs/mcp/quickstart/#next-steps)
--- START: docs/mcp/tools/tools.md ---
Documentation menu
[Home](/) / [Docs](/docs/) / Tools reference
 Copy as Markdown
Tools reference
===============
Every tool the Peaka MCP server exposes, grouped by area.
The Peaka MCP server exposes the tools below to your AI assistant. Most are scoped to a single Peaka project — the assistant passes a `projectId` argument with each call. If the project hasn't been chosen yet, the assistant typically calls [`peaka_list_projects`](https://www.peaka.com/docs/mcp/tools/#peaka-list-projects) first.
The server also exposes two **resources** the assistant can pull in for context:
* **`peaka_sql_query_rule_set`** — guidelines for writing valid Peaka SQL.
* **`peaka_artifact_template`** — style guide and HTML template for generating visual reports, dashboards, and artifacts from query results.
Projects
--------
### `peaka_list_projects`
List all projects accessible with the current credentials. Under OAuth (remote) or a Partner API key, enumerates projects across all organizations and workspaces. Under a Project API key, returns the single project bound to the key.
Metadata
--------
### `peaka_get_project_metadata`
Get metadata for all catalogs, schemas, and tables in the project in a single call. Optionally filter by `catalogId` and/or `schemaName`.
### `peaka_list_catalogs`
List all available catalogs in the project. Returns catalog names, types, and connection info.
### `peaka_list_schemas`
List all available schemas for a given catalog.
### `peaka_list_tables`
List all available tables for a given catalog and schema.
### `peaka_list_columns`
List all columns for a given table. Returns column names, data types, and constraints.
### `peaka_get_relations`
Get table relationships (foreign keys) for a catalog. Useful for constructing accurate JOINs.
### `peaka_get_table_statistics`
Get column-level statistics for a table, including distinct-value fractions per column.
### `peaka_refresh_project_metadata`
Refresh project metadata for a specific catalog. Long-running; triggers the refresh and polls for completion.
### `peaka_get_metadata_refresh_status`
Check the current status of a metadata refresh job for a specific catalog.
Query execution
---------------
### `peaka_execute_sql_query`
Run an arbitrary SQL query on Peaka.
### `peaka_query_golden_sqls`
Query the project's golden-SQL store for question/SQL pairs. If an existing golden query matches the user's question, the assistant can reuse it directly instead of generating new SQL.
Cache
-----
### `peaka_create_cache`
Create a cache for a single table. Caching improves query performance by storing the data locally.
### `peaka_create_cache_batch`
Create caches for multiple tables in a single call. Preferred over repeated `peaka_create_cache` calls.
### `peaka_get_cache_statuses`
Get all cache statuses for tables in the project, including current caching state, execution history, and progress.
### `peaka_refresh_cache_full`
Trigger a full refresh on an existing cache.
### `peaka_refresh_cache_incremental`
Trigger an incremental update on an existing cache, fetching only new or changed rows.
### `peaka_update_cache`
Update cache settings (schedules) on an existing cache. Replaces both schedules entirely on each call.
### `peaka_delete_cache`
Delete an existing cache. The underlying table is not affected.
Saved queries
-------------
### `peaka_list_queries`
List all saved queries in the project. Returns query names, SQL content, and whether they are plain or materialized.
### `peaka_execute_query`
Execute a saved query by its ID.
### `peaka_create_query`
Create a named, saved query in the project's semantic layer. Returns the created query, including its ID.
### `peaka_update_query`
Update an existing saved query's display name and/or SQL body.
### `peaka_delete_query`
Delete a saved query from the project.
Connections
-----------
### `peaka_list_connections`
List all data source connections in the project — each connection's id, name, type, and (for OAuth-based connections) callback URL.
### `peaka_get_connection_detail`
Get connection-specific configuration detail for a data source connection.
Semantic catalogs
-----------------
### `peaka_create_semantic_catalog`
Create a semantic catalog. A semantic catalog groups semantic tables (saved queries surfaced as queryable tables) under a single namespace.
### `peaka_create_semantic_table`
Create a semantic table inside a semantic catalog, backed by a saved query. Requires `catalogId`, `schemaName`, `tableName`, and `queryId`.
### `peaka_delete_semantic_table`
Delete a semantic table from a semantic catalog. The underlying saved query is not affected.
* * *
The canonical, version-pinned tool list lives in the [`peakacom/peaka-mcp-server` README](https://github.com/peakacom/peaka-mcp-server#readme).
On this page
* [Projects](https://www.peaka.com/docs/mcp/tools/#projects)
* [peaka\_list\_projects](https://www.peaka.com/docs/mcp/tools/#peaka-list-projects)
* [Metadata](https://www.peaka.com/docs/mcp/tools/#metadata)
* [peaka\_get\_project\_metadata](https://www.peaka.com/docs/mcp/tools/#peaka-get-project-metadata)
* [peaka\_list\_catalogs](https://www.peaka.com/docs/mcp/tools/#peaka-list-catalogs)
* [peaka\_list\_schemas](https://www.peaka.com/docs/mcp/tools/#peaka-list-schemas)
* [peaka\_list\_tables](https://www.peaka.com/docs/mcp/tools/#peaka-list-tables)
* [peaka\_list\_columns](https://www.peaka.com/docs/mcp/tools/#peaka-list-columns)
* [peaka\_get\_relations](https://www.peaka.com/docs/mcp/tools/#peaka-get-relations)
* [peaka\_get\_table\_statistics](https://www.peaka.com/docs/mcp/tools/#peaka-get-table-statistics)
* [peaka\_refresh\_project\_metadata](https://www.peaka.com/docs/mcp/tools/#peaka-refresh-project-metadata)
* [peaka\_get\_metadata\_refresh\_status](https://www.peaka.com/docs/mcp/tools/#peaka-get-metadata-refresh-status)
* [Query execution](https://www.peaka.com/docs/mcp/tools/#query-execution)
* [peaka\_execute\_sql\_query](https://www.peaka.com/docs/mcp/tools/#peaka-execute-sql-query)
* [peaka\_query\_golden\_sqls](https://www.peaka.com/docs/mcp/tools/#peaka-query-golden-sqls)
* [Cache](https://www.peaka.com/docs/mcp/tools/#cache)
* [peaka\_create\_cache](https://www.peaka.com/docs/mcp/tools/#peaka-create-cache)
* [peaka\_create\_cache\_batch](https://www.peaka.com/docs/mcp/tools/#peaka-create-cache-batch)
* [peaka\_get\_cache\_statuses](https://www.peaka.com/docs/mcp/tools/#peaka-get-cache-statuses)
* [peaka\_refresh\_cache\_full](https://www.peaka.com/docs/mcp/tools/#peaka-refresh-cache-full)
* [peaka\_refresh\_cache\_incremental](https://www.peaka.com/docs/mcp/tools/#peaka-refresh-cache-incremental)
* [peaka\_update\_cache](https://www.peaka.com/docs/mcp/tools/#peaka-update-cache)
* [peaka\_delete\_cache](https://www.peaka.com/docs/mcp/tools/#peaka-delete-cache)
* [Saved queries](https://www.peaka.com/docs/mcp/tools/#saved-queries)
* [peaka\_list\_queries](https://www.peaka.com/docs/mcp/tools/#peaka-list-queries)
* [peaka\_execute\_query](https://www.peaka.com/docs/mcp/tools/#peaka-execute-query)
* [peaka\_create\_query](https://www.peaka.com/docs/mcp/tools/#peaka-create-query)
* [peaka\_update\_query](https://www.peaka.com/docs/mcp/tools/#peaka-update-query)
* [peaka\_delete\_query](https://www.peaka.com/docs/mcp/tools/#peaka-delete-query)
* [Connections](https://www.peaka.com/docs/mcp/tools/#connections)
* [peaka\_list\_connections](https://www.peaka.com/docs/mcp/tools/#peaka-list-connections)
* [peaka\_get\_connection\_detail](https://www.peaka.com/docs/mcp/tools/#peaka-get-connection-detail)
* [Semantic catalogs](https://www.peaka.com/docs/mcp/tools/#semantic-catalogs)
* [peaka\_create\_semantic\_catalog](https://www.peaka.com/docs/mcp/tools/#peaka-create-semantic-catalog)
* [peaka\_create\_semantic\_table](https://www.peaka.com/docs/mcp/tools/#peaka-create-semantic-table)
* [peaka\_delete\_semantic\_table](https://www.peaka.com/docs/mcp/tools/#peaka-delete-semantic-table)
--- START: docs/mcp/troubleshooting/troubleshooting.md ---
Documentation menu
[Home](/) / [Docs](/docs/) / Troubleshooting
 Copy as Markdown
Troubleshooting
===============
Common errors with the Peaka MCP server and how to fix them.
The server doesn't show up in my client
---------------------------------------
After editing your client's MCP config, you usually need to fully restart the client (not just close the chat window). Check the client's "MCP servers" or "Tools" panel — if `Peaka` doesn't appear, the config wasn't picked up.
If it appears but reports an error on startup, look at the client's MCP logs:
* **Claude Desktop:** `~/Library/Logs/Claude/mcp*.log` (macOS) or `%APPDATA%\Claude\logs\mcp*.log` (Windows)
* **Cursor / Windsurf / VS Code:** the **Output** panel — choose the MCP/extension channel
* **Claude Code:** `claude mcp list` and inspect the named server
OAuth window never opens (remote)
---------------------------------
The remote server returns `401 Unauthorized` with OAuth metadata on the first request, and the client is expected to open a browser. If that doesn't happen:
* Confirm your client supports remote MCP with OAuth.
* Some clients cache failed auth attempts. Remove the server from the client config, restart, and re-add it.
"401 Unauthorized" on every call
--------------------------------
* **Remote:** your token expired or was revoked. Re-trigger OAuth by removing and re-adding the server in your client.
* **NPM / from source:** `PEAKA_API_KEY` is missing, malformed, or revoked. Re-issue the key in Peaka and update the `env` block in your client config.
`peaka_list_projects` returns only one project
----------------------------------------------
Expected when authenticating with a **Project** API key — the key is bound to a single project. To enumerate projects across organizations and workspaces, use a [Partner API key](/docs/cookbook/how-to-manage-partner-api-key) or the [remote server](/docs/mcp/install/remote) with OAuth.
The assistant keeps asking for `projectId`
------------------------------------------
Every project-scoped tool call needs a `projectId`. The remote server is stateless about which project you're working with — the assistant is instructed to ask once per session and reuse the answer. If it asks more often than that, mention the project up front: _"In my `analytics-prod` project, list the tables in the `events` schema."_
Cache or metadata refresh seems stuck
-------------------------------------
Both are async. Check status with:
* [`peaka_get_cache_statuses`](/docs/mcp/tools#peaka-get-cache-statuses) for cache jobs.
* [`peaka_get_metadata_refresh_status`](/docs/mcp/tools#peaka-get-metadata-refresh-status) for catalog metadata refreshes.
Environment variables
---------------------
The local installs read one variable:
Name
Description
`PEAKA_API_KEY`
Project or Partner API key. Required for [NPM](/docs/mcp/install/npm) and [from source](/docs/mcp/install/local) installs. The remote server uses OAuth and does not read this variable.
Still stuck?
------------
* File an issue at [`peakacom/peaka-mcp-server`](https://github.com/peakacom/peaka-mcp-server/issues).
* Ask in the [Peaka Community Discord](https://discord.com/invite/peaka).
* Email [support@peaka.com](mailto:support@peaka.com).
On this page
* [The server doesn't show up in my client](https://www.peaka.com/docs/mcp/troubleshooting/#the-server-doesn-t-show-up-in-my-client)
* [OAuth window never opens (remote)](https://www.peaka.com/docs/mcp/troubleshooting/#oauth-window-never-opens-remote)
* ["401 Unauthorized" on every call](https://www.peaka.com/docs/mcp/troubleshooting/#401-unauthorized-on-every-call)
* [peaka\_list\_projects returns only one project](https://www.peaka.com/docs/mcp/troubleshooting/#peaka-list-projects-returns-only-one-project)
* [The assistant keeps asking for projectId](https://www.peaka.com/docs/mcp/troubleshooting/#the-assistant-keeps-asking-for-projectid)
* [Cache or metadata refresh seems stuck](https://www.peaka.com/docs/mcp/troubleshooting/#cache-or-metadata-refresh-seems-stuck)
* [Environment variables](https://www.peaka.com/docs/mcp/troubleshooting/#environment-variables)
* [Still stuck?](https://www.peaka.com/docs/mcp/troubleshooting/#still-stuck)
--- START: docs/organization-operations/create-organization/create-organization.md ---
Documentation menu
[Home](/) / [Docs](/docs/) / Create Organization
 Copy as Markdown
Create Organization
===================
Learn how to create an organization in Peaka.
This article explains how you can create an organization in Peaka.
1. Log in to your Peaka account.
2. Click on the "**Create Organization**" button.
3. Enter organization name and click on the "**Next**" button.
4. If you want to add members to your organization, enter their email addresses and select their role from the dropdown menu and click on the "**Next**" button. If you don't want to add members, click on the "**Skip for now**" button.
5. Your organization will be created and click on the "**Finish**" button to go to the organization page.
--- START: docs/organization-operations/delete-organization/delete-organization.md ---
Documentation menu
[Home](/) / [Docs](/docs/) / Delete Organization
 Copy as Markdown
Delete Organization
===================
Learn how to delete an organization in Peaka.
This article explains how you can delete an organization in Peaka.
1. Log in to your Peaka account.
2. Click on the three-dots button (ellipsis icon) associated with the organization and click on the "**Settings**" option.
3. Click on the "**Delete Organization**" button.
4. Enter the organization name and click on the "**Delete**" button.
That's it! Your organization will be deleted.
--- START: docs/organization-operations/leave-organization/leave-organization.md ---
Documentation menu
[Home](/) / [Docs](/docs/) / Leave Organization
 Copy as Markdown
Leave Organization
==================
Learn how to leave an organization in Peaka.
This article explains how you can leave an organization in Peaka.
1. Log in to your Peaka account.
2. Click on the three-dots button (ellipsis icon) next to the organization you want to leave and select the **Leave Organization** option. Alternatively, navigate to **Organization Settings** and click the **Leave Organization** button in the top-right corner.
3. A confirmation modal will appear. Follow the steps based on your role in the organization:
* **If you are the owner:** Select a new owner from the **Transfer ownership to** dropdown and click the **Transfer & Leave** button.
* **If you are an admin or member:** Click the **Leave** button to confirm.
You have successfully left the organization.
--- START: docs/organization-operations/manage-organization-groups/manage-organization-groups.md ---
Documentation menu
[Home](/) / [Docs](/docs/) / Manage Organization Groups
 Copy as Markdown
Manage Organization Groups
==========================
Learn how to manage organization groups in Peaka.
This article explains how you can manage organization groups in Peaka.
### Accessing Organization Groups
1. Log in to your Peaka account.
2. Click on the three-dots button (ellipsis icon) associated with the organization and click on the "**Settings**" option.

3. Click on the "**Groups**" tab on the tabs list.
### Creating a new group
1. Click on the "**Create Group**" button on the top right corner of the page or center of the page if you don't have any groups.

2. Enter the group name, description and select the members you want to add to the group. Then click on the "**Create**" button.
That's it. The group will be created.
### Updating group name
1. Click the three-dots button (ellipsis icon) associated with the group and click on the "**Rename**" option.
2. Enter the new group name in inline edit mode and click on the "Enter" key to confirm the change.
That's it. The group name will be updated.
### Delete a group
1. Click the three-dots button (ellipsis icon) associated with the group and click on the "**Delete**" option.

2. Click on the "**Delete**" button on the confirmation modal.
That's it. The group will be deleted.
### Add a member to a group
1. Click on the **Add Member** button on the associated group.
2. Select the member you want to add to the group and click on the "**Add Member**" button.
That's it. The member will be added to the group.
### Remove a member from a group
1. Click the three-dots button (ellipsis icon) associated with the group member and click on the "**Remove Member**" option.
2. Click on the "**Remove Member**" button on the confirmation modal.
That's it. The member will be removed from the group.
On this page
* [Accessing Organization Groups](https://www.peaka.com/docs/organization-operations/manage-organization-groups/#accessing-organization-groups)
* [Creating a new group](https://www.peaka.com/docs/organization-operations/manage-organization-groups/#creating-a-new-group)
* [Updating group name](https://www.peaka.com/docs/organization-operations/manage-organization-groups/#updating-group-name)
* [Delete a group](https://www.peaka.com/docs/organization-operations/manage-organization-groups/#delete-a-group)
* [Add a member to a group](https://www.peaka.com/docs/organization-operations/manage-organization-groups/#add-a-member-to-a-group)
* [Remove a member from a group](https://www.peaka.com/docs/organization-operations/manage-organization-groups/#remove-a-member-from-a-group)
--- START: docs/organization-operations/manage-organization-members/manage-organization-members.md ---
Documentation menu
[Home](/) / [Docs](/docs/) / Manage Organization Members
 Copy as Markdown
Manage Organization Members
===========================
Learn how to manage organization members in Peaka.
This article explains how you can manage organization members in Peaka.
### Accessing Organization Members
1. Log in to your Peaka account.
2. Click on the three-dots button (ellipsis icon) associated with the organization and click on the "**Settings**" option.

3. Click on the "**Organization Members**" tab on the tabs list.
### Inviting a member to the organization
1. Click on the "**Invite Member**" button on the top right corner of the page.
2. Enter the email address of the member you want to add and select their adding type (Workspace / Group), select roles and add message if you want to. Then click on the "**Invite**" button.
That's it. After accepting the invitation, the member will be added to the organization.
### Cancelling an invitation
1. After inviting a member, you can cancel the invitation. Click on the "**Pending Invitations**" tab to see the pending invitations.
2. Click on the three-dots button (ellipsis icon) associated with the invitation and click on the "**Cancel**" option.
3. Click on the "**Cancel**" button on the confirmation modal.
That's it. The invitation will be cancelled.
### Updating a member's role
1. Click on the member's role to open the role selection dropdown and select the new role.
That's it. The member's role will be updated.
### Updating a member's Group
Note: If the member is added to a group, you can update the group of the member.
1. Click on the member's group to open the group selection dropdown and select the new group.
That's it. The member's group will be updated.
### Removing a member from the organization
1. Click on the three-dots button (ellipsis icon) associated with the member and click on the "**Remove**" option.
2. Click on the "**Remove**" button on the confirmation modal.
That's it. The member will be removed from the organization.
On this page
* [Accessing Organization Members](https://www.peaka.com/docs/organization-operations/manage-organization-members/#accessing-organization-members)
* [Inviting a member to the organization](https://www.peaka.com/docs/organization-operations/manage-organization-members/#inviting-a-member-to-the-organization)
* [Cancelling an invitation](https://www.peaka.com/docs/organization-operations/manage-organization-members/#cancelling-an-invitation)
* [Updating a member's role](https://www.peaka.com/docs/organization-operations/manage-organization-members/#updating-a-member-s-role)
* [Updating a member's Group](https://www.peaka.com/docs/organization-operations/manage-organization-members/#updating-a-member-s-group)
* [Removing a member from the organization](https://www.peaka.com/docs/organization-operations/manage-organization-members/#removing-a-member-from-the-organization)
--- START: docs/organization-operations/update-organization/update-organization.md ---
Documentation menu
[Home](/) / [Docs](/docs/) / Update Organization
 Copy as Markdown
Update Organization
===================
Learn how to update an organization in Peaka.
This article explains how you can update an organization in Peaka.
1. Log in to your Peaka account.
2. Click on the three-dots button (ellipsis icon) associated with the organization and click on the "**Settings**" option.

3. Update the organization image, name and description and click on the "**Save**" button.

That's it! Your organization will be updated.
--- START: docs/project-operations/clone-a-project/clone-a-project.md ---
Documentation menu
[Home](/) / [Docs](/docs/) / How to clone a project in Peaka
 Copy as Markdown
How to clone a project in Peaka
===============================
Get started with Project Operations: Learn how you can clone an existing project in Peaka.
Follow these simple steps to clone an existing project in Peaka:
1. Click on the three-dots button (ellipsis icon) associated with the project and click on the "Clone" button.
2. Enter the project name and click on the "Clone" button.
That's it. The project will be cloned. You can see the cloned project page on the list of projects.
--- START: docs/project-operations/delete-a-project/delete-a-project.md ---
Documentation menu
[Home](/) / [Docs](/docs/) / How to delete a project in Peaka
 Copy as Markdown
How to delete a project in Peaka
================================
Get started with Project Operations: Learn how you can delete a project in Peaka.
Follow these steps to delete a project in Peaka:
1. Click on the three-dots button (ellipsis icon) associated with the project and click on the "Delete" button.

2. Click on the "Delete" button on the confirmation modal.
That's it. The project will be deleted. You can see the project page on the list of projects.
--- START: docs/project-operations/how-to-create-a-project/how-to-create-a-project.md ---
Documentation menu
[Home](/) / [Docs](/docs/) / How to create a project
 Copy as Markdown
How to create a project
=======================
Get started with Project Operations: Learn how you can start a new project in Peaka.
Follow these steps to create a project in Peaka:
1. Click on the "New Project" button.

2. Select workspace, enter the project name, description and click on the "Create Project" button.

That's it. The project will be created. You can see the project page on the list of projects.

--- START: docs/project-operations/manage-members/manage-members.md ---
Documentation menu
[Home](/) / [Docs](/docs/) / Manage Members
 Copy as Markdown
Manage Members
==============
Learn how to manage project members in Peaka.
This article explains how you can manage project members in Peaka.
### Opening manage members modal
1. Click on the three-dots button (ellipsis icon) associated with the project and click on the "**Manage Project Members**" button.

That's it. You can see the manage members modal.
### Add new member to the project
1. Click on the "Add Member" button on the top right corner of the modal.
2. Select the member or group from the dropdown menu and click on the "Add" button.
That's it. The member will be added to the project. You can see the member on the list of members.
### Updating member's or group's role
1. Click on the role of the member or group to open the role selection dropdown and select the new role.
2. Select the new role from the dropdown.
That's it. The member's role will be updated.
### Remove member or group from the project
1. Click on the three-dots button (ellipsis icon) associated with the member or group and click on the "Remove" option.
2. Click on the "Remove" button from the dropdown menu.

That's it. The member or group will be removed from the project.
On this page
* [Opening manage members modal](https://www.peaka.com/docs/project-operations/manage-members/#opening-manage-members-modal)
* [Add new member to the project](https://www.peaka.com/docs/project-operations/manage-members/#add-new-member-to-the-project)
* [Updating member's or group's role](https://www.peaka.com/docs/project-operations/manage-members/#updating-member-s-or-group-s-role)
* [Remove member or group from the project](https://www.peaka.com/docs/project-operations/manage-members/#remove-member-or-group-from-the-project)
--- START: docs/project-operations/rename-a-project/rename-a-project.md ---
Documentation menu
[Home](/) / [Docs](/docs/) / How to rename a project in Peaka
 Copy as Markdown
How to rename a project in Peaka
================================
Get started with Project Operations: Learn how you can change the name of your Peaka project.
Follow these steps to rename a project in Peaka:
1. Click on the three-dots button (ellipsis icon) associated with the project and click on the "Rename" button.

2. Enter the new project name and click on the "Change" button.
That's it. The project name will be updated. You can see the project page on the list of projects.
--- START: docs/sql/introduction/introduction.md ---
Documentation menu
[Home](/) / [Docs](/docs/) / Introduction
 Copy as Markdown
Introduction
============
Introduction to how to use SQL with Peaka.
Welcome
-------
Peaka uses Trino's ANSI SQL compliant query engine. This standard compliance allows Peaka users to integrate their favorite data tools, including BI and ETL tools with any underlying data source.
Our query engine validates and translates the received SQL statements into the necessary operations on the connected data source.
This section provides a reference to the supported SQL data types and other general characteristics of the SQL support of Peaka.
On this page
* [Welcome](https://www.peaka.com/docs/sql/introduction/#welcome)
--- START: docs/mcp/install/local/local.md ---
Documentation menu
[Home](/) / [Docs](/docs/) / From source
 Copy as Markdown
From source
===========
Build and run the Peaka MCP server from a local clone of the GitHub repository.
For contributors and users who need to run a modified or pinned build, the server can be cloned from GitHub and run from source.
For most users, [Remote](/docs/mcp/install/remote) or [NPM](/docs/mcp/install/npm) is simpler.
Prerequisites
-------------
* Node.js 18 or newer.
* A Peaka API key — see [Authentication](/docs/mcp/authentication).
Clone and build
---------------
git clone https://github.com/peakacom/peaka-mcp-server.git
cd peaka-mcp-server
npm install
npm run build
The build emits `dist/index.js`, which is the binary your client will launch.
Configure your client
---------------------
Point your client at the local build and pass the API key as an environment variable:
{
"mcpServers": {
"peaka": {
"command": "node",
"args": ["/absolute/path/to/peaka-mcp-server/dist/index.js"],
"env": {
"PEAKA_API_KEY": ""
}
}
}
}
Use an absolute path. Restart the client after editing its config.
Environment variables
---------------------
Name
Description
`PEAKA_API_KEY`
Project or Partner API key for authenticating with Peaka. **Required.**
Updating
--------
Pull the latest changes and rebuild:
git pull
npm install
npm run build
Your client will pick up the new binary on its next launch of the server.
Contributing
------------
Issues and pull requests are welcome on [`peakacom/peaka-mcp-server`](https://github.com/peakacom/peaka-mcp-server).
On this page
* [Prerequisites](https://www.peaka.com/docs/mcp/install/local/#prerequisites)
* [Clone and build](https://www.peaka.com/docs/mcp/install/local/#clone-and-build)
* [Configure your client](https://www.peaka.com/docs/mcp/install/local/#configure-your-client)
* [Environment variables](https://www.peaka.com/docs/mcp/install/local/#environment-variables)
* [Updating](https://www.peaka.com/docs/mcp/install/local/#updating)
* [Contributing](https://www.peaka.com/docs/mcp/install/local/#contributing)
--- START: docs/mcp/install/npm/npm.md ---
Documentation menu
[Home](/) / [Docs](/docs/) / NPM
 Copy as Markdown
NPM
===
Run the Peaka MCP server locally via npx, authenticated with a Peaka API key.
The published [`@peaka/mcp-server-peaka`](https://www.npmjs.com/package/@peaka/mcp-server-peaka) package runs the server over stdio. Your MCP client launches it on demand with `npx`, and authentication is a single environment variable.
This is the right choice when you want:
* A locally-running server, no remote dependency.
* API-key auth (for CI, headless scripts, or pinning to a specific Peaka identity).
* Faster cold-starts than a remote round-trip.
For the zero-install path, see [Remote](/docs/mcp/install/remote).
Configure your client
---------------------
Add the server to your MCP client config:
{
"mcpServers": {
"peaka": {
"command": "npx",
"args": ["-y", "@peaka/mcp-server-peaka@latest"],
"env": {
"PEAKA_API_KEY": ""
}
}
}
}
Replace `` with a Peaka API key. Restart the client after editing the config.
[Supported clients](/docs/mcp/clients) shows where each client's config file lives.
Get an API key
--------------
You can use either a **Project** or **Partner** API key:
* **Project API key** — bound to a single Peaka project. Simplest. Good for everyday use against one project. See [How to generate API keys](/docs/cookbook/how-to-generate-api-keys).
* **Partner API key** — enumerates projects across organizations and workspaces. Use this if you want the assistant to discover and switch between projects. See [How to manage Partner API keys](/docs/cookbook/how-to-manage-partner-api-key).
Full breakdown in [Authentication](/docs/mcp/authentication).
Environment variables
---------------------
Name
Description
`PEAKA_API_KEY`
Project or Partner API key for authenticating with Peaka. **Required.**
Verify it's working
-------------------
After your client restarts:
1. Confirm the `peaka` server shows up in your client's MCP server list.
2. Ask your assistant: _"List my Peaka projects."_
3. The first response should call [`peaka_list_projects`](/docs/mcp/tools#peaka-list-projects) and return the projects your key can see.
If nothing happens, see [Troubleshooting](/docs/mcp/troubleshooting).
Updating
--------
Because the config uses `@latest`, every cold start picks up the newest server release. To pin a version:
"args": ["-y", "@peaka/mcp-server-peaka@0.7.0"]
Releases live on [npm](https://www.npmjs.com/package/@peaka/mcp-server-peaka) and [GitHub](https://github.com/peakacom/peaka-mcp-server).
On this page
* [Configure your client](https://www.peaka.com/docs/mcp/install/npm/#configure-your-client)
* [Get an API key](https://www.peaka.com/docs/mcp/install/npm/#get-an-api-key)
* [Environment variables](https://www.peaka.com/docs/mcp/install/npm/#environment-variables)
* [Verify it's working](https://www.peaka.com/docs/mcp/install/npm/#verify-it-s-working)
* [Updating](https://www.peaka.com/docs/mcp/install/npm/#updating)
--- START: docs/mcp/install/remote/remote.md ---
Documentation menu
[Home](/) / [Docs](/docs/) / Remote
 Copy as Markdown
Remote
======
Connect to the hosted Peaka MCP server over streamable HTTP, authenticated with OAuth.
Peaka hosts a remote MCP server at:
https://mcp.peaka.studio/mcp
It speaks the [streamable HTTP transport](https://modelcontextprotocol.io/specification/draft/basic/transports#streamable-http) and uses OAuth for authentication. There is nothing to install — point any MCP client that supports remote servers at the URL.
When to use this
----------------
* You want zero install. Just paste a URL.
* You want the assistant to act under **your** Peaka identity, scoped to what you're authorized to do.
* You don't want to copy an API key around.
If you instead need a key-authenticated, locally-running server (e.g. for CI, scripts, or air-gapped setups), see [NPM](/docs/mcp/install/npm) or [From source](/docs/mcp/install/local).
Add it to your client
---------------------
{
"mcpServers": {
"peaka": {
"url": "https://mcp.peaka.studio/mcp"
}
}
}
[Supported clients](/docs/mcp/clients) lists which form each client expects and links to its "add an MCP server" instructions.
OAuth flow
----------
The first time your client opens a session your client opens a browser window to Peaka, where you sign in to Peaka and approve access.
1
Client connects
Your AI assistant opens an MCP session against `https://mcp.peaka.studio/mcp`.
2
You approve in the browser
The client opens Peaka in your browser. Sign in to Peaka and approve the consent screen.

3
Connected
The assistant will confirm the connection.

4
The connection is available
You can view the connector from your assistant's tools.
The assistant can now act on your behalf.
Working with projects
---------------------
The remote server is stateless with respect to project selection. Each tool call carries its own `projectId`.
To keep the conversation natural, the assistant is instructed to:
* **Ask once per session** which project you want to work with, then reuse it.
* **Skip the question** if you mention a specific project up front (e.g. _"In my `analytics-prod` project, list the catalogs"_).
If you want to switch mid-session, just say so: _"Switch to my `staging` project."_
Use [`peaka_list_projects`](/docs/mcp/tools#peaka-list-projects) to discover the projects you have access to. The assistant will typically call this for you.
Limits and behavior
-------------------
* **Permissions follow the user.** Each call is authorized as the OAuth-signed-in user. If the user can't do something in Peaka, the server can't do it either.
* **Rate limits.** Standard Peaka API limits apply.
* **Long-running operations.** Cache refreshes and metadata refreshes are async and report progress via the relevant `_status` tools.
Troubleshooting
---------------
If the OAuth window never opens, or your client gets stuck on `401`, see [Troubleshooting](/docs/mcp/troubleshooting).
On this page
* [When to use this](https://www.peaka.com/docs/mcp/install/remote/#when-to-use-this)
* [Add it to your client](https://www.peaka.com/docs/mcp/install/remote/#add-it-to-your-client)
* [OAuth flow](https://www.peaka.com/docs/mcp/install/remote/#oauth-flow)
* [Working with projects](https://www.peaka.com/docs/mcp/install/remote/#working-with-projects)
* [Limits and behavior](https://www.peaka.com/docs/mcp/install/remote/#limits-and-behavior)
* [Troubleshooting](https://www.peaka.com/docs/mcp/install/remote/#troubleshooting)
--- START: docs/sql/functions/aggregate/aggregate.md ---
Documentation menu
[Home](/) / [Docs](/docs/) / Aggregate functions
 Copy as Markdown
Aggregate functions
===================
Aggregate functions operate on a set of values to compute a single result.
Except for `count`, `count_if`, `max_by`, `min_by` and `approx_distinct`, all of these aggregate functions ignore null values and return null for no input rows or when all values are null. For example, `sum` returns null rather than zero and `avg` does not include null values in the count. The `coalesce` function can be used to convert null into zero.
Ordering during aggregation
---------------------------
Some aggregate functions such as `array_agg` produce different results depending on the order of input values. This ordering can be specified by writing an order by clause within the aggregate function:
array_agg(x ORDER BY y DESC)
array_agg(x ORDER BY x, y, z)
Filtering during aggregation
----------------------------
The `FILTER` keyword can be used to remove rows from aggregation processing with a condition expressed using a `WHERE` clause. This is evaluated for each row before it is used in the aggregation and is supported for all aggregate functions.
aggregate_function(...) FILTER (WHERE )
A common and very useful example is to use `FILTER` to remove nulls from consideration when using `array_agg`
SELECT array_agg(name) FILTER (WHERE name IS NOT NULL)
FROM region;
As another example, imagine you want to add a condition on the count for Iris flowers, modifying the following query:
SELECT species,
count(*) AS count
FROM iris
GROUP BY species;
species | count
-----------+-------
setosa | 50
virginica | 50
versicolor | 50
If you just use a normal `WHERE` statement you lose information:
SELECT species,
count(*) AS count
FROM iris
WHERE petal_length_cm > 4
GROUP BY species;
species | count
-----------+-------
virginica | 50
versicolor | 34
Using a filter you retain all information:
SELECT species,
count(*) FILTER (where petal_length_cm > 4) AS count
FROM iris
GROUP BY species;
species | count
-----------+-------
virginica | 50
setosa | 0
versicolor | 34
General aggregate functions
---------------------------
### any\_value
any_value(x) -> [same as input]
Returns an arbitrary non-null value `x`, if one exists. `x` can be any valid expression. This allows you to return values from columns that are not directly part of the aggregation, inluding expressions using these columns, in a query.
For example, the following query returns the customer name from the `name` column, and returns the sum of all total prices as customer spend. The aggregation however uses the rows grouped by the customer identifier `custkey` a required, since only that column is guaranteed to be unique:
SELECT sum(o.totalprice) as spend,
any_value(c.name)
FROM tpch.tiny.orders o
JOIN tpch.tiny.customer c
ON o.custkey = c.custkey
GROUP BY c.custkey;
ORDER BY spend;
### arbitrary
arbitrary(x) -> [same as input]
Returns an arbitrary non-null value of `x`, if one exists. Identical to [any\_value](https://www.peaka.com/docs/sql/functions/aggregate/#any-value).
### array\_agg
array_agg(x) -> array<[same as input]>
Returns an array created from the input `x` elements.
### avg
avg(x) -> double
Returns the average (arithmetic mean) of all input values.
avg(time interval type) -> time interval type
Returns the average interval length of all input values.
### bool\_and
bool_and(boolean) -> boolean
Returns `TRUE` if every input value is `TRUE`, otherwise `FALSE`.
### bool\_or
bool_or(boolean) -> boolean
Returns `TRUE` if any input value is `TRUE`, otherwise `FALSE`.
### checksum
checksum(x) -> varbinary
Returns an order-insensitive checksum of the given values.
### count
count(*) -> bigint
Returns the number of input rows.
count(x) -> bigint
Returns the number of non-null input values.
### count\_if
count_if(x) -> bigint
Returns the number of `TRUE` input values. This function is equivalent to `count(CASE WHEN x THEN 1 END)`.
### every
every(boolean) -> boolean
This is an alias for `bool_and`.
### geometric\_mean
geometric_mean(x) -> double
Returns the geometric mean of all input values.
### listagg
listagg(x, separator) -> varchar
Returns the concatenated input values, separated by the `separator` string.
Synopsis:
LISTAGG( expression [, separator] [ON OVERFLOW overflow_behaviour])
WITHIN GROUP (ORDER BY sort_item, [...]) [FILTER (WHERE condition)]
If `separator` is not specified, the empty string will be used as `separator`.
In its simplest form the function looks like:
SELECT listagg(value, ',') WITHIN GROUP (ORDER BY value) csv_value
FROM (VALUES 'a', 'c', 'b') t(value);
and results in:
csv_value
-----------
'a,b,c'
The overflow behaviour is by default to throw an error in case that the length of the output of the function exceeds `1048576` bytes:
SELECT listagg(value, ',' ON OVERFLOW ERROR) WITHIN GROUP (ORDER BY value) csv_value
FROM (VALUES 'a', 'b', 'c') t(value);
There exists also the possibility to truncate the output `WITH COUNT` or `WITHOUT COUNT` of omitted non-null values in case that the length of the output of the function exceeds `1048576` bytes:
SELECT listagg(value, ',' ON OVERFLOW TRUNCATE '.....' WITH COUNT) WITHIN GROUP (ORDER BY value)
FROM (VALUES 'a', 'b', 'c') t(value);
If not specified, the truncation filler string is by default `'...'`.
This aggregation function can be also used in a scenario involving grouping:
SELECT id, listagg(value, ',') WITHIN GROUP (ORDER BY o) csv_value
FROM (VALUES
(100, 1, 'a'),
(200, 3, 'c'),
(200, 2, 'b')
) t(id, o, value)
GROUP BY id
ORDER BY id;
results in:
id | csv_value
-----+-----------
100 | a
200 | b,c
This aggregation function supports [filtering during aggregation](https://www.peaka.com/docs/sql/functions/aggregate/#filtering-during-aggregation) for scenarios where the aggregation for the data not matching the filter condition still needs to show up in the output:
SELECT
country,
listagg(city, ',')
WITHIN GROUP (ORDER BY population DESC)
FILTER (WHERE population >= 10_000_000) megacities
FROM (VALUES
('India', 'Bangalore', 13_700_000),
('India', 'Chennai', 12_200_000),
('India', 'Ranchi', 1_547_000),
('Austria', 'Vienna', 1_897_000),
('Poland', 'Warsaw', 1_765_000)
) t(country, city, population)
GROUP BY country
ORDER BY country;
results in:
country | megacities
---------+-------------------
Austria | NULL
India | Bangalore,Chennai
Poland | NULL
The current implementation of `listagg` function does not support window frames.
### max
max(x) -> [same as input]
Returns the maximum value of all input values.
max(x, n) -> array<[same as x]>
Returns `n` largest values of all input values of `x`.
### max\_by
max_by(x, y) -> [same as x]
Returns the value of `x` associated with the maximum value of `y` over all input values.
max_by(x, y, n) -> array<[same as x]>
Returns `n` values of `x` associated with the `n` largest of all input values of `y` in descending order of `y`.
### min
min(x) -> [same as input]
Returns the minimum value of all input values.
min(x, n) -> array<[same as x]>
Returns `n` smallest values of all input values of `x`.
### min\_by
min_by(x, y) -> [same as x]
Returns the value of `x` associated with the minimum value of `y` over all input values.
min_by(x, y, n) -> array<[same as x]>
Returns `n` values of `x` associated with the `n` smallest of all input values of `y` in ascending order of `y`.
### sum
sum(x) -> [same as input]
Returns the sum of all input values.
Bitwise aggregate functions
---------------------------
### bitwise\_and\_agg
bitwise_and_agg(x) -> bigint
Returns the bitwise AND of all input values in 2's complement representation.
### bitwise\_or\_agg
bitwise_or_agg(x) -> bigint
Returns the bitwise OR of all input values in 2's complement representation.
Map aggregate functions
-----------------------
### histogram
histogram(x) -> map
Returns a map containing the count of the number of times each input value occurs.
### map\_agg
map_agg(key, value) -> map
Returns a map created from the input `key` / `value` pairs.
### map\_union
map_union(x(K,V)) -> map
Returns the union of all the input maps. If a key is found in multiple input maps, that key's value in the resulting map comes from an arbitrary input map.
For example, take the following histogram function that creates multiple maps from the Iris dataset:
SELECT histogram(floor(petal_length_cm)) petal_data
FROM memory.default.iris
GROUP BY species;
petal_data
-- {4.0=6, 5.0=33, 6.0=11}
-- {4.0=37, 5.0=2, 3.0=11}
-- {1.0=50}
You can combine these maps using `map_union`:
SELECT map_union(petal_data) petal_data_union
FROM (
SELECT histogram(floor(petal_length_cm)) petal_data
FROM memory.default.iris
GROUP BY species
);
petal_data_union
--{4.0=6, 5.0=2, 6.0=11, 1.0=50, 3.0=11}
### multimap\_agg
multimap_agg(key, value) -> map
Returns a multimap created from the input `key` / `value` pairs. Each key can be associated with multiple values.
Approximate aggregate functions
-------------------------------
### approx\_distinct
approx_distinct(x) -> bigint
Returns the approximate number of distinct input values. This function provides an approximation of `count(DISTINCT x)`. Zero is returned if all input values are null.
This function should produce a standard error of 2.3%, which is the standard deviation of the (approximately normal) error distribution over all possible sets. It does not guarantee an upper bound on the error for any specific input set.
approx_distinct(x, e) -> bigint
Returns the approximate number of distinct input values. This function provides an approximation of `count(DISTINCT x)`. Zero is returned if all input values are null.
This function should produce a standard error of no more than `e`, which is the standard deviation of the (approximately normal) error distribution over all possible sets. It does not guarantee an upper bound on the error for any specific input set. The current implementation of this function requires that `e` be in the range of `[0.0040625, 0.26000]`.
### approx\_most\_frequent
approx_most_frequent(buckets, value, capacity) -> map<[same as value], bigint>
Computes the top frequent values up to `buckets` elements approximately. Approximate estimation of the function enables us to pick up the frequent values with less memory. Larger `capacity` improves the accuracy of underlying algorithm with sacrificing the memory capacity. The returned value is a map containing the top elements with corresponding estimated frequency.
The error of the function depends on the permutation of the values and its cardinality. We can set the capacity same as the cardinality of the underlying data to achieve the least error.
`buckets` and `capacity` must be `bigint`. `value` can be numeric or string type.
The function uses the stream summary data structure proposed in the paper [Efficient Computation of Frequent and Top-k Elements in Data Streams](https://www.cse.ust.hk/~raywong/comp5331/References/EfficientComputationOfFrequentAndTop-kElementsInDataStreams.pdf) by A. Metwalley, D. Agrawl and A. Abbadi.
### approx\_percentile
approx_percentile(x, percentage) -> [same as x]
Returns the approximate percentile for all input values of `x` at the given `percentage`. The value of `percentage` must be between zero and one and must be constant for all input rows.
approx_percentile(x, percentages) -> array<[same as x]>
Returns the approximate percentile for all input values of `x` at each of the specified percentages. Each element of the `percentages` array must be between zero and one, and the array must be constant for all input rows.
approx_percentile(x, w, percentage) -> [same as x]
Returns the approximate weighed percentile for all input values of `x` using the per-item weight `w` at the percentage `percentage`. Weights must be greater or equal to 1. Integer-value weights can be thought of as a replication count for the value `x` in the percentile set. The value of `percentage` must be between zero and one and must be constant for all input rows.
approx_percentile(x, w, percentages) -> array<[same as x]>
Returns the approximate weighed percentile for all input values of `x` using the per-item weight `w` at each of the given percentages specified in the array. Weights must be greater or equal to 1. Integer-value weights can be thought of as a replication count for the value `x` in the percentile set. Each element of the `percentages` array must be between zero and one, and the array must be constant for all input rows.
### approx\_set
approx_set(x) -> HyperLogLog
See [HyperLogLog Functions](/docs/sql/functions/hyperloglog).
### merge
merge(x) -> HyperLogLog
See [HyperLogLog Functions](/docs/sql/functions/hyperloglog).
merge(qdigest(T)) -> qdigest(T)
See [Quantile digest functions](/docs/sql/functions/qdigest).
merge(tdigest) -> tdigest
### numeric\_histogram
numeric_histogram(buckets, value) -> map
Computes an approximate histogram with up to `buckets` number of buckets for all `value`s. This function is equivalent to the variant of `numeric_histogram` that takes a `weight`, with a per-item weight of `1`.
numeric_histogram(buckets, value, weight) -> map
Computes an approximate histogram with up to `buckets` number of buckets for all `value`s with a per-item weight of `weight`. The algorithm is based loosely on:
Yael Ben-Haim and Elad Tom-Tov, "A streaming parallel decision tree algorithm",
J. Machine Learning Research 11 (2010), pp. 849--872.
`buckets` must be a `bigint`. `value` and `weight` must be numeric.
### qdigest\_agg
qdigest_agg(x) -> qdigest([same as x])
qdigest_agg(x, w) -> qdigest([same as x])
qdigest_agg(x, w, accuracy) -> qdigest([same as x])
### tdigest\_agg
tdigest_agg(x) -> tdigest
tdigest_agg(x, w) -> tdigest
Statistical aggregate functions
-------------------------------
### corr
corr(y, x) -> double
Returns correlation coefficient of input values.
### covar\_pop
covar_pop(y, x) -> double
Returns the population covariance of input values.
### covar\_samp
covar_samp(y, x) -> double
Returns the sample covariance of input values.
### kurtosis
kurtosis(x) -> double
Returns the excess kurtosis of all input values. Unbiased estimate using the following expression:
kurtosis(x) = n(n+1)/((n-1)(n-2)(n-3))sum[(x_i-mean)^4]/stddev(x)^4-3(n-1)^2/((n-2)(n-3))
### regr\_intercept
regr_intercept(y, x) -> double
Returns linear regression intercept of input values. `y` is the dependent value. `x` is the independent value.
### regr\_slope
regr_slope(y, x) -> double
Returns linear regression slope of input values. `y` is the dependent value. `x` is the independent value.
### skewness
skewness(x) -> double
Returns the Fisher's moment coefficient of [skewness](https://wikipedia.org/wiki/Skewness) of all input values.
### stddev
stddev(x) -> double
This is an alias for `stddev_samp`.
### stddev\_pop
stddev_pop(x) -> double
Returns the population standard deviation of all input values.
### stddev\_samp
stddev_samp(x) -> double
Returns the sample standard deviation of all input values.
### variance
variance(x) -> double
This is an alias for `var_samp`.
### var\_pop
var_pop(x) -> double
Returns the population variance of all input values.
### var\_samp
var_samp(x) -> double
Returns the sample variance of all input values.
Lambda aggregate functions
--------------------------
### reduce\_agg
reduce_agg(inputValue T, initialState S, inputFunction(S, T, S), combineFunction(S, S, S)) -> S
Reduces all input values into a single value. `inputFunction` will be invoked for each non-null input value. In addition to taking the input value, `inputFunction` takes the current state, initially `initialState`, and returns the new state. `combineFunction` will be invoked to combine two states into a new state. The final state is returned:
SELECT id, reduce_agg(value, 0, (a, b) -> a + b, (a, b) -> a + b)
FROM (
VALUES
(1, 3),
(1, 4),
(1, 5),
(2, 6),
(2, 7)
) AS t(id, value)
GROUP BY id;
-- (1, 12)
-- (2, 13)
SELECT id, reduce_agg(value, 1, (a, b) -> a * b, (a, b) -> a * b)
FROM (
VALUES
(1, 3),
(1, 4),
(1, 5),
(2, 6),
(2, 7)
) AS t(id, value)
GROUP BY id;
-- (1, 60)
-- (2, 42)
The state type must be a boolean, integer, floating-point, char, varchar or date/time/interval.
On this page
* [Ordering during aggregation](https://www.peaka.com/docs/sql/functions/aggregate/#ordering-during-aggregation)
* [Filtering during aggregation](https://www.peaka.com/docs/sql/functions/aggregate/#filtering-during-aggregation)
* [General aggregate functions](https://www.peaka.com/docs/sql/functions/aggregate/#general-aggregate-functions)
* [any\_value](https://www.peaka.com/docs/sql/functions/aggregate/#any-value)
* [arbitrary](https://www.peaka.com/docs/sql/functions/aggregate/#arbitrary)
* [array\_agg](https://www.peaka.com/docs/sql/functions/aggregate/#array-agg)
* [avg](https://www.peaka.com/docs/sql/functions/aggregate/#avg)
* [bool\_and](https://www.peaka.com/docs/sql/functions/aggregate/#bool-and)
* [bool\_or](https://www.peaka.com/docs/sql/functions/aggregate/#bool-or)
* [checksum](https://www.peaka.com/docs/sql/functions/aggregate/#checksum)
* [count](https://www.peaka.com/docs/sql/functions/aggregate/#count)
* [count\_if](https://www.peaka.com/docs/sql/functions/aggregate/#count-if)
* [every](https://www.peaka.com/docs/sql/functions/aggregate/#every)
* [geometric\_mean](https://www.peaka.com/docs/sql/functions/aggregate/#geometric-mean)
* [listagg](https://www.peaka.com/docs/sql/functions/aggregate/#listagg)
* [max](https://www.peaka.com/docs/sql/functions/aggregate/#max)
* [max\_by](https://www.peaka.com/docs/sql/functions/aggregate/#max-by)
* [min](https://www.peaka.com/docs/sql/functions/aggregate/#min)
* [min\_by](https://www.peaka.com/docs/sql/functions/aggregate/#min-by)
* [sum](https://www.peaka.com/docs/sql/functions/aggregate/#sum)
* [Bitwise aggregate functions](https://www.peaka.com/docs/sql/functions/aggregate/#bitwise-aggregate-functions)
* [bitwise\_and\_agg](https://www.peaka.com/docs/sql/functions/aggregate/#bitwise-and-agg)
* [bitwise\_or\_agg](https://www.peaka.com/docs/sql/functions/aggregate/#bitwise-or-agg)
* [Map aggregate functions](https://www.peaka.com/docs/sql/functions/aggregate/#map-aggregate-functions)
* [histogram](https://www.peaka.com/docs/sql/functions/aggregate/#histogram)
* [map\_agg](https://www.peaka.com/docs/sql/functions/aggregate/#map-agg)
* [map\_union](https://www.peaka.com/docs/sql/functions/aggregate/#map-union)
* [multimap\_agg](https://www.peaka.com/docs/sql/functions/aggregate/#multimap-agg)
* [Approximate aggregate functions](https://www.peaka.com/docs/sql/functions/aggregate/#approximate-aggregate-functions)
* [approx\_distinct](https://www.peaka.com/docs/sql/functions/aggregate/#approx-distinct)
* [approx\_most\_frequent](https://www.peaka.com/docs/sql/functions/aggregate/#approx-most-frequent)
* [approx\_percentile](https://www.peaka.com/docs/sql/functions/aggregate/#approx-percentile)
* [approx\_set](https://www.peaka.com/docs/sql/functions/aggregate/#approx-set)
* [merge](https://www.peaka.com/docs/sql/functions/aggregate/#merge)
* [numeric\_histogram](https://www.peaka.com/docs/sql/functions/aggregate/#numeric-histogram)
* [qdigest\_agg](https://www.peaka.com/docs/sql/functions/aggregate/#qdigest-agg)
* [tdigest\_agg](https://www.peaka.com/docs/sql/functions/aggregate/#tdigest-agg)
* [Statistical aggregate functions](https://www.peaka.com/docs/sql/functions/aggregate/#statistical-aggregate-functions)
* [corr](https://www.peaka.com/docs/sql/functions/aggregate/#corr)
* [covar\_pop](https://www.peaka.com/docs/sql/functions/aggregate/#covar-pop)
* [covar\_samp](https://www.peaka.com/docs/sql/functions/aggregate/#covar-samp)
* [kurtosis](https://www.peaka.com/docs/sql/functions/aggregate/#kurtosis)
* [regr\_intercept](https://www.peaka.com/docs/sql/functions/aggregate/#regr-intercept)
* [regr\_slope](https://www.peaka.com/docs/sql/functions/aggregate/#regr-slope)
* [skewness](https://www.peaka.com/docs/sql/functions/aggregate/#skewness)
* [stddev](https://www.peaka.com/docs/sql/functions/aggregate/#stddev)
* [stddev\_pop](https://www.peaka.com/docs/sql/functions/aggregate/#stddev-pop)
* [stddev\_samp](https://www.peaka.com/docs/sql/functions/aggregate/#stddev-samp)
* [variance](https://www.peaka.com/docs/sql/functions/aggregate/#variance)
* [var\_pop](https://www.peaka.com/docs/sql/functions/aggregate/#var-pop)
* [var\_samp](https://www.peaka.com/docs/sql/functions/aggregate/#var-samp)
* [Lambda aggregate functions](https://www.peaka.com/docs/sql/functions/aggregate/#lambda-aggregate-functions)
* [reduce\_agg](https://www.peaka.com/docs/sql/functions/aggregate/#reduce-agg)
--- START: docs/sql/functions/array/array.md ---
Documentation menu
[Home](/) / [Docs](/docs/) / Array functions and operators
 Copy as Markdown
Array functions and operators
=============================
Subscript operator: \[\]
------------------------
The `[]` operator is used to access an element of an array and is indexed starting from one:
SELECT my_array[1] AS first_element
Concatenation operator: ||
--------------------------
The `||` operator is used to concatenate an array with an array or an element of the same type:
SELECT ARRAY[1] || ARRAY[2];
-- [1, 2]
SELECT ARRAY[1] || 2;
-- [1, 2]
SELECT 2 || ARRAY[1];
-- [2, 1]
Array functions
---------------
### all\_match
all_match(array(T), function(T,boolean)) -> boolean
Returns whether all elements of an array match the given predicate. Returns `true` if all the elements match the predicate (a special case is when the array is empty); `false` if one or more elements don't match; `NULL` if the predicate function returns `NULL` for one or more elements and `true` for all other elements.
### any\_match
any_match(array(T), function(T,boolean)) -> boolean
Returns whether any elements of an array match the given predicate. Returns `true` if one or more elements match the predicate; `false` if none of the elements matches (a special case is when the array is empty); `NULL` if the predicate function returns `NULL` for one or more elements and `false` for all other elements.
### array\_distinct
array_distinct(x) -> array
Remove duplicate values from the array `x`.
### array\_intersect
array_intersect(x, y) -> array
Returns an array of the elements in the intersection of `x` and `y`, without duplicates.
### array\_union
array_union(x, y) -> array
Returns an array of the elements in the union of `x` and `y`, without duplicates.
### array\_except
array_except(x, y) -> array
Returns an array of elements in `x` but not in `y`, without duplicates.
### array\_histogram
array_histogram(x) -> map
Returns a map where the keys are the unique elements in the input array `x` and the values are the number of times that each element appears in `x`. Null values are ignored.
SELECT array_histogram(ARRAY[42, 7, 42, NULL]);
-- {42=2, 7=1}
Returns an empty map if the input array has no non-null elements.
SELECT array_histogram(ARRAY[NULL, NULL]);
-- {}
### array\_join
array_join(x, delimiter) -> varchar
Concatenates the elements of the given array using the delimiter. Null elements are omitted in the result.
array_join(x, delimiter, null_replacement) -> varchar
Concatenates the elements of the given array using the delimiter and an optional string to replace nulls.
### array\_max
array_max(x) -> x
Returns the maximum value of input array.
### array\_min
array_min(x) -> x
Returns the minimum value of input array.
### array\_position
array_position(x, element) -> bigint
Returns the position of the first occurrence of the `element` in array `x` (or 0 if not found).
### array\_remove
array_remove(x, element) -> array
Remove all elements that equal `element` from array `x`.
### array\_sort
array_sort(x) -> array
Sorts and returns the array `x`. The elements of `x` must be orderable. Null elements will be placed at the end of the returned array.
array_sort(array(T), function(T,T,int)) -> array(T)
Sorts and returns the `array` based on the given comparator `function`. The comparator will take two nullable arguments representing two nullable elements of the `array`. It returns -1, 0, or 1 as the first nullable element is less than, equal to, or greater than the second nullable element. If the comparator function returns other values (including `NULL`), the query will fail and raise an error.
SELECT array_sort(ARRAY[3, 2, 5, 1, 2],
(x, y) -> IF(x < y, 1, IF(x = y, 0, -1)));
-- [5, 3, 2, 2, 1]
SELECT array_sort(ARRAY['bc', 'ab', 'dc'],
(x, y) -> IF(x < y, 1, IF(x = y, 0, -1)));
-- ['dc', 'bc', 'ab']
SELECT array_sort(ARRAY[3, 2, null, 5, null, 1, 2],
-- sort null first with descending order
(x, y) -> CASE WHEN x IS NULL THEN -1
WHEN y IS NULL THEN 1
WHEN x < y THEN 1
WHEN x = y THEN 0
ELSE -1 END);
-- [null, null, 5, 3, 2, 2, 1]
SELECT array_sort(ARRAY[3, 2, null, 5, null, 1, 2],
-- sort null last with descending order
(x, y) -> CASE WHEN x IS NULL THEN 1
WHEN y IS NULL THEN -1
WHEN x < y THEN 1
WHEN x = y THEN 0
ELSE -1 END);
-- [5, 3, 2, 2, 1, null, null]
SELECT array_sort(ARRAY['a', 'abcd', 'abc'],
-- sort by string length
(x, y) -> IF(length(x) < length(y), -1,
IF(length(x) = length(y), 0, 1)));
-- ['a', 'abc', 'abcd']
SELECT array_sort(ARRAY[ARRAY[2, 3, 1], ARRAY[4, 2, 1, 4], ARRAY[1, 2]],
-- sort by array length
(x, y) -> IF(cardinality(x) < cardinality(y), -1,
IF(cardinality(x) = cardinality(y), 0, 1)));
-- [[1, 2], [2, 3, 1], [4, 2, 1, 4]]
### arrays\_overlap
arrays_overlap(x, y) -> boolean
Tests if arrays `x` and `y` have any non-null elements in common. Returns null if there are no non-null elements in common but either array contains null.
### cardinality
cardinality(x) -> bigint
Returns the cardinality (size) of the array `x`.
### concat
concat(array1, array2, ..., arrayN) -> array
Concatenates the arrays `array1`, `array2`, `...`, `arrayN`. This function provides the same functionality as the SQL-standard concatenation operator (`||`).
### combinations
combinations(array(T), n) -> array(array(T))
Returns n-element sub-groups of input array. If the input array has no duplicates, `combinations` returns n-element subsets.
SELECT combinations(ARRAY['foo', 'bar', 'baz'], 2);
-- [['foo', 'bar'], ['foo', 'baz'], ['bar', 'baz']]
SELECT combinations(ARRAY[1, 2, 3], 2);
-- [[1, 2], [1, 3], [2, 3]]
SELECT combinations(ARRAY[1, 2, 2], 2);
-- [[1, 2], [1, 2], [2, 2]]
Order of sub-groups is deterministic but unspecified. Order of elements within a sub-group deterministic but unspecified. `n` must be not be greater than 5, and the total size of sub-groups generated must be smaller than 100,000.
### contains
contains(x, element) -> boolean
Returns true if the array `x` contains the `element`.
### contains\_sequence
contains_sequence(x, seq) -> boolean
Return true if array `x` contains all of array `seq` as a subsequence (all values in the same consecutive order).
### element\_at
element_at(array(E), index) -> E
Returns element of `array` at given `index`. If `index` > 0, this function provides the same functionality as the SQL-standard subscript operator (`[]`), except that the function returns `NULL` when accessing an `index` larger than array length, whereas the subscript operator would fail in such a case. If `index` < 0, `element_at` accesses elements from the last to the first.
### filter
filter(array(T), function(T,boolean)) -> array(T)
Constructs an array from those elements of `array` for which `function` returns true:
SELECT filter(ARRAY[], x -> true);
-- []
SELECT filter(ARRAY[5, -6, NULL, 7], x -> x > 0);
-- [5, 7]
SELECT filter(ARRAY[5, NULL, 7, NULL], x -> x IS NOT NULL);
-- [5, 7]
### flatten
flatten(x) -> array
Flattens an `array(array(T))` to an `array(T)` by concatenating the contained arrays.
### ngrams
ngrams(array(T), n) -> array(array(T))
Returns `n`\-grams (sub-sequences of adjacent `n` elements) for the `array`. The order of the `n`\-grams in the result is unspecified.
SELECT ngrams(ARRAY['foo', 'bar', 'baz', 'foo'], 2);
-- [['foo', 'bar'], ['bar', 'baz'], ['baz', 'foo']]
SELECT ngrams(ARRAY['foo', 'bar', 'baz', 'foo'], 3);
-- [['foo', 'bar', 'baz'], ['bar', 'baz', 'foo']]
SELECT ngrams(ARRAY['foo', 'bar', 'baz', 'foo'], 4);
-- [['foo', 'bar', 'baz', 'foo']]
SELECT ngrams(ARRAY['foo', 'bar', 'baz', 'foo'], 5);
-- [['foo', 'bar', 'baz', 'foo']]
SELECT ngrams(ARRAY[1, 2, 3, 4], 2);
-- [[1, 2], [2, 3], [3, 4]]
### none\_match
none_match(array(T), function(T,boolean)) -> boolean
Returns whether no elements of an array match the given predicate. Returns `true` if none of the elements matches the predicate (a special case is when the array is empty); `false` if one or more elements match; `NULL` if the predicate function returns `NULL` for one or more elements and `false` for all other elements.
### reduce
reduce(array(T), initialState S, inputFunction(S,T,S), outputFunction(S,R)) -> R
Returns a single value reduced from `array`. `inputFunction` will be invoked for each element in `array` in order. In addition to taking the element, `inputFunction` takes the current state, initially `initialState`, and returns the new state. `outputFunction` will be invoked to turn the final state into the result value. It may be the identity function (`i -> i`).
SELECT reduce(ARRAY[], 0,
(s, x) -> s + x,
s -> s);
-- 0
SELECT reduce(ARRAY[5, 20, 50], 0,
(s, x) -> s + x,
s -> s);
-- 75
SELECT reduce(ARRAY[5, 20, NULL, 50], 0,
(s, x) -> s + x,
s -> s);
-- NULL
SELECT reduce(ARRAY[5, 20, NULL, 50], 0,
(s, x) -> s + coalesce(x, 0),
s -> s);
-- 75
SELECT reduce(ARRAY[5, 20, NULL, 50], 0,
(s, x) -> IF(x IS NULL, s, s + x),
s -> s);
-- 75
SELECT reduce(ARRAY[2147483647, 1], BIGINT '0',
(s, x) -> s + x,
s -> s);
-- 2147483648
-- calculates arithmetic average
SELECT reduce(ARRAY[5, 6, 10, 20],
CAST(ROW(0.0, 0) AS ROW(sum DOUBLE, count INTEGER)),
(s, x) -> CAST(ROW(x + s.sum, s.count + 1) AS
ROW(sum DOUBLE, count INTEGER)),
s -> IF(s.count = 0, NULL, s.sum / s.count));
-- 10.25
### repeat
repeat(element, count) -> array
Repeat `element` for `count` times.
### reverse
reverse(x) -> array
Returns an array which has the reversed order of array `x`.
### sequence
sequence(start, stop) -> array(bigint)
Generate a sequence of integers from `start` to `stop`, incrementing by `1` if `start` is less than or equal to `stop`, otherwise `-1`.
sequence(start, stop, step) -> array(bigint)
Generate a sequence of integers from `start` to `stop`, incrementing by `step`.
sequence(start, stop) -> array(date)
Generate a sequence of dates from `start` date to `stop` date, incrementing by `1` day if `start` date is less than or equal to `stop` date, otherwise `-1` day.
sequence(start, stop, step) -> array(date)
Generate a sequence of dates from `start` to `stop`, incrementing by `step`. The type of `step` can be either `INTERVAL DAY TO SECOND` or `INTERVAL YEAR TO MONTH`.
sequence(start, stop, step) -> array(timestamp)
Generate a sequence of timestamps from `start` to `stop`, incrementing by `step`. The type of `step` can be either `INTERVAL DAY TO SECOND` or `INTERVAL YEAR TO MONTH`.
### shuffle
shuffle(x) -> array
Generate a random permutation of the given array `x`.
### slice
slice(x, start, length) -> array
Subsets array `x` starting from index `start` (or starting from the end if `start` is negative) with a length of `length`.
### trim\_array
trim_array(x, n) -> array
Remove `n` elements from the end of array:
SELECT trim_array(ARRAY[1, 2, 3, 4], 1);
-- [1, 2, 3]
SELECT trim_array(ARRAY[1, 2, 3, 4], 2);
-- [1, 2]
### transform
transform(array(T), function(T,U)) -> array(U)
Returns an array that is the result of applying `function` to each element of `array`:
SELECT transform(ARRAY[], x -> x + 1);
-- []
SELECT transform(ARRAY[5, 6], x -> x + 1);
-- [6, 7]
SELECT transform(ARRAY[5, NULL, 6], x -> coalesce(x, 0) + 1);
-- [6, 1, 7]
SELECT transform(ARRAY['x', 'abc', 'z'], x -> x || '0');
-- ['x0', 'abc0', 'z0']
SELECT transform(ARRAY[ARRAY[1, NULL, 2], ARRAY[3, NULL]],
a -> filter(a, x -> x IS NOT NULL));
-- [[1, 2], [3]]
### zip
zip(array1, array2[, ...]) -> array(row)
Merges the given arrays, element-wise, into a single array of rows. The M-th element of the N-th argument will be the N-th field of the M-th output element. If the arguments have an uneven length, missing values are filled with `NULL`.
SELECT zip(ARRAY[1, 2], ARRAY['1b', null, '3b']);
-- [ROW(1, '1b'), ROW(2, null), ROW(null, '3b')]
### zip\_with
zip_with(array(T), array(U), function(T,U,R)) -> array(R)
Merges the two given arrays, element-wise, into a single array using `function`. If one array is shorter, nulls are appended at the end to match the length of the longer array, before applying `function`.
SELECT zip_with(ARRAY[1, 3, 5], ARRAY['a', 'b', 'c'],
(x, y) -> (y, x));
-- [ROW('a', 1), ROW('b', 3), ROW('c', 5)]
SELECT zip_with(ARRAY[1, 2], ARRAY[3, 4],
(x, y) -> x + y);
-- [4, 6]
SELECT zip_with(ARRAY['a', 'b', 'c'], ARRAY['d', 'e', 'f'],
(x, y) -> concat(x, y));
-- ['ad', 'be', 'cf']
SELECT zip_with(ARRAY['a'], ARRAY['d', null, 'f'],
(x, y) -> coalesce(x, y));
-- ['a', null, 'f']
On this page
* [Subscript operator: \[\]](https://www.peaka.com/docs/sql/functions/array/#subscript-operator)
* [Concatenation operator: ||](https://www.peaka.com/docs/sql/functions/array/#concatenation-operator)
* [Array functions](https://www.peaka.com/docs/sql/functions/array/#array-functions)
* [all\_match](https://www.peaka.com/docs/sql/functions/array/#all-match)
* [any\_match](https://www.peaka.com/docs/sql/functions/array/#any-match)
* [array\_distinct](https://www.peaka.com/docs/sql/functions/array/#array-distinct)
* [array\_intersect](https://www.peaka.com/docs/sql/functions/array/#array-intersect)
* [array\_union](https://www.peaka.com/docs/sql/functions/array/#array-union)
* [array\_except](https://www.peaka.com/docs/sql/functions/array/#array-except)
* [array\_histogram](https://www.peaka.com/docs/sql/functions/array/#array-histogram)
* [array\_join](https://www.peaka.com/docs/sql/functions/array/#array-join)
* [array\_max](https://www.peaka.com/docs/sql/functions/array/#array-max)
* [array\_min](https://www.peaka.com/docs/sql/functions/array/#array-min)
* [array\_position](https://www.peaka.com/docs/sql/functions/array/#array-position)
* [array\_remove](https://www.peaka.com/docs/sql/functions/array/#array-remove)
* [array\_sort](https://www.peaka.com/docs/sql/functions/array/#array-sort)
* [arrays\_overlap](https://www.peaka.com/docs/sql/functions/array/#arrays-overlap)
* [cardinality](https://www.peaka.com/docs/sql/functions/array/#cardinality)
* [concat](https://www.peaka.com/docs/sql/functions/array/#concat)
* [combinations](https://www.peaka.com/docs/sql/functions/array/#combinations)
* [contains](https://www.peaka.com/docs/sql/functions/array/#contains)
* [contains\_sequence](https://www.peaka.com/docs/sql/functions/array/#contains-sequence)
* [element\_at](https://www.peaka.com/docs/sql/functions/array/#element-at)
* [filter](https://www.peaka.com/docs/sql/functions/array/#filter)
* [flatten](https://www.peaka.com/docs/sql/functions/array/#flatten)
* [ngrams](https://www.peaka.com/docs/sql/functions/array/#ngrams)
* [none\_match](https://www.peaka.com/docs/sql/functions/array/#none-match)
* [reduce](https://www.peaka.com/docs/sql/functions/array/#reduce)
* [repeat](https://www.peaka.com/docs/sql/functions/array/#repeat)
* [reverse](https://www.peaka.com/docs/sql/functions/array/#reverse)
* [sequence](https://www.peaka.com/docs/sql/functions/array/#sequence)
* [shuffle](https://www.peaka.com/docs/sql/functions/array/#shuffle)
* [slice](https://www.peaka.com/docs/sql/functions/array/#slice)
* [trim\_array](https://www.peaka.com/docs/sql/functions/array/#trim-array)
* [transform](https://www.peaka.com/docs/sql/functions/array/#transform)
* [zip](https://www.peaka.com/docs/sql/functions/array/#zip)
* [zip\_with](https://www.peaka.com/docs/sql/functions/array/#zip-with)
--- START: docs/sql/functions/binary/binary.md ---
Documentation menu
[Home](/) / [Docs](/docs/) / Binary functions and operators
 Copy as Markdown
Binary functions and operators
==============================
Binary operators
----------------
The `||` operator performs concatenation.
Binary functions
----------------
### concat
concat(binary1, ..., binaryN) -> varbinary
Returns the concatenation of `binary1`, `binary2`, `...`, `binaryN`. This function provides the same functionality as the SQL-standard concatenation operator (`||`).
### length
length(binary) -> bigint
Returns the length of `binary` in bytes.
### lpad
lpad(binary, size, padbinary) -> varbinary
Left pads `binary` to `size` bytes with `padbinary`. If `size` is less than the length of `binary`, the result is truncated to `size` characters. `size` must not be negative and `padbinary` must be non-empty.
### rpad
rpad(binary, size, padbinary) -> varbinary
Right pads `binary` to `size` bytes with `padbinary`. If `size` is less than the length of `binary`, the result is truncated to `size` characters. `size` must not be negative and `padbinary` must be non-empty.
### substr
substr(binary, start) -> varbinary
Returns the rest of `binary` from the starting position `start`, measured in bytes. Positions start with `1`. A negative starting position is interpreted as being relative to the end of the string.
substr(binary, start, length) -> varbinary
Returns a substring from `binary` of length `length` from the starting position `start`, measured in bytes. Positions start with `1`. A negative starting position is interpreted as being relative to the end of the string.
### reverse
reverse(binary) -> varbinary
Returns `binary` with the bytes in reverse order.
Base64 encoding functions
-------------------------
The Base64 functions implement the encoding specified in RFC 4648.
### from\_base64
from_base64(string) -> varbinary
Decodes binary data from the base64 encoded `string`.
### to\_base64
to_base64(binary) -> varchar
Encodes `binary` into a base64 string representation.
### from\_base64url
from_base64url(string) -> varbinary
Decodes binary data from the base64 encoded `string` using the URL safe alphabet.
### to\_base64url
to_base64url(binary) -> varchar
Encodes `binary` into a base64 string representation using the URL safe alphabet.
### from\_base32
from_base32(string) -> varbinary
Decodes binary data from the base32 encoded `string`.
### to\_base32
to_base32(binary) -> varchar
Encodes `binary` into a base32 string representation.
Hex encoding functions
----------------------
### from\_hex
from_hex(string) -> varbinary
Decodes binary data from the hex encoded `string`.
### to\_hex
to_hex(binary) -> varchar
Encodes `binary` into a hex string representation.
Integer encoding functions
--------------------------
### from\_big\_endian\_32
from_big_endian_32(binary) -> integer
Decodes the 32-bit two's complement big-endian `binary`. The input must be exactly 4 bytes.
### to\_big\_endian\_32
to_big_endian_32(integer) -> varbinary
Encodes `integer` into a 32-bit two's complement big-endian format.
### from\_big\_endian\_64
from_big_endian_64(binary) -> bigint
Decodes the 64-bit two's complement big-endian `binary`. The input must be exactly 8 bytes.
### to\_big\_endian\_64
to_big_endian_64(bigint) -> varbinary
Encodes `bigint` into a 64-bit two's complement big-endian format.
Floating-point encoding functions
---------------------------------
### from\_ieee754\_32
from_ieee754_32(binary) -> real
Decodes the 32-bit big-endian `binary` in IEEE 754 single-precision floating-point format. The input must be exactly 4 bytes.
### to\_ieee754\_32
to_ieee754_32(real) -> varbinary
Encodes `real` into a 32-bit big-endian binary according to IEEE 754 single-precision floating-point format.
### from\_ieee754\_64
from_ieee754_64(binary) -> double
Decodes the 64-bit big-endian `binary` in IEEE 754 double-precision floating-point format. The input must be exactly 8 bytes.
### to\_ieee754\_64
to_ieee754_64(double) -> varbinary
Encodes `double` into a 64-bit big-endian binary according to IEEE 754 double-precision floating-point format.
Hashing functions
-----------------
### crc32
crc32(binary) -> bigint
Computes the CRC-32 of `binary`. For general purpose hashing, use `xxhash64`, as it is much faster and produces a better quality hash.
### md5
md5(binary) -> varbinary
Computes the MD5 hash of `binary`.
### sha1
sha1(binary) -> varbinary
Computes the SHA1 hash of `binary`.
### sha256
sha256(binary) -> varbinary
Computes the SHA256 hash of `binary`.
### sha512
sha512(binary) -> varbinary
Computes the SHA512 hash of `binary`.
### spooky\_hash\_v2\_32
spooky_hash_v2_32(binary) -> varbinary
Computes the 32-bit SpookyHashV2 hash of `binary`.
### spooky\_hash\_v2\_64
spooky_hash_v2_64(binary) -> varbinary
Computes the 64-bit SpookyHashV2 hash of `binary`.
### xxhash64
xxhash64(binary) -> varbinary
Computes the xxHash64 hash of `binary`.
### murmur3
murmur3(binary) -> varbinary
Computes the 128-bit [MurmurHash3](https://wikipedia.org/wiki/MurmurHash) hash of `binary`.
> SELECT murmur3(from_base64('aaaaaa'));
> -- ba 58 55 63 55 69 b4 2f 49 20 37 2c a0 e3 96 ef
HMAC functions
--------------
### hmac\_md5
hmac_md5(binary, key) -> varbinary
Computes HMAC with MD5 of `binary` with the given `key`.
### hmac\_sha1
hmac_sha1(binary, key) -> varbinary
Computes HMAC with SHA1 of `binary` with the given `key`.
### hmac\_sha256
hmac_sha256(binary, key) -> varbinary
Computes HMAC with SHA256 of `binary` with the given `key`.
### hmac\_sha512
hmac_sha512(binary, key) -> varbinary
Computes HMAC with SHA512 of `binary` with the given `key`.
On this page
* [Binary operators](https://www.peaka.com/docs/sql/functions/binary/#binary-operators)
* [Binary functions](https://www.peaka.com/docs/sql/functions/binary/#binary-functions)
* [concat](https://www.peaka.com/docs/sql/functions/binary/#concat)
* [length](https://www.peaka.com/docs/sql/functions/binary/#length)
* [lpad](https://www.peaka.com/docs/sql/functions/binary/#lpad)
* [rpad](https://www.peaka.com/docs/sql/functions/binary/#rpad)
* [substr](https://www.peaka.com/docs/sql/functions/binary/#substr)
* [reverse](https://www.peaka.com/docs/sql/functions/binary/#reverse)
* [Base64 encoding functions](https://www.peaka.com/docs/sql/functions/binary/#base64-encoding-functions)
* [from\_base64](https://www.peaka.com/docs/sql/functions/binary/#from-base64)
* [to\_base64](https://www.peaka.com/docs/sql/functions/binary/#to-base64)
* [from\_base64url](https://www.peaka.com/docs/sql/functions/binary/#from-base64url)
* [to\_base64url](https://www.peaka.com/docs/sql/functions/binary/#to-base64url)
* [from\_base32](https://www.peaka.com/docs/sql/functions/binary/#from-base32)
* [to\_base32](https://www.peaka.com/docs/sql/functions/binary/#to-base32)
* [Hex encoding functions](https://www.peaka.com/docs/sql/functions/binary/#hex-encoding-functions)
* [from\_hex](https://www.peaka.com/docs/sql/functions/binary/#from-hex)
* [to\_hex](https://www.peaka.com/docs/sql/functions/binary/#to-hex)
* [Integer encoding functions](https://www.peaka.com/docs/sql/functions/binary/#integer-encoding-functions)
* [from\_big\_endian\_32](https://www.peaka.com/docs/sql/functions/binary/#from-big-endian-32)
* [to\_big\_endian\_32](https://www.peaka.com/docs/sql/functions/binary/#to-big-endian-32)
* [from\_big\_endian\_64](https://www.peaka.com/docs/sql/functions/binary/#from-big-endian-64)
* [to\_big\_endian\_64](https://www.peaka.com/docs/sql/functions/binary/#to-big-endian-64)
* [Floating-point encoding functions](https://www.peaka.com/docs/sql/functions/binary/#floating-point-encoding-functions)
* [from\_ieee754\_32](https://www.peaka.com/docs/sql/functions/binary/#from-ieee754-32)
* [to\_ieee754\_32](https://www.peaka.com/docs/sql/functions/binary/#to-ieee754-32)
* [from\_ieee754\_64](https://www.peaka.com/docs/sql/functions/binary/#from-ieee754-64)
* [to\_ieee754\_64](https://www.peaka.com/docs/sql/functions/binary/#to-ieee754-64)
* [Hashing functions](https://www.peaka.com/docs/sql/functions/binary/#hashing-functions)
* [crc32](https://www.peaka.com/docs/sql/functions/binary/#crc32)
* [md5](https://www.peaka.com/docs/sql/functions/binary/#md5)
* [sha1](https://www.peaka.com/docs/sql/functions/binary/#sha1)
* [sha256](https://www.peaka.com/docs/sql/functions/binary/#sha256)
* [sha512](https://www.peaka.com/docs/sql/functions/binary/#sha512)
* [spooky\_hash\_v2\_32](https://www.peaka.com/docs/sql/functions/binary/#spooky-hash-v2-32)
* [spooky\_hash\_v2\_64](https://www.peaka.com/docs/sql/functions/binary/#spooky-hash-v2-64)
* [xxhash64](https://www.peaka.com/docs/sql/functions/binary/#xxhash64)
* [murmur3](https://www.peaka.com/docs/sql/functions/binary/#murmur3)
* [HMAC functions](https://www.peaka.com/docs/sql/functions/binary/#hmac-functions)
* [hmac\_md5](https://www.peaka.com/docs/sql/functions/binary/#hmac-md5)
* [hmac\_sha1](https://www.peaka.com/docs/sql/functions/binary/#hmac-sha1)
* [hmac\_sha256](https://www.peaka.com/docs/sql/functions/binary/#hmac-sha256)
* [hmac\_sha512](https://www.peaka.com/docs/sql/functions/binary/#hmac-sha512)
--- START: docs/sql/functions/bitwise/bitwise.md ---
Documentation menu
[Home](/) / [Docs](/docs/) / Bitwise functions
 Copy as Markdown
Bitwise functions
=================
Bitwise functions
-----------------
### bit\_count
bit_count(x, bits) -> bigint
Count the number of bits set in `x` (treated as `bits`\-bit signed integer) in 2's complement representation:
SELECT bit_count(9, 64); -- 2
SELECT bit_count(9, 8); -- 2
SELECT bit_count(-7, 64); -- 62
SELECT bit_count(-7, 8); -- 6
### bitwise\_and
bitwise_and(x, y) -> bigint
Returns the bitwise AND of `x` and `y` in 2's complement representation.
Bitwise AND of `19` (binary: `10011`) and `25` (binary: `11001`) results in `17` (binary: `10001`):
SELECT bitwise_and(19,25); -- 17
### bitwise\_not
bitwise_not(x) -> bigint
Returns the bitwise NOT of `x` in 2's complement representation (`NOT x = -x - 1`):
SELECT bitwise_not(-12); -- 11
SELECT bitwise_not(19); -- -20
SELECT bitwise_not(25); -- -26
### bitwise\_or
bitwise_or(x, y) -> bigint
Returns the bitwise OR of `x` and `y` in 2's complement representation.
Bitwise OR of `19` (binary: `10011`) and `25` (binary: `11001`) results in `27` (binary: `11011`):
SELECT bitwise_or(19,25); -- 27
### bitwise\_xor
bitwise_xor(x, y) -> bigint
Returns the bitwise XOR of `x` and `y` in 2's complement representation.
Bitwise XOR of `19` (binary: `10011`) and `25` (binary: `11001`) results in `10` (binary: `01010`):
SELECT bitwise_xor(19,25); -- 10
### bitwise\_left\_shift
bitwise_left_shift(value, shift) -> [same as value]
Returns the left shifted value of `value`.
Shifting `1` (binary: `001`) by two bits results in `4` (binary: `00100`):
SELECT bitwise_left_shift(1, 2); -- 4
Shifting `5` (binary: `0101`) by two bits results in `20` (binary: `010100`):
SELECT bitwise_left_shift(5, 2); -- 20
Shifting a `value` by `0` always results in the original `value`:
SELECT bitwise_left_shift(20, 0); -- 20
SELECT bitwise_left_shift(42, 0); -- 42
Shifting `0` by a `shift` always results in `0`:
SELECT bitwise_left_shift(0, 1); -- 0
SELECT bitwise_left_shift(0, 2); -- 0
### bitwise\_right\_shift
bitwise_right_shift(value, shift) -> [same as value]
Returns the logical right shifted value of `value`.
Shifting `8` (binary: `1000`) by three bits results in `1` (binary: `001`):
SELECT bitwise_right_shift(8, 3); -- 1
Shifting `9` (binary: `1001`) by one bit results in `4` (binary: `100`):
SELECT bitwise_right_shift(9, 1); -- 4
Shifting a `value` by `0` always results in the original `value`:
SELECT bitwise_right_shift(20, 0); -- 20
SELECT bitwise_right_shift(42, 0); -- 42
Shifting a `value` by `64` or more bits results in `0`:
SELECT bitwise_right_shift( 12, 64); -- 0
SELECT bitwise_right_shift(-45, 64); -- 0
Shifting `0` by a `shift` always results in `0`:
SELECT bitwise_right_shift(0, 1); -- 0
SELECT bitwise_right_shift(0, 2); -- 0
### bitwise\_right\_shift\_arithmetic
bitwise_right_shift_arithmetic(value, shift) -> [same as value]
Returns the arithmetic right shifted value of `value`.
Returns the same values as [bitwise\_right\_shift](https://www.peaka.com/docs/sql/functions/bitwise/#bitwise-right-shift) when shifting by less than `64` bits. Shifting by `64` or more bits results in `0` for a positive and `-1` for a negative `value`:
SELECT bitwise_right_shift_arithmetic( 12, 64); -- 0
SELECT bitwise_right_shift_arithmetic(-45, 64); -- -1
See also [bitwise\_and\_agg](/docs/sql/functions/aggregate#bitwise-and-agg) and [bitwise\_or\_agg](/docs/sql/functions/aggregate#bitwise-or-agg).
On this page
* [Bitwise functions](https://www.peaka.com/docs/sql/functions/bitwise/#bitwise-functions)
* [bit\_count](https://www.peaka.com/docs/sql/functions/bitwise/#bit-count)
* [bitwise\_and](https://www.peaka.com/docs/sql/functions/bitwise/#bitwise-and)
* [bitwise\_not](https://www.peaka.com/docs/sql/functions/bitwise/#bitwise-not)
* [bitwise\_or](https://www.peaka.com/docs/sql/functions/bitwise/#bitwise-or)
* [bitwise\_xor](https://www.peaka.com/docs/sql/functions/bitwise/#bitwise-xor)
* [bitwise\_left\_shift](https://www.peaka.com/docs/sql/functions/bitwise/#bitwise-left-shift)
* [bitwise\_right\_shift](https://www.peaka.com/docs/sql/functions/bitwise/#bitwise-right-shift)
* [bitwise\_right\_shift\_arithmetic](https://www.peaka.com/docs/sql/functions/bitwise/#bitwise-right-shift-arithmetic)
--- START: docs/sql/functions/comparison/comparison.md ---
Documentation menu
[Home](/) / [Docs](/docs/) / Comparison functions and operators
 Copy as Markdown
Comparison functions and operators
==================================
Comparison operators
--------------------
Operator
Description
<
Less than
\>
Greater than
<=
Less than or equal to
\>=
Greater than or equal to
\=
Equal
<>
Not equal
!=
Not equal
Range operator: BETWEEN
-----------------------
The `BETWEEN` operator tests if a value is within a specified range. It uses the syntax `value BETWEEN min AND max`:
SELECT 3 BETWEEN 2 AND 6;
The statement shown above is equivalent to the following statement:
SELECT 3 >= 2 AND 3 <= 6;
To test if a value does not fall within the specified range use `NOT BETWEEN`:
SELECT 3 NOT BETWEEN 2 AND 6;
The statement shown above is equivalent to the following statement:
SELECT 3 < 2 OR 3 > 6;
A `NULL` in a `BETWEEN` or `NOT BETWEEN` statement is evaluated using the standard `NULL` evaluation rules applied to the equivalent expression above:
SELECT NULL BETWEEN 2 AND 4; -- null
SELECT 2 BETWEEN NULL AND 6; -- null
SELECT 2 BETWEEN 3 AND NULL; -- false
SELECT 8 BETWEEN NULL AND 6; -- false
The `BETWEEN` and `NOT BETWEEN` operators can also be used to evaluate any orderable type. For example, a `VARCHAR`:
SELECT 'Paul' BETWEEN 'John' AND 'Ringo'; -- true
Note that the value, min, and max parameters to `BETWEEN` and `NOT BETWEEN` must be the same type. For example, Trino will produce an error if you ask it if John is between 2.3 and 35.2.
IS NULL and IS NOT NULL
-----------------------
The `IS NULL` and `IS NOT NULL` operators test whether a value is null (undefined). Both operators work for all data types.
Using `NULL` with `IS NULL` evaluates to true:
select NULL IS NULL; -- true
But any other constant does not:
SELECT 3.0 IS NULL; -- false
IS DISTINCT FROM and IS NOT DISTINCT FROM
-----------------------------------------
In SQL a `NULL` value signifies an unknown value, so any comparison involving a `NULL` will produce `NULL`. The `IS DISTINCT FROM` and `IS NOT DISTINCT FROM` operators treat `NULL` as a known value and both operators guarantee either a true or false outcome even in the presence of `NULL` input:
SELECT NULL IS DISTINCT FROM NULL; -- false
SELECT NULL IS NOT DISTINCT FROM NULL; -- true
In the example shown above, a `NULL` value is not considered distinct from `NULL`. When you are comparing values which may include `NULL` use these operators to guarantee either a `TRUE` or `FALSE` result.
The following truth table demonstrate the handling of `NULL` in `IS DISTINCT FROM` and `IS NOT DISTINCT FROM`:
a
b
a = b
a <> b
a DISTINCT b
a NOT DISTINCT b
`1`
`1`
`TRUE`
`FALSE`
`FALSE`
`TRUE`
`1`
`2`
`FALSE`
`TRUE`
`TRUE`
`FALSE`
`1`
`NULL`
`NULL`
`NULL`
`TRUE`
`FALSE`
`NULL`
`NULL`
`NULL`
`NULL`
`FALSE`
`TRUE`
GREATEST and LEAST
------------------
These functions are not in the SQL standard, but are a common extension. Like most other functions in Trino, they return null if any argument is null. Note that in some other databases, such as PostgreSQL, they only return null if all arguments are null.
The following types are supported: `DOUBLE`, `BIGINT`, `VARCHAR`, `TIMESTAMP`, `TIMESTAMP WITH TIME ZONE`, `DATE`
greatest(value1, value2, ..., valueN) -> [same as input]
Returns the largest of the provided values.
least(value1, value2, ..., valueN) -> [same as input]
Returns the smallest of the provided values.
Quantified comparison predicates: ALL, ANY and SOME
---------------------------------------------------
The `ALL`, `ANY` and `SOME` quantifiers can be used together with comparison operators in the following way:
expression operator quantifier ( subquery )
For example:
SELECT 'hello' = ANY (VALUES 'hello', 'world'); -- true
SELECT 21 < ALL (VALUES 19, 20, 21); -- false
SELECT 42 >= SOME (SELECT 41 UNION ALL SELECT 42 UNION ALL SELECT 43); -- true
Here are the meanings of some quantifier and comparison operator combinations:
Expression
Meaning
`A = ALL (...)`
Evaluates to `true` when `A` is equal to all values.
`A <> ALL (...)`
Evaluates to `true` when `A` doesn't match any value.
`A < ALL (...)`
Evaluates to `true` when `A` is smaller than the smallest value.
`A = ANY (...)`
Evaluates to `true` when `A` is equal to any of the values. This form is equivalent to `A IN (...)`.
`A <> ANY (...)`
Evaluates to `true` when `A` doesn't match one or more values.
`A < ANY (...)`
Evaluates to `true` when `A` is smaller than the biggest value.
`ANY` and `SOME` have the same meaning and can be used interchangeably.
Pattern comparison: LIKE
------------------------
The `LIKE` operator can be used to compare values with a pattern:
... column [NOT] LIKE 'pattern' ESCAPE 'character';
Matching characters is case sensitive, and the pattern supports two symbols for matching:
* `_` matches any single character
* `%` matches zero or more characters
Typically it is often used as a condition in `WHERE` statements. An example is a query to find all continents starting with `E`, which returns `Europe`:
SELECT * FROM (VALUES 'America', 'Asia', 'Africa', 'Europe', 'Australia', 'Antarctica') AS t (continent)
WHERE continent LIKE 'E%';
You can negate the result by adding `NOT`, and get all other continents, all not starting with `E`:
SELECT * FROM (VALUES 'America', 'Asia', 'Africa', 'Europe', 'Australia', 'Antarctica') AS t (continent)
WHERE continent NOT LIKE 'E%';
If you only have one specific character to match, you can use the `_` symbol for each character. The following query uses two underscores and produces only `Asia` as result:
SELECT * FROM (VALUES 'America', 'Asia', 'Africa', 'Europe', 'Australia', 'Antarctica') AS t (continent)
WHERE continent LIKE 'A__A';
The wildcard characters `_` and `%` must be escaped to allow you to match them as literals. This can be achieved by specifying the `ESCAPE` character to use:
SELECT 'South_America' LIKE 'South\_America' ESCAPE '\';
The above query returns `true` since the escaped underscore symbol matches. If you need to match the used escape character as well, you can escape it.
If you want to match for the chosen escape character, you simply escape itself. For example, you can use `\\` to match for `\`.
Row comparison: IN
------------------
The `IN` operator can be used in a `WHERE` clause to compare column values with a list of values. The list of values can be supplied by a subquery or directly as static values in an array:
... WHERE column [NOT] IN ('value1','value2');
... WHERE column [NOT] IN ( subquery );
Use the optional `NOT` keyword to negate the condition.
The following example shows a simple usage with a static array:
SELECT * FROM region WHERE name IN ('AMERICA', 'EUROPE');
The values in the clause are used for multiple comparisons that are combined as a logical `OR`. The preceding query is equivalent to the following query:
SELECT * FROM region WHERE name = 'AMERICA' OR name = 'EUROPE';
You can negate the comparisons by adding `NOT`, and get all other regions except the values in list:
SELECT * FROM region WHERE name NOT IN ('AMERICA', 'EUROPE');
When using a subquery to determine the values to use in the comparison, the subquery must return a single column and one or more rows.
SELECT name
FROM nation
WHERE regionkey IN (
SELECT starts_with(regionkey,"A") AS regionkey
FROM region
);
On this page
* [Comparison operators](https://www.peaka.com/docs/sql/functions/comparison/#comparison-operators)
* [Range operator: BETWEEN](https://www.peaka.com/docs/sql/functions/comparison/#range-operator-between)
* [IS NULL and IS NOT NULL](https://www.peaka.com/docs/sql/functions/comparison/#is-null-and-is-not-null)
* [IS DISTINCT FROM and IS NOT DISTINCT FROM](https://www.peaka.com/docs/sql/functions/comparison/#is-distinct-from-and-is-not-distinct-from)
* [GREATEST and LEAST](https://www.peaka.com/docs/sql/functions/comparison/#greatest-and-least)
* [Quantified comparison predicates: ALL, ANY and SOME](https://www.peaka.com/docs/sql/functions/comparison/#quantified-comparison-predicates-all-any-and-some)
* [Pattern comparison: LIKE](https://www.peaka.com/docs/sql/functions/comparison/#pattern-comparison-like)
* [Row comparison: IN](https://www.peaka.com/docs/sql/functions/comparison/#row-comparison-in)
--- START: docs/sql/functions/conditional/conditional.md ---
Documentation menu
[Home](/) / [Docs](/docs/) / Conditional Expressions
 Copy as Markdown
Conditional Expressions
=======================
CASE
----
The standard SQL `CASE` expression has two forms. The "simple" form searches each `value` expression from left to right until it finds one that equals `expression`:
CASE expression
WHEN value THEN result
[ WHEN ... ]
[ ELSE result ]
END
The `result` for the matching `value` is returned. If no match is found, the `result` from the `ELSE` clause is returned if it exists, otherwise null is returned. Example:
SELECT a,
CASE a
WHEN 1 THEN 'one'
WHEN 2 THEN 'two'
ELSE 'many'
END
The "searched" form evaluates each boolean `condition` from left to right until one is true and returns the matching `result`:
CASE
WHEN condition THEN result
[ WHEN ... ]
[ ELSE result ]
END
If no conditions are true, the `result` from the `ELSE` clause is returned if it exists, otherwise null is returned. Example:
SELECT a, b,
CASE
WHEN a = 1 THEN 'aaa'
WHEN b = 2 THEN 'bbb'
ELSE 'ccc'
END
SQL routines can use [`CASE` statements](/docs/sql/routines/case) that use a slightly different syntax from the CASE expressions. Specifically note the requirements for terminating each clause with a semicolon `;` and the usage of `END CASE`.
IF
--
The `IF` expression has two forms, one supplying only a `true_value` and the other supplying both a `true_value` and a `false_value`:
if(condition, true_value)
Evaluates and returns `true_value` if `condition` is true, otherwise null is returned and `true_value` is not evaluated.
if(condition, true_value, false_value)
Evaluates and returns `true_value` if `condition` is true, otherwise evaluates and returns `false_value`.
The following `IF` and `CASE` expressions are equivalent:
SELECT
orderkey,
totalprice,
IF(totalprice >= 150000, 'High Value', 'Low Value')
FROM tpch.sf1.orders;
SELECT
orderkey,
totalprice,
CASE
WHEN totalprice >= 150000 THEN 'High Value'
ELSE 'Low Value'
END
FROM tpch.sf1.orders;
SQL routines can use [`IF` statements](/docs/sql/routines/if) that use a slightly different syntax from `IF` expressions. Specifically note the requirement for terminating each clause with a semicolon `;` and the usage of `END IF`.
COALESCE
--------
coalesce(value1, value2[, ...])
Returns the first non-null `value` in the argument list. Like a `CASE` expression, arguments are only evaluated if necessary.
NULLIF
------
nullif(value1, value2)
Returns null if `value1` equals `value2`, otherwise returns `value1`.
TRY
---
try(expression)
Evaluate an expression and handle certain types of errors by returning `NULL`.
In cases where it is preferable that queries produce `NULL` or default values instead of failing when corrupt or invalid data is encountered, the `TRY` function may be useful. To specify default values, the `TRY` function can be used in conjunction with the `COALESCE` function.
The following errors are handled by `TRY`:
* Division by zero
* Invalid cast or function argument
* Numeric value out of range
### Examples
Source table with some invalid data:
SELECT * FROM shipping;
origin_state | origin_zip | packages | total_cost
--------------+------------+----------+------------
California | 94131 | 25 | 100
California | P332a | 5 | 72
California | 94025 | 0 | 155
New Jersey | 08544 | 225 | 490
(4 rows)
Query failure without `TRY`:
SELECT CAST(origin_zip AS BIGINT) FROM shipping;
Query failed: Cannot cast 'P332a' to BIGINT
`NULL` values with `TRY`:
SELECT TRY(CAST(origin_zip AS BIGINT)) FROM shipping;
origin_zip
------------
94131
NULL
94025
08544
(4 rows)
Query failure without `TRY`:
SELECT total_cost / packages AS per_package FROM shipping;
Query failed: Division by zero
Default values with `TRY` and `COALESCE`:
SELECT COALESCE(TRY(total_cost / packages), 0) AS per_package FROM shipping;
per_package
-------------
4
14
0
19
(4 rows)
On this page
* [CASE](https://www.peaka.com/docs/sql/functions/conditional/#case)
* [IF](https://www.peaka.com/docs/sql/functions/conditional/#if)
* [COALESCE](https://www.peaka.com/docs/sql/functions/conditional/#coalesce)
* [NULLIF](https://www.peaka.com/docs/sql/functions/conditional/#nullif)
* [TRY](https://www.peaka.com/docs/sql/functions/conditional/#try)
* [Examples](https://www.peaka.com/docs/sql/functions/conditional/#examples)
--- START: docs/sql/functions/conversion/conversion.md ---
Documentation menu
[Home](/) / [Docs](/docs/) / Conversion functions
 Copy as Markdown
Conversion functions
====================
Conversion functions
====================
Trino will implicitly convert numeric and character values to the correct type if such a conversion is possible. Trino will not convert between character and numeric types. For example, a query that expects a varchar will not automatically convert a bigint value to an equivalent varchar.
When necessary, values can be explicitly cast to a particular type.
Conversion functions
--------------------
### cast
cast(value AS type) -> type
Explicitly cast a value as a type. This can be used to cast a varchar to a numeric value type and vice versa.
### try\_cast
try_cast(value AS type) -> type
Like [cast](https://www.peaka.com/docs/sql/functions/conversion/#cast), but returns null if the cast fails.
Formatting
----------
### format
format(format, args...) -> varchar
Returns a formatted string using the specified [format string](https://docs.oracle.com/en/java/javase/21/docs/api/java.base/java/util/Formatter.html#syntax) and arguments:
SELECT format('%s%%', 123);
-- '123%'
SELECT format('%.5f', pi());
-- '3.14159'
SELECT format('%03d', 8);
-- '008'
SELECT format('%,.2f', 1234567.89);
-- '1,234,567.89'
SELECT format('%-7s,%7s', 'hello', 'world');
-- 'hello , world'
SELECT format('%2$s %3$s %1$s', 'a', 'b', 'c');
-- 'b c a'
SELECT format('%1$tA, %1$tB %1$te, %1$tY', date '2006-07-04');
-- 'Tuesday, July 4, 2006'
### format\_number
format_number(number) -> varchar
Returns a formatted string using a unit symbol:
SELECT format_number(123456); -- '123K'
SELECT format_number(1000000); -- '1M'
Data size
---------
The `parse_data_size` function supports the following units:
Unit
Description
Value
`B`
Bytes
1
`kB`
Kilobytes
1024
`MB`
Megabytes
10242
`GB`
Gigabytes
10243
`TB`
Terabytes
10244
`PB`
Petabytes
10245
`EB`
Exabytes
10246
`ZB`
Zettabytes
10247
`YB`
Yottabytes
10248
### parse\_data\_size
parse_data_size(string) -> decimal(38)
Parses `string` of format `value unit` into a number, where `value` is the fractional number of `unit` values:
SELECT parse_data_size('1B'); -- 1
SELECT parse_data_size('1kB'); -- 1024
SELECT parse_data_size('1MB'); -- 1048576
SELECT parse_data_size('2.3MB'); -- 2411724
Miscellaneous
-------------
### typeof
typeof(expr) -> varchar
Returns the name of the type of the provided expression:
SELECT typeof(123); -- integer
SELECT typeof('cat'); -- varchar(3)
SELECT typeof(cos(2) + 1.5); -- double
On this page
* [Conversion functions](https://www.peaka.com/docs/sql/functions/conversion/#conversion-functions)
* [Conversion functions](https://www.peaka.com/docs/sql/functions/conversion/#conversion-functions-1)
* [Formatting](https://www.peaka.com/docs/sql/functions/conversion/#formatting)
* [Data size](https://www.peaka.com/docs/sql/functions/conversion/#data-size)
* [Miscellaneous](https://www.peaka.com/docs/sql/functions/conversion/#miscellaneous)
--- START: docs/sql/functions/datetime/datetime.md ---
Documentation menu
[Home](/) / [Docs](/docs/) / Date and time functions and operators
 Copy as Markdown
Date and time functions and operators
=====================================
These functions and operators operate on [date and time data types](/docs/sql/reference/types#date-time-data-types).
Date and time operators
-----------------------
Operator
Example
Result
`+`
`date '2012-08-08' + interval '2' day`
`2012-08-10`
`+`
`time '01:00' + interval '3' hour`
`04:00:00.000`
`+`
`timestamp '2012-08-08 01:00' + interval '29' hour`
`2012-08-09 06:00:00.000`
`+`
`timestamp '2012-10-31 01:00' + interval '1' month`
`2012-11-30 01:00:00.000`
`+`
`interval '2' day + interval '3' hour`
`2 03:00:00.000`
`+`
`interval '3' year + interval '5' month`
`3-5`
`-`
`date '2012-08-08' - interval '2' day`
`2012-08-06`
`-`
`time '01:00' - interval '3' hour`
`22:00:00.000`
`-`
`timestamp '2012-08-08 01:00' - interval '29' hour`
`2012-08-06 20:00:00.000`
`-`
`timestamp '2012-10-31 01:00' - interval '1' month`
`2012-09-30 01:00:00.000`
`-`
`interval '2' day - interval '3' hour`
`1 21:00:00.000`
`-`
`interval '3' year - interval '5' month`
`2-7`
Time zone conversion
--------------------
The `AT TIME ZONE` operator sets the time zone of a timestamp:
SELECT timestamp '2012-10-31 01:00 UTC';
-- 2012-10-31 01:00:00.000 UTC
SELECT timestamp '2012-10-31 01:00 UTC' AT TIME ZONE 'America/Los_Angeles';
-- 2012-10-30 18:00:00.000 America/Los_Angeles
Date and time functions
-----------------------
### current\_date
current_date
Returns the current date as of the start of the query.
### current\_time
current_time
Returns the current time with time zone as of the start of the query.
### current\_timestamp
current_timestamp
Returns the current timestamp with time zone as of the start of the query, with `3` digits of subsecond precision,
current_timestamp(p)
Returns the current [timestamp with time zone](/docs/sql/reference/types#timestamp-with-time-zone-data-type) as of the start of the query, with `p` digits of subsecond precision:
SELECT current_timestamp(6);
-- 2020-06-24 08:25:31.759993 America/Los_Angeles
### current\_timezone
current_timezone() -> varchar
Returns the current time zone in the format defined by IANA (e.g., `America/Los_Angeles`) or as fixed offset from UTC (e.g., `+08:35`)
### date
date(x) -> date
This is an alias for `CAST(x AS date)`.
### last\_day\_of\_month
last_day_of_month(x) -> date
Returns the last day of the month.
### from\_iso8601\_timestamp
from_iso8601_timestamp(string) -> timestamp(3) with time zone
Parses the ISO 8601 formatted date `string`, optionally with time and time zone, into a `timestamp(3) with time zone`. The time defaults to `00:00:00.000`, and the time zone defaults to the session time zone:
SELECT from_iso8601_timestamp('2020-05-11');
-- 2020-05-11 00:00:00.000 America/Vancouver
SELECT from_iso8601_timestamp('2020-05-11T11:15:05');
-- 2020-05-11 11:15:05.000 America/Vancouver
SELECT from_iso8601_timestamp('2020-05-11T11:15:05.055+01:00');
-- 2020-05-11 11:15:05.055 +01:00
### from\_iso8601\_timestamp\_nanos
from_iso8601_timestamp_nanos(string) -> timestamp(9) with time zone
Parses the ISO 8601 formatted date and time `string`. The time zone defaults to the session time zone:
SELECT from_iso8601_timestamp_nanos('2020-05-11T11:15:05');
-- 2020-05-11 11:15:05.000000000 America/Vancouver
SELECT from_iso8601_timestamp_nanos('2020-05-11T11:15:05.123456789+01:00');
-- 2020-05-11 11:15:05.123456789 +01:00
### from\_iso8601\_date
from_iso8601_date(string) -> date
Parses the ISO 8601 formatted date `string` into a `date`. The date can be a calendar date, a week date using ISO week numbering, or year and day of year combined:
SELECT from_iso8601_date('2020-05-11');
-- 2020-05-11
SELECT from_iso8601_date('2020-W10');
-- 2020-03-02
SELECT from_iso8601_date('2020-123');
-- 2020-05-02
### at\_timezone
at_timezone(timestamp(p), zone) -> timestamp(p) with time zone
Returns the timestamp specified in `timestamp` with the time zone converted from the session time zone to the time zone specified in `zone` with precision `p`. In the following example, the session time zone is set to `America/New_York`, which is three hours ahead of `America/Los_Angeles`:
SELECT current_timezone()
-- America/New_York
SELECT at_timezone(TIMESTAMP '2022-11-01 09:08:07.321', 'America/Los_Angeles')
-- 2022-11-01 06:08:07.321 America/Los_Angeles
### with\_timezone
with_timezone(timestamp(p), zone) -> timestamp(p) with time zone
Returns the timestamp specified in `timestamp` with the time zone specified in `zone` with precision `p`:
SELECT current_timezone()
-- America/New_York
SELECT with_timezone(TIMESTAMP '2022-11-01 09:08:07.321', 'America/Los_Angeles')
-- 2022-11-01 09:08:07.321 America/Los_Angeles
### from\_unixtime
from_unixtime(unixtime) -> timestamp(3) with time zone
Returns the UNIX timestamp `unixtime` as a timestamp with time zone. `unixtime` is the number of seconds since `1970-01-01 00:00:00 UTC`.
from_unixtime(unixtime, zone) -> timestamp(3) with time zone
Returns the UNIX timestamp `unixtime` as a timestamp with time zone using `zone` for the time zone. `unixtime` is the number of seconds since `1970-01-01 00:00:00 UTC`.
from_unixtime(unixtime, hours, minutes) -> timestamp(3) with time zone
Returns the UNIX timestamp `unixtime` as a timestamp with time zone using `hours` and `minutes` for the time zone offset. `unixtime` is the number of seconds since `1970-01-01 00:00:00` in `double` data type.
### from\_unixtime\_nanos
from_unixtime_nanos(unixtime) -> timestamp(9) with time zone
Returns the UNIX timestamp `unixtime` as a timestamp with time zone. `unixtime` is the number of nanoseconds since `1970-01-01 00:00:00.000000000 UTC`:
SELECT from_unixtime_nanos(100);
-- 1970-01-01 00:00:00.000000100 UTC
SELECT from_unixtime_nanos(DECIMAL '1234');
-- 1970-01-01 00:00:00.000001234 UTC
SELECT from_unixtime_nanos(DECIMAL '1234.499');
-- 1970-01-01 00:00:00.000001234 UTC
SELECT from_unixtime_nanos(DECIMAL '-1234');
-- 1969-12-31 23:59:59.999998766 UTC
### localtime
localtime
Returns the current time as of the start of the query.
### localtimestamp
localtimestamp
Returns the current timestamp as of the start of the query, with `3` digits of subsecond precision.
localtimestamp(p)
Returns the current [timestamp](/docs/sql/reference/types#timestamp) as of the start of the query, with `p` digits of subsecond precision:
SELECT localtimestamp(6);
-- 2020-06-10 15:55:23.383628
### now
now() -> timestamp(3) with time zone
This is an alias for `current_timestamp`.
### to\_iso8601
to_iso8601(x) -> varchar
Formats `x` as an ISO 8601 string. `x` can be date, timestamp, or timestamp with time zone.
### to\_milliseconds
to_milliseconds(interval) -> bigint
Returns the day-to-second `interval` as milliseconds.
### to\_unixtime
to_unixtime(timestamp) -> double
Returns `timestamp` as a UNIX timestamp.
The following SQL-standard functions do not use parenthesis:
* `current_date`
* `current_time`
* `current_timestamp`
* `localtime`
* `localtimestamp`
Truncation function
-------------------
The `date_trunc` function supports the following units:
Unit
Example Truncated Value
`millisecond`
`2001-08-22 03:04:05.321`
`second`
`2001-08-22 03:04:05.000`
`minute`
`2001-08-22 03:04:00.000`
`hour`
`2001-08-22 03:00:00.000`
`day`
`2001-08-22 00:00:00.000`
`week`
`2001-08-20 00:00:00.000`
`month`
`2001-08-01 00:00:00.000`
`quarter`
`2001-07-01 00:00:00.000`
`year`
`2001-01-01 00:00:00.000`
The above examples use the timestamp `2001-08-22 03:04:05.321` as the input.
### date\_trunc
date_trunc(unit, x) -> [same as input]
Returns `x` truncated to `unit`:
SELECT date_trunc('day' , TIMESTAMP '2022-10-20 05:10:00');
-- 2022-10-20 00:00:00.000
SELECT date_trunc('month' , TIMESTAMP '2022-10-20 05:10:00');
-- 2022-10-01 00:00:00.000
SELECT date_trunc('year', TIMESTAMP '2022-10-20 05:10:00');
-- 2022-01-01 00:00:00.000
Interval functions
------------------
The functions in this section support the following interval units:
Unit
Description
`millisecond`
Milliseconds
`second`
Seconds
`minute`
Minutes
`hour`
Hours
`day`
Days
`week`
Weeks
`month`
Months
`quarter`
Quarters of a year
`year`
Years
### date\_add
date_add(unit, value, timestamp) -> [same as input]
Adds an interval `value` of type `unit` to `timestamp`. Subtraction can be performed by using a negative value:
SELECT date_add('second', 86, TIMESTAMP '2020-03-01 00:00:00');
-- 2020-03-01 00:01:26.000
SELECT date_add('hour', 9, TIMESTAMP '2020-03-01 00:00:00');
-- 2020-03-01 09:00:00.000
SELECT date_add('day', -1, TIMESTAMP '2020-03-01 00:00:00 UTC');
-- 2020-02-29 00:00:00.000 UTC
### date\_diff
date_diff(unit, timestamp1, timestamp2) -> bigint
Returns `timestamp2 - timestamp1` expressed in terms of `unit`:
SELECT date_diff('second', TIMESTAMP '2020-03-01 00:00:00', TIMESTAMP '2020-03-02 00:00:00');
-- 86400
SELECT date_diff('hour', TIMESTAMP '2020-03-01 00:00:00 UTC', TIMESTAMP '2020-03-02 00:00:00 UTC');
-- 24
SELECT date_diff('day', DATE '2020-03-01', DATE '2020-03-02');
-- 1
SELECT date_diff('second', TIMESTAMP '2020-06-01 12:30:45.000000000', TIMESTAMP '2020-06-02 12:30:45.123456789');
-- 86400
SELECT date_diff('millisecond', TIMESTAMP '2020-06-01 12:30:45.000000000', TIMESTAMP '2020-06-02 12:30:45.123456789');
-- 86400123
Duration function
-----------------
The `parse_duration` function supports the following units:
Unit
Description
`ns`
Nanoseconds
`us`
Microseconds
`ms`
Milliseconds
`s`
Seconds
`m`
Minutes
`h`
Hours
`d`
Days
### parse\_duration
parse_duration(string) -> interval
Parses `string` of format `value unit` into an interval, where `value` is fractional number of `unit` values:
SELECT parse_duration('42.8ms');
-- 0 00:00:00.043
SELECT parse_duration('3.81 d');
-- 3 19:26:24.000
SELECT parse_duration('5m');
-- 0 00:05:00.000
### human\_readable\_seconds
human_readable_seconds(double) -> varchar
Formats the double value of `seconds` into a human readable string containing `weeks`, `days`, `hours`, `minutes`, and `seconds`:
SELECT human_readable_seconds(96);
-- 1 minute, 36 seconds
SELECT human_readable_seconds(3762);
-- 1 hour, 2 minutes, 42 seconds
SELECT human_readable_seconds(56363463);
-- 93 weeks, 1 day, 8 hours, 31 minutes, 3 seconds
MySQL date functions
--------------------
The functions in this section use a format string that is compatible with the MySQL `date_parse` and `str_to_date` functions. The following table, based on the MySQL manual, describes the format specifiers:
Specifier
Description
`%a`
Abbreviated weekday name (`Sun` .. `Sat`)
`%b`
Abbreviated month name (`Jan` .. `Dec`)
`%c`
Month, numeric (`1` .. `12`), this specifier does not support `0` as a month.
`%D`
Day of the month with English suffix (`0th`, `1st`, `2nd`, `3rd`, ...)
`%d`
Day of the month, numeric (`01` .. `31`), this specifier does not support `0` as a month or day.
`%e`
Day of the month, numeric (`1` .. `31`), this specifier does not support `0` as a day.
`%f`
Fraction of second (6 digits for printing: `000000` .. `999000`; 1 - 9 digits for parsing: `0` .. `999999999`), timestamp is truncated to milliseconds.
`%H`
Hour (`00` .. `23`)
`%h`
Hour (`01` .. `12`)
`%I`
Hour (`01` .. `12`)
`%i`
Minutes, numeric (`00` .. `59`)
`%j`
Day of year (`001` .. `366`)
`%k`
Hour (`0` .. `23`)
`%l`
Hour (`1` .. `12`)
`%M`
Month name (`January` .. `December`)
`%m`
Month, numeric (`01` .. `12`), this specifier does not support `0` as a month.
`%p`
`AM` or `PM`
`%r`
Time of day, 12-hour (equivalent to `%h:%i:%s %p`)
`%S`
Seconds (`00` .. `59`)
`%s`
Seconds (`00` .. `59`)
`%T`
Time of day, 24-hour (equivalent to `%H:%i:%s`)
`%U`
Week (`00` .. `53`), where Sunday is the first day of the week
`%u`
Week (`00` .. `53`), where Monday is the first day of the week
`%V`
Week (`01` .. `53`), where Sunday is the first day of the week; used with `%X`
`%v`
Week (`01` .. `53`), where Monday is the first day of the week; used with `%x`
`%W`
Weekday name (`Sunday` .. `Saturday`)
`%w`
Day of the week (`0` .. `6`), where Sunday is the first day of the week, this specifier is not supported,consider using `day_of_week` (it uses `1-7` instead of `0-6`).
`%X`
Year for the week where Sunday is the first day of the week, numeric, four digits; used with `%V`
`%x`
Year for the week, where Monday is the first day of the week, numeric, four digits; used with `%v`
`%Y`
Year, numeric, four digits
`%y`
Year, numeric (two digits), when parsing, two-digit year format assumes range `1970` .. `2069`, so "70" will result in year `1970` but "69" will produce `2069`.
`%%`
A literal `%` character
`%x`
`x`, for any `x` not listed above
The following specifiers are not currently supported: `%D %U %u %V %w %X`
### date\_format
date_format(timestamp, format) -> varchar
Formats `timestamp` as a string using `format`:
SELECT date_format(TIMESTAMP '2022-10-20 05:10:00', '%m-%d-%Y %H');
-- 10-20-2022 05
### date\_parse
date_parse(string, format) → timestamp(3)
Parses `string` into a timestamp using `format`:
SELECT date_parse('2022/10/20/05', '%Y/%m/%d/%H');
-- 2022-10-20 05:00:00.000
Java date functions
-------------------
The functions in this section use a format string that is compatible with JodaTime's [DateTimeFormat](http://joda-time.sourceforge.net/apidocs/org/joda/time/format/DateTimeFormat.html) pattern format.
### format\_datetime
format_datetime(timestamp, format) -> varchar
Formats `timestamp` as a string using `format`.
### parse\_datetime
parse_datetime(string, format) -> timestamp with time zone
Parses `string` into a timestamp with time zone using `format`.
Extraction function
-------------------
The `extract` function supports the following fields:
Field
Description
`YEAR`
`year`
`QUARTER`
`quarter`
`MONTH`
`month`
`WEEK`
`week`
`DAY`
`day`
`DAY_OF_MONTH`
`day`
`DAY_OF_WEEK`
`day_of_week`
`DOW`
`day_of_week`
`DAY_OF_YEAR`
`day_of_year`
`DOY`
`day_of_year`
`YEAR_OF_WEEK`
`year_of_week`
`YOW`
`year_of_week`
`HOUR`
`hour`
`MINUTE`
`minute`
`SECOND`
`second`
`TIMEZONE_HOUR`
`timezone_hour`
`TIMEZONE_MINUTE`
`timezone_minute`
The types supported by the `extract` function vary depending on the field to be extracted. Most fields support all date and time types.
### extract
extract(field FROM x) -> bigint
Returns `field` from `x`:
SELECT extract(YEAR FROM TIMESTAMP '2022-10-20 05:10:00');
-- 2022
This SQL-standard function uses special syntax for specifying the arguments.
Convenience extraction functions
--------------------------------
### day
day(x) -> bigint
Returns the day of the month from `x`.
### day\_of\_month
day_of_month(x) -> bigint
This is an alias for `day`.
### day\_of\_week
day_of_week(x) -> bigint
Returns the ISO day of the week from `x`. The value ranges from `1` (Monday) to `7` (Sunday).
### day\_of\_year
day_of_year(x) -> bigint
Returns the day of the year from `x`. The value ranges from `1` to `366`.
### dow
dow(x) -> bigint
This is an alias for `day_of_week`.
### doy
doy(x) -> bigint
This is an alias for `day_of_year`.
### hour
hour(x) -> bigint
Returns the hour of the day from `x`. The value ranges from `0` to `23`.
### millisecond
millisecond(x) -> bigint
Returns the millisecond of the second from `x`.
### minute
minute(x) -> bigint
Returns the minute of the hour from `x`.
### month
month(x) -> bigint
Returns the month of the year from `x`.
### quarter
quarter(x) -> bigint
Returns the quarter of the year from `x`. The value ranges from `1` to `4`.
### second
second(x) -> bigint
Returns the second of the minute from `x`.
### timezone\_hour
timezone_hour(timestamp) -> bigint
Returns the hour of the time zone offset from `timestamp`.
### timezone\_minute
timezone_minute(timestamp) -> bigint
Returns the minute of the time zone offset from `timestamp`.
### week
week(x) -> bigint
Returns the ISO week of the year from `x`. The value ranges from `1` to `53`.
### week\_of\_year
week_of_year(x) -> bigint
This is an alias for [week](https://www.peaka.com/docs/sql/functions/datetime/#week).
### year
year(x) -> bigint
Returns the year from `x`.
### year\_of\_week
year_of_week(x) -> bigint
Returns the year of the \[ISO week\] from `x`.
### yow
yow(x) -> bigint
This is an alias for [year\_of\_week](https://www.peaka.com/docs/sql/functions/datetime/#year-of-week).
On this page
* [Date and time operators](https://www.peaka.com/docs/sql/functions/datetime/#date-and-time-operators)
* [Time zone conversion](https://www.peaka.com/docs/sql/functions/datetime/#time-zone-conversion)
* [Date and time functions](https://www.peaka.com/docs/sql/functions/datetime/#date-and-time-functions)
* [current\_date](https://www.peaka.com/docs/sql/functions/datetime/#current-date)
* [current\_time](https://www.peaka.com/docs/sql/functions/datetime/#current-time)
* [current\_timestamp](https://www.peaka.com/docs/sql/functions/datetime/#current-timestamp)
* [current\_timezone](https://www.peaka.com/docs/sql/functions/datetime/#current-timezone)
* [date](https://www.peaka.com/docs/sql/functions/datetime/#date)
* [last\_day\_of\_month](https://www.peaka.com/docs/sql/functions/datetime/#last-day-of-month)
* [from\_iso8601\_timestamp](https://www.peaka.com/docs/sql/functions/datetime/#from-iso8601-timestamp)
* [from\_iso8601\_timestamp\_nanos](https://www.peaka.com/docs/sql/functions/datetime/#from-iso8601-timestamp-nanos)
* [from\_iso8601\_date](https://www.peaka.com/docs/sql/functions/datetime/#from-iso8601-date)
* [at\_timezone](https://www.peaka.com/docs/sql/functions/datetime/#at-timezone)
* [with\_timezone](https://www.peaka.com/docs/sql/functions/datetime/#with-timezone)
* [from\_unixtime](https://www.peaka.com/docs/sql/functions/datetime/#from-unixtime)
* [from\_unixtime\_nanos](https://www.peaka.com/docs/sql/functions/datetime/#from-unixtime-nanos)
* [localtime](https://www.peaka.com/docs/sql/functions/datetime/#localtime)
* [localtimestamp](https://www.peaka.com/docs/sql/functions/datetime/#localtimestamp)
* [now](https://www.peaka.com/docs/sql/functions/datetime/#now)
* [to\_iso8601](https://www.peaka.com/docs/sql/functions/datetime/#to-iso8601)
* [to\_milliseconds](https://www.peaka.com/docs/sql/functions/datetime/#to-milliseconds)
* [to\_unixtime](https://www.peaka.com/docs/sql/functions/datetime/#to-unixtime)
* [Truncation function](https://www.peaka.com/docs/sql/functions/datetime/#truncation-function)
* [date\_trunc](https://www.peaka.com/docs/sql/functions/datetime/#date-trunc)
* [Interval functions](https://www.peaka.com/docs/sql/functions/datetime/#interval-functions)
* [date\_add](https://www.peaka.com/docs/sql/functions/datetime/#date-add)
* [date\_diff](https://www.peaka.com/docs/sql/functions/datetime/#date-diff)
* [Duration function](https://www.peaka.com/docs/sql/functions/datetime/#duration-function)
* [parse\_duration](https://www.peaka.com/docs/sql/functions/datetime/#parse-duration)
* [human\_readable\_seconds](https://www.peaka.com/docs/sql/functions/datetime/#human-readable-seconds)
* [MySQL date functions](https://www.peaka.com/docs/sql/functions/datetime/#mysql-date-functions)
* [date\_format](https://www.peaka.com/docs/sql/functions/datetime/#date-format)
* [date\_parse](https://www.peaka.com/docs/sql/functions/datetime/#date-parse)
* [Java date functions](https://www.peaka.com/docs/sql/functions/datetime/#java-date-functions)
* [format\_datetime](https://www.peaka.com/docs/sql/functions/datetime/#format-datetime)
* [parse\_datetime](https://www.peaka.com/docs/sql/functions/datetime/#parse-datetime)
* [Extraction function](https://www.peaka.com/docs/sql/functions/datetime/#extraction-function)
* [extract](https://www.peaka.com/docs/sql/functions/datetime/#extract)
* [Convenience extraction functions](https://www.peaka.com/docs/sql/functions/datetime/#convenience-extraction-functions)
* [day](https://www.peaka.com/docs/sql/functions/datetime/#day)
* [day\_of\_month](https://www.peaka.com/docs/sql/functions/datetime/#day-of-month)
* [day\_of\_week](https://www.peaka.com/docs/sql/functions/datetime/#day-of-week)
* [day\_of\_year](https://www.peaka.com/docs/sql/functions/datetime/#day-of-year)
* [dow](https://www.peaka.com/docs/sql/functions/datetime/#dow)
* [doy](https://www.peaka.com/docs/sql/functions/datetime/#doy)
* [hour](https://www.peaka.com/docs/sql/functions/datetime/#hour)
* [millisecond](https://www.peaka.com/docs/sql/functions/datetime/#millisecond)
* [minute](https://www.peaka.com/docs/sql/functions/datetime/#minute)
* [month](https://www.peaka.com/docs/sql/functions/datetime/#month)
* [quarter](https://www.peaka.com/docs/sql/functions/datetime/#quarter)
* [second](https://www.peaka.com/docs/sql/functions/datetime/#second)
* [timezone\_hour](https://www.peaka.com/docs/sql/functions/datetime/#timezone-hour)
* [timezone\_minute](https://www.peaka.com/docs/sql/functions/datetime/#timezone-minute)
* [week](https://www.peaka.com/docs/sql/functions/datetime/#week)
* [week\_of\_year](https://www.peaka.com/docs/sql/functions/datetime/#week-of-year)
* [year](https://www.peaka.com/docs/sql/functions/datetime/#year)
* [year\_of\_week](https://www.peaka.com/docs/sql/functions/datetime/#year-of-week)
* [yow](https://www.peaka.com/docs/sql/functions/datetime/#yow)
--- START: docs/sql/functions/decimal/decimal.md ---
Documentation menu
[Home](/) / [Docs](/docs/) / Decimal functions and operators
 Copy as Markdown
Decimal functions and operators
===============================
Decimal literals
----------------
Use the `DECIMAL 'xxxxxxx.yyyyyyy'` syntax to define a decimal literal.
The precision of a decimal type for a literal will be equal to the number of digits in the literal (including trailing and leading zeros). The scale will be equal to the number of digits in the fractional part (including trailing zeros).
Example literal
Data type
`DECIMAL '0'`
`DECIMAL(1)`
`DECIMAL '12345'`
`DECIMAL(5)`
`DECIMAL '0000012345.1234500000'`
`DECIMAL(20, 10)`
Binary arithmetic decimal operators
-----------------------------------
Standard mathematical operators are supported. The table below explains precision and scale calculation rules for result. Assuming `x` is of type `DECIMAL(xp, xs)` and `y` is of type `DECIMAL(yp, ys)`.
Operation
Result type precision
Result type scale
`x + y` and `x - y`
`min(38, 1 + max(xs, ys) + max(xp - xs, yp - ys))`
`max(xs, ys)`
`x * y`
`min(38, xp + yp)`
`xs + ys`
`x / y`
`min(38, xp + ys-xs + max(0, ys-xs))`
`max(xs, ys)`
`x % y`
`min(xp - xs, yp - ys) + max(xs, bs)`
`max(xs, ys)`
If the mathematical result of the operation is not exactly representable with the precision and scale of the result data type, then an exception condition is raised: `Value is out of range`.
When operating on decimal types with different scale and precision, the values are first coerced to a common super type. For types near the largest representable precision (38), this can result in Value is out of range errors when one of the operands doesn't fit in the common super type. For example, the common super type of decimal(38, 0) and decimal(38, 1) is decimal(38, 1), but certain values that fit in decimal(38, 0) cannot be represented as a decimal(38, 1).
Comparison operators
--------------------
All standard [comparison](/docs/sql/functions/comparison#comparison-operators) work for the decimal type.
Unary decimal operators
-----------------------
The `-` operator performs negation. The type of result is same as type of argument.
On this page
* [Decimal literals](https://www.peaka.com/docs/sql/functions/decimal/#decimal-literals)
* [Binary arithmetic decimal operators](https://www.peaka.com/docs/sql/functions/decimal/#binary-arithmetic-decimal-operators)
* [Comparison operators](https://www.peaka.com/docs/sql/functions/decimal/#comparison-operators)
* [Unary decimal operators](https://www.peaka.com/docs/sql/functions/decimal/#unary-decimal-operators)
--- START: docs/sql/functions/hyperloglog/hyperloglog.md ---
Documentation menu
[Home](/) / [Docs](/docs/) / HyperLogLog Functions
 Copy as Markdown
HyperLogLog Functions
=====================
Trino implements the `approx_distinct` function using the [HyperLogLog](https://wikipedia.org/wiki/HyperLogLog) data structure.
Data structures
---------------
Trino implements HyperLogLog data sketches as a set of 32-bit buckets which store a _maximum hash_. They can be stored sparsely (as a map from bucket ID to bucket), or densely (as a contiguous memory block). The HyperLogLog data structure starts as the sparse representation, switching to dense when it is more efficient. The P4HyperLogLog structure is initialized densely and remains dense for its lifetime.
[HyperLogLog](/docs/sql/reference/types#hyperloglog) implicitly casts to [P4HyperLogLog](/docs/sql/reference/types#p4hyperloglog), while one can explicitly cast `HyperLogLog` to `P4HyperLogLog`:
cast(hll AS P4HyperLogLog)
Serialization
-------------
Data sketches can be serialized to and deserialized from `varbinary`. This allows them to be stored for later use. Combined with the ability to merge multiple sketches, this allows one to calculate `approx_distinct` of the elements of a partition of a query, then for the entirety of a query with very little cost.
For example, calculating the `HyperLogLog` for daily unique users will allow weekly or monthly unique users to be calculated incrementally by combining the dailies. This is similar to computing weekly revenue by summing daily revenue. Uses of `approx_distinct` with `GROUPING SETS` can be converted to use `HyperLogLog`. Examples:
CREATE TABLE visit_summaries (
visit_date date,
hll varbinary
);
INSERT INTO visit_summaries
SELECT visit_date, cast(approx_set(user_id) AS varbinary)
FROM user_visits
GROUP BY visit_date;
SELECT cardinality(merge(cast(hll AS HyperLogLog))) AS weekly_unique_users
FROM visit_summaries
WHERE visit_date >= current_date - interval '7' day;
Functions
---------
### approx\_set
approx_set(x) -> HyperLogLog
Returns the `HyperLogLog` sketch of the input data set of `x`. This data sketch underlies `approx_distinct` and can be stored and used later by calling `cardinality()`.
### cardinality
cardinality(hll) -> bigint
This will perform `approx_distinct` on the data summarized by the `hll` HyperLogLog data sketch.
### empty\_approx\_set
empty_approx_set() -> HyperLogLog
Returns an empty `HyperLogLog`.
### merge
merge(HyperLogLog) -> HyperLogLog
Returns the `HyperLogLog` of the aggregate union of the individual `hll` HyperLogLog structures.
On this page
* [Data structures](https://www.peaka.com/docs/sql/functions/hyperloglog/#data-structures)
* [Serialization](https://www.peaka.com/docs/sql/functions/hyperloglog/#serialization)
* [Functions](https://www.peaka.com/docs/sql/functions/hyperloglog/#functions)
* [approx\_set](https://www.peaka.com/docs/sql/functions/hyperloglog/#approx-set)
* [cardinality](https://www.peaka.com/docs/sql/functions/hyperloglog/#cardinality)
* [empty\_approx\_set](https://www.peaka.com/docs/sql/functions/hyperloglog/#empty-approx-set)
* [merge](https://www.peaka.com/docs/sql/functions/hyperloglog/#merge)
--- START: docs/sql/functions/json/json.md ---
Documentation menu
[Home](/) / [Docs](/docs/) / JSON functions and operators
 Copy as Markdown
JSON functions and operators
============================
The SQL standard describes functions and operators to process JSON data. They allow you to access JSON data according to its structure, generate JSON data, and store it persistently in SQL tables.
Importantly, the SQL standard imposes that there is no dedicated data type to represent JSON data in SQL. Instead, JSON data is represented as character or binary strings. Although Trino supports `JSON` type, it is not used or produced by the following functions.
Trino supports three functions for querying JSON data: [json\_exists](https://www.peaka.com/docs/sql/functions/json/#json-exists), [json\_query](https://www.peaka.com/docs/sql/functions/json/#json-query), and [json\_value](https://www.peaka.com/docs/sql/functions/json/#json-value). Each of them is based on the same mechanism of exploring and processing JSON input using JSON path.
Trino also supports two functions for generating JSON data: [json-array](https://www.peaka.com/docs/sql/functions/json/#json-array), and [json\_object](https://www.peaka.com/docs/sql/functions/json/#json-object).
JSON path language
------------------
The JSON path language is a special language, used exclusively by certain SQL operators to specify the query to perform on the JSON input. Although JSON path expressions are embedded in SQL queries, their syntax significantly differs from SQL. The semantics of predicates, operators, etc. in JSON path expressions generally follow the semantics of SQL. The JSON path language is case-sensitive for keywords and identifiers.
### JSON path syntax and semantics
JSON path expressions are recursive structures. Although the name "path" suggests a linear sequence of operations going step by step deeper into the JSON structure, a JSON path expression is in fact a tree. It can access the input JSON item multiple times, in multiple ways, and combine the results. Moreover, the result of a JSON path expression is not a single item, but an ordered sequence of items. Each of the sub-expressions takes one or more input sequences, and returns a sequence as the result.
In the lax mode, most path operations first unnest all JSON arrays in the input sequence. Any divergence from this rule is mentioned in the following listing. Path modes are explained in [JSON path modes](#json-path-modes).
The JSON path language features are divided into: literals, variables, arithmetic binary expressions, arithmetic unary expressions, and a group of operators collectively known as accessors.
#### literals
* numeric literals
They include exact and approximate numbers, and are interpreted as if they were SQL values.
-1, 1.2e3, NaN
* string literals
They are enclosed in double quotes.
"Some text"
* boolean literals
true, false
* null literal
It has the semantics of the JSON null, not of SQL null. See [comparison rules](https://www.peaka.com/docs/sql/functions/json/#comparison-rules).
null
#### variables
* context variable
It refers to the currently processed input of the JSON function.
$
* named variable
It refers to a named parameter by its name.
$param
* current item variable
It is used inside the filter expression to refer to the currently processed item from the input sequence.
@
* last subscript variable
It refers to the last index of the innermost enclosing array. Array indexes in JSON path expressions are zero-based.
last
#### arithmetic binary expressions
The JSON path language supports five arithmetic binary operators:
+
-
*
/
%
Both operands, `` and ``, are evaluated to sequences of items. For arithmetic binary operators, each input sequence must contain a single numeric item. The arithmetic operation is performed according to SQL semantics, and it returns a sequence containing a single element with the result.
The operators follow the same precedence rules as in SQL arithmetic operations, and parentheses can be used for grouping.
#### arithmetic unary expressions
+
-
The operand `` is evaluated to a sequence of items. Every item must be a numeric value. The unary plus or minus is applied to every item in the sequence, following SQL semantics, and the results form the returned sequence.
#### member accessor
The member accessor returns the value of the member with the specified key for each JSON object in the input sequence.
.key
."key"
The condition when a JSON object does not have such a member is called a structural error. In the lax mode, it is suppressed, and the faulty object is excluded from the result.
Let `` return a sequence of three JSON objects:
{"customer" : 100, "region" : "AFRICA"},
{"region" : "ASIA"},
{"customer" : 300, "region" : "AFRICA", "comment" : null}
the expression `.customer` succeeds in the first and the third object, but the second object lacks the required member. In strict mode, path evaluation fails. In lax mode, the second object is silently skipped, and the resulting sequence is `100, 300`.
All items in the input sequence must be JSON objects.
Trino does not support JSON objects with duplicate keys.
#### wildcard member accessor
Returns values from all key-value pairs for each JSON object in the input sequence. All the partial results are concatenated into the returned sequence.
.*
Let `` return a sequence of three JSON objects:
{"customer" : 100, "region" : "AFRICA"},
{"region" : "ASIA"},
{"customer" : 300, "region" : "AFRICA", "comment" : null}
The results is:
100, "AFRICA", "ASIA", 300, "AFRICA", null
All items in the input sequence must be JSON objects.
The order of values returned from a single JSON object is arbitrary. The sub-sequences from all JSON objects are concatenated in the same order in which the JSON objects appear in the input sequence.
#### descendant member accessor
Returns the values associated with the specified key in all JSON objects on all levels of nesting in the input sequence.
..key
.."key"
The order of returned values is that of preorder depth first search. First, the enclosing object is visited, and then all child nodes are visited.
This method does not perform array unwrapping in the lax mode. The results are the same in the lax and strict modes. The method traverses into JSON arrays and JSON objects. Non-structural JSON items are skipped.
Let `` be a sequence containing a JSON object:
{
"id" : 1,
"notes" : [{"type" : 1, "comment" : "foo"}, {"type" : 2, "comment" : null}],
"comment" : ["bar", "baz"]
}
..comment --> ["bar", "baz"], "foo", null
#### array accessor
Returns the elements at the specified indexes for each JSON array in the input sequence. Indexes are zero-based.
[ ]
The `` list contains one or more subscripts. Each subscript specifies a single index or a range (ends inclusive):
[, to , ,...]
In lax mode, any non-array items resulting from the evaluation of the input sequence are wrapped into single-element arrays. Note that this is an exception to the rule of automatic array wrapping.
Each array in the input sequence is processed in the following way:
* The variable `last` is set to the last index of the array.
* All subscript indexes are computed in order of declaration. For a singleton subscript ``, the result must be a singleton numeric item. For a range subscript ` to `, two numeric items are expected.
* The specified array elements are added in order to the output sequence.
Let `` return a sequence of three JSON arrays:
[0, 1, 2], ["a", "b", "c", "d"], [null, null]
The following expression returns a sequence containing the last element from every array:
[last] --> 2, "d", null
The following expression returns the third and fourth element from every array:
[2 to 3] --> 2, "c", "d"
Note that the first array does not have the fourth element, and the last array does not have the third or fourth element. Accessing non-existent elements is a structural error. In strict mode, it causes the path expression to fail. In lax mode, such errors are suppressed, and only the existing elements are returned.
Another example of a structural error is an improper range specification such as `5 to 3`.
Note that the subscripts may overlap, and they do not need to follow the element order. The order in the returned sequence follows the subscripts:
[1, 0, 0] --> 1, 0, 0, "b", "a", "a", null, null, null
#### wildcard array accessor
Returns all elements of each JSON array in the input sequence.
[*]
In lax mode, any non-array items resulting from the evaluation of the input sequence are wrapped into single-element arrays. Note that this is an exception to the rule of automatic array wrapping.
The output order follows the order of the original JSON arrays. Also, the order of elements within the arrays is preserved.
Let `` return a sequence of three JSON arrays:
[0, 1, 2], ["a", "b", "c", "d"], [null, null]
[*] --> 0, 1, 2, "a", "b", "c", "d", null, null
#### filter
Retrieves the items from the input sequence which satisfy the predicate.
?( )
JSON path predicates are syntactically similar to boolean expressions in SQL. However, the semantics are different in many aspects:
* They operate on sequences of items.
* They have their own error handling (they never fail).
* They behave different depending on the lax or strict mode.
The predicate evaluates to `true`, `false`, or `unknown`. Note that some predicate expressions involve nested JSON path expression. When evaluating the nested path, the variable `@` refers to the currently examined item from the input sequence.
The following predicate expressions are supported:
* Conjunction
&&
* Disjunction
||
* Negation
!
* `exists` predicate
exists( )
Returns `true` if the nested path evaluates to a non-empty sequence, and `false` when the nested path evaluates to an empty sequence. If the path evaluation throws an error, returns `unknown`.
* `starts with` predicate
starts with "Some text"
starts with $variable
The nested `` must evaluate to a sequence of textual items, and the other operand must evaluate to a single textual item. If evaluating of either operand throws an error, the result is `unknown`. All items from the sequence are checked for starting with the right operand. The result is `true` if a match is found, otherwise `false`. However, if any of the comparisons throws an error, the result in the strict mode is `unknown`. The result in the lax mode depends on whether the match or the error was found first.
* `is unknown` predicate
( ) is unknown
Returns `true` if the nested predicate evaluates to `unknown`, and `false` otherwise.
* Comparisons
==
<>
!=
<
>
<=
>=